IBM/Any-to-Any
IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.
Category · text
Open-weight large language models for chat, writing, and general reasoning — the foundation models you can download, fine-tune, and self-host instead of calling a closed API.
197 releases
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
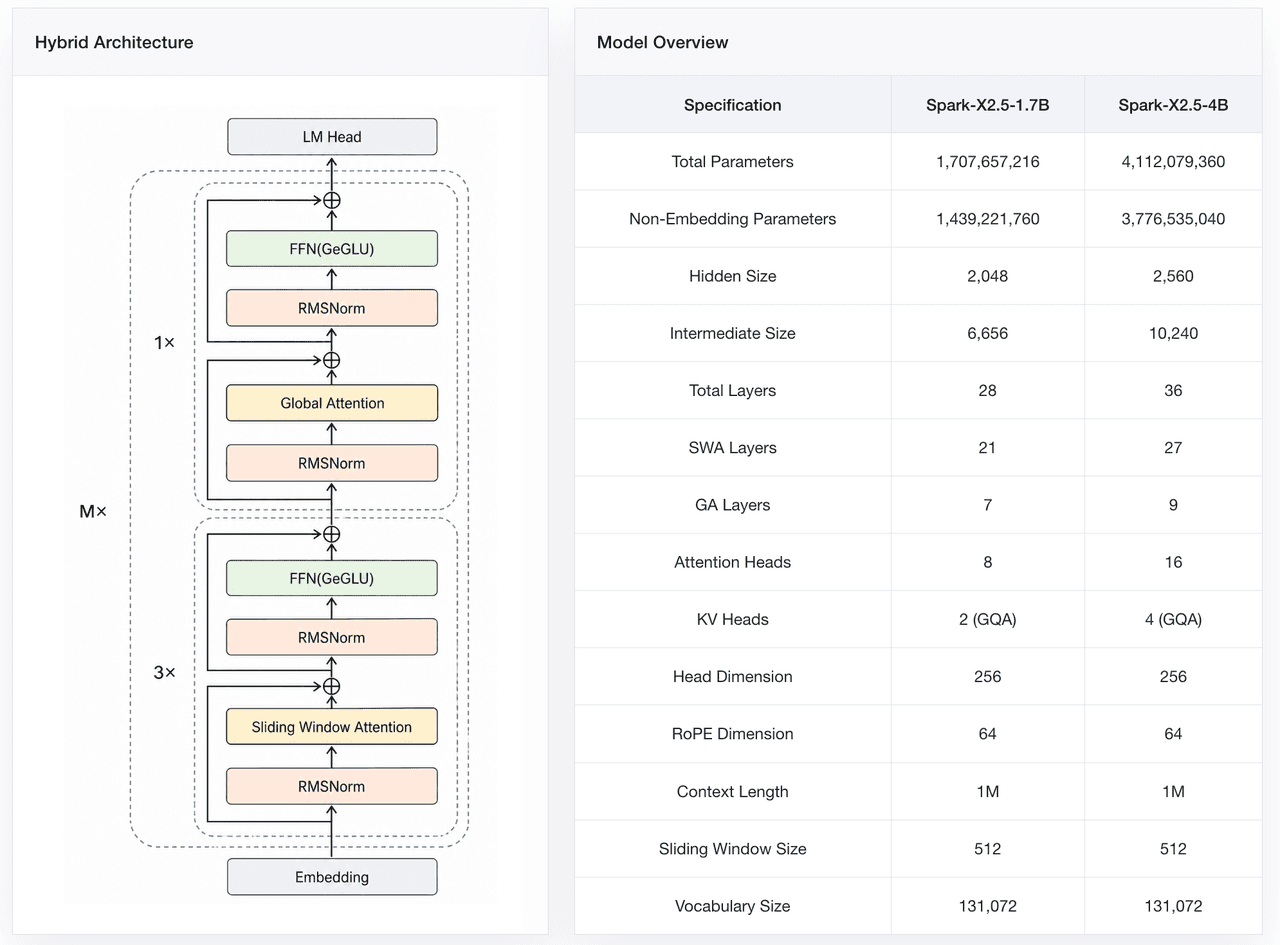
A compact 1.7B-parameter multilingual model built to run locally and serve as the base for specialized multimodal variants.
The new conversational LLM ships under a permissive license with community GGUF builds already available for local use.
The Korean game studio behind PUBG puts out a compact, permissively licensed language model as an early preview.
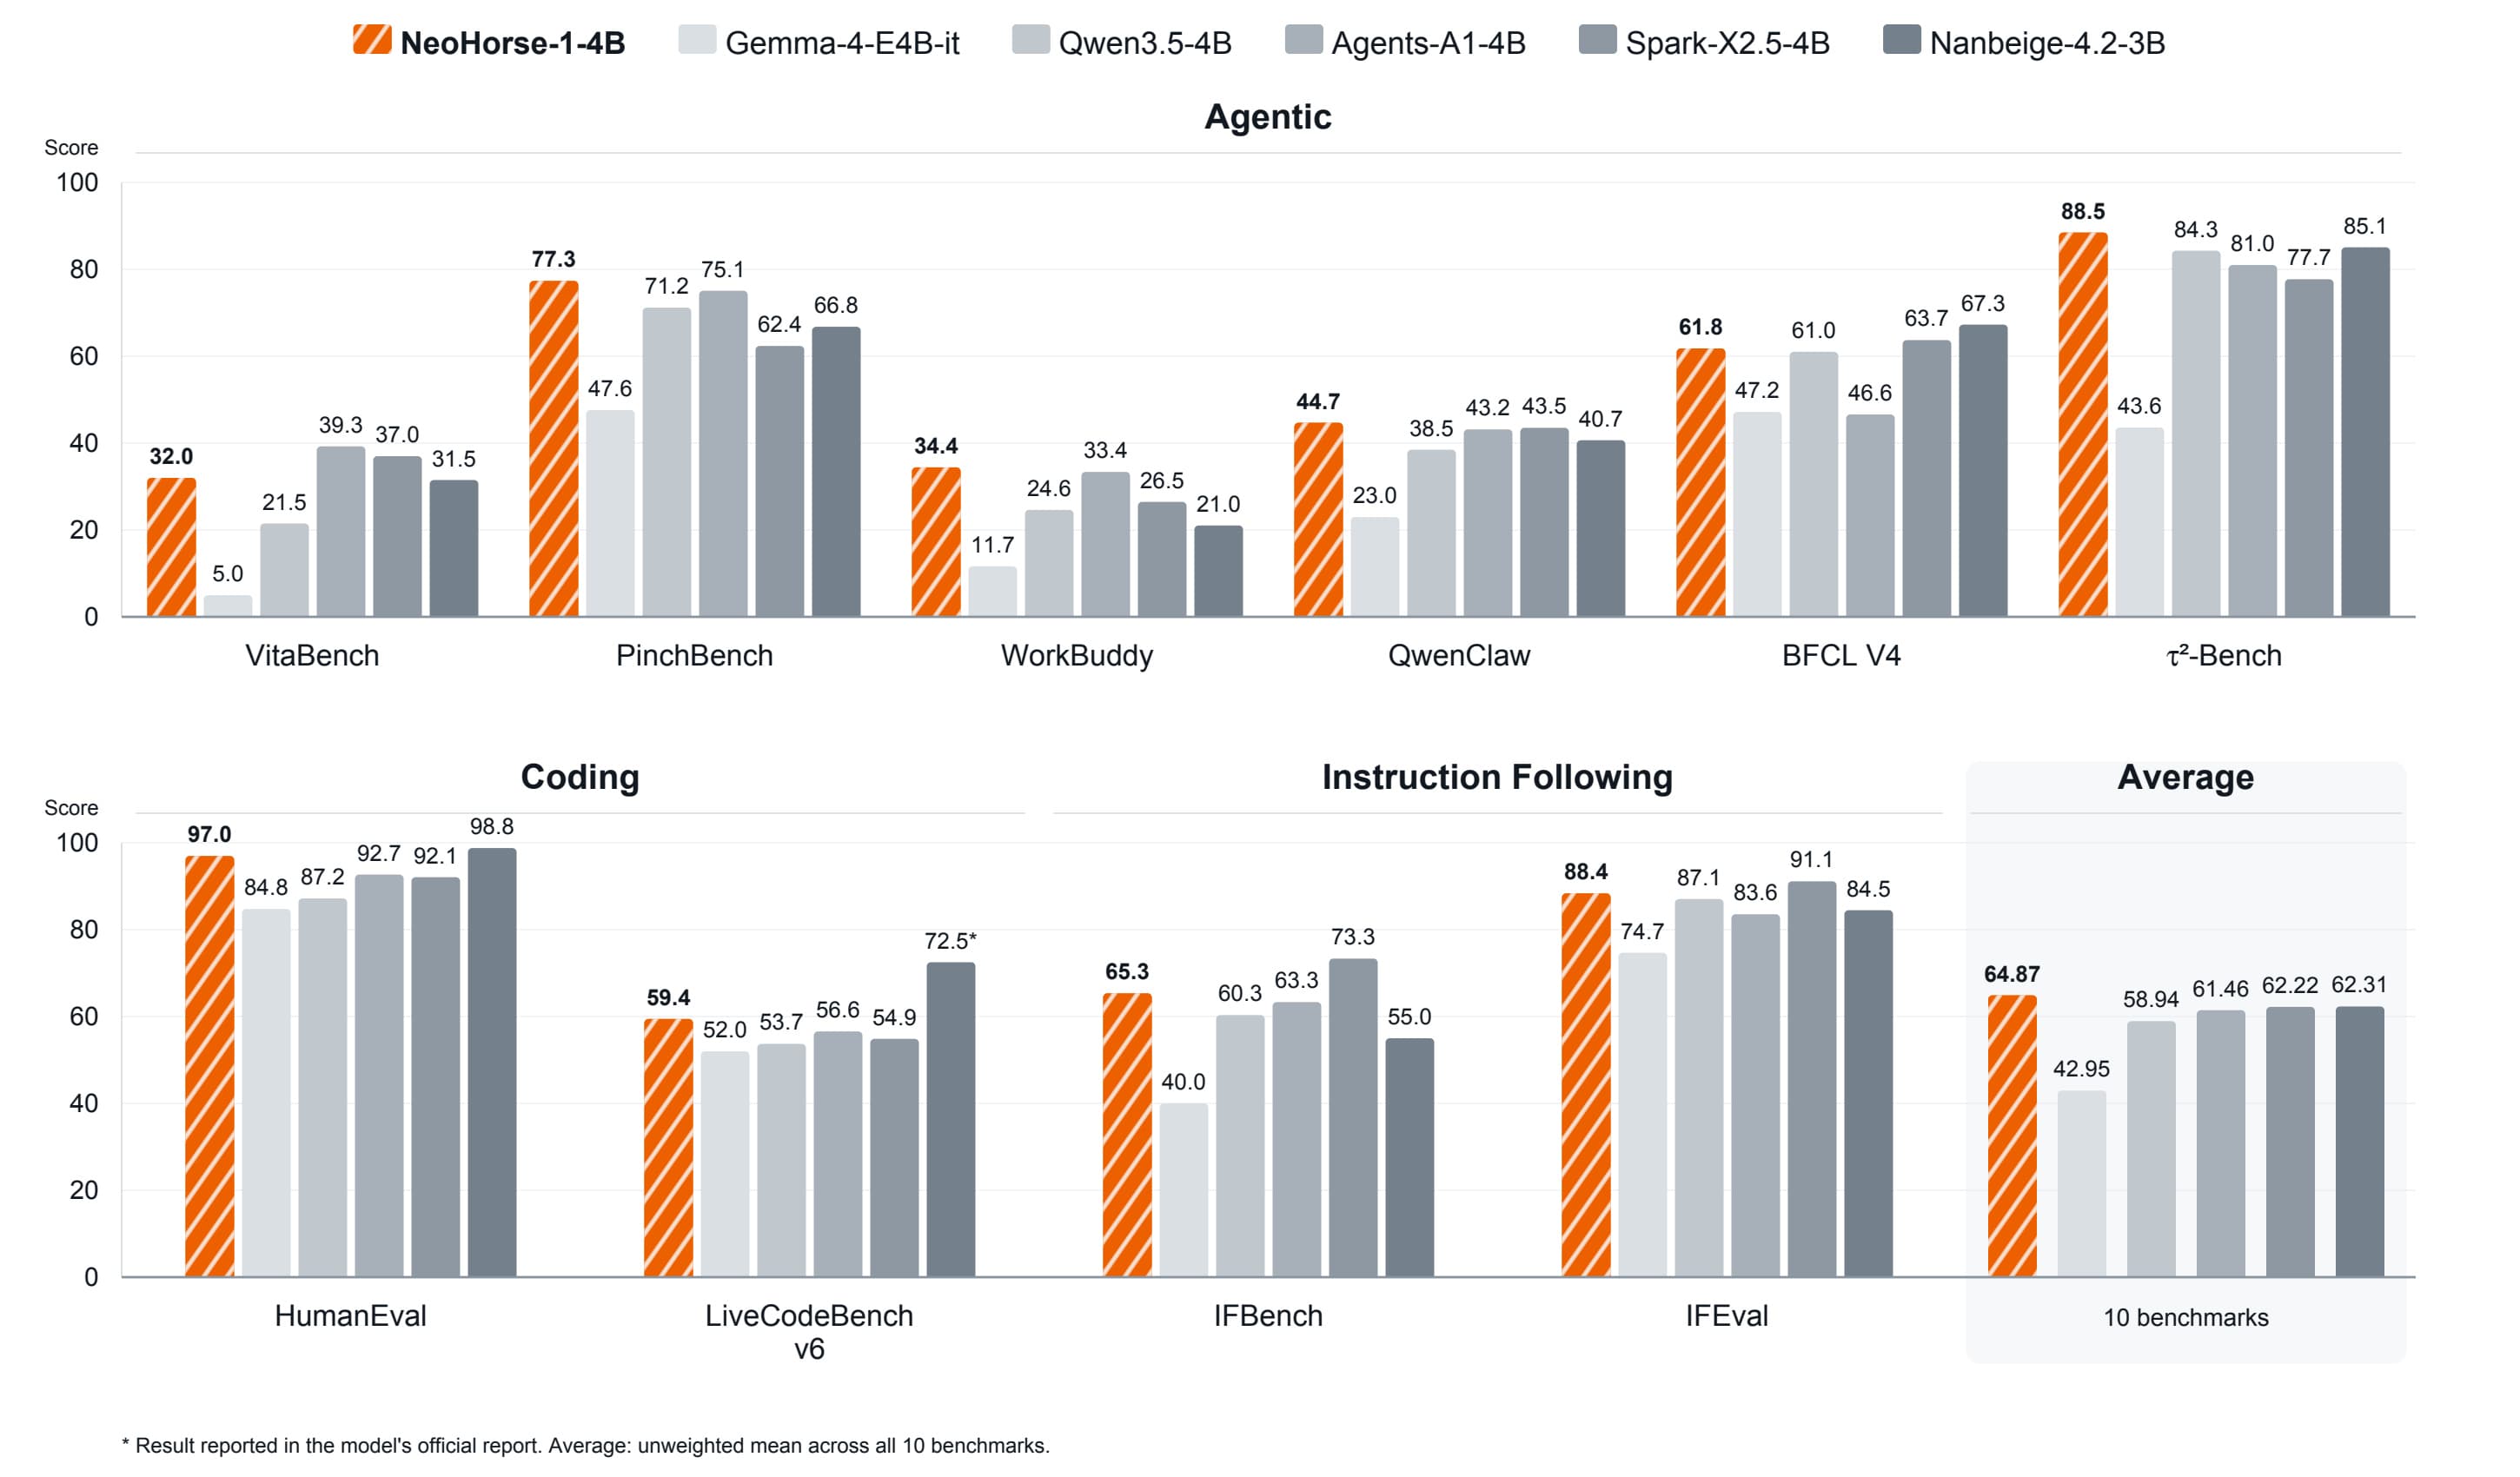
A compact 4-billion-parameter instruction model targets English and Chinese tasks under a permissive Apache 2.0 license.
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
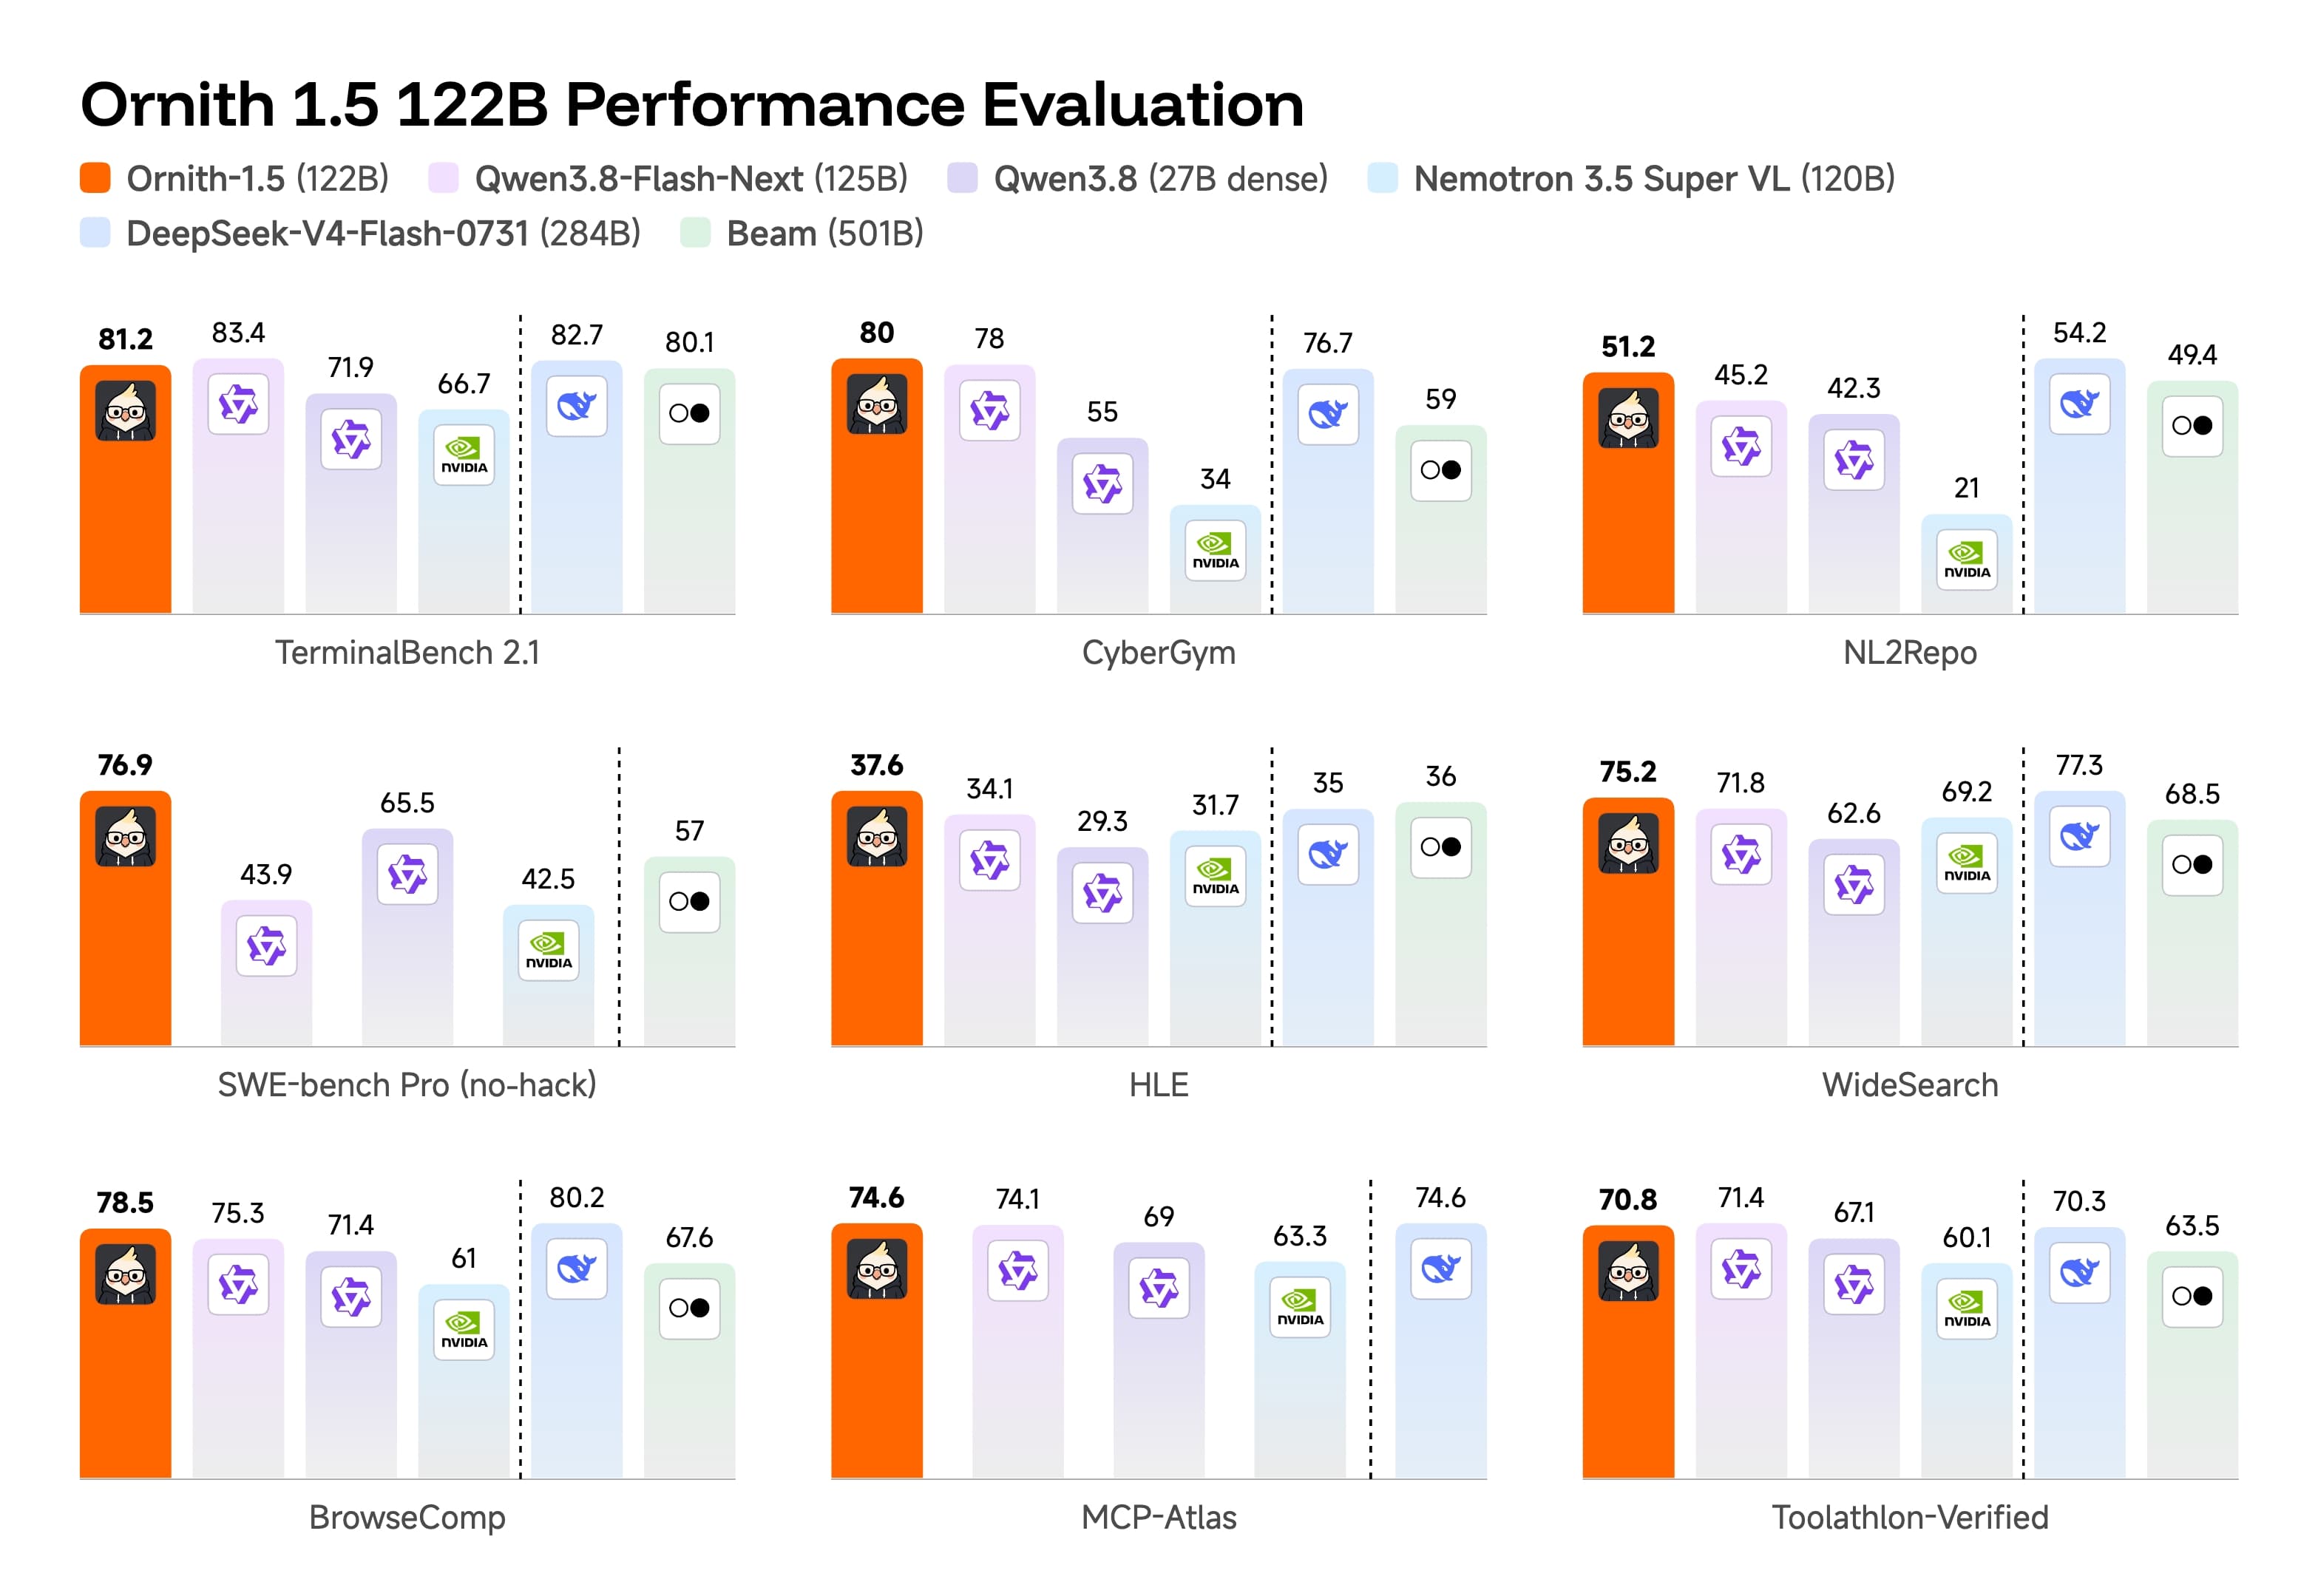
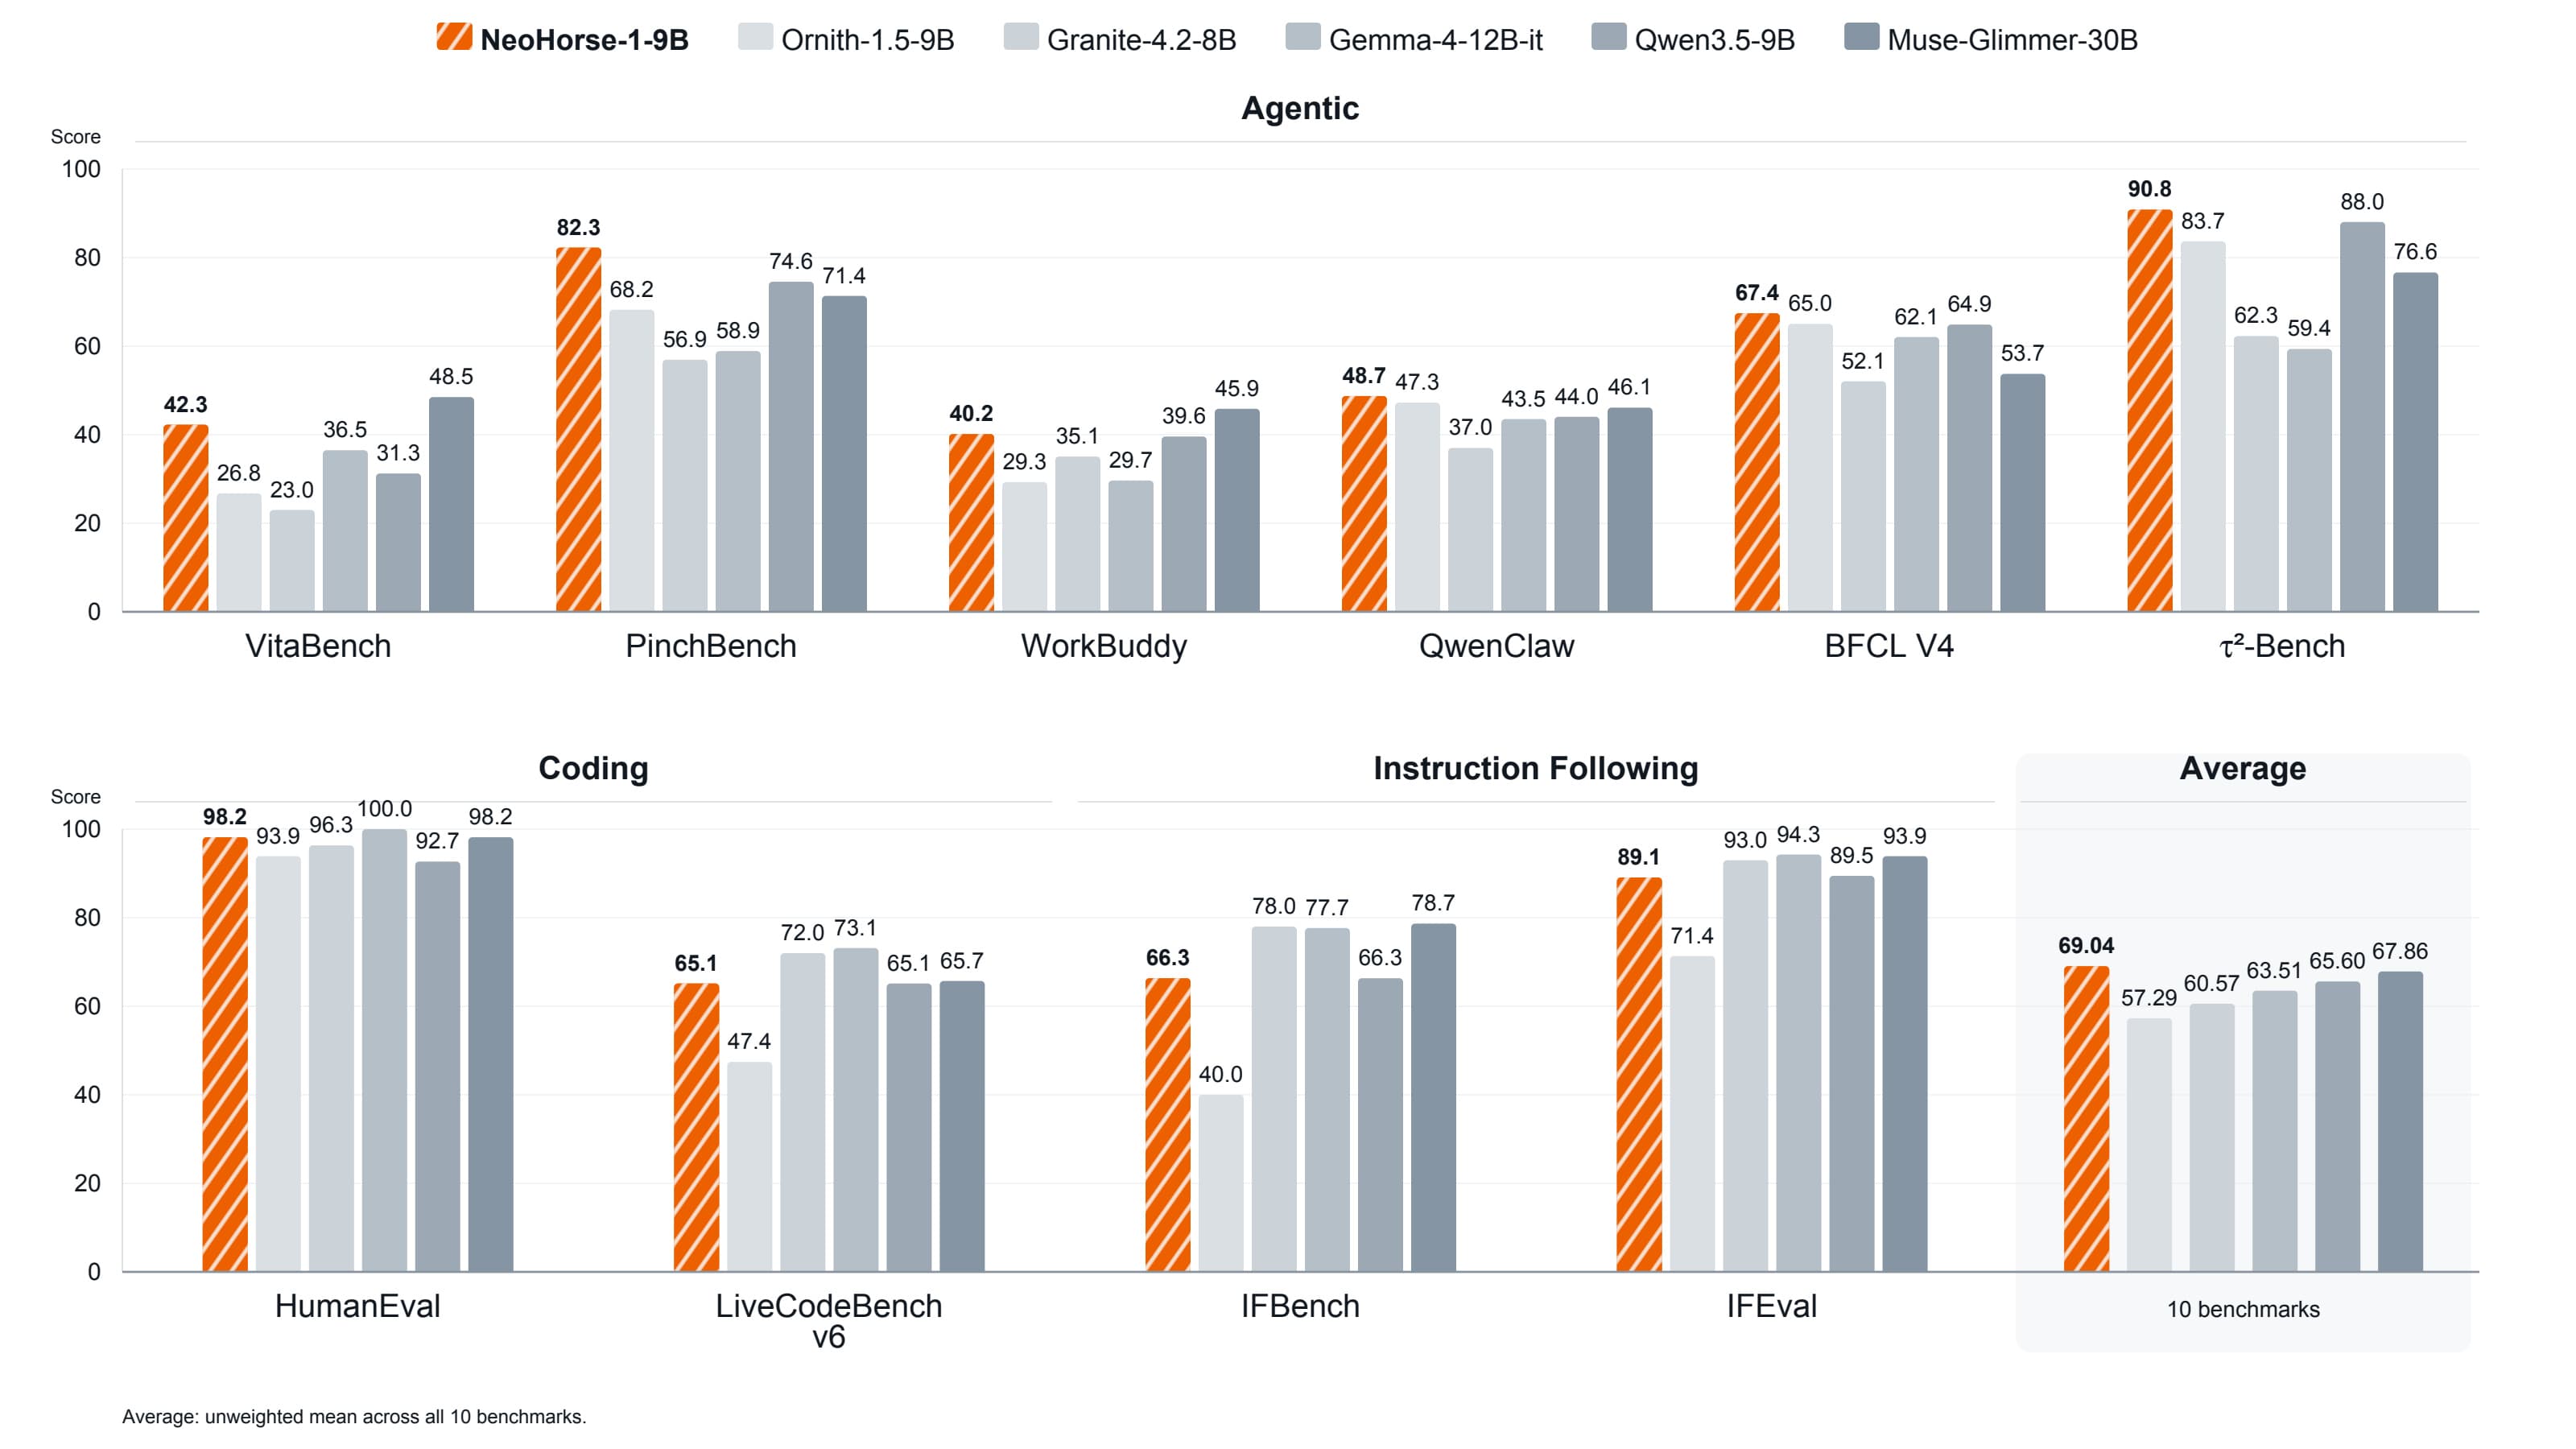
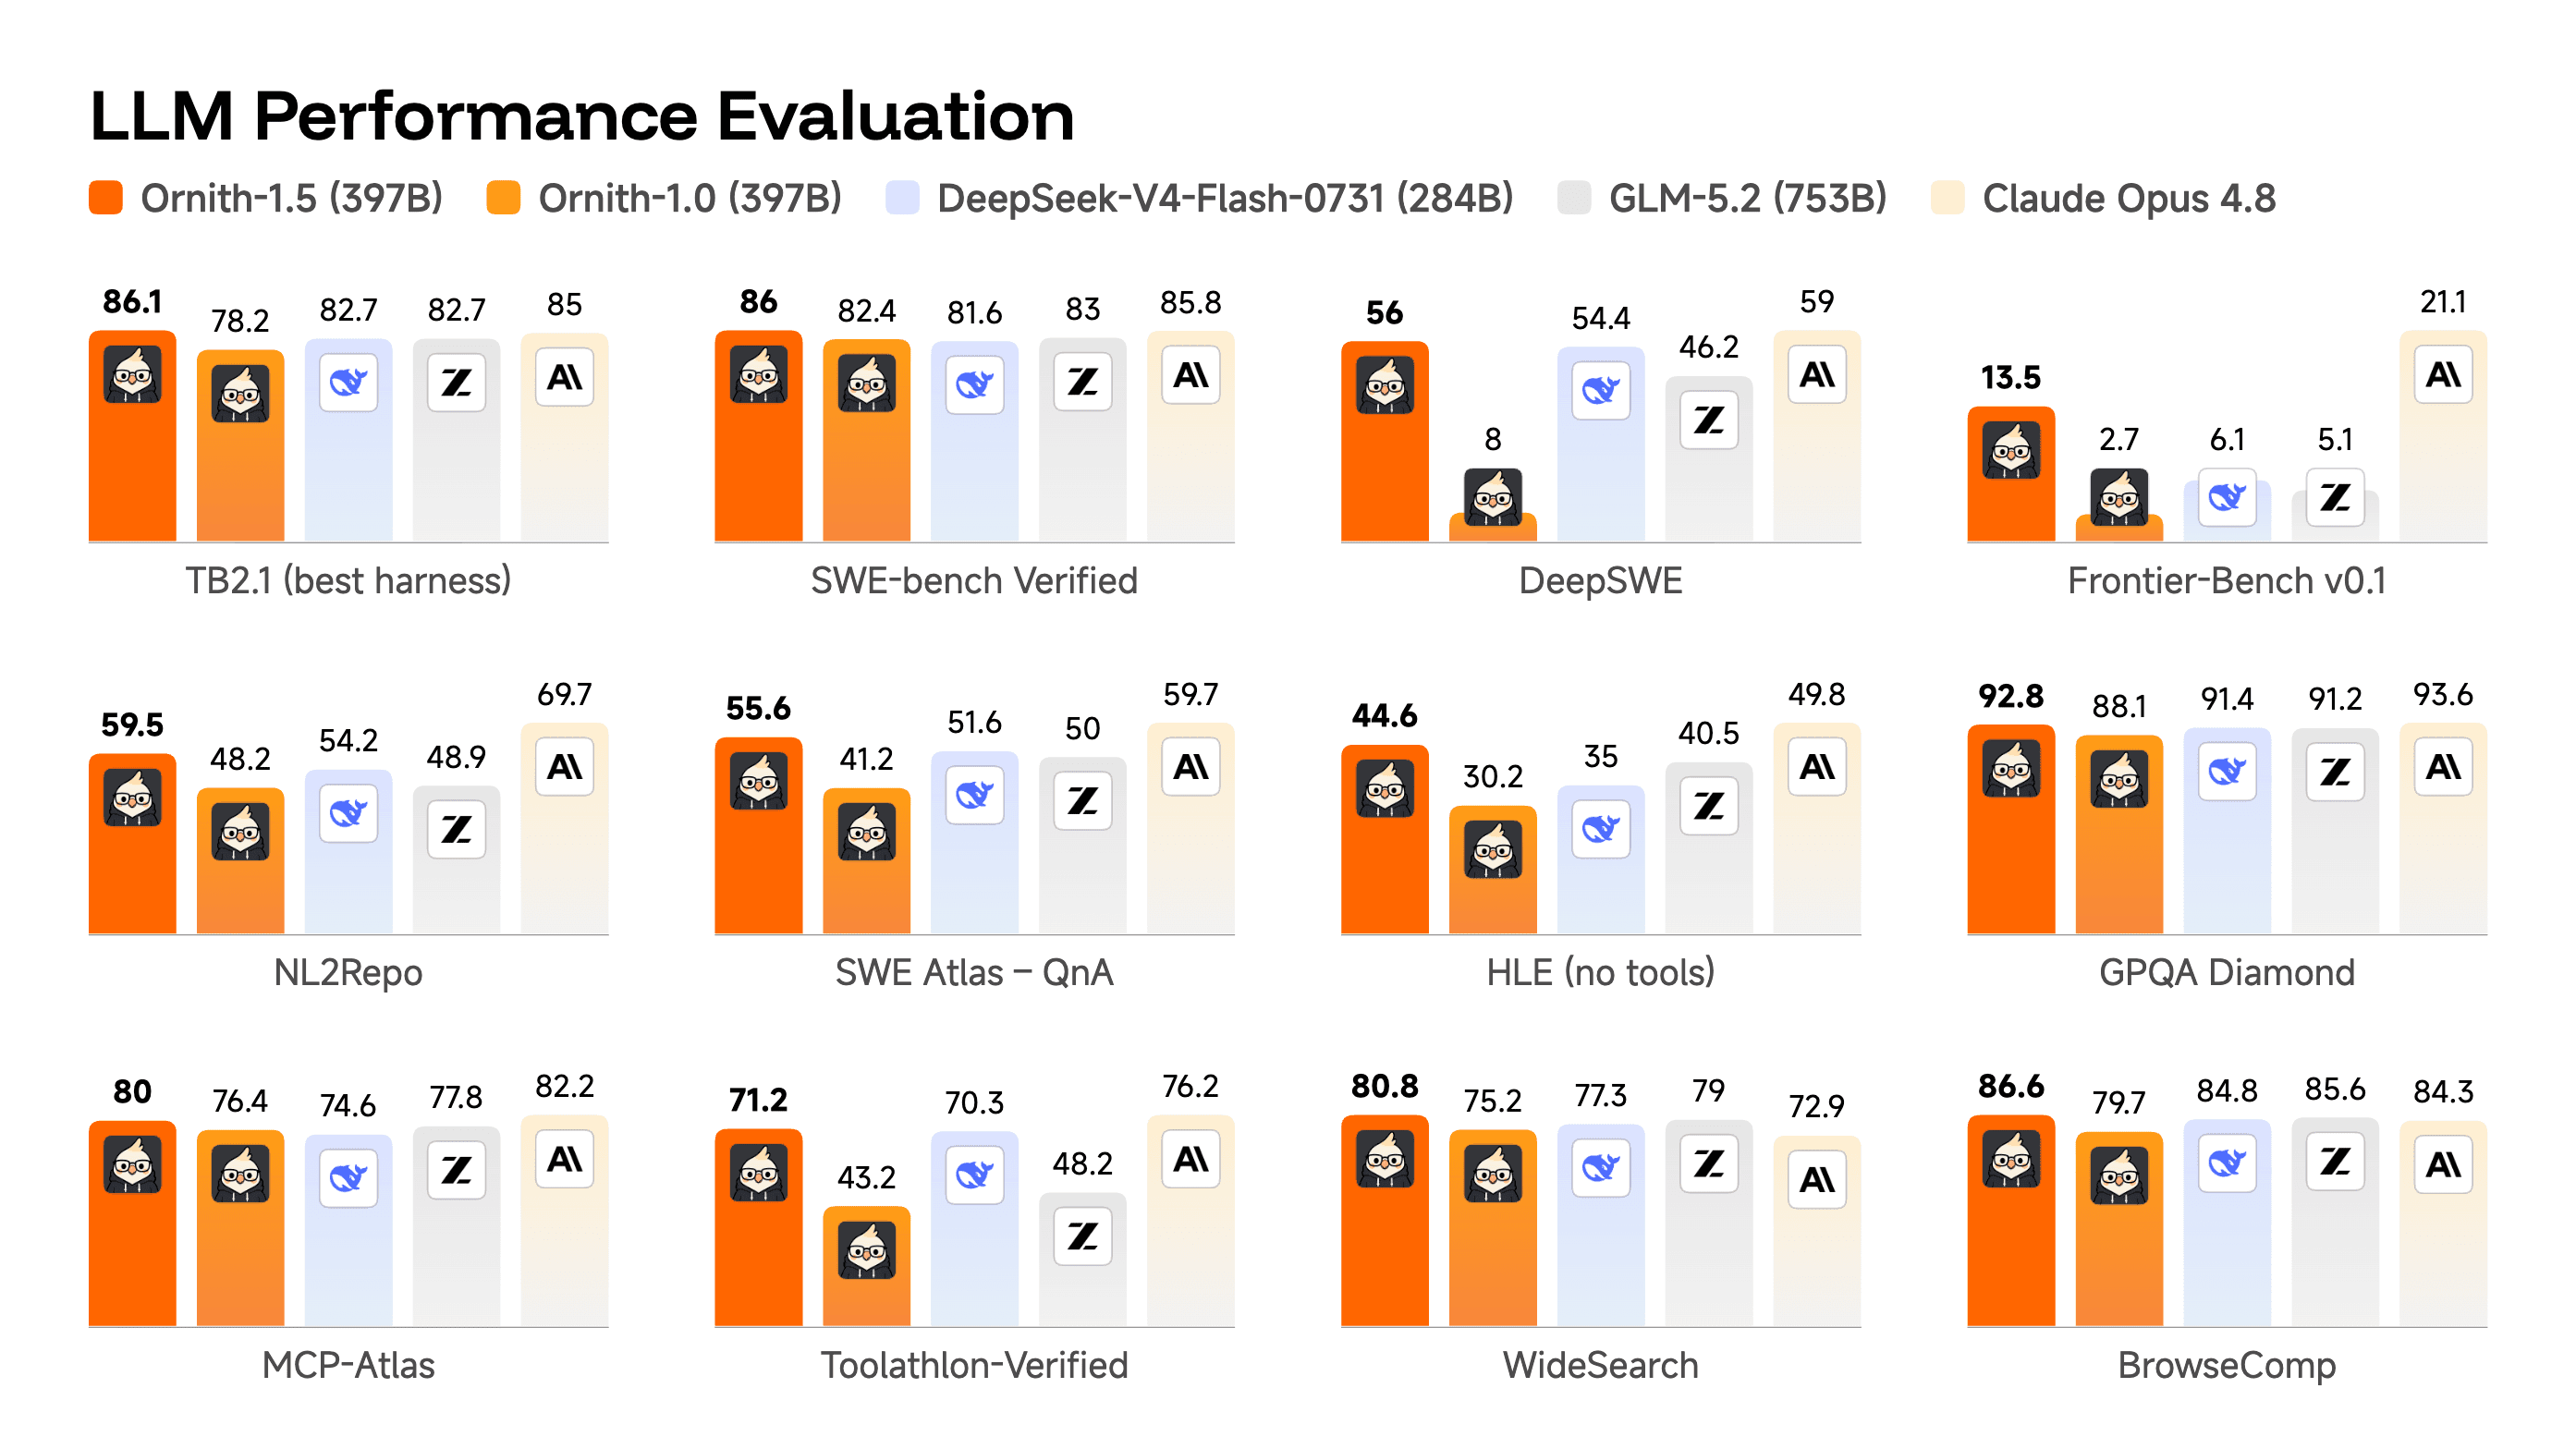
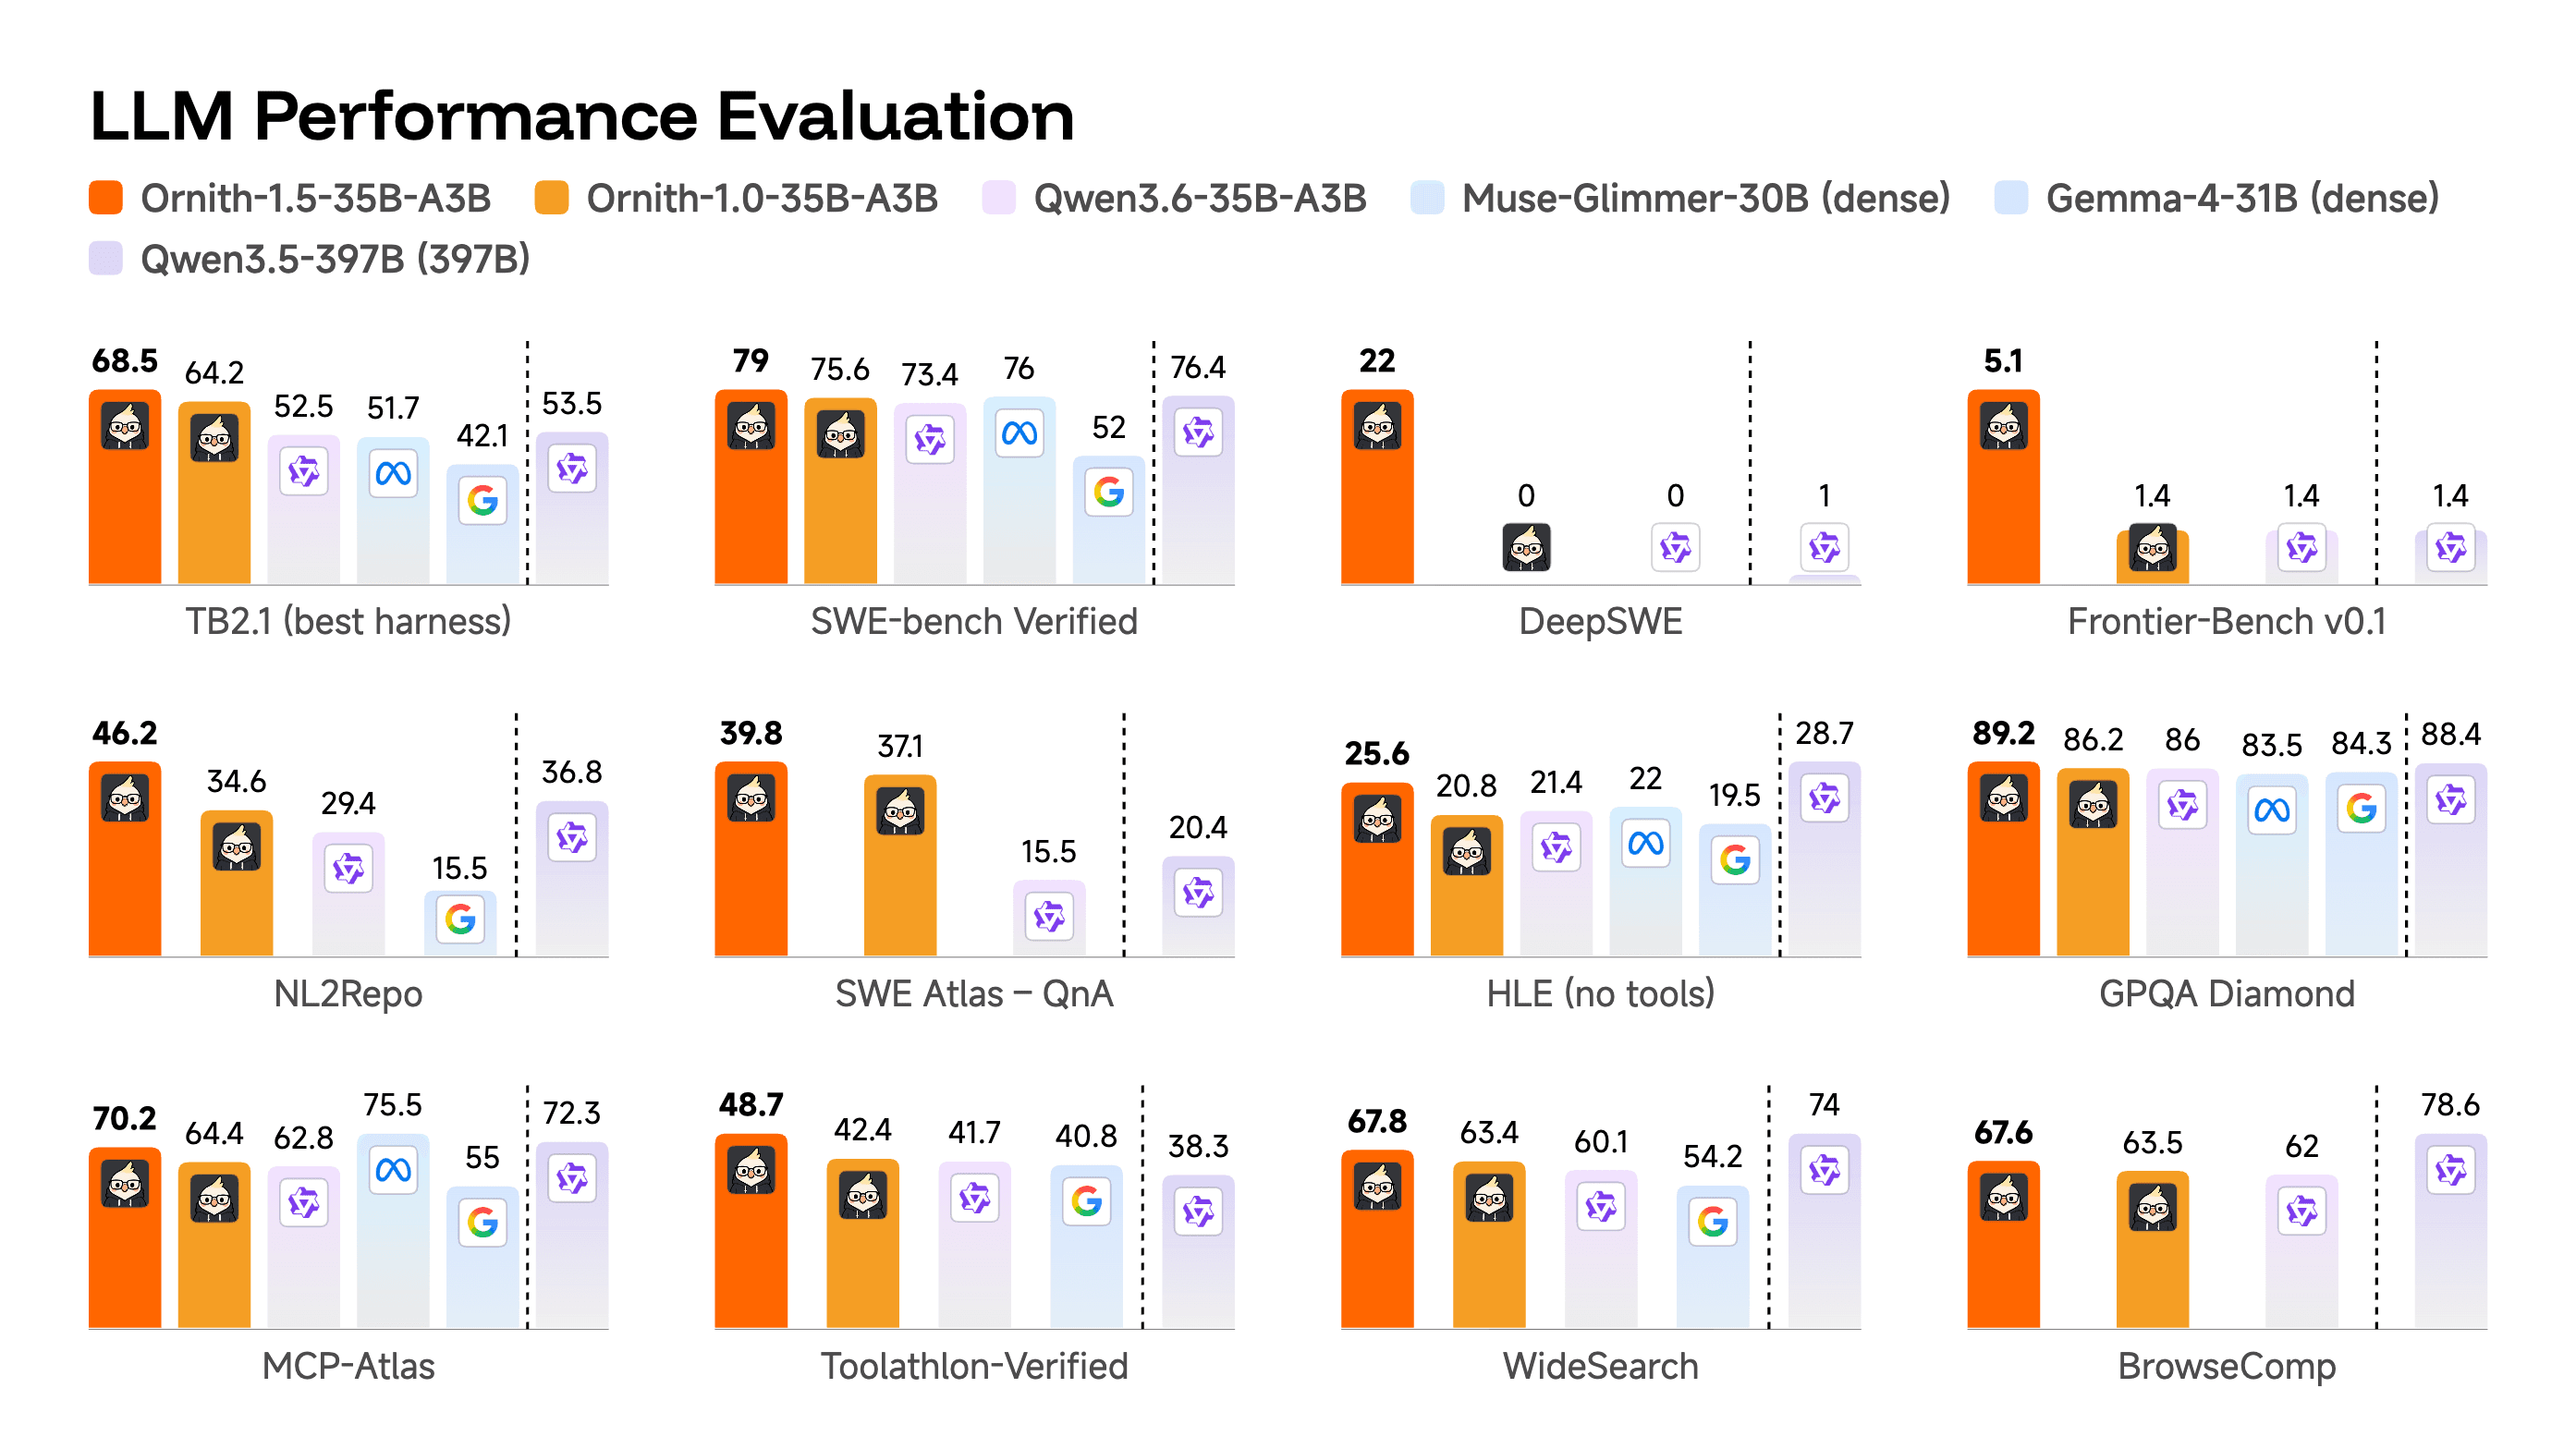
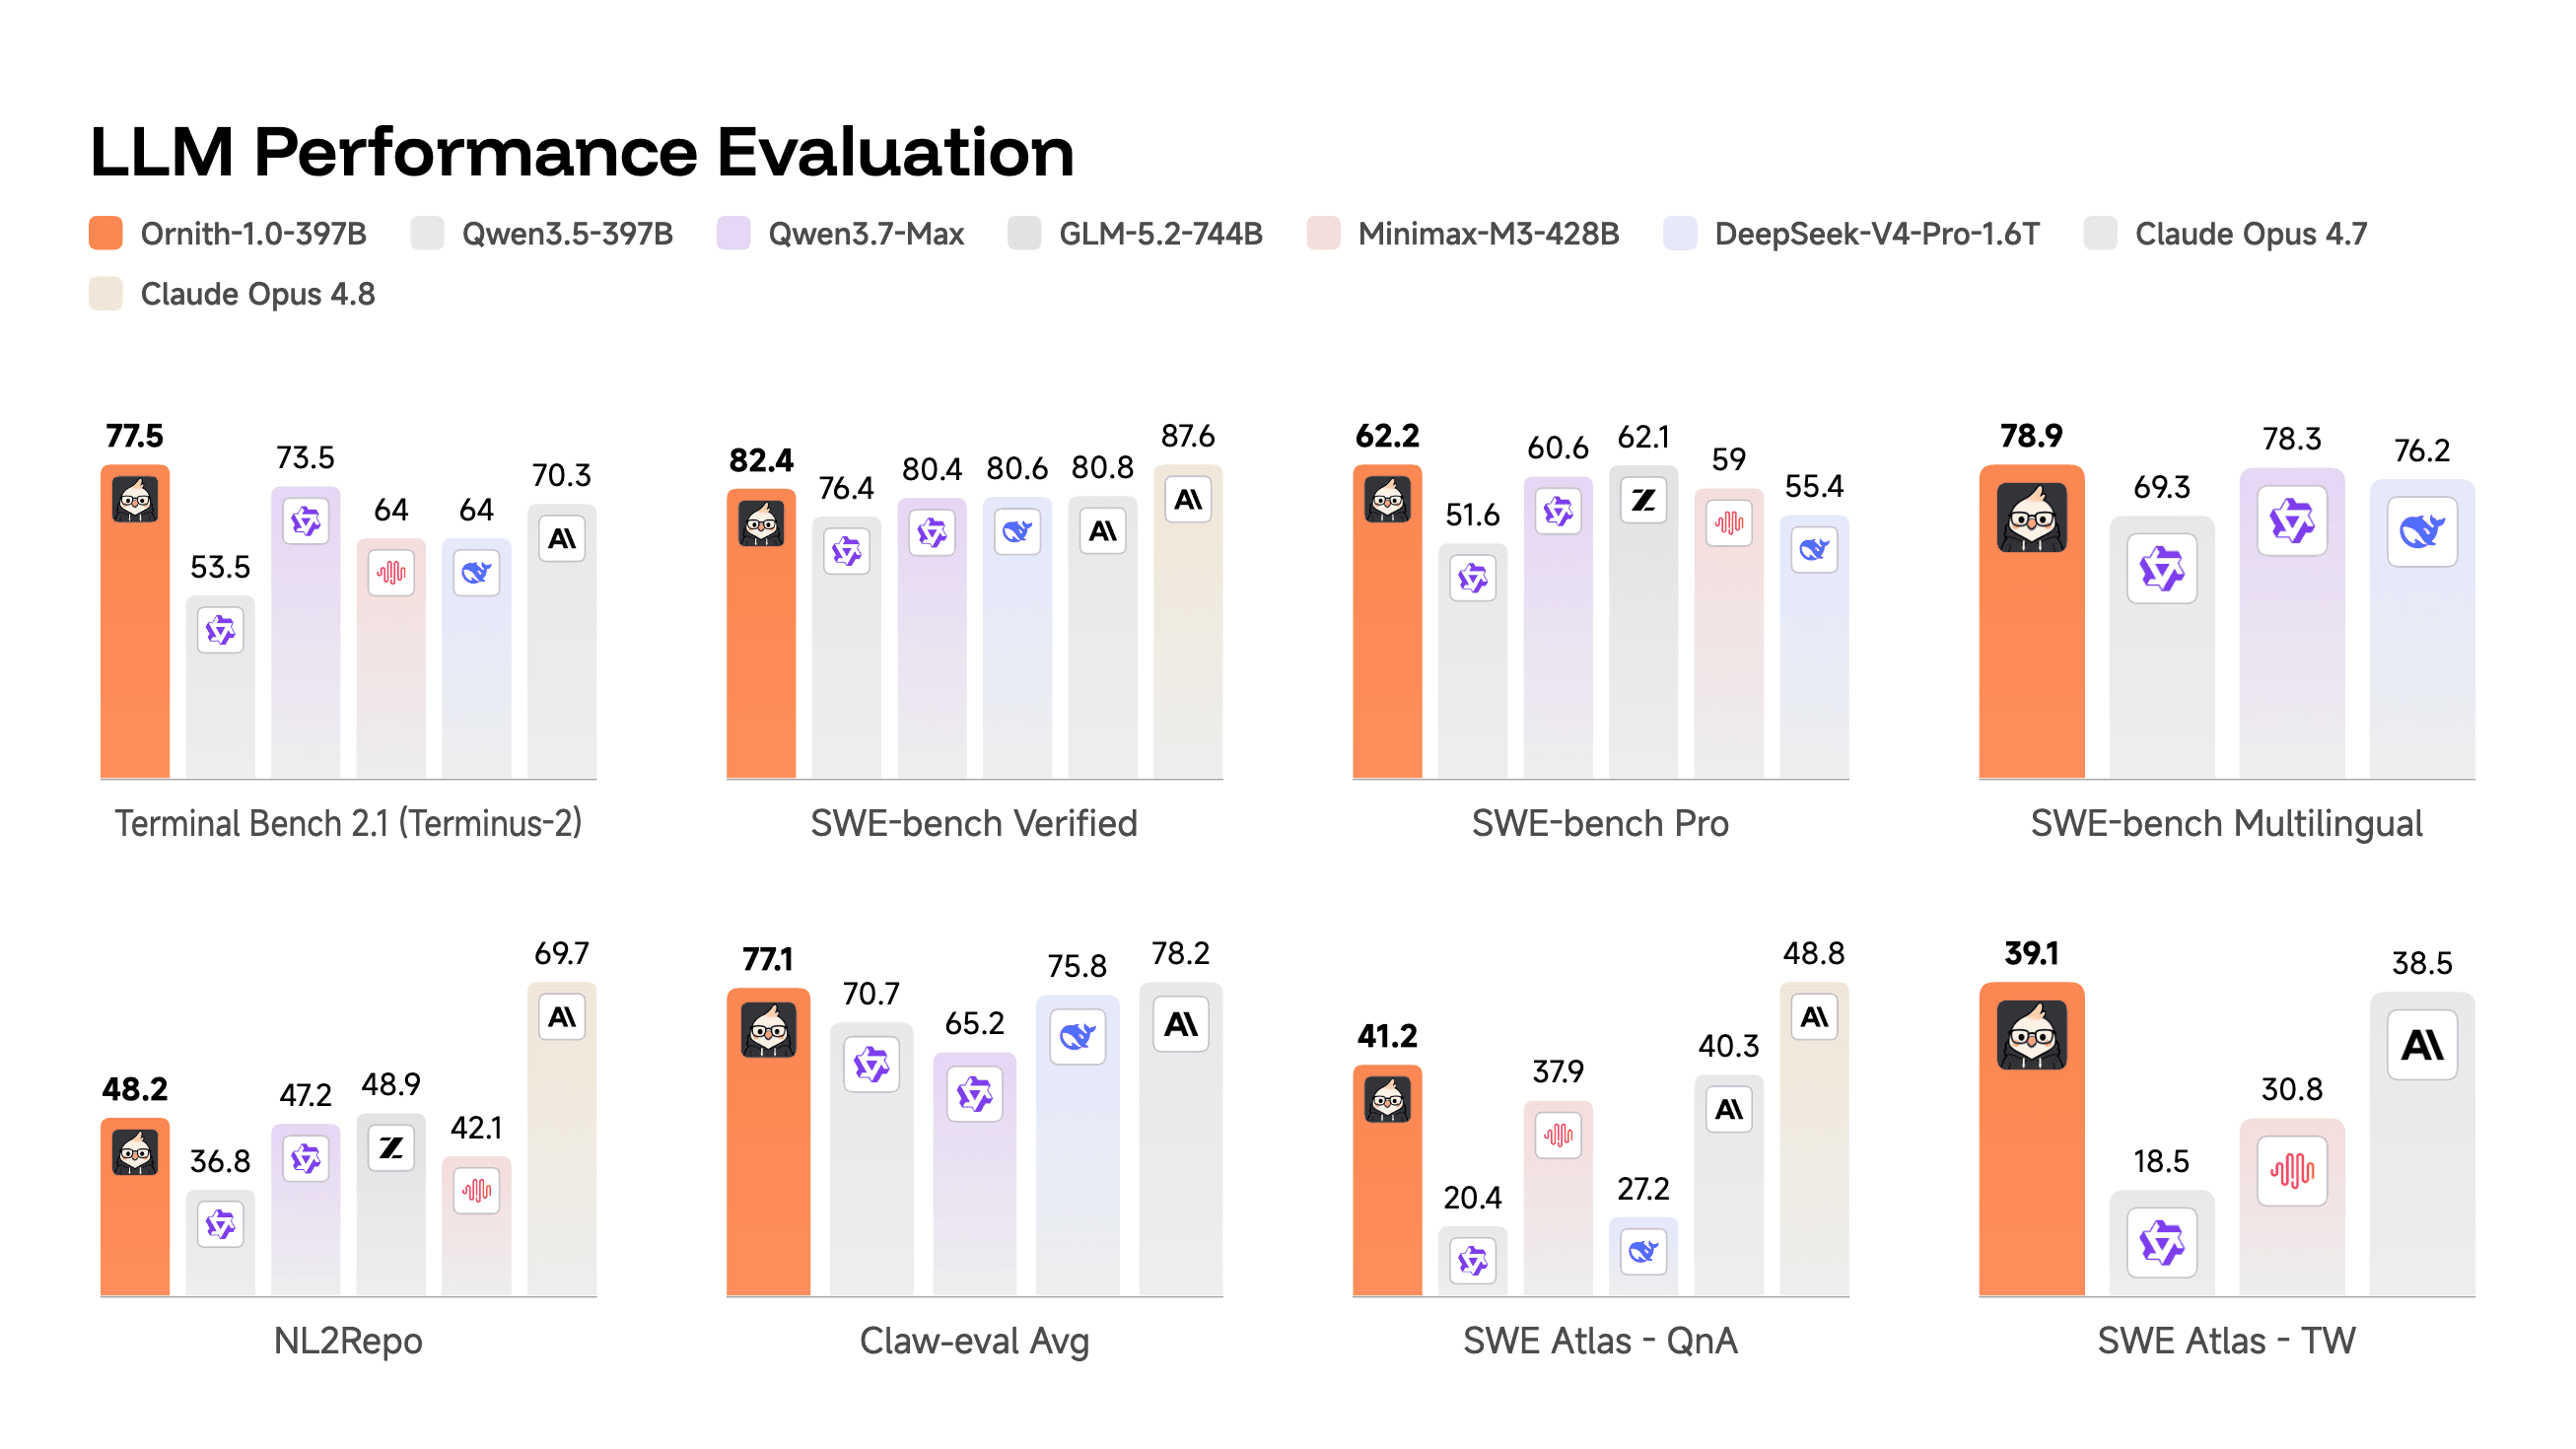
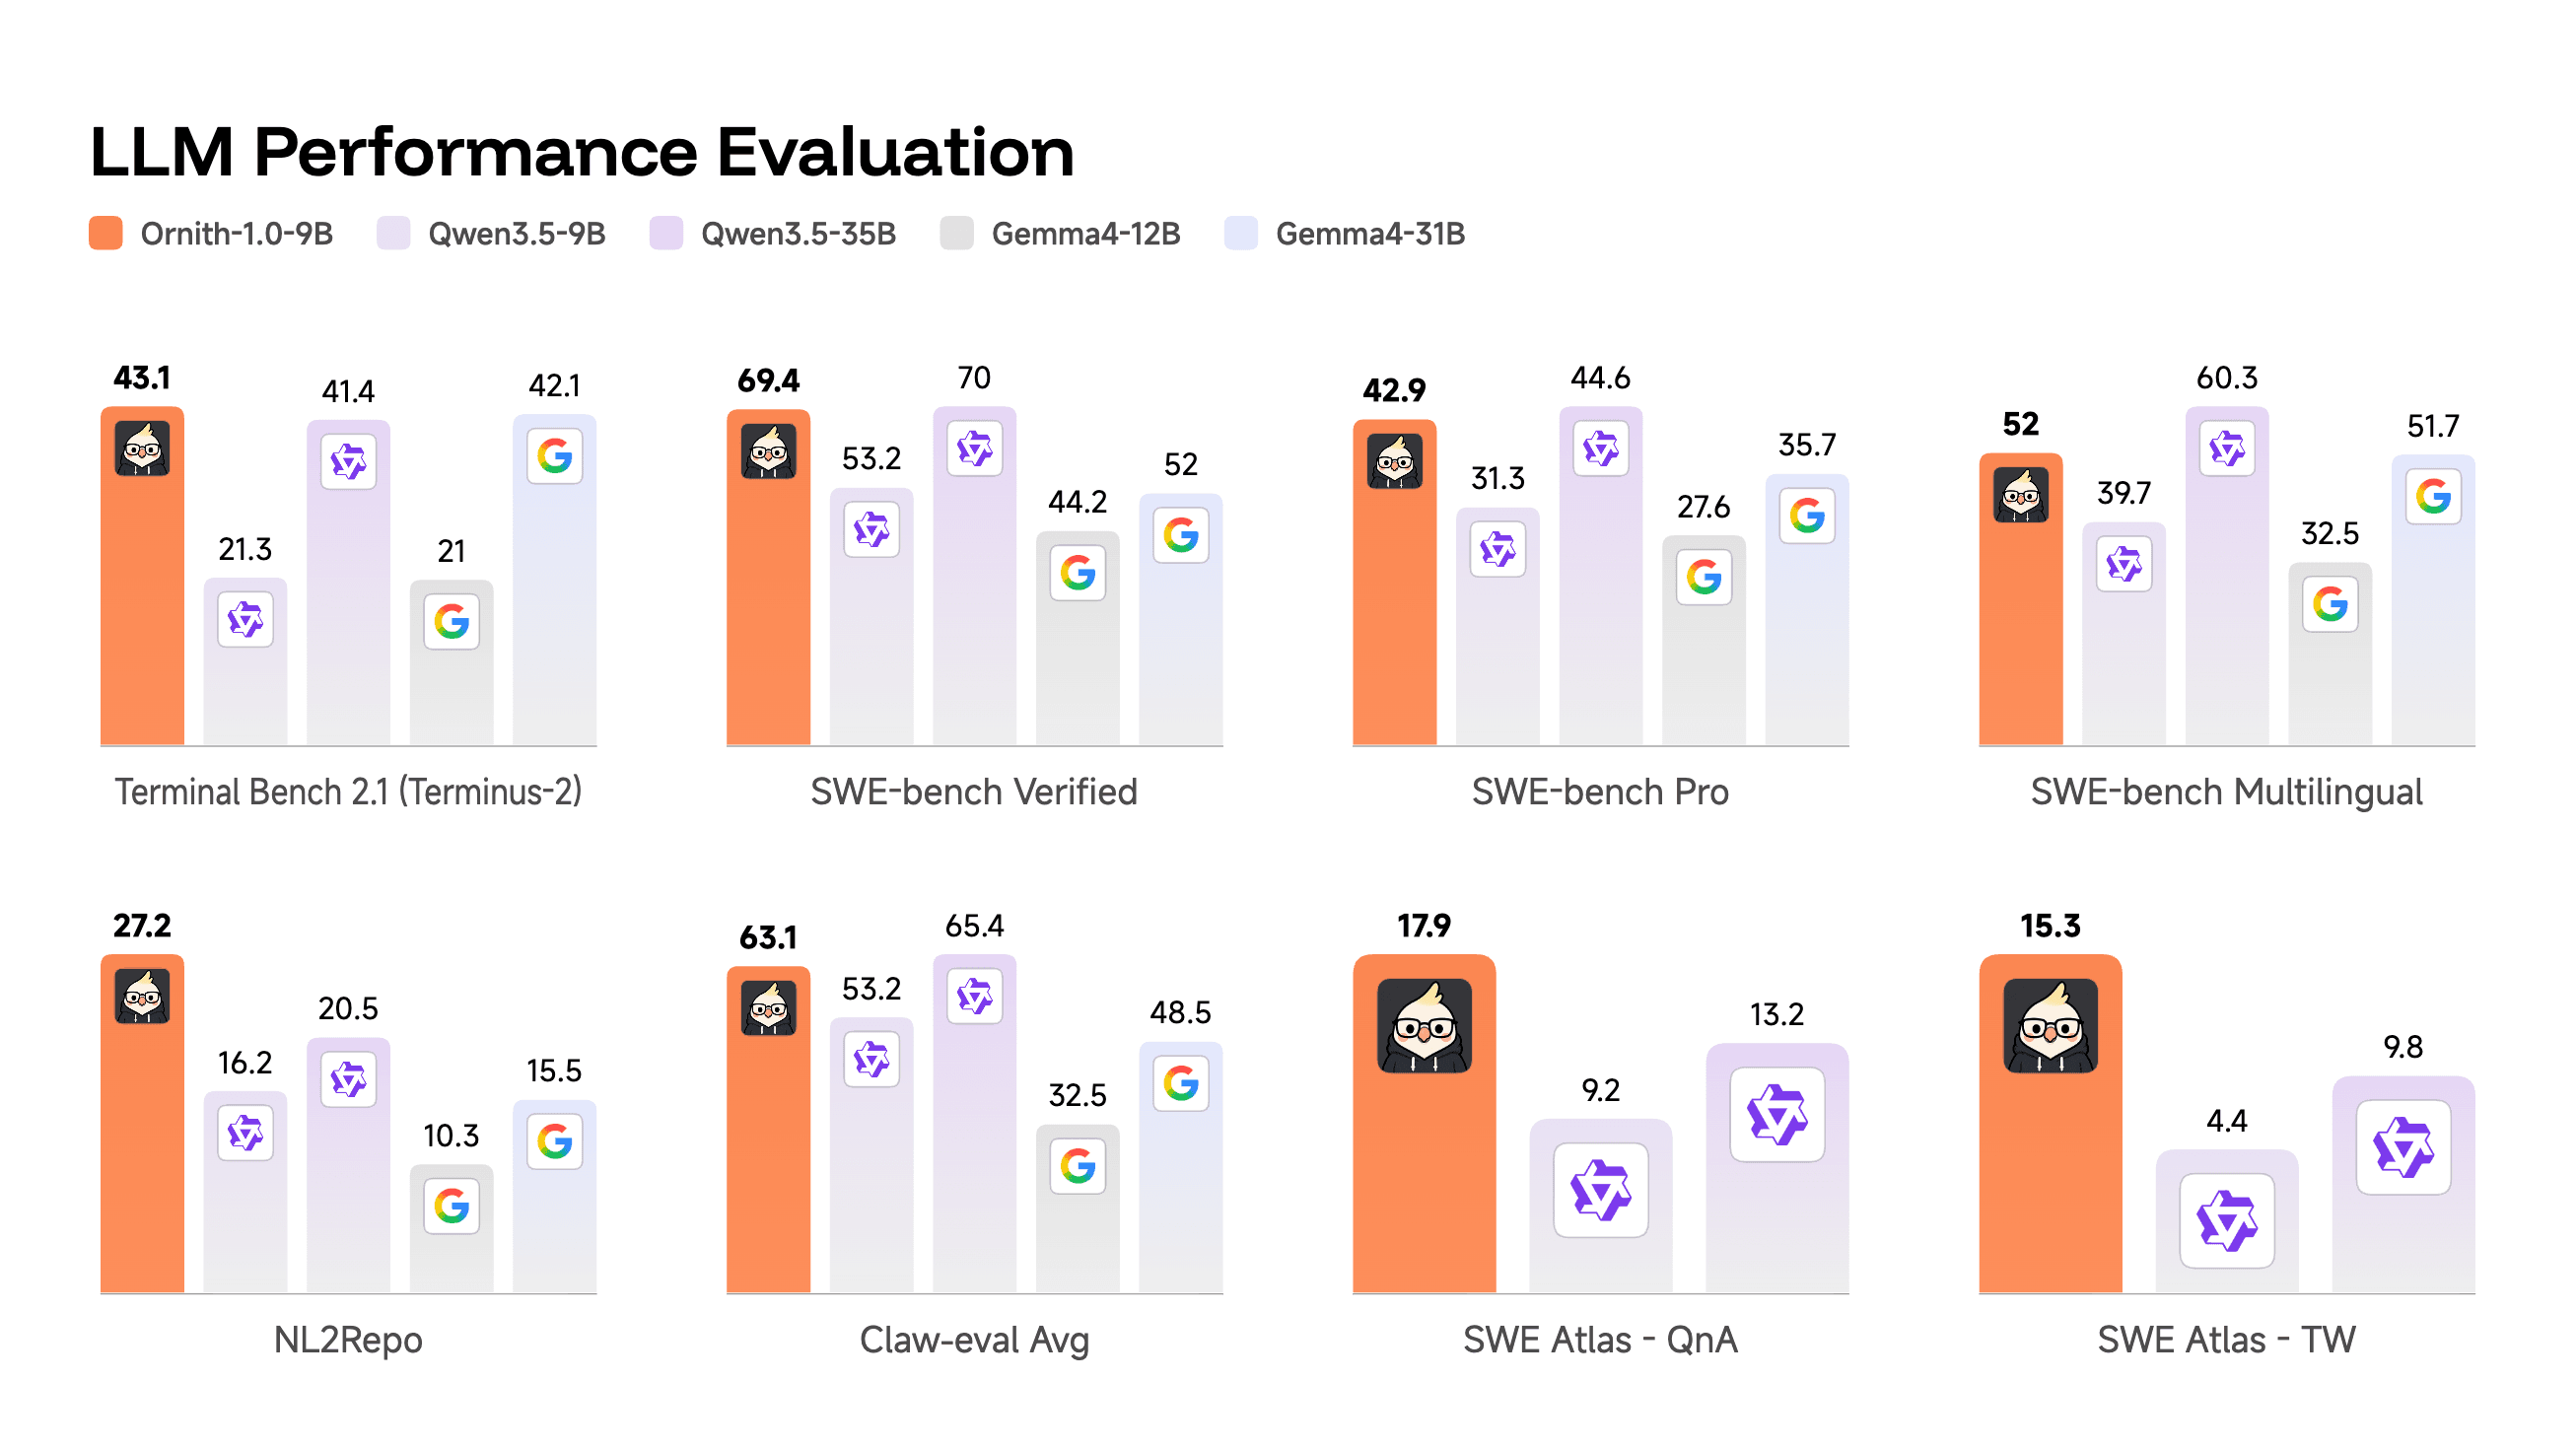
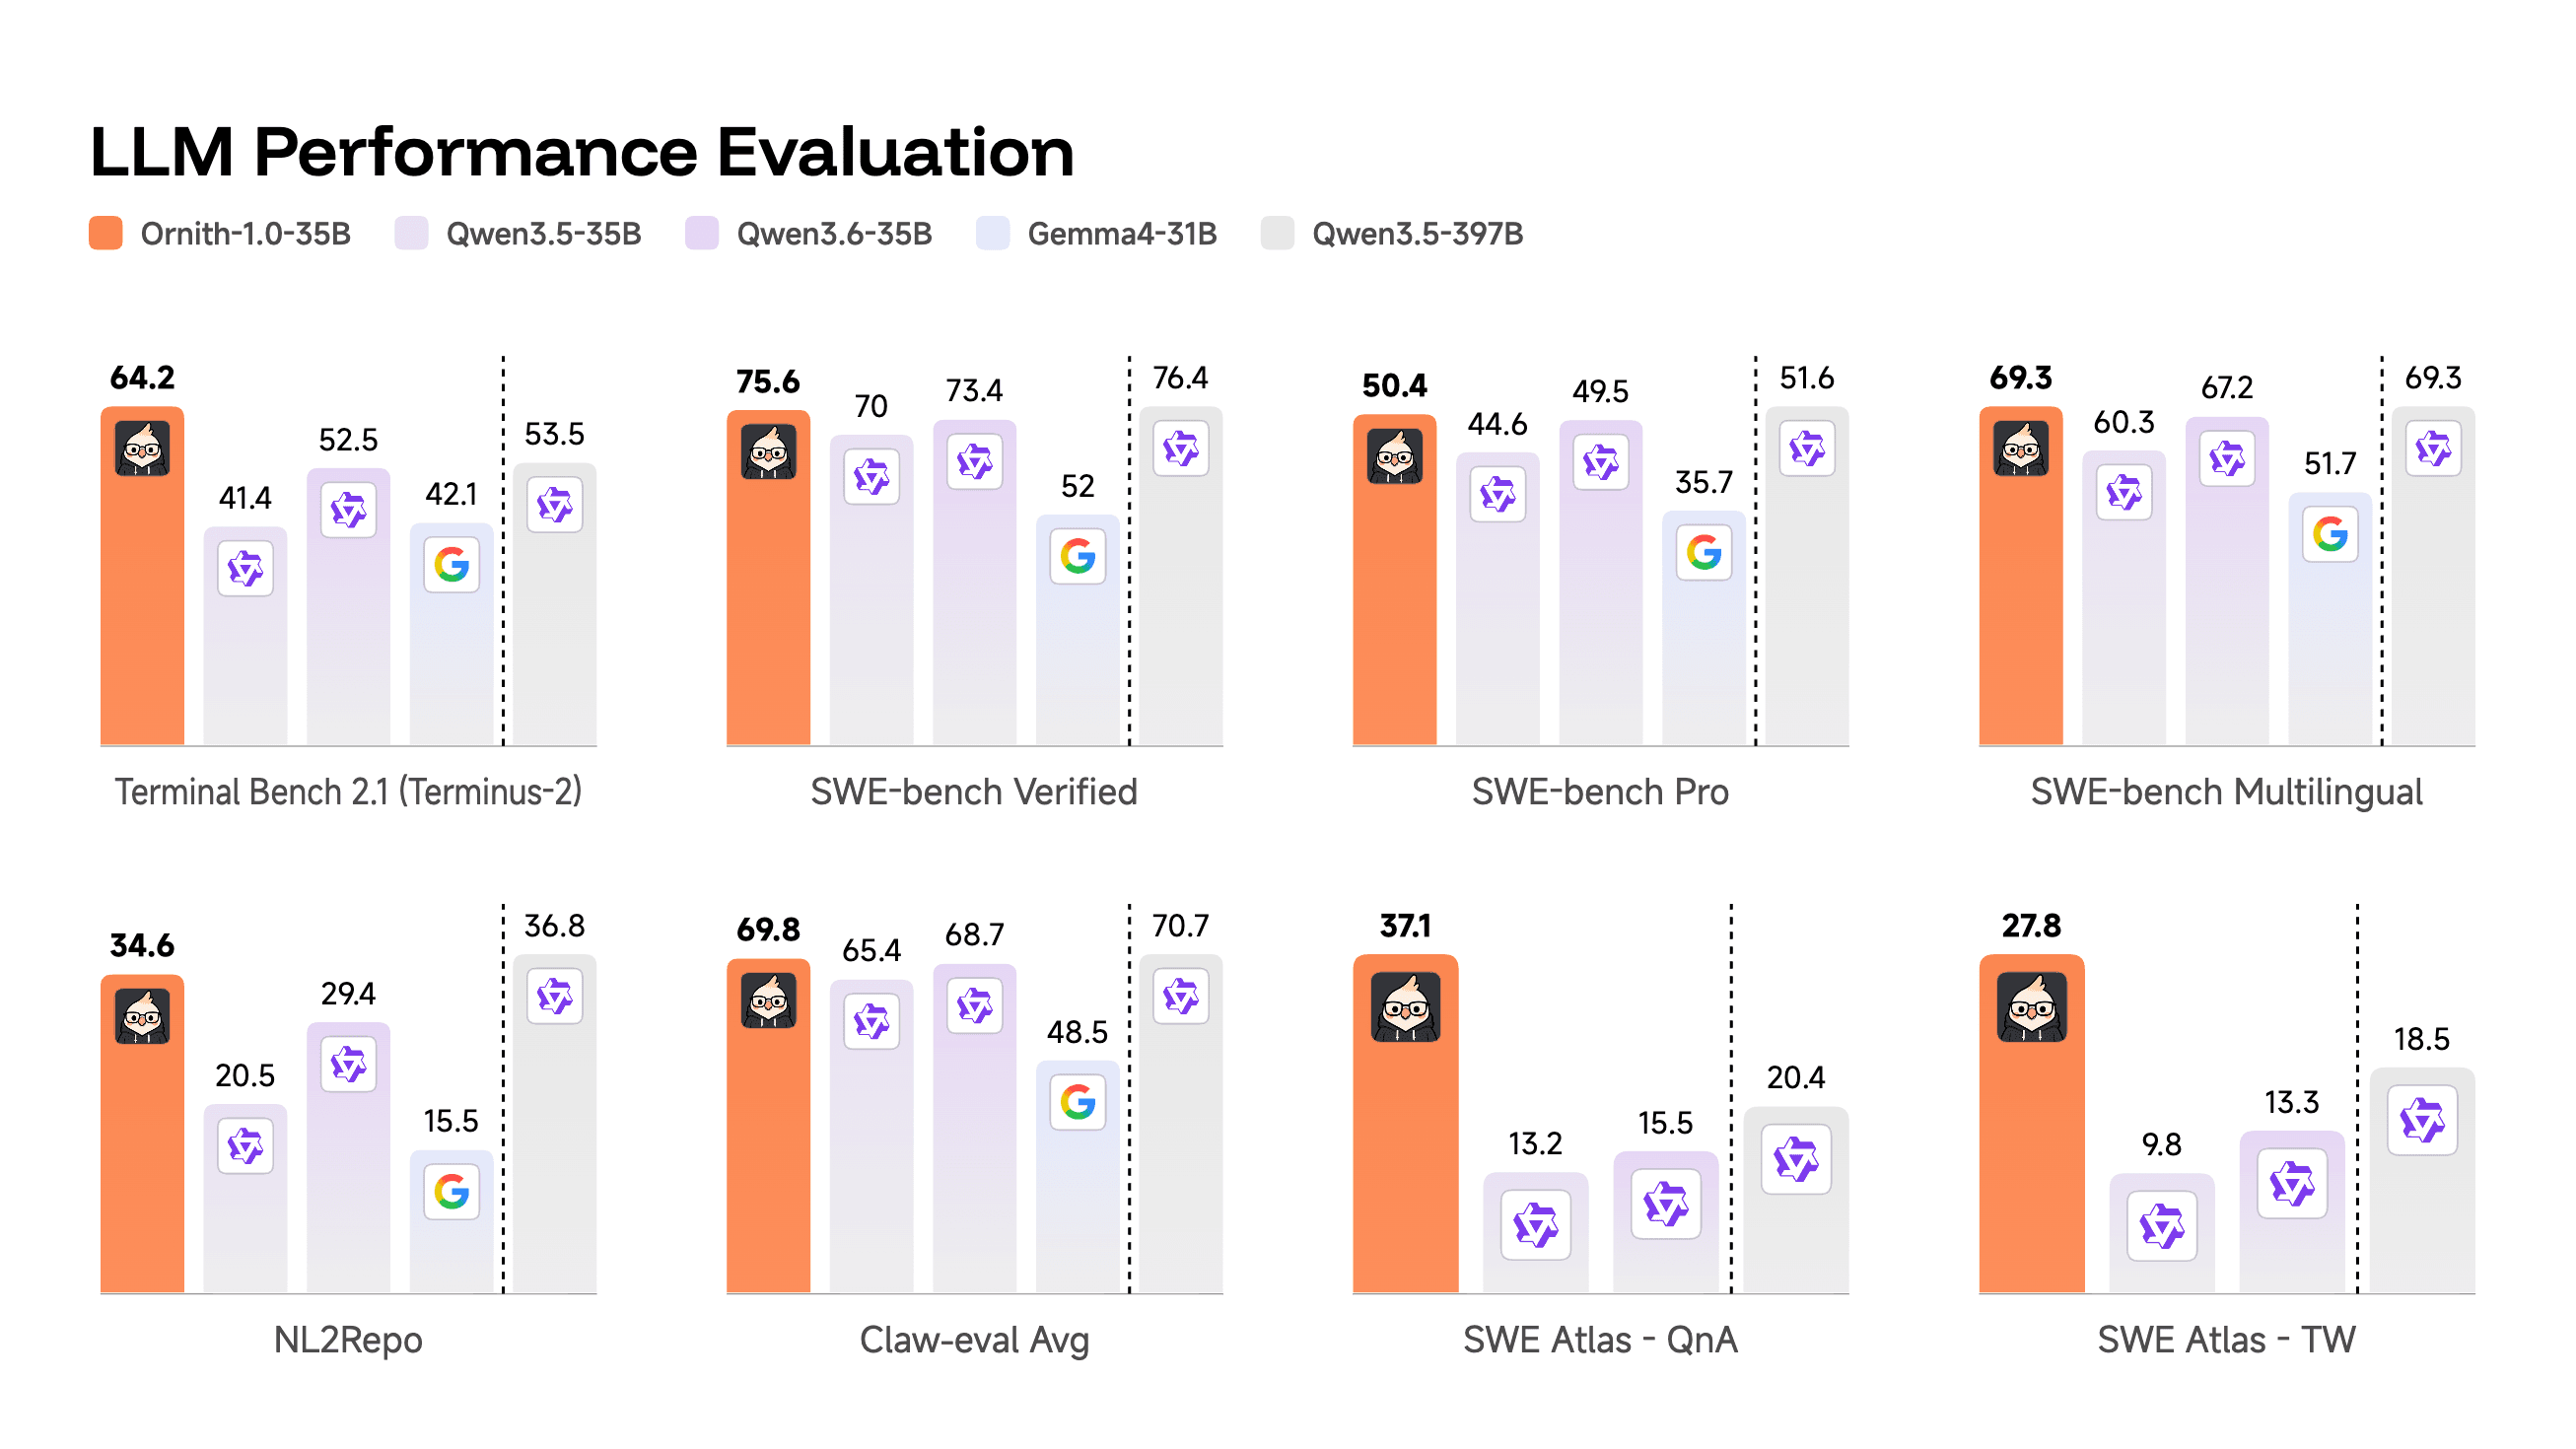
The Qwen3.5-based Ornith-1.5 pairs a mixture-of-experts design with vision support and an unusually permissive license.
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
The open-weight model pairs a million-token context window with a focus on long-horizon code tasks.
The new open-weight model pairs a million-token context window with Meta's bet on long-horizon coding agents.
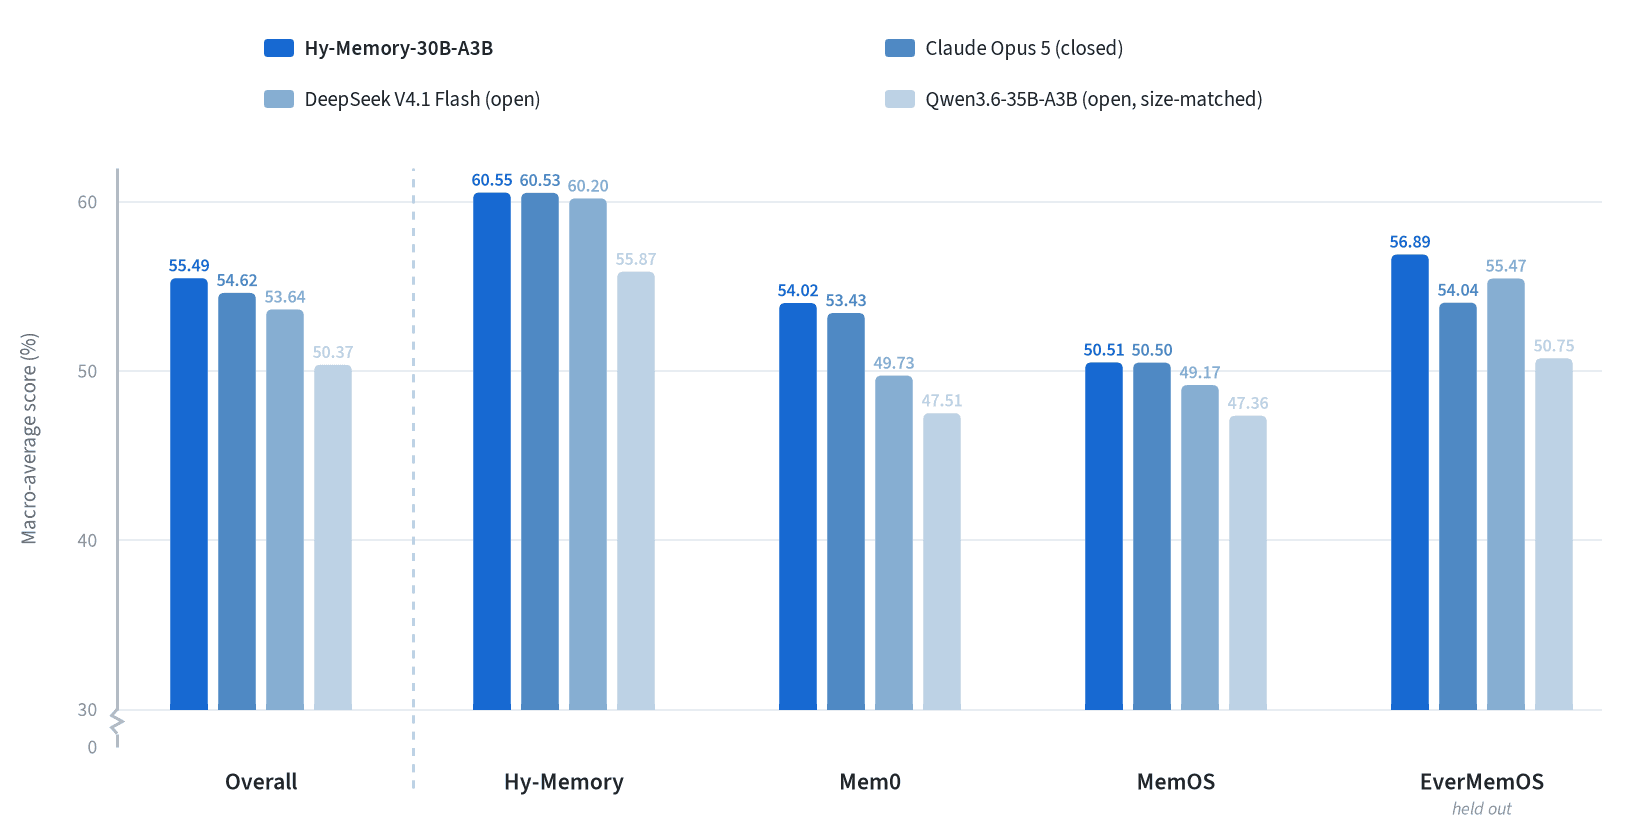
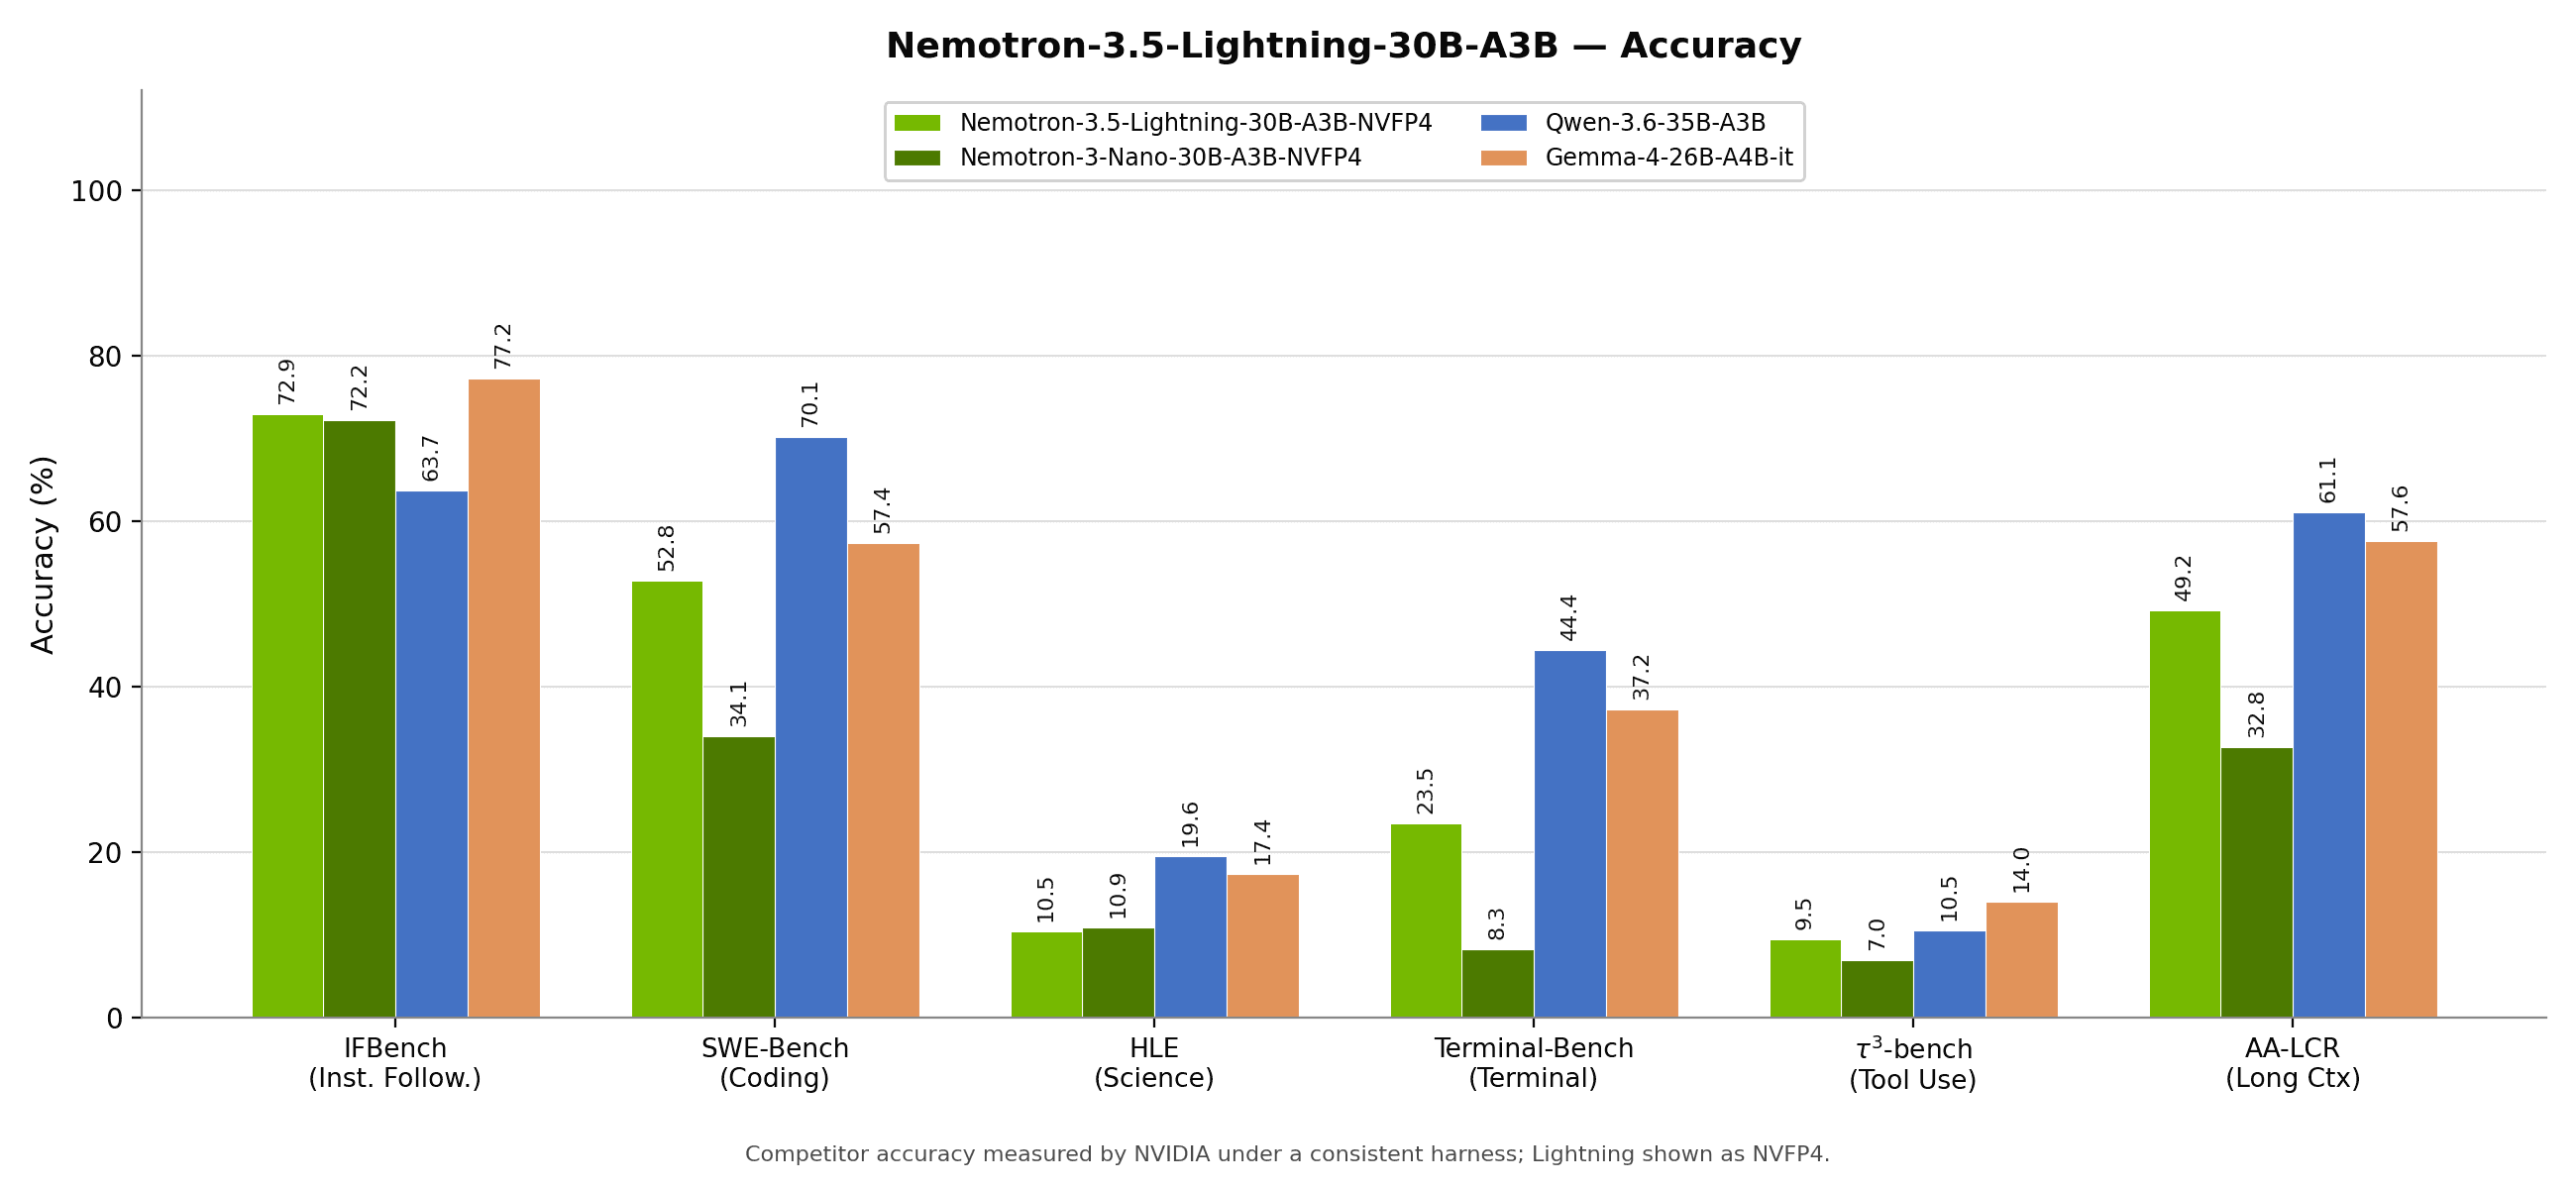
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
The French lab releases a compact 209M-parameter foundation model aimed squarely at time-series prediction.
A new hybrid mixture-of-experts text model arrives on Hugging Face with permissive licensing and a focus on fast inference.
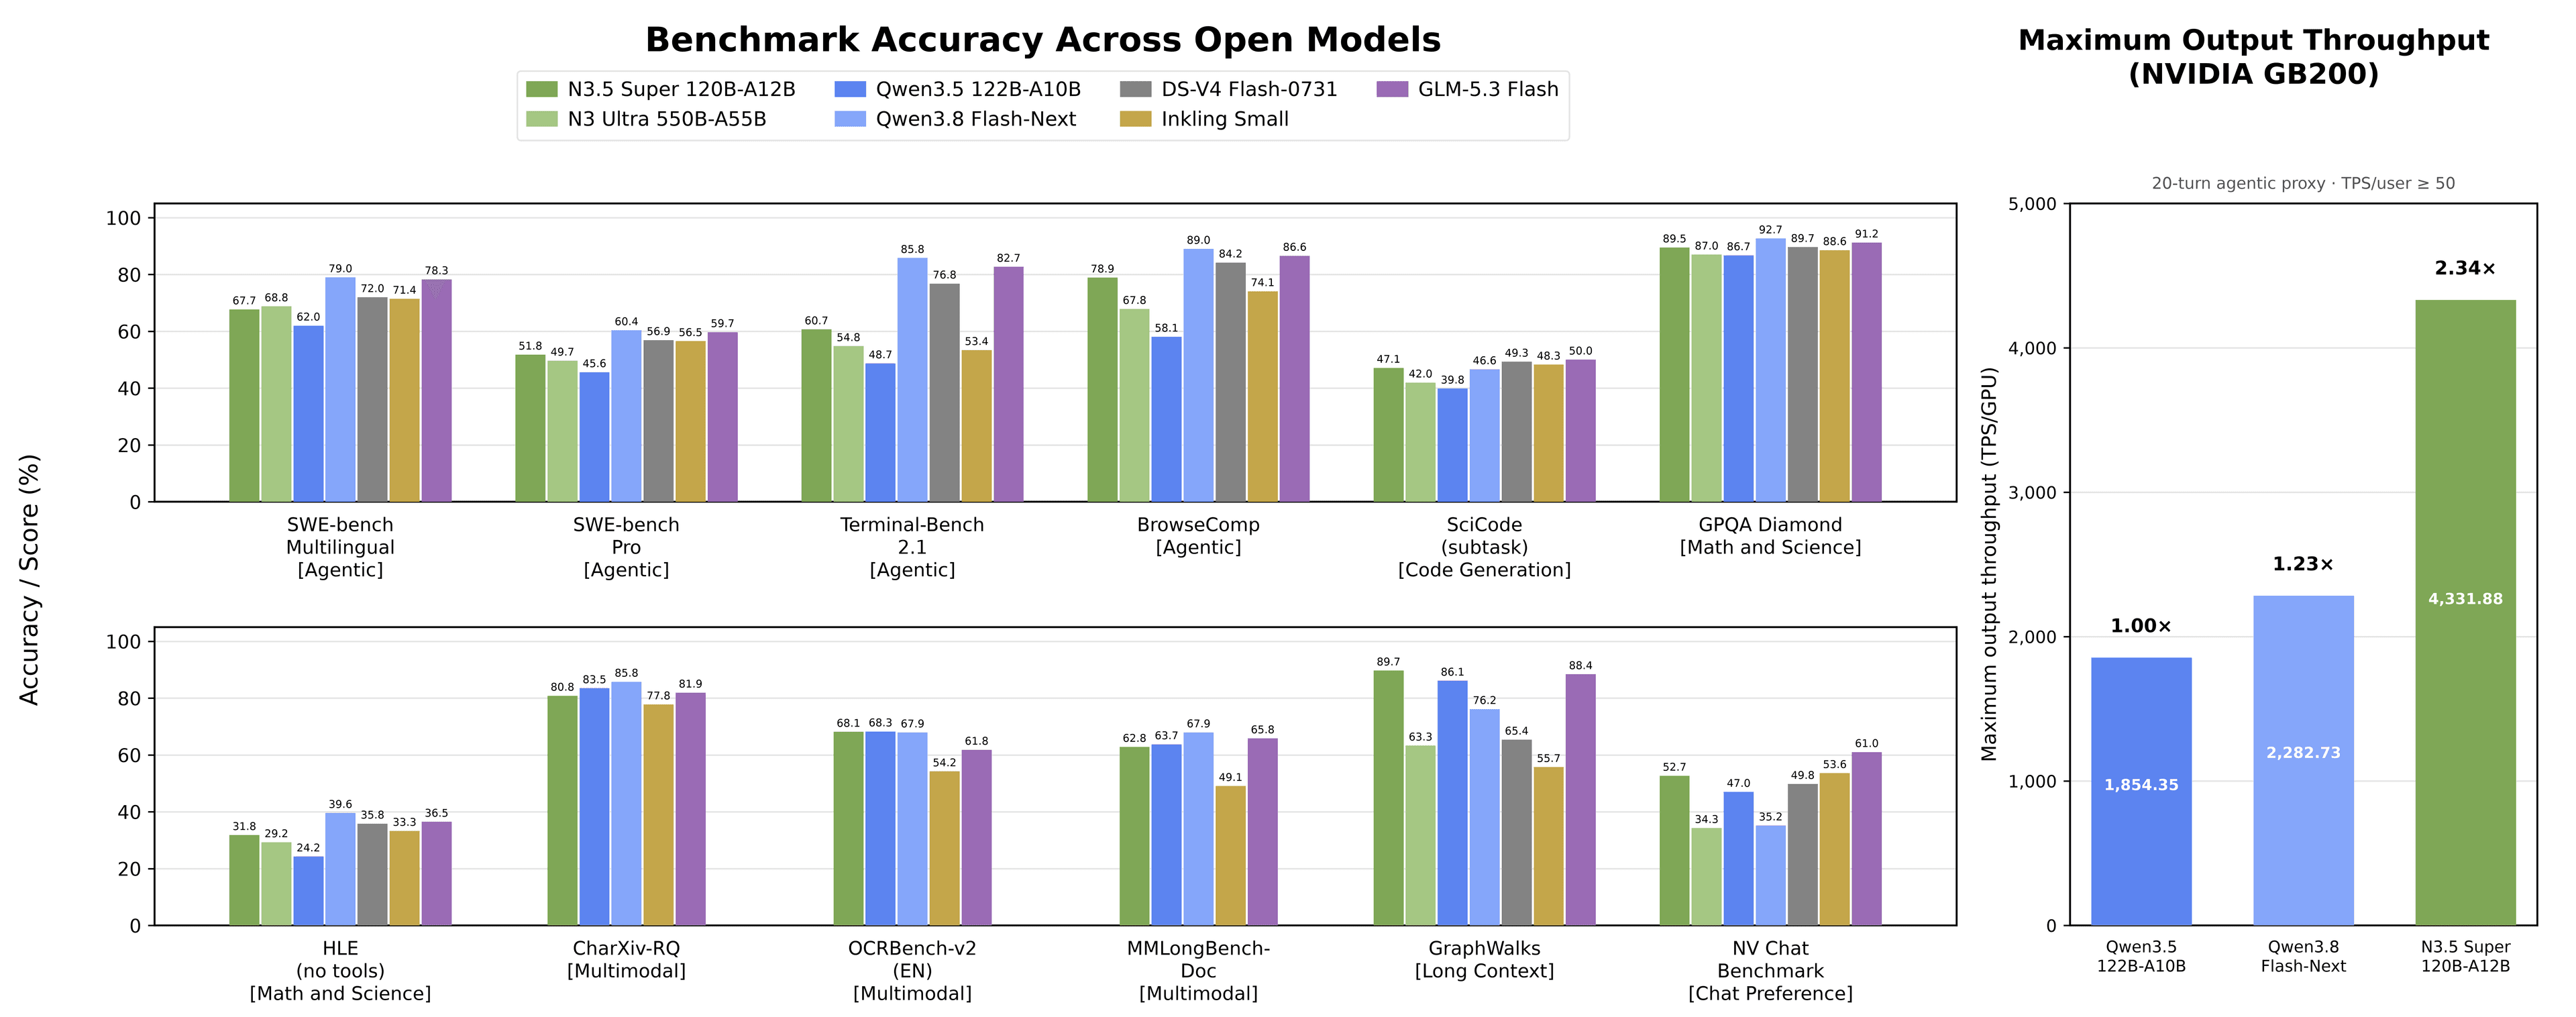
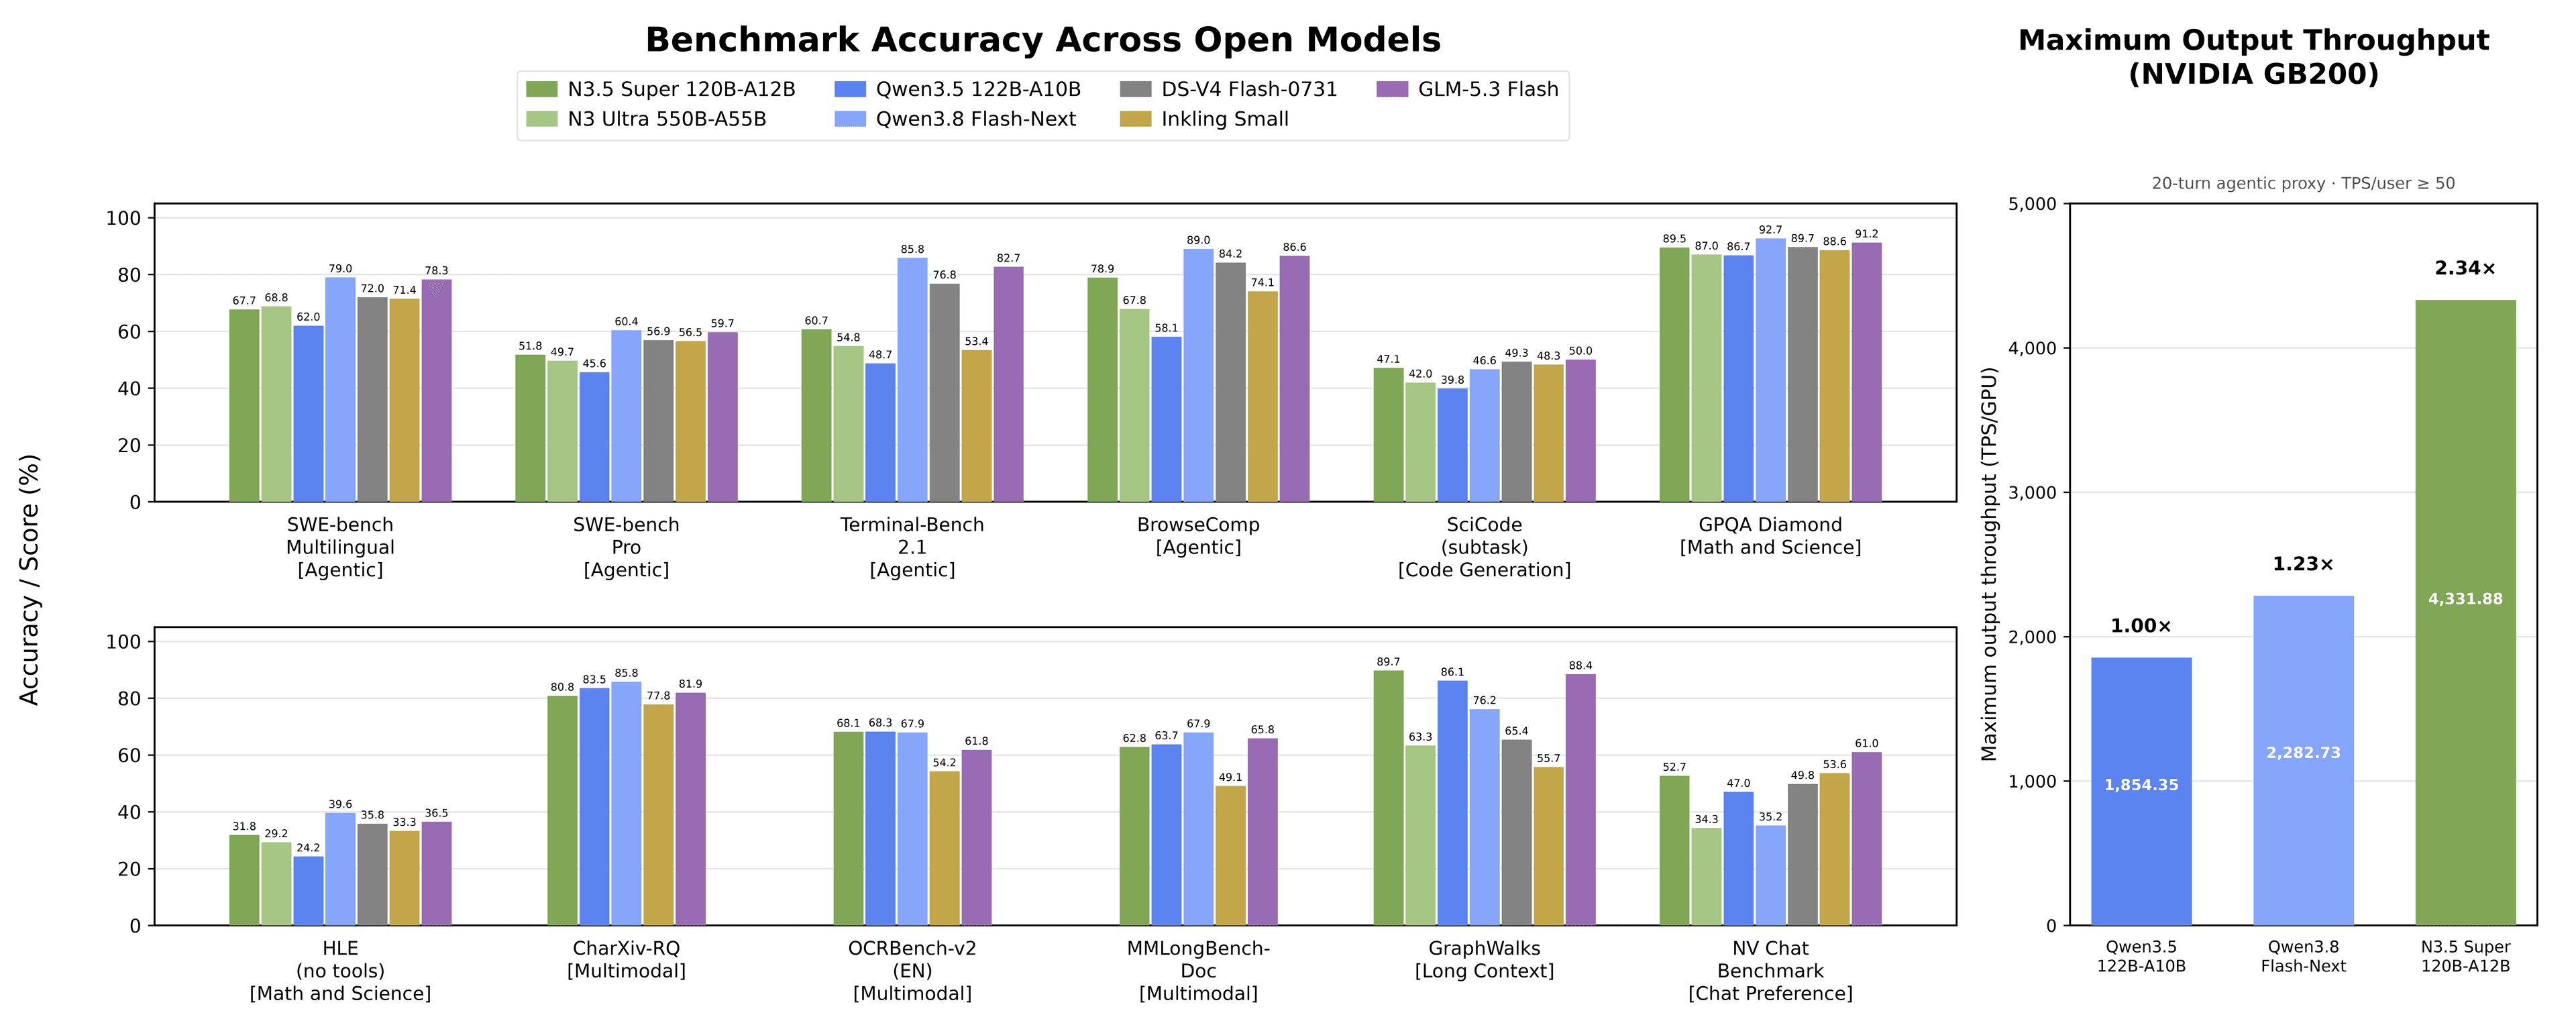
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
The new mixture-of-experts model keeps total capacity high while activating only about 2B parameters per token for edge agents.
The frontier AI startup's first open-weight model activates just 23B parameters per token while targeting reasoning, code, and tool use.
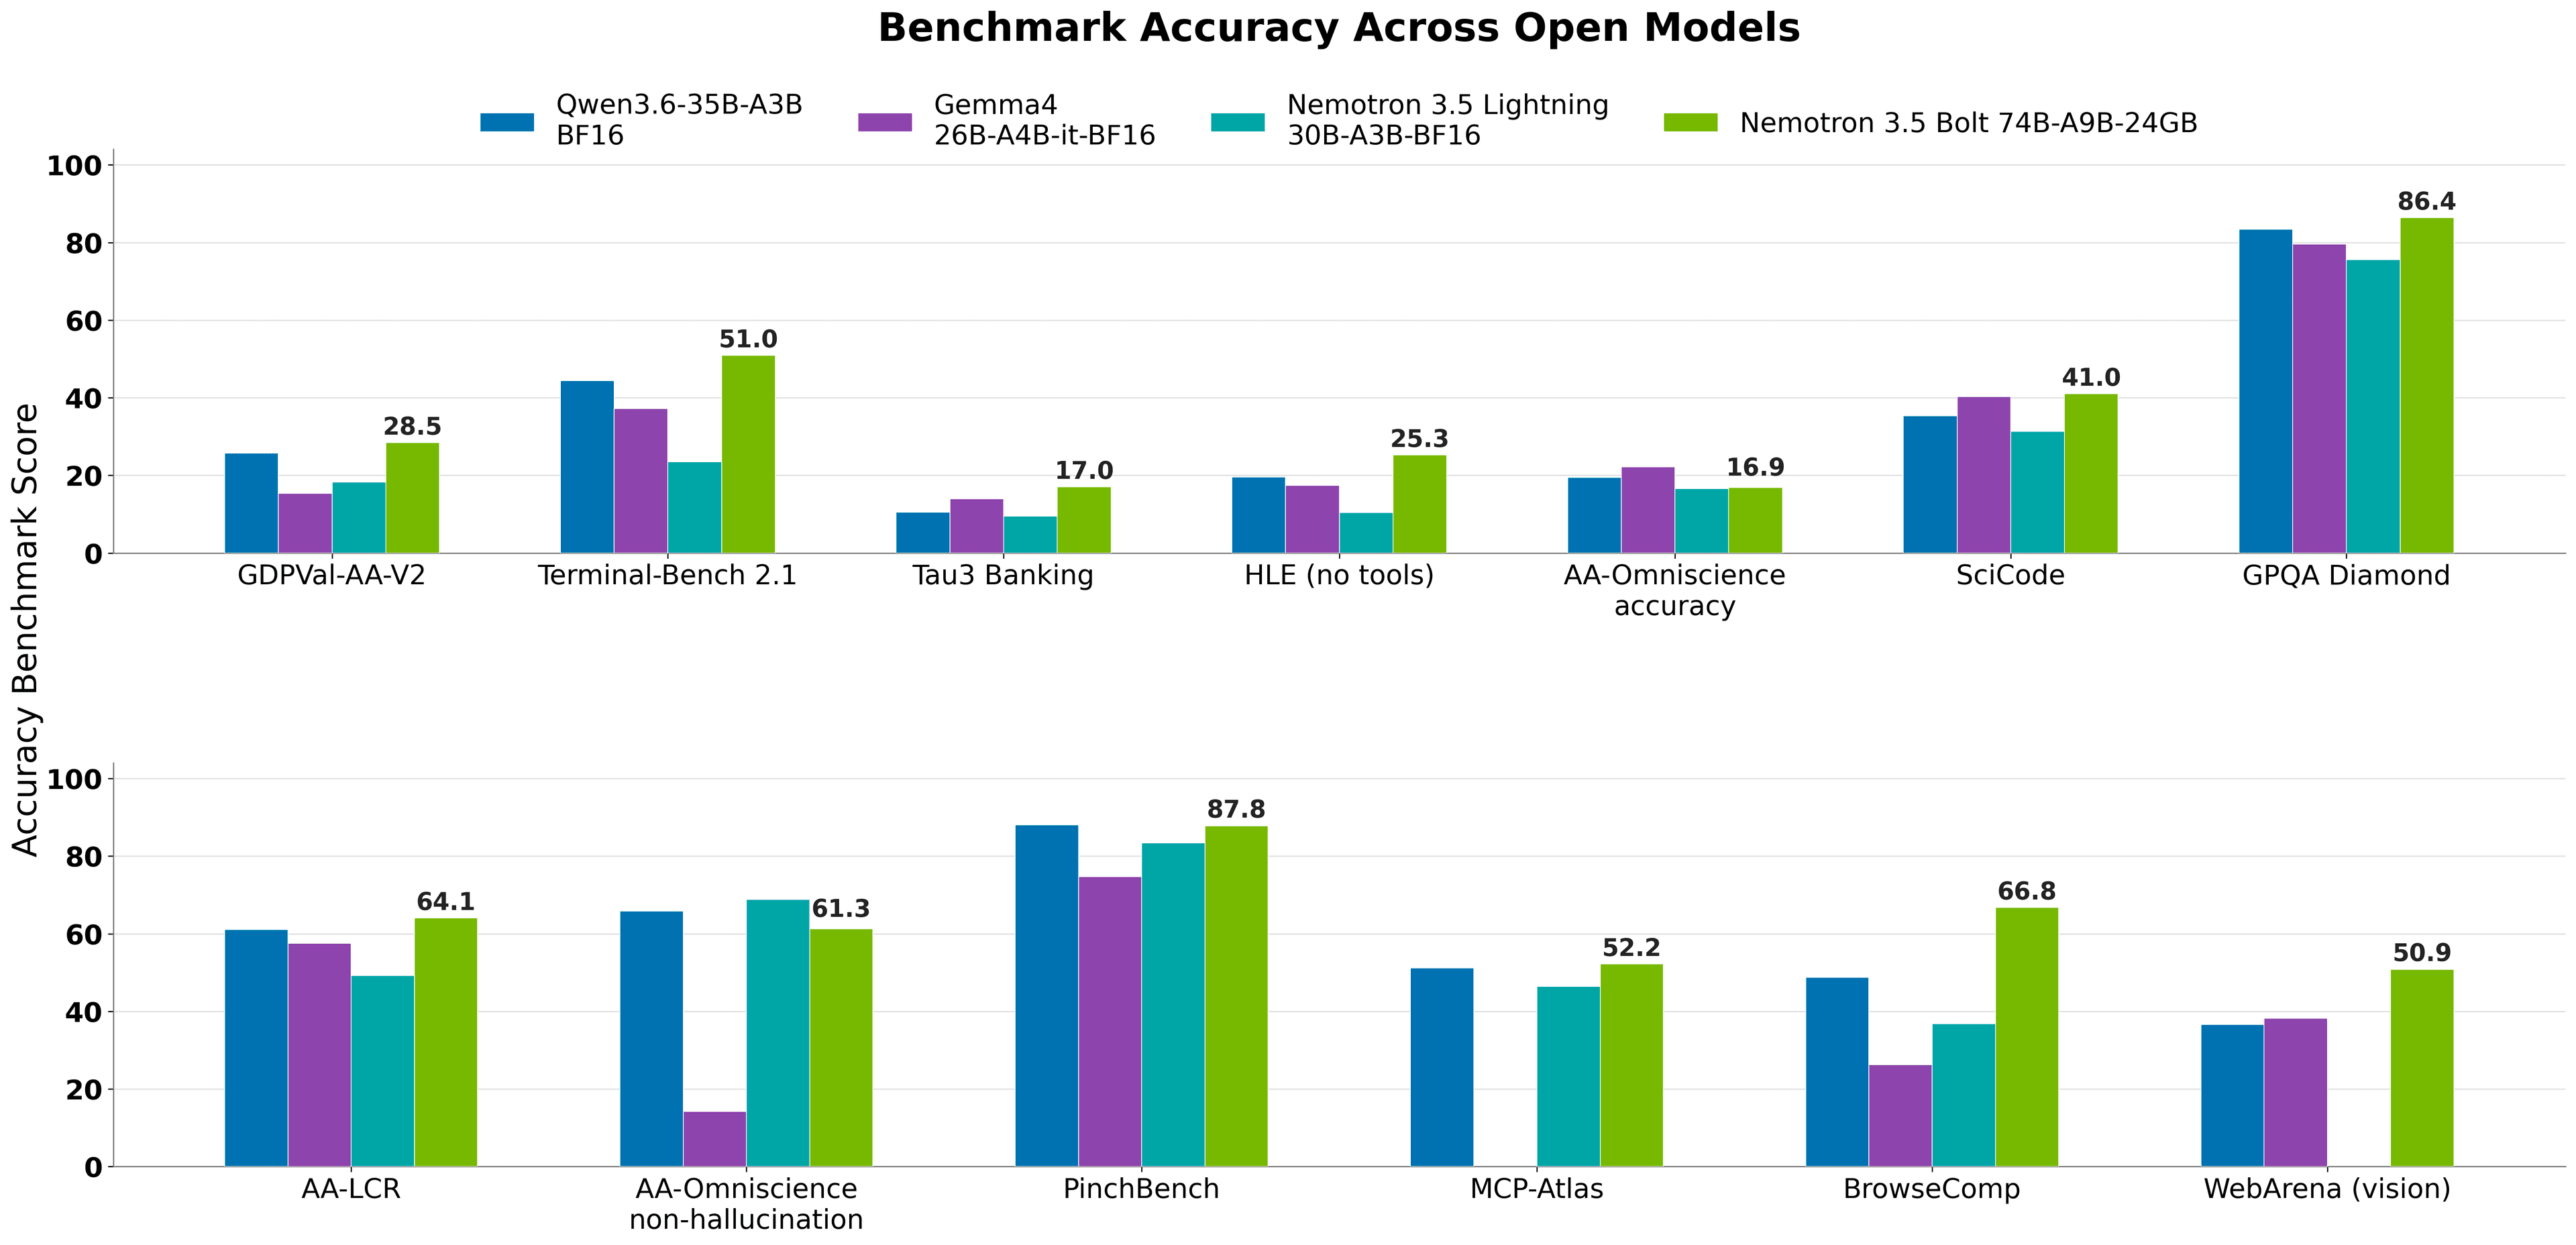
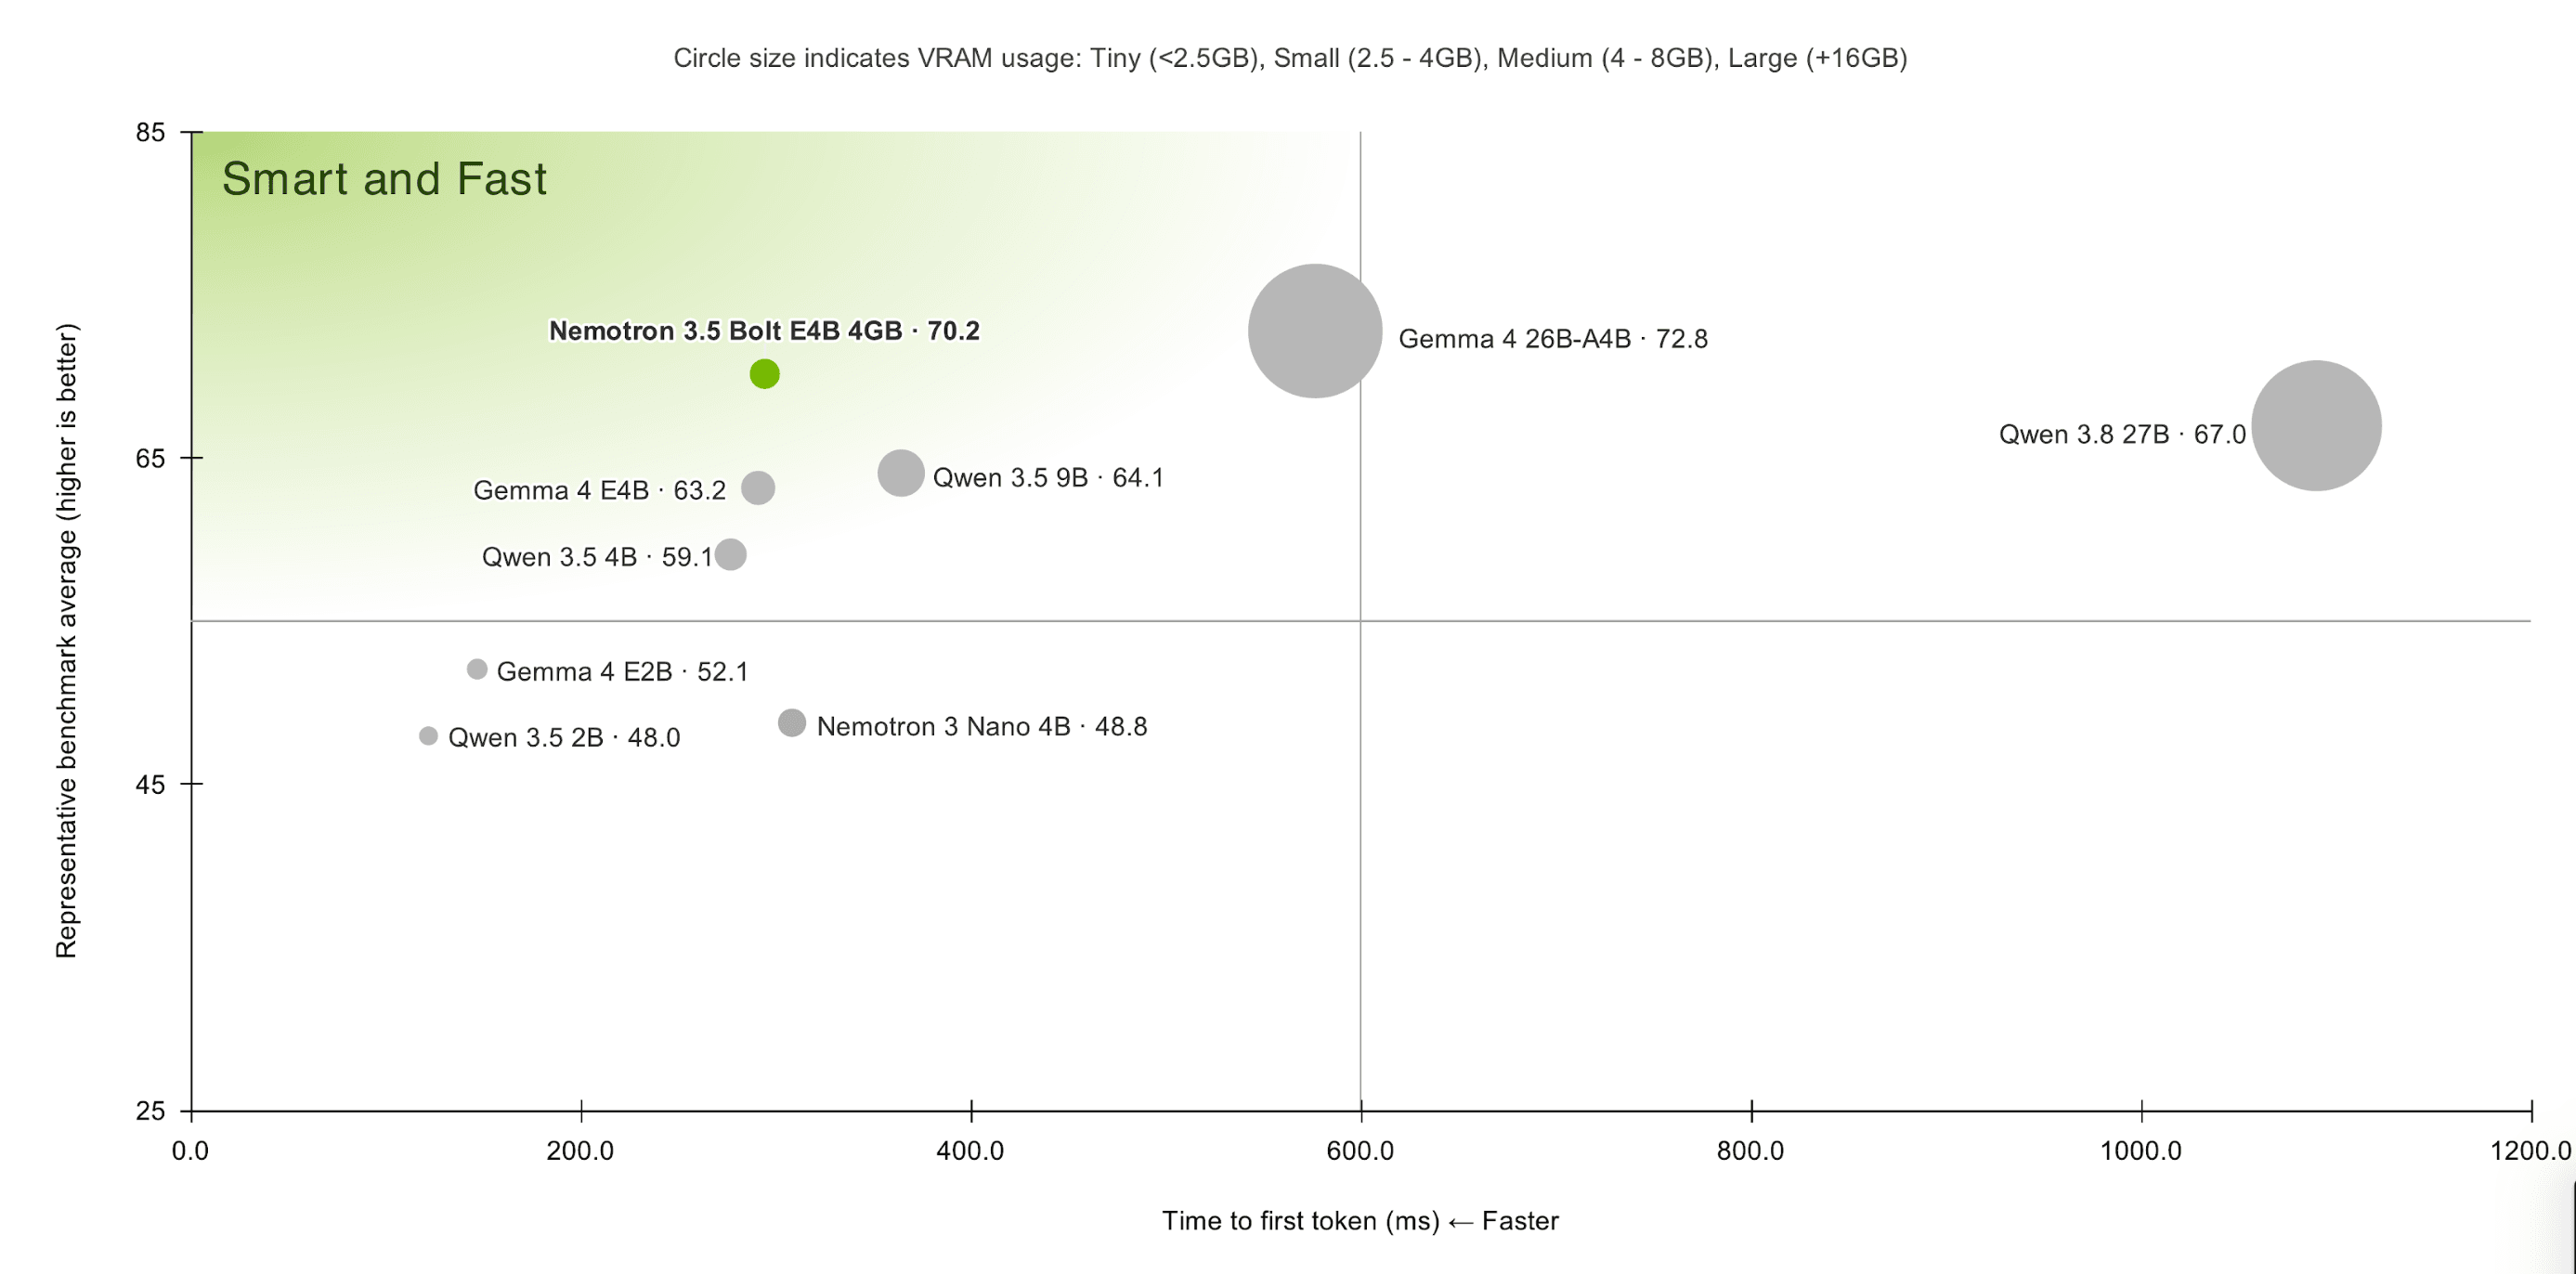
A multimodal mixture-of-experts model with 74B total parameters but just 9B active, tuned to fit consumer-class hardware.
The new flagship is a sparse mixture-of-experts model with roughly 49B active parameters per token.
TII's Falcon family gets a variant built around Emirati Arabic, aiming at culture and nuance rather than generic Gulf Arabic.
The startup's first open-weight release is a dense 501-billion-parameter model aimed at text and reasoning tasks.
The startup's first frontier-scale model ships with downloadable weights and a mixture-of-experts design aimed at reasoning.
The compact 4-billion-parameter text model is tuned for multilingual work on memory-constrained hardware.
The German AI firm positions its new open-weight language model as a European alternative built with digital sovereignty in mind.
The German AI lab frames its new open-weight language model around European data sovereignty and transparency.
The German AI firm positions its new open-weight language model as a European alternative built for data control and compliance.
The fast report-generation model behind AI2's Asta research assistant is now available under an Apache 2.0 license.
The German AI company's open-weight mixture-of-experts model targets European needs with strong German and English reasoning.
A sub-1B model bundling entity extraction, intent, sentiment and topic classification arrives on Hugging Face.
The new MiMo-V2.6-Distill-Qwen-9B targets agentic workloads, coding, and tool use in a size that fits on modest hardware.
An RL-tuned model that reads images, audio, and video while handling long context, aimed at agentic tasks.
The Chinese AI lab's early look at its next multimodal system arrives on Hugging Face ahead of a full release.
A new "System-One" model from Convai Innovations focuses on routing, scoring and safety checks rather than open-ended generation.
The compact 4-billion-parameter text model lands on Hugging Face with a permissive license aimed at developers.
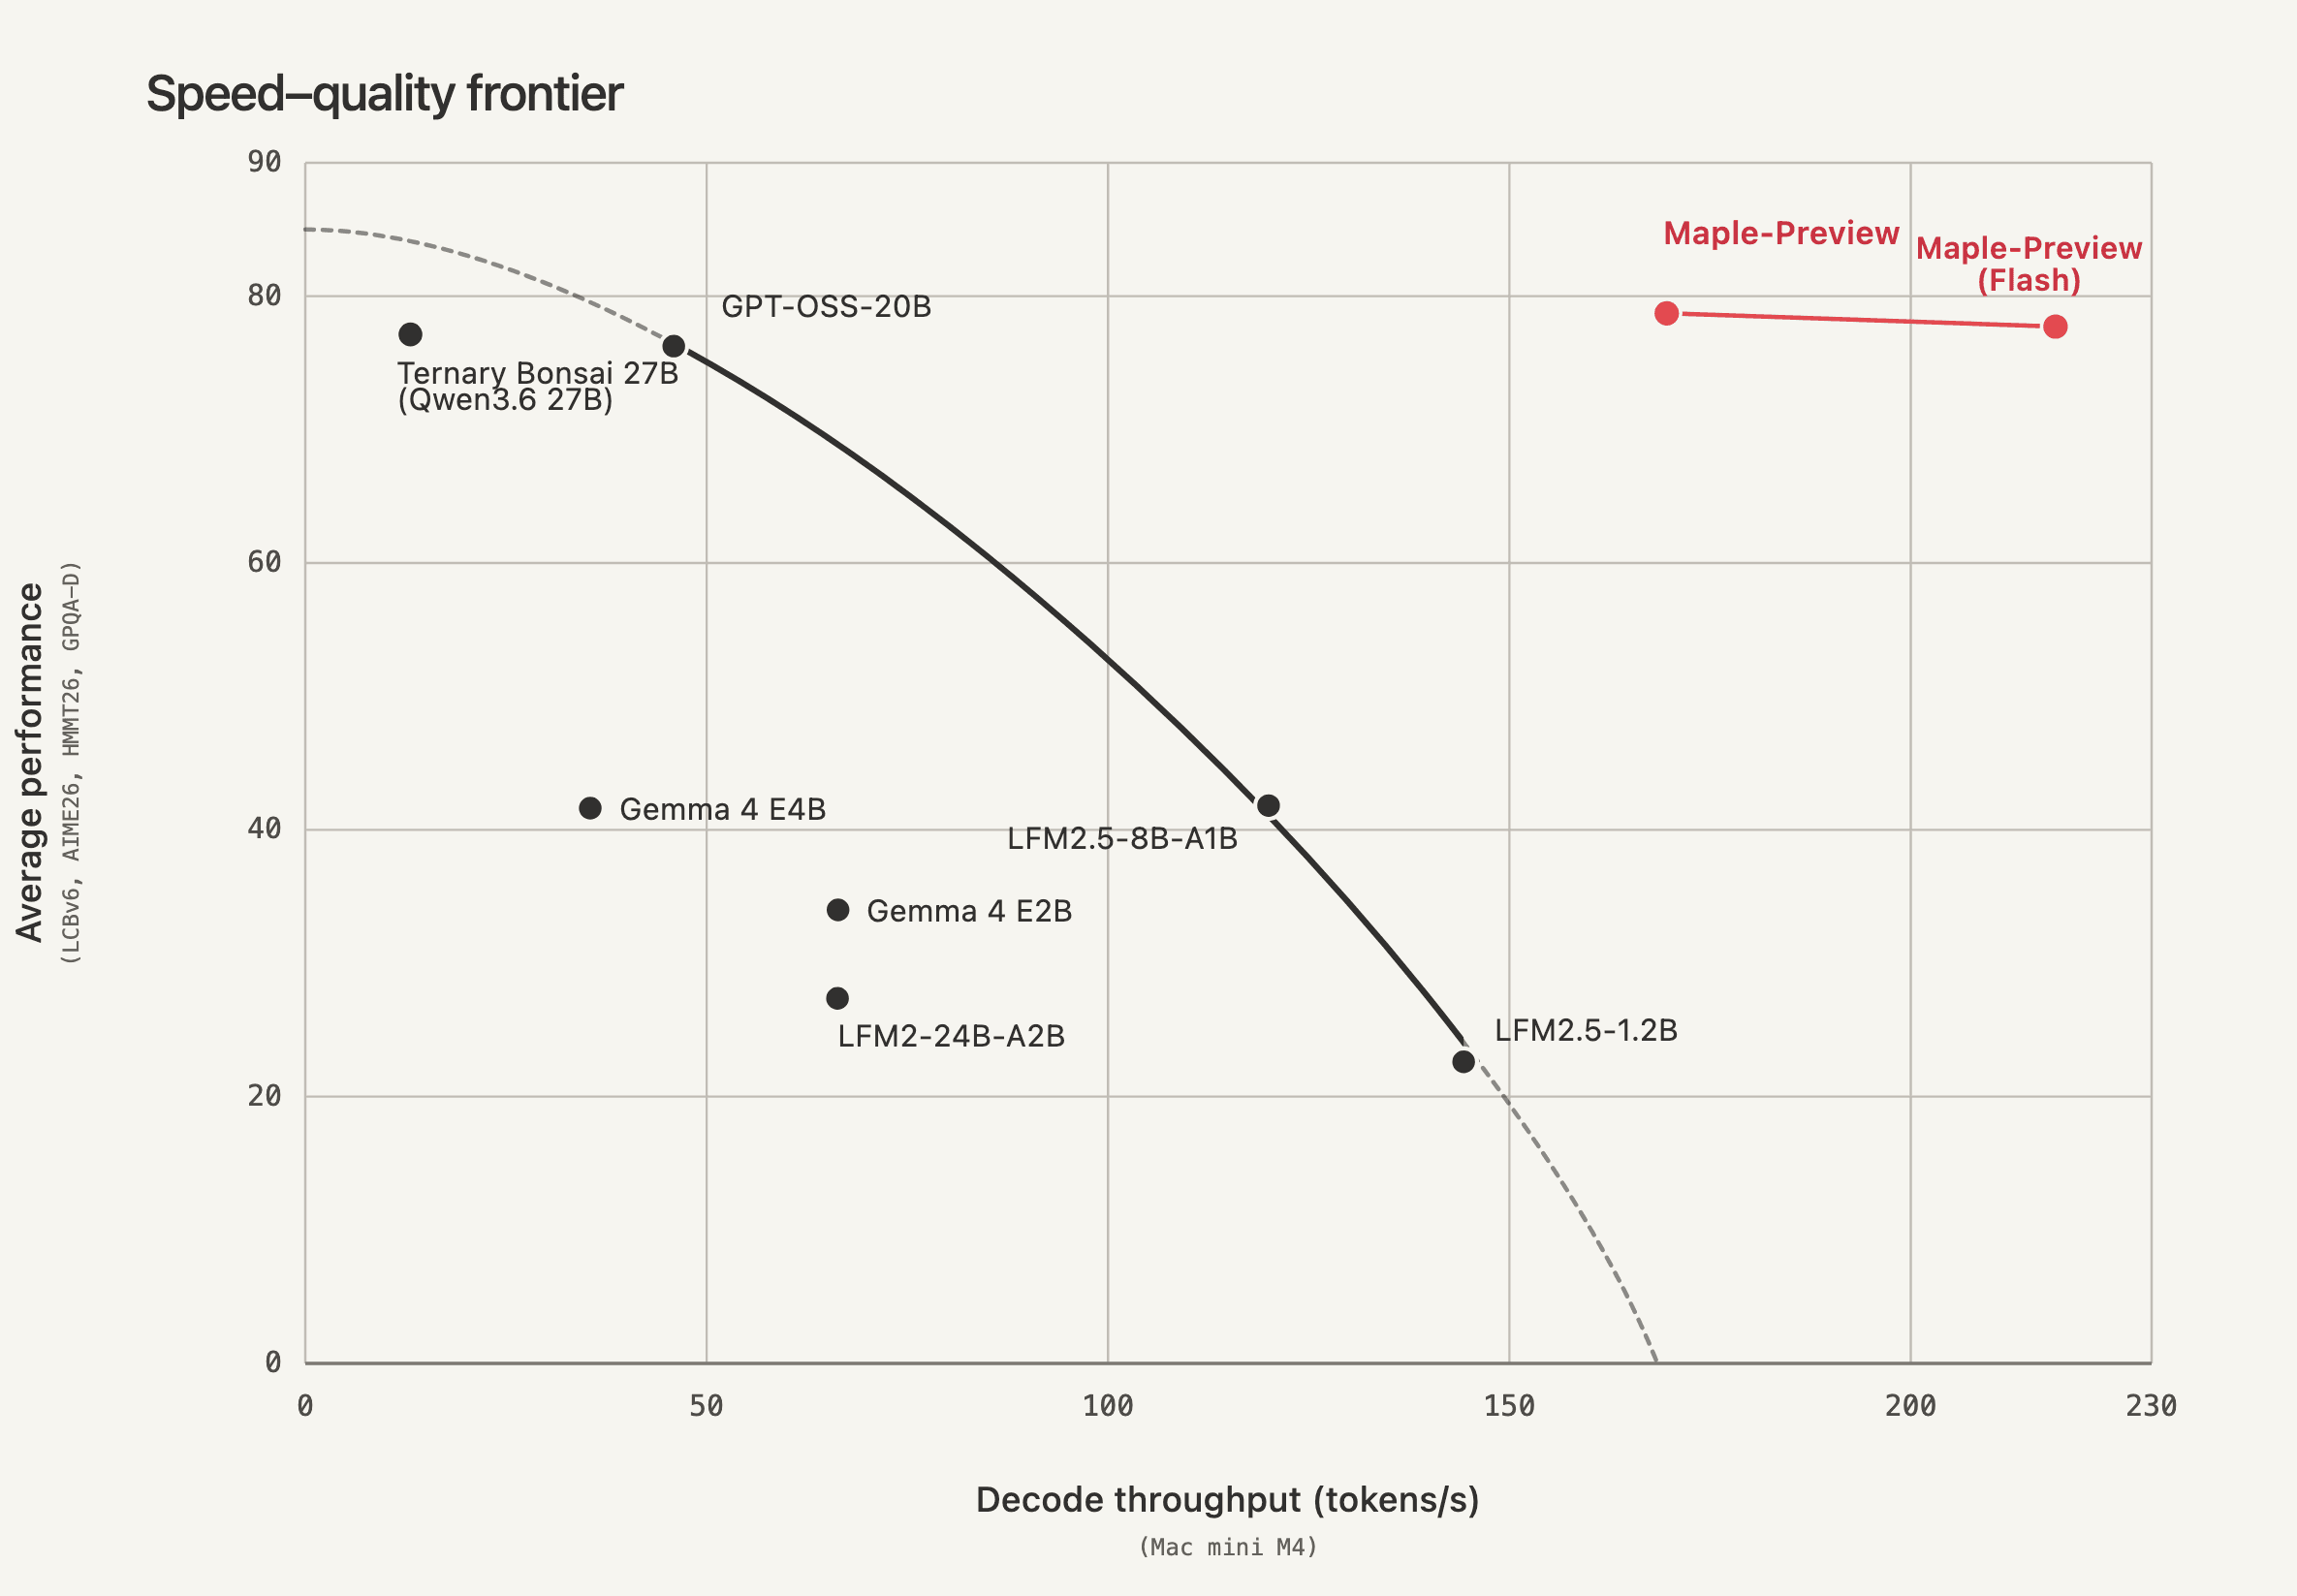
A ternary-quantized 27B model with hybrid attention targets on-device inference across CUDA and Metal.
inclusionAI's new text model uses a mixture-of-experts design to keep compute low while shipping under an Apache-2.0 license.
Cactus Compute's 8–29MB models aim to run automation and tool-calling entirely on-device, rivaling far larger cloud systems.
The 816B-parameter mixture-of-experts model activates just 42B per token and targets agentic coding across a million-token context.
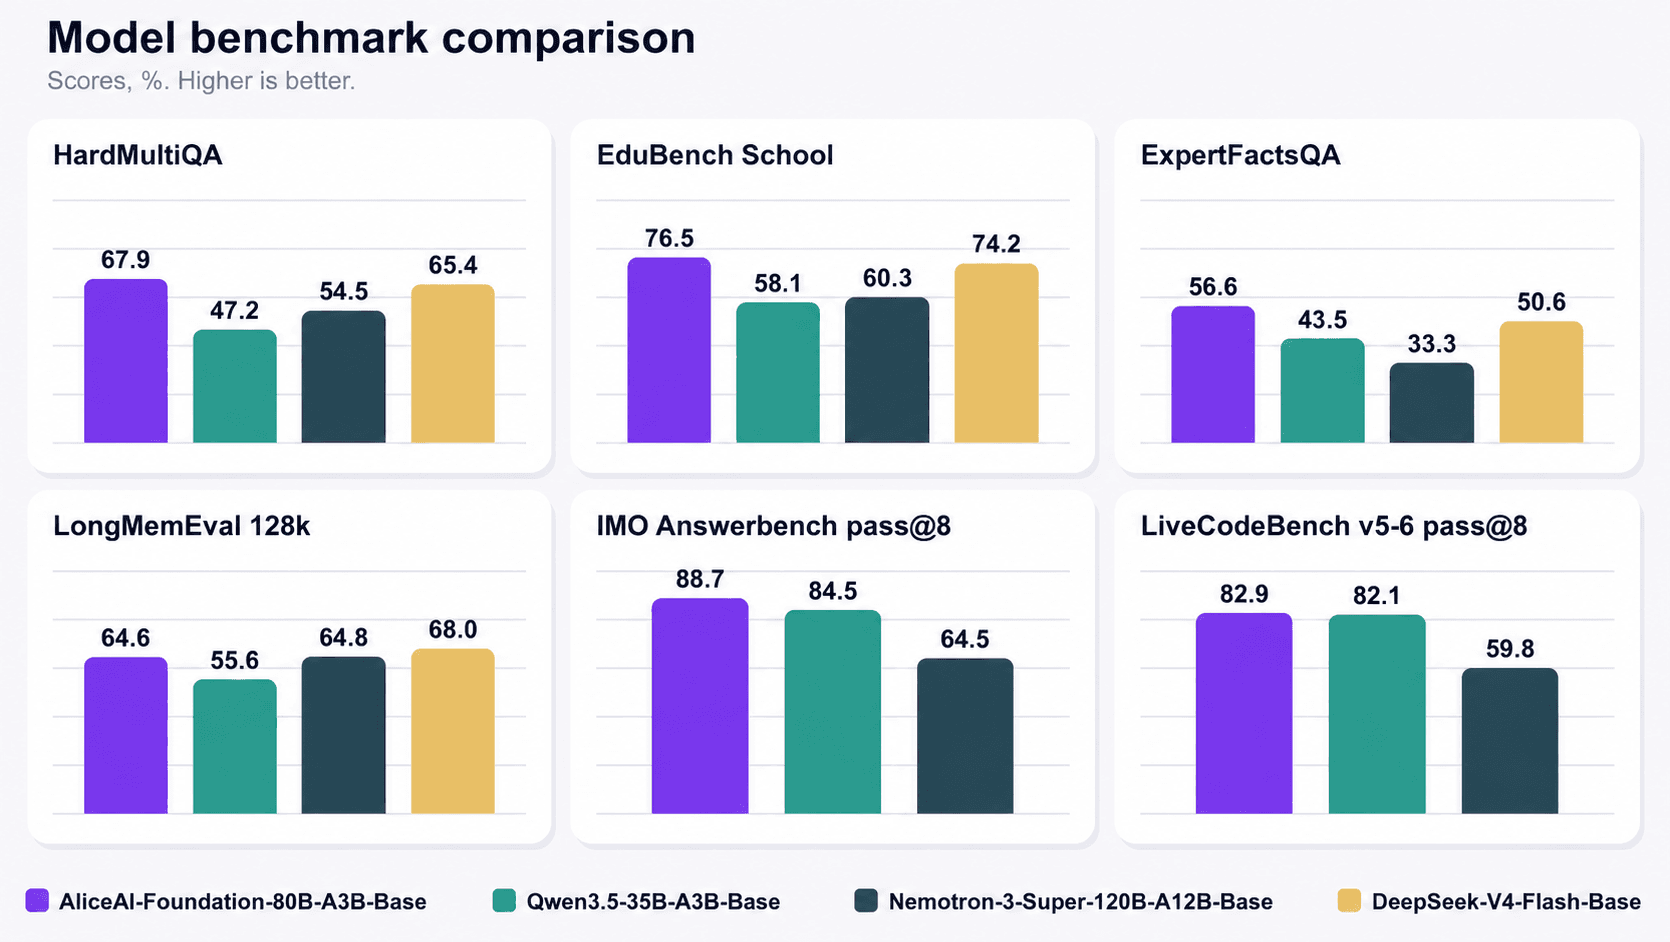
AliceAI-Foundation is a sparse mixture-of-experts model with just 3B active parameters, aimed at Russian and English text.
The new release pairs vision-language understanding with a hybrid-attention design aimed at long-context reasoning.
A new mixture-of-experts model trained on verified tool interactions arrives as an early preview under an MIT license.
A compact foundation model targets math reasoning and agentic search with tool use, and its makers are releasing it fully open.
The AliceAI-T5-35B-A0.6B is an encoder-decoder mixture-of-experts model that keeps only a sliver of its 35B parameters active per token.
A 122B mixture-of-experts model trained with reinforcement learning claims state-of-the-art results on Terminal-Bench.
A preview mixture-of-experts model uses trained routing prediction to run on machines that can't hold it all in memory.
A permissively licensed multimodal mixture-of-experts model built on a Qwen3-style MoE backbone.
The compact mixture-of-experts model handles both text and vision, and ships under a permissive Apache-2.0 license.
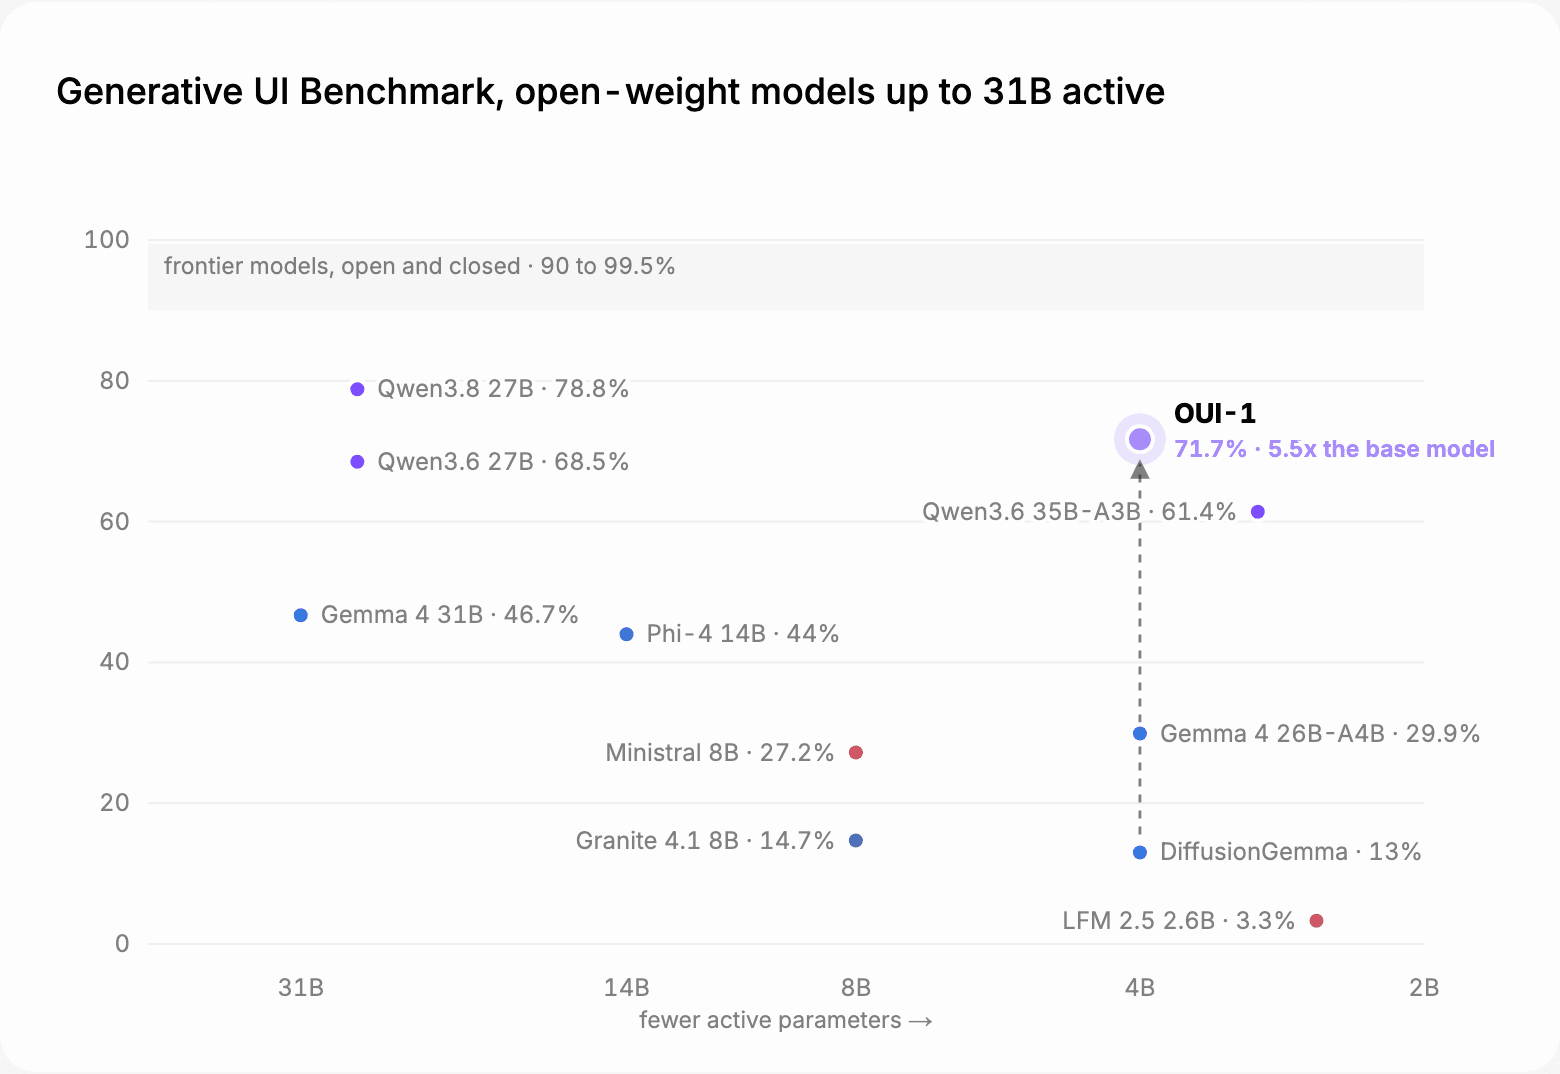
Thesys releases an experimental diffusion language model aimed at turning prompts into user interfaces, built atop Google's Gemma.
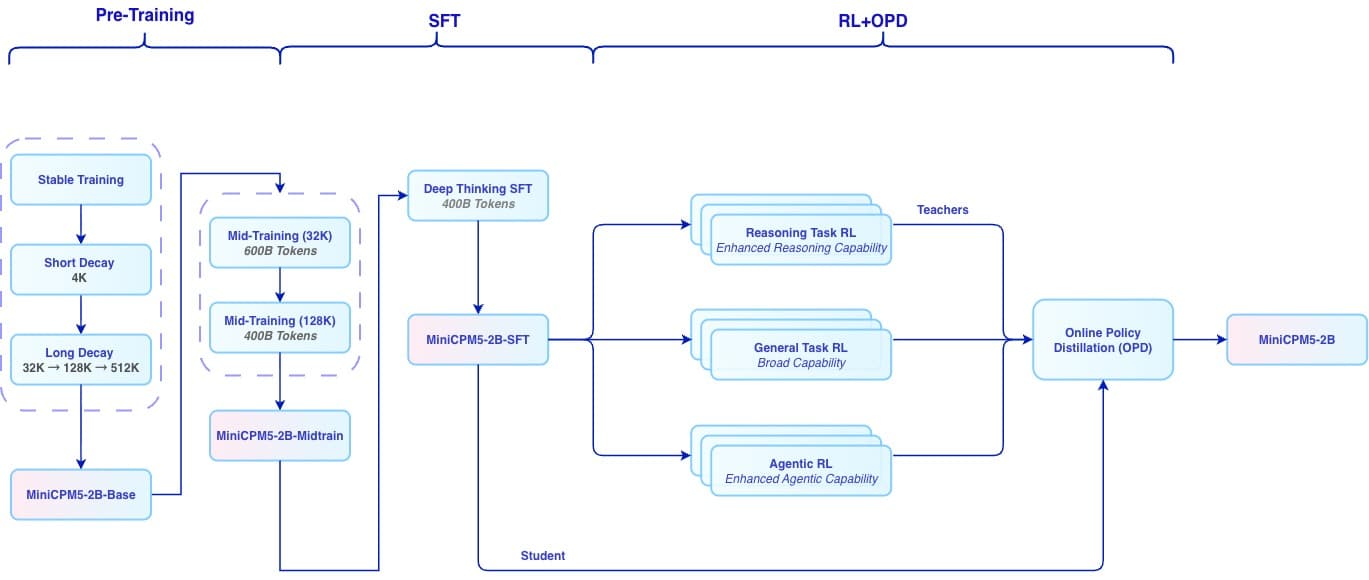
The compact 2-billion-parameter model adds long-context handling and tool-calling in a footprint small enough to run locally.
A 9-billion-parameter model built on Qwen3.5 aims squarely at tool use and code generation.
A compact 4-billion-parameter model built for tool use, coding, and multi-step reasoning arrives from TokenRhythm.
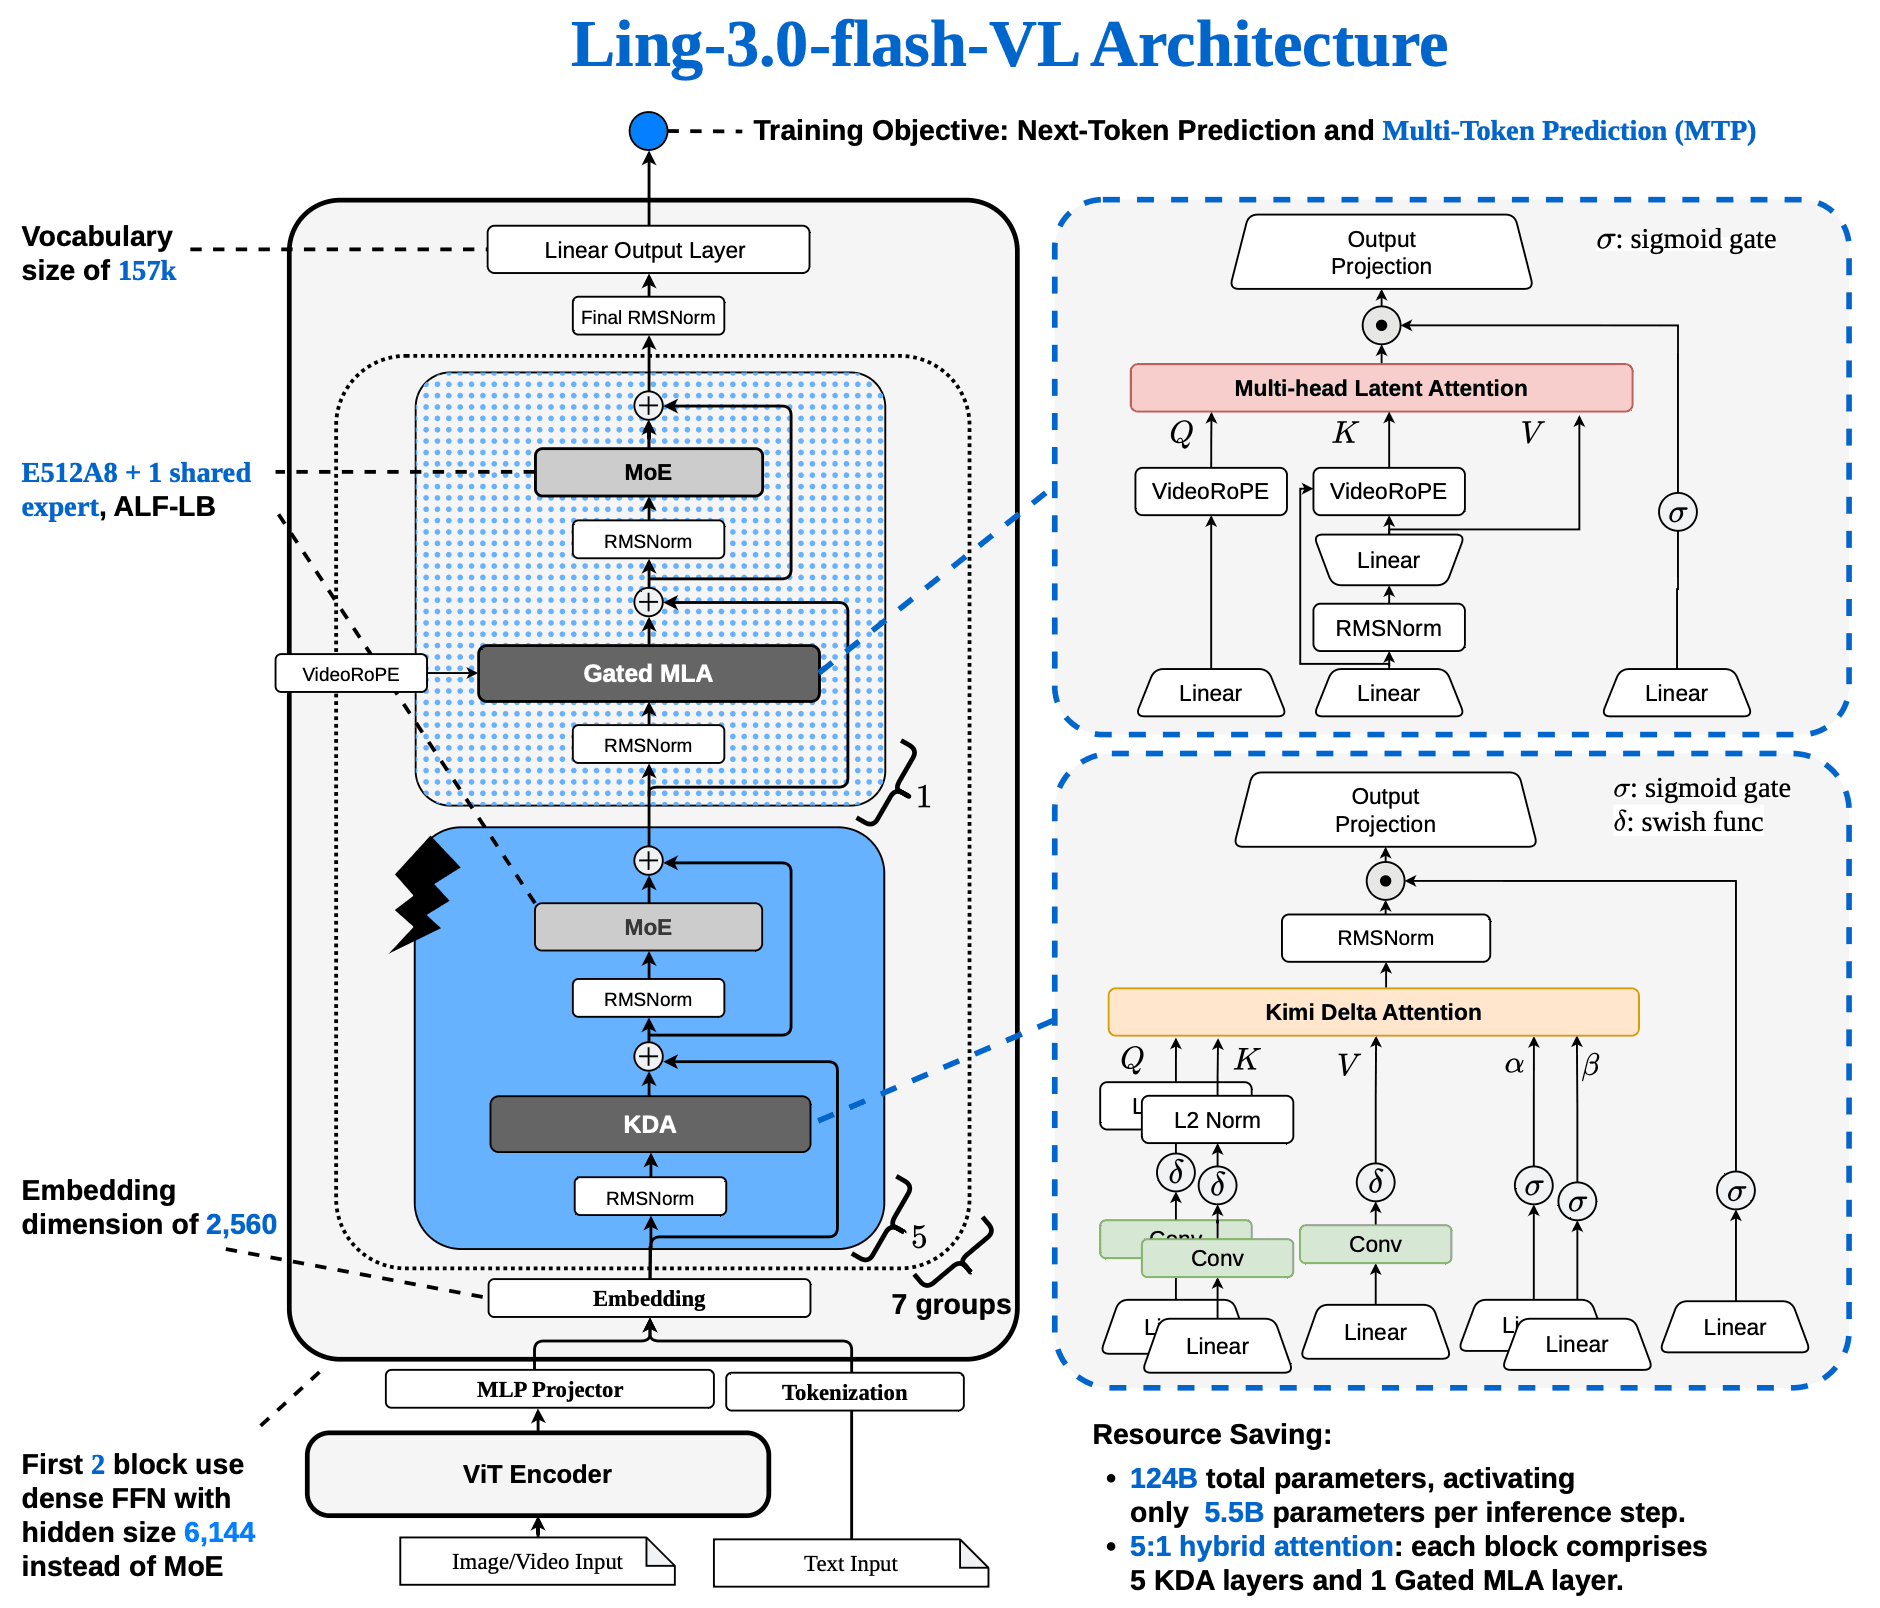
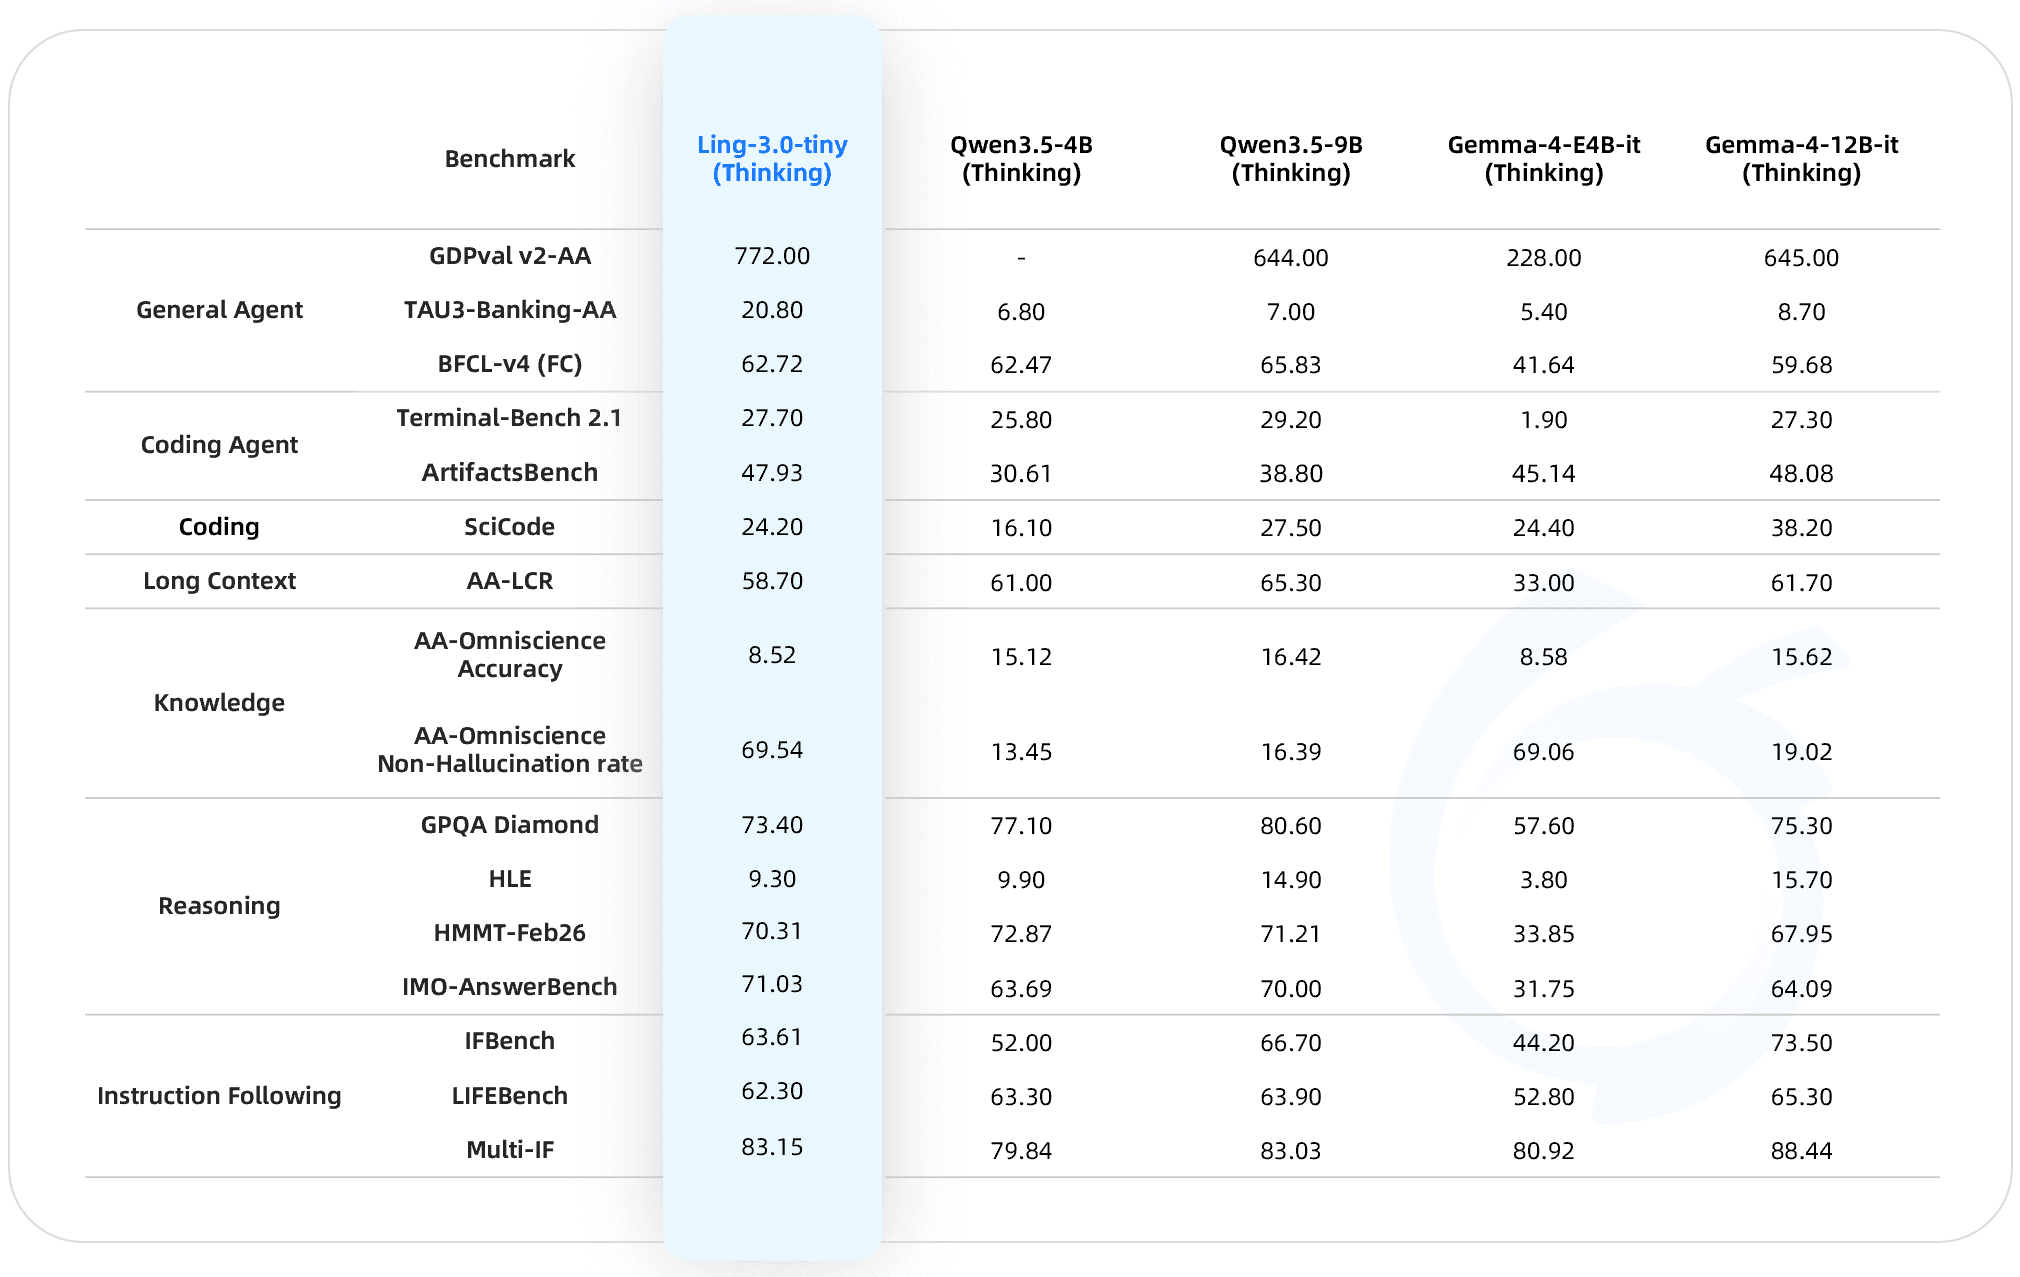
The new Ling-3.0-flash-VL brings a mixture-of-experts vision-language model to inclusionAI's open lineup under a permissive MIT license.
A new open 35B model is tuned for multi-step, co-working tasks rather than one-shot answers.
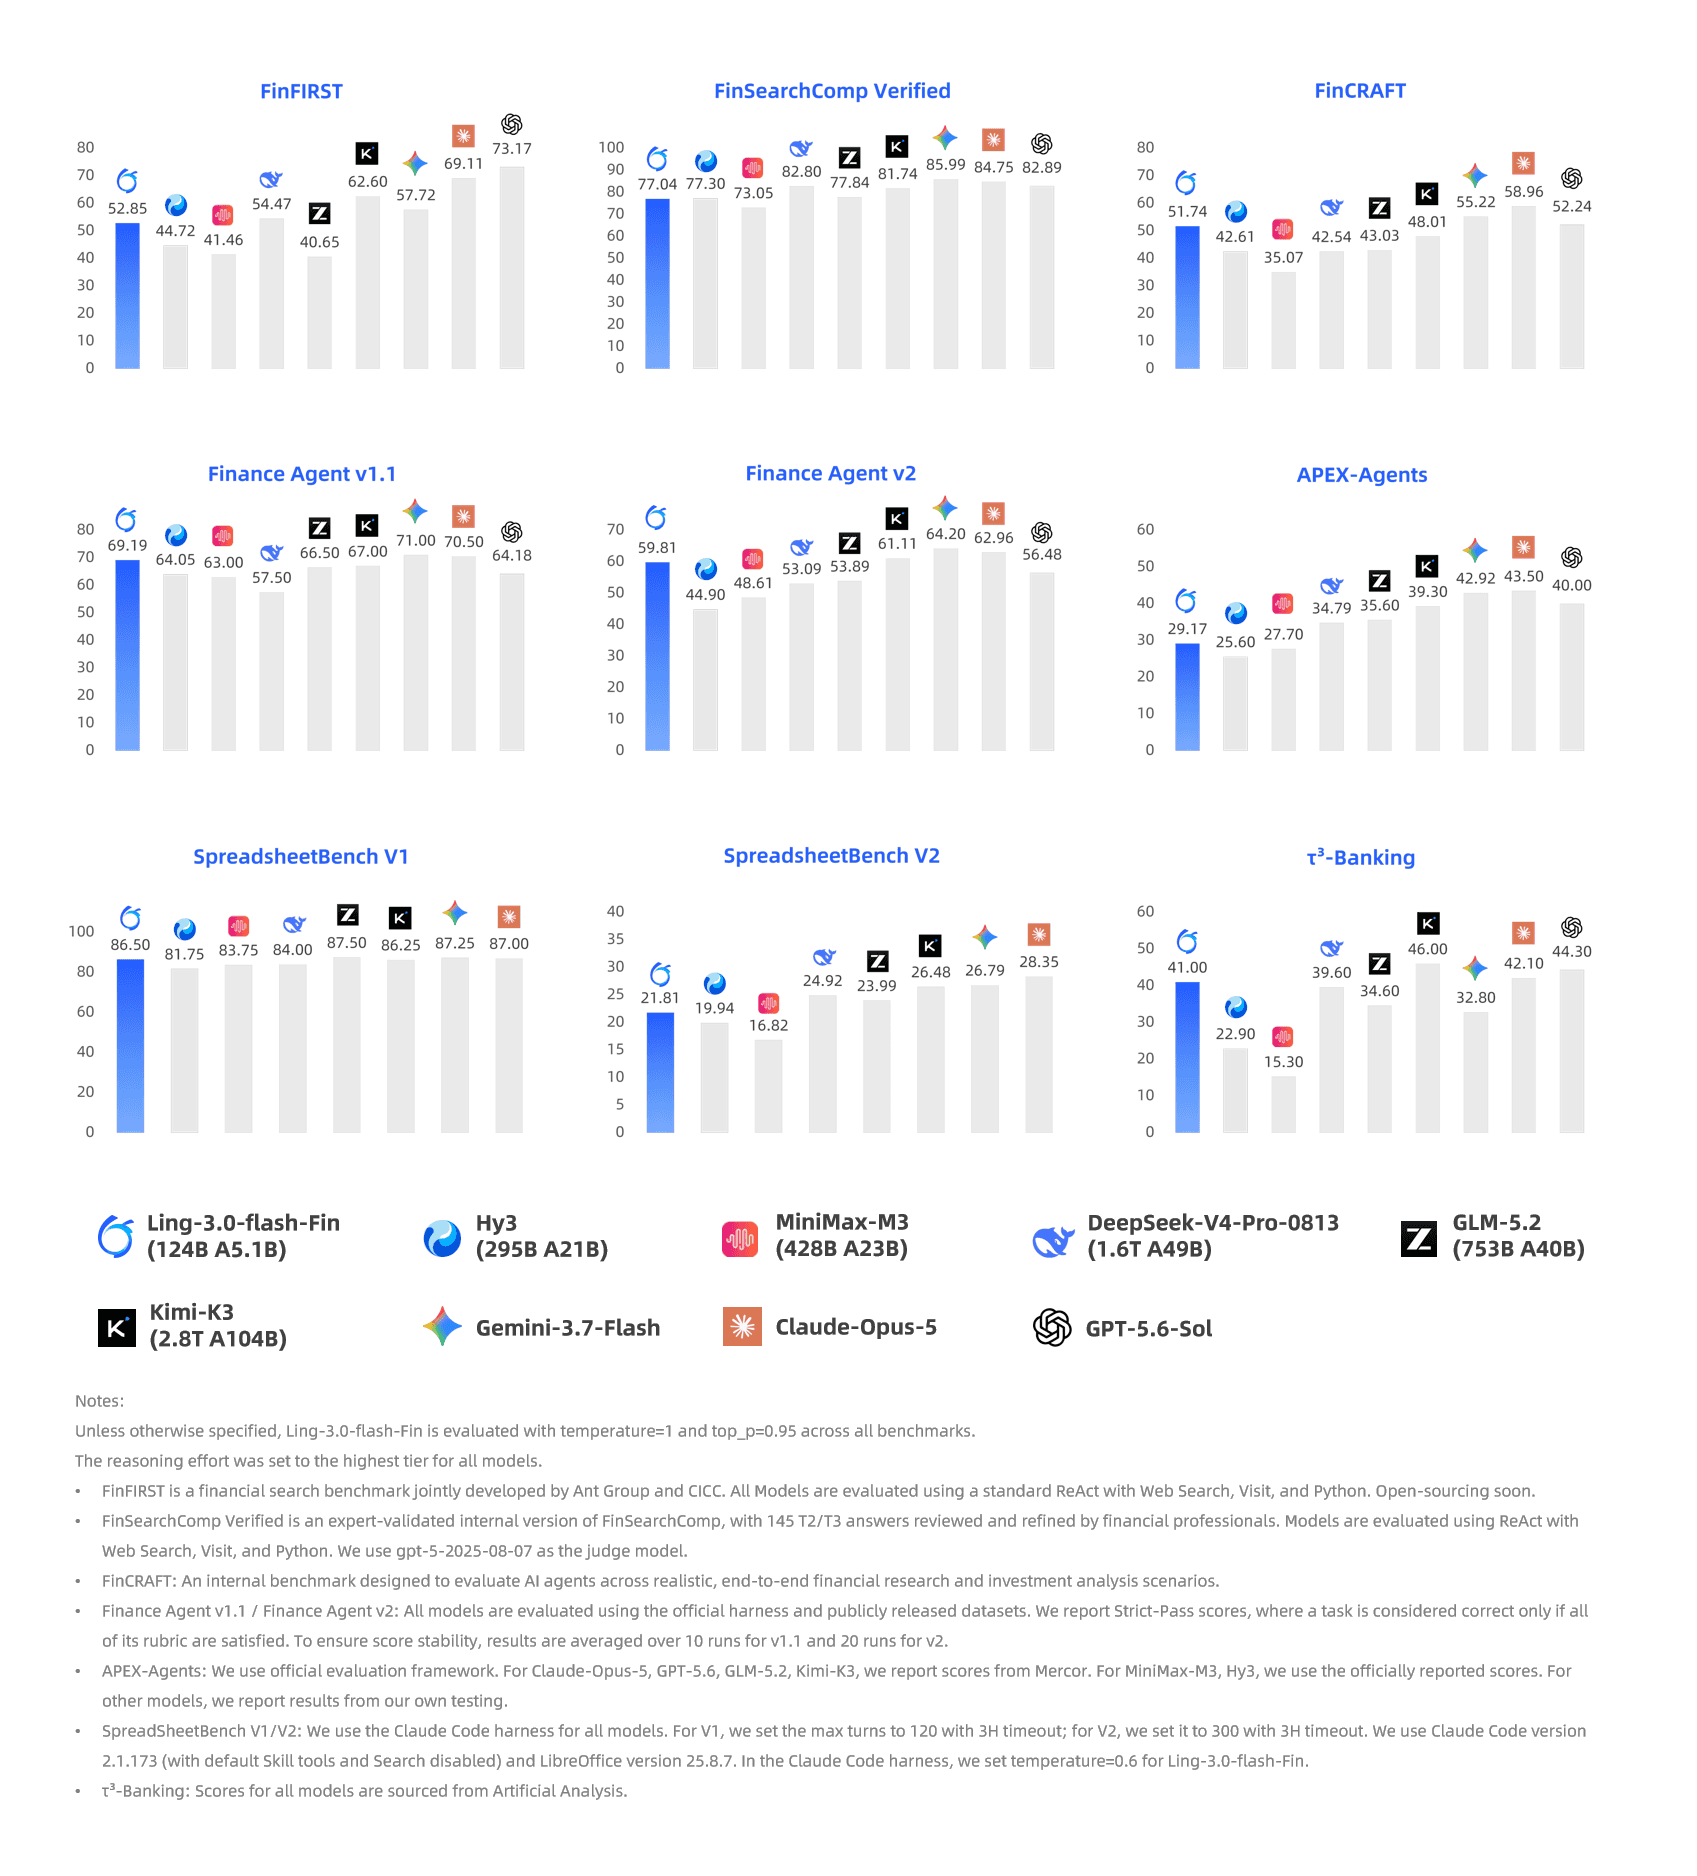
A finance-focused variant of the Ling-3.0-flash MoE model targets financial research and agentic tool use.
The latest RWKV7 checkpoint scales the recurrent, attention-free architecture to 13.3 billion parameters under a permissive Apache 2.0 license.
The flagship model uses a mixture-of-experts design that activates just 23 billion parameters per token, keeping inference costs in check.
The dense 7-billion-parameter model ships as open weights alongside the datasets used to train it.
The open-weight language model activates just 4B of its 36B parameters per token, aiming for efficiency without shedding capacity.
An experimental, MIT-licensed vision-language model brings image understanding to DeepSeek's fast V4 Flash architecture.
The company's next-generation Hunyuan language model arrives as an early preview with a permissive license and a mixture-of-experts design.
The latest update to IBM's Apache 2.0 model family leans into structured reasoning while keeping its enterprise-friendly licensing.
A speed-tuned member of the GLM-5.3 family arrives with open weights and mixture-of-experts design aimed at fast, low-cost inference.
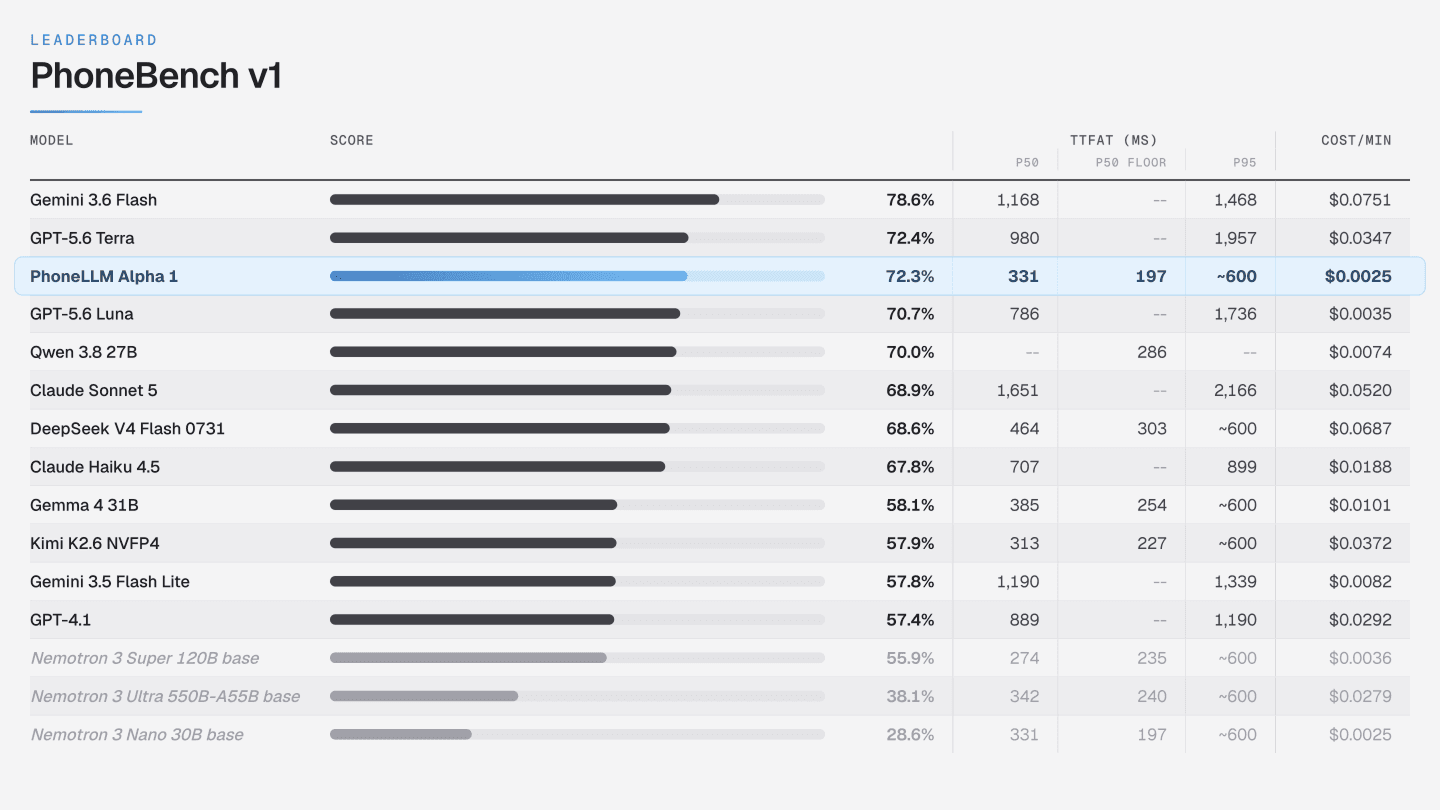
An early alpha release brings a Nemotron-H mixture-of-experts model tuned for phone-based tool use and function calling.
The Apache-2.0 instruction-tuned model targets developers who want a small, permissively licensed text generator.
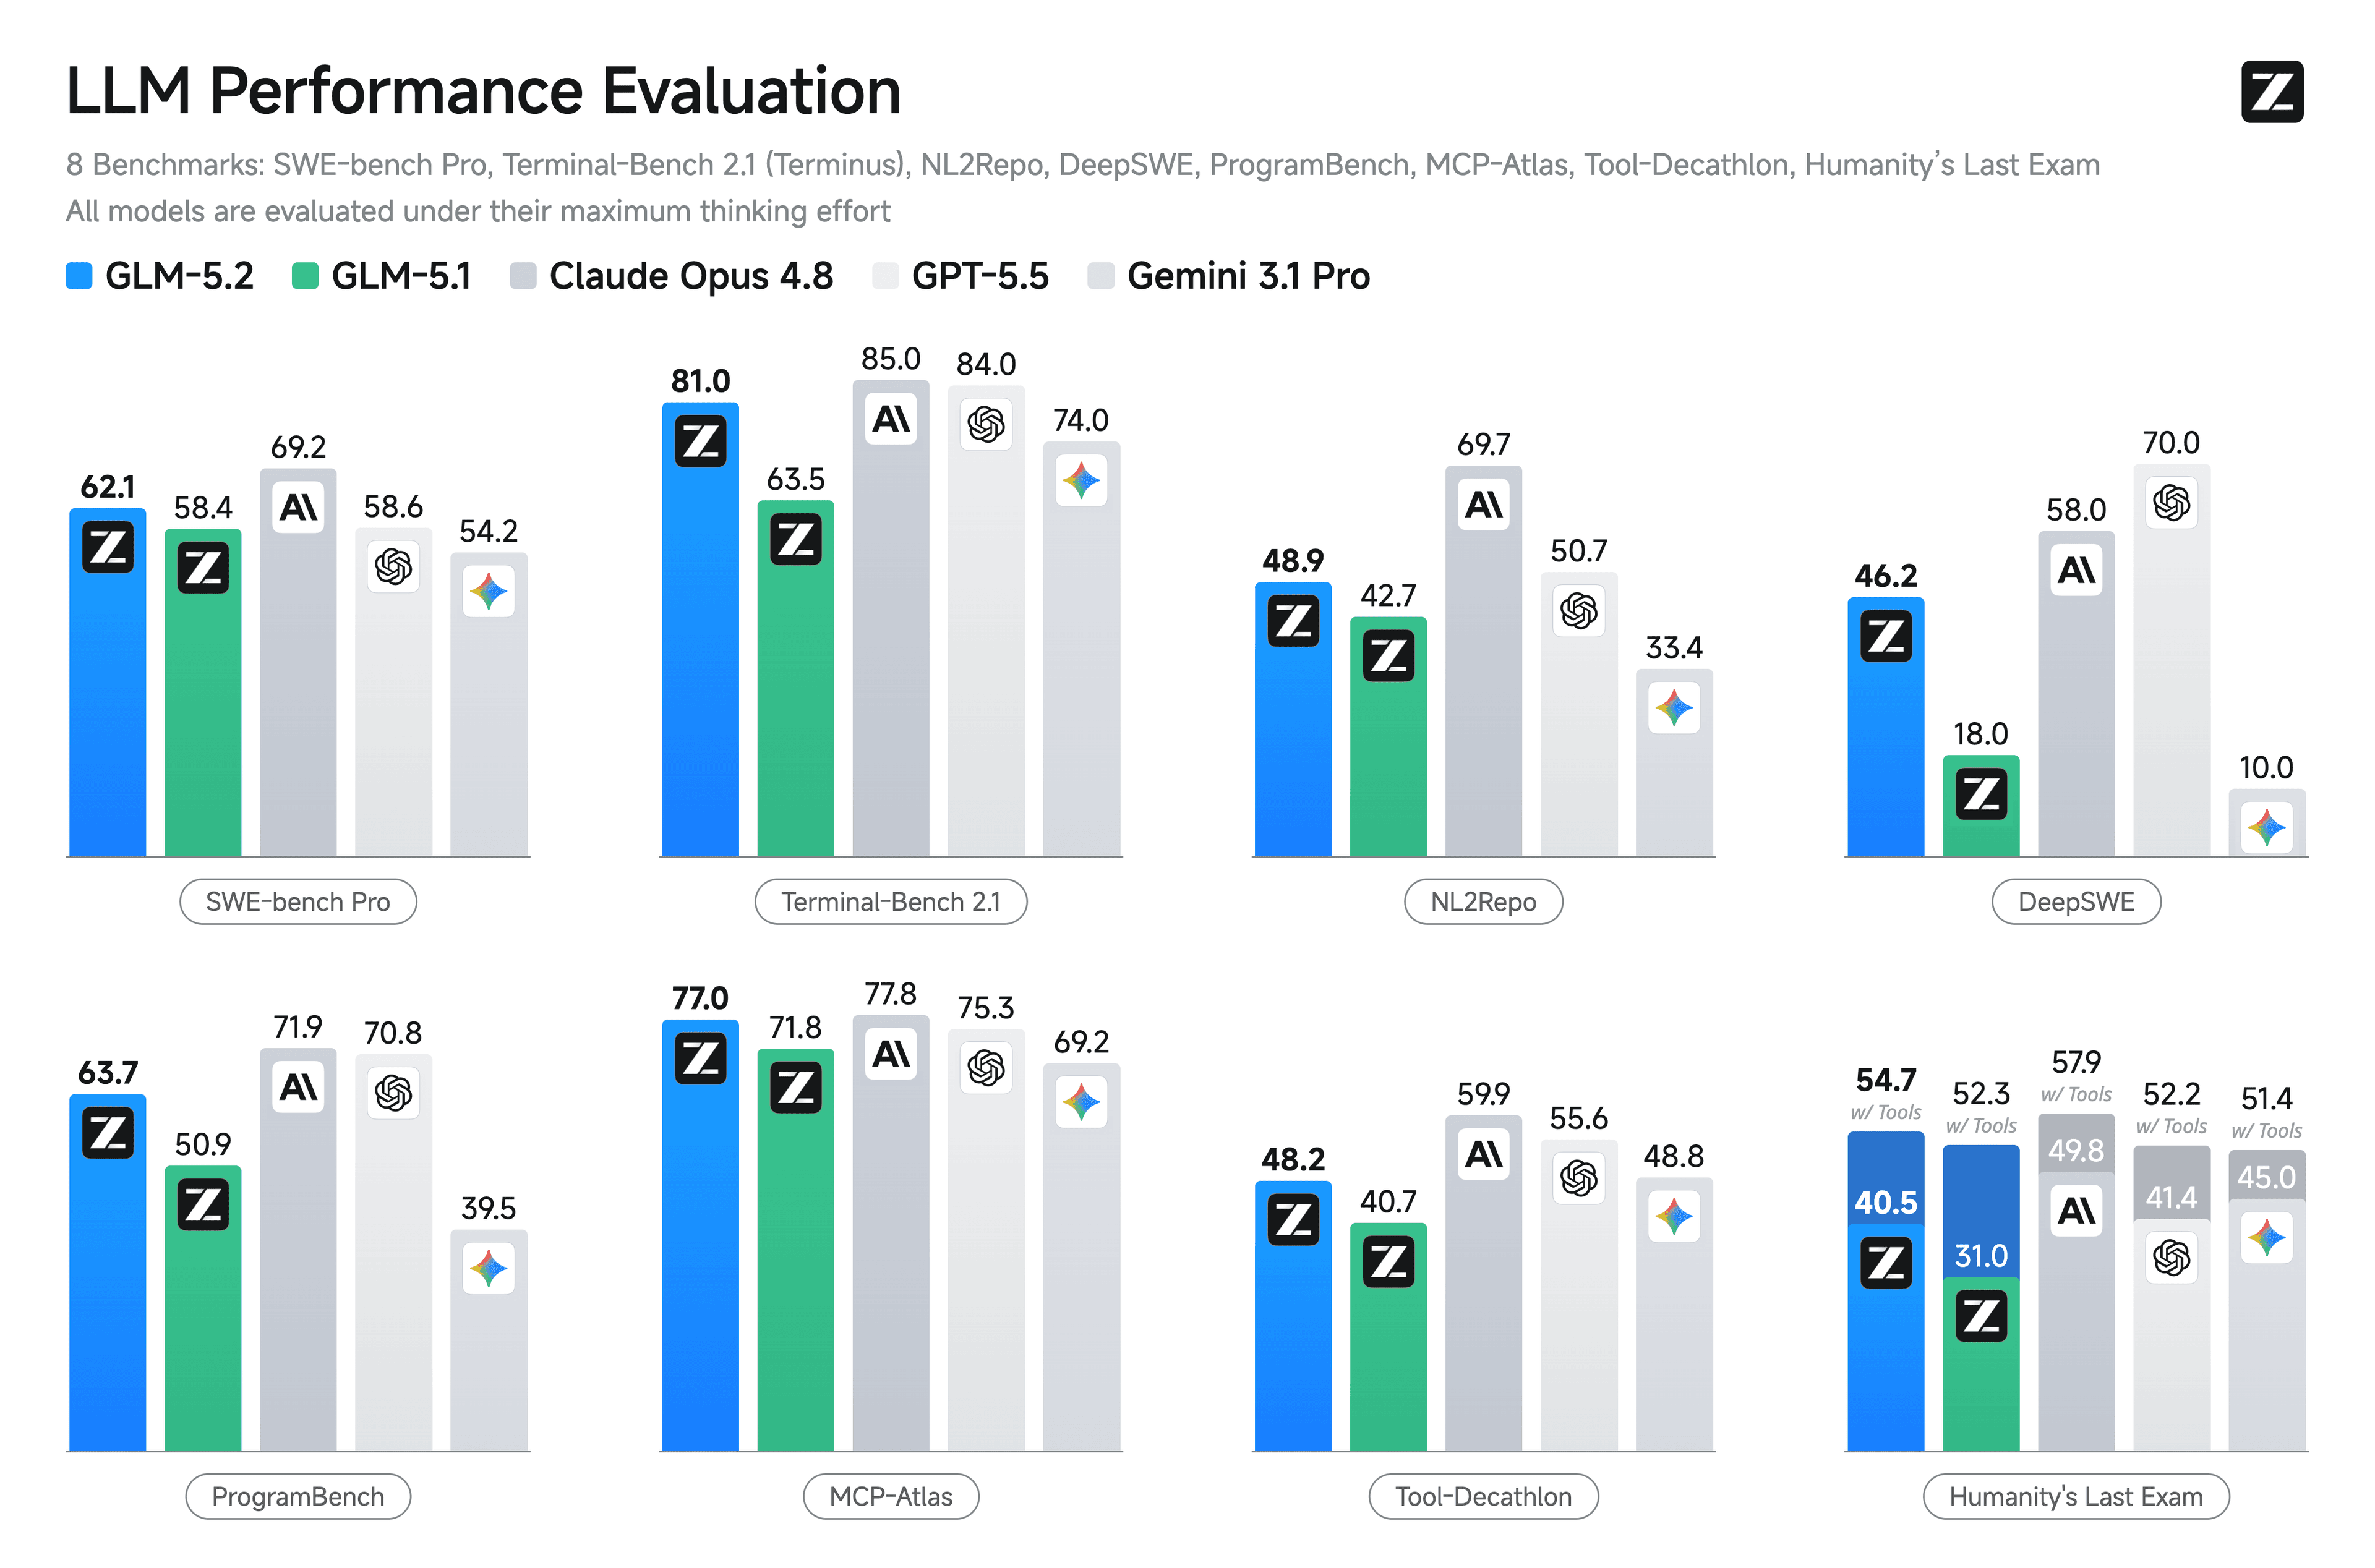
The open-weight MoE model from Zhipu AI aims to match frontier closed systems on coding tasks while undercutting them on price.
The new efficient language model claims up to 3.2x faster inference, extending Liquid AI's push toward lean, deployable models.
The company's latest LFM2.5 variant promises up to 3.2x faster inference without leaning on cloud-scale hardware.
The information giant's first frontier model is a mixture-of-experts system tuned on its proprietary legal, tax, and news data.
The MIT-licensed release spans a 397B mixture-of-experts flagship plus 9B and 35B-A3B variants for lighter deployments.
The MIT-licensed model activates just 3B parameters per token, borrowing the Qwen3.5 MoE design for text and reasoning tasks.
An MoE model built on Qwen3.5-35B-A3B aims at complex, multi-step tasks rather than one-shot answers.
A new open vision-language model family uses gated cross-attention to enable streaming, low-latency multimodal exchanges.
A multilingual model built for structured extraction tasks like named-entity recognition, relation extraction, and JSON output.
The company's newest flagship targets reasoning and coding while keeping a permissive open-source license.
The Chinese lab pushes a higher-capability checkpoint of its V4 line to Hugging Face under a permissive MIT license.
The new hybrid mixture-of-experts model targets efficient text generation under a permissive license.
Alibaba's Qwen team pushes its largest sparse model yet, activating 95 billion parameters per token from a 2.4-trillion-parameter pool.
The new dense model brings optional step-by-step thinking and function calling under a permissive Apache-2.0 license.
Motif Technologies debuts a mixture-of-experts language model built around grouped differential latent attention for long-context reasoning and code.
OpenMOSS releases what it calls the first open-source 8B language model built specifically for Yiddish, paired with an evaluation benchmark.
Alibaba's latest Qwen release pairs image understanding with text under a permissive Apache-2.0 license.
A permissively licensed reasoning model that pairs a mixture-of-experts design with ternary weights, aiming for efficiency.
A 30-billion-parameter mixture-of-experts model activates just 3 billion parameters per token, using a hybrid Mamba design to keep inference fast.
The latest entry in the Bailing family pairs a hybrid mixture-of-experts design with a permissive license aimed at fast, low-cost text generation.
The latest Liquid Foundation Model targets multilingual text generation on laptops and phones, packaged in GGUF for local runtimes.
A 30B mixture-of-experts model with just 3B active parameters aims at fast, agentic coding workloads.
The food-delivery giant's newest open model trims its mixture-of-experts design for more efficient inference under an MIT license.
The latest checkpoint in DeepSeek's V4 line leans into agentic workflows while keeping the permissive MIT license.
The MIT-licensed mixture-of-experts model returns in an updated build shipping with FP8 weights for cheaper inference.
Cactus Compute's tiny model brings tool and function calling to phones, wearables, and robots.
The new mixture-of-experts model activates 37B parameters per token and targets English, Korean, and Spanish reasoning tasks.
A compact 2.6-billion-parameter model built to run local, multilingual agents without leaning on the cloud.
The Korean telecom carrier's latest open language model targets English, Korean, Chinese, Japanese, and Spanish under a permissive license.
The Apache-2.0 model brings mixture-of-experts efficiency to image, audio, and text tasks in a smaller footprint.
Switzerland's open-model effort ships a 70-billion-parameter, multilingual and multimodal system that anyone can use, modify, and deploy.
A new open mixture-of-experts model with 16B total parameters and just 3B active is tuned to run on AMD's own accelerator stack.
Kuaishou's coding team ships an open mixture-of-experts model built on the Qwen3.5 MoE architecture and tuned for agentic development work.
The Korean AI firm's latest open release scales to 250 billion parameters with a mixture-of-experts design tuned for English and Korean.
The new English-Chinese language model targets efficient deployment in a small parameter footprint.
The Korean AI lab's preview release is a mixture-of-experts language model built for long-context, multilingual work.
A collaborative European effort ships a dense 30-billion-parameter model that claims top marks on both English and German benchmarks.
A compact 3B open-weights classifier flags unsafe text and visual content, and ships under Apache 2.0.
A new Apache-2.0 mixture-of-experts model that generates text through diffusion rather than left-to-right decoding.
The lab's inaugural open-weights release is a mixture-of-experts system that takes image and audio inputs, shipped under a permissive Apache 2.0 license.
The Mira Murati-founded lab makes its debut with an open-weights, reasoning-focused language model.
A new mixture-of-experts model learns to reason through reinforcement learning alone, without human-annotated chains of thought.
The AI coding startup puts a version of its Laguna family on Hugging Face under the permissive OpenMDW license.
The multilingual instruct model activates 28B parameters per token and leans on hybrid attention for efficiency at scale.
A ternary-weight 27B model with hybrid attention aims to run large-model reasoning on everyday hardware.
The company's latest mixture-of-experts model arrives as an openly licensed conversational LLM on Hugging Face.
The new open-weights family adds a mixture-of-experts design, encoder-free multimodal inputs, and an optional thinking mode.
The new Apache-2.0 mixture-of-experts model activates just 6B parameters per token, trading raw density for cheaper inference.
A Mamba-2 mixture-of-experts model claims top marks in both English and German benchmarks.
A 230-million-parameter language model built to run locally on constrained hardware like the Raspberry Pi.
A 230-million-parameter language model built to run on hardware as modest as a Raspberry Pi.
A 230-million-parameter model built to run on constrained hardware like Raspberry Pi and edge robotics.
The Chinese delivery giant continues its push into open AI with a new text model on Hugging Face.
The new flagship arrives as a mixture-of-experts system with FP8 weights and open reasoning capabilities under a permissive license.
A lighter, faster member of DeepSeek's V4 line arrives on Hugging Face under a permissive MIT license.
The new dense model ships in GGUF format under a permissive MIT license, aimed at local and self-hosted deployment.
A 230-million-parameter multilingual model built to run efficiently at the edge rather than in the cloud.
A 75-billion-parameter mixture-of-experts reasoning model that activates just 9 billion parameters per token.
The 75B-parameter model activates just 9B per token and ships in NVIDIA's NVFP4 format for efficient inference.
The flagship of a new open model family arrives under a permissive MIT license, with reasoning among its stated strengths.
Alibaba's new MoE model acts as a language world model, generating the environments that agents act within.
InclusionAI's new mixture-of-experts model bets that agent-horizon scaling can rival far larger systems on long-running tasks.
A compact, MIT-licensed 9B model built for autonomous coding tasks arrives on Hugging Face.
An MIT-licensed mixture-of-experts model targets self-scaffolding code tasks without the footprint of a frontier system.
The compact, code-focused language model arrives on Hugging Face under an open model license.
The new bilingual model from the Chinese AI firm uses a Mixture of Experts architecture and sparse attention under a fully permissive license.
The AI coding startup steps into open weights with an Apache-2.0 mixture-of-experts model built for text and code.
A compact Qwen3-derived model built to explore repositories, released under a permissive MIT license.
The open-weights multimodal model leans into coding and agentic tasks, extending Moonshot's Kimi line into a new scale bracket.
The new 3-billion-parameter model from the Chinese tech giant focuses on challenging benchmarks in mathematics, coding, and graduate-level questions.
The new Mixture-of-Experts model from the Chinese AI company can generate code while also understanding visual inputs, a rare combination in open models.
The new 26B parameter model from DeepMind uses a diffusion-based architecture, a technique more common in image generation, to produce text.
The new Apache 2.0-licensed model is designed for code generation and agentic chat applications, using a Mixture-of-Experts architecture for efficiency.
The new 12-billion-parameter open model from DeepMind introduces a unified 'any-to-any' architecture for advanced multimodal tasks.
The new 12-billion-parameter model from Google DeepMind is designed to handle a flexible mix of data types, moving beyond traditional text and image inputs.
The compact 1B-parameter model brings long-context handling and tool-calling to phones and laptops.
The team behind GLiNER releases an open-source small language model aimed at making safety moderation cheaper and quicker to run.
Cactus Compute distilled Gemini's tool-calling behavior into a tiny model meant to run locally.
The 1.8 billion-parameter model from the Chinese tech giant is designed for high-quality translation across a wide range of language pairs.
Moonshot AI's open-weights mixture-of-experts model reportedly outperformed Claude, GPT-5.5, and Gemini on a programming challenge.
The new 26-billion-parameter model from DeepMind uses a mixture-of-experts design for greater efficiency and is tuned for assistant-style tasks.
The new 31-billion-parameter model is an instruction-tuned, 'any-to-any' powerhouse released under a permissive Apache 2.0 license.
The new 4-billion-parameter model is instruction-tuned for 'any-to-any' tasks, handling a flexible mix of data types.
The new compact model from DeepMind is instruction-tuned for "any-to-any" tasks, capable of processing and generating mixed data types.
The new flagship model combines a Mixture-of-Experts architecture with a permissive MIT license, positioning it for wide commercial adoption.
The new Mixture of Experts model from the Beijing-based AI lab is optimized for fast, efficient conversational AI and carries a fully permissive license.
The new dense model, licensed under Apache 2.0, brings both text and image understanding to the midrange parameter space.
The new Qwen3.6-35B-A3B from Alibaba's Qwen team combines vision and language capabilities using an efficient sparse architecture.
The Chinese AI lab has published weights for its new vision-language model, though a restrictive license limits its use to research applications.
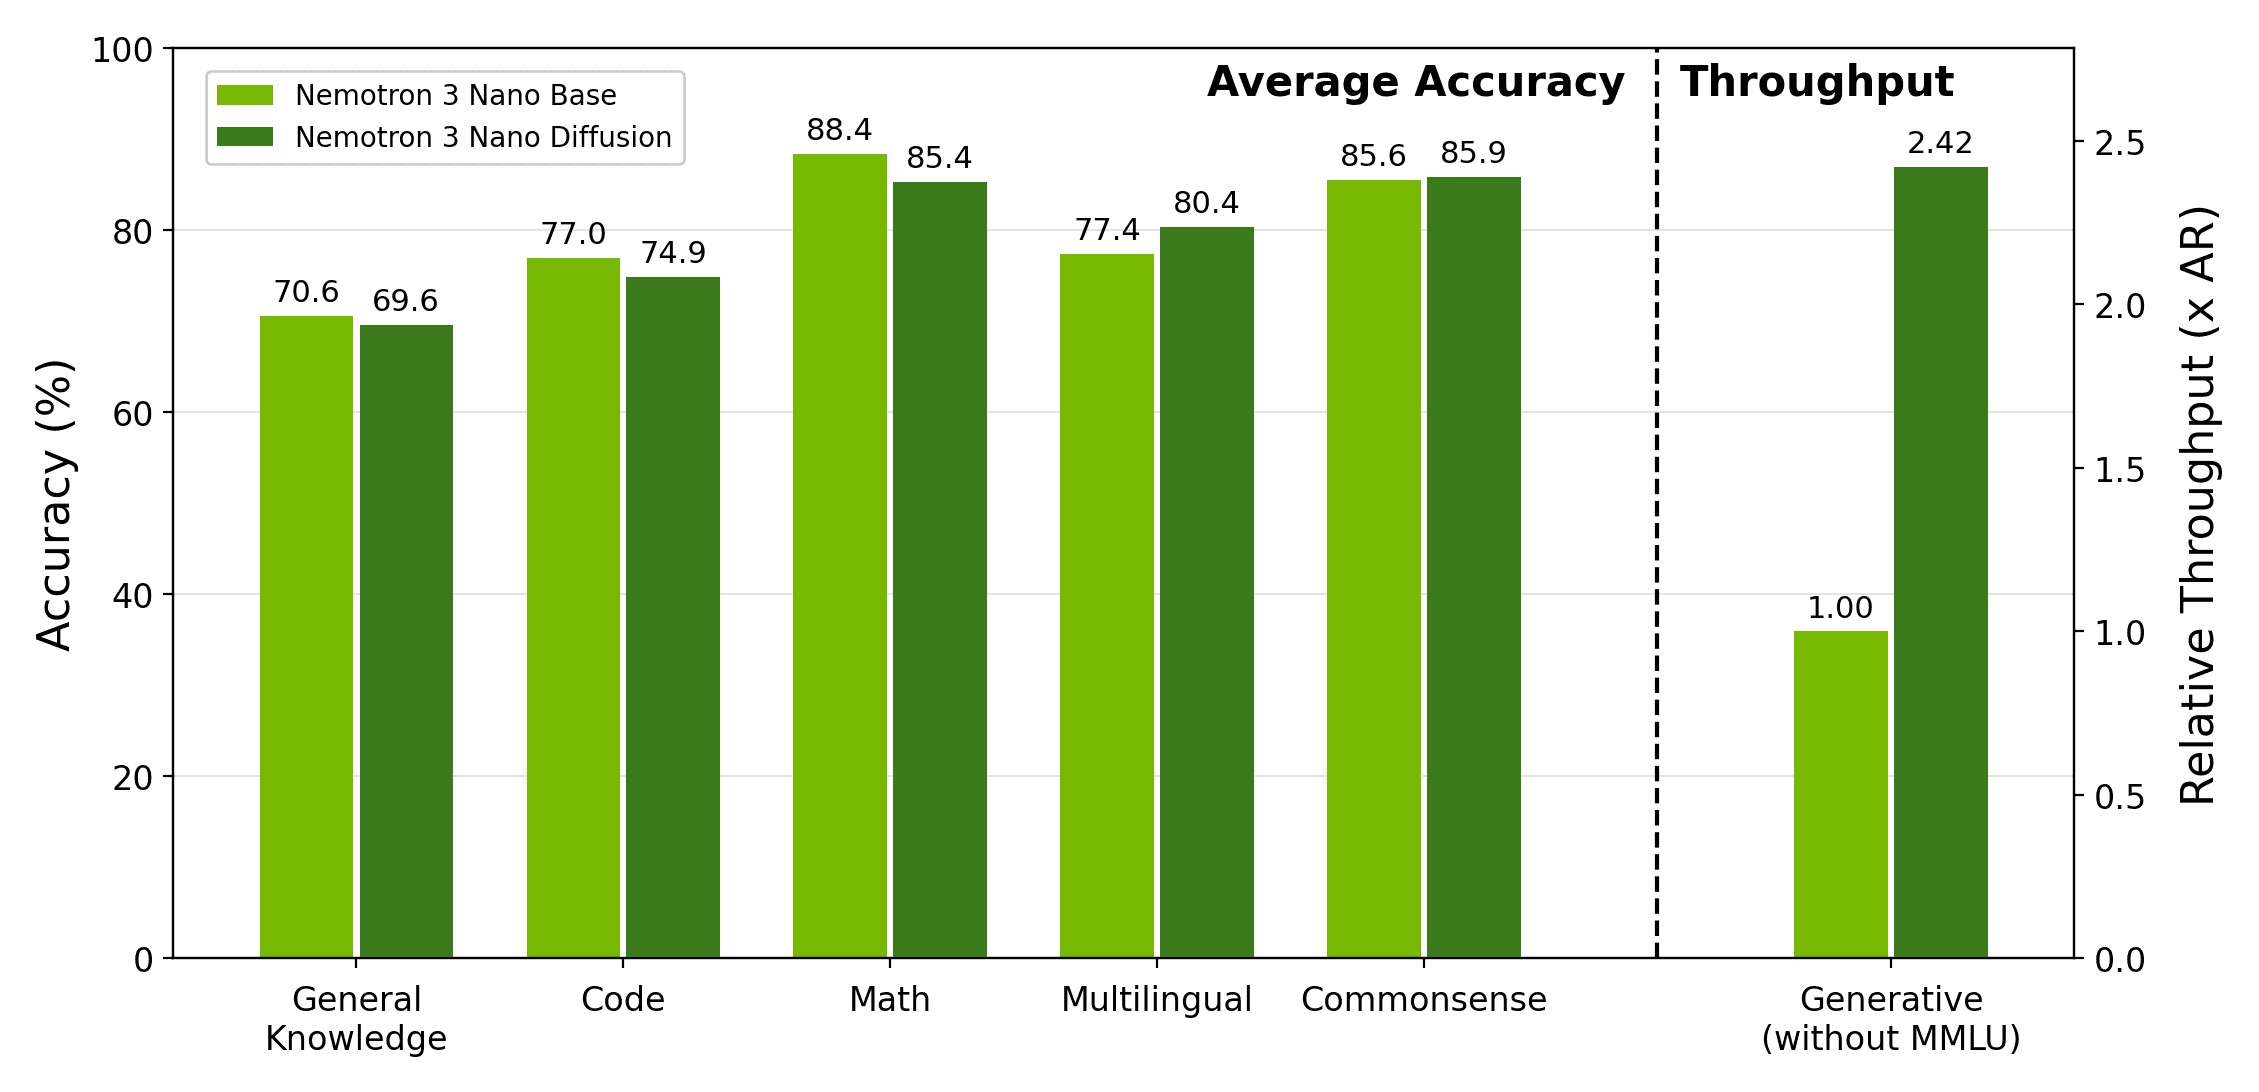
A new 30B mixture-of-experts base model activates just 3B parameters per token and pairs a hybrid diffusion/Mamba design.
An experimental 30B mixture-of-experts base model blends diffusion and Mamba ideas under a two-tower design.
The new conversational language model from the Chinese AI company uses a Mixture-of-Experts architecture and 8-bit weights, but is released under a restrictive custom license.
The new bilingual model from the Chinese AI firm features an efficient Mixture-of-Experts architecture and a fully permissive MIT license.
The Chinese tech company has released the weights for a unified model that can process and generate combinations of text, images, audio, and video.
Cactus Compute's tiny encoder-decoder is distilled specifically for function calling at the edge, trading general chat for a narrow, useful job.
The new open-source model from DeepMind uses a Mixture-of-Experts architecture to handle both text and image inputs efficiently.
The new 31-billion-parameter model is instruction-tuned and can process both text and images, marking a significant expansion for the Gemma family.
The new 2-billion-parameter model from Google DeepMind brings efficient image-and-text understanding to the open-source Gemma family.
The new 2-billion-parameter model from DeepMind can process text, vision, and audio, making it a versatile and efficient foundation for developers.
The new 4-billion-parameter vision-language model brings image and text understanding to Google's popular open-source family.
The new 4-billion parameter model from Google DeepMind is designed for versatile input and output, handling text, images, and other data types.
The new 800-million-parameter model is the smallest in the Qwen3.5 family, designed for efficient multimodal tasks on consumer-grade hardware.
The new Qwen3.5-4B model combines text and image understanding in a compact, permissively licensed package for developers.
The new open-source vision-language model from Alibaba's Qwen team offers strong performance in a compact, Apache 2.0-licensed package.
The new Qwen3.5-122B-A10B combines a massive parameter count with an efficient Mixture-of-Experts architecture for advanced vision and language tasks.
The new model from Alibaba's Qwen team combines multimodal understanding with a 131K token context window under a permissive Apache 2.0 license.
The new Qwen3.5-35B-A3B model from Alibaba combines vision and language capabilities with a resource-friendly Mixture of Experts design.
The new open-source model from Alibaba uses a Mixture-of-Experts architecture to balance massive scale with efficient inference.
The Chinese AI company's first open-weight release uses an efficient FP8 data type but comes with a restrictive, non-commercial license.
The new Mixture-of-Experts model from the Chinese AI company combines an advanced architecture with a fully permissive MIT license for commercial use.
The new Llama-based model was trained from scratch on 3.5 trillion tokens of Chinese and English data to enhance its bilingual capabilities.
The new model from Alibaba's Qwen team uses a Mixture-of-Experts architecture and is released under the commercially-friendly Apache 2.0 license.
The new Mixture-of-Experts model from the Beijing-based AI company is optimized for speed and released under the permissive MIT license.
The new 4B-parameter model is an instruction-tuned variant of Gemma, designed specifically for high-quality multilingual translation tasks.
The new vision-language model from the Chinese AI firm uses a Mixture-of-Experts architecture and is now available on Hugging Face.
The new Mixture of Experts model from the Chinese AI firm uses 8-bit floating-point precision for a smaller memory footprint and faster inference.
The new Mixture-of-Experts model from DeepSeek AI combines an efficient FP8 architecture with a fully permissive license for commercial use.
The new Mixture-of-Experts model is designed for complex tasks but arrives in a custom compressed format with a restrictive license.
The Shanghai-based AI startup has released a new Mixture-of-Experts model focused on complex reasoning, coding, and agentic tasks.
The new 270-million-parameter model from Google DeepMind is fine-tuned specifically for reliable function calling and tool use.
The new Mixture-of-Experts model is available under a permissive MIT license and is optimized for complex reasoning and coding tasks.
The new Qwen3-Next model from Alibaba combines a large parameter count with an efficient MoE architecture to balance performance and computational cost.
The new DeepSeek-V3.1-Base is a massive 671-billion-parameter Mixture-of-Experts model designed for efficient, large-scale research and development.
The new ultra-compact model from DeepMind is designed for efficient performance in resource-constrained environments like mobile and web.
The new `gpt-oss-20b` is an Apache 2.0-licensed Mixture-of-Experts model designed to run efficiently on consumer-grade hardware.
The new 117-billion-parameter `gpt-oss-120b` is a Mixture-of-Experts model focused on reasoning, released under a permissive Apache 2.0 license.
The new Apache 2.0 model from Alibaba's Qwen team uses a Mixture-of-Experts architecture to deliver strong performance with only 3B active parameters.
The new flagship coding model from Alibaba's Qwen team uses a massive Mixture-of-Experts architecture and is released under a permissive Apache-2.0 license.
The new Mixture-of-Experts model combines massive scale with a fully permissive license, targeting complex reasoning and agentic applications.
The new Mixture-of-Experts model brings massive scale to the open-weights community, focusing on complex reasoning and coding tasks with a 128K context window.