The Open Weights
LatestModelsLeaderboardsCompanies
Subscribe
The Open Weights

The daily record of open-source AI. New model releases, leaderboards, and what's coming next — written for people who ship.

Refreshed every 12 hours

Discover

  • Latest releases
  • New today
  • Trending models

Browse

  • All models
  • Companies
  • Categories
  • Leaderboards

About

  • About
  • Editorial policy
  • Hardware estimates
  • RSS feed
  • llms.txt
  • Newsletter

© 2026 The Open Weights. An independent publication.

PrivacyTermsSMSAggregated by Claude · curated by humans.
New TodayMistral AI

Mistral Large 4 arrives as a trillion-param MoE

The new flagship is a sparse mixture-of-experts model with roughly 49B active parameters per token.

Oct 6, 2026
Text / LLMReasoning
Datacenter
Read the story
Parameters
1000B · MoE
Active params
49B active
License
OTHER

OpenAI/Text / LLMMulti-GPU server

Reflection releases Beam, a 501B open-weight model

The startup's first frontier-scale model ships with downloadable weights and a mixture-of-experts design aimed at reasoning.
Oct 5, 2026
DeepSeek-V4-Pro-0813
DeepSeek/Text / LLMDatacenter

DeepSeek Releases V4-Pro, an MIT-Licensed MoE Model

The company's newest flagship targets reasoning and coding while keeping a permissive open-source license.
Aug 13, 2026
Muse Glimmer 30B
Meta AI/Vision-LanguageConsumer GPU

Meta's Muse Glimmer 30B Targets Local Agentic Coding

A 30-billion-parameter multimodal model built to run locally, released under Apache 2.0 with an eye on agentic coding workflows.

Aug 10, 2026

The Weekly Weights

Every open release, in your inbox.

One concise email a week: the model launches that mattered, leaderboard shifts, and what's coming next. No noise.

The feed

Latest releases

View all
Tencent/Vision-LanguageRuns on a laptop

Tencent's Youtu-Parsing-Omni tackles docs, audio, video

A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.

Oct 9, 2026
Vision-LanguageAny-to-Any
Youtu-Parsing-Omni
Qwen · Alibaba/Text → ImageRuns on a laptop

Qwen-Image-2.1-Turbo targets faster generation

Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.

Oct 9, 2026
Text → ImageImage Editing
Qwen-Image-2.1-Turbo
Xiaomi/Vision-Language

Xiaomi's MiMo-V2.6 bets on RL for self-improvement

The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.

Oct 7, 2026
ReasoningAny-to-Any
LiquidAI/Vision-LanguageRuns anywhere

Liquid AI's d1-3B brings multimodal models to the edge

The new LFM2-based d1-3B is a compact vision-language model aimed at running decisions directly on-device.

Oct 7, 2026
Vision-Language
LFM2 d1-3B
NVIDIA/Speech → Text

TII Brings Falcon to Speech With New ASR Model

The team behind the Falcon language models expands into speech-to-text with its first automatic speech recognition release.

Oct 7, 2026
Speech → Text
IBM/Speech → Text

TII extends the Falcon family into speech recognition

The Abu Dhabi lab behind the Falcon language models releases Falcon ASR, an open speech-to-text system.

Oct 7, 2026
Speech → Text

Momentum

Trending models

View all
1

DeepSeek

DeepSeek-V3.2

Text / LLM · 4.7M downloads

+813.5K
2

Zhipu AI

GLM-5.3-Flash

Text / LLM · 6.5M downloads

+748.7K
3

Prism Ml

Ternary-Bonsai-2-27B

Text / LLM · 4.6M downloads

+494.7K
4

Thinkingmachines

Inkling

Any-to-Any · 1.1M downloads

+220.3K
5

Qwen · Alibaba

Qwen3.8-27B

Vision-Language · 3.6M downloads

+170.1K

Benchmarks

Open LLM leaderboard

All boards
#ModelAvg.
1
MaziyarPanahi/calme-3.2-instruct-78b
52.1
2
MaziyarPanahi/calme-3.1-instruct-78b
51.3
3
dfurman/CalmeRys-78B-Orpo-v0.1
51.2
4
MaziyarPanahi/calme-2.4-rys-78b
50.8
5
huihui-ai/Qwen2.5-72B-Instruct-abliterated
48.1
6
Qwen/Qwen2.5-72B-Instruct
Qwen · Alibaba
48.0
By type

Newest in each category

View all
Text → Image →
Qwen-Image-2.1-Turbo
Qwen · Alibaba/Text → ImageRuns on a laptop

Qwen-Image-2.1-Turbo targets faster generation

Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.

Oct 9, 2026
Code →
MiMo-V2.6
Xiaomi/Vision-LanguageRuns on a laptop

Xiaomi distills MiMo V2.6 into a 9B model

The new MiMo-V2.6-Distill-Qwen-9B targets agentic workloads, coding, and tool use in a size that fits on modest hardware.

Sep 21, 2026
Text → Video →
Unknown/Text → VideoConsumer GPU

Kandinsky 6.0 Generates Video and Audio Together

Kandinsky Lab's new foundation models produce synchronized sound and motion from a text prompt, in 3B and 29B sizes.
Oct 3, 2026
Vision-Language →
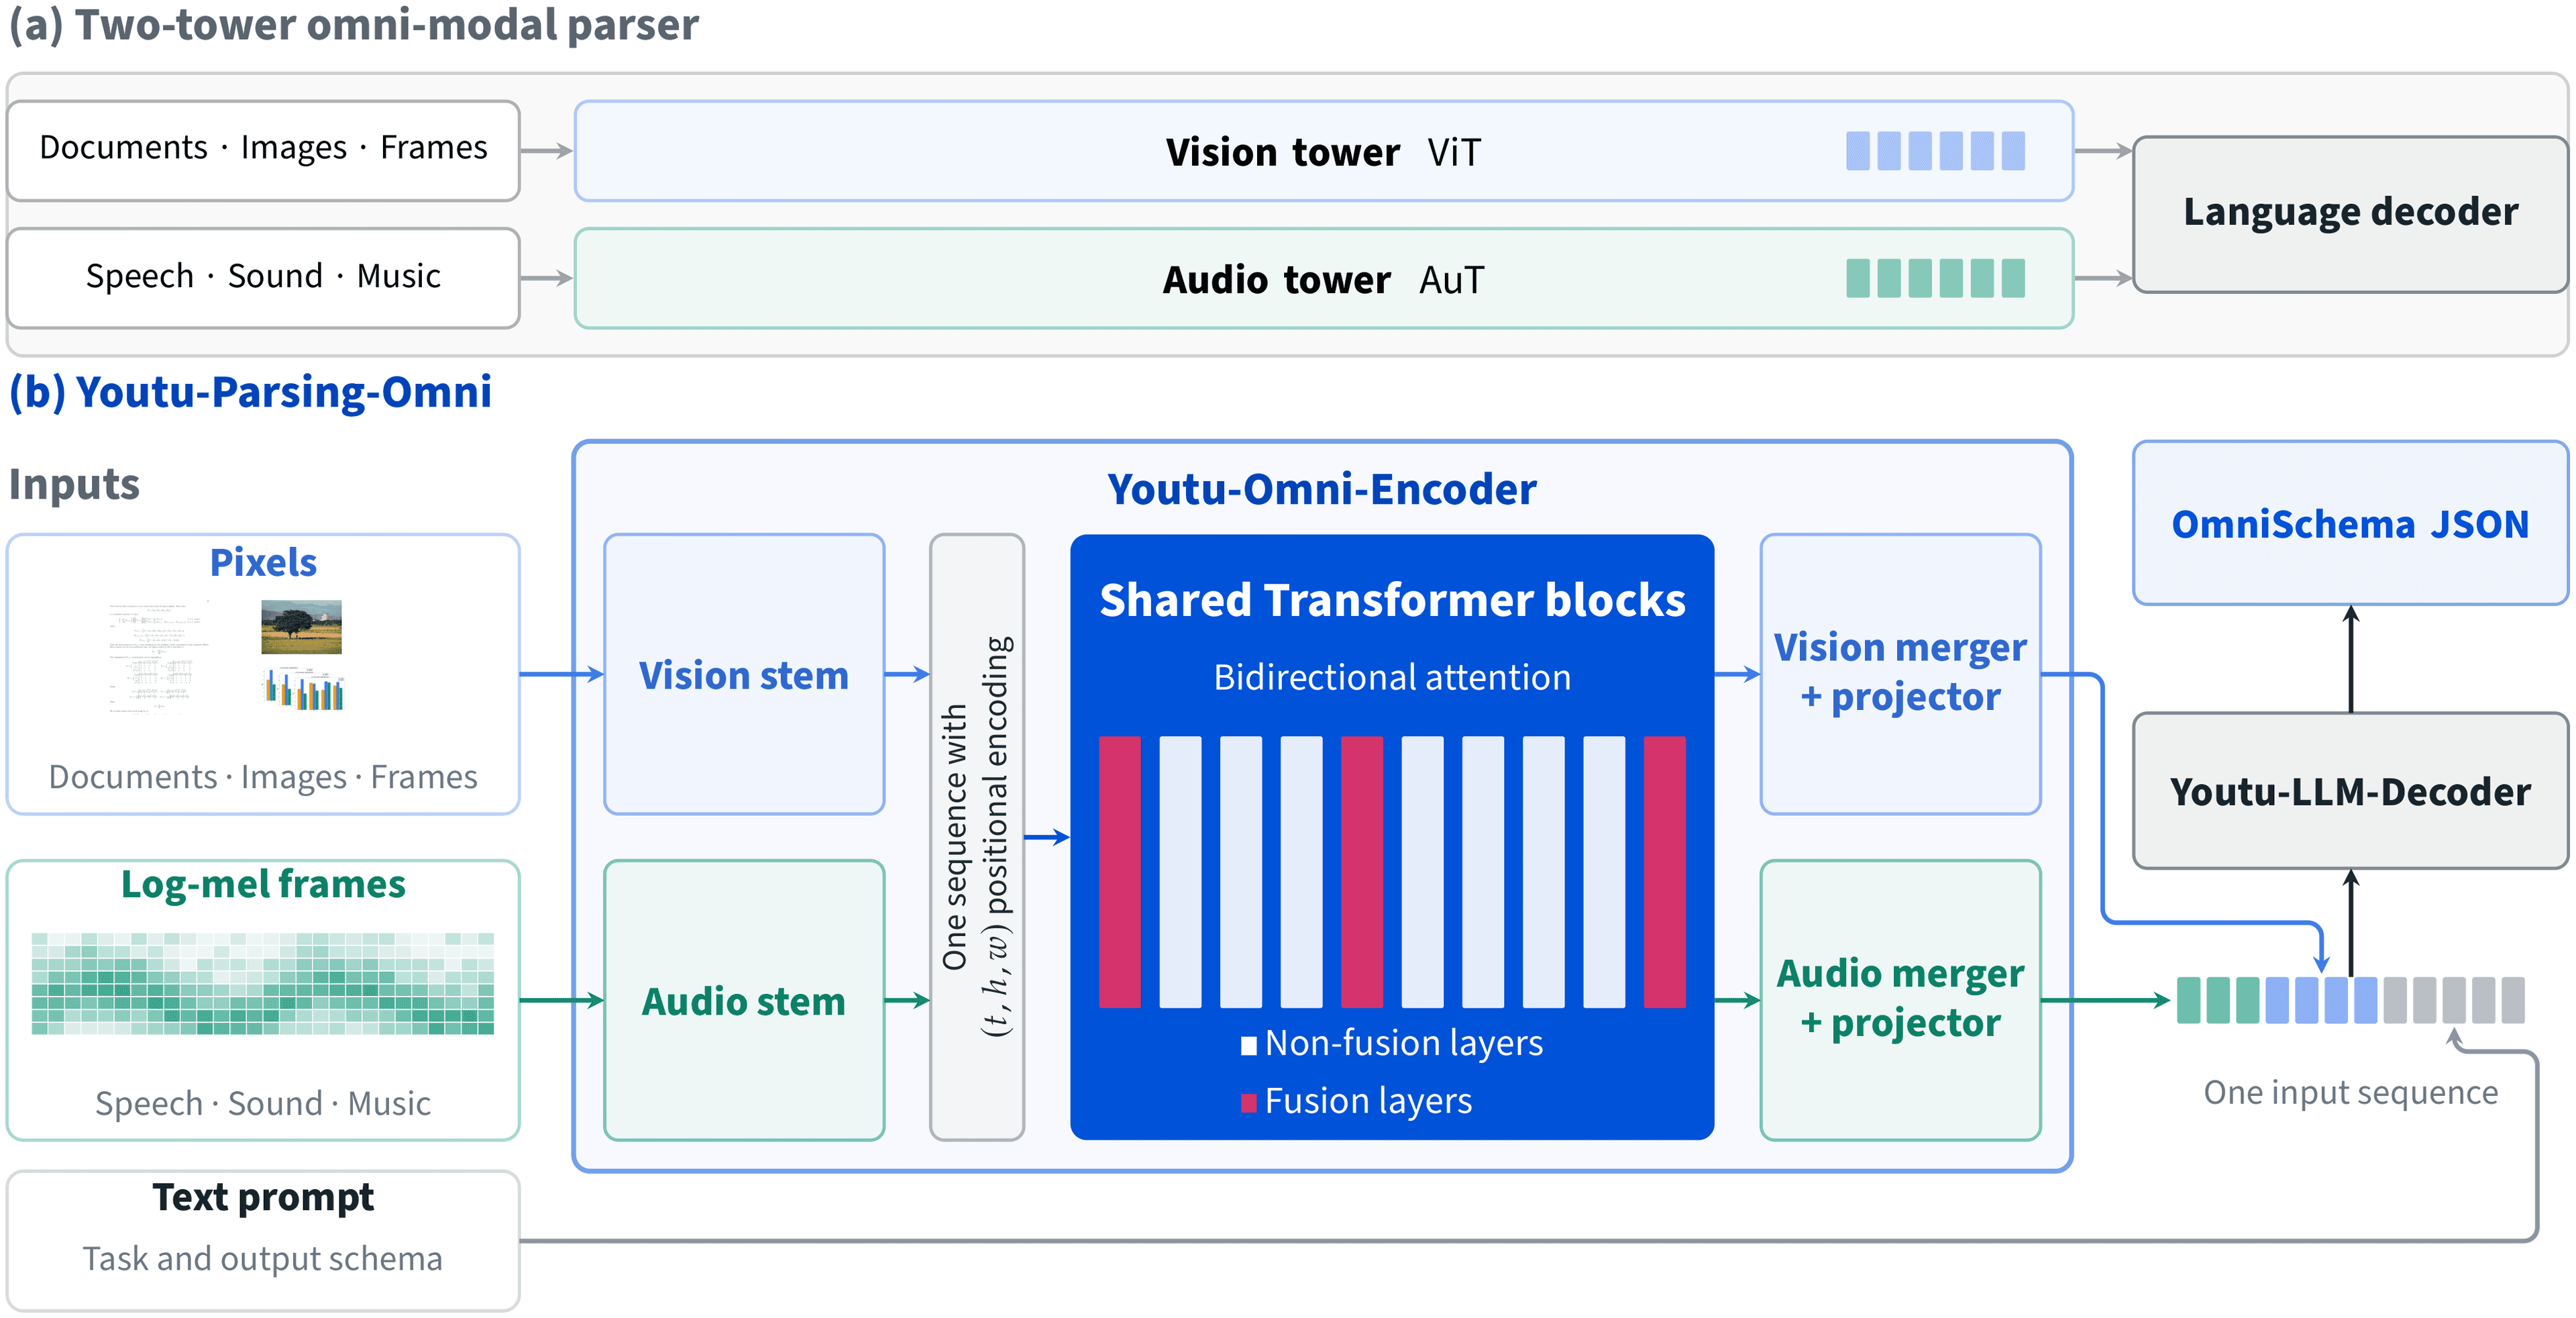
Youtu-Parsing-Omni
Tencent/Vision-LanguageRuns on a laptop

Tencent's Youtu-Parsing-Omni tackles docs, audio, video

A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.

Oct 9, 2026
On the horizon

Upcoming launches

View all
AnnouncedAug 26, 2026

Qwen Teases 3.8-Flash-Next, a 125B Sparse MoE

Alibaba's next Qwen release pairs a large parameter pool with a tiny active footprint, promising speed without the full compute bill.

Qwen · Alibaba·Text / LLM
AnnouncedSep 9, 2026

DeepSeek Announces V4.1 Flash, a Cheaper Reasoning Model

The new mixture-of-experts model is billed as more capable than V4 Pro while costing less to run, and ships under an MIT license.

DeepSeek·Text / LLM
Announced

Zing-0.5 aims for playable worlds in real time

A 5B-parameter autoregressive world model blends action and text control to generate interactive environments on the fly.
Unknown·Any-to-Any