MiniMax/Vision-LanguageMulti-GPU server
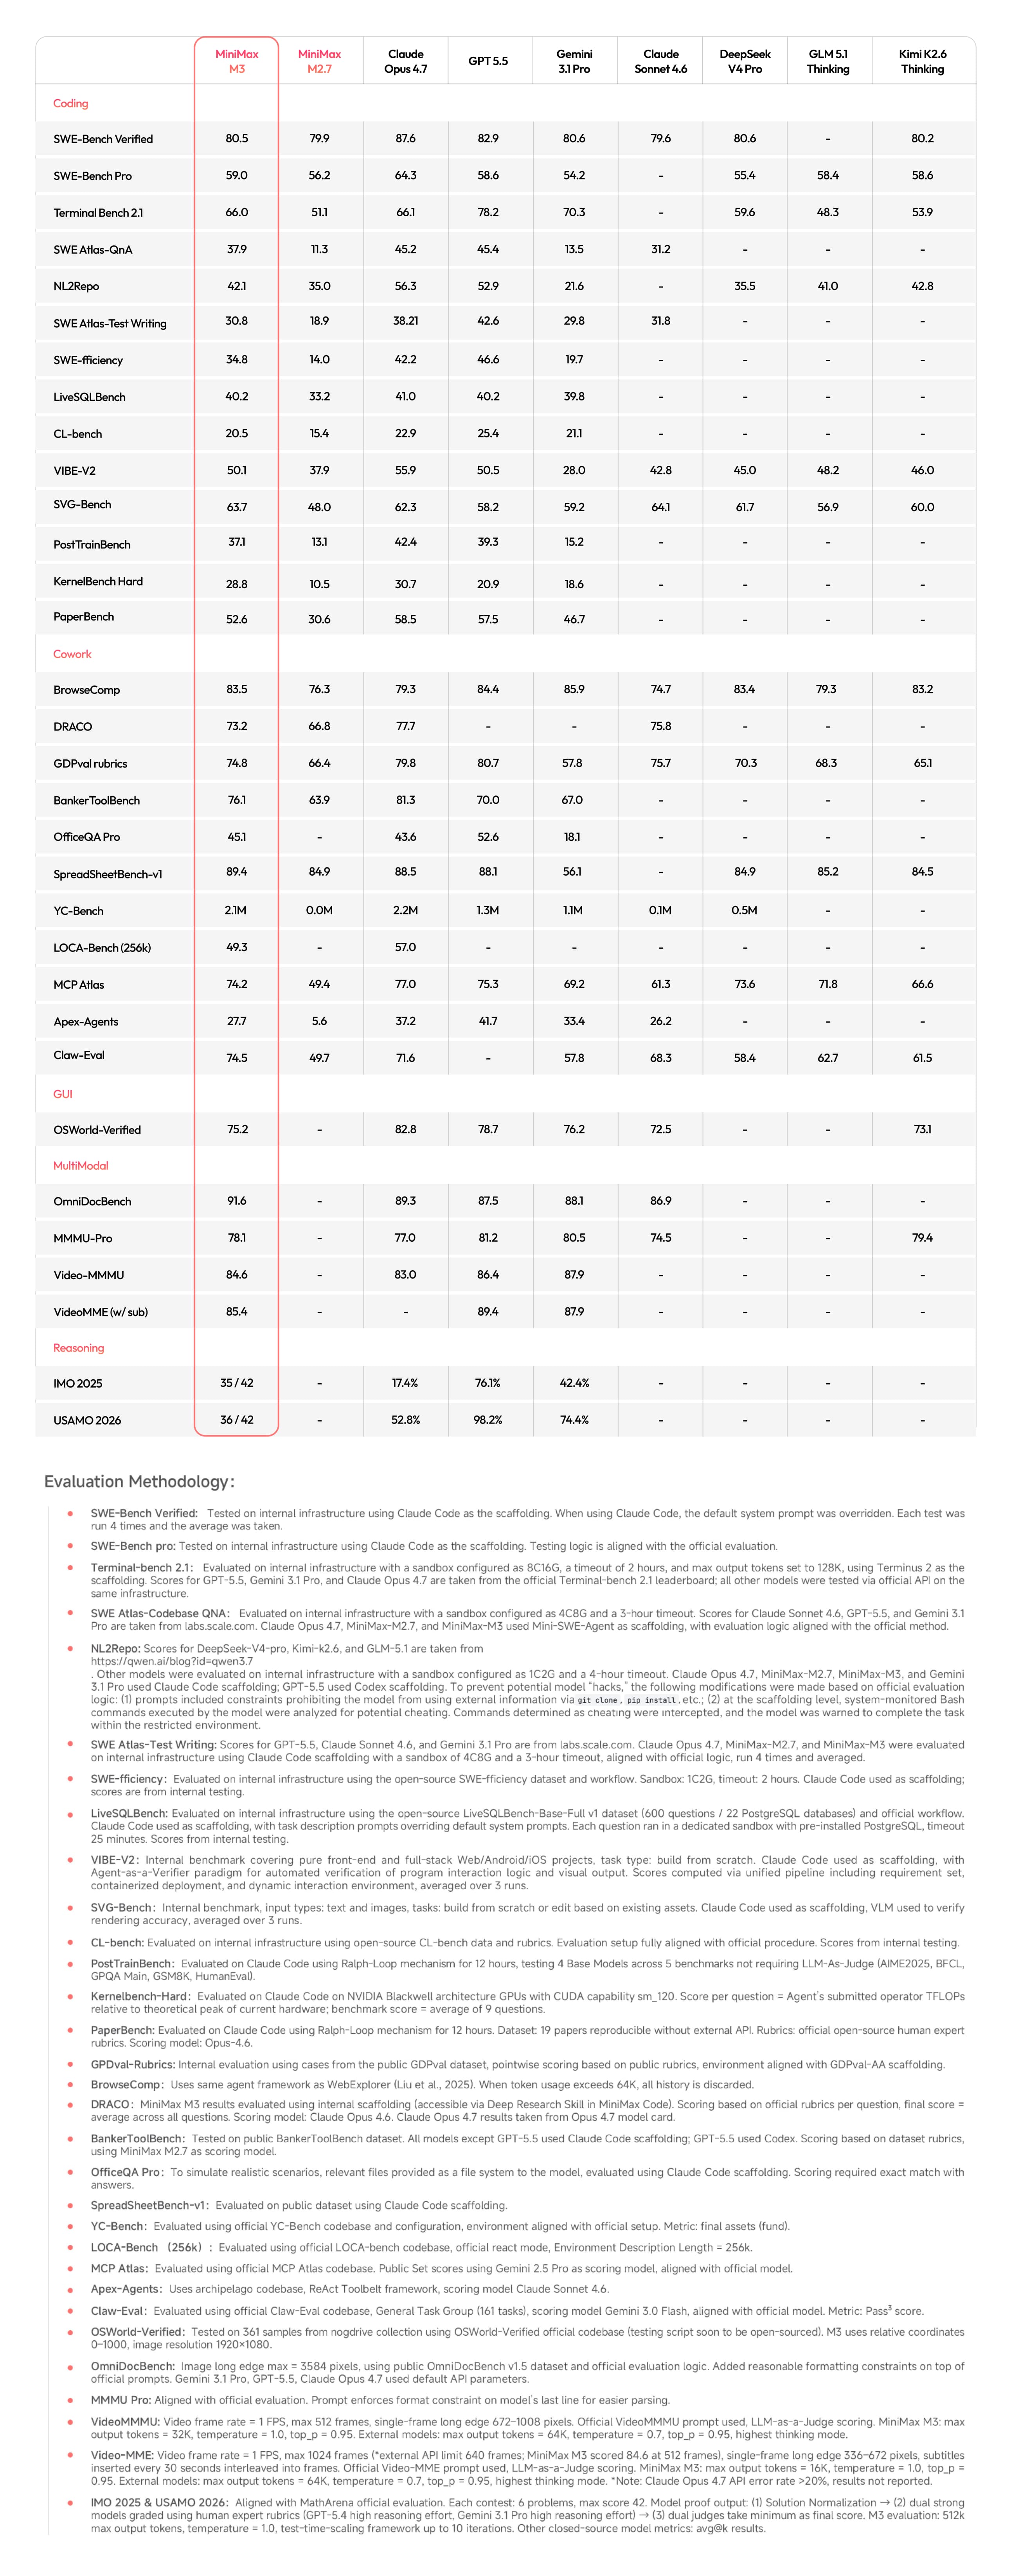
MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
Category · text
Open-weight coding models for autocomplete, refactoring, and agentic development — the engines behind self-hosted copilots and local code assistants.
37 releases
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
The open-weight model pairs a million-token context window with a focus on long-horizon code tasks.
The new open-weight model pairs a million-token context window with Meta's bet on long-horizon coding agents.
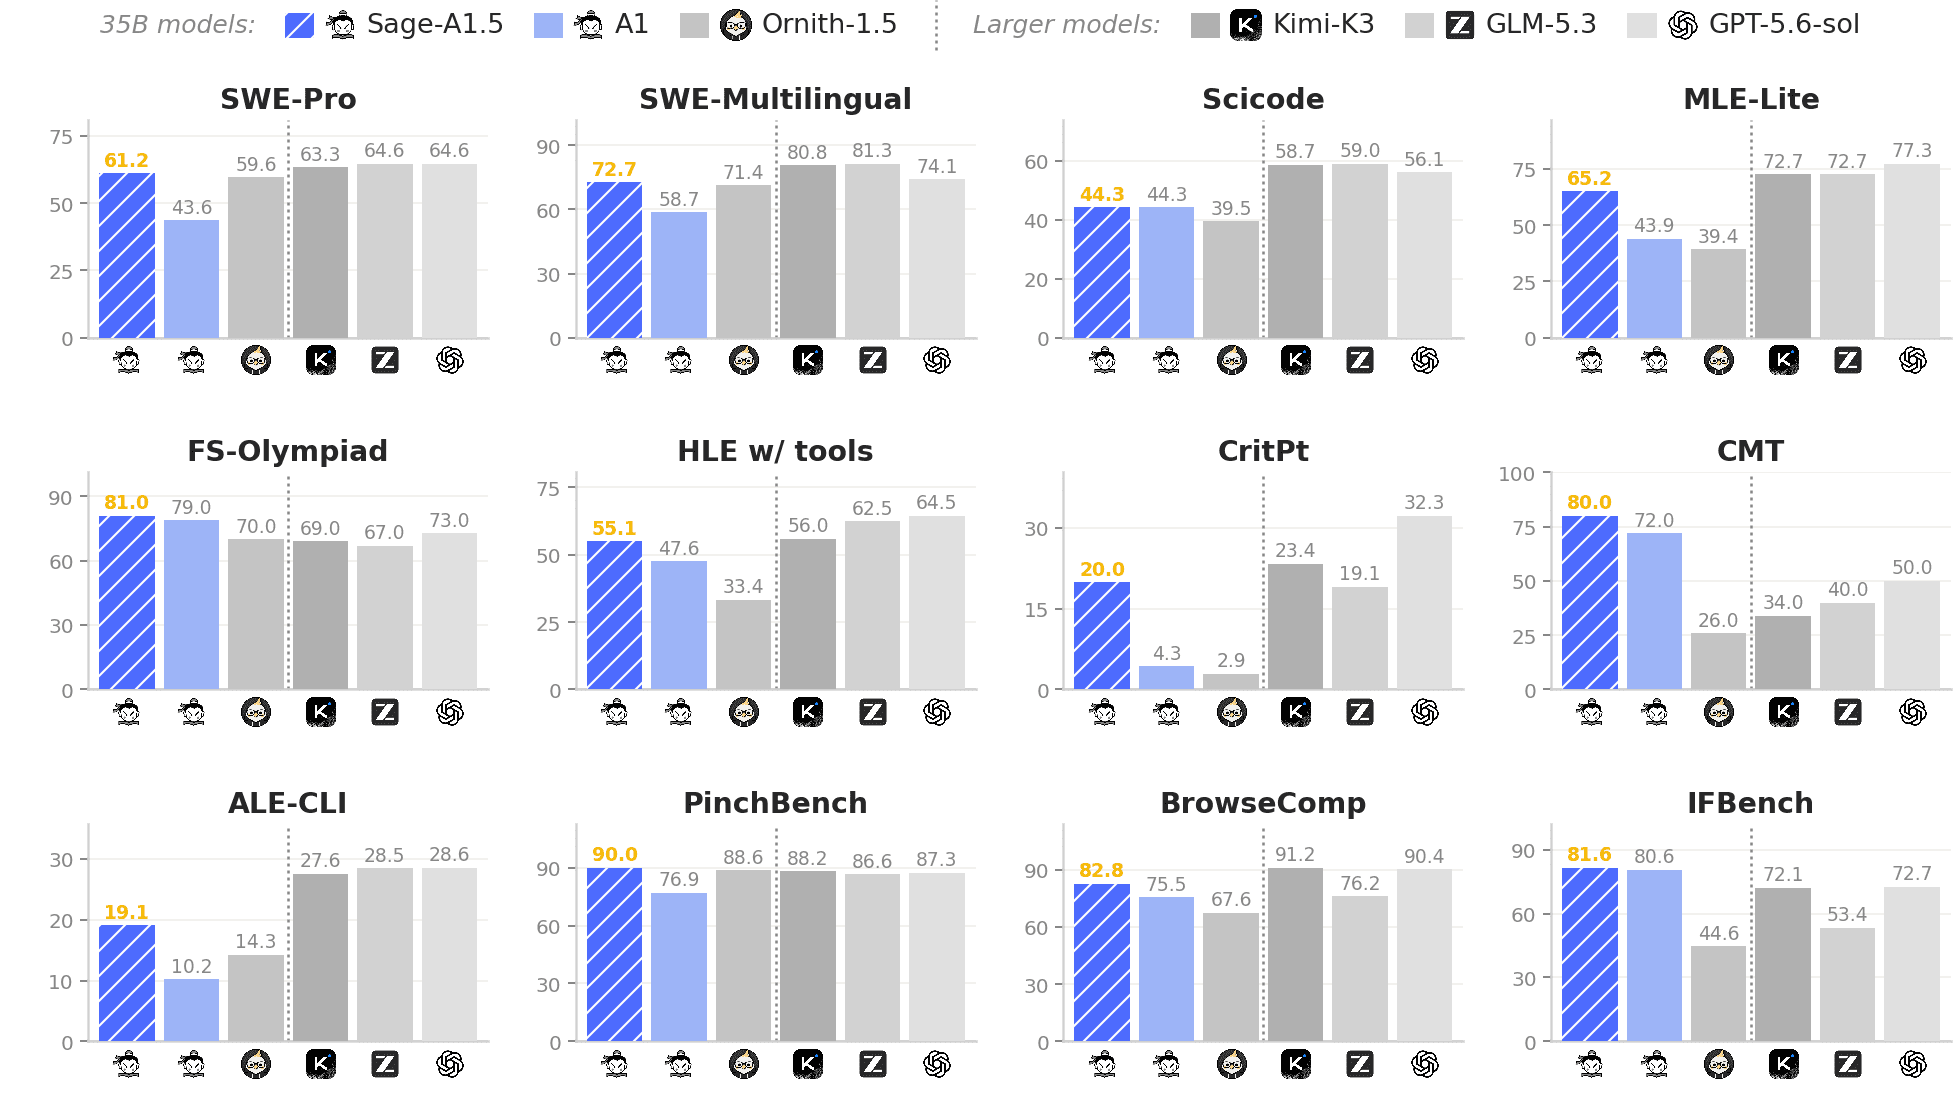
InclusionAI's new mixture-of-experts model pairs visual understanding with tool use and code, aiming at agentic workflows under an Apache 2.0 license.
The frontier AI startup's first open-weight model activates just 23B parameters per token while targeting reasoning, code, and tool use.
The new MiMo-V2.6-Distill-Qwen-9B targets agentic workloads, coding, and tool use in a size that fits on modest hardware.
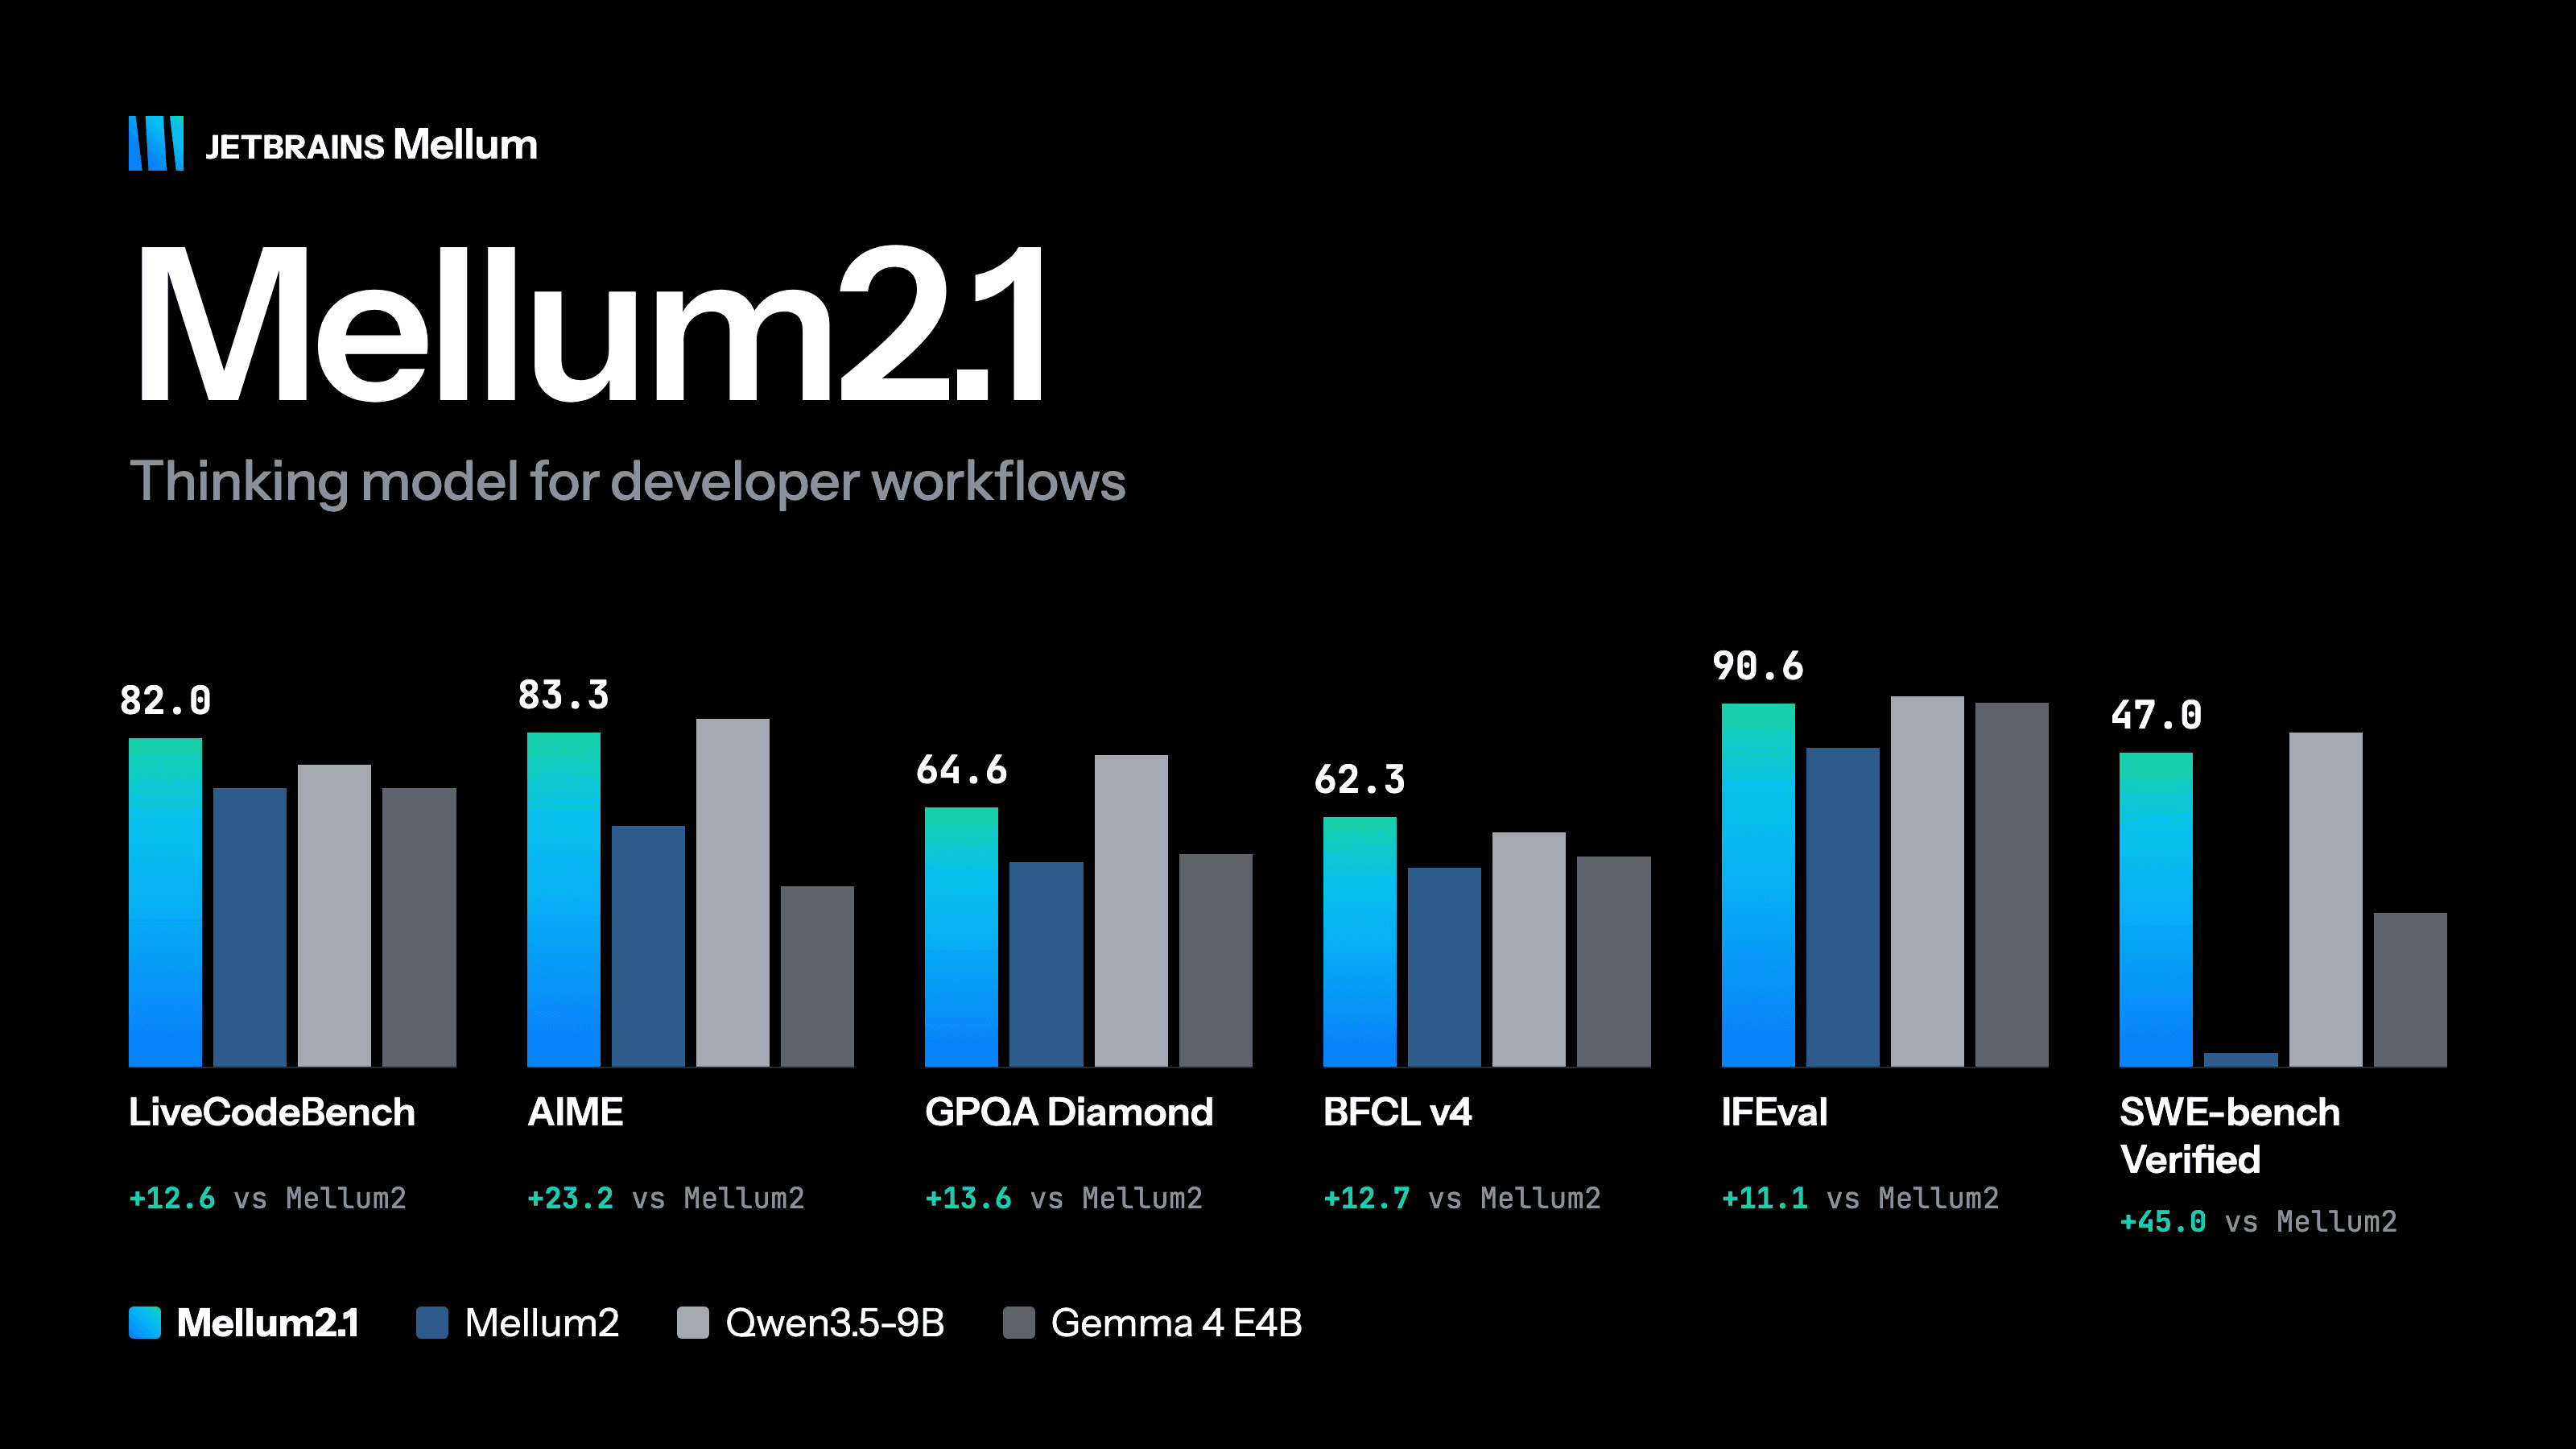
The updated Mellum packs 12B total parameters but activates just 2.5B, pairing code specialization with a new thinking mode under Apache-2.0.
Cactus Compute's 8–29MB models aim to run automation and tool-calling entirely on-device, rivaling far larger cloud systems.
A 122B mixture-of-experts model trained with reinforcement learning claims state-of-the-art results on Terminal-Bench.
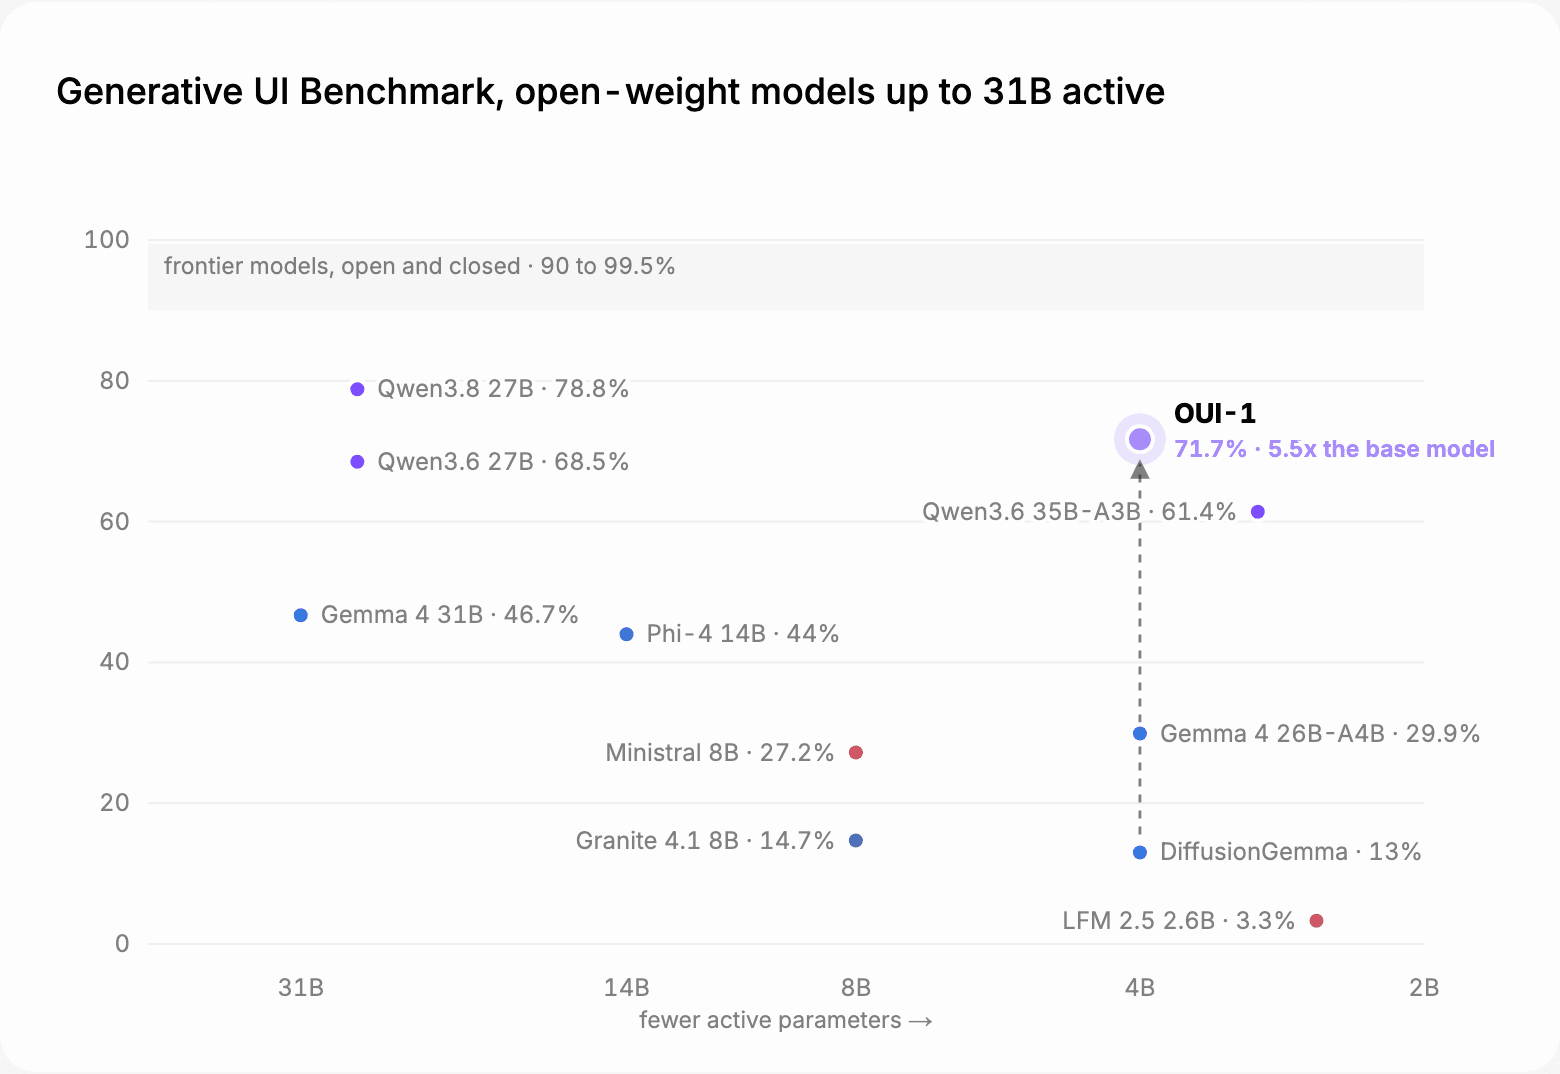
Thesys releases an experimental diffusion language model aimed at turning prompts into user interfaces, built atop Google's Gemma.
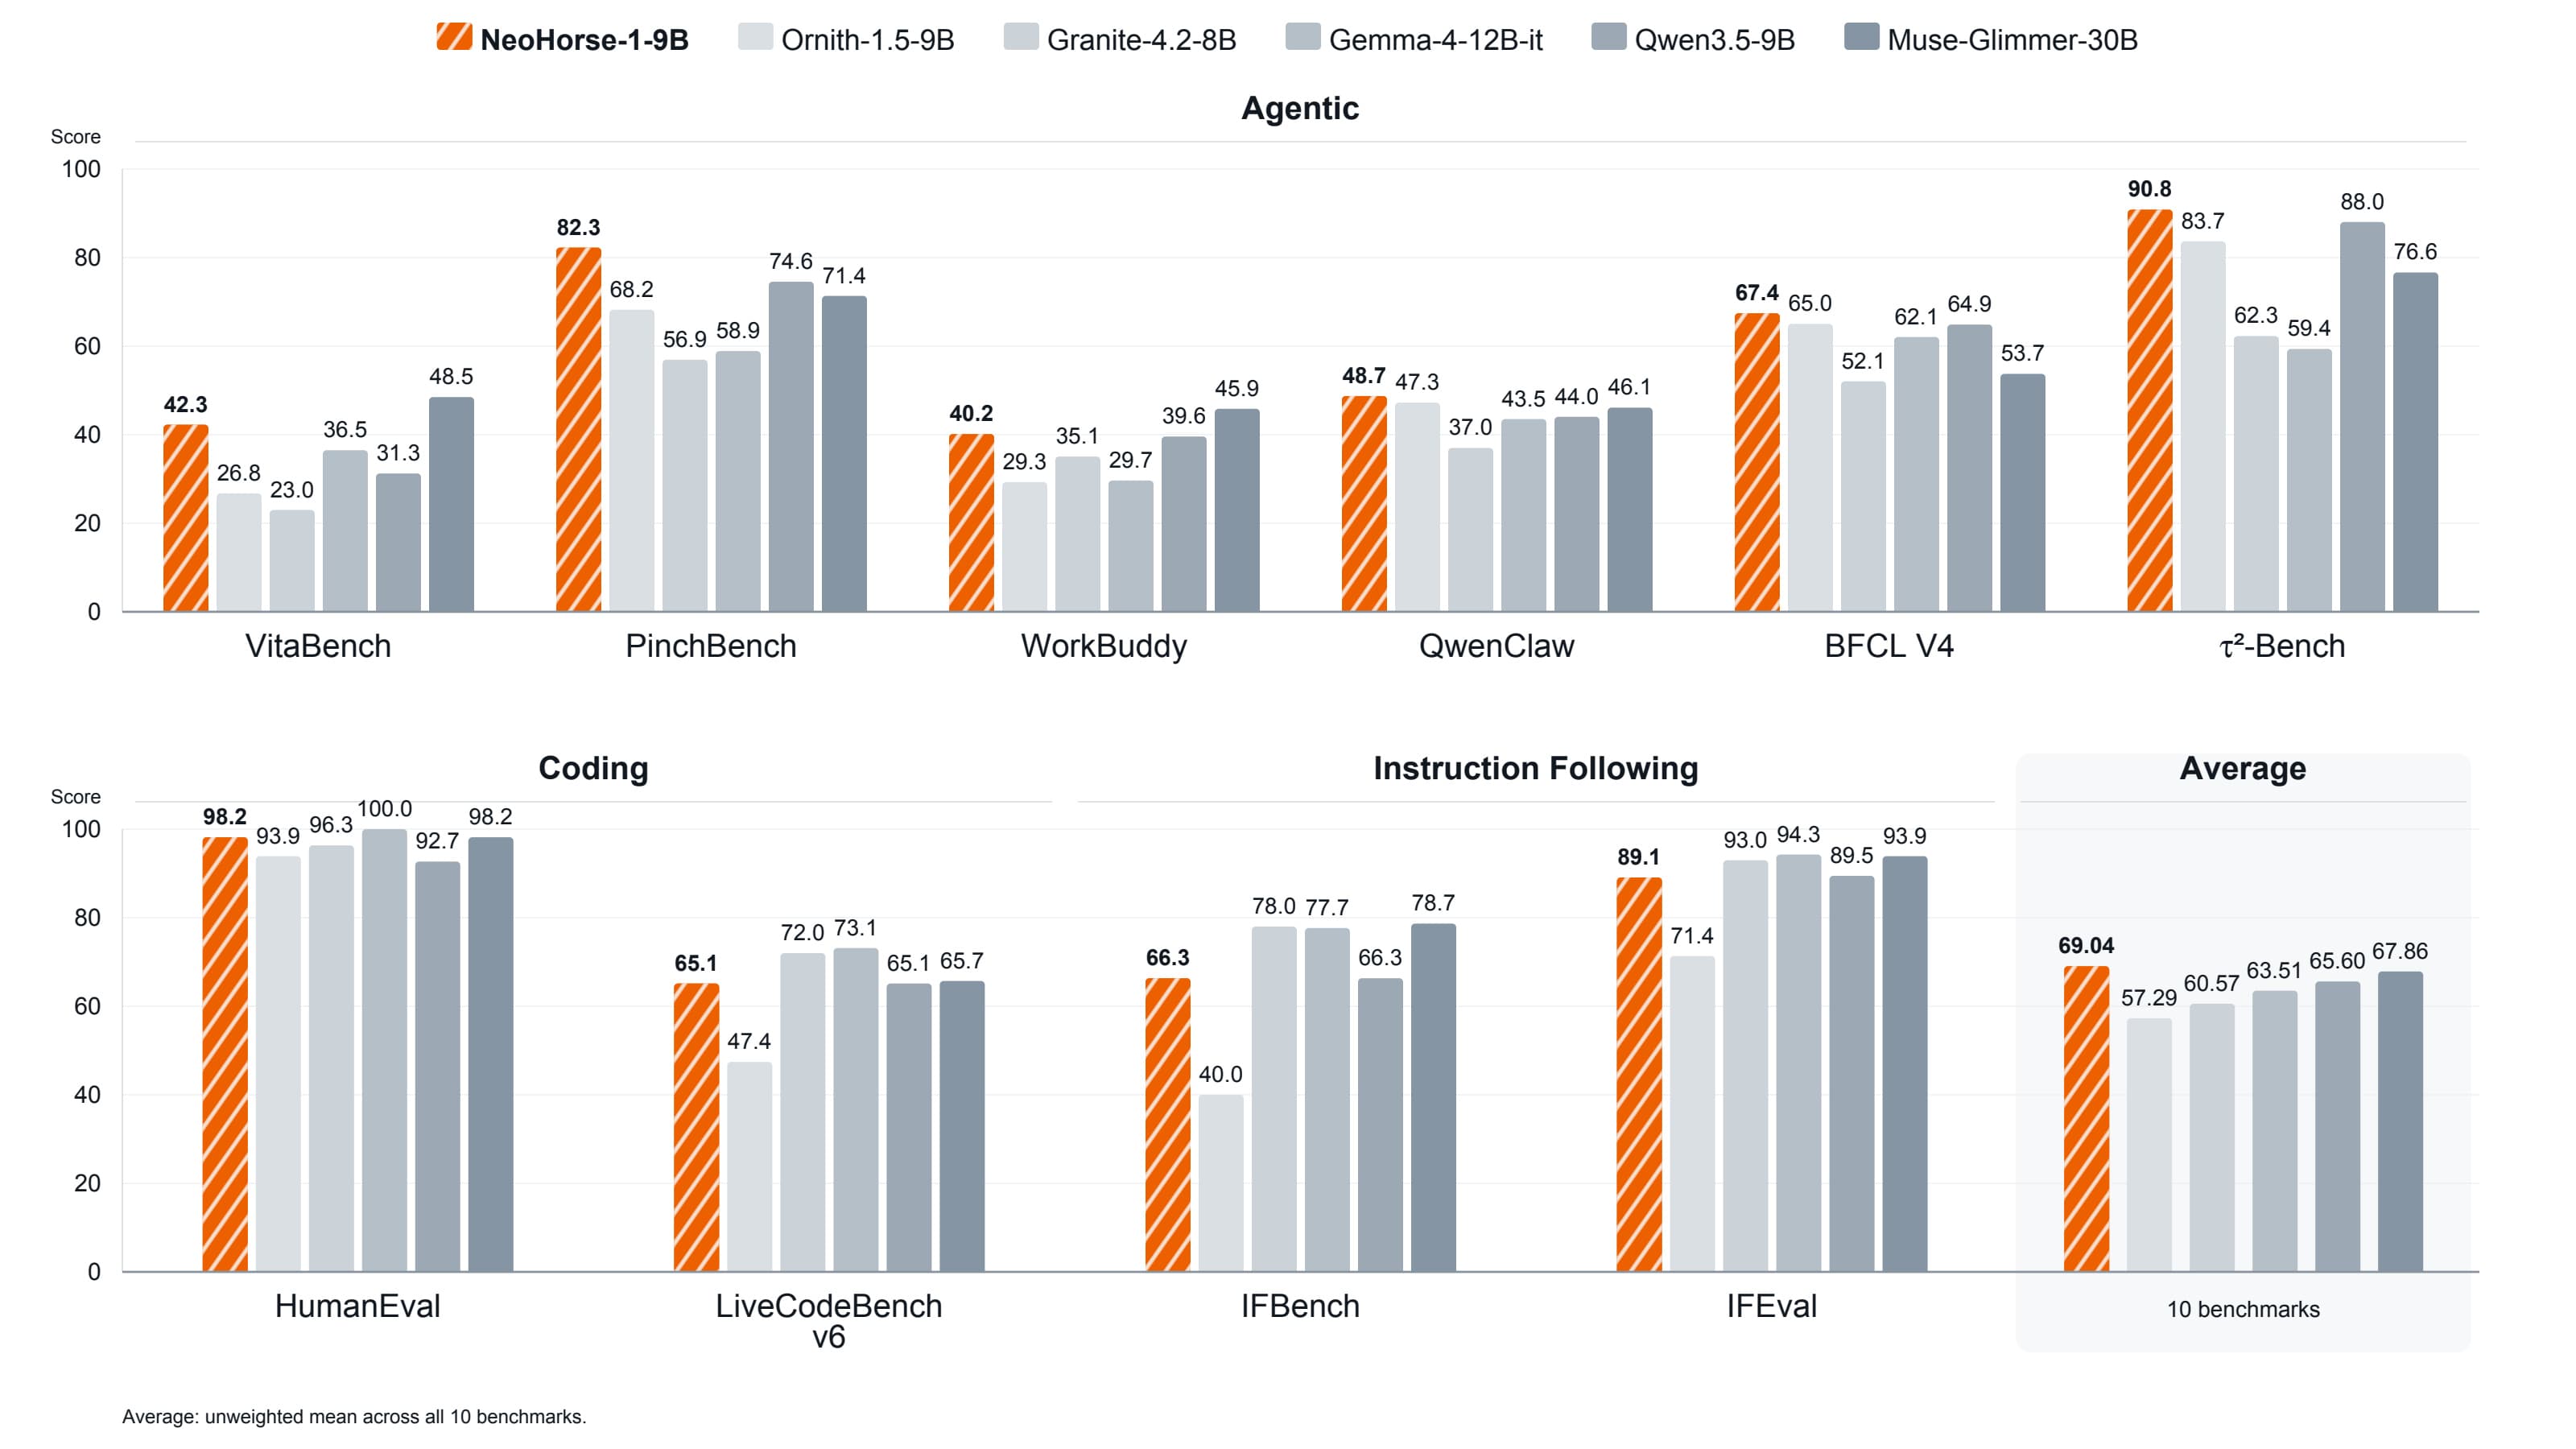
A 9-billion-parameter model built on Qwen3.5 aims squarely at tool use and code generation.
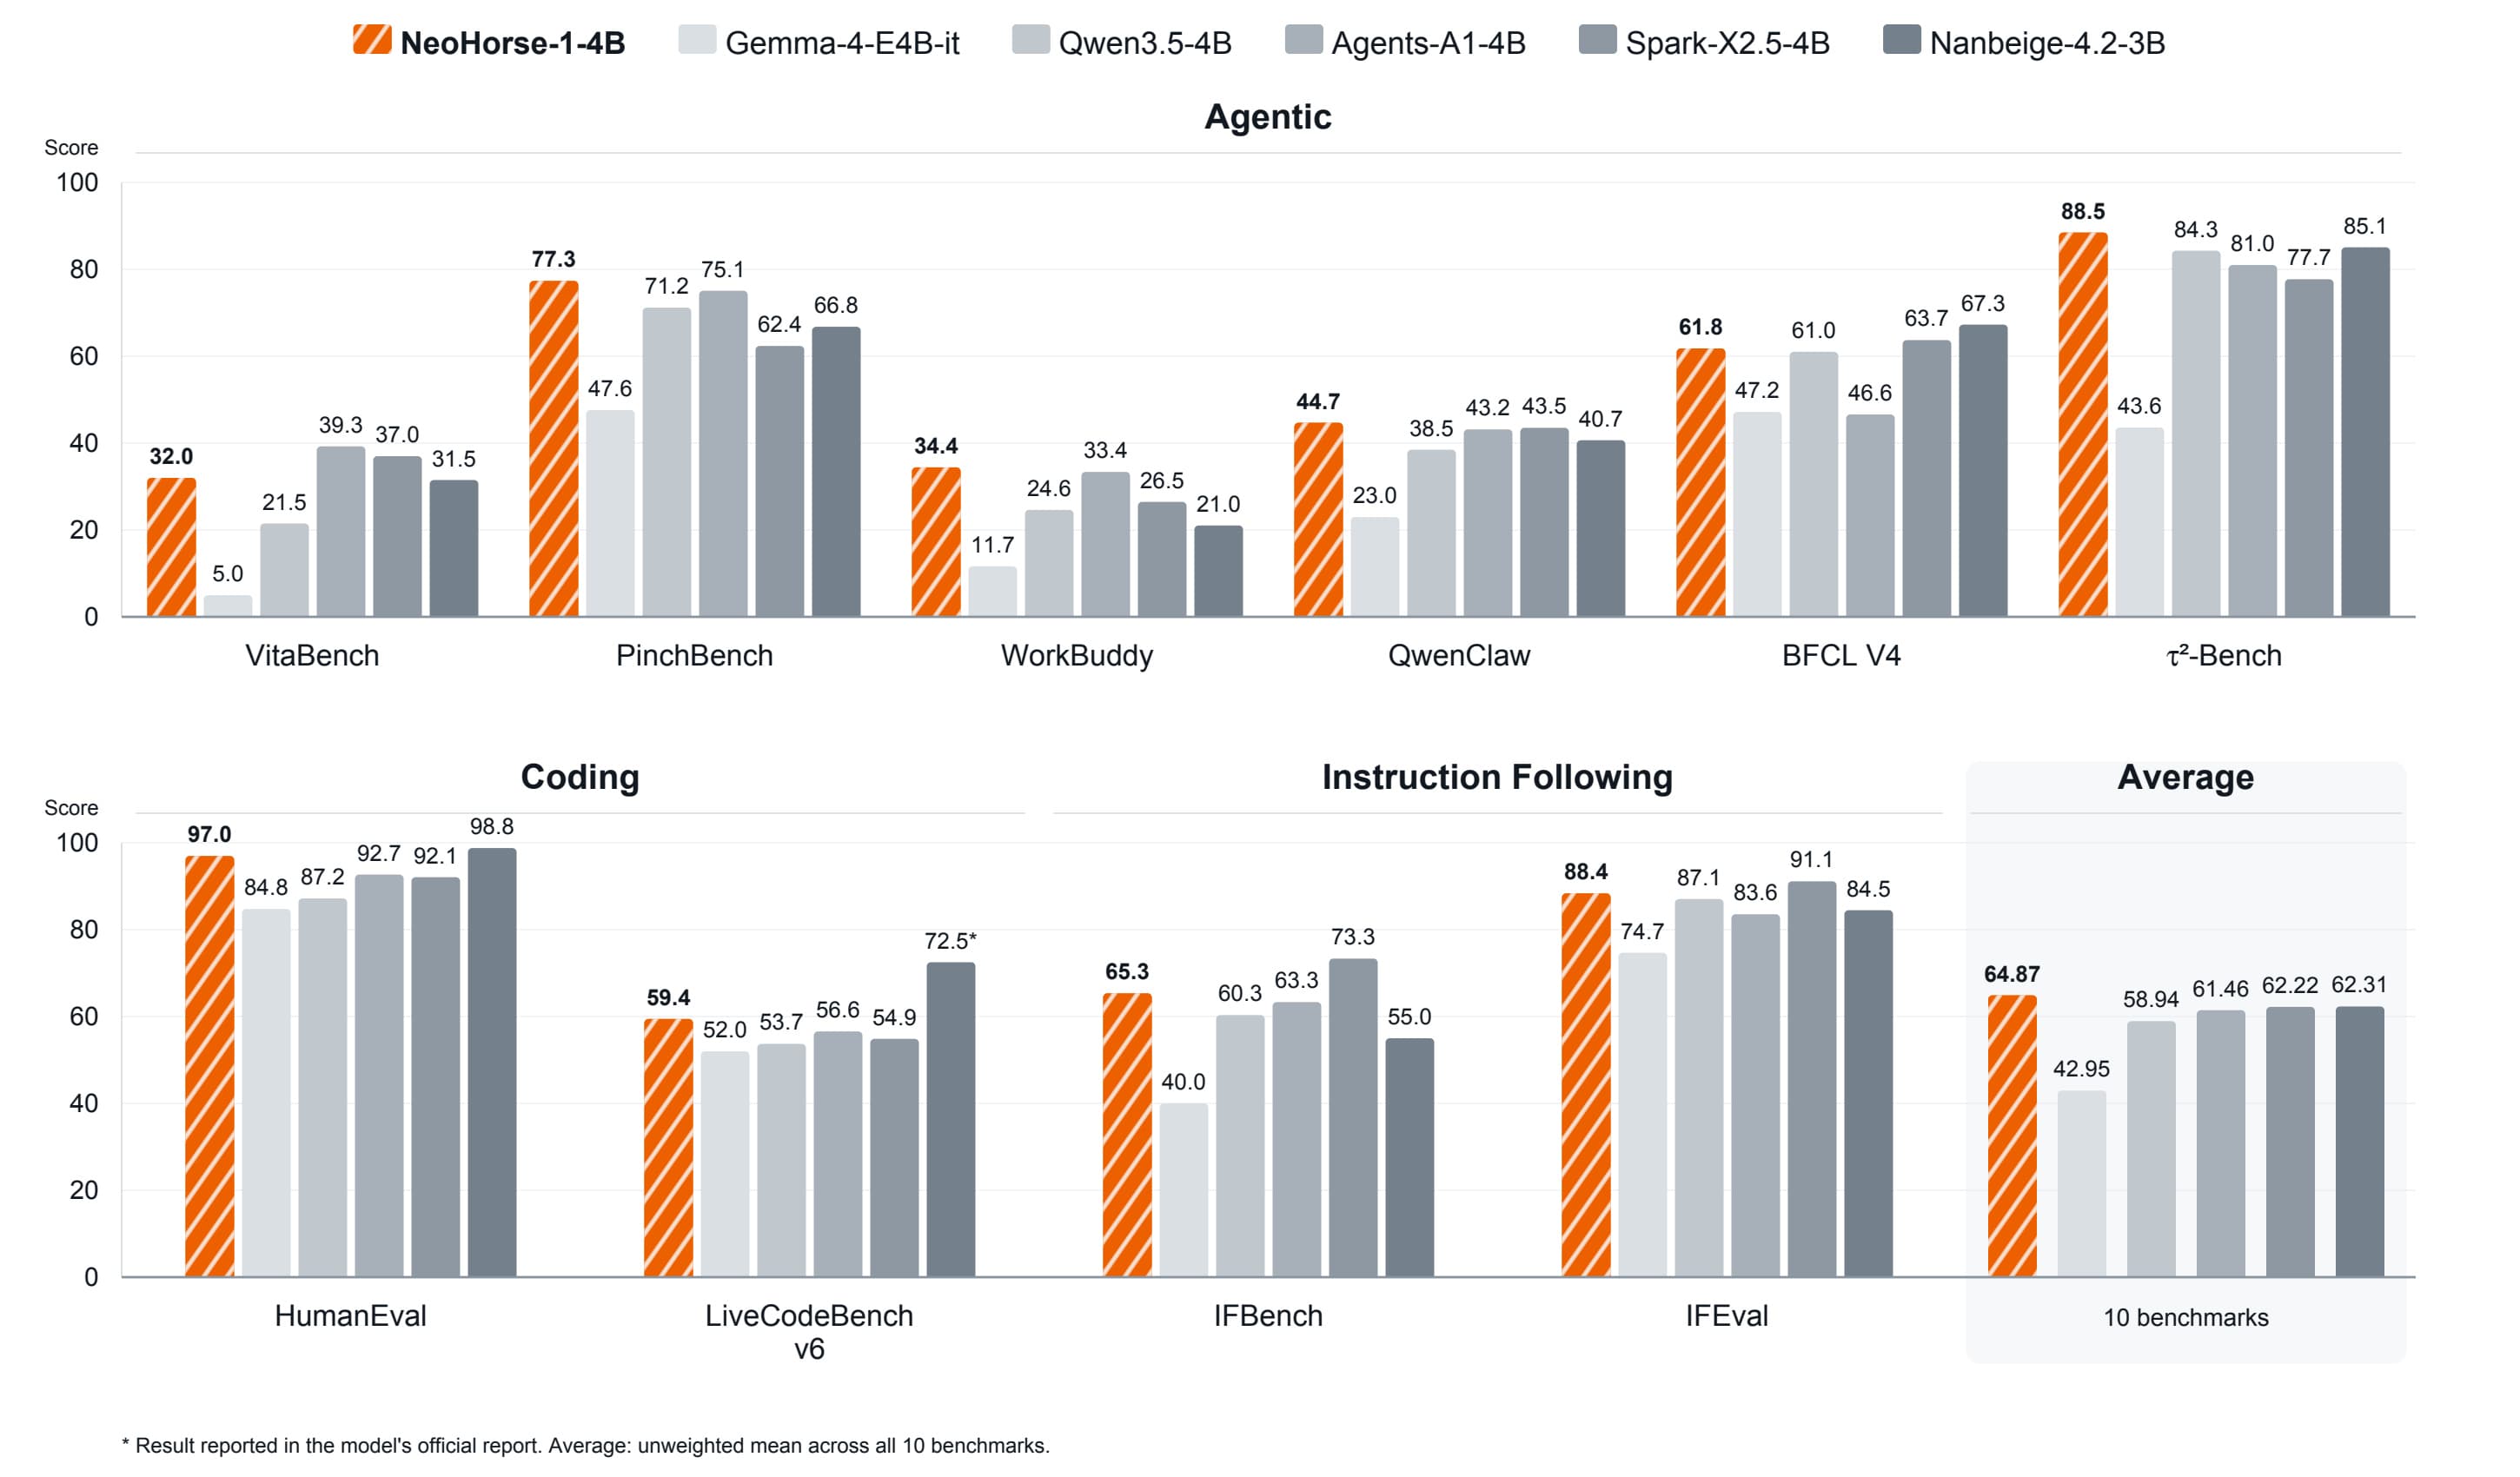
A compact 4-billion-parameter model built for tool use, coding, and multi-step reasoning arrives from TokenRhythm.
The open-weight MoE model from Zhipu AI aims to match frontier closed systems on coding tasks while undercutting them on price.
The company's newest flagship targets reasoning and coding while keeping a permissive open-source license.
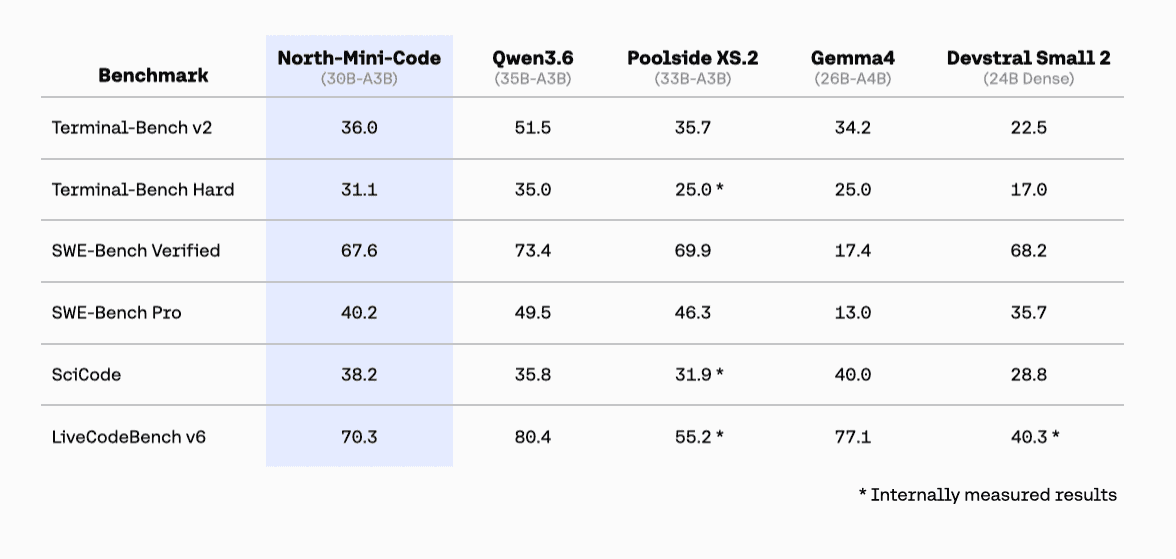
A 30-billion-parameter multimodal model built to run locally, released under Apache 2.0 with an eye on agentic coding workflows.
Motif Technologies debuts a mixture-of-experts language model built around grouped differential latent attention for long-context reasoning and code.
Cactus Compute's tiny model brings tool and function calling to phones, wearables, and robots.
Kuaishou's coding team ships an open mixture-of-experts model built on the Qwen3.5 MoE architecture and tuned for agentic development work.
The AI coding startup puts a version of its Laguna family on Hugging Face under the permissive OpenMDW license.
A compact, MIT-licensed 9B model built for autonomous coding tasks arrives on Hugging Face.
An MIT-licensed mixture-of-experts model targets self-scaffolding code tasks without the footprint of a frontier system.
The compact, code-focused language model arrives on Hugging Face under an open model license.
The AI coding startup steps into open weights with an Apache-2.0 mixture-of-experts model built for text and code.
A compact Qwen3-derived model built to explore repositories, released under a permissive MIT license.
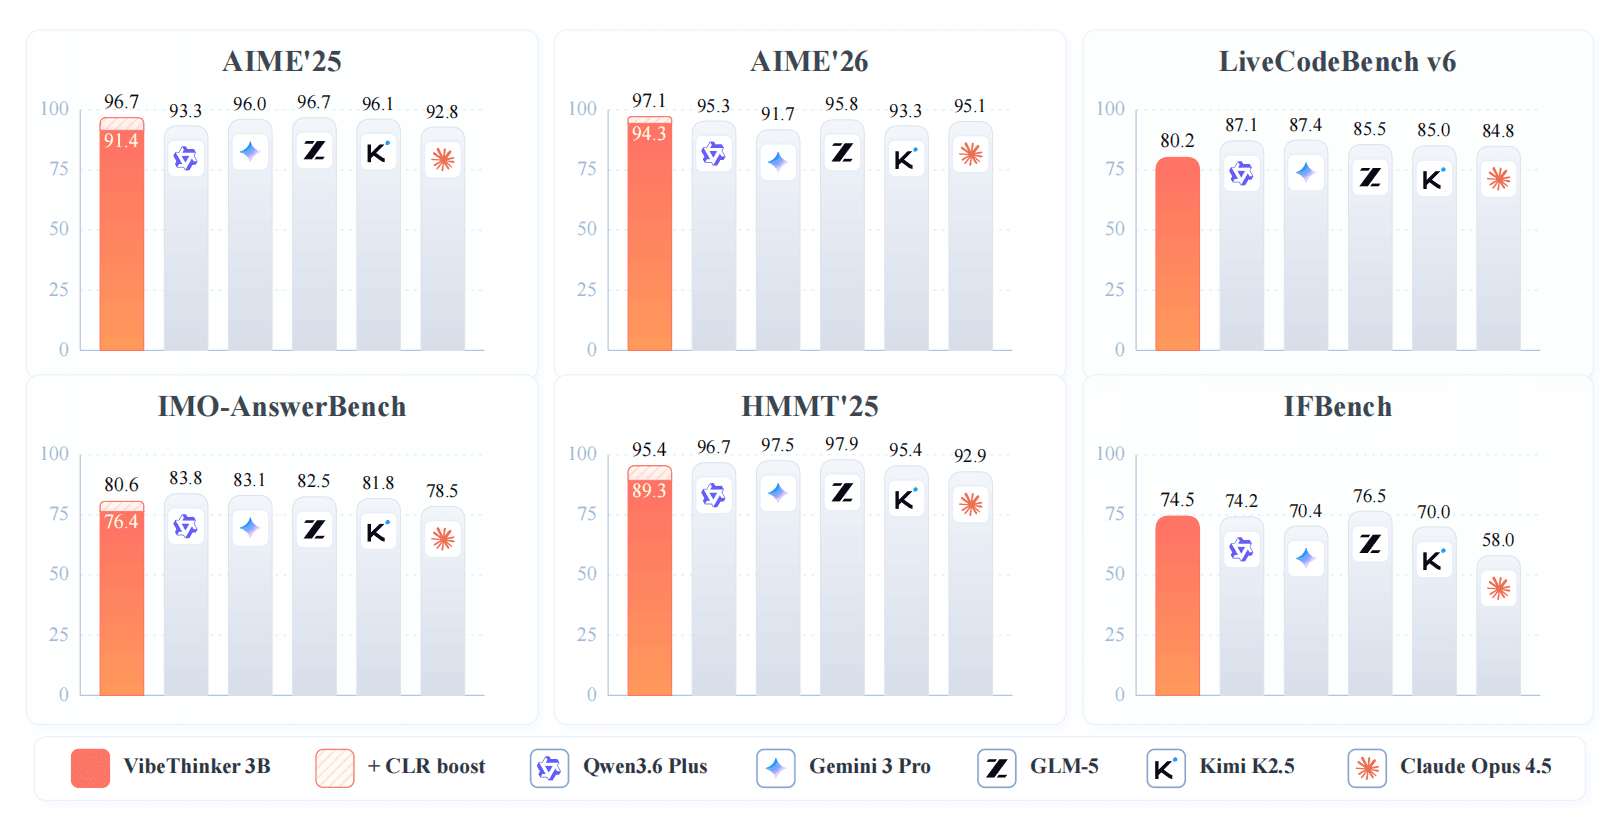
The new 3-billion-parameter model from the Chinese tech giant focuses on challenging benchmarks in mathematics, coding, and graduate-level questions.
The new Mixture-of-Experts model from the Chinese AI company can generate code while also understanding visual inputs, a rare combination in open models.
The new Apache 2.0-licensed model is designed for code generation and agentic chat applications, using a Mixture-of-Experts architecture for efficiency.
The new open-weight model from MiniMax AI combines vision, coding, and reasoning using a Mixture-of-Experts architecture.
Cactus Compute distilled Gemini's tool-calling behavior into a tiny model meant to run locally.
Moonshot AI's open-weights mixture-of-experts model reportedly outperformed Claude, GPT-5.5, and Gemini on a programming challenge.
The new flagship model combines a Mixture-of-Experts architecture with a permissive MIT license, positioning it for wide commercial adoption.
Cactus Compute's tiny encoder-decoder is distilled specifically for function calling at the edge, trading general chat for a narrow, useful job.
The new model from Alibaba's Qwen team uses a Mixture-of-Experts architecture and is released under the commercially-friendly Apache 2.0 license.
The Shanghai-based AI startup has released a new Mixture-of-Experts model focused on complex reasoning, coding, and agentic tasks.
The new Apache 2.0 model from Alibaba's Qwen team uses a Mixture-of-Experts architecture to deliver strong performance with only 3B active parameters.
The new flagship coding model from Alibaba's Qwen team uses a massive Mixture-of-Experts architecture and is released under a permissive Apache-2.0 license.
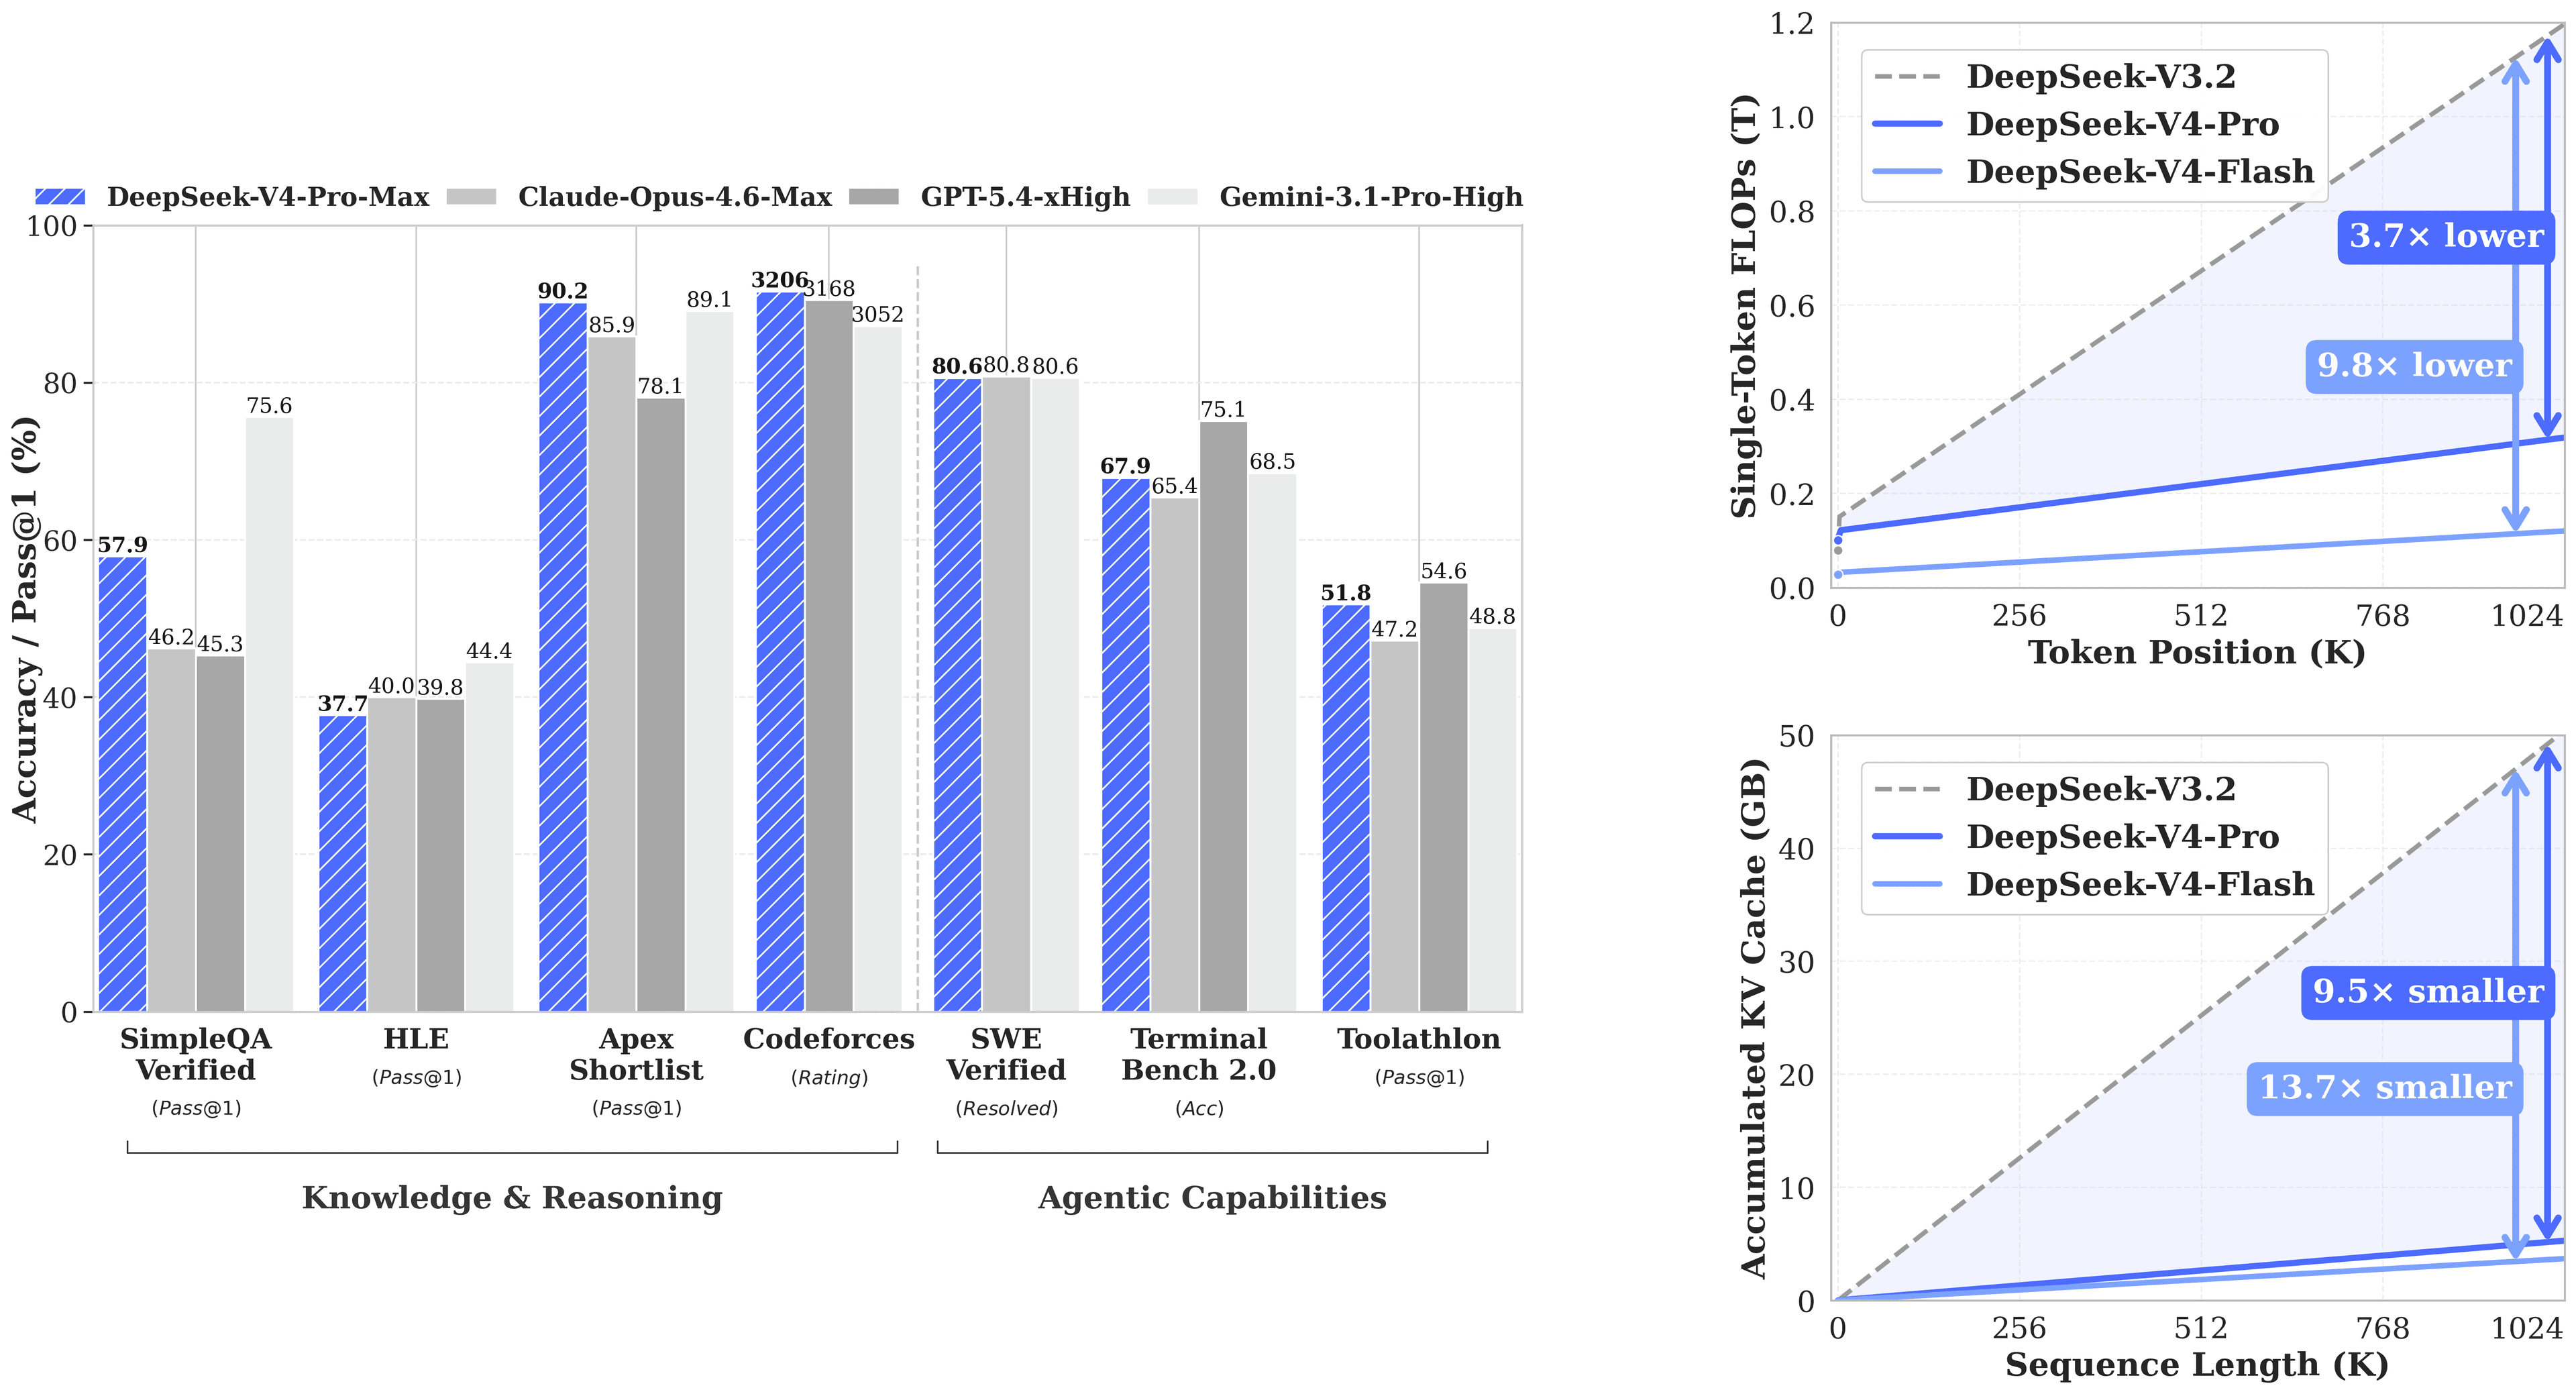
The new Mixture-of-Experts model combines massive scale with a fully permissive license, targeting complex reasoning and agentic applications.