Sage-A1.5 Brings Agentic Vision to Open MoE Models
InclusionAI's new mixture-of-experts model pairs visual understanding with tool use and code, aiming at agentic workflows under an Apache 2.0 license.
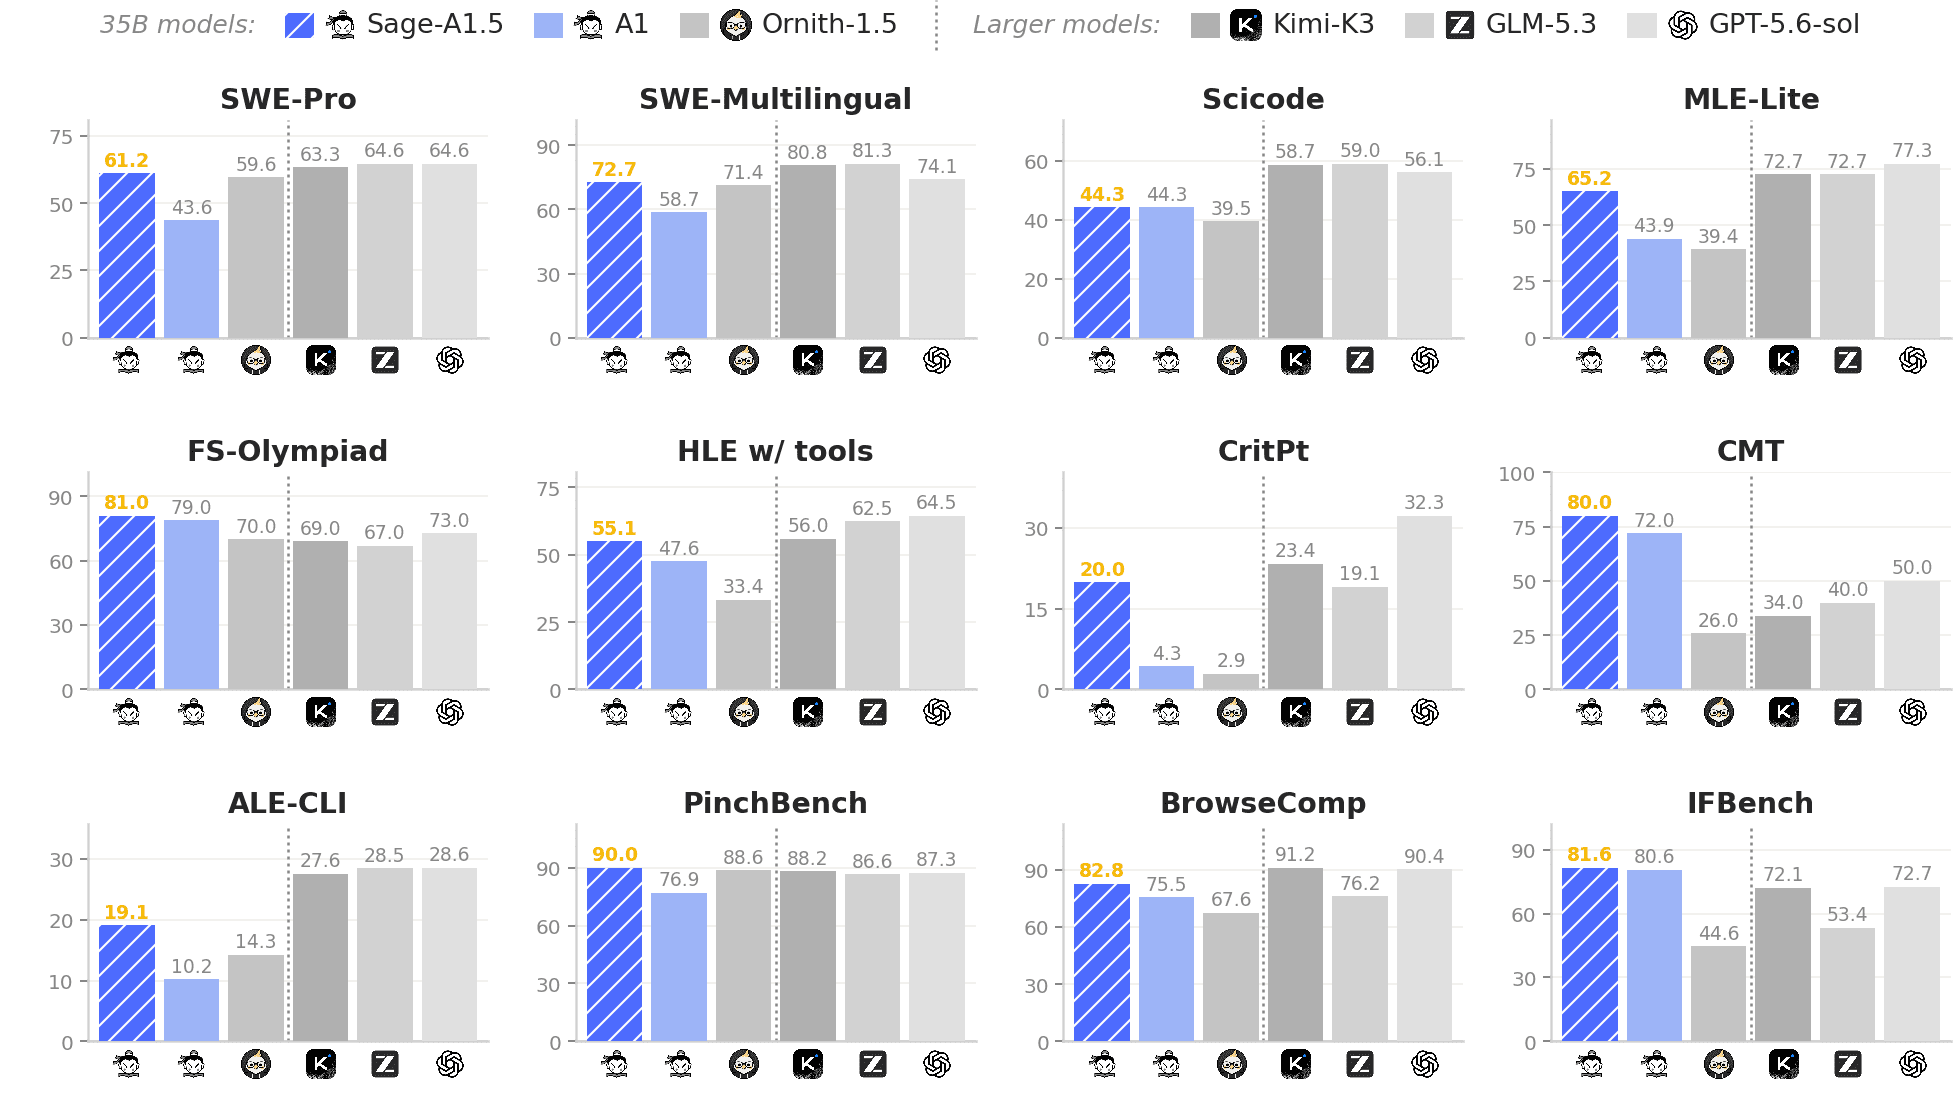
InclusionAI has published Sage-A1.5, a vision-language model that leans into agentic behavior rather than static image captioning. Released on Hugging Face under the permissive Apache 2.0 license, the model combines multimodal understanding with reasoning, tool-use, and code capabilities — a combination aimed squarely at systems that need to see, plan, and act.
The model uses a mixture-of-experts (MoE) architecture, a design that activates only a subset of parameters per token to keep inference costs lower than a comparably sized dense model. That approach has become increasingly common among teams trying to scale capability without proportionally scaling compute.
Why it matters
Agentic vision-language models are a growing category because many real-world tasks — navigating interfaces, interpreting screenshots, or debugging visual output — require a model that can both perceive and take action. Sage-A1.5 folds several of these capabilities into one release:
- Vision-language understanding as the primary modality
- Reasoning and tool-use for multi-step tasks
- Code generation for executable workflows
The open license is the other notable piece here. Apache 2.0 allows commercial use and modification, lowering the barrier for developers who want to build agents on top of an open base rather than a closed API.
InclusionAI has not published detailed parameter counts or context-length figures alongside this release, so builders will want to consult the model card directly for specifics before integrating it into production pipelines.
Sources
- Visit
InternScience/Sage-A1.5
Hugging Face
More from InternScience
All InternScience releases →
Agents-A1: A 35B MoE Built for Agentic Scaling
InclusionAI's new mixture-of-experts model bets that agent-horizon scaling can rival far larger systems on long-running tasks.
More in Vision-Language
All Vision-Language →
MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.

DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
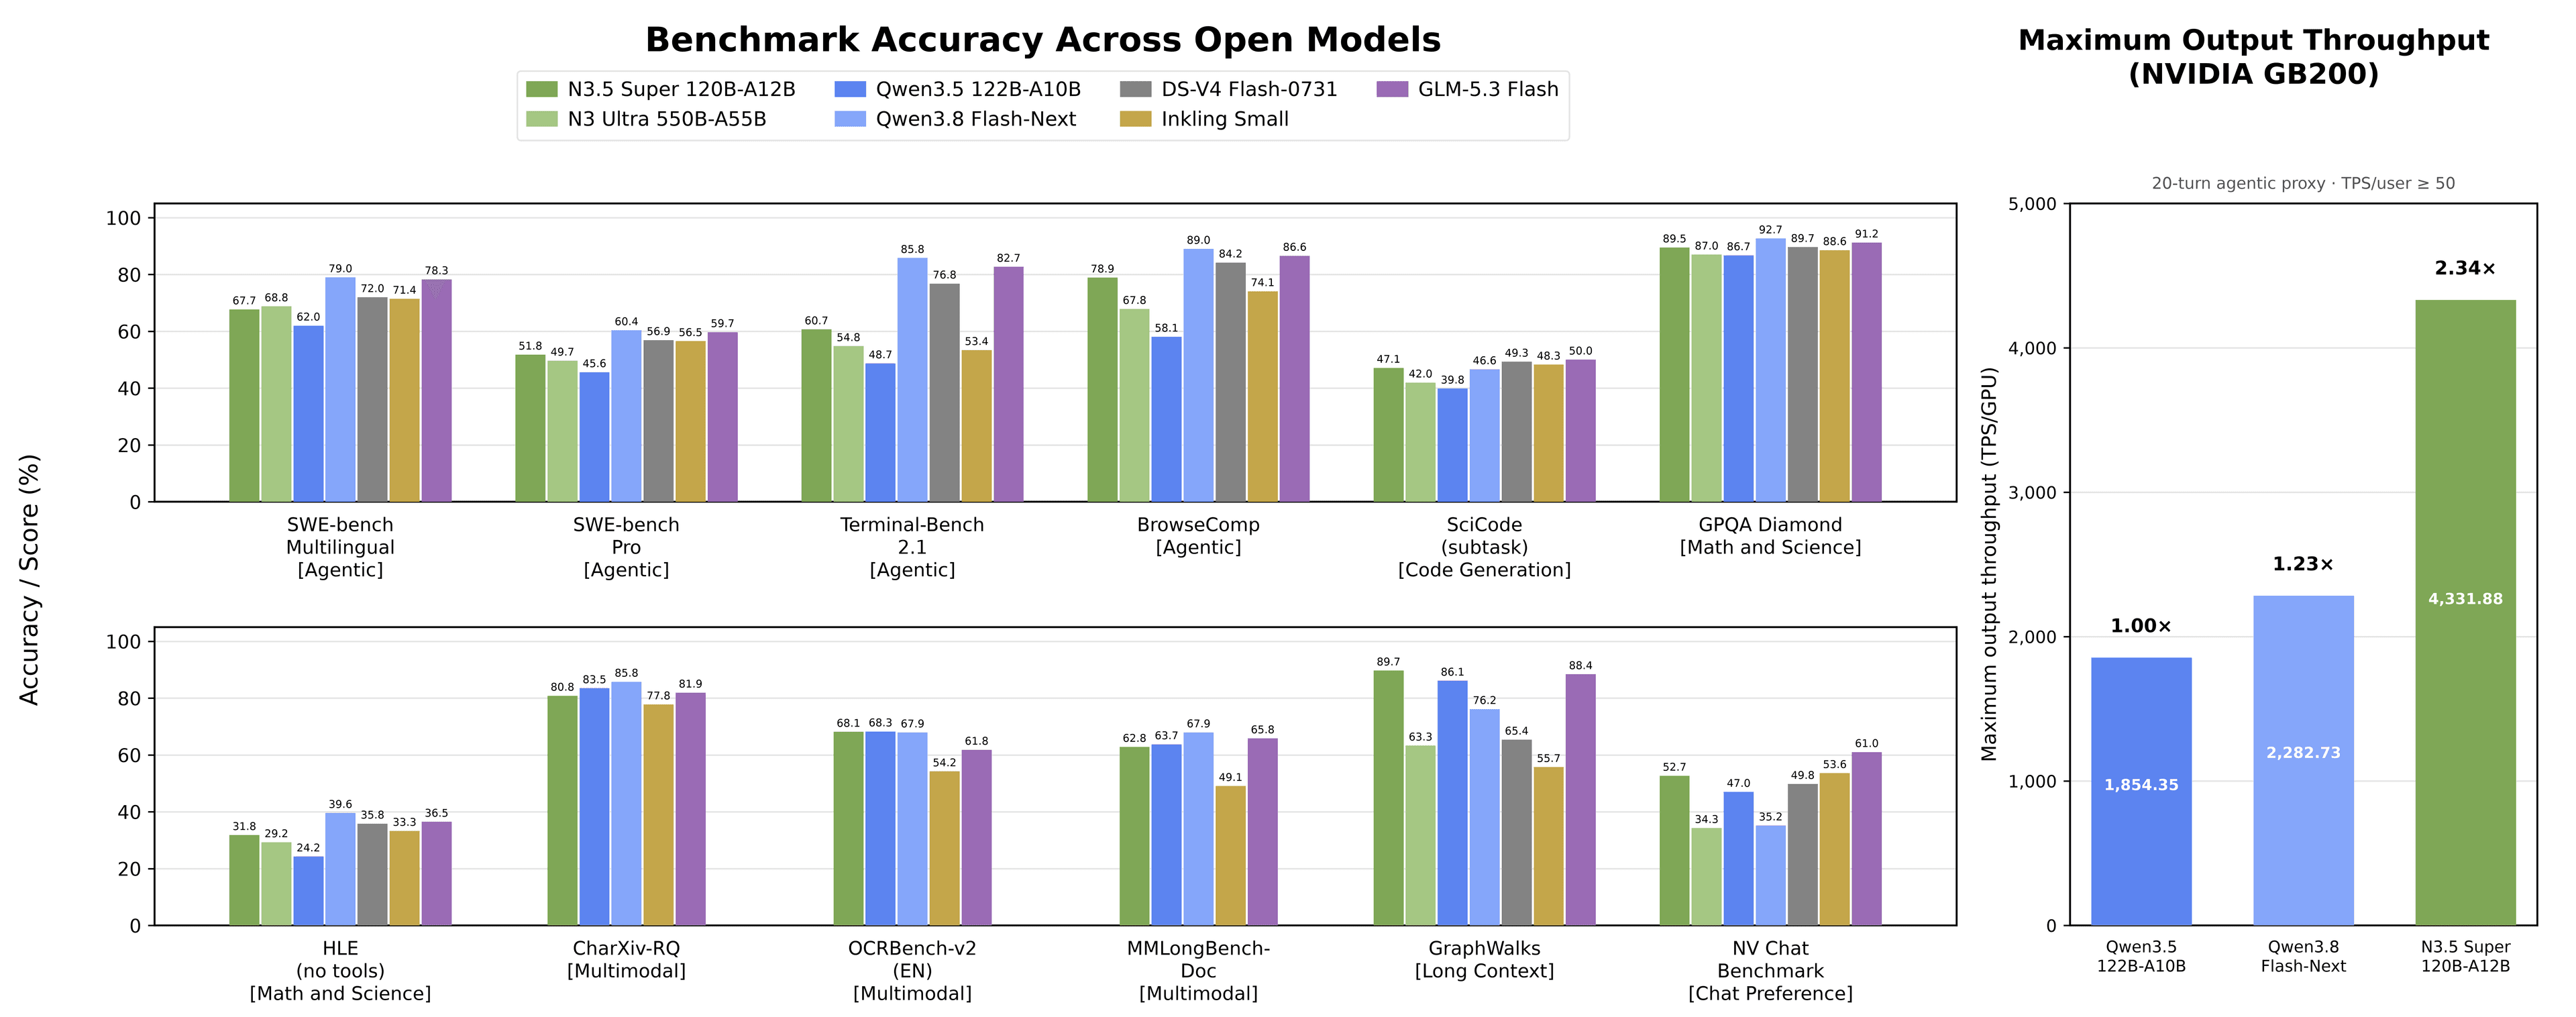
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
0 comments
No comments yet. Be the first to weigh in.