NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
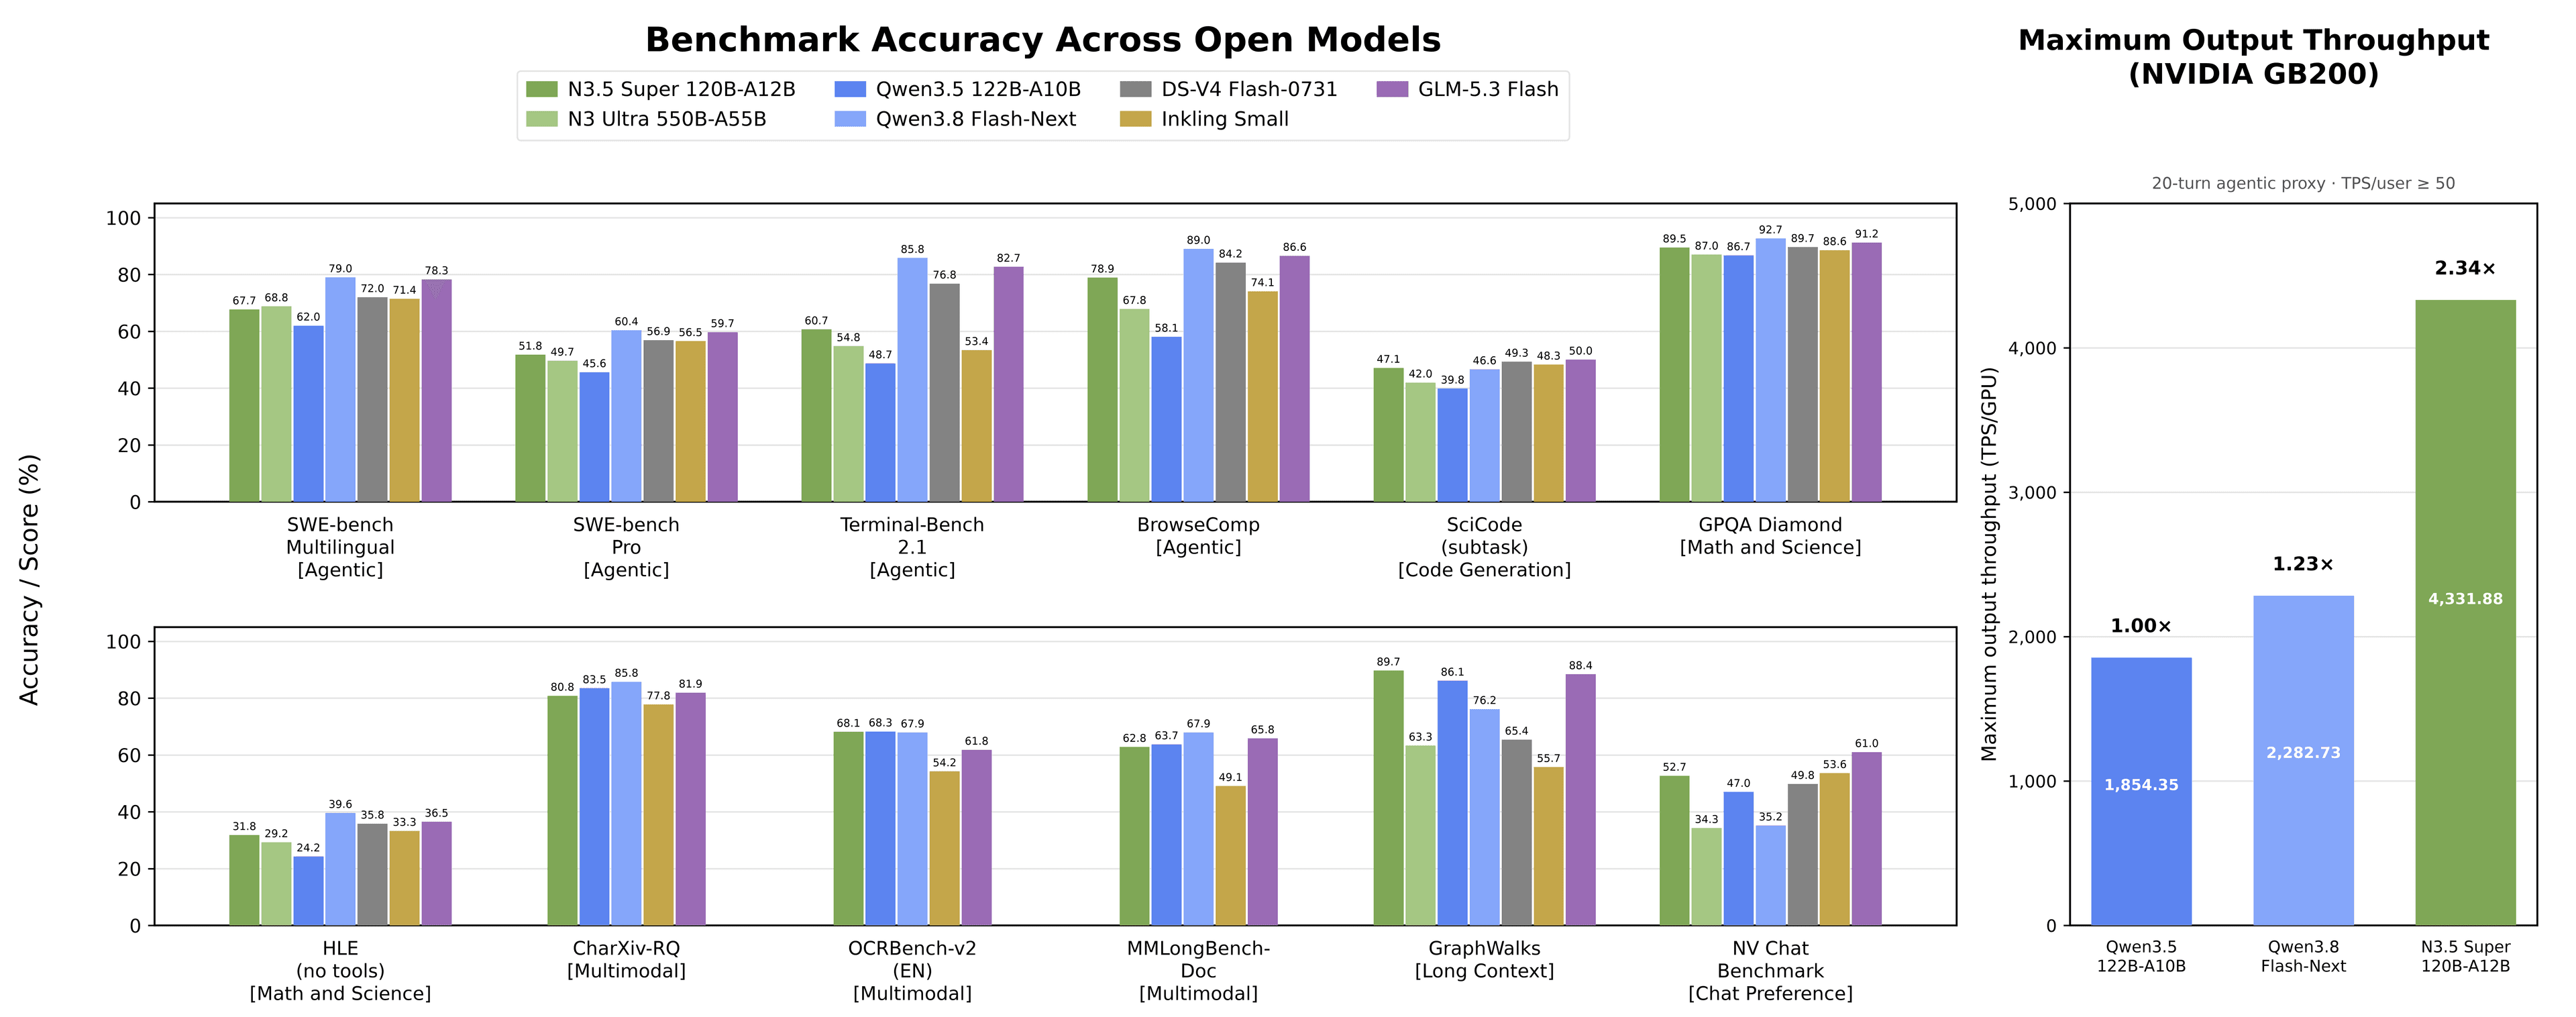
NVIDIA has released Nemotron 3.5 Super VL 120B-A12B, a vision-language model that leans on a mixture-of-experts design to keep compute costs in check. The model carries 120 billion total parameters but activates only about 12 billion per token, a ratio meant to deliver large-model capability without large-model inference bills.
The model handles both image and text inputs, placing it in the growing category of open vision-language systems aimed at document understanding, multimodal reasoning, and multilingual tasks. NVIDIA describes the release as multilingual, broadening its usefulness beyond English-centric workloads.
Why the NVFP4 format matters
This checkpoint ships in NVFP4, NVIDIA's 4-bit floating-point quantization format. That choice signals the company's intent to make large MoE models practical to run on its newer hardware, trimming memory footprint while preserving accuracy. For teams weighing deployment, the combination of sparse activation and aggressive quantization is the headline:
- 120B total parameters, ~12B active per token
- Vision-language and text modalities
- Multilingual support
- NVFP4 4-bit quantization out of the box
As part of the broader Nemotron line, the "Super" tier positions this model between NVIDIA's smaller and largest offerings, targeting users who want strong multimodal performance without the heaviest infrastructure. Full licensing terms and specifications are available on the model's Hugging Face page.
Sources
- Visit
nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-NVFP4
Hugging Face
More from NVIDIA
All NVIDIA releases →TII Brings Falcon to Speech With New ASR Model
The team behind the Falcon language models expands into speech-to-text with its first automatic speech recognition release.
Falcon-Emirati tunes an LLM for local dialect
TII's Falcon family gets a variant built around Emirati Arabic, aiming at culture and nuance rather than generic Gulf Arabic.
NVIDIA's Nemotron-3 Brings Streaming Speaker Diarization
The new open model applies NVIDIA's Sortformer approach to identify who's speaking, in real time.
More in Vision-Language
All Vision-Language →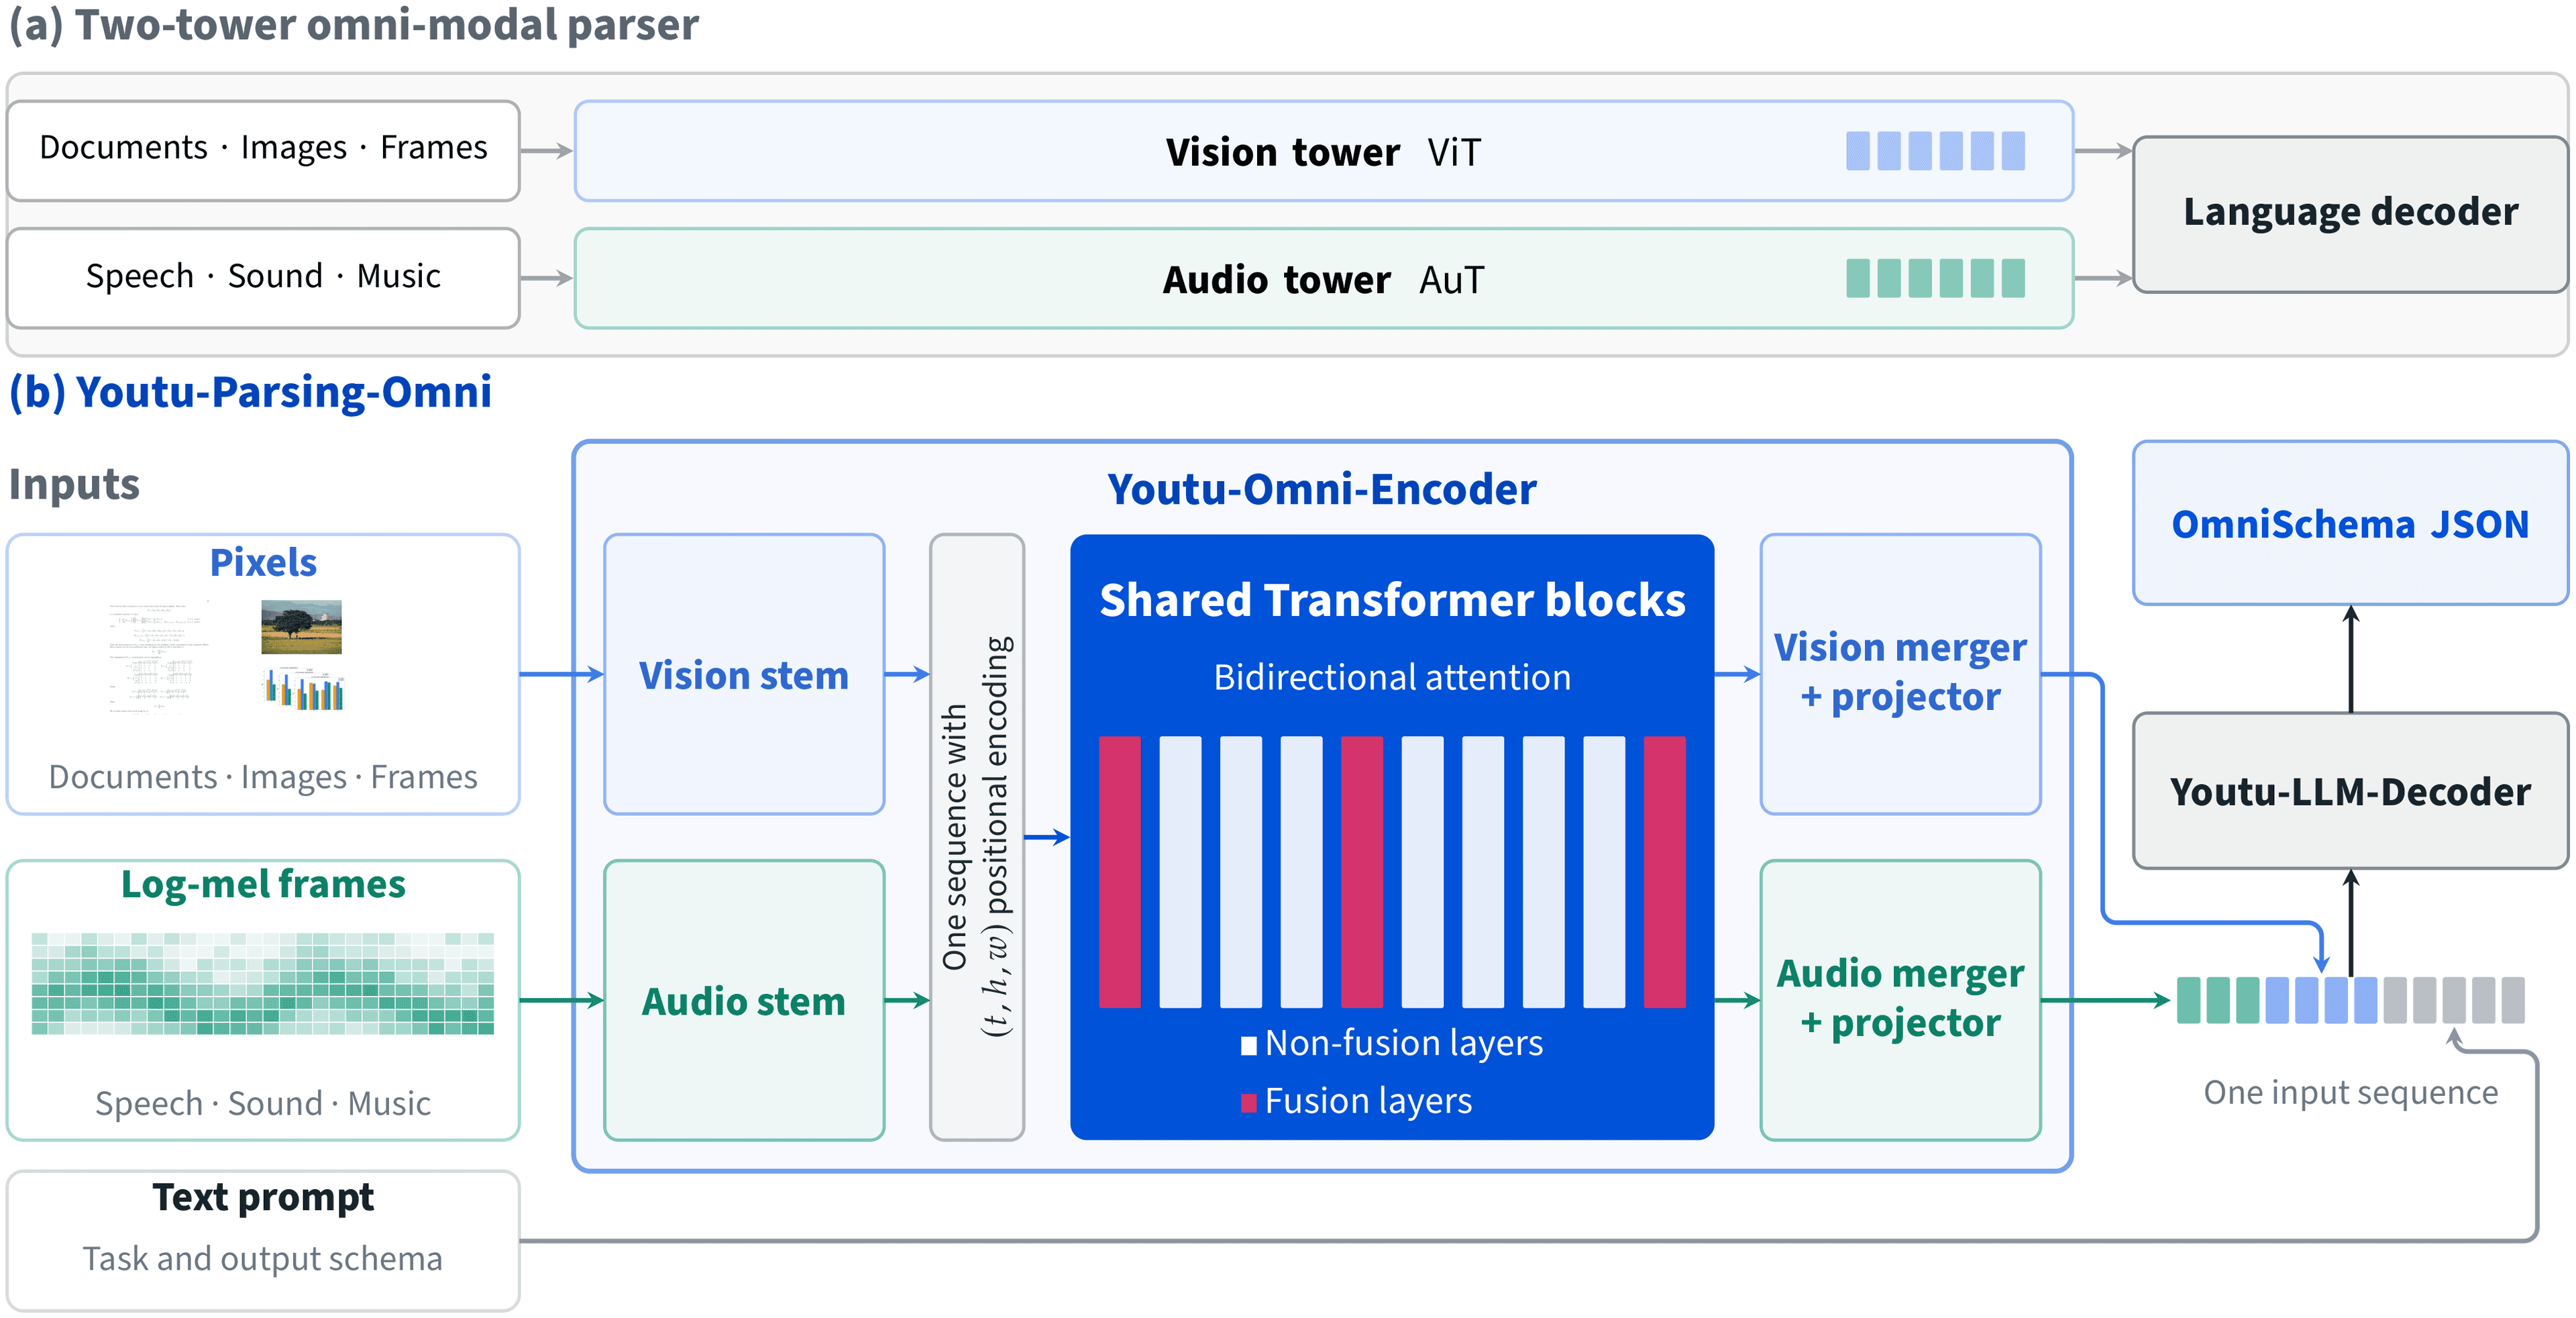
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
Liquid AI's d1-3B brings multimodal models to the edge
The new LFM2-based d1-3B is a compact vision-language model aimed at running decisions directly on-device.
OpenBMB's MiniCPM-V 4.7 brings MoE to vision models
The new 35B-parameter vision-language model activates just 3B parameters per pass, aiming for efficiency without sacrificing capability.
0 comments
No comments yet. Be the first to weigh in.