NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
NVIDIA has published Dory 1.0, a compact 4-billion-parameter text model, under its Nemotron Labs banner. Released on Hugging Face in BF16 format, the dense model is trained on NVIDIA's Nemotron datasets and targets text generation workloads.
At 4 billion parameters, Dory sits firmly in the small-model tier that has become increasingly competitive. Models in this range are prized for running on modest hardware, from single consumer GPUs to edge deployments, while still handling a meaningful share of everyday reasoning and generation tasks.
Where it fits
The release extends NVIDIA's ongoing Nemotron effort, which pairs curated training data with openly available model weights. For developers, that lineage matters:
- A dense (non-MoE) architecture that is straightforward to fine-tune and serve
- BF16 weights suited to modern accelerators
- Training grounded in NVIDIA's own Nemotron datasets
NVIDIA has not published detailed benchmark figures or context-length specifications alongside this initial release, so practical evaluation will depend on hands-on testing. As a first version from Dory, it establishes a baseline for a new small-model line rather than a headline flagship.
The model ships under a custom NVIDIA license, so teams should review the terms before building on it. For a compact, openly downloadable option from a major vendor, Dory 1.0 is worth a look for anyone prototyping lightweight text applications.
Sources
- Visit
nvidia/NVIDIA-Nemotron-Labs-Dory1.0-4B-BF16
Hugging Face
More from NVIDIA
All NVIDIA releases →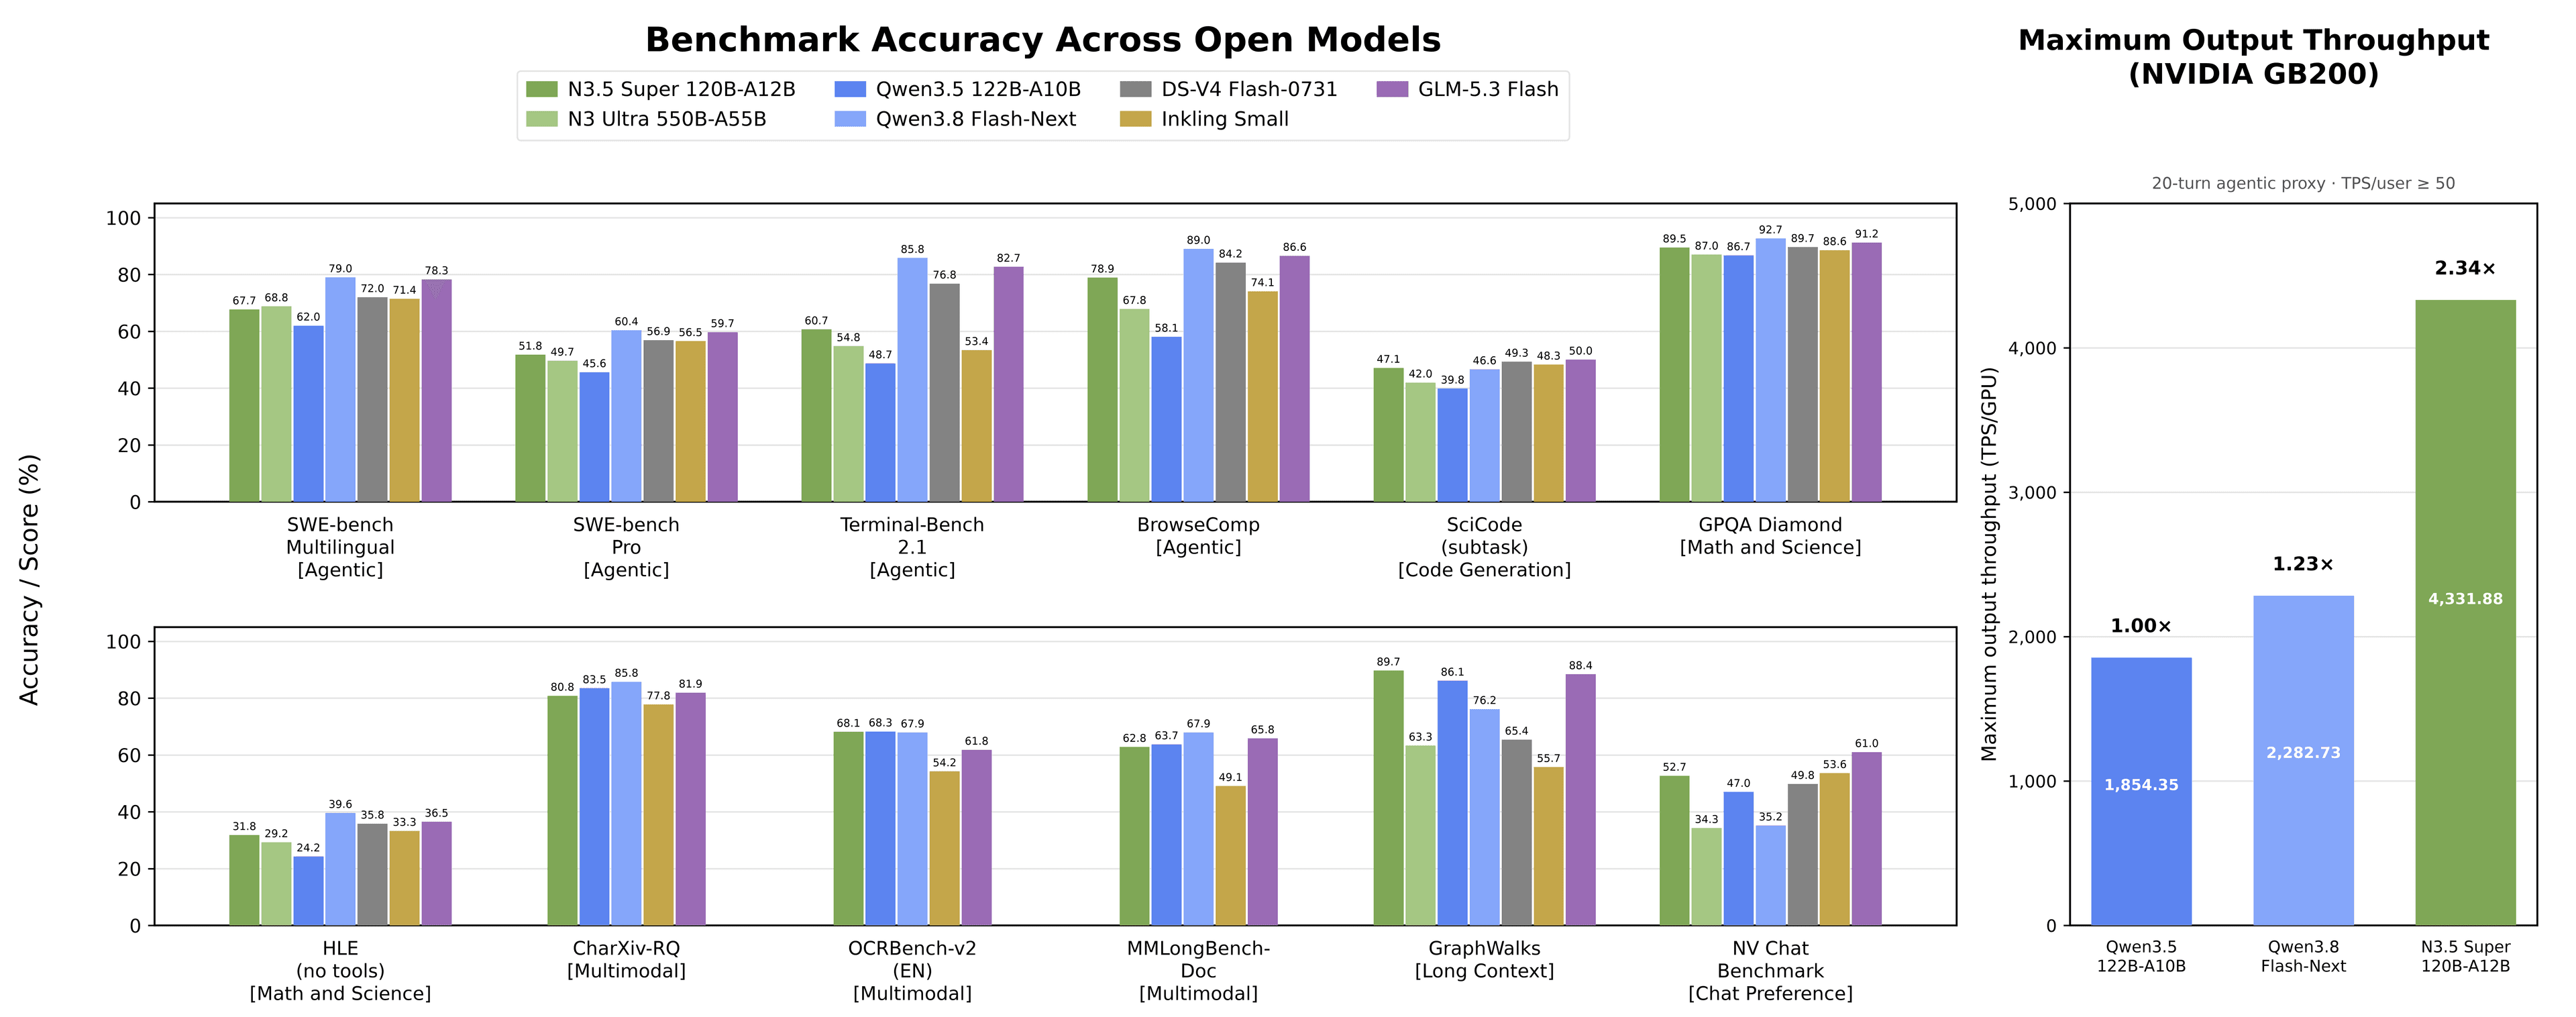
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
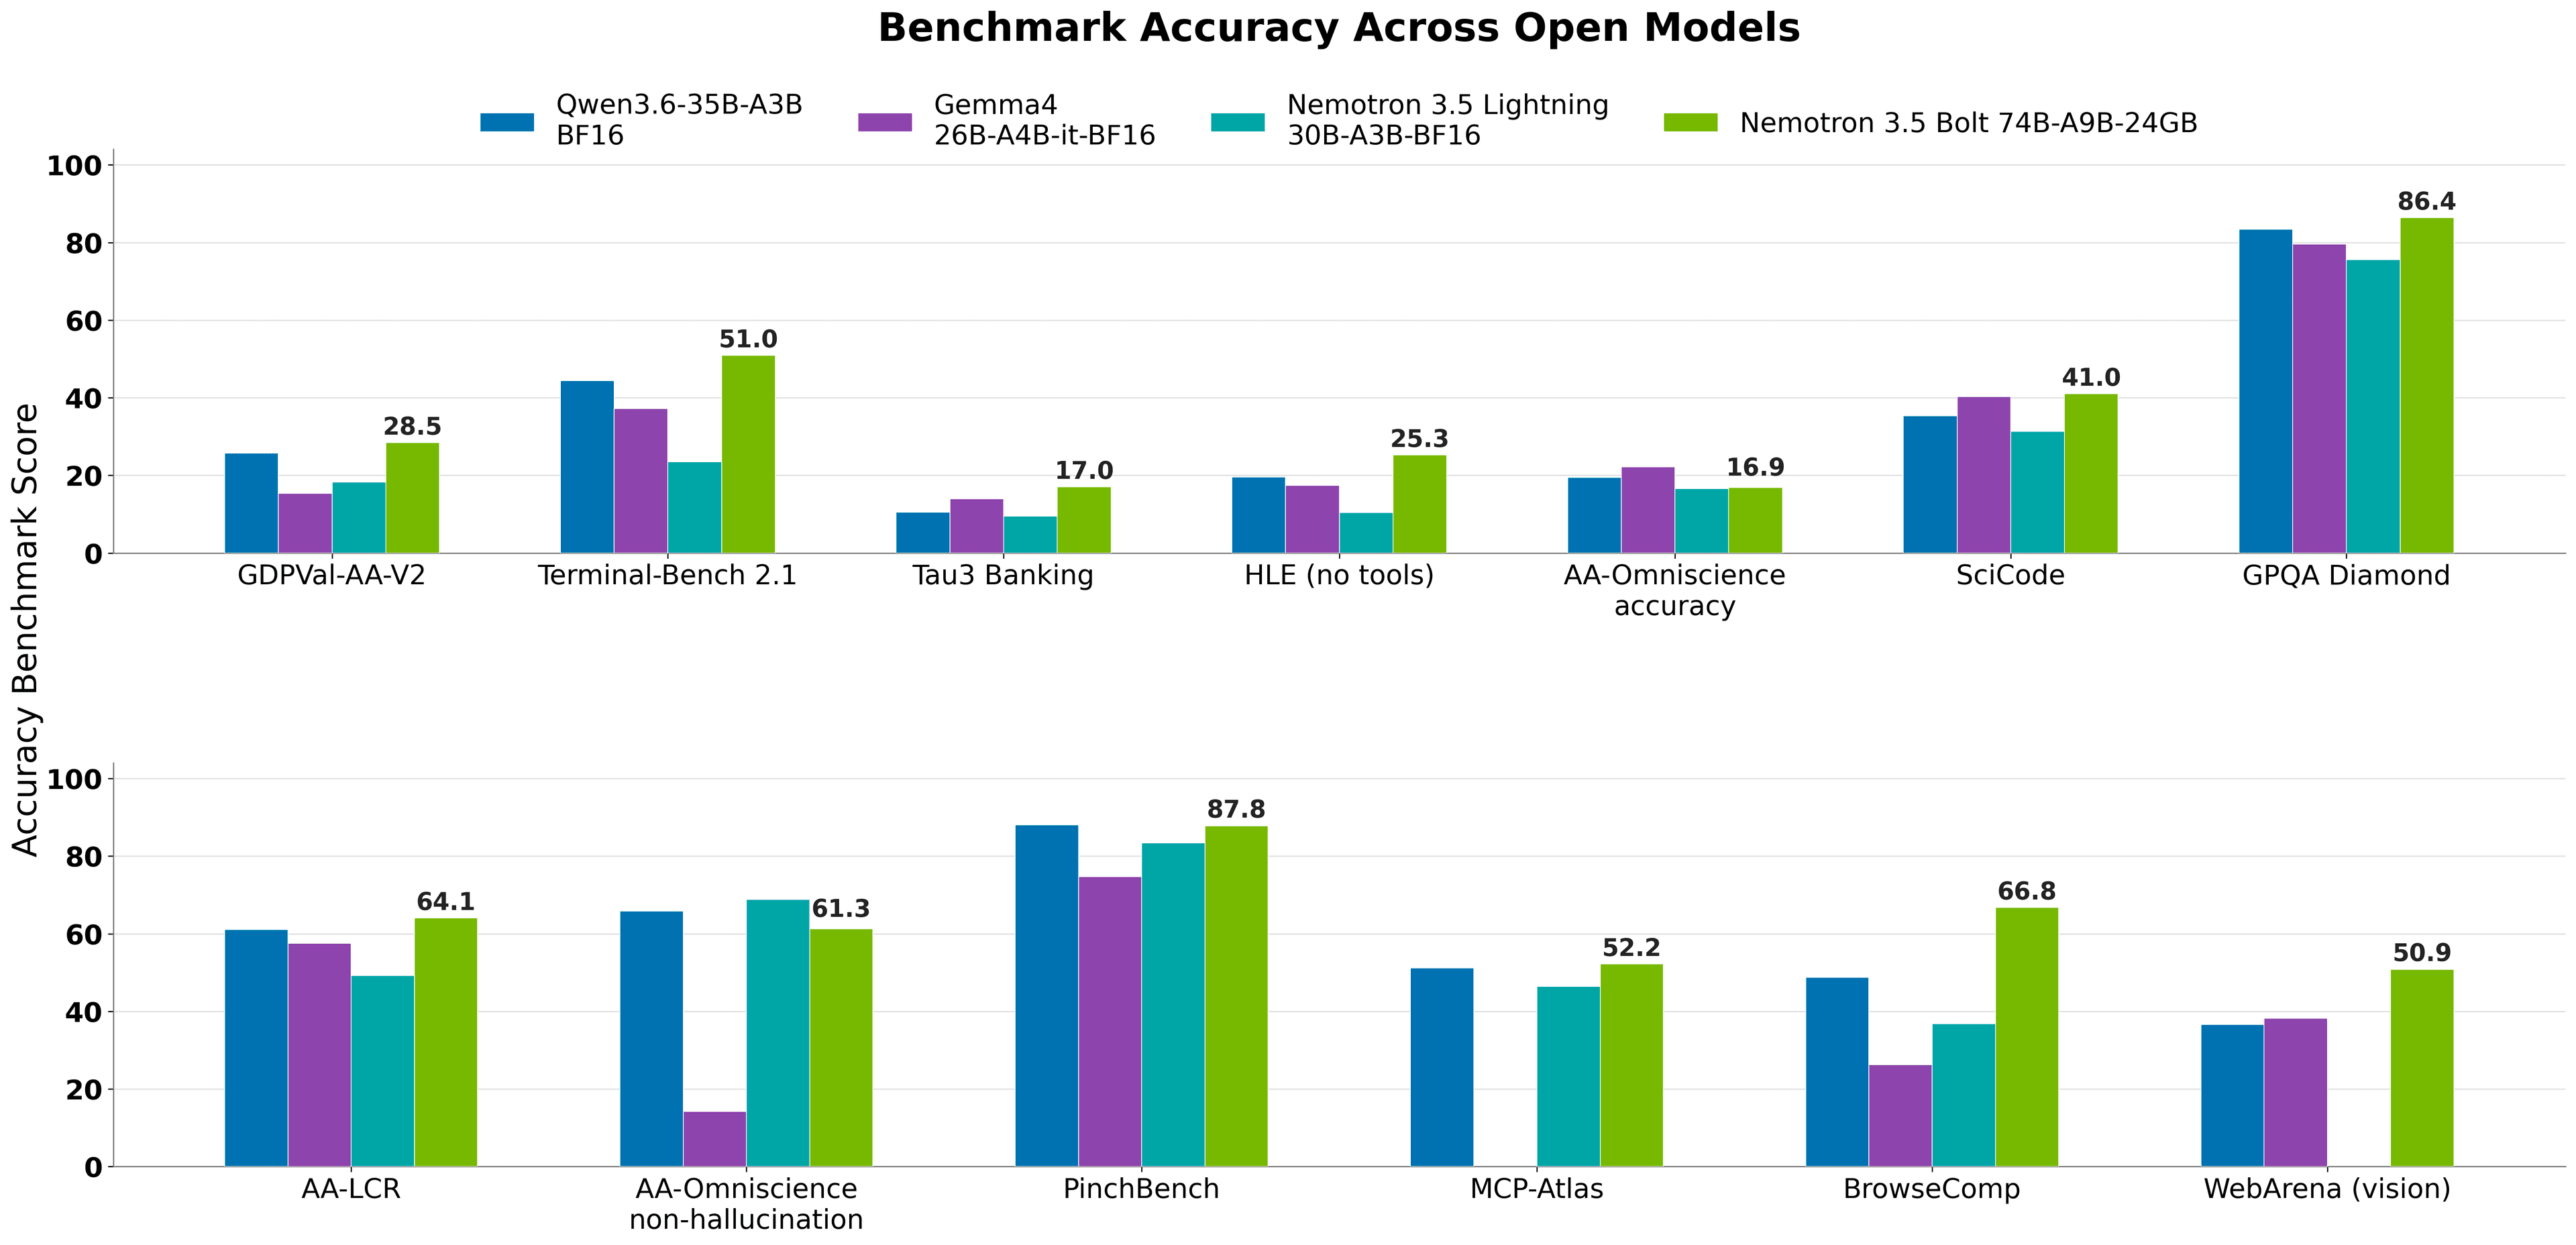
NVIDIA's Nemotron-3.5 Bolt targets 24GB GPUs
A multimodal mixture-of-experts model with 74B total parameters but just 9B active, tuned to fit consumer-class hardware.
TII Brings Falcon to Speech With New ASR Model
The team behind the Falcon language models expands into speech-to-text with its first automatic speech recognition release.
More in Text / LLM
All Text / LLM →
DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
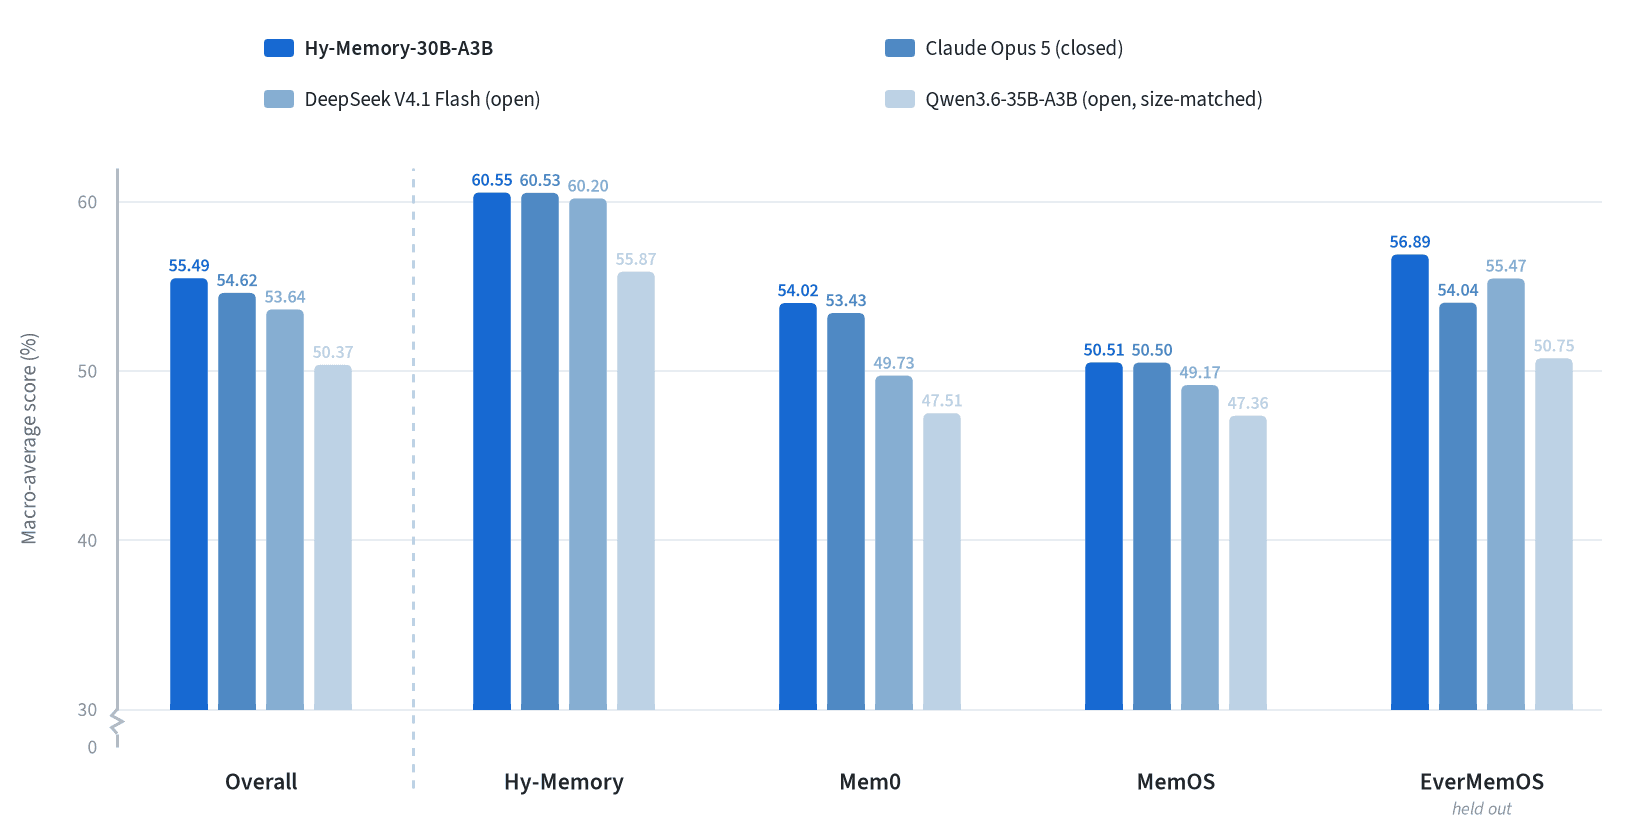
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
0 comments
No comments yet. Be the first to weigh in.