NVIDIA's Cosmos 3 Brings Open Interactive World Models
The new open release pushes beyond passive video generation toward simulated worlds that respond to input.
NVIDIA has released Cosmos 3, the latest generation of its open model family aimed at interactive world simulation and video generation. The release continues NVIDIA's push to make world models — systems that can generate and extend visual environments — available to the broader developer community rather than keeping them locked inside proprietary stacks.
Cosmos 3 supports both text-to-video and image-to-video generation, meaning developers can seed a simulation from a written prompt or an existing frame and have the model produce coherent video continuations. The "interactive" framing is the notable shift: rather than treating generation as a one-shot output, the models are oriented toward worlds that can evolve in response to input.
Why it matters
World models are increasingly central to robotics, autonomous systems, and simulation-heavy training pipelines, where generating realistic, controllable environments is often more practical than collecting real-world data. Making these capabilities openly available lowers the barrier for teams that want to build on top of them.
- Text-to-video and image-to-video generation in one family
- Focus on interactive, simulatable worlds rather than static clips
- Released as open models under NVIDIA's own license terms
As with prior NVIDIA open releases, the license is NVIDIA-specific rather than a standard permissive license, so teams should read the terms carefully before building commercial products. Full details and access are available through NVIDIA's announcement on Hugging Face.
Sources
- Visit
New NVIDIA Cosmos 3 Open Models for Interactive World Simulation
Announcement
More from NVIDIA
All NVIDIA releases →NVIDIA Releases Cosmos 3 for World Simulation
The new open models push NVIDIA's world-foundation effort toward interactive, real-time video generation.
NVIDIA releases compact Dory 1.0 4B text model
The new Nemotron Labs model packs a 4-billion-parameter language model trained on NVIDIA's Nemotron datasets.
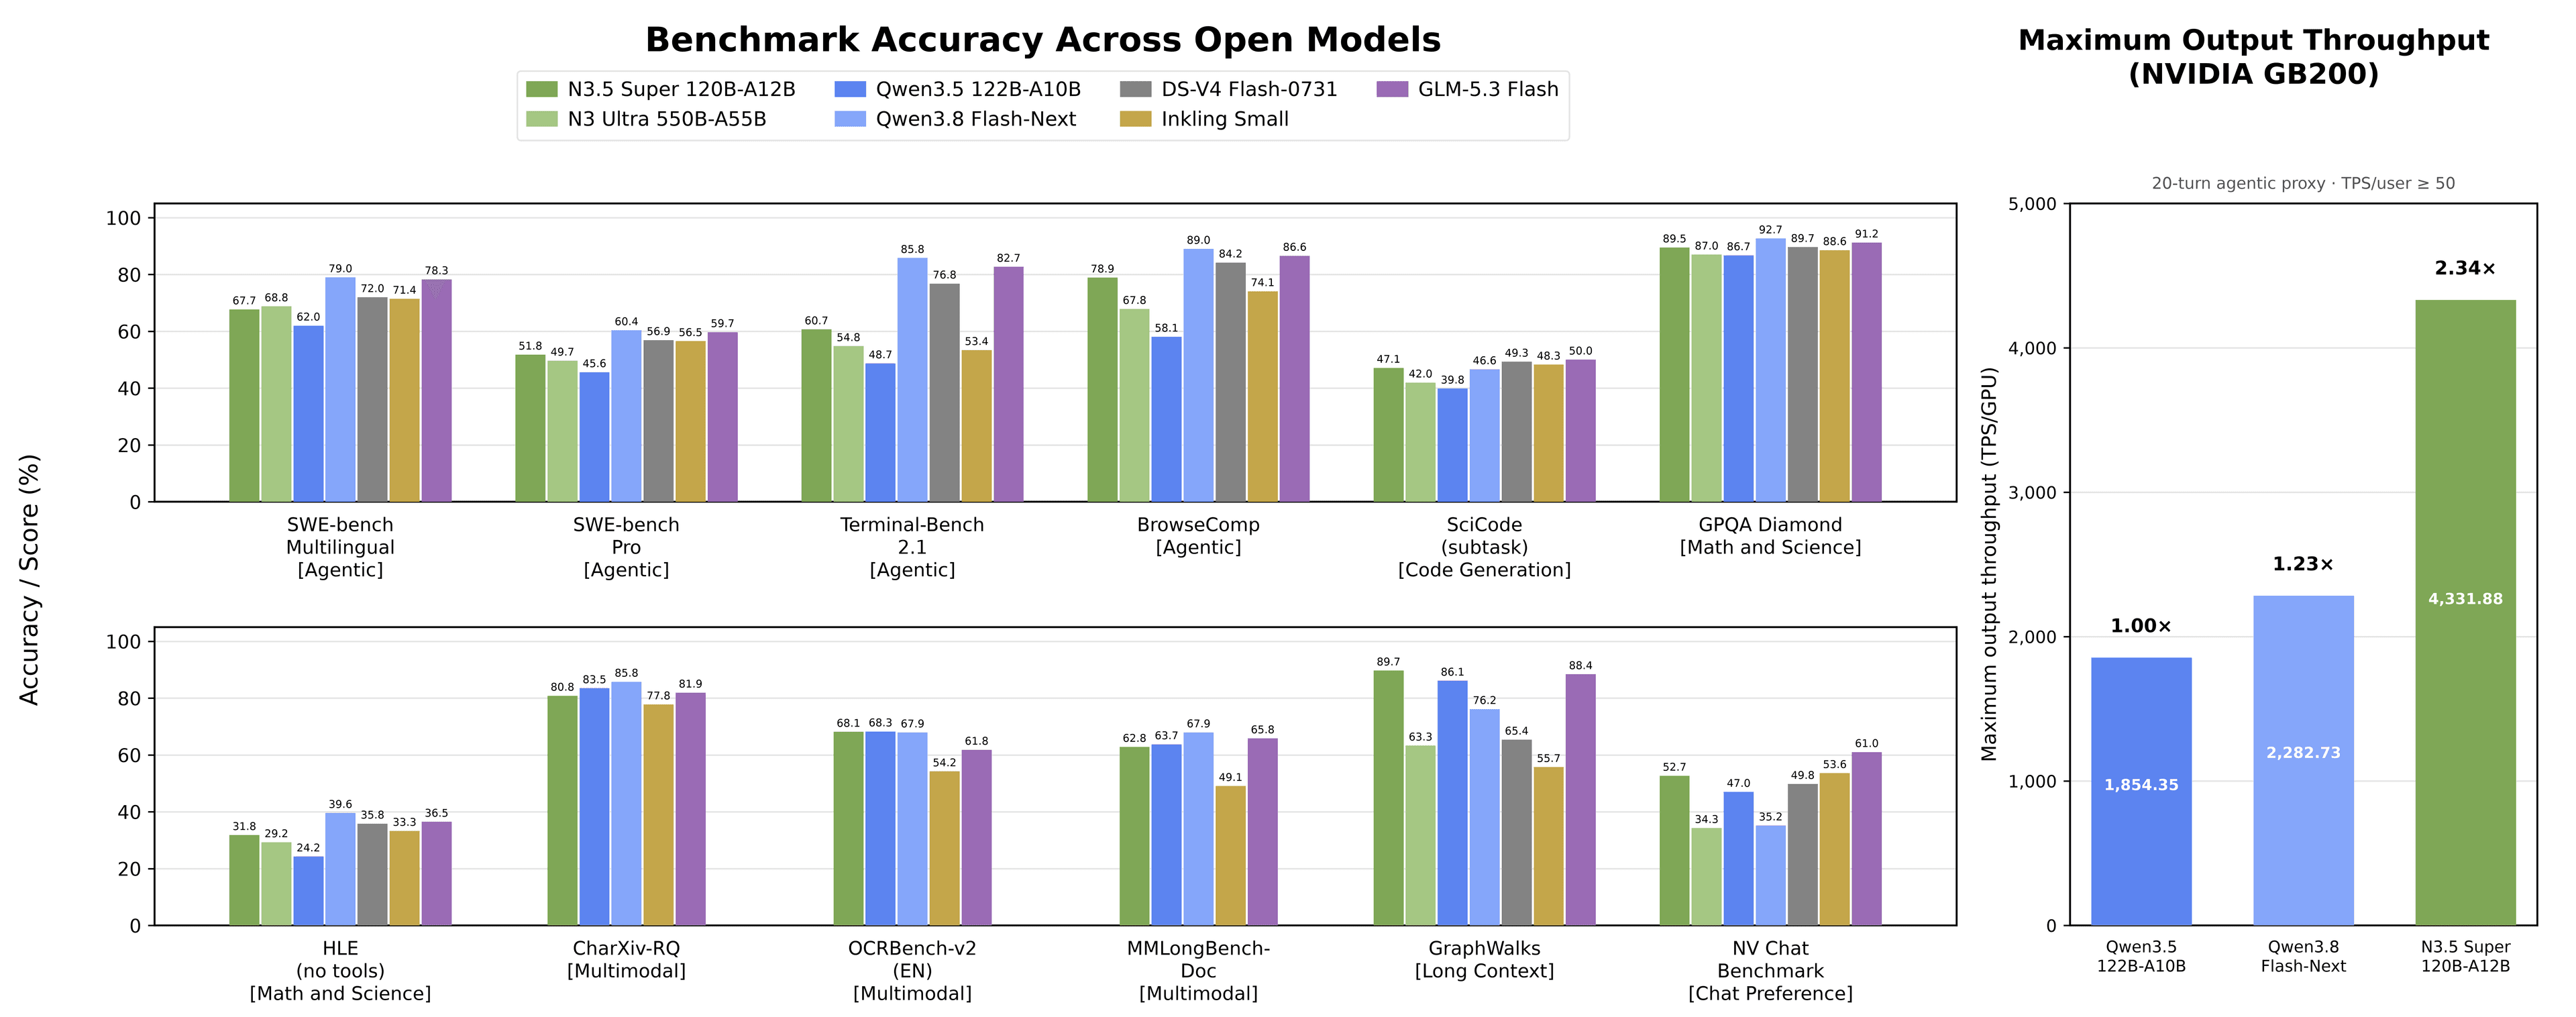
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
More in Text → Video
All Text → Video →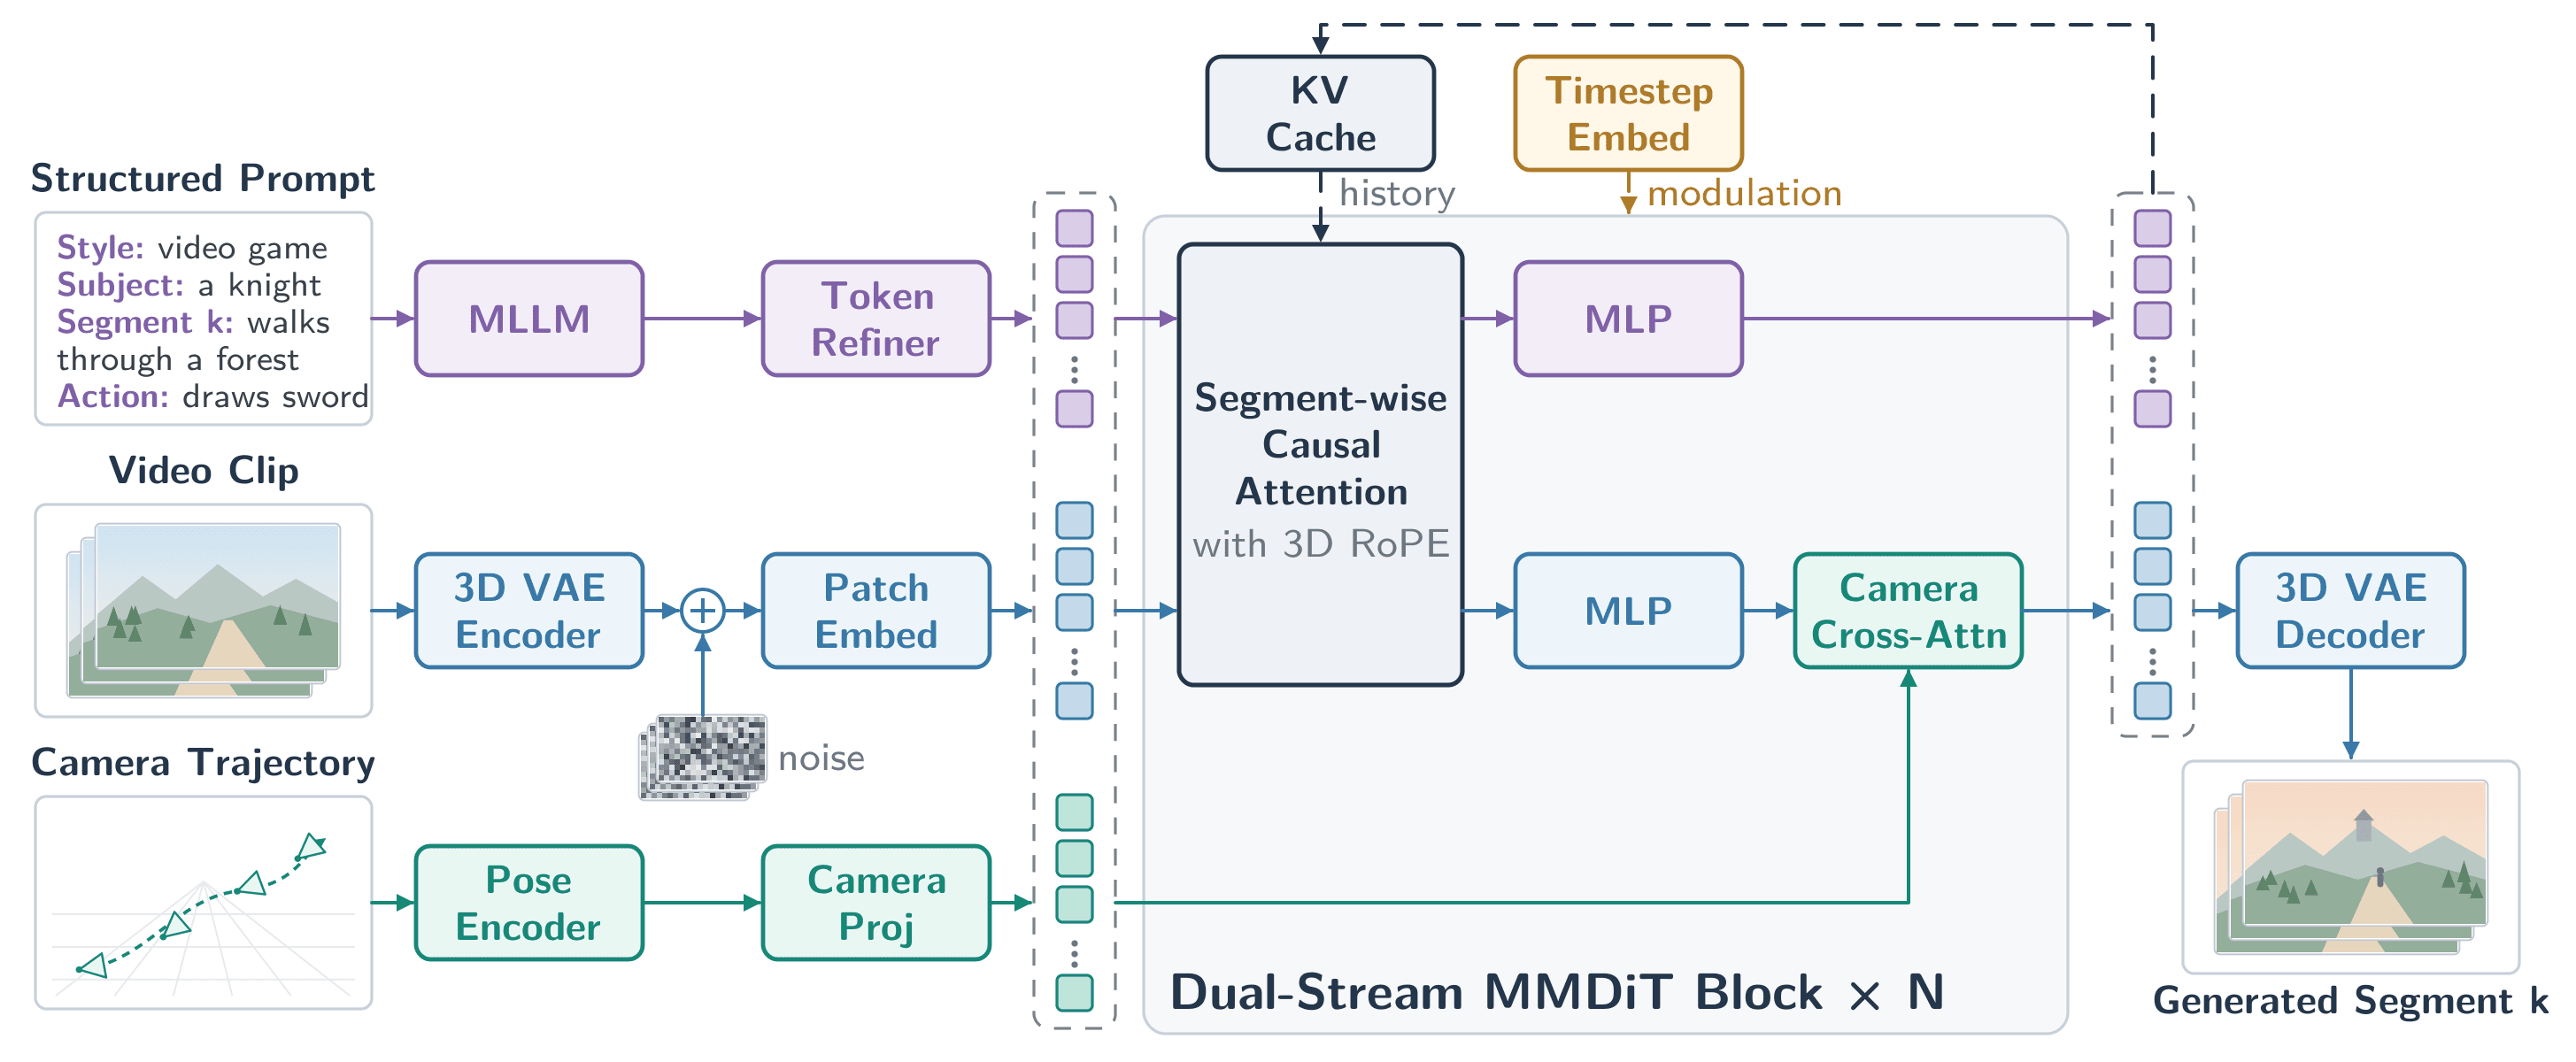
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
Kandinsky 6.0 Generates Video and Audio Together
Kandinsky Lab's new foundation models produce synchronized sound and motion from a text prompt, in 3B and 29B sizes.
MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
0 comments
No comments yet. Be the first to weigh in.