MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
MiniMax has published MiniMax-H3, a diffusion-based video generation model, on Hugging Face. The release supports both text-to-video and image-to-video workflows, positioning it against a growing field of open video generators.
What sets H3 apart, according to its model page, is support for joint audio-video generation — producing a soundtrack alongside the visuals rather than leaving audio as a separate post-processing step. That capability is still relatively rare in openly available video models, most of which output silent clips.
Why it matters
Open video generation has moved quickly over the past year, but audio remains a persistent gap. A model that generates sound and picture together lowers the friction for creators who would otherwise need to stitch in music or effects manually.
A few caveats are worth noting:
- MiniMax has not published parameter counts, resolution, frame rate, or maximum clip duration in the release record.
- The model ships under a non-standard "other" license, so teams should review the terms before commercial use.
As with any newly posted checkpoint, real-world quality and the practical limits of the audio-video feature will become clearer once the community begins testing it. For now, the weights and documentation are live on Hugging Face.
Sources
- Visit
MiniMaxAI/MiniMax-H3
Hugging Face
More from MiniMax
All MiniMax releases →
MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.

MiniMax Opens Its Music3 Text-to-Music Model
The Chinese AI lab brings its music generation system to Hugging Face, expanding the roster of open audio models.
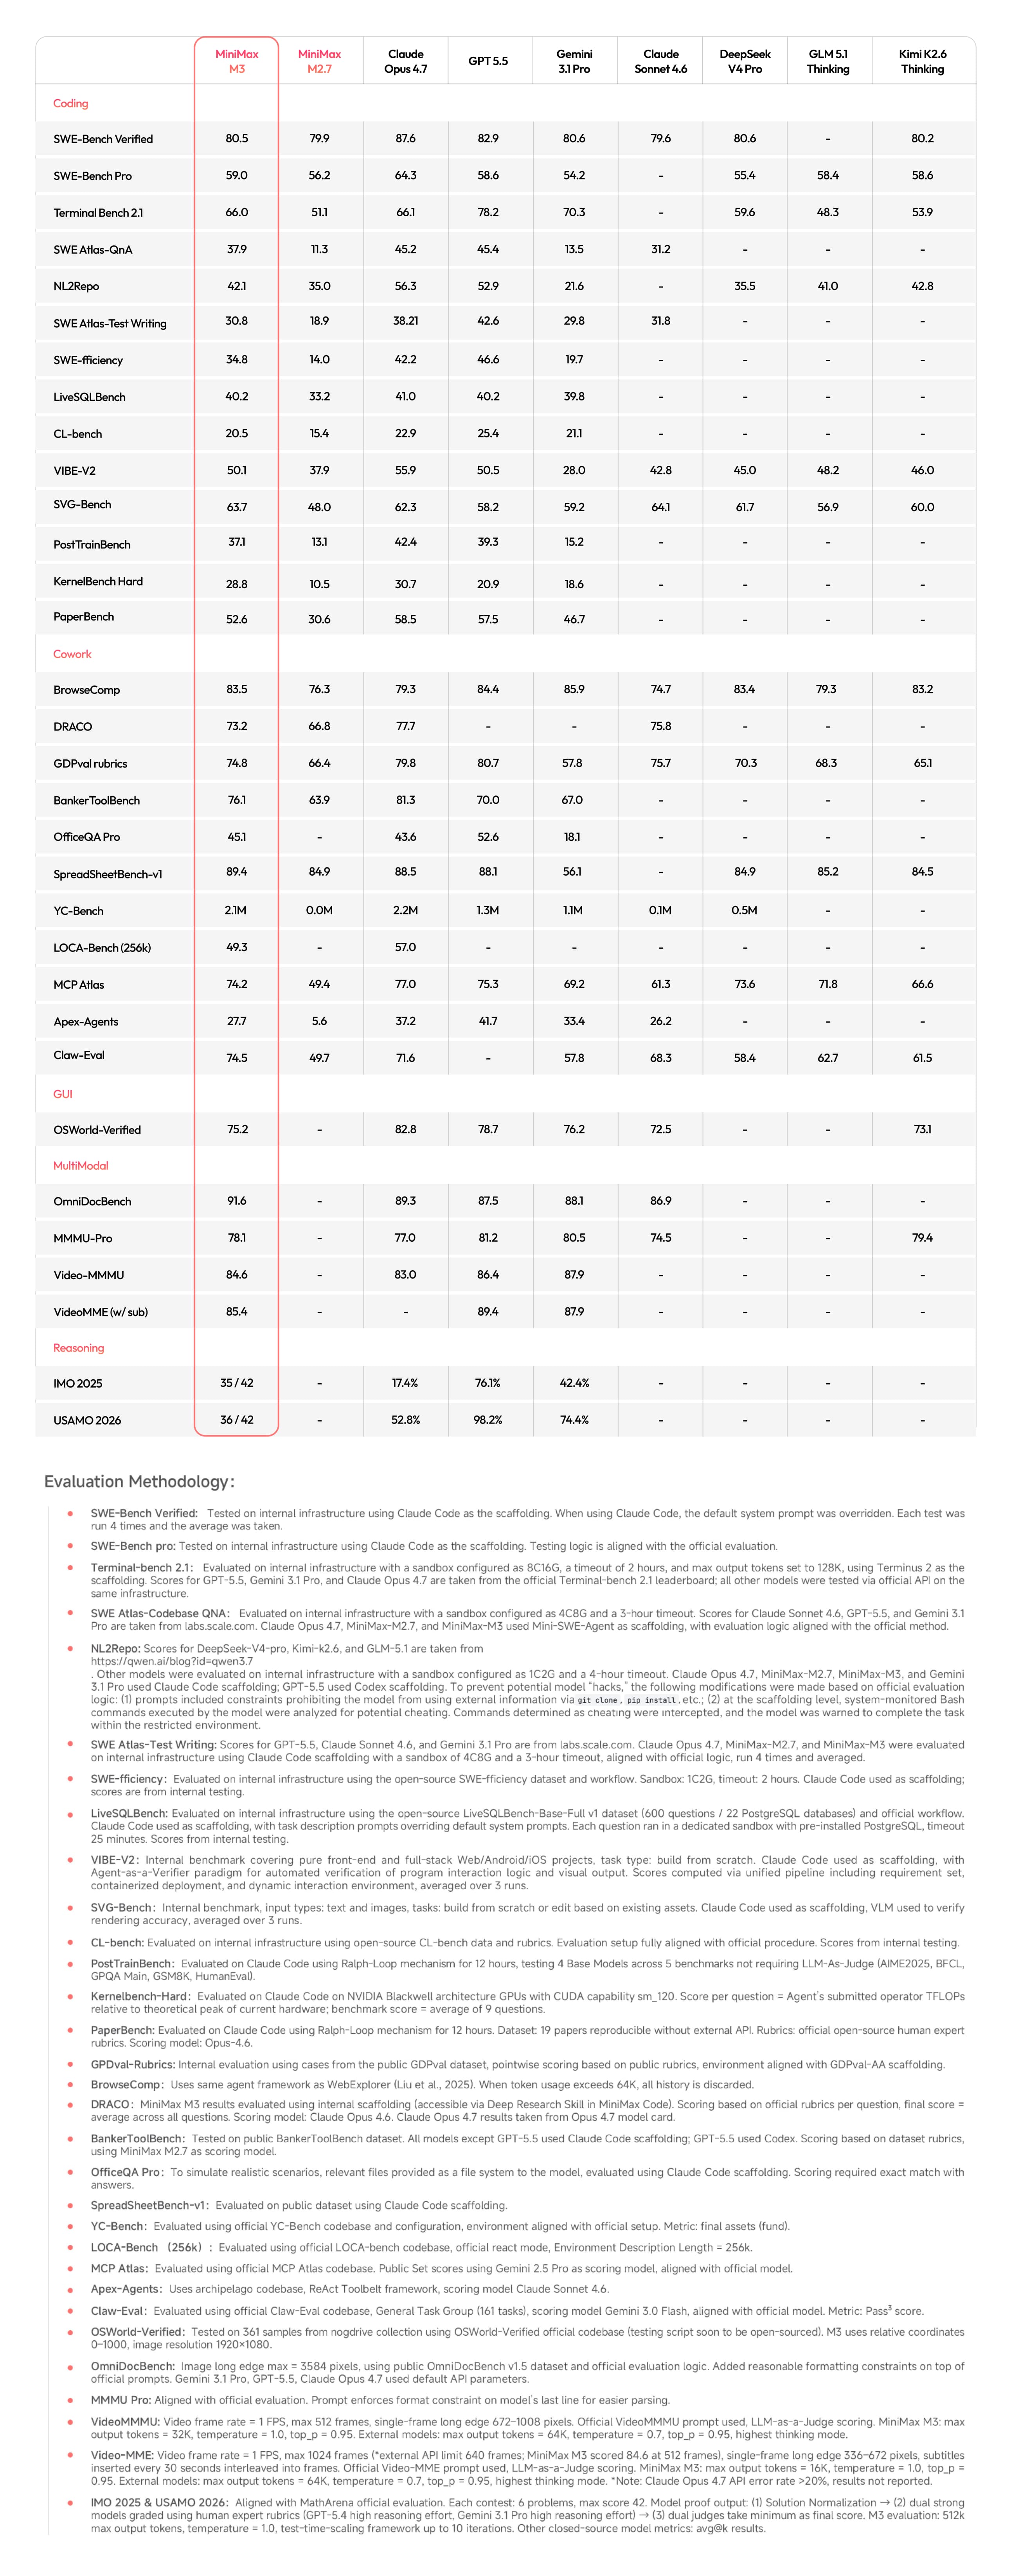
MiniMax Releases M3, a Multimodal MoE Model
The new open-weight model from MiniMax AI combines vision, coding, and reasoning using a Mixture-of-Experts architecture.
More in Text → Video
All Text → Video →
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
Kandinsky 6.0 Generates Video and Audio Together
Kandinsky Lab's new foundation models produce synchronized sound and motion from a text prompt, in 3B and 29B sizes.
Lightricks Releases LTX-2.5 Video Model
The latest LTX generator handles text-to-video, image-to-video, and audio-video pipelines in one open release.
0 comments
No comments yet. Be the first to weigh in.