MiniMax Releases M3, a Multimodal MoE Model
The new open-weight model from MiniMax AI combines vision, coding, and reasoning using a Mixture-of-Experts architecture.
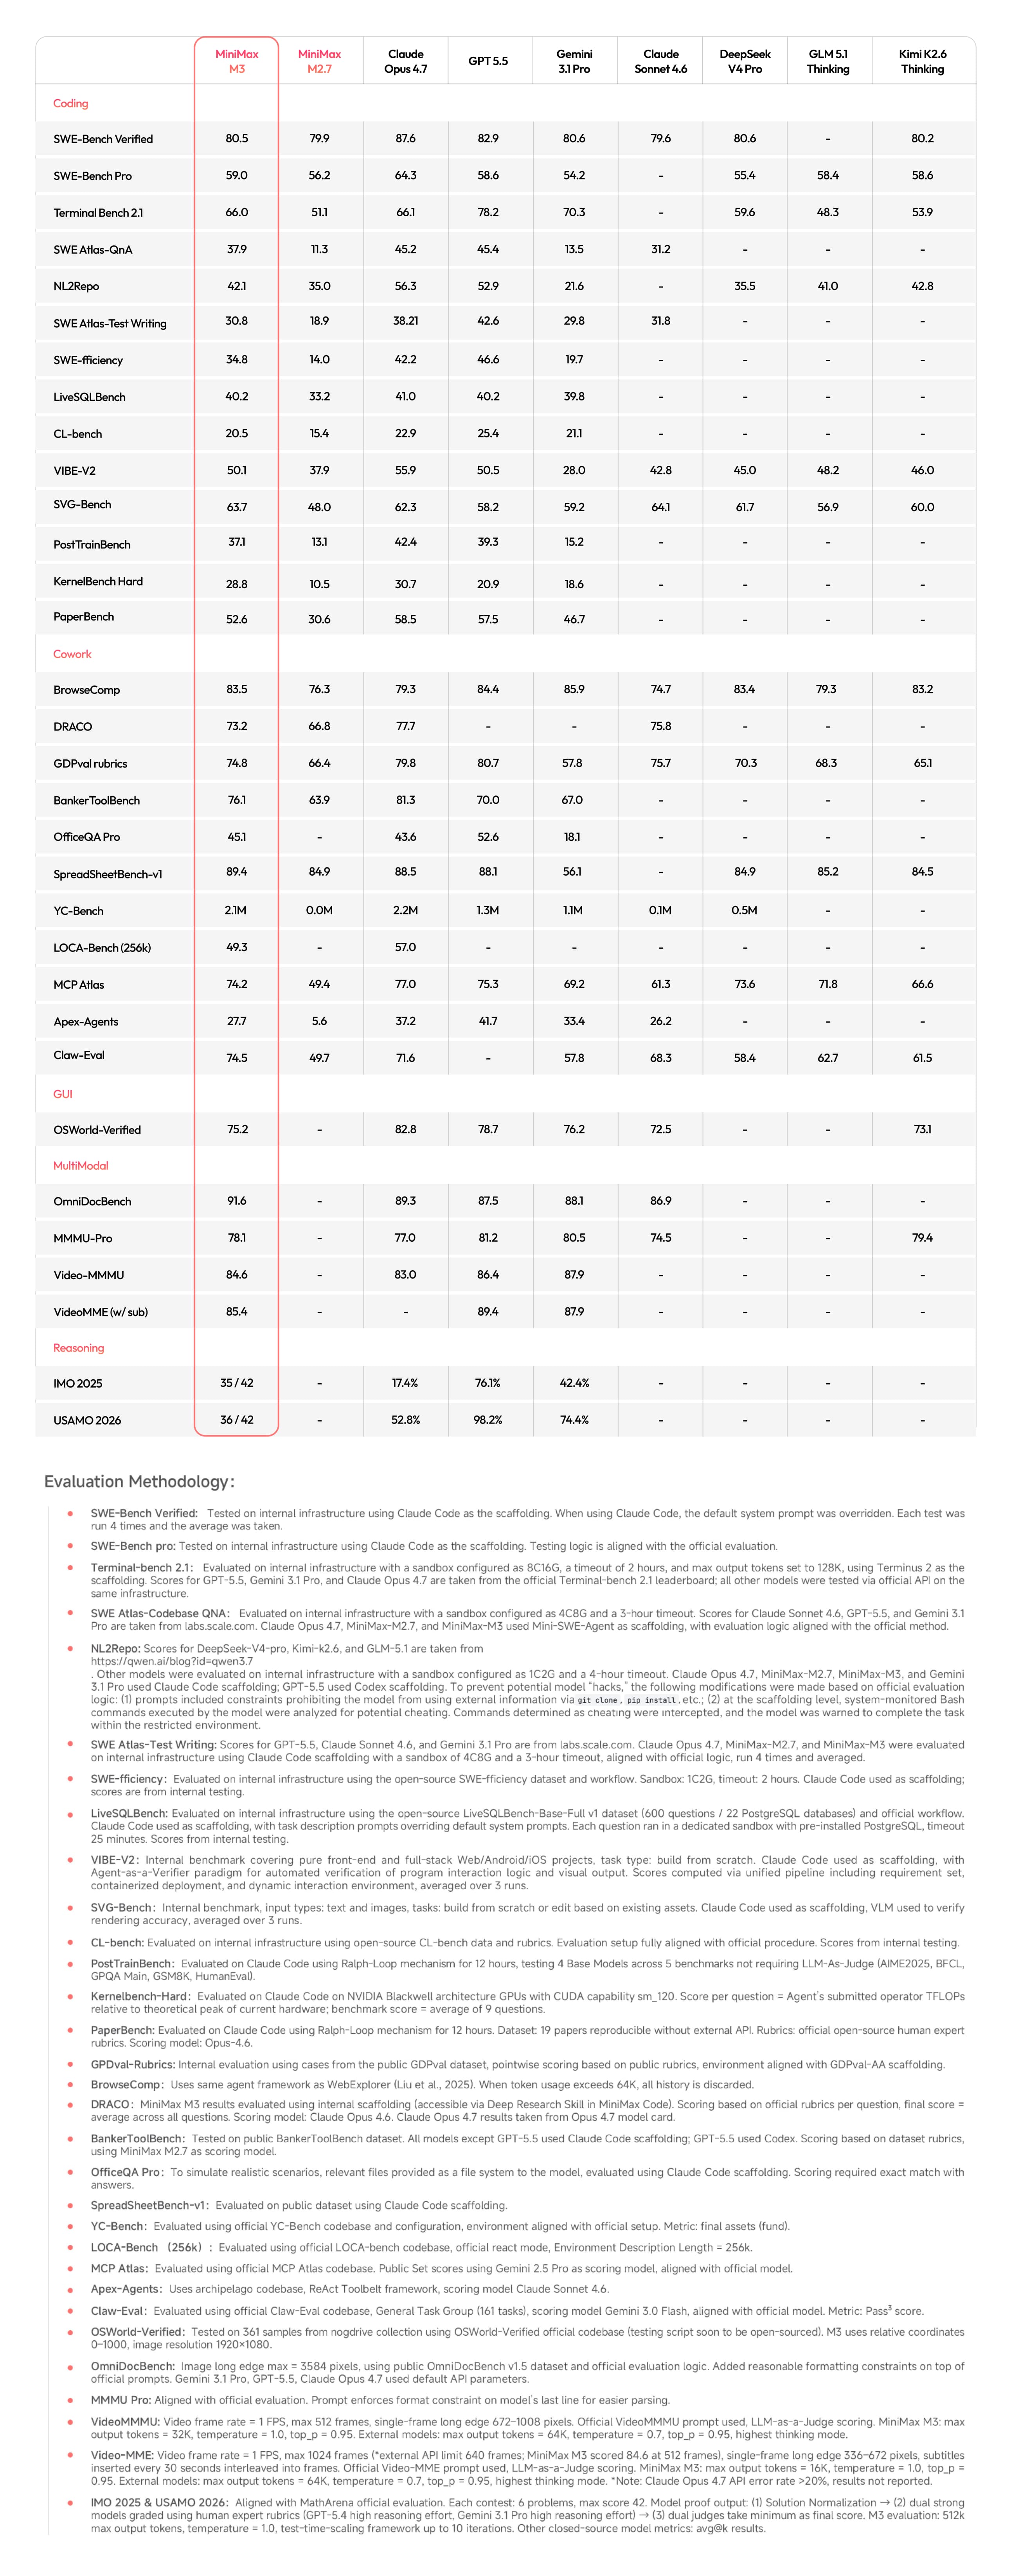
MiniMax AI has entered the open-weight model space with the release of MiniMax-M3, a new multimodal foundation model. Available now on Hugging Face, the model stands out for its sophisticated Mixture-of-Experts (MoE) architecture, a design choice often used to scale models efficiently without a proportional increase in computational cost.
M3 is designed as a versatile system, capable of handling a diverse range of inputs and tasks. Its core strengths lie in its multimodal understanding, allowing it to process and interpret both text and images. Beyond vision, the model is also engineered for coding and complex reasoning, positioning it as a powerful tool for developing more capable AI agents.
The use of an MoE architecture is the key technical detail here. This design activates only relevant neural network pathways—or 'experts'—for a given task. This allows the model to contain a vast number of parameters while keeping inference costs manageable, making powerful capabilities more accessible to a wider range of developers and researchers.
While the model's weights are publicly available, it's released under a custom license rather than a permissive open-source license. This 'open-weight' approach requires users to agree to specific terms for use, reflecting a growing trend where companies release powerful models with some restrictions.
Sources
More from MiniMax
All MiniMax releases →
MiniMax Releases H3 Image, Its Open Text-to-Image Model
The Chinese AI lab enters the open image-generation space with a single model that both creates and edits pictures from text.
MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.

MiniMax Opens Its Music3 Text-to-Music Model
The Chinese AI lab brings its music generation system to Hugging Face, expanding the roster of open audio models.
More in Vision-Language
All Vision-Language →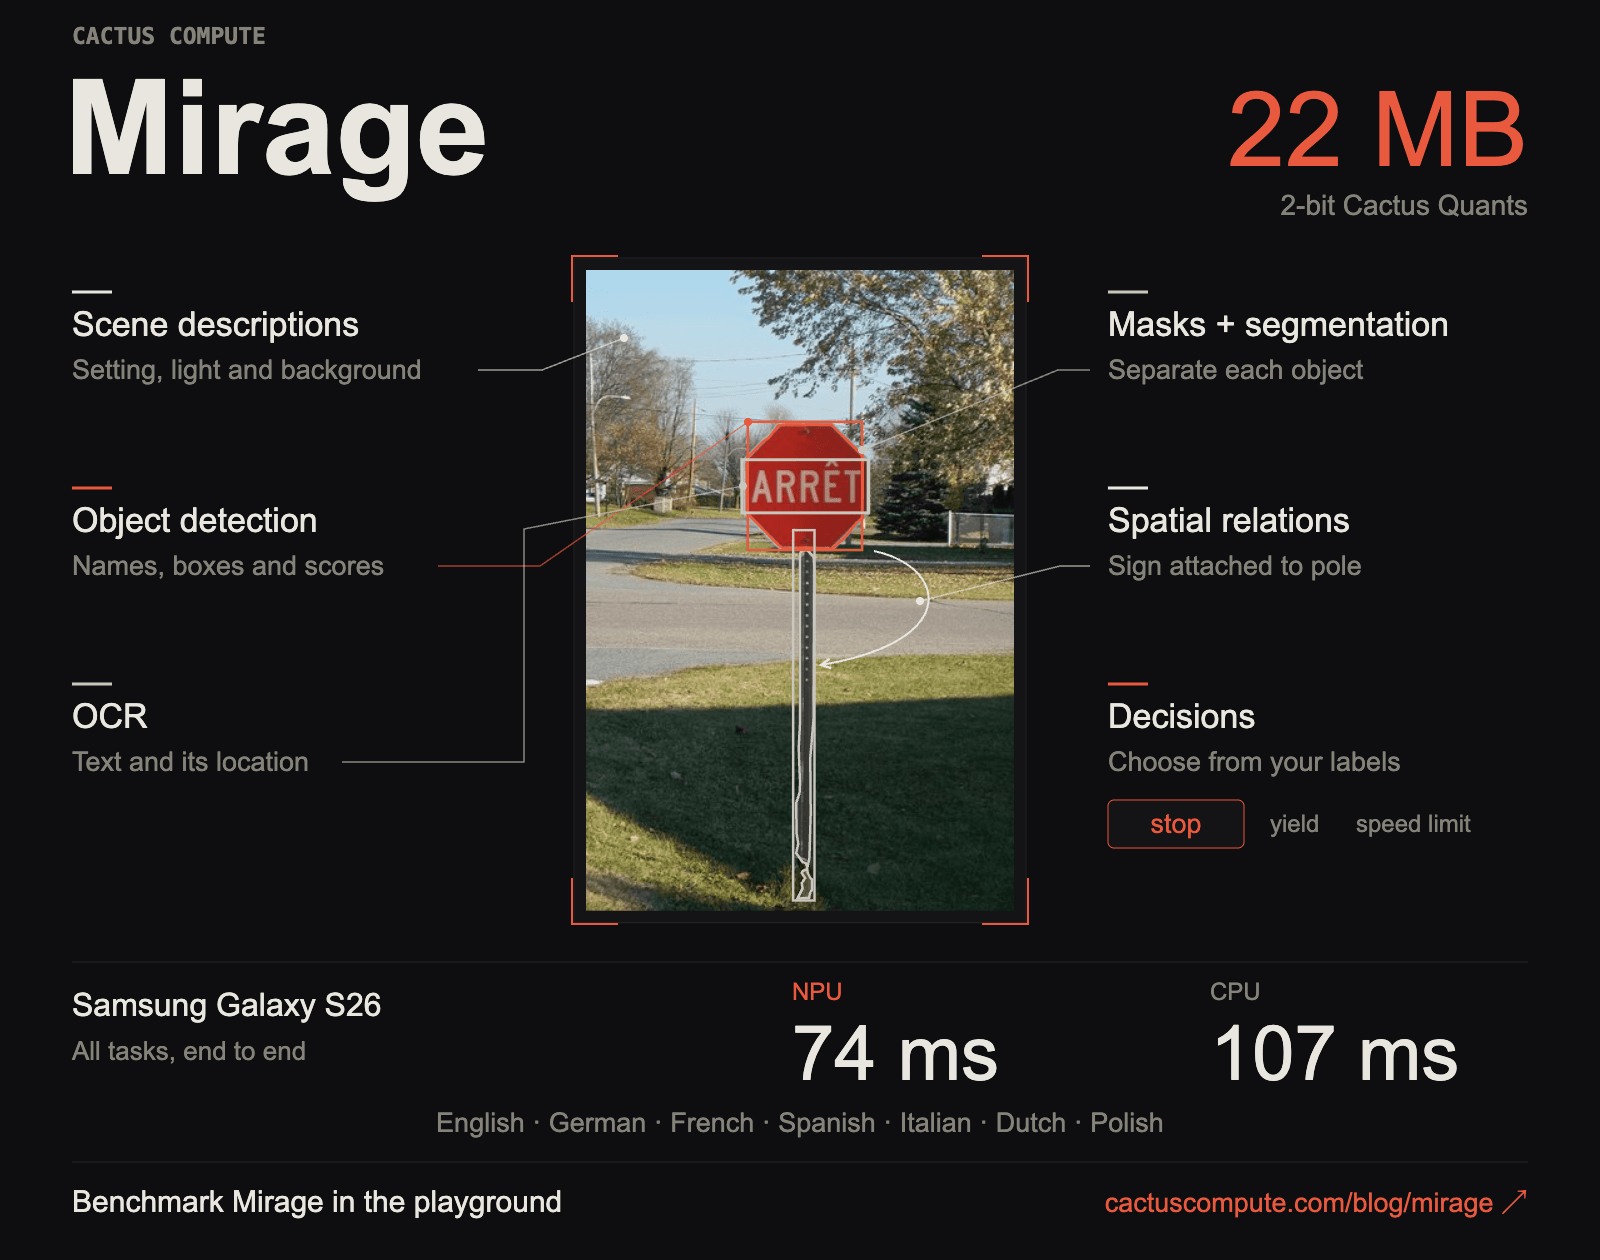
Cactus Compute's Mirage brings vision tasks on-device
The new open vision-language model targets detection, segmentation, and visual Q&A without relying on the cloud.
Thinking Machines ships Inkling-2-Small, an open MoE VLM
The Apache-2.0 vision-language model uses a mixture-of-experts design and lands openly on Hugging Face.
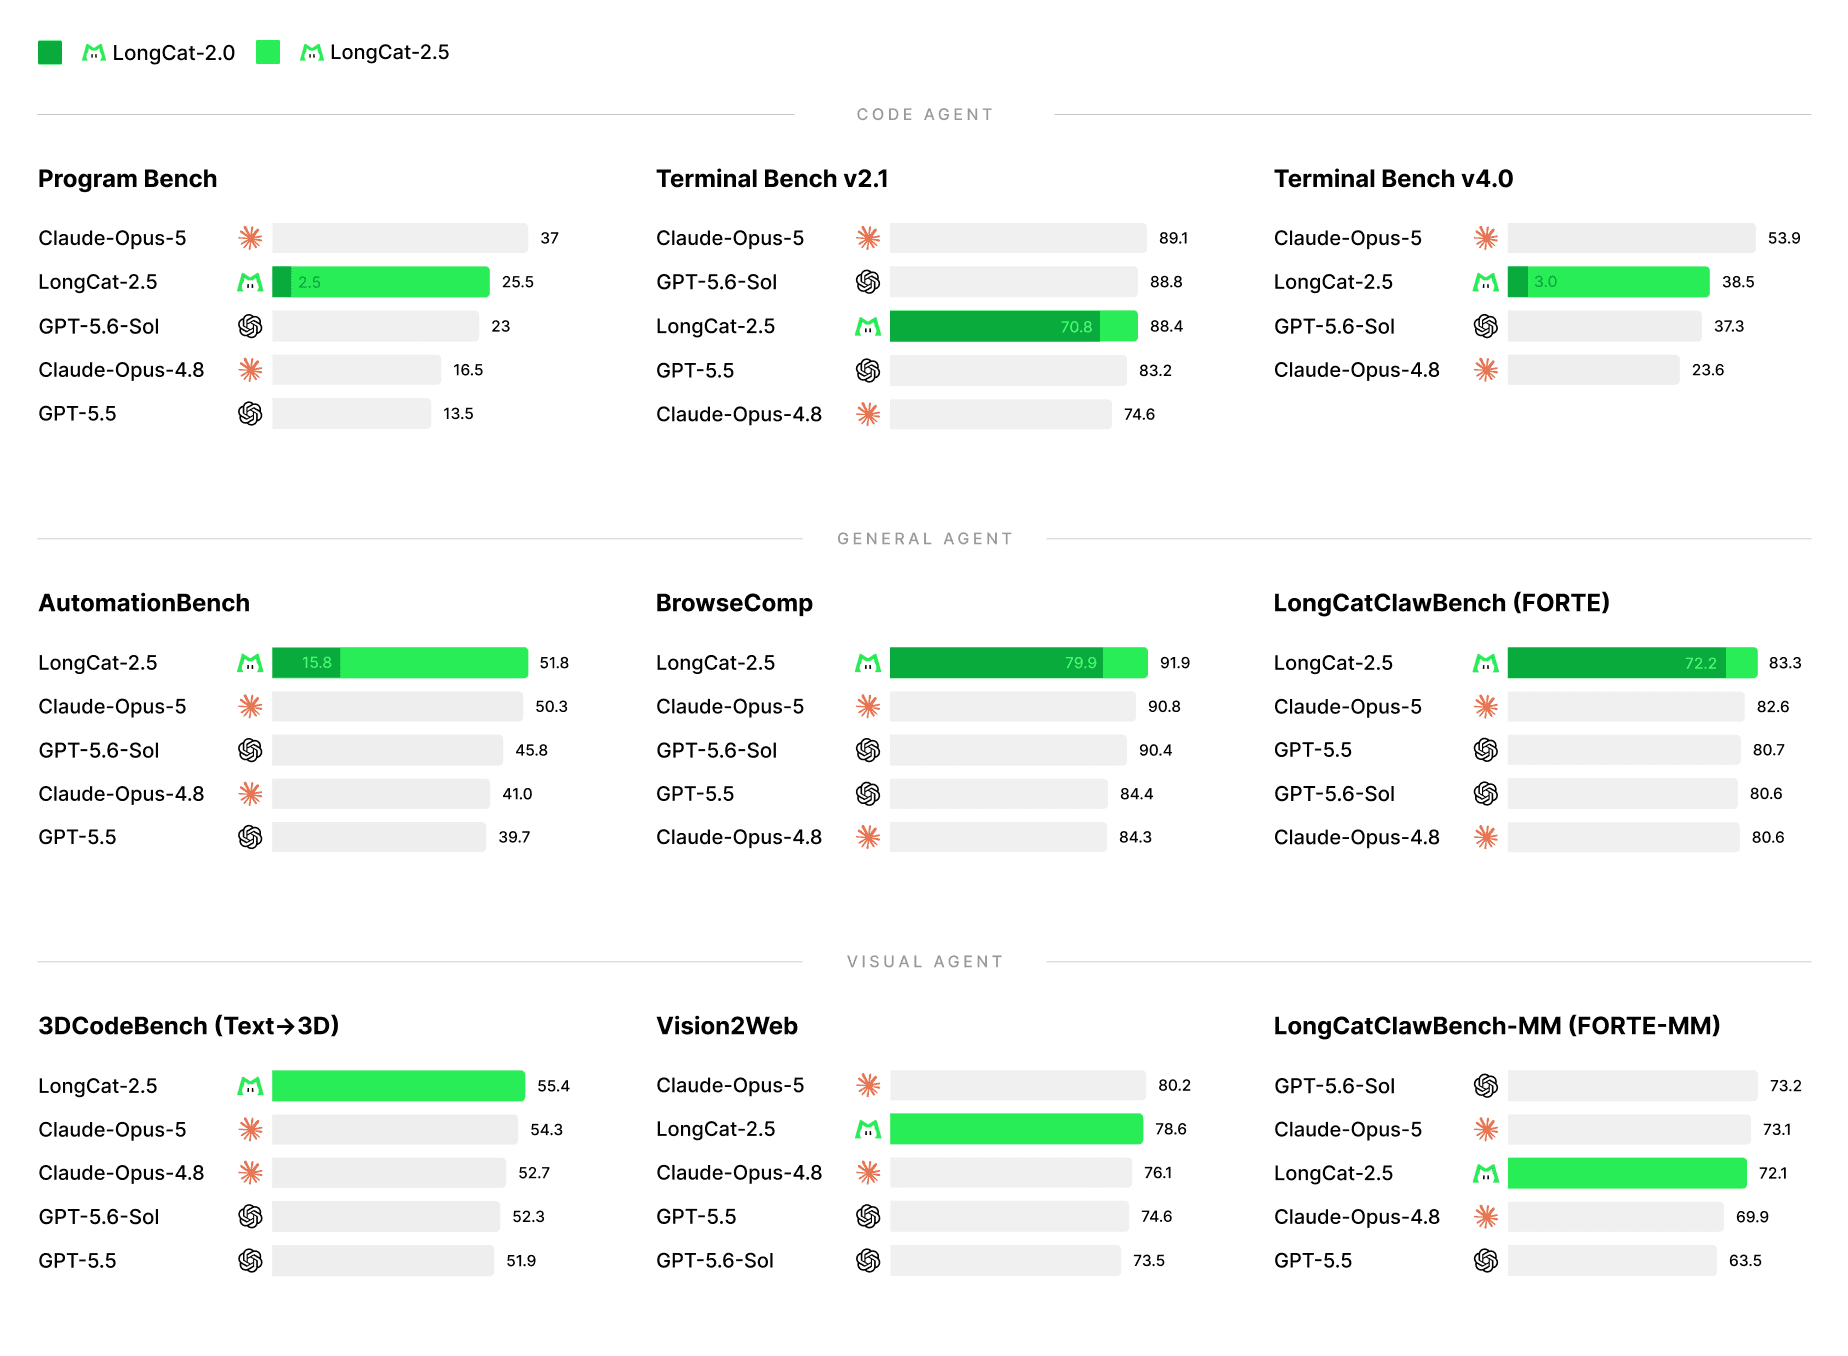
Meituan Releases LongCat 2.5, an MIT-Licensed MoE
The Chinese delivery giant expands its open-model push with a multimodal, agentic mixture-of-experts system.
0 comments
No comments yet. Be the first to weigh in.