MiniMax Opens Its Music3 Text-to-Music Model
The Chinese AI lab brings its music generation system to Hugging Face, expanding the roster of open audio models.

MiniMax has published MiniMax-Music3 on Hugging Face, an open text-to-music generation model from the Chinese AI lab best known for its large language and multimodal systems. The release moves MiniMax squarely into a corner of generative AI that has, until recently, been dominated by a handful of closed commercial services.
Music3 turns text prompts into audio, joining a growing class of models that let users describe a style, mood, or instrumentation and receive a generated track in return. Details on parameter count and architecture were not disclosed in the release record, and the model ships under a custom license rather than a standard permissive one, so prospective users should read the terms before building on it.
Why it matters
Open music models remain scarcer than their text and image counterparts, in part because of the thorny licensing and training-data questions that surround audio. Each credible open release gives researchers and developers something they can inspect and experiment with directly, rather than treating music generation as a black-box API.
- A new open entrant in a modality with few strong alternatives
- Backed by MiniMax, an established multimodal lab
- Released under a custom license worth reviewing closely
For teams weighing music generation, Music3 is worth a look — with the usual caveat that the practical value will depend on audio quality, prompt control, and how the license handles commercial use. Full details are available on the model's Hugging Face page.
Sources
- Visit
MiniMaxAI/MiniMax-Music3
Hugging Face
More in Music
StepFun's StepAudio 3 Music Plans Before It Plays
The new open model separates musical structure from sound, generating long-form tracks from text prompts with an explicit planning stage.
StepFun's StepAudio 3 Gen Unifies TTS and Music
A single discrete autoregressive model handles speech, voice design, sound effects, and music generation.
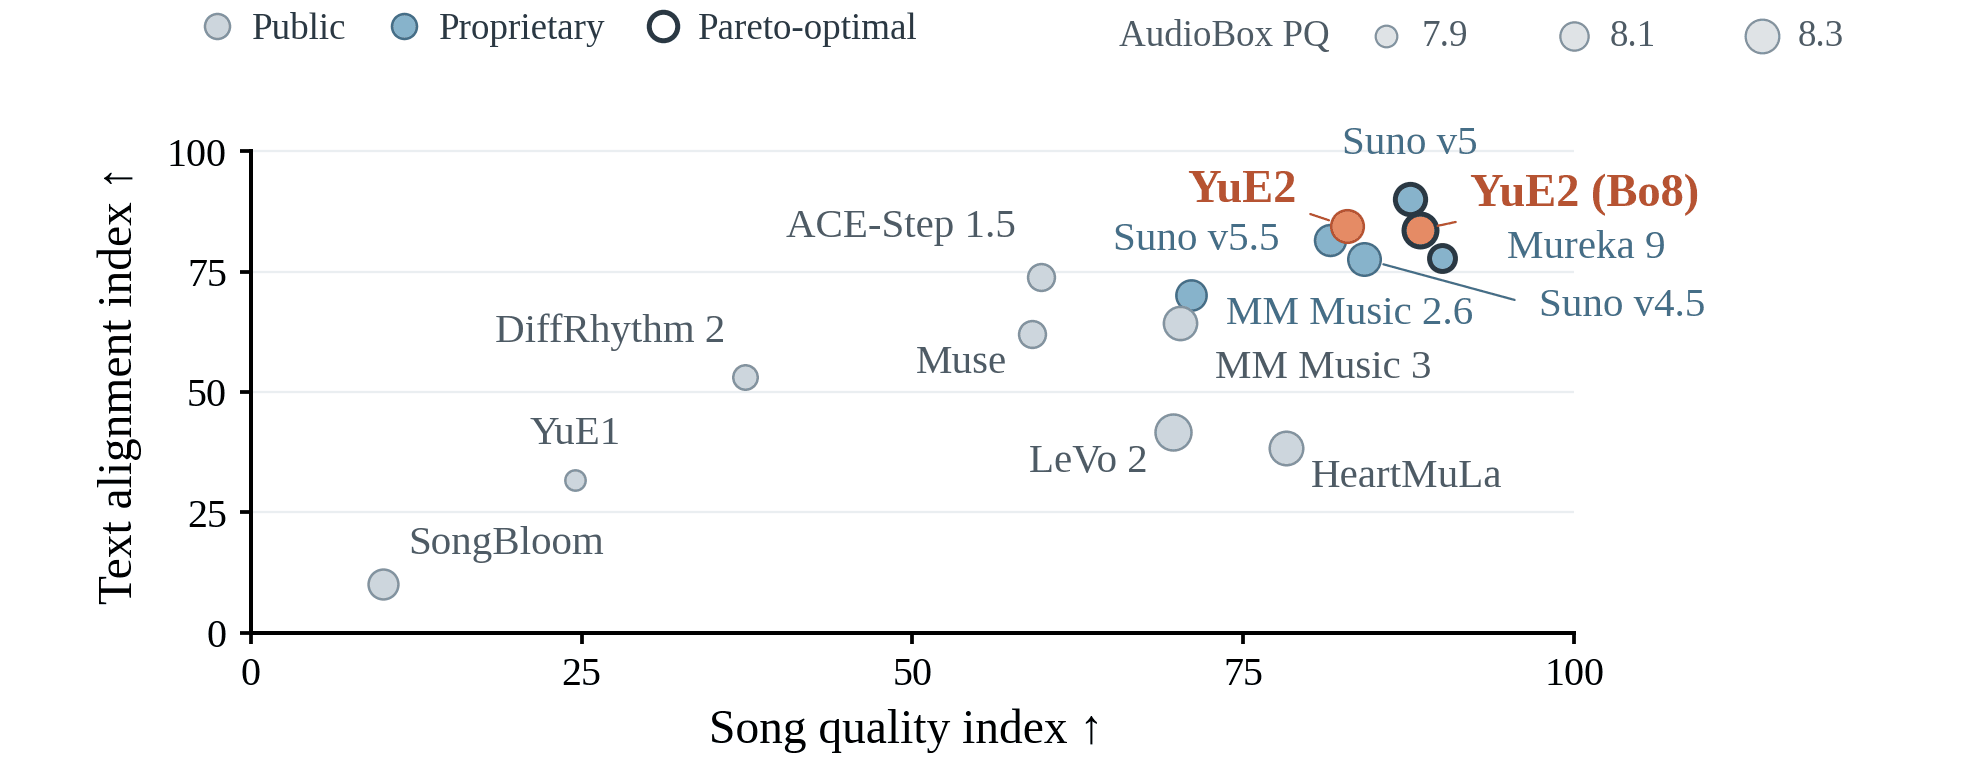
OpenMOSS Unveils YuE2-3B Music Generation Model
The 3-billion-parameter model adds symbolic planning and agentic editing to open-source music generation.
0 comments
No comments yet. Be the first to weigh in.