MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
MiniMax has released MiniMax-M3.1-Flash, a multimodal model that combines a mixture-of-experts (MoE) architecture with support for vision, code, and general any-to-any tasks. The model is available on Hugging Face under a custom license.
According to the release, M3.1 Flash is positioned as a versatile workhorse rather than a narrow specialist. It targets three overlapping use cases that have become the center of gravity for frontier open models:
- Agentic workflows, where a model plans and executes multi-step tasks
- Coding, a benchmark-heavy area where open models have made rapid gains
- Video understanding, extending the model beyond text and still images
Why it matters
The "Flash" naming signals a lean, speed-oriented tier, and the MoE design fits that goal: by activating only a subset of parameters per request, mixture-of-experts models can offer large-model capability at lower inference cost. That tradeoff has made MoE the default choice for labs shipping practical, deployable systems.
MiniMax has been steadily expanding its open-weight lineup, and M3.1 Flash reflects a broader industry shift toward consolidating multiple modalities into one model instead of maintaining separate systems for text, vision, and video. Full specifications — including parameter counts, active-expert configuration, and context length — were not detailed in the release record, so developers will want to consult the model card directly before building on it.
Sources
- Visit
MiniMaxAI/MiniMax-M3.1-Flash
Hugging Face
More from MiniMax
All MiniMax releases →
MiniMax Opens Its Music3 Text-to-Music Model
The Chinese AI lab brings its music generation system to Hugging Face, expanding the roster of open audio models.
MiniMax Releases H3 Video Model on Hugging Face
The company's new diffusion model handles text-to-video and image-to-video, with support for joint audio-video generation.
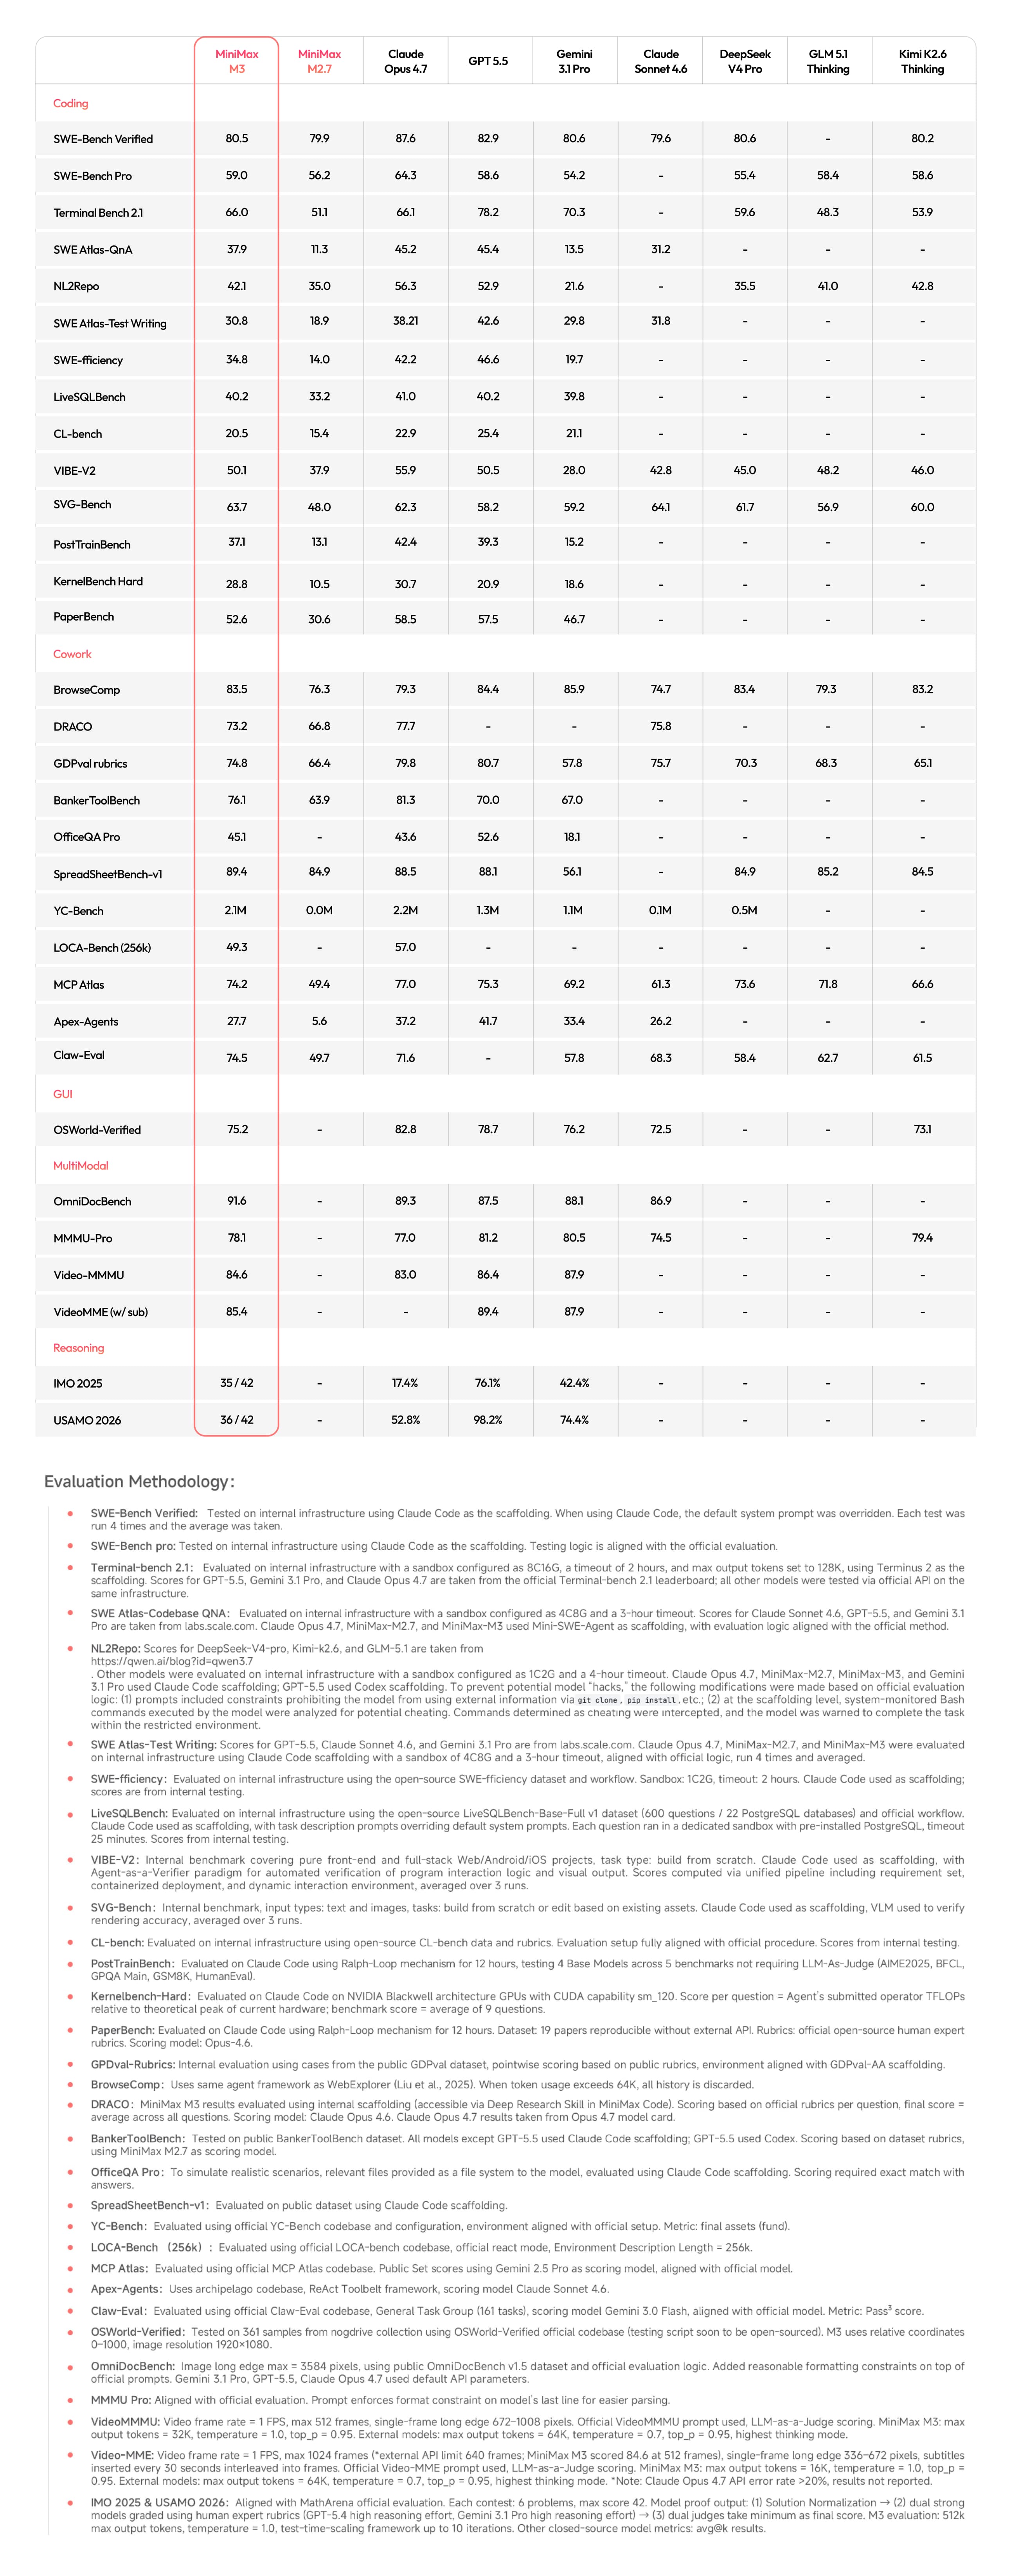
MiniMax Releases M3, a Multimodal MoE Model
The new open-weight model from MiniMax AI combines vision, coding, and reasoning using a Mixture-of-Experts architecture.
More in Vision-Language
All Vision-Language →
DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE
The new vision-language model carries 120B total parameters but activates just 12B per token, aiming to keep multimodal inference efficient.
0 comments
No comments yet. Be the first to weigh in.