DeepSeek Releases V4.1-Flash, an Open Multimodal MoE
The new mixture-of-experts model handles text, vision, and reasoning, and ships under a permissive MIT license.

DeepSeek has published DeepSeek-V4.1-Flash, a mixture-of-experts (MoE) model that combines text, vision, and reasoning capabilities in a single release. The weights are available now on Hugging Face under an MIT license, one of the most permissive terms a developer can adopt.
The "Flash" naming signals DeepSeek's intent to position this as a faster, more efficient member of the V4.1 line. As an MoE design, the model routes each input through a subset of specialized expert networks rather than activating every parameter, a approach that keeps inference costs lower while preserving capacity. DeepSeek has not published a full parameter count or context window alongside this release.
Why it matters
Multimodal models that are genuinely open remain relatively scarce, and an MIT license removes most of the friction that holds teams back from building on or fine-tuning a model commercially. The combination here is notable:
- Text, vision (VLM), and reasoning in one checkpoint
- MoE architecture aimed at efficient inference
- Fully permissive MIT terms
DeepSeek has built a reputation for shipping competitive open models at a pace that pressures both open and closed competitors, and V4.1-Flash extends that strategy into multimodal territory. Developers evaluating the release will want to confirm context length, active-parameter counts, and benchmark figures as more documentation lands on the model's Hugging Face page.
Sources
More from DeepSeek
All DeepSeek releases →DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.

DeepSeek adds vision to its V4 Flash line
An experimental, MIT-licensed vision-language model brings image understanding to DeepSeek's fast V4 Flash architecture.
DeepSeek Releases V4-Pro-0813 With Open Weights
The Chinese lab pushes a higher-capability checkpoint of its V4 line to Hugging Face under a permissive MIT license.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.
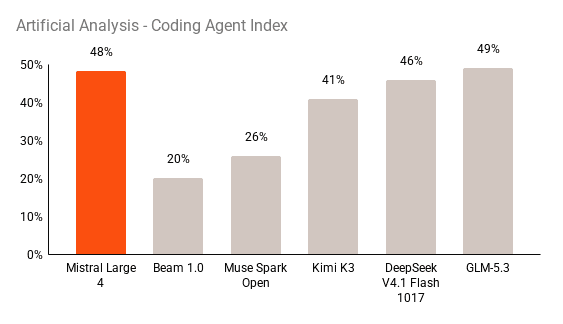
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.
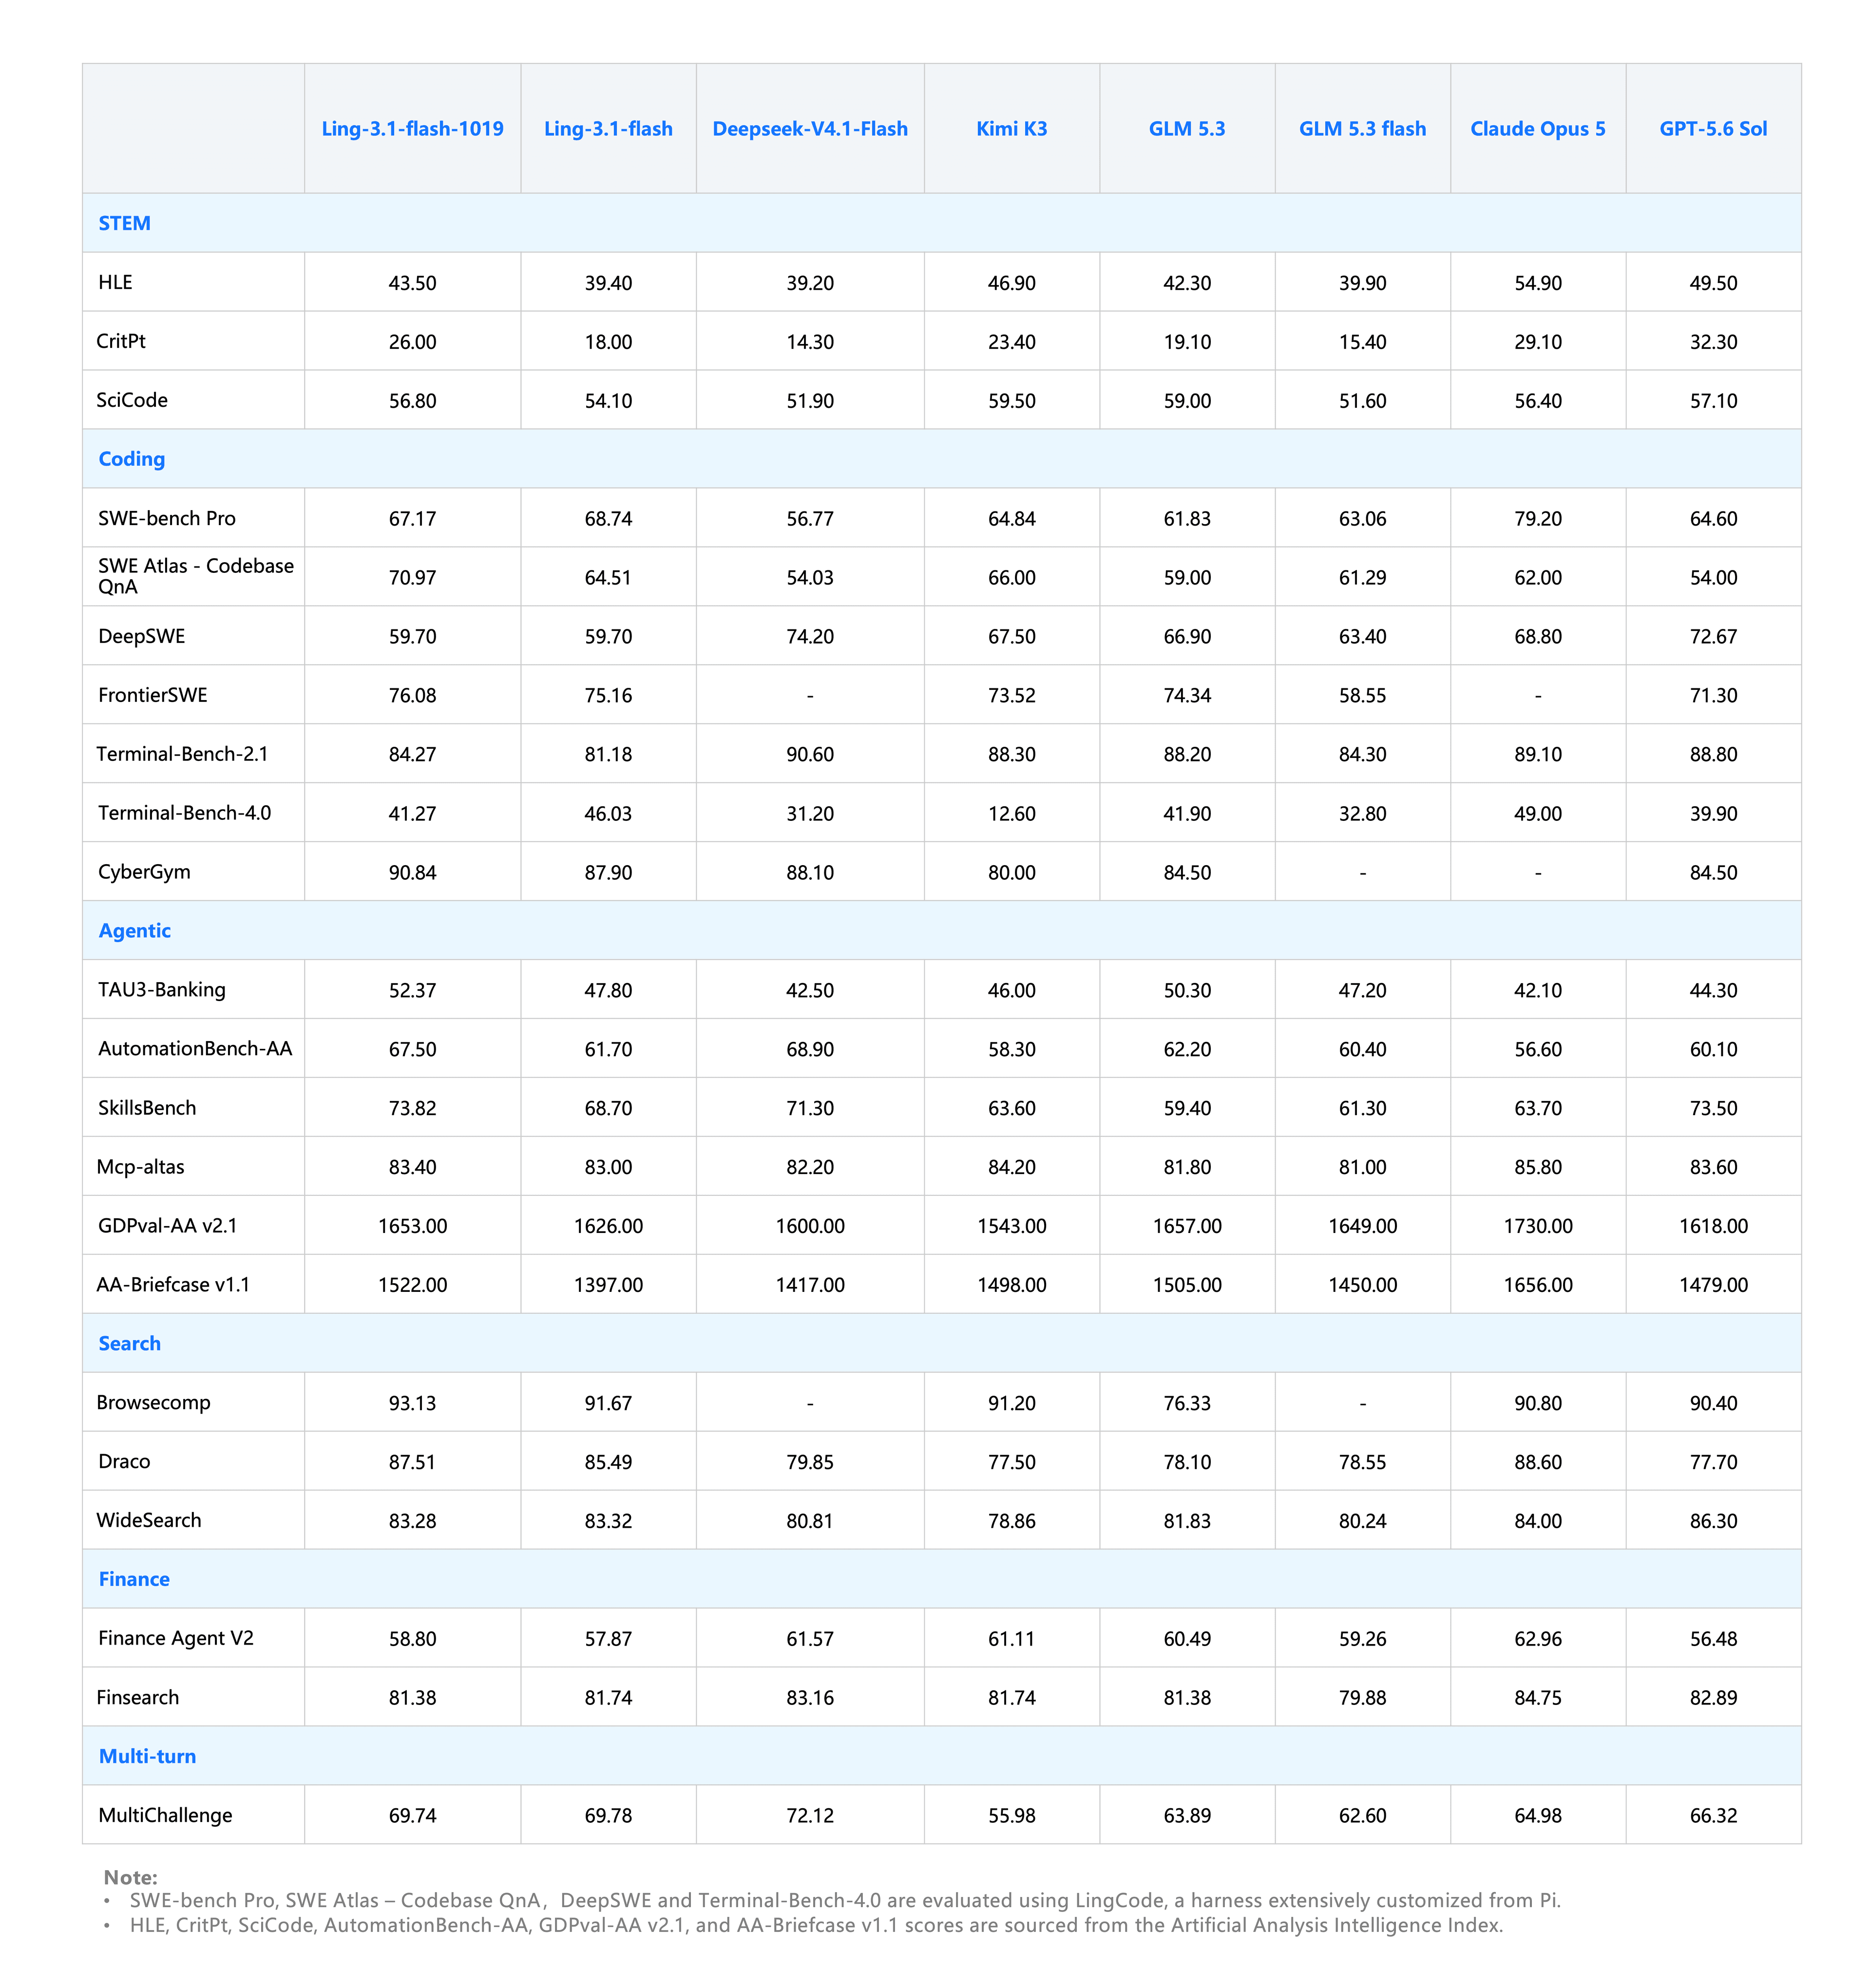
inclusionAI releases Ling-3.1-flash, an MIT MoE model
The new text model pairs a hybrid mixture-of-experts design with FP8 weights under a permissive license.
0 comments
No comments yet. Be the first to weigh in.