DeepSeek adds vision to its V4 Flash line
An experimental, MIT-licensed vision-language model brings image understanding to DeepSeek's fast V4 Flash architecture.

DeepSeek has published DeepSeek-V4-Flash-Vision-Exp, an experimental vision-language variant of its V4 Flash model. As the name signals, this is a work-in-progress release rather than a polished flagship, but it extends the company's fast, lightweight line into multimodal territory.
The model handles both image and text inputs, pairing visual understanding with the text generation of the underlying Flash architecture. Like other recent DeepSeek releases, it uses a mixture-of-experts design, which activates only part of the network per token to keep inference costs down while preserving capacity.
Why it matters
DeepSeek has built a reputation for shipping capable models under permissive terms, and this release continues that pattern:
- It carries an MIT license, allowing broad commercial and research use.
- It targets the Flash tier, oriented toward efficiency rather than maximum scale.
- It marks the family's first step into vision-language tasks.
The "Exp" tag is a clear caution: DeepSeek is signaling that behavior, capabilities, and stability may shift before any production-grade version arrives. For developers, that makes this a model to experiment with rather than deploy, but it offers an early look at how DeepSeek intends to fold vision into its faster models. Details on parameter counts, context length, and benchmarks were not specified in the release; those interested should consult the model card directly.
Sources
- Visit
deepseek-ai/DeepSeek-V4-Flash-Vision-Exp
Hugging Face
More from DeepSeek
All DeepSeek releases →
DeepSeek Releases V4-Pro-0813 With Open Weights
The Chinese lab pushes a higher-capability checkpoint of its V4 line to Hugging Face under a permissive MIT license.
DeepSeek Releases V4-Pro, an MIT-Licensed MoE Model
The company's newest flagship targets reasoning and coding while keeping a permissive open-source license.

DeepSeek Ships V4-Flash, a 304B MoE Tuned for Agents
The latest checkpoint in DeepSeek's V4 line leans into agentic workflows while keeping the permissive MIT license.
More in Vision-Language
All Vision-Language →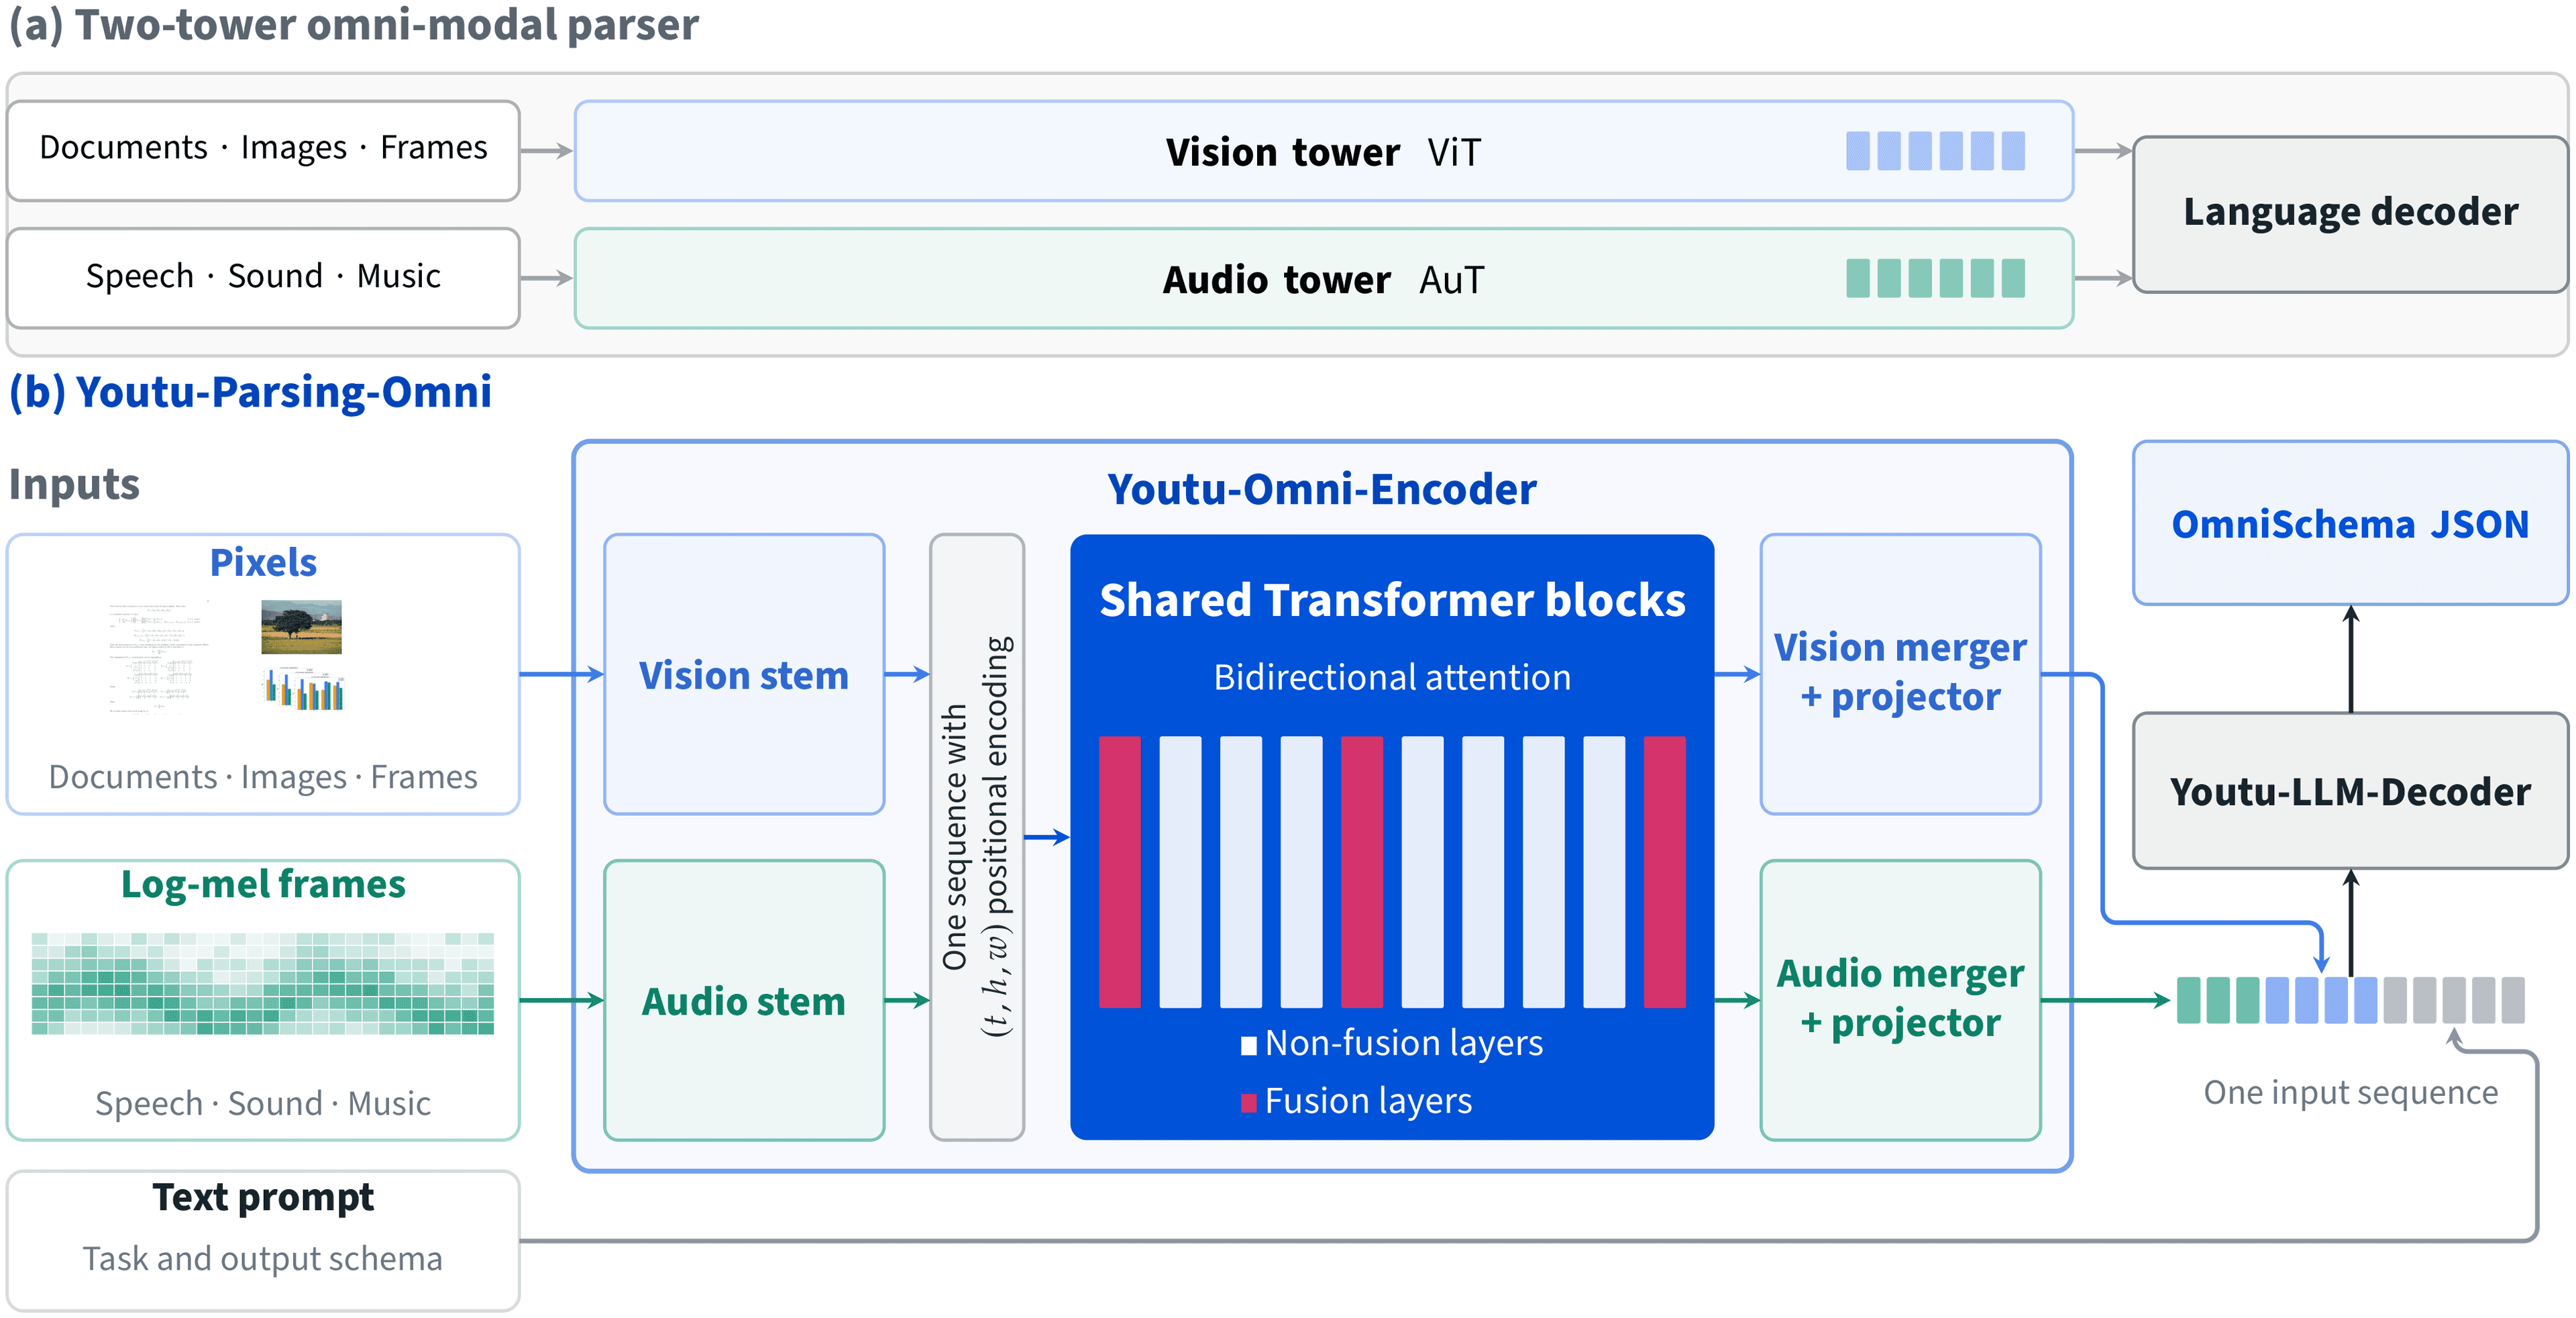
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
Liquid AI's d1-3B brings multimodal models to the edge
The new LFM2-based d1-3B is a compact vision-language model aimed at running decisions directly on-device.
OpenBMB's MiniCPM-V 4.7 brings MoE to vision models
The new 35B-parameter vision-language model activates just 3B parameters per pass, aiming for efficiency without sacrificing capability.
0 comments
No comments yet. Be the first to weigh in.