DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.

DeepSeek has published a new checkpoint in its Flash family, DeepSeek-V4.1-Flash-1017, on Hugging Face. The model combines vision-language understanding with text generation and reasoning, and it ships under a permissive MIT license that allows commercial use.
The Flash branding signals DeepSeek's lighter, latency-focused tier, meant to run more efficiently than the company's flagship models while still covering a broad set of tasks. Under the hood it uses a mixture-of-experts (MoE) design, which activates only a subset of parameters per token to keep inference costs down.
Why it matters
Multimodal capability is quickly becoming table stakes for open-weight releases, and DeepSeek extending that into its fast Flash line lowers the barrier for developers who need image-aware reasoning without paying for the largest checkpoints.
- Vision-language, text, and reasoning in a single model
- Mixture-of-experts architecture for efficient inference
- MIT license, permitting commercial deployment
DeepSeek has not published detailed specifications such as parameter counts or context length alongside the release, so independent evaluation will determine how the checkpoint stacks up against peers. For now, the weights are available directly from the project's Hugging Face repository.
Sources
- Visit
deepseek-ai/DeepSeek-V4.1-Flash-1017
Hugging Face
More from DeepSeek
All DeepSeek releases →
DeepSeek adds vision to its V4 Flash line
An experimental, MIT-licensed vision-language model brings image understanding to DeepSeek's fast V4 Flash architecture.
DeepSeek Releases V4-Pro, an MIT-Licensed MoE Model
The company's newest flagship targets reasoning and coding while keeping a permissive open-source license.
DeepSeek Releases V4-Pro-0813 With Open Weights
The Chinese lab pushes a higher-capability checkpoint of its V4 line to Hugging Face under a permissive MIT license.
More in Vision-Language
All Vision-Language →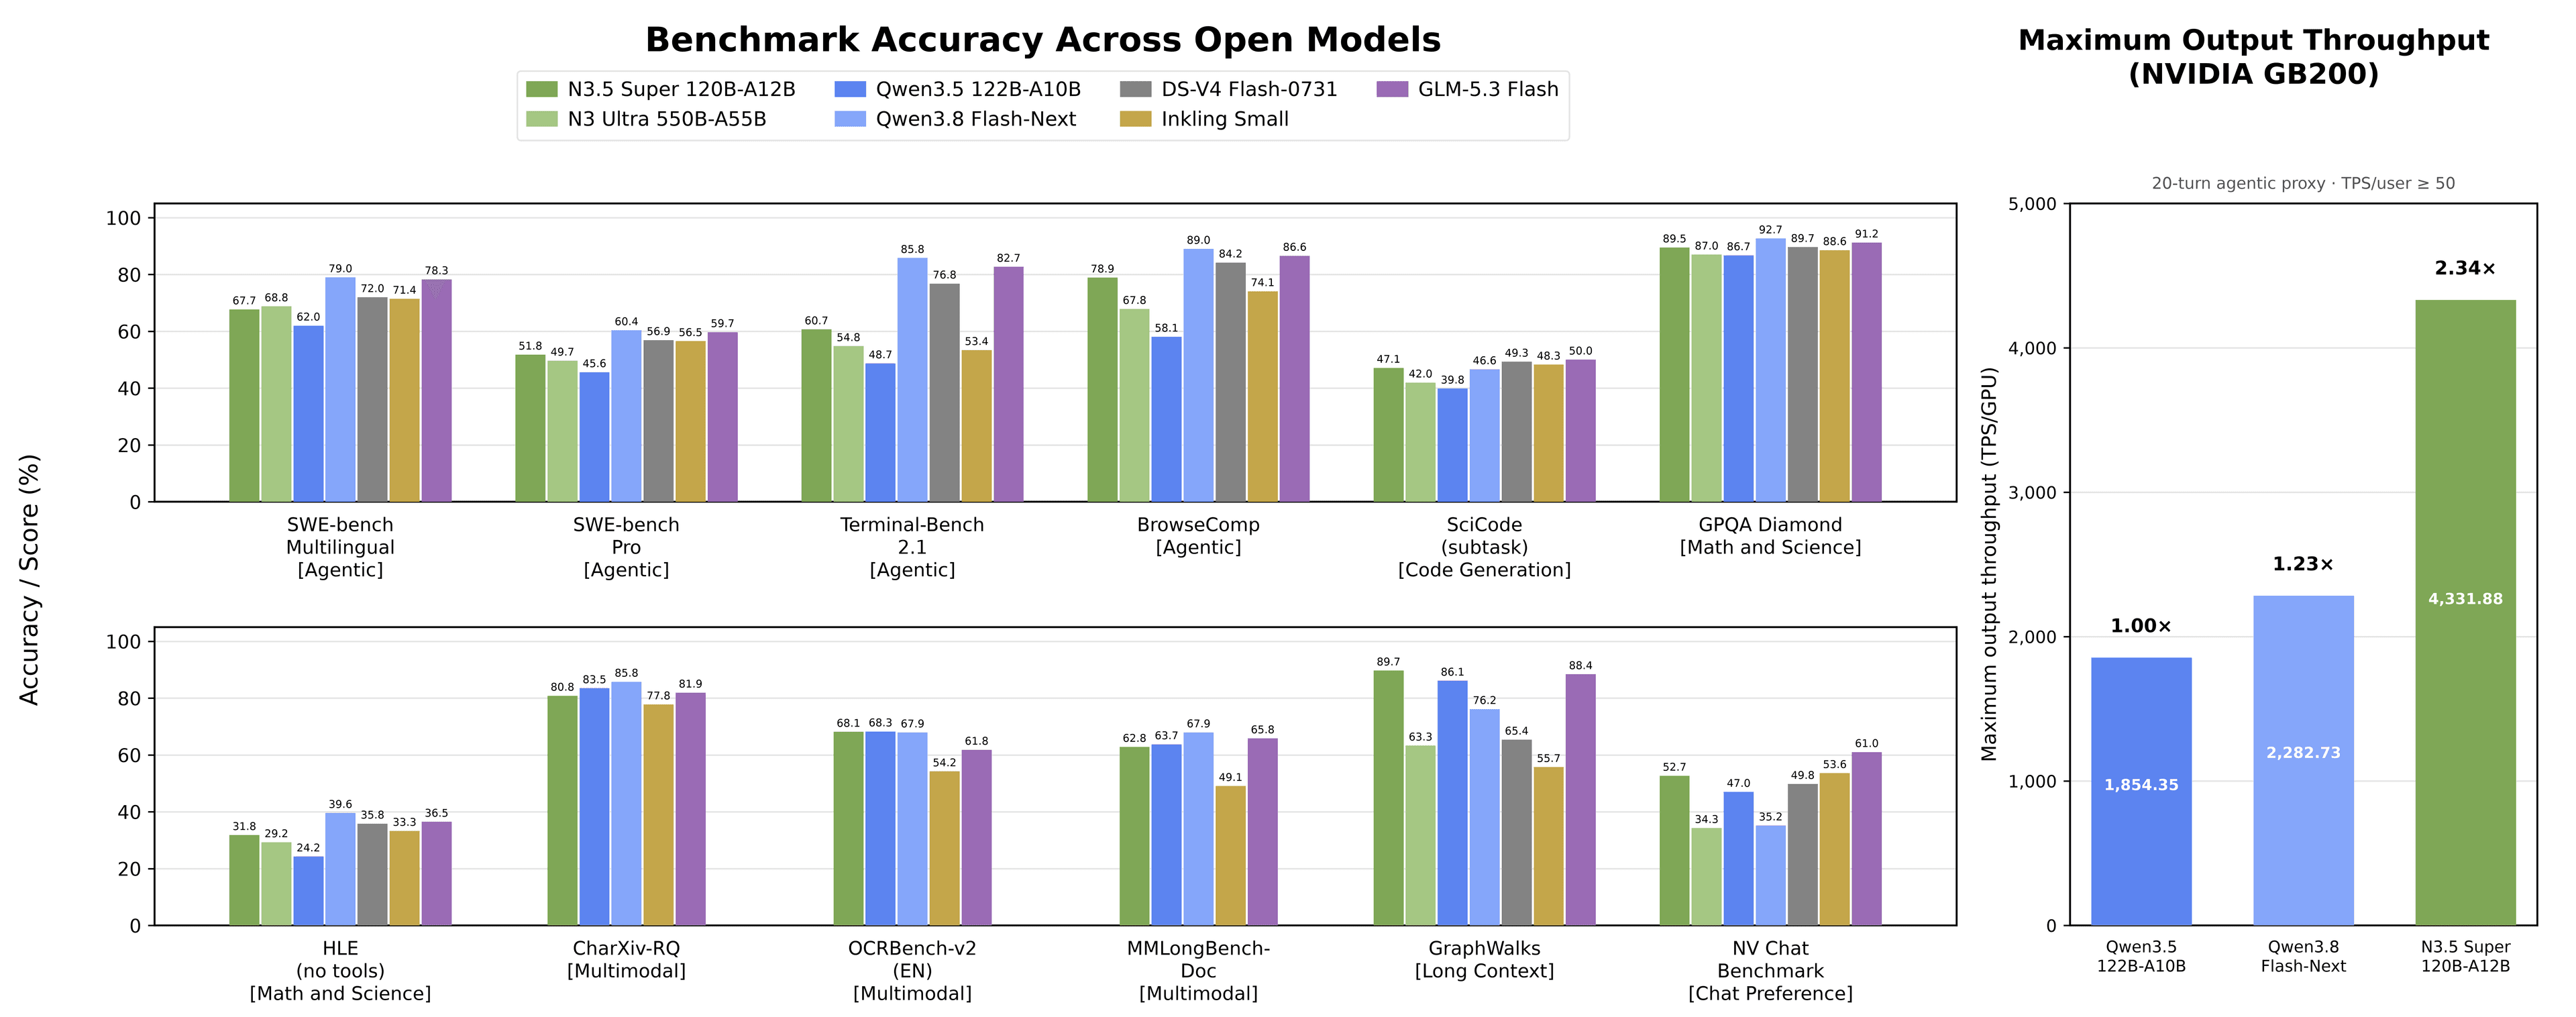
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
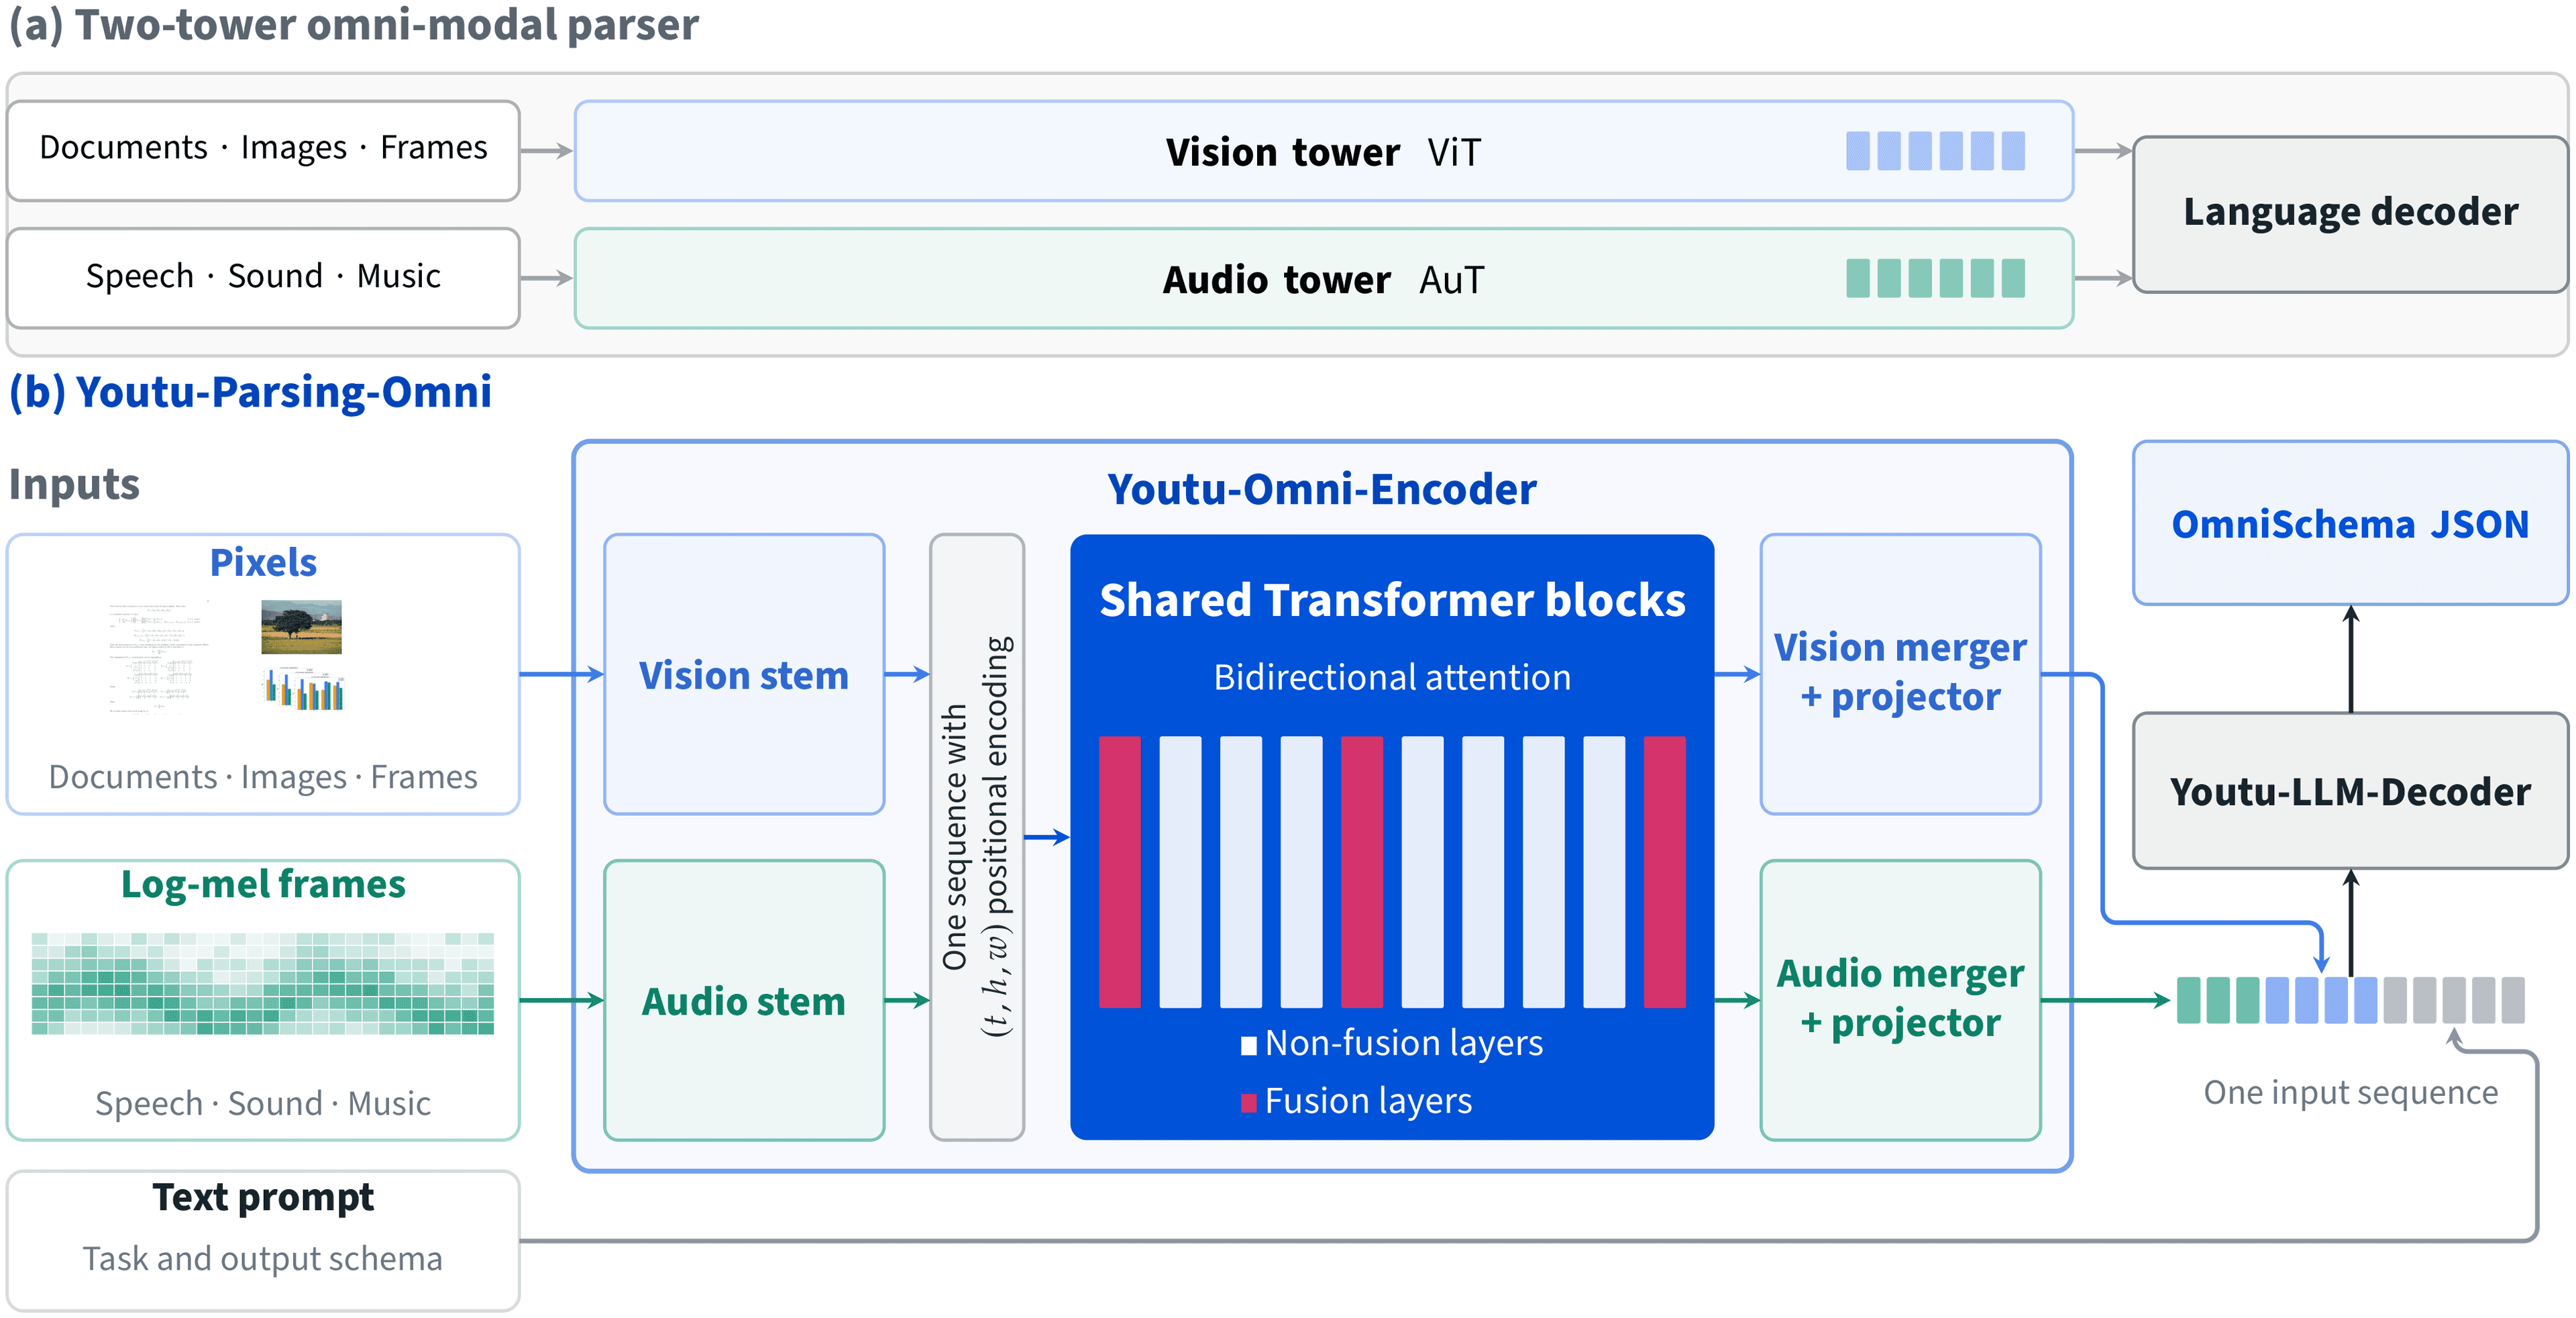
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
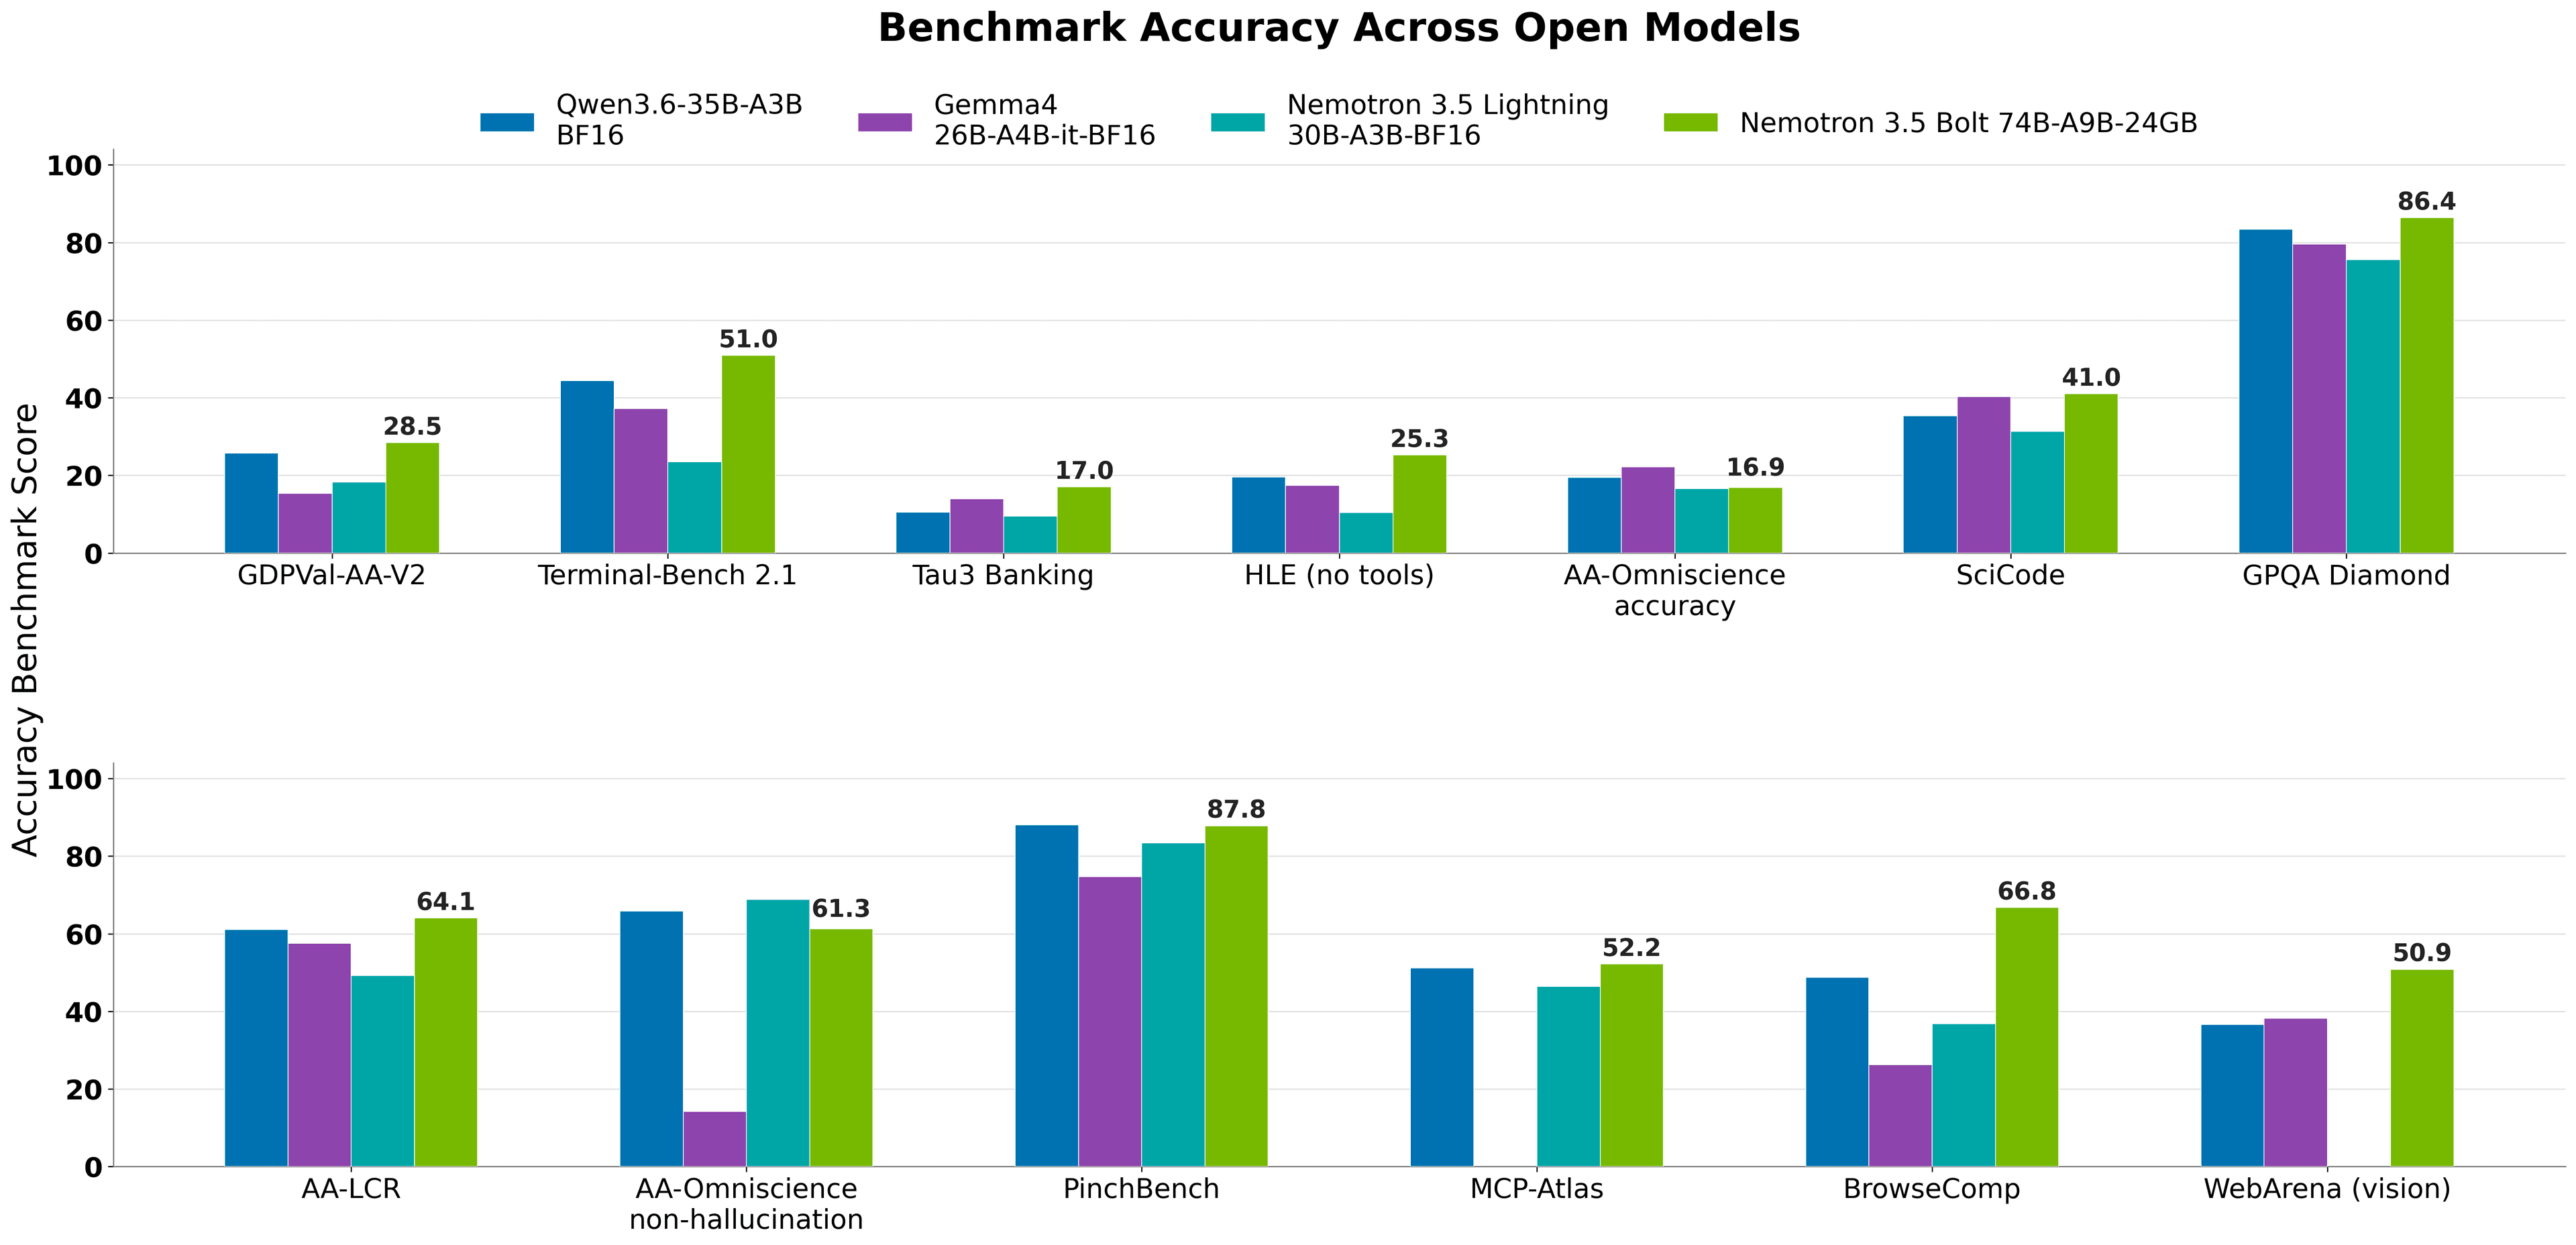
NVIDIA's Nemotron-3.5 Bolt targets 24GB GPUs
A multimodal mixture-of-experts model with 74B total parameters but just 9B active, tuned to fit consumer-class hardware.
0 comments
No comments yet. Be the first to weigh in.