The Open Weights
LatestModelsLeaderboardsCompanies
Subscribe
The Open Weights

The daily record of open-source AI. New model releases, leaderboards, and what's coming next — written for people who ship.

Refreshed every 12 hours

Discover

  • Latest releases
  • New today
  • Trending models

Browse

  • All models
  • Companies
  • Categories
  • Leaderboards

About

  • About
  • Editorial policy
  • Hardware estimates
  • RSS feed
  • llms.txt
  • Newsletter

© 2026 The Open Weights. An independent publication.

PrivacyTermsSMSAggregated by Claude · curated by humans.

Category · text

Latest Reasoning models

Open models tuned for step-by-step problem solving — math, logic, and multi-step planning — that show their work and trade extra compute for harder answers.

Filter

80 releases

DeepSeek/Vision-LanguageMajor releaseDatacenter

DeepSeek V4.1-Flash Adds Vision and Reasoning

The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.

Oct 17, 2026
Text / LLMReasoning
DeepSeek-V4.1-Flash (1017)
Meta AI/Any-to-Any
Major release

Meta's Muse Spark Open Targets Agentic Coding

The new open-weight model pairs a million-token context window with Meta's bet on long-horizon coding agents.

Oct 15, 2026
CodeText / LLM
InternScience/Vision-LanguageConsumer GPU

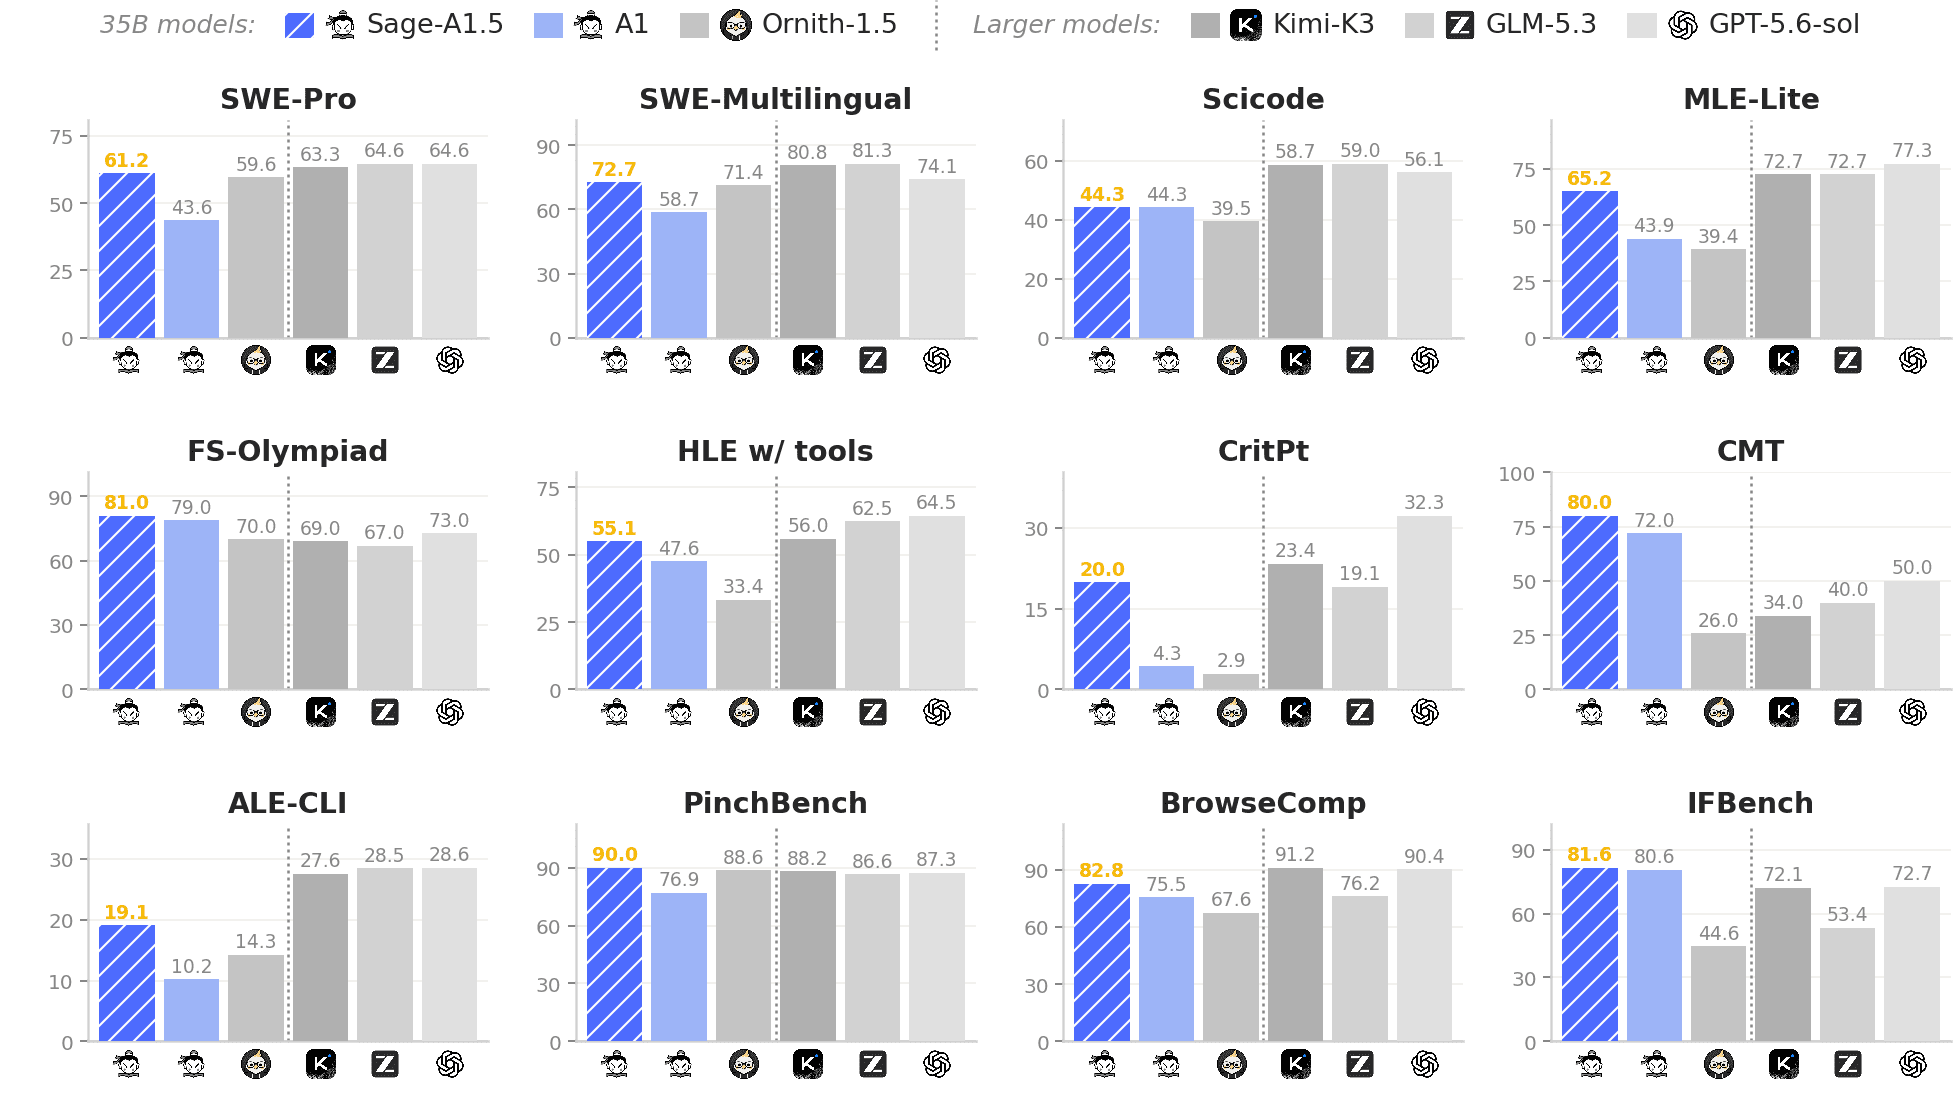
Sage-A1.5 Brings Agentic Vision to Open MoE Models

InclusionAI's new mixture-of-experts model pairs visual understanding with tool use and code, aiming at agentic workflows under an Apache 2.0 license.

Oct 15, 2026
CodeReasoning
Sage-A1.5
Xiaomi/Vision-Language

Xiaomi's MiMo-V2.6 bets on RL for self-improvement

The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.

Oct 7, 2026
Any-to-AnyReasoning
Reflection/ReasoningMajor releaseMulti-GPU server

Reflection releases Beam 1.0, a 501B open MoE

The frontier AI startup's first open-weight model activates just 23B parameters per token while targeting reasoning, code, and tool use.

Oct 7, 2026
CodeText / LLM
Beam 1.0 501B-A23B
Mistral AI/Text / LLMMajor releaseDatacenter

Mistral Large 4 arrives as a trillion-param MoE

The new flagship is a sparse mixture-of-experts model with roughly 49B active parameters per token.

Oct 6, 2026
Text / LLMReasoning
OpenAI/Text / LLMMajor releaseMulti-GPU server

Reflection releases Beam, a 501B open-weight model

The startup's first frontier-scale model ships with downloadable weights and a mixture-of-experts design aimed at reasoning.

Oct 5, 2026
Text / LLMReasoning
Reflection AI/Text / LLMMulti-GPU server

Reflection AI debuts Beam, a 501B open model

The startup's first open-weight release is a dense 501-billion-parameter model aimed at text and reasoning tasks.

Oct 5, 2026
Text / LLMReasoning
Aleph Alpha/ReasoningWorkstation GPU

Aleph Alpha releases Kolibri, a sovereign reasoning model

The German AI company's open-weight mixture-of-experts model targets European needs with strong German and English reasoning.

Oct 2, 2026
Text / LLMReasoning
Kolibri-1
BAAI/ReasoningConsumer GPU

AREX-2 arrives as an open deep-research agent model

The reasoning-focused release pairs tool use with long context and self-improvement, and ships as a vision-language model on Hugging Face.

Sep 29, 2026
ReasoningVision-Language
AREX-2
Xiaomi/Any-to-AnyMulti-GPU server

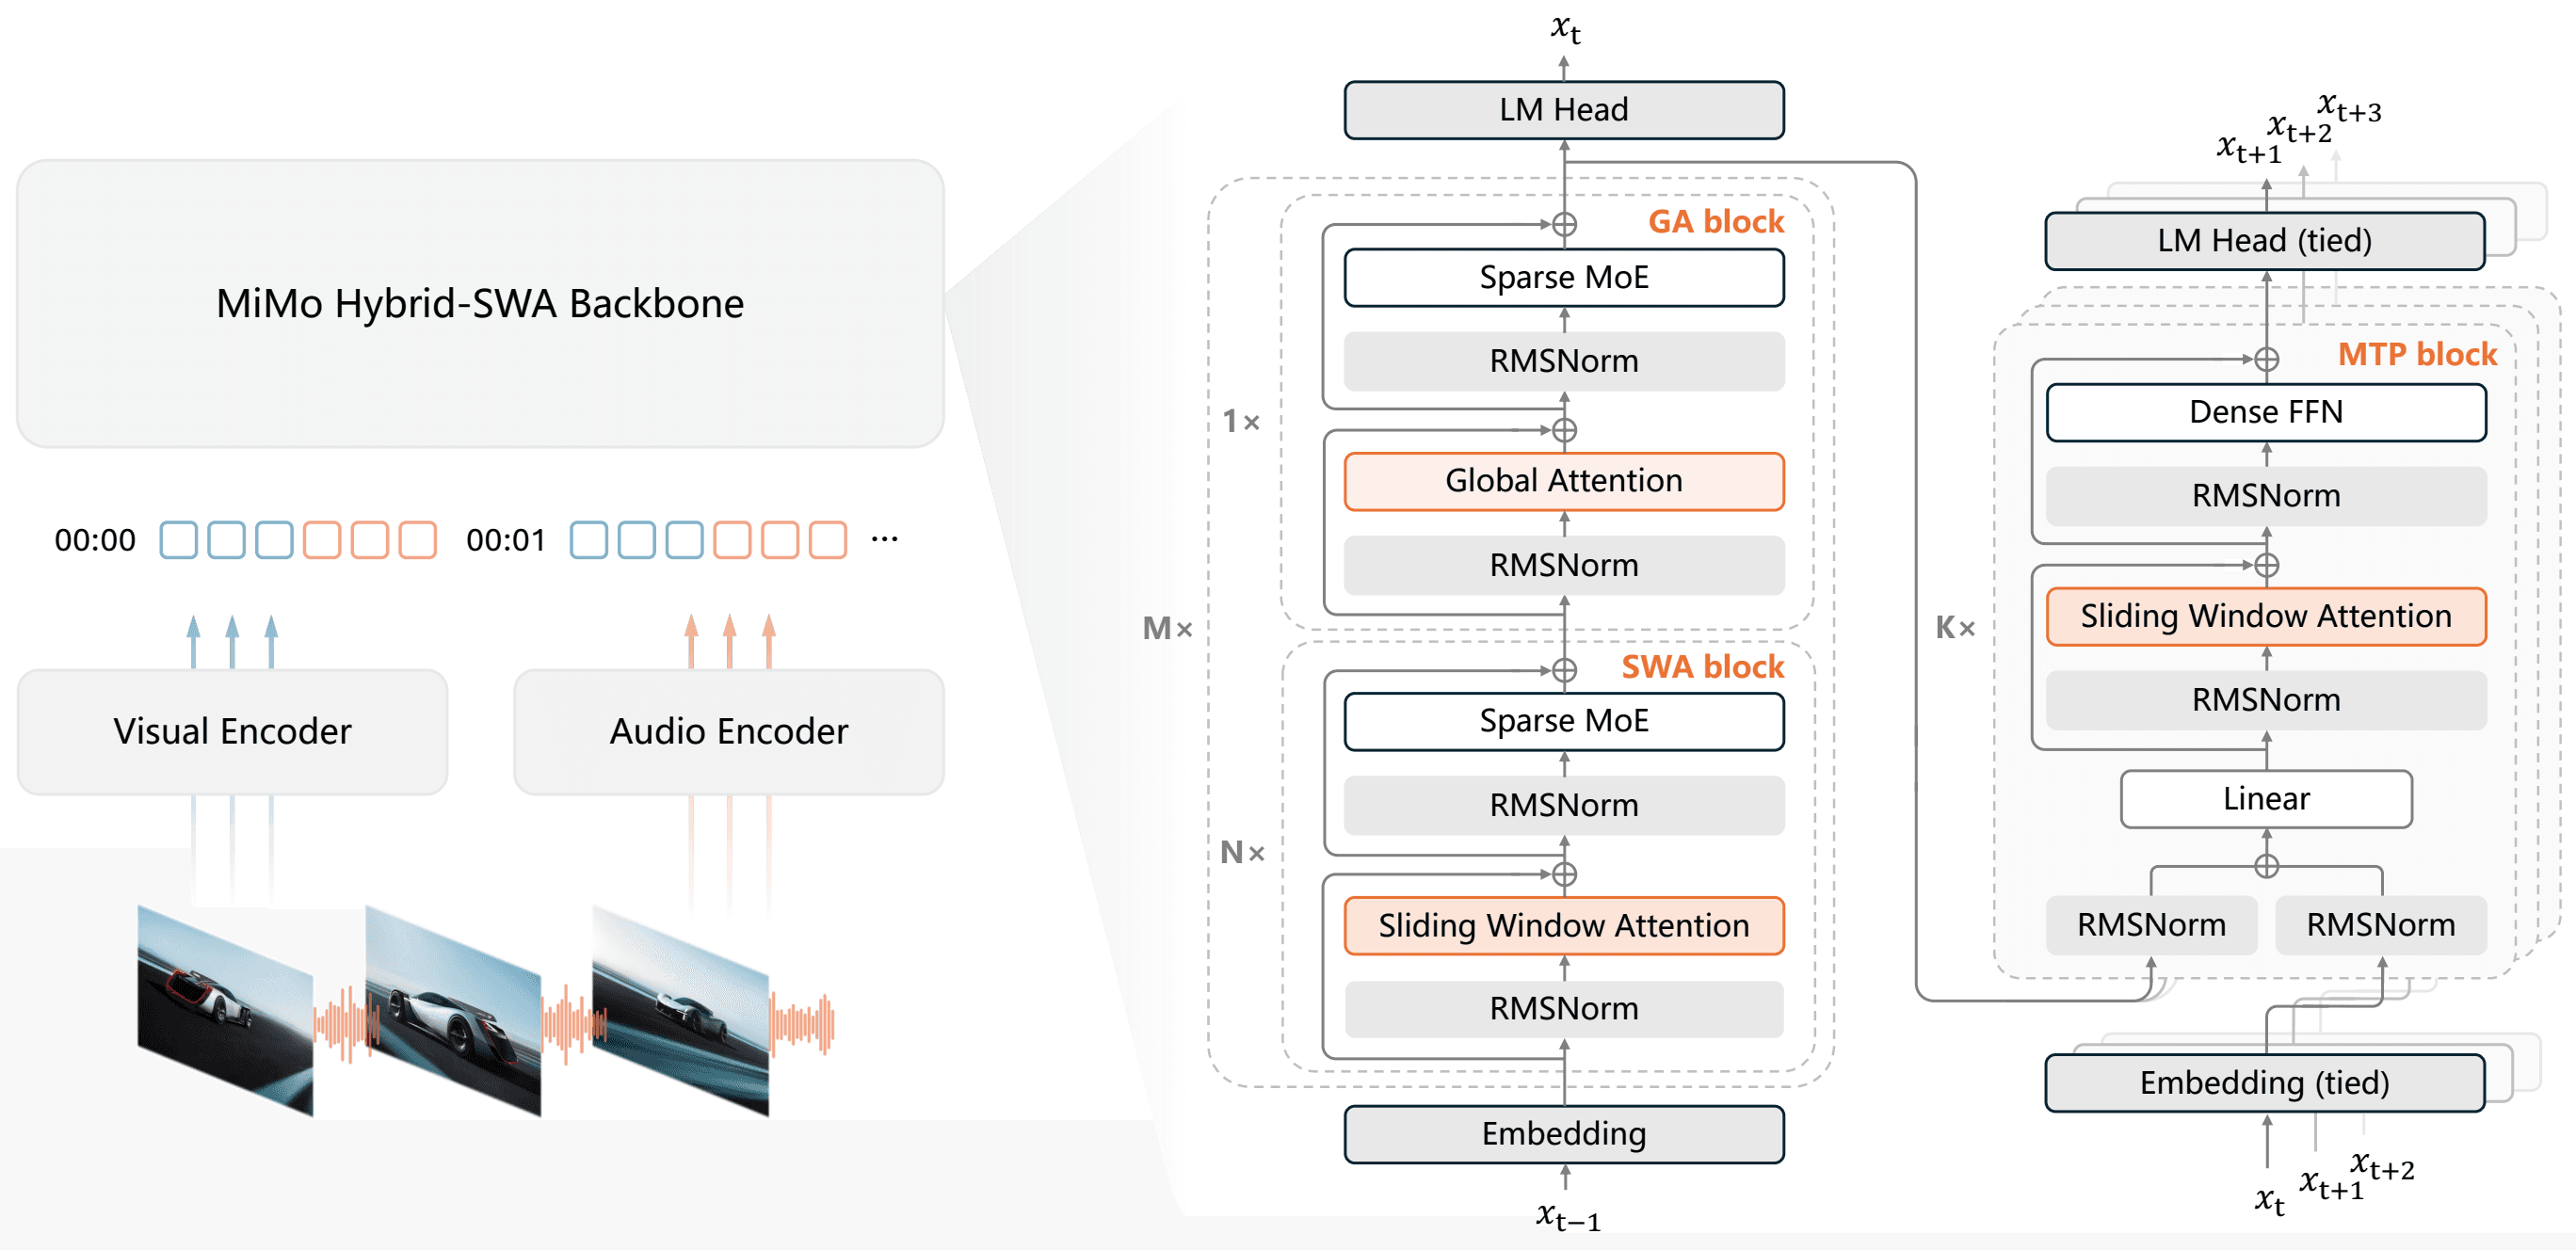
Xiaomi expands MiMo line with V2.6 multimodal models

The new Flash, Pro, and Distill variants add vision, audio, agentic behavior, and long-context handling to Xiaomi's open MiMo family.

Sep 21, 2026
Any-to-AnyReasoning
MiMo-V2.6 (Flash/Pro
Xiaomi/Vision-LanguageDatacenter

Xiaomi's MiMo V2.6-Pro-RL Targets Agentic Multimodal Work

An RL-tuned model that reads images, audio, and video while handling long context, aimed at agentic tasks.

Sep 21, 2026
Text / LLMReasoning
MiMo-V2.6-Pro-RL
JetBrains/CodeRuns on a laptop

JetBrains ships Mellum 2.1, a reasoning MoE for code

The updated Mellum packs 12B total parameters but activates just 2.5B, pairing code specialization with a new thinking mode under Apache-2.0.

Sep 20, 2026
CodeReasoning
Mellum2.1-12B-A2.5B-Thinking
Ukisai/ReasoningConsumer GPU

Swift-1.5 Trims Reasoning Tokens on a 27B Qwen Model

XingChen-AGI's new tune aims to make Qwen3.8-27B reason faster by cutting its thinking budget roughly in half.

Sep 16, 2026
ReasoningVision-Language
Swift-1.5-Qwen3.8-27B
Agnes AI/Vision-LanguageConsumer GPU

Agnes-3.0-Flash arrives as a multimodal reasoning model

The new release pairs vision-language understanding with a hybrid-attention design aimed at long-context reasoning.

Sep 11, 2026
Text / LLMReasoning
Agnes-3.0-Flash
Internlm/ReasoningDatacenter

InternLM's Atria Dawn Preview Targets Agentic Tasks

A new mixture-of-experts model trained on verified tool interactions arrives as an early preview under an MIT license.

Sep 11, 2026
Text / LLMReasoning
Atria Dawn Preview
Unknown/ReasoningRuns on a laptop

ZGCM-1 arrives as a fully open 7B reasoning model

A compact foundation model targets math reasoning and agentic search with tool use, and its makers are releasing it fully open.

Sep 10, 2026
Text / LLMReasoning
Tencent/ReasoningWorkstation GPU

Tencent's T1 Targets Long-Horizon Terminal Work

A 122B mixture-of-experts model trained with reinforcement learning claims state-of-the-art results on Terminal-Bench.

Sep 9, 2026
CodeText / LLM
TokenRhythm/Text / LLMRuns on a laptop

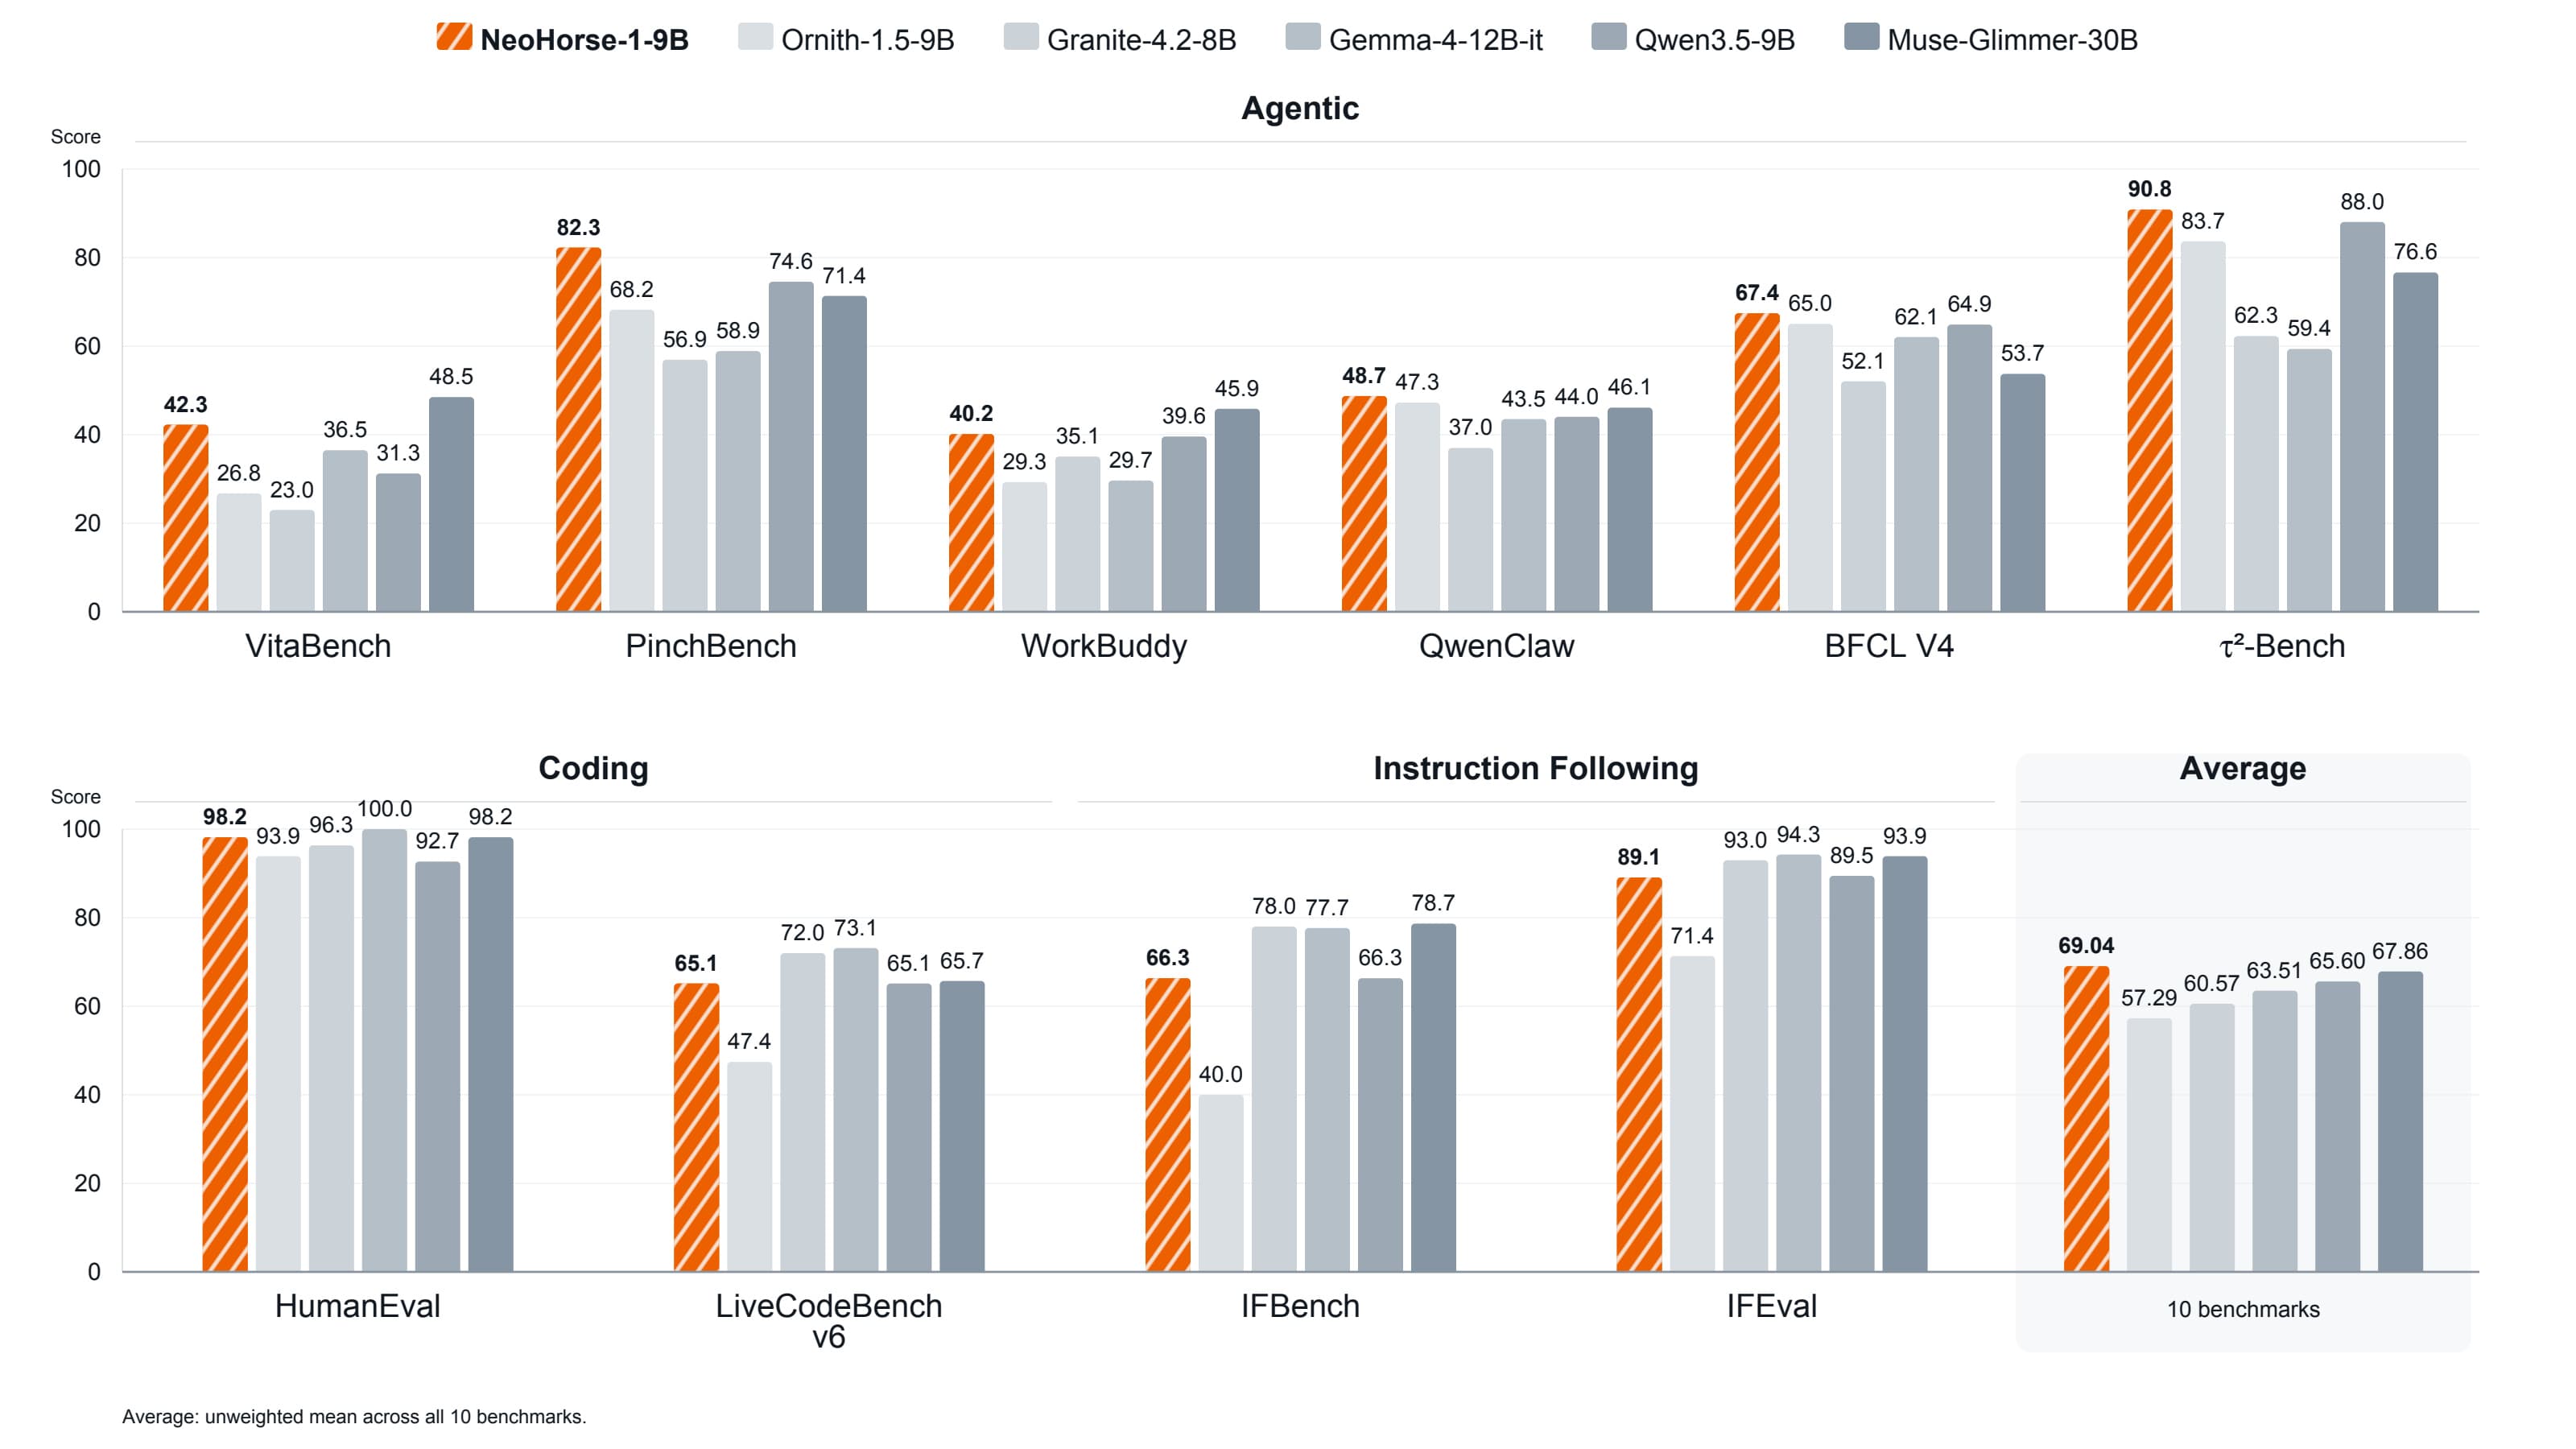
NeoHorse-1-9B targets agentic coding tasks

A 9-billion-parameter model built on Qwen3.5 aims squarely at tool use and code generation.

Sep 5, 2026
CodeText / LLM
NeoHorse-1-9B
TokenRhythm/Text / LLMRuns on a laptop

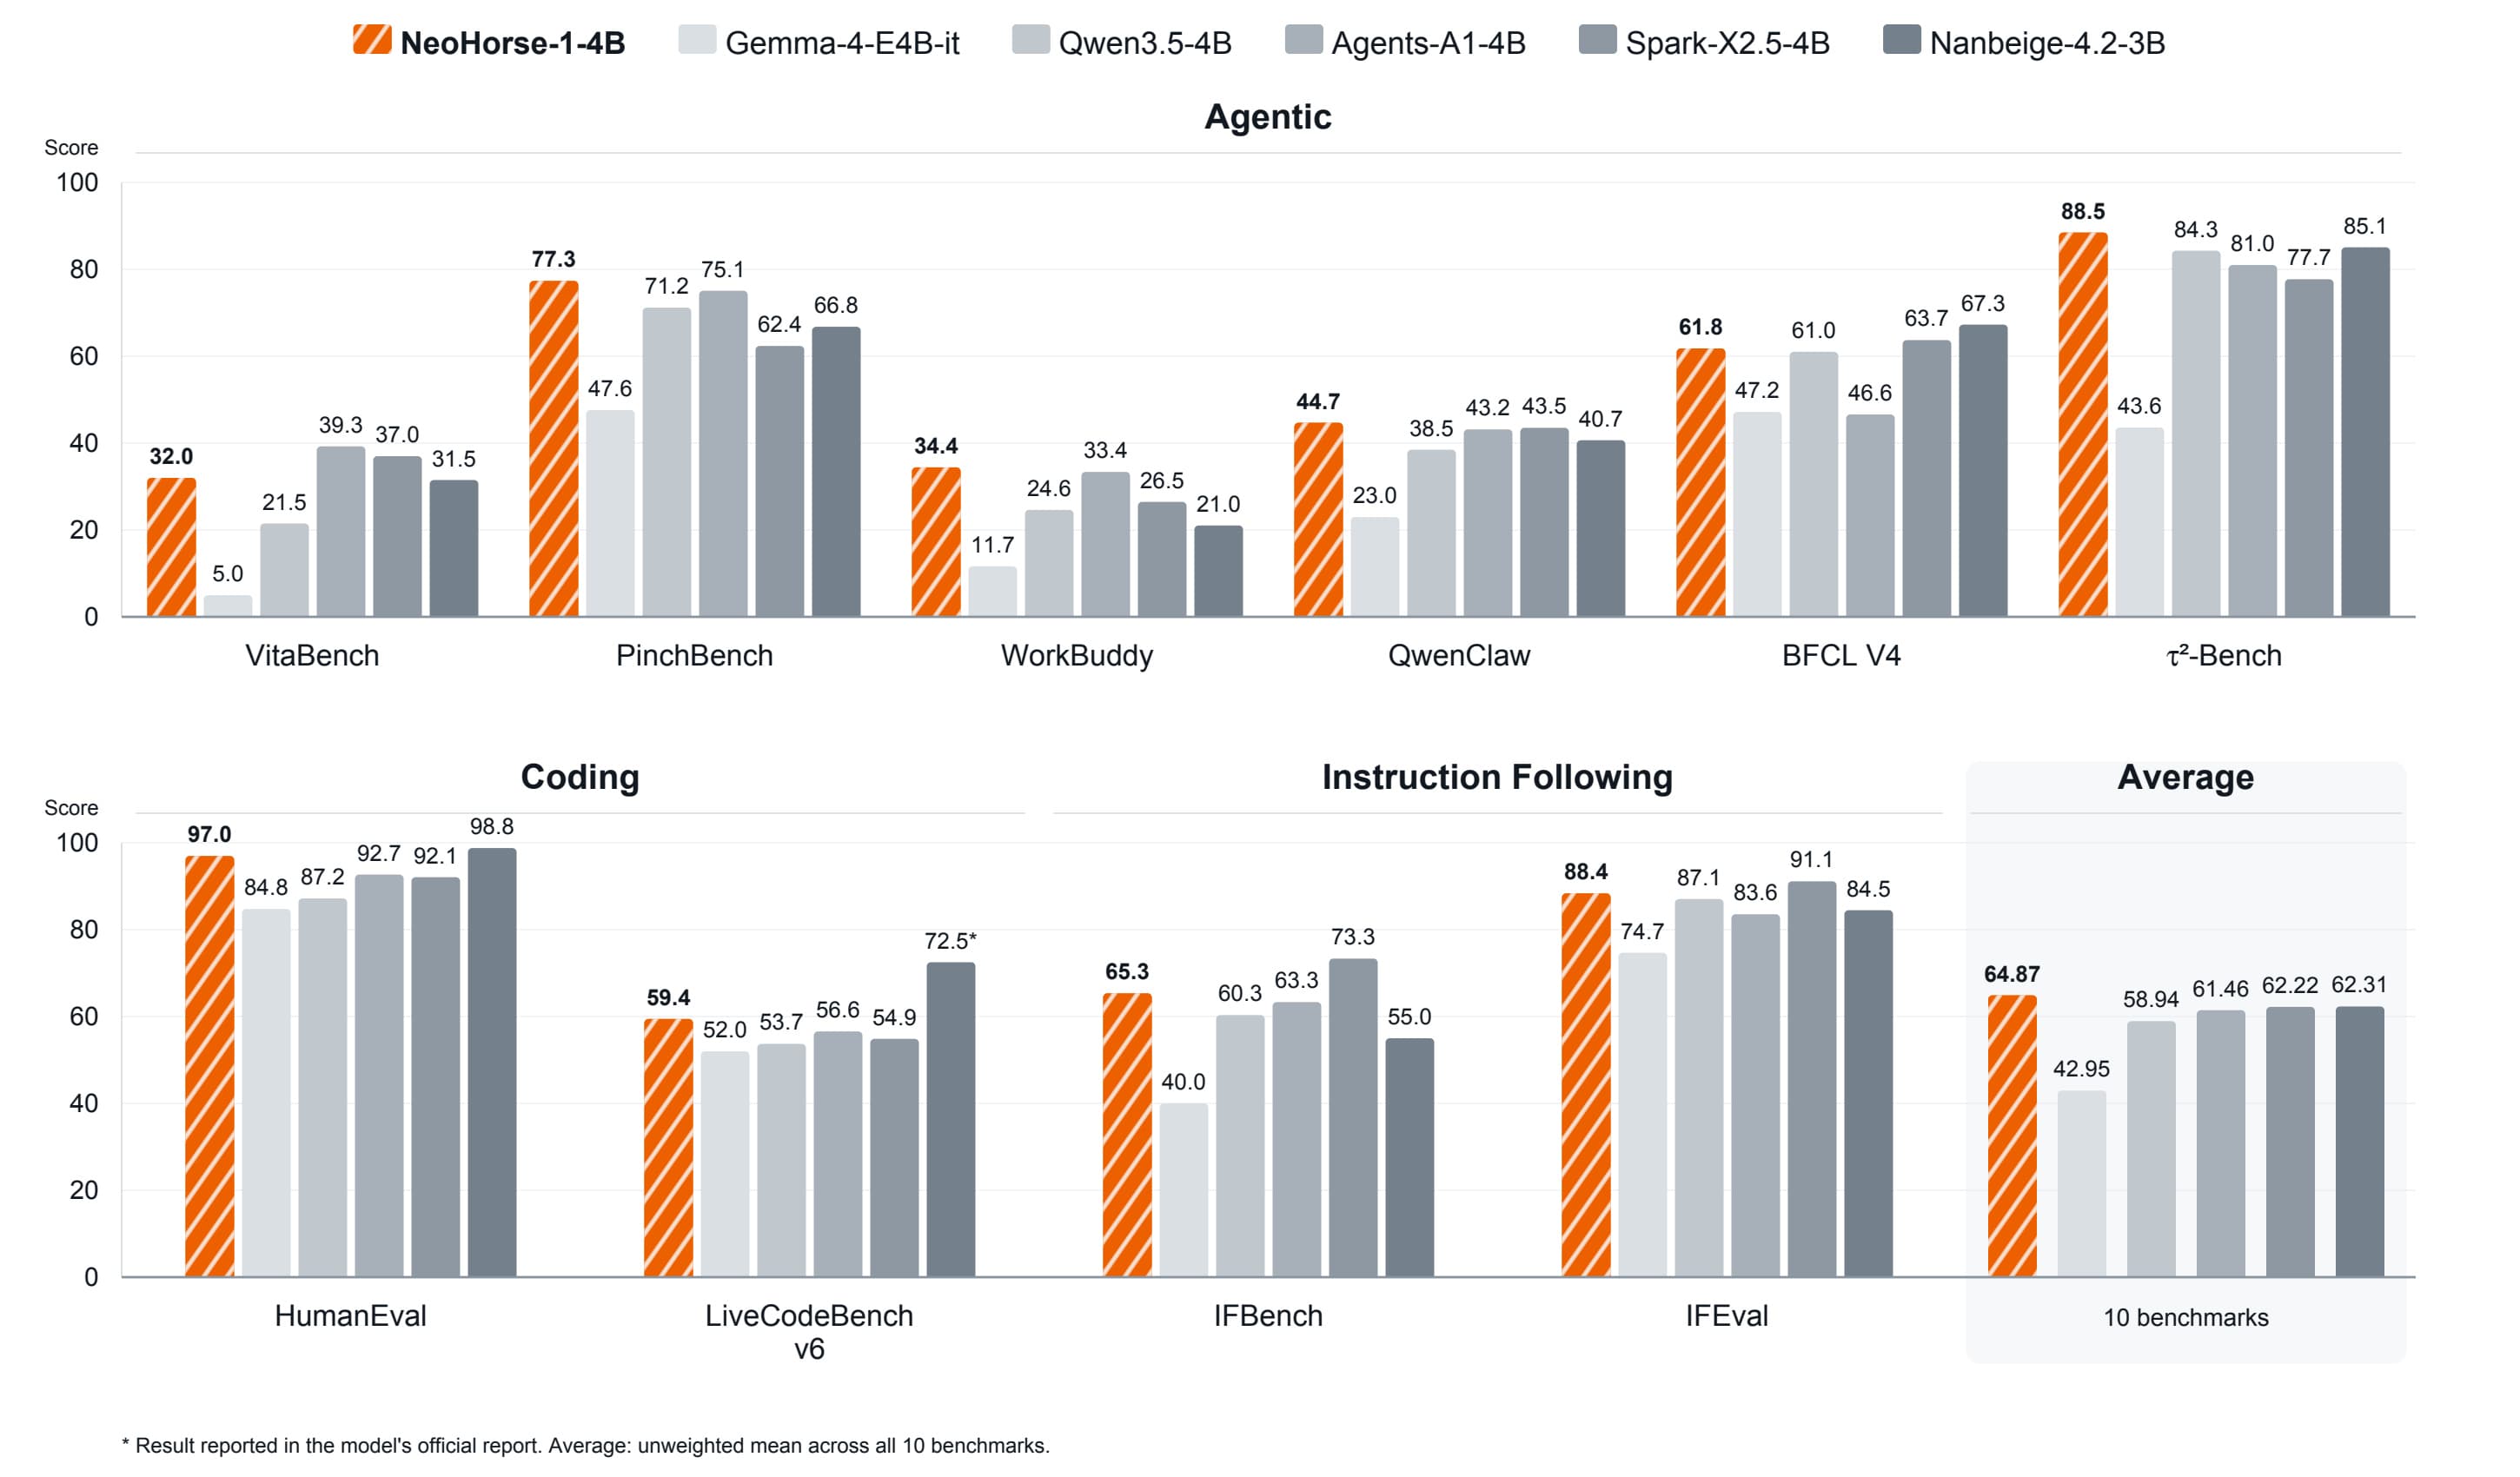
NeoHorse-1-4B tunes Qwen3.5 for agentic work

A compact 4-billion-parameter model built for tool use, coding, and multi-step reasoning arrives from TokenRhythm.

Sep 5, 2026
CodeText / LLM
NeoHorse-1-9B
Unknown/Text / LLMConsumer GPU

Occamy-1.0 targets long-horizon agent work at 35B

A new open 35B model is tuned for multi-step, co-working tasks rather than one-shot answers.

Sep 3, 2026
Text / LLMReasoning
IFM/Text / LLMMulti-GPU server

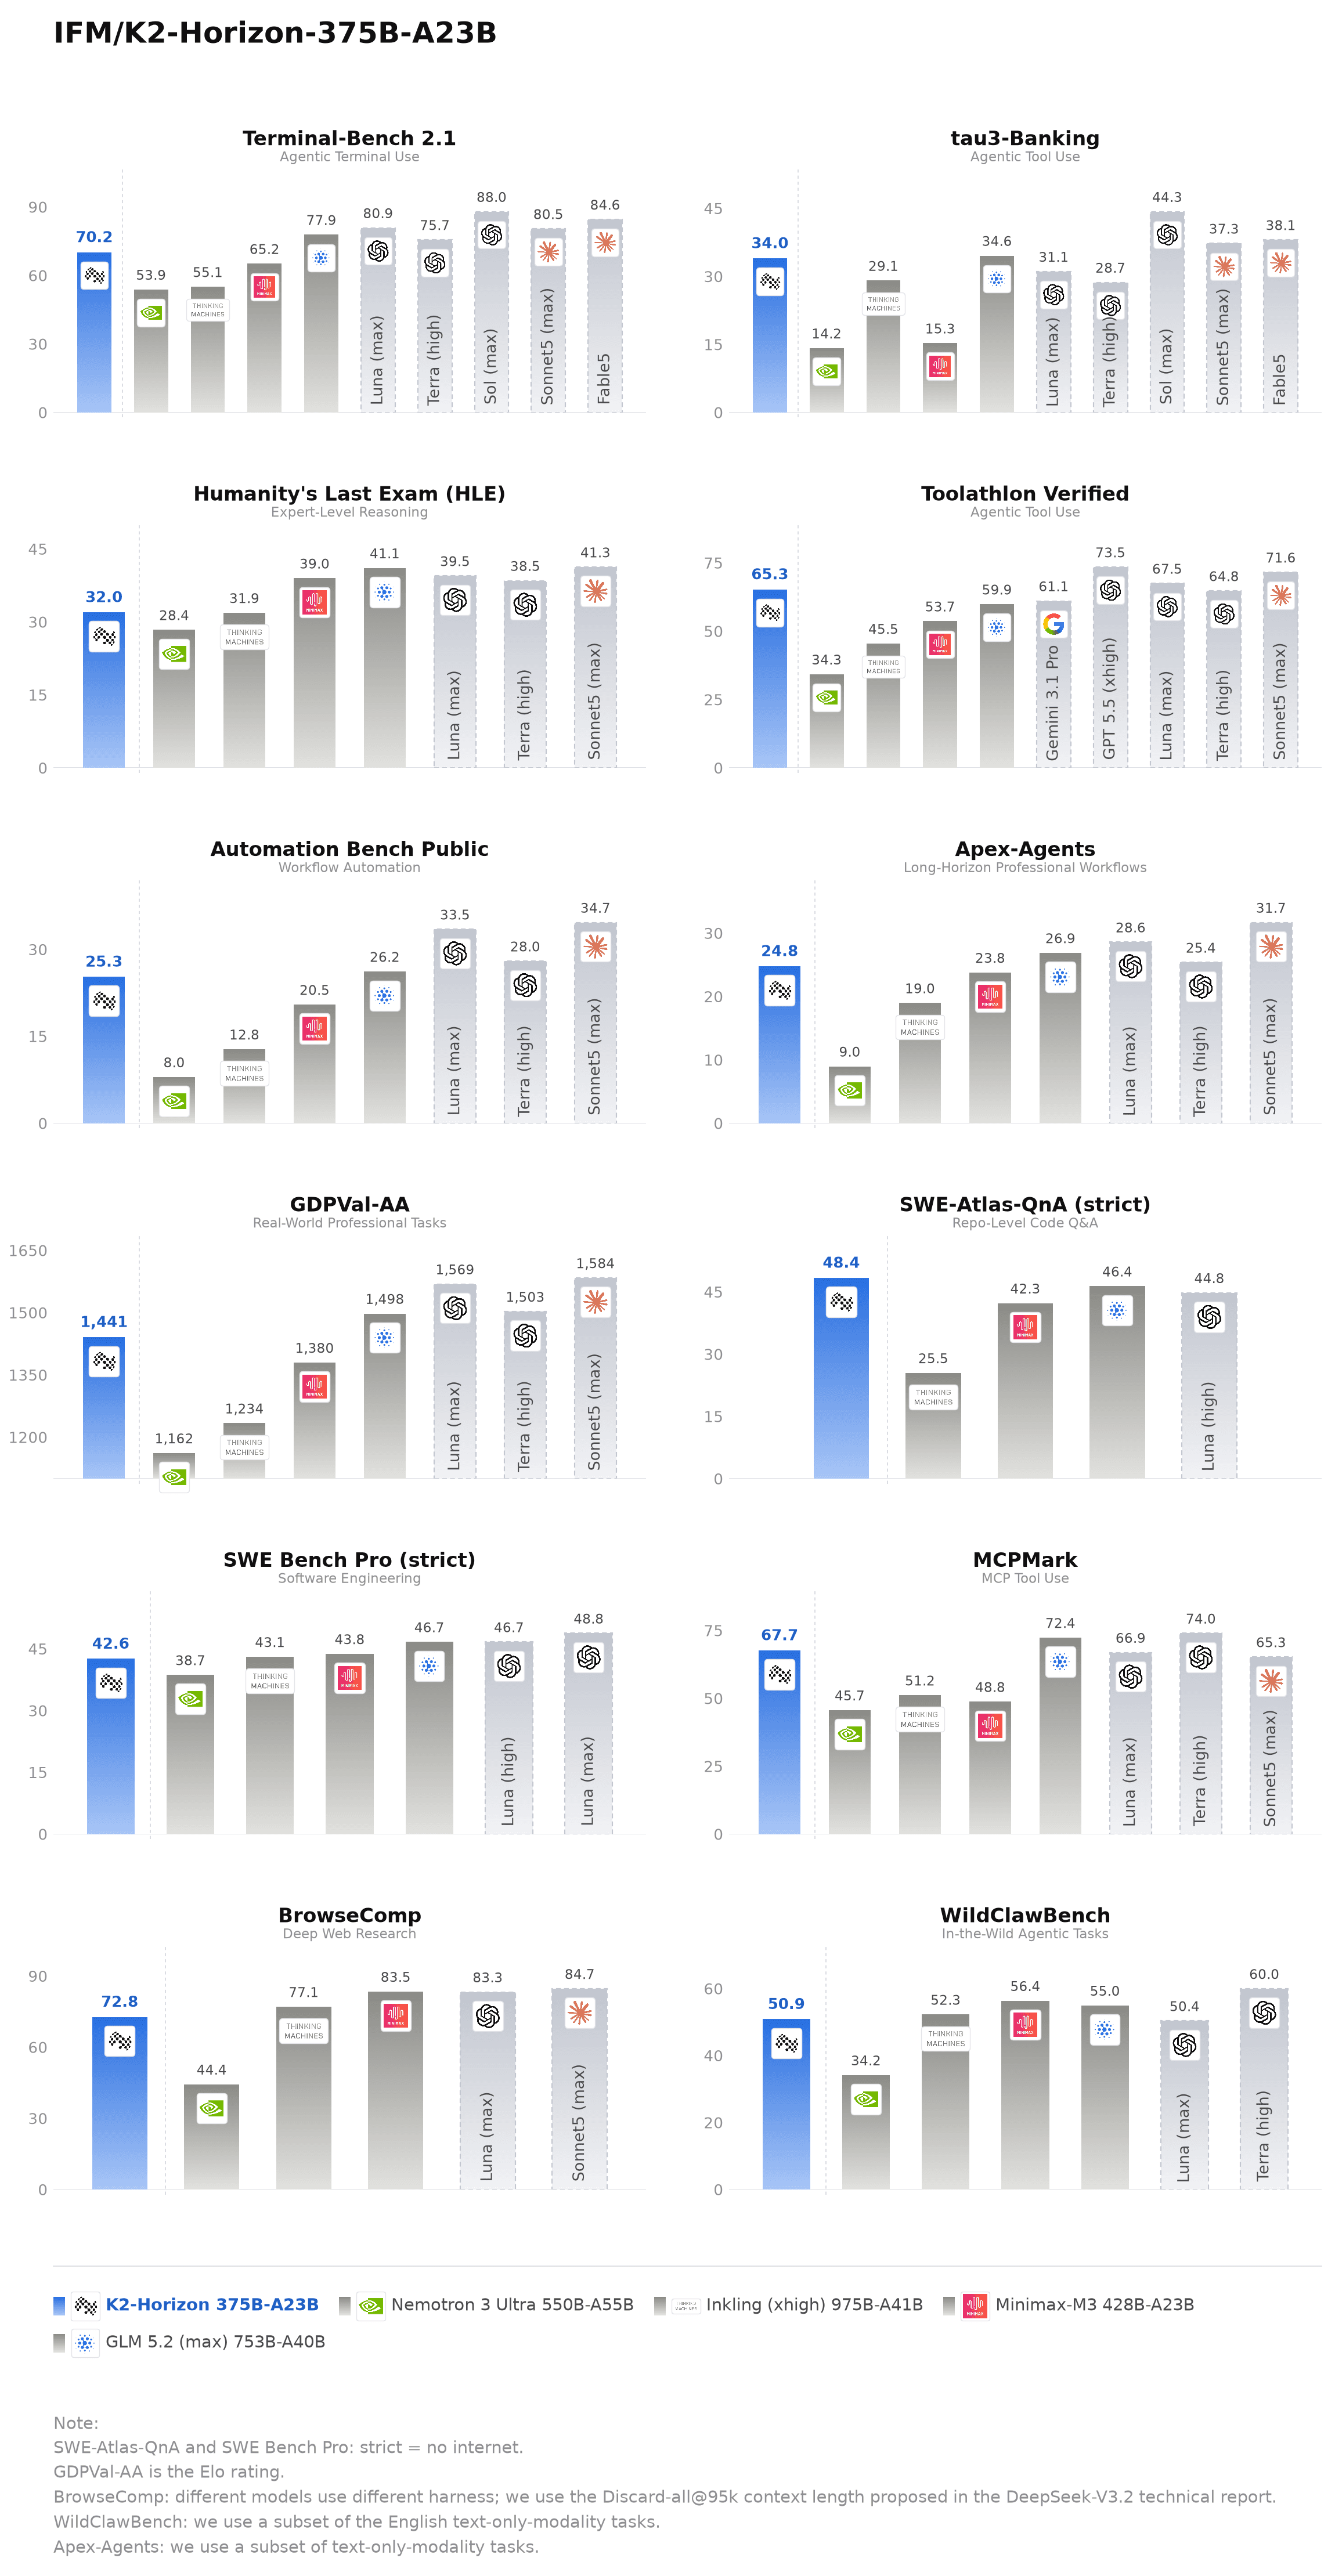
IFM releases K2-Horizon, a 375B open-weight MoE

The flagship model uses a mixture-of-experts design that activates just 23 billion parameters per token, keeping inference costs in check.

Sep 1, 2026
Text / LLMReasoning
K2-Horizon-375B-A23B
Tencent/Text / LLMDatacenter

Tencent Previews Hunyuan Hy4, an Apache MoE Model

The company's next-generation Hunyuan language model arrives as an early preview with a permissive license and a mixture-of-experts design.

Aug 27, 2026
Text / LLMReasoning
Hunyuan Hy4 (preview)
IBM/Text / LLM

IBM's Granite 4.2 Adds Reasoning to Open LLM Line

The latest update to IBM's Apache 2.0 model family leans into structured reasoning while keeping its enterprise-friendly licensing.

Aug 25, 2026
Text / LLMReasoning
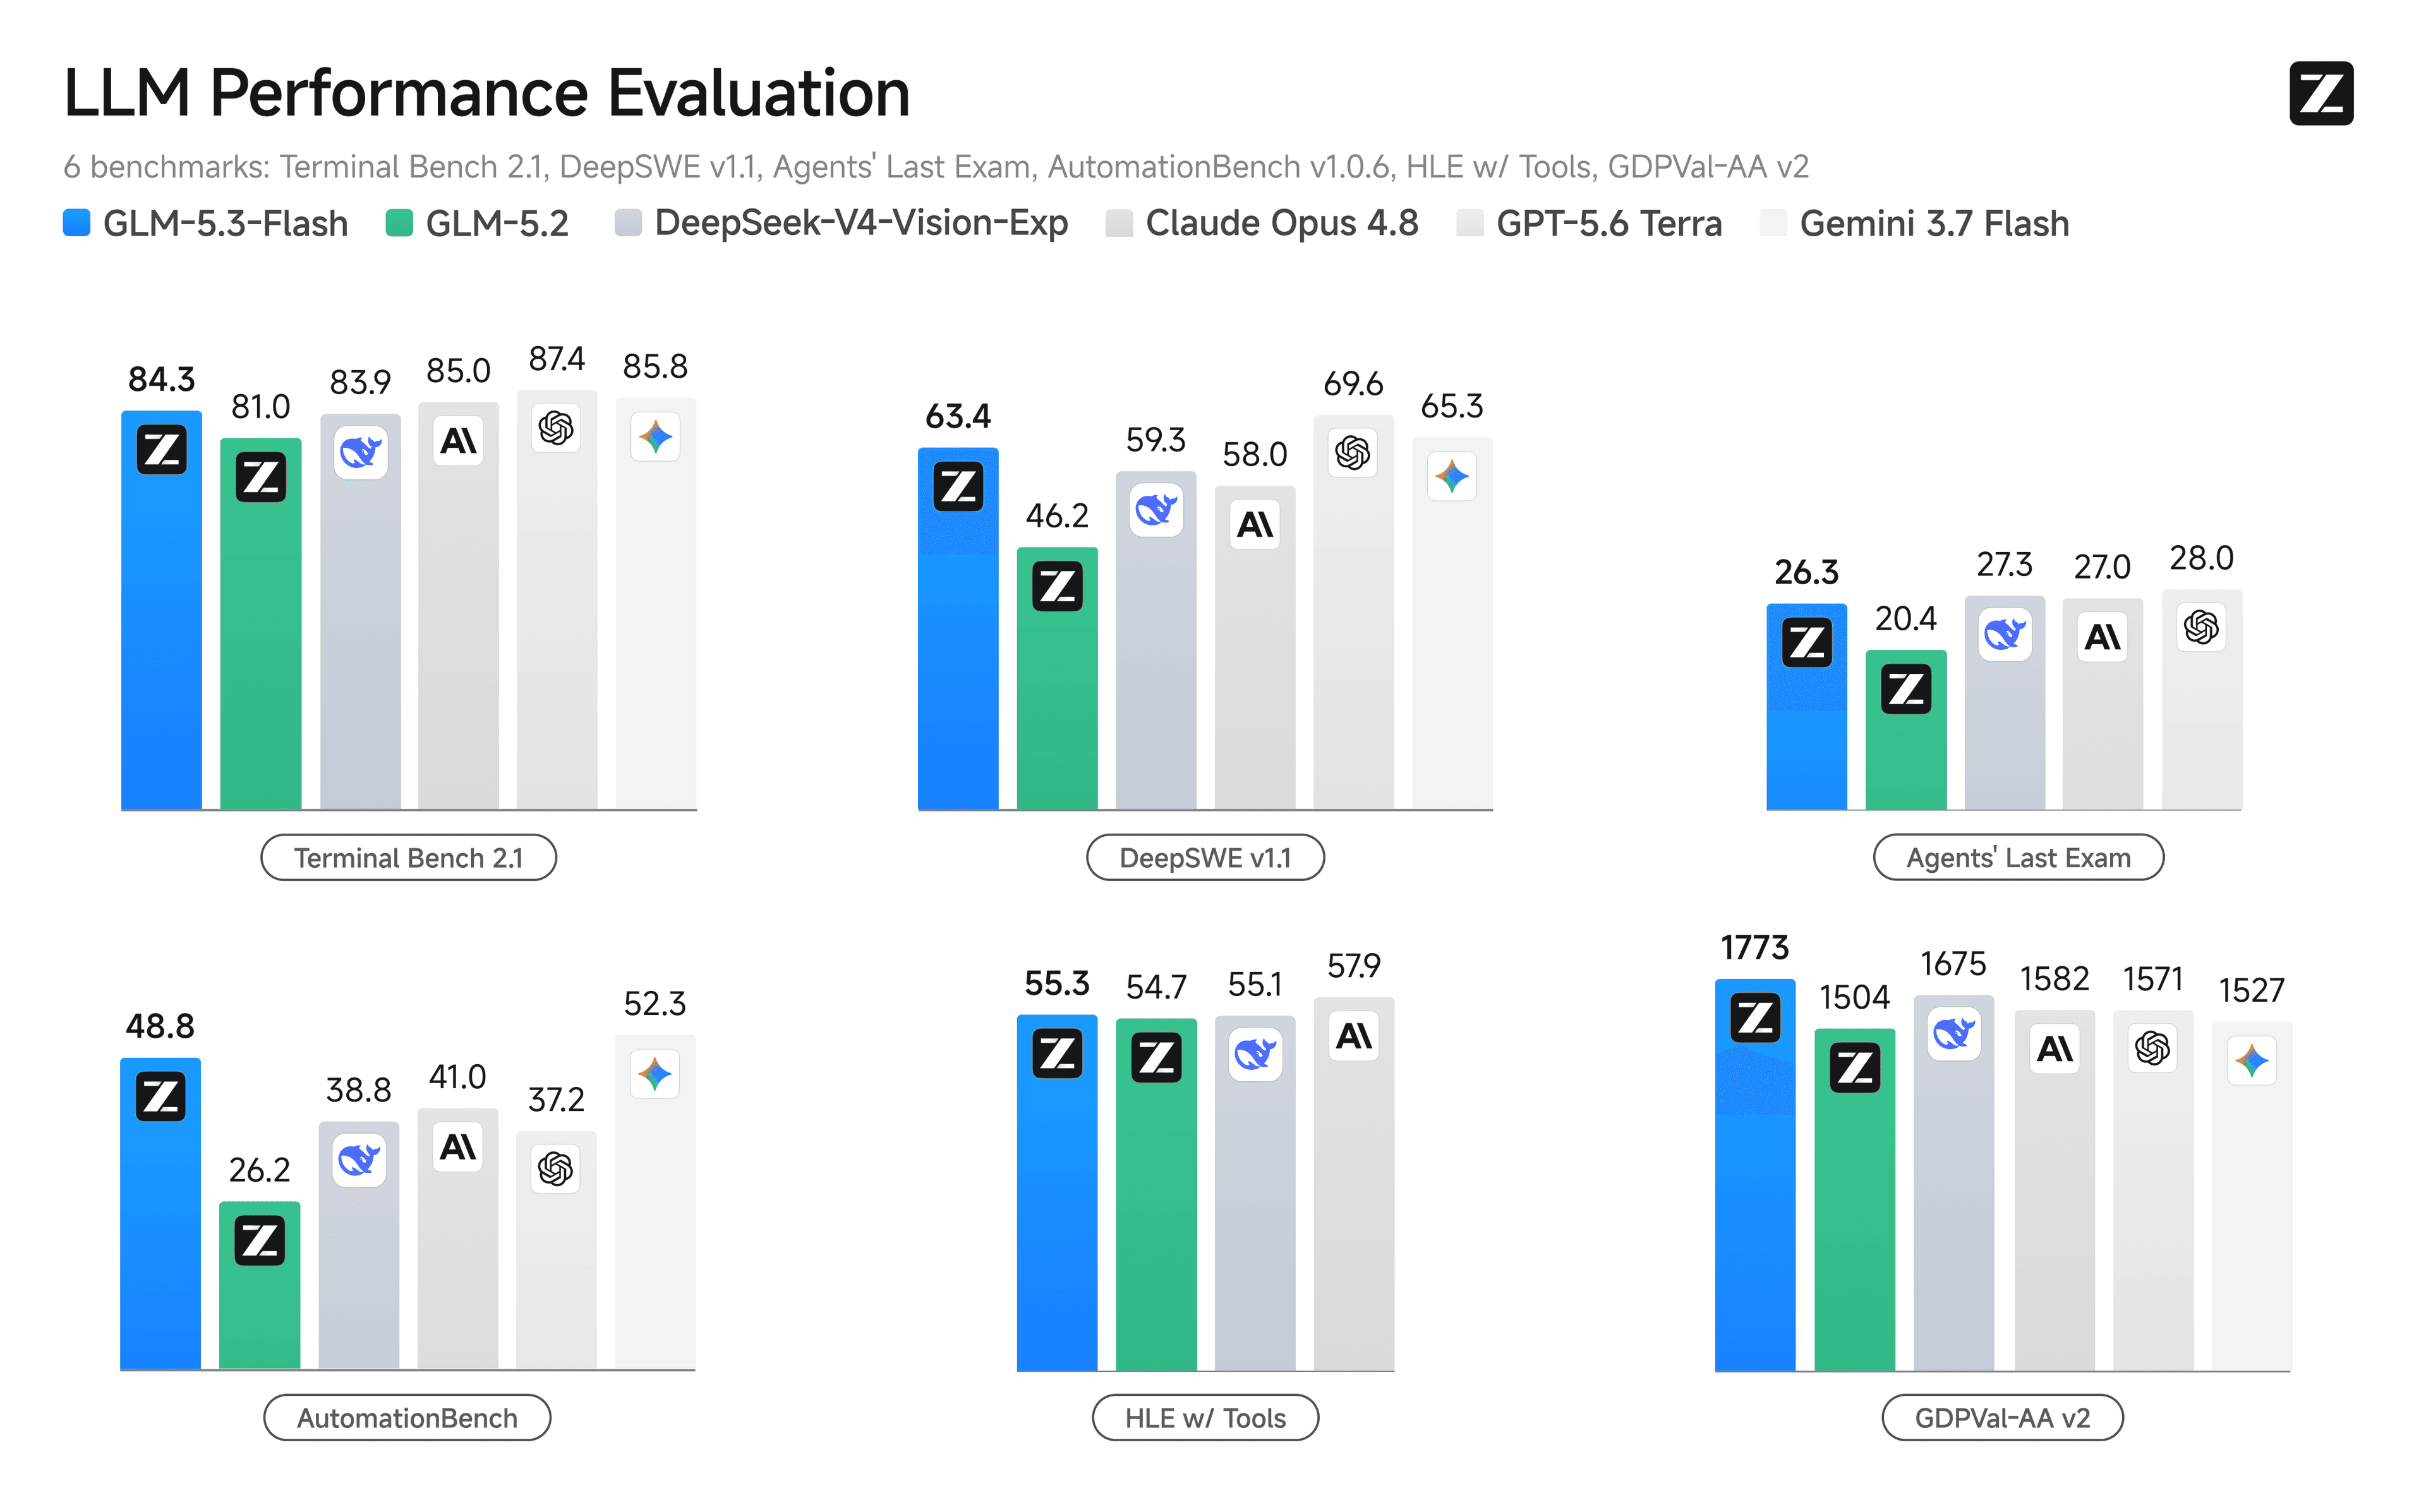
Zhipu AI/Text / LLMMulti-GPU server

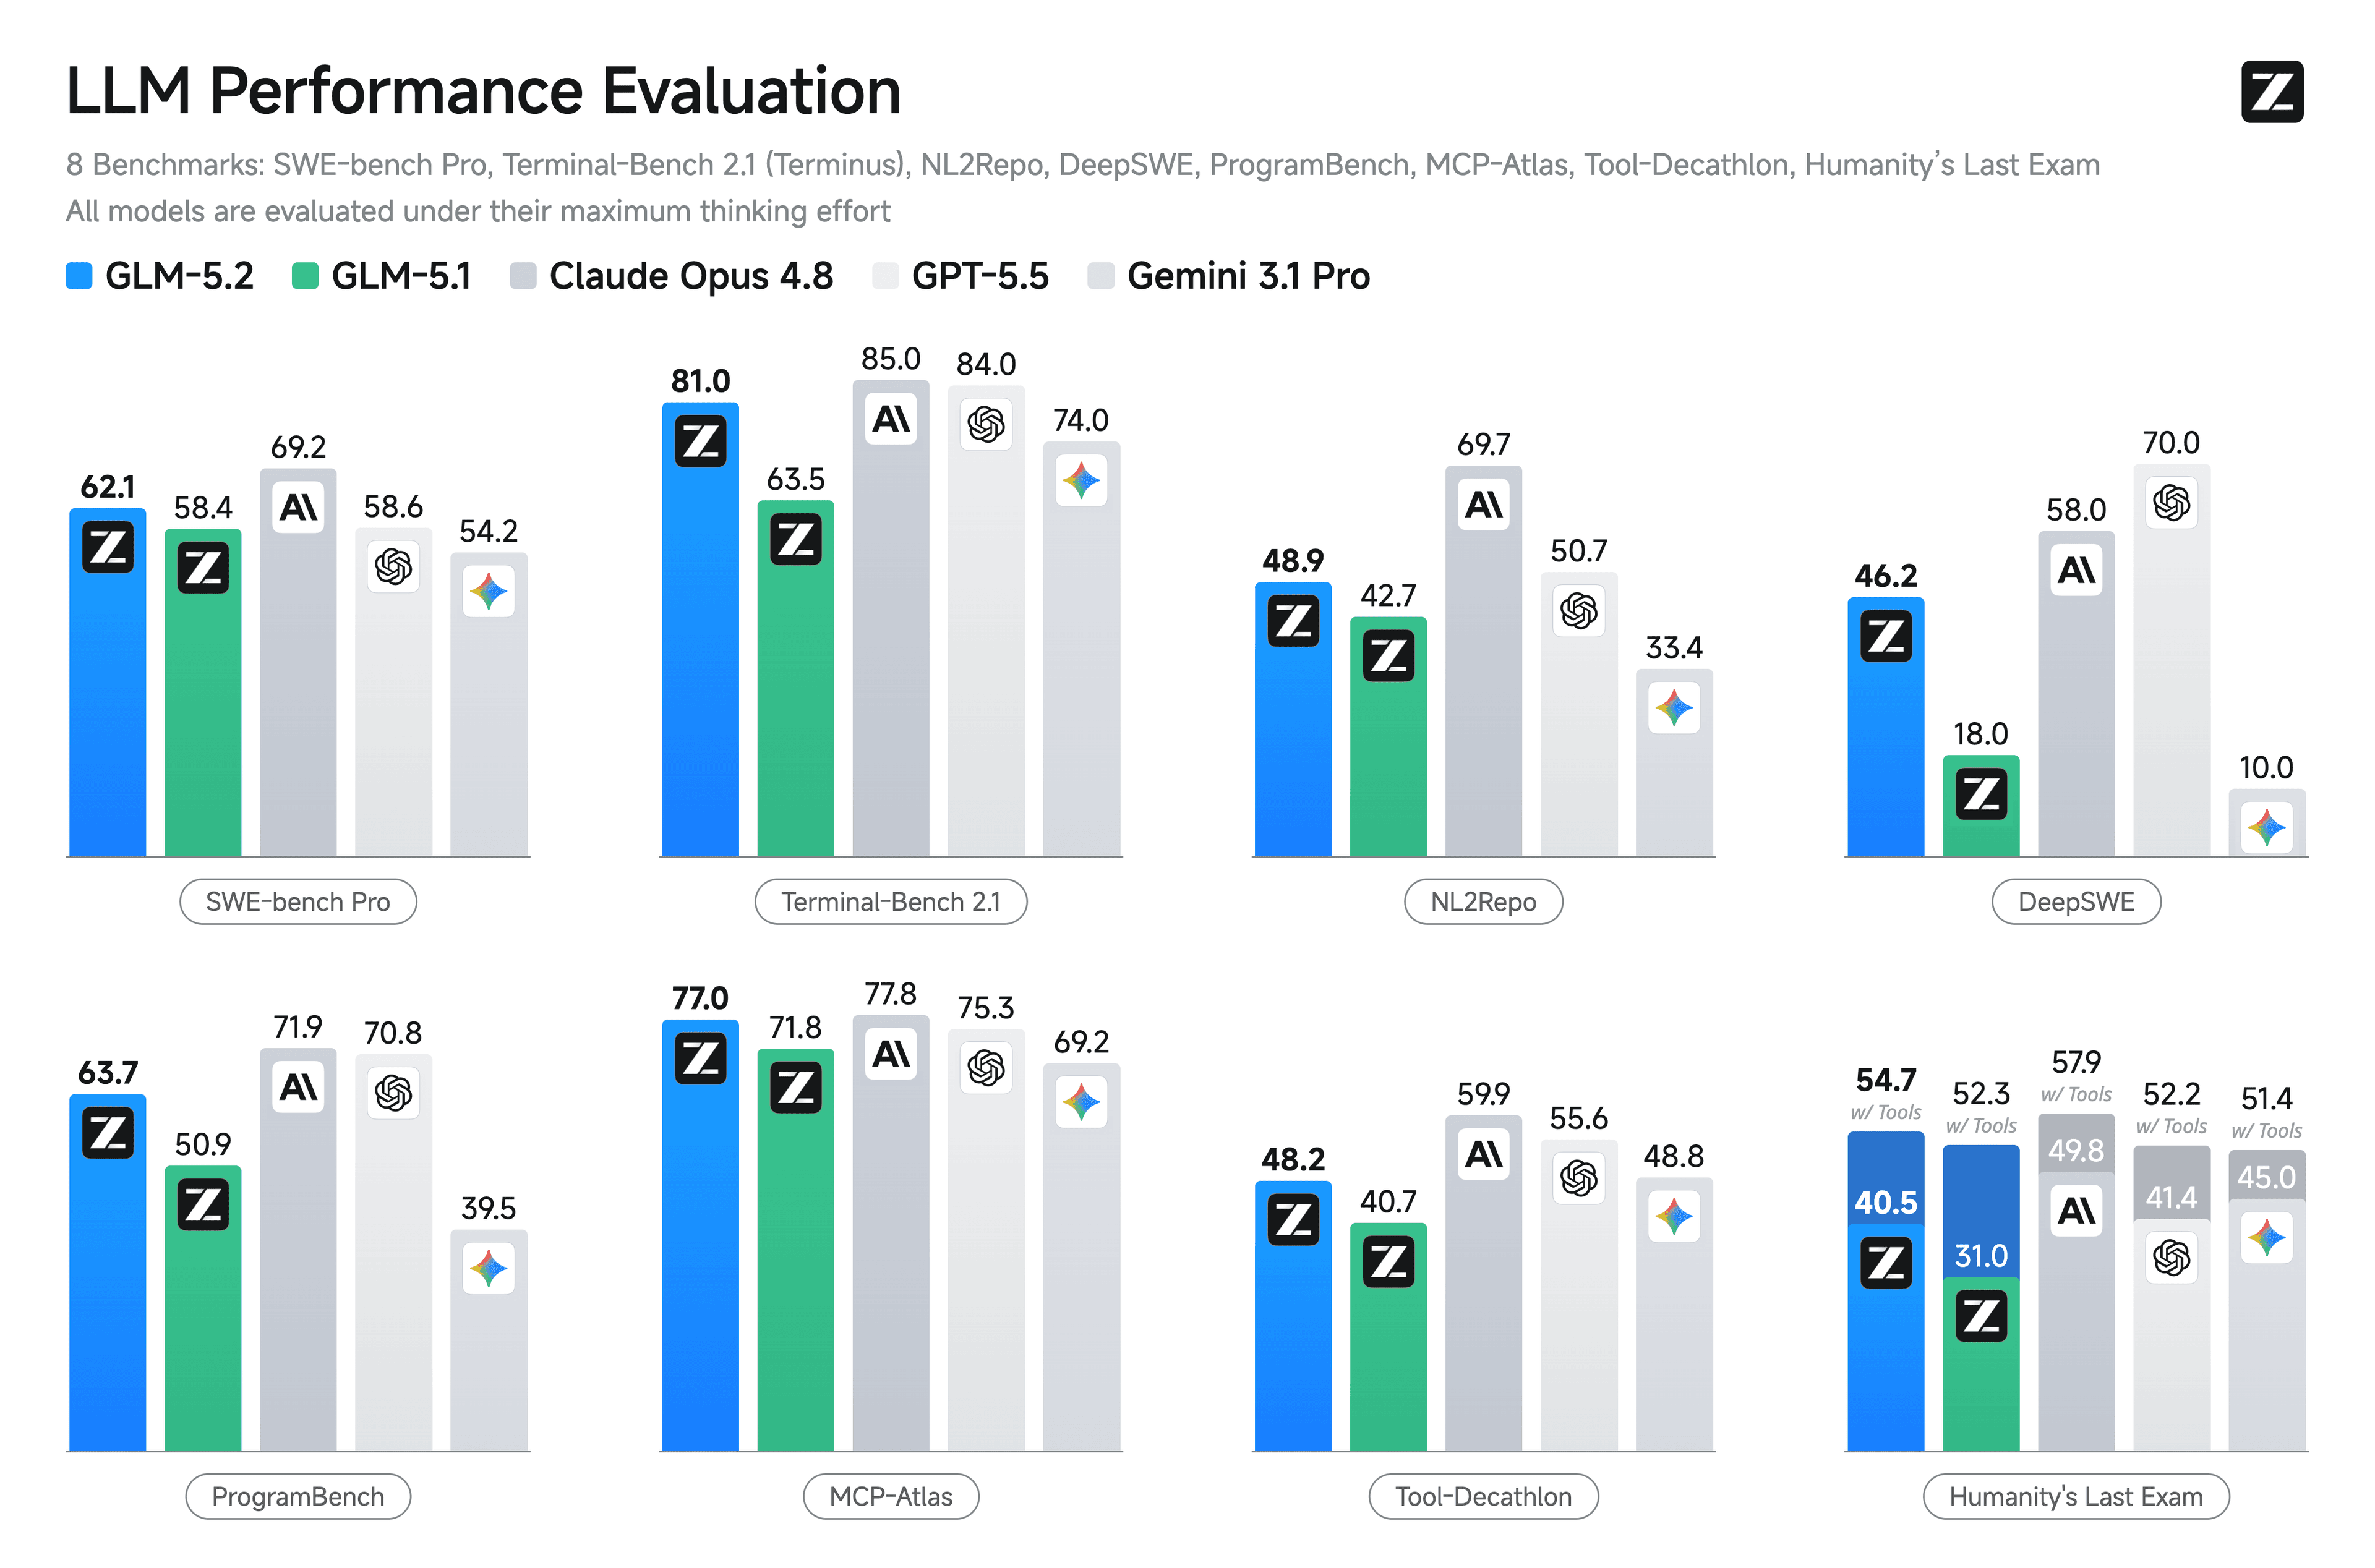
Zhipu releases GLM-5.3-Flash under MIT license

A speed-tuned member of the GLM-5.3 family arrives with open weights and mixture-of-experts design aimed at fast, low-cost inference.

Aug 25, 2026
Text / LLMReasoning
GLM-5.3-Flash
Zhipu AI/Text / LLM

Zhipu's GLM-5.3 Targets Coding at a Fraction of the Cost

The open-weight MoE model from Zhipu AI aims to match frontier closed systems on coding tasks while undercutting them on price.

Aug 23, 2026
CodeText / LLM
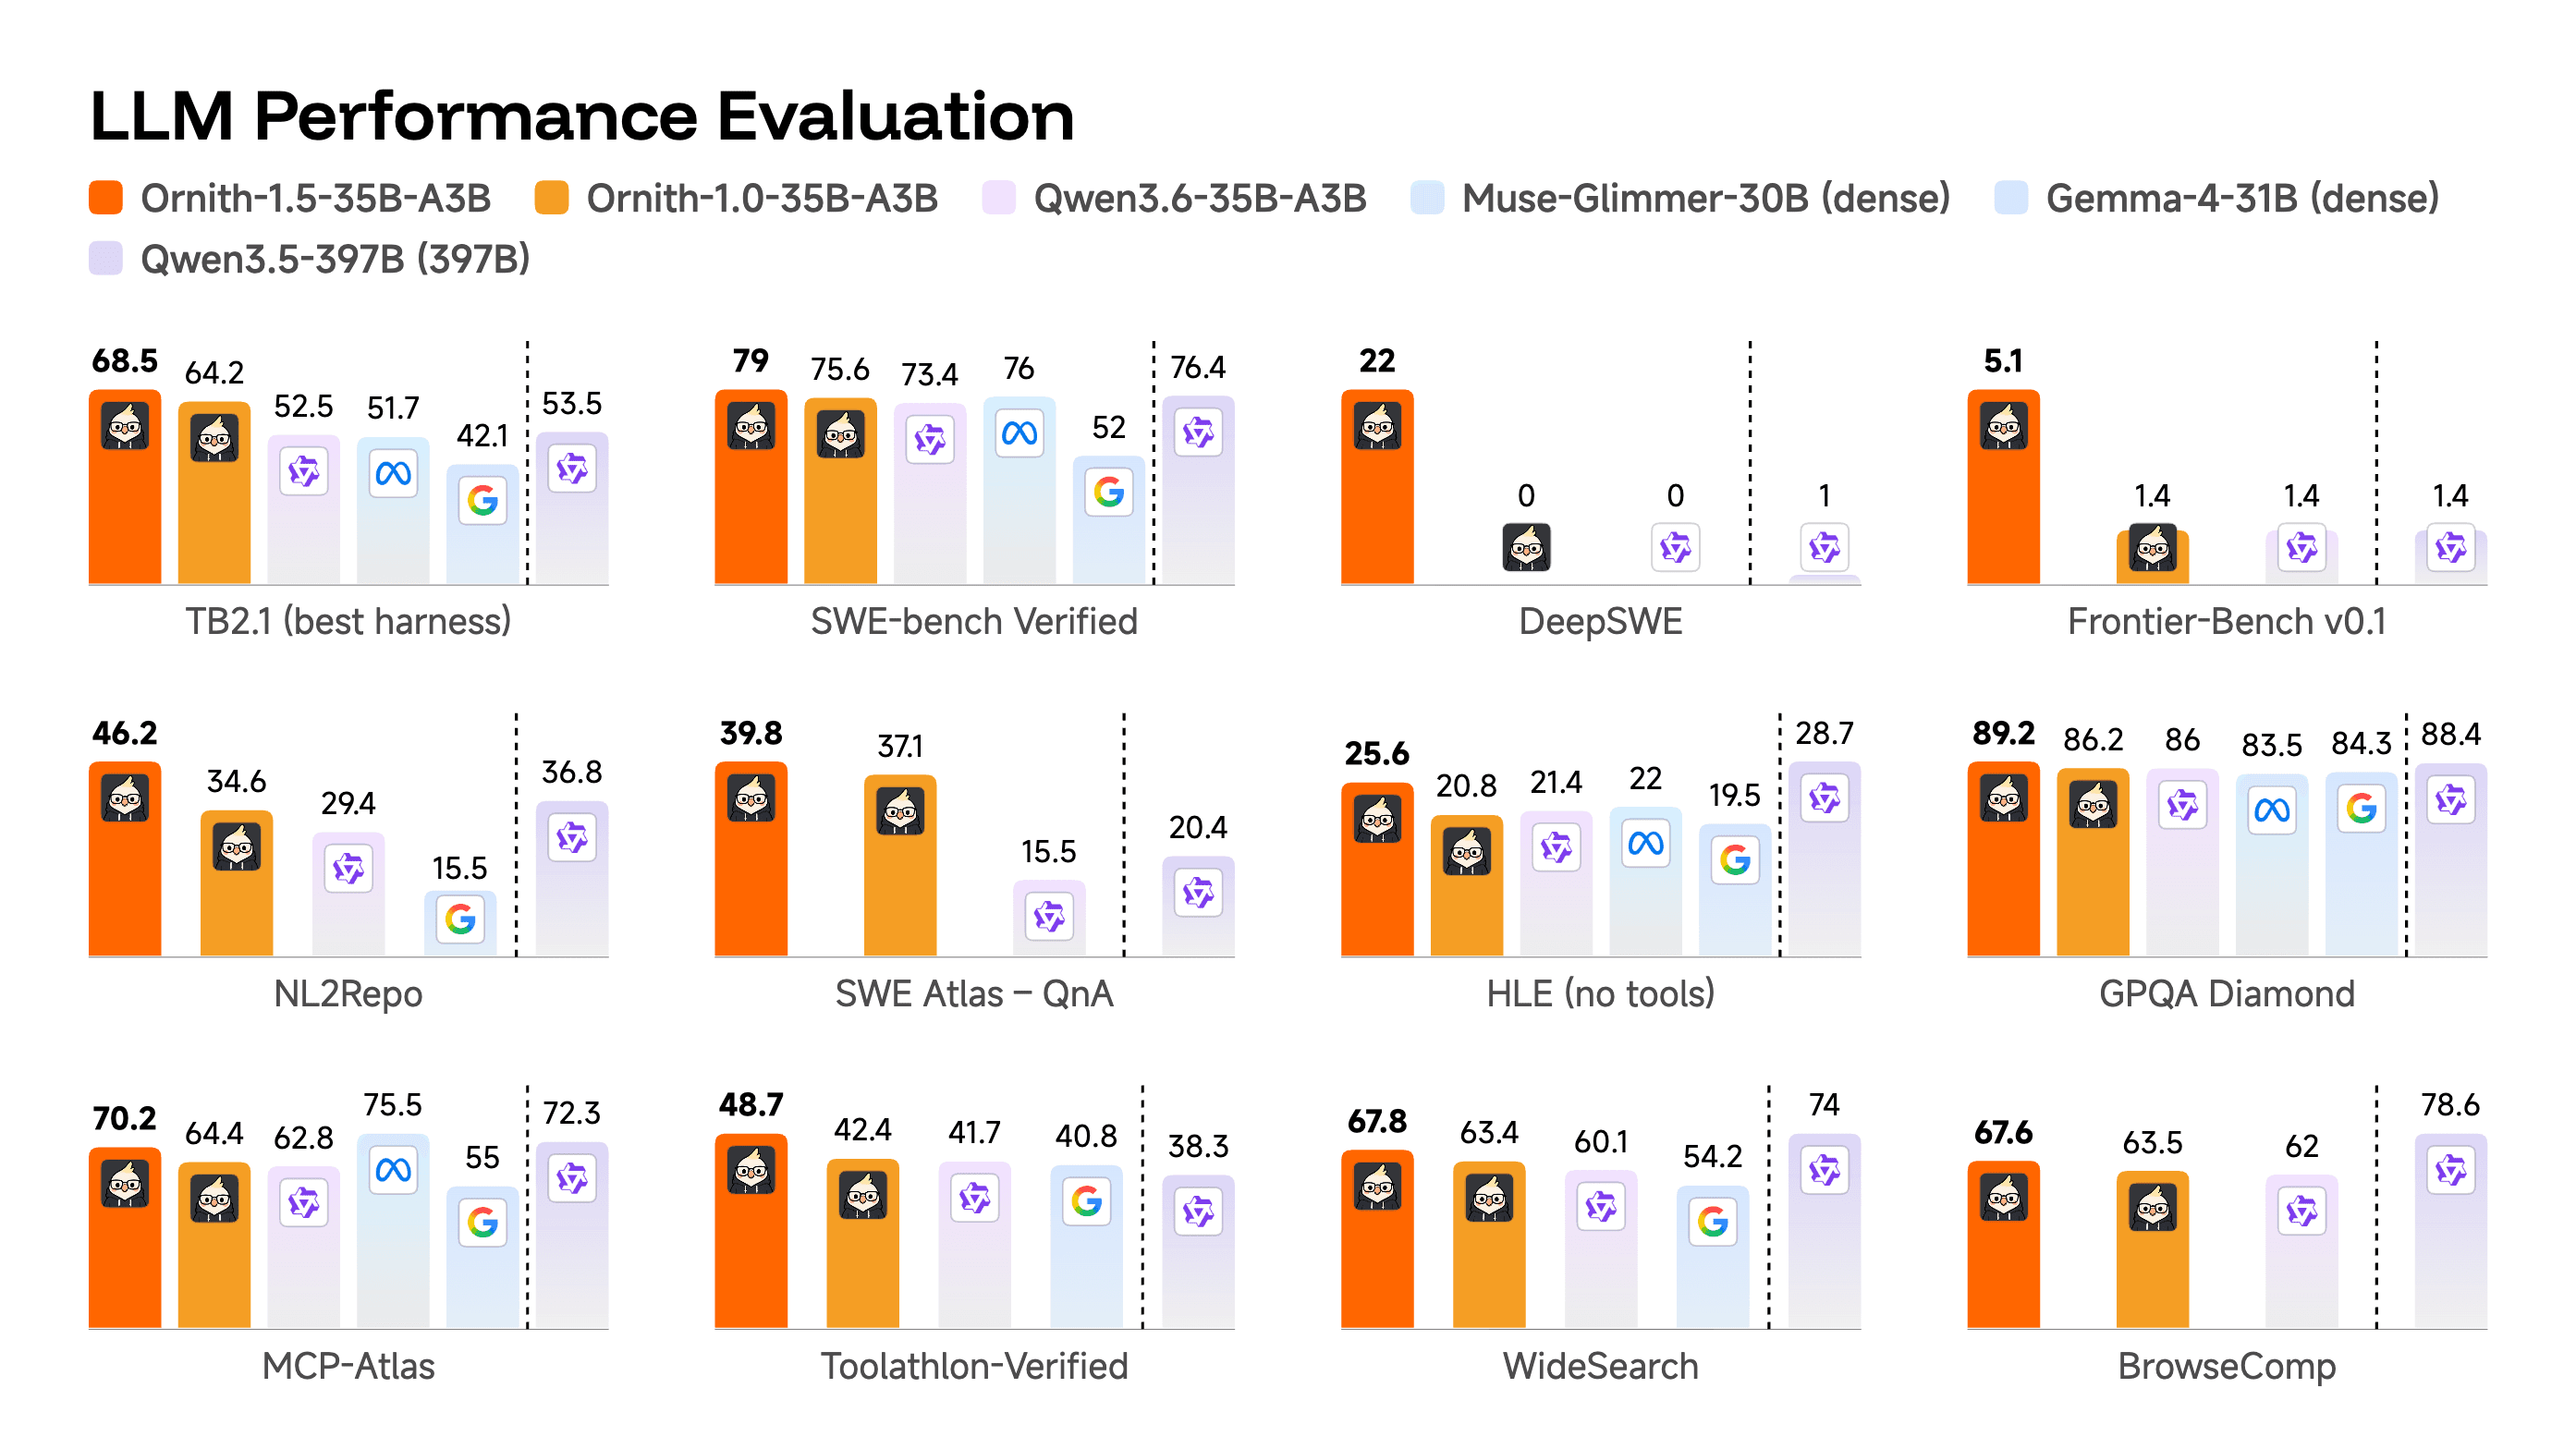
Ornith Ai/Text / LLMConsumer GPU

Ornith 1.5 Brings a Lean 35B MoE to Open Weights

The MIT-licensed model activates just 3B parameters per token, borrowing the Qwen3.5 MoE design for text and reasoning tasks.

Aug 18, 2026
Text / LLMReasoning
Ornith-1.5-122B
Apodex/Text / LLMConsumer GPU

Apodex 1.1 mini targets long-horizon agentic work

An MoE model built on Qwen3.5-35B-A3B aims at complex, multi-step tasks rather than one-shot answers.

Aug 17, 2026
Text / LLMReasoning
Apodex 1.1 mini
DeepSeek/Text / LLMMajor releaseDatacenter

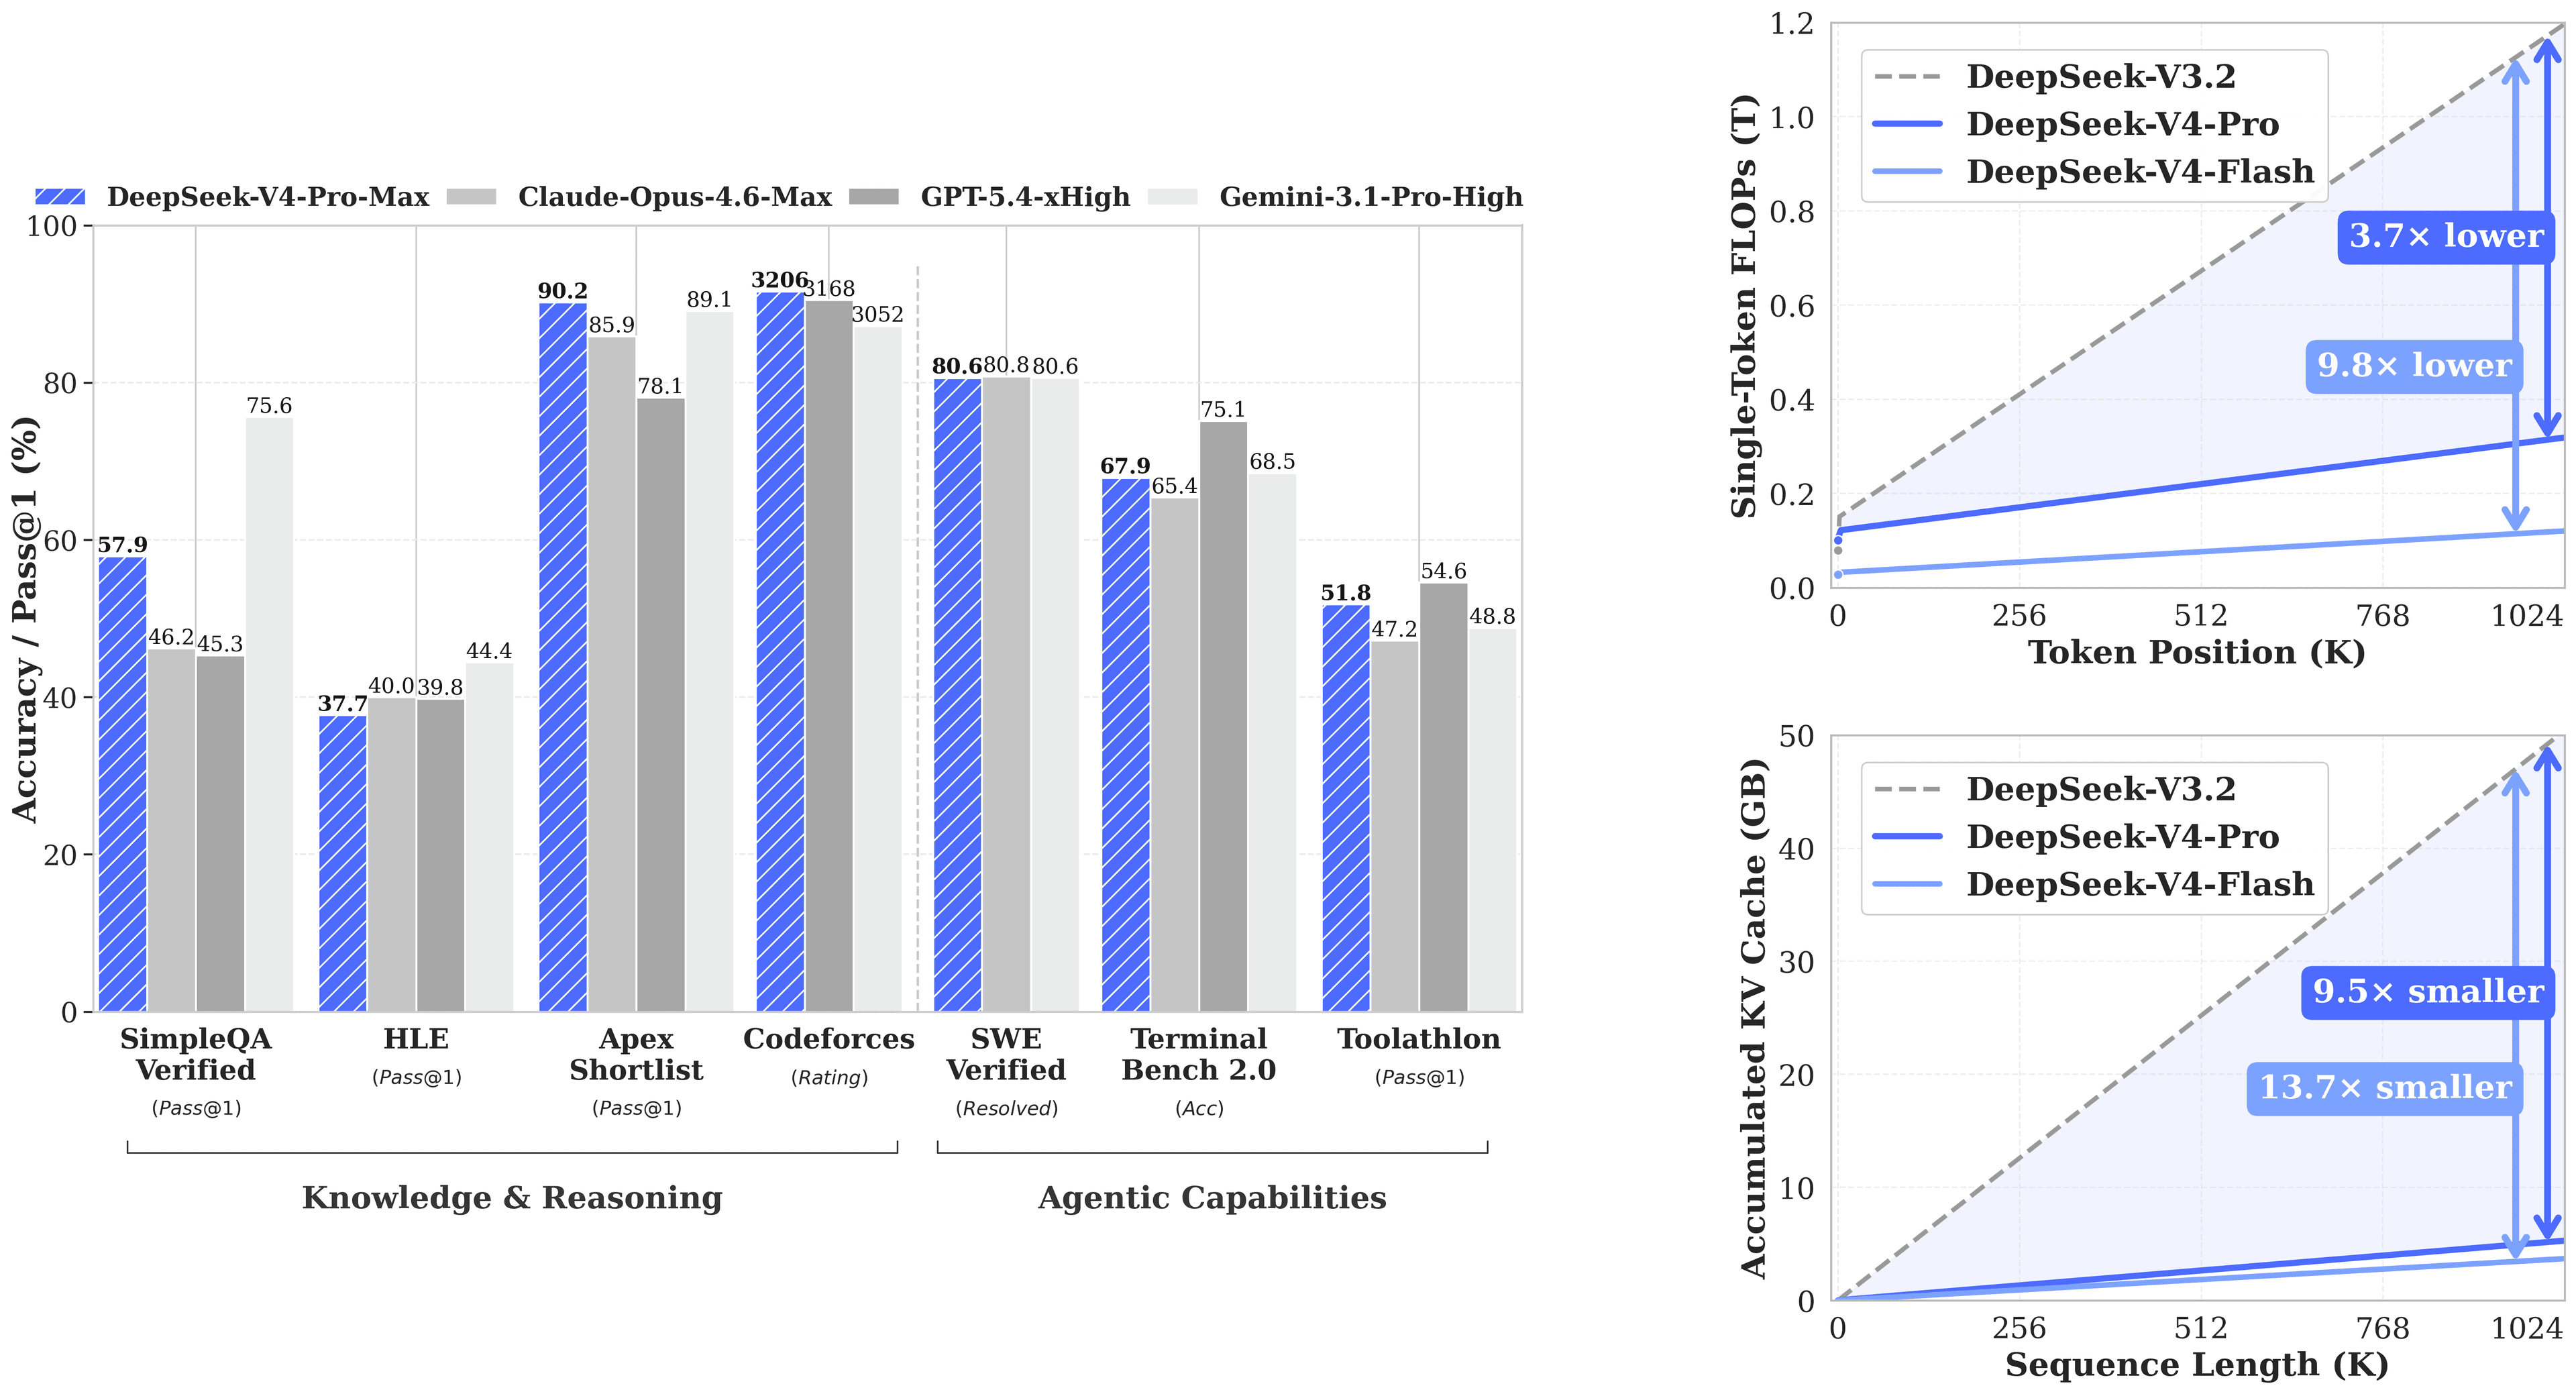
DeepSeek Releases V4-Pro, an MIT-Licensed MoE Model

The company's newest flagship targets reasoning and coding while keeping a permissive open-source license.

Aug 13, 2026
CodeText / LLM
DeepSeek-V4-Pro-0813
DeepSeek/Text / LLMDatacenter

DeepSeek Releases V4-Pro-0813 With Open Weights

The Chinese lab pushes a higher-capability checkpoint of its V4 line to Hugging Face under a permissive MIT license.

Aug 13, 2026
Text / LLMReasoning
DeepSeek-V4-Pro-0813
Meta AI/Vision-LanguageMajor releaseConsumer GPU

Meta's Muse Glimmer 30B Targets Local Agentic Coding

A 30-billion-parameter multimodal model built to run locally, released under Apache 2.0 with an eye on agentic coding workflows.

Aug 10, 2026
CodeReasoning
Muse Glimmer 30B
Qwen · Alibaba/Text / LLMMajor releaseDatacenter

Qwen releases 2.4T-parameter open MoE with 95B active

Alibaba's Qwen team pushes its largest sparse model yet, activating 95 billion parameters per token from a 2.4-trillion-parameter pool.

Aug 8, 2026
Text / LLMReasoning
Qwen3.8-2.4T-A95B
IBM/Text / LLMConsumer GPU

IBM's Granite 4.2 30B adds reasoning and tool calls

The new dense model brings optional step-by-step thinking and function calling under a permissive Apache-2.0 license.

Aug 7, 2026
Text / LLMReasoning
Granite 4.2 30B
Motif Technologies/Text / LLMMulti-GPU server

Motif 3 brings a sparse MoE approach to reasoning

Motif Technologies debuts a mixture-of-experts language model built around grouped differential latent attention for long-context reasoning and code.

Aug 7, 2026
CodeText / LLM
Motif 3
Deepgrove/ReasoningRuns on a laptop

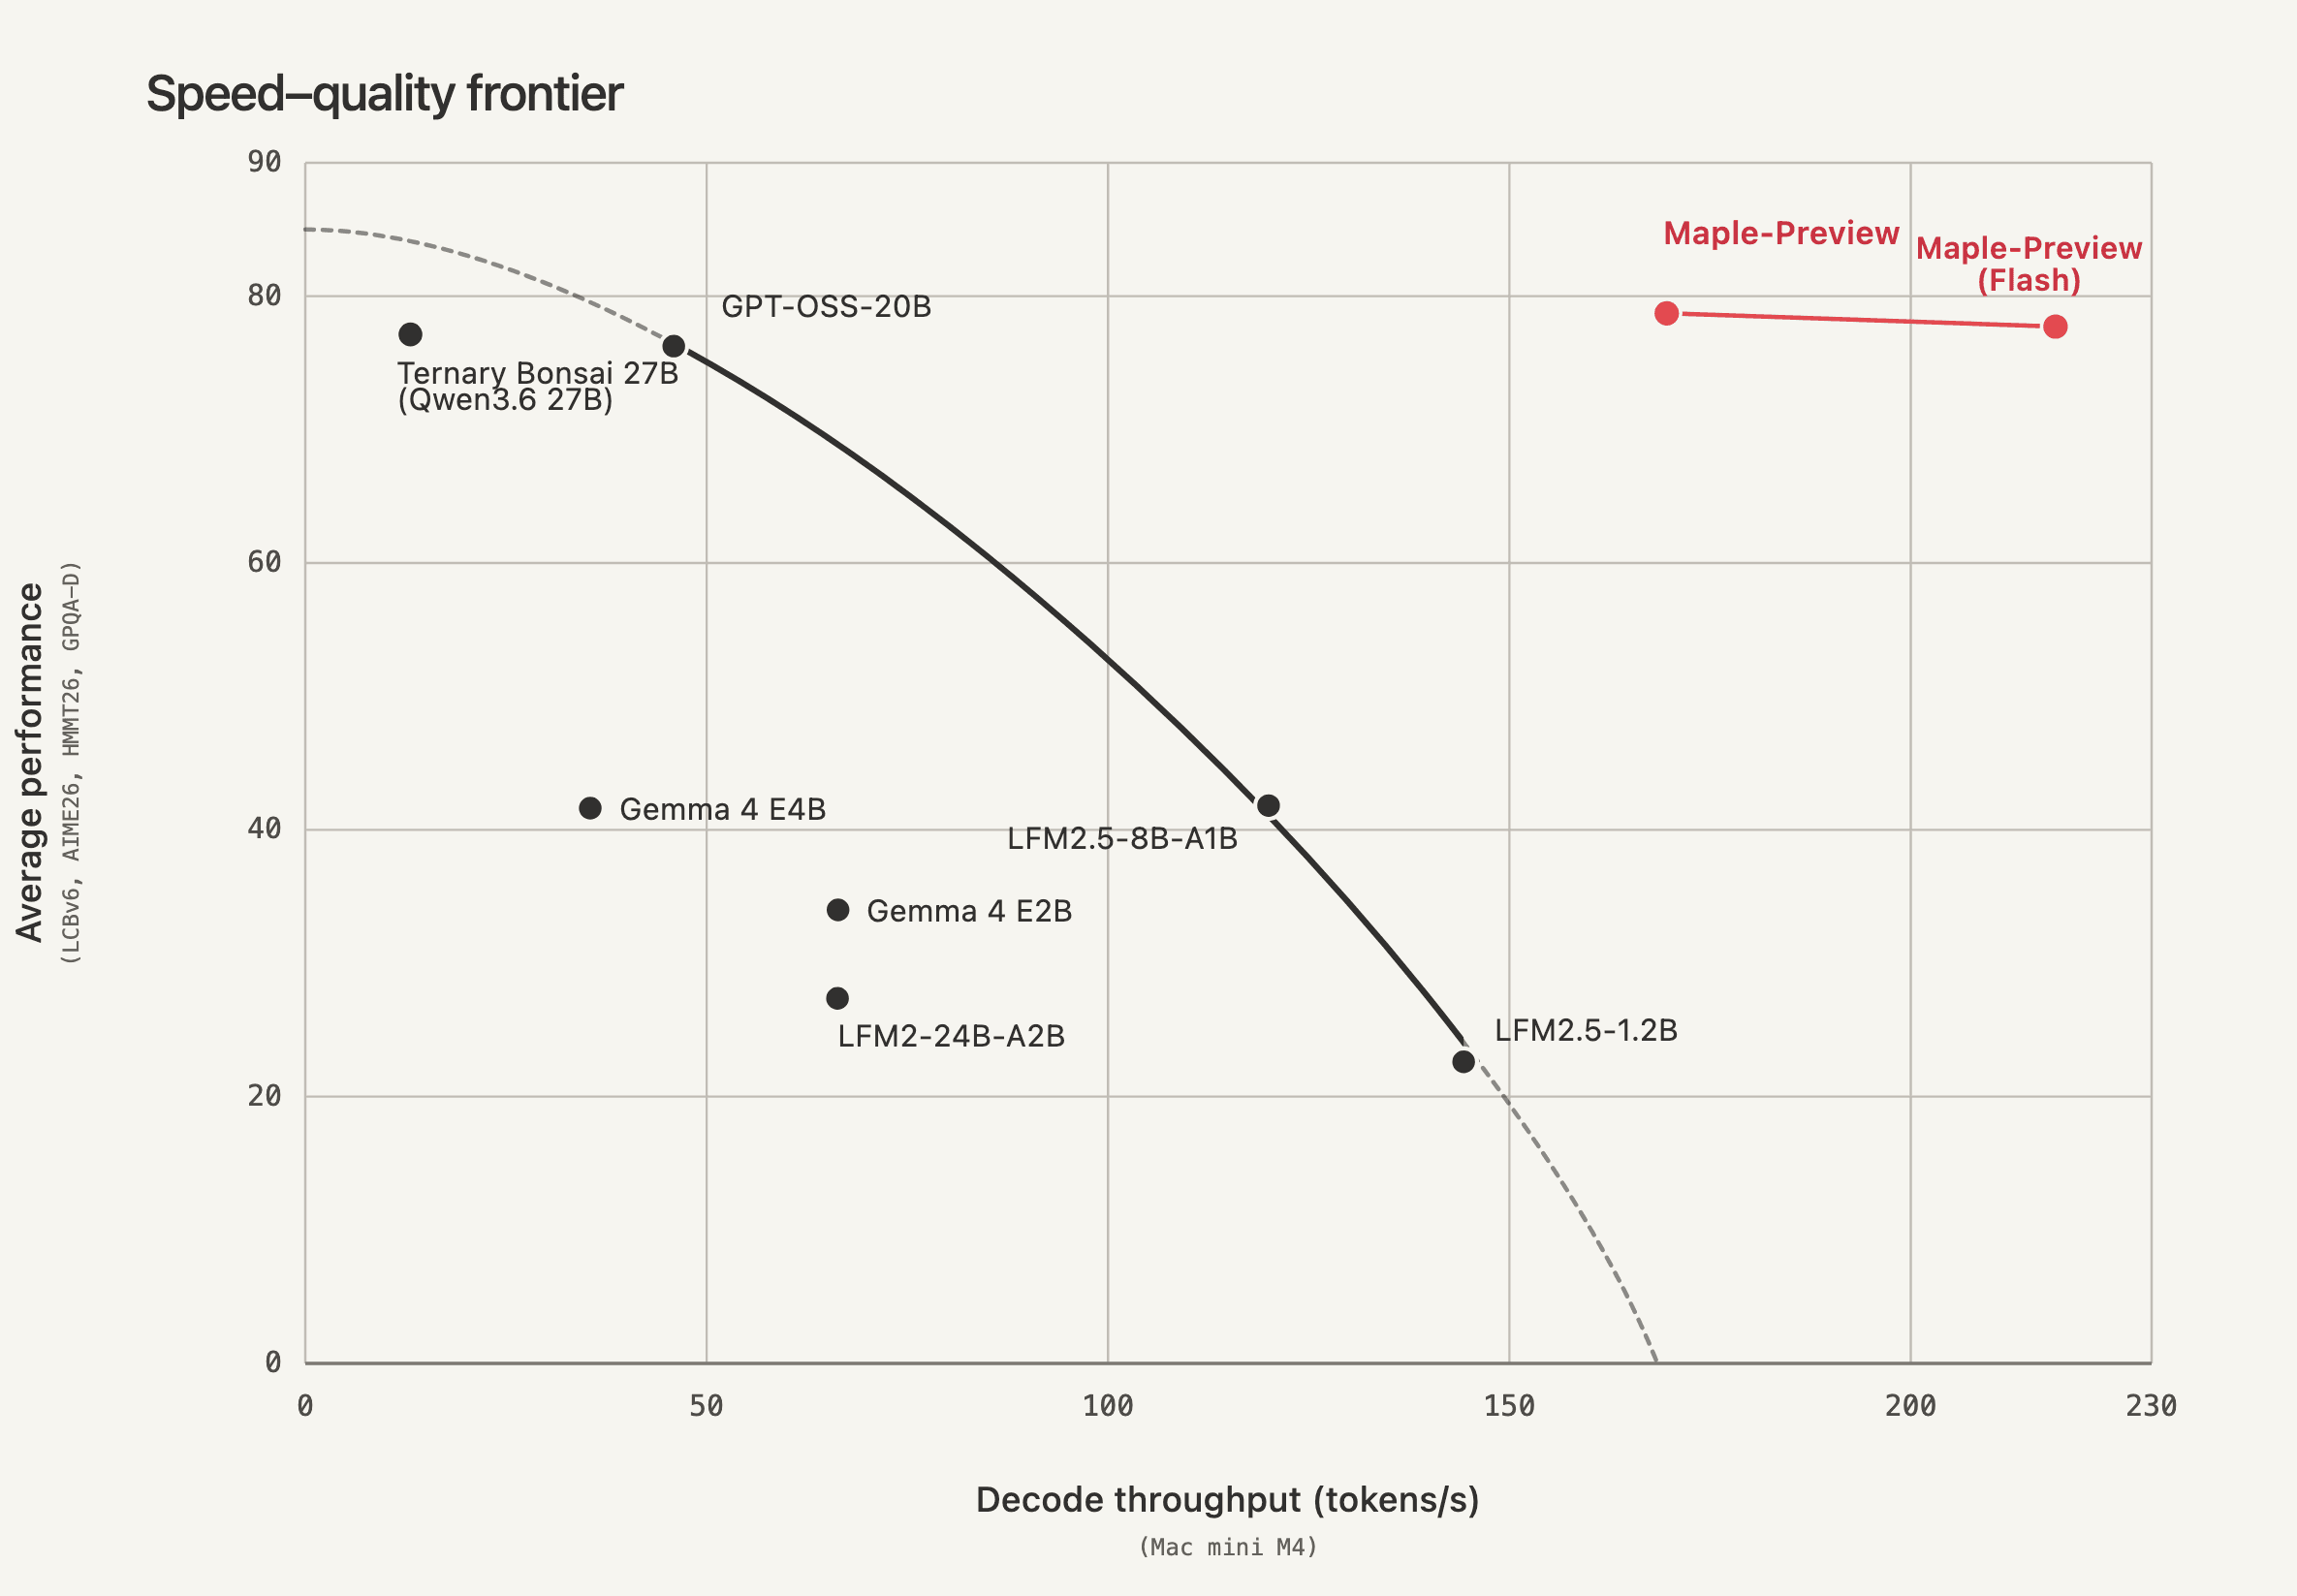
Deepgrove's Maple Preview bets on ternary-weight MoE

A permissively licensed reasoning model that pairs a mixture-of-experts design with ternary weights, aiming for efficiency.

Aug 4, 2026
Text / LLMReasoning
Maple Preview
NVIDIA/Text / LLMRuns on a laptop

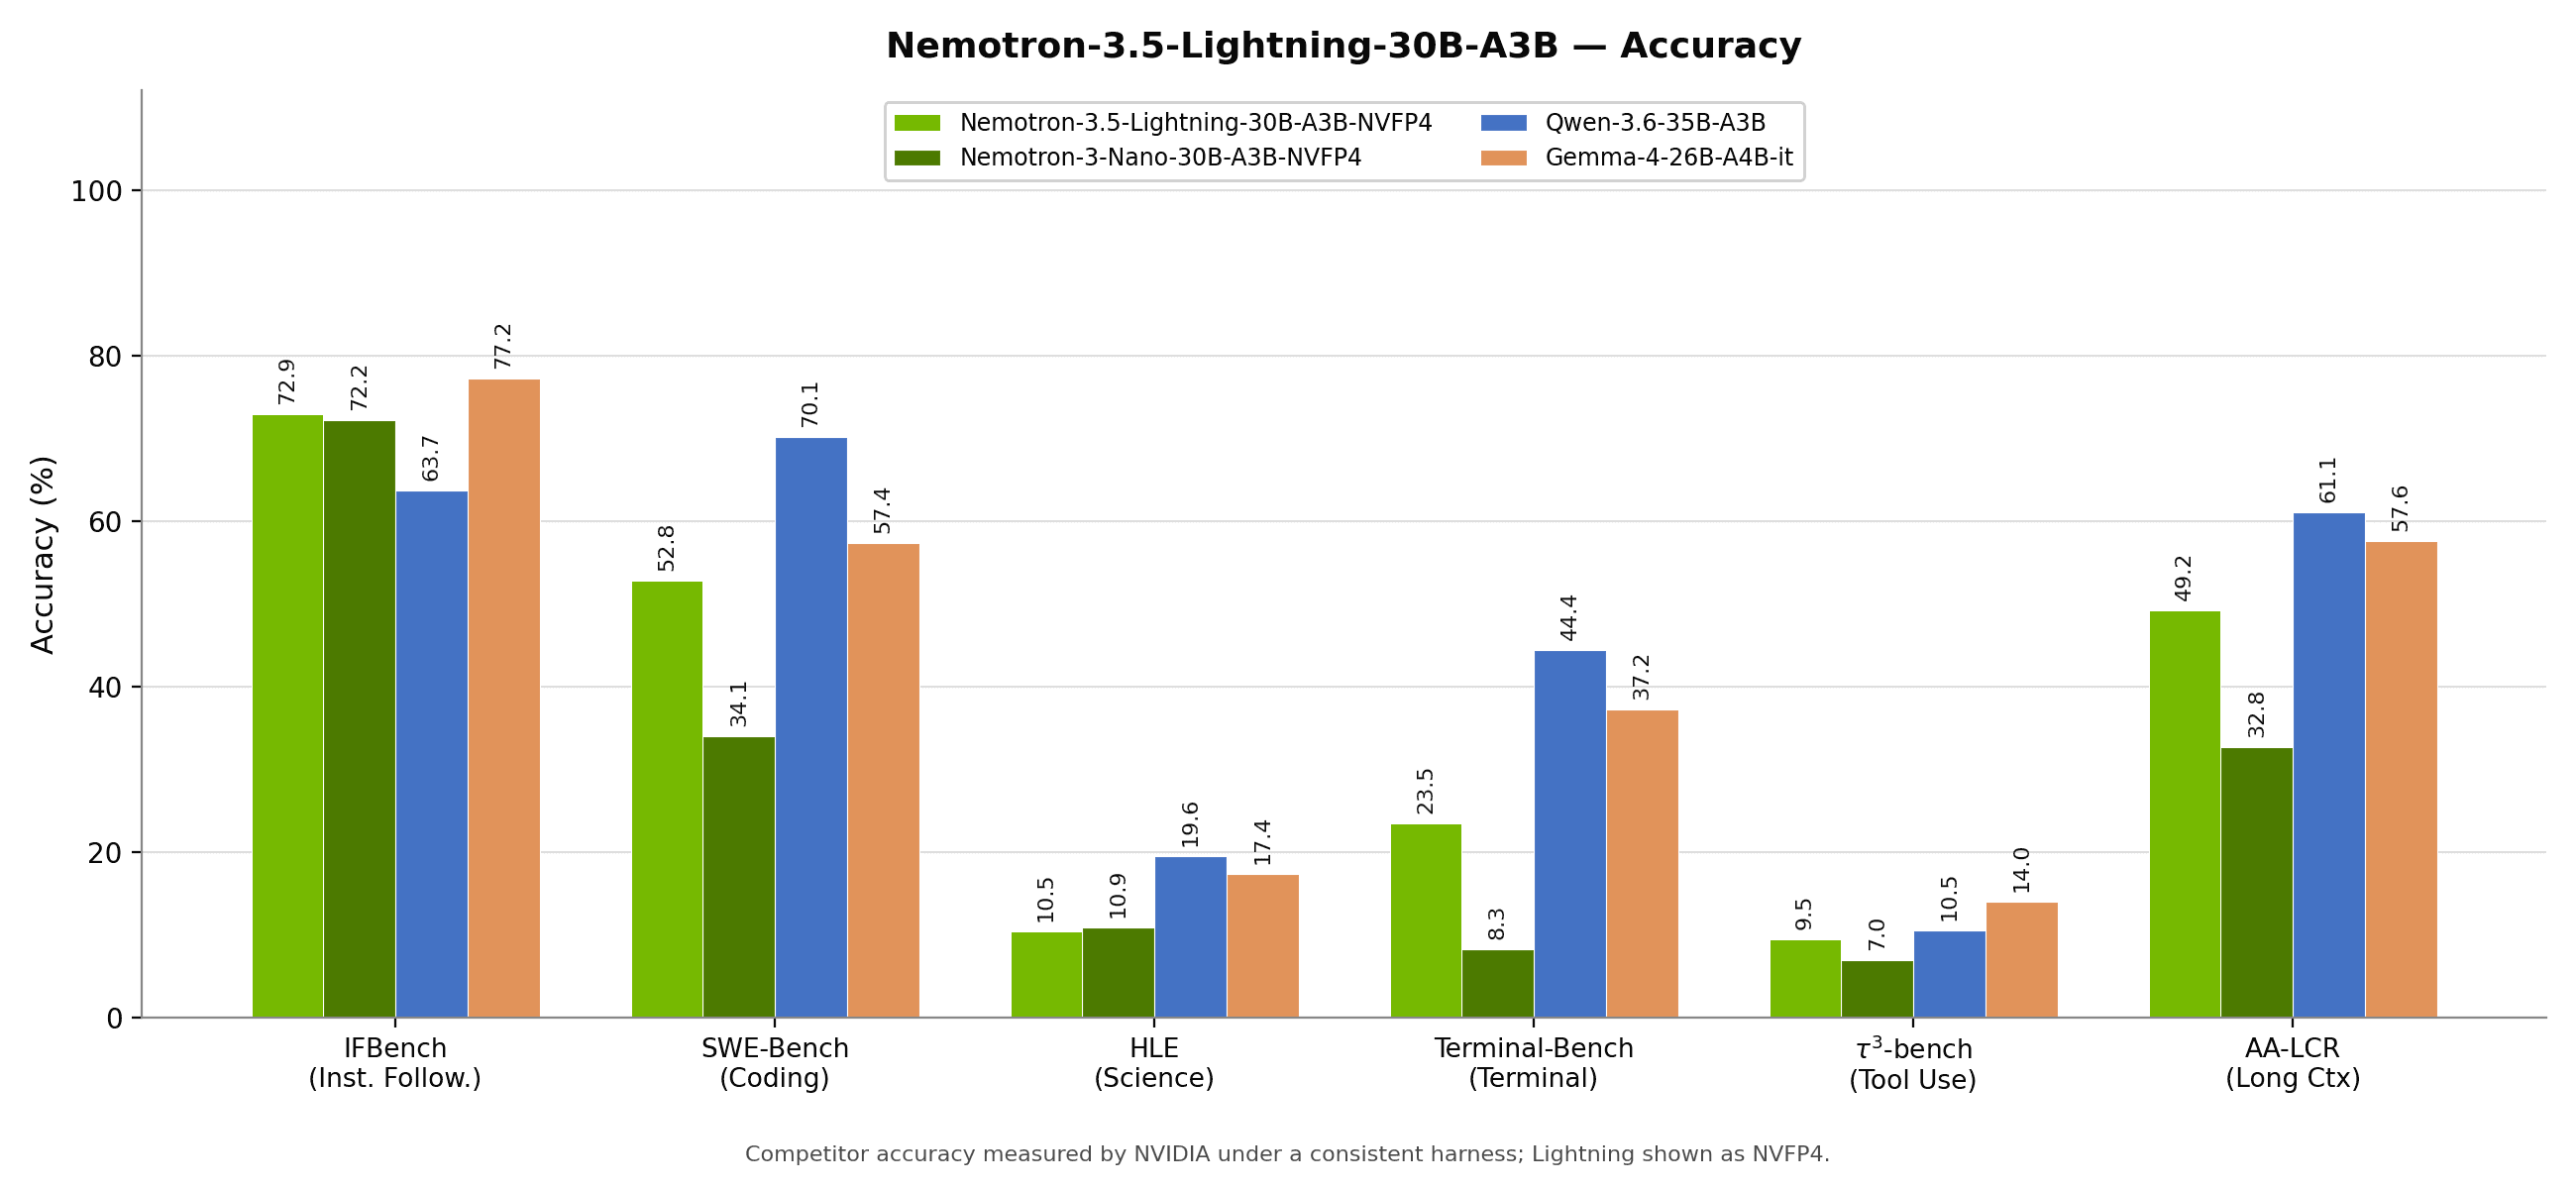
NVIDIA's Nemotron 3.5 Lightning trims MoE for speed

A 30-billion-parameter mixture-of-experts model activates just 3 billion parameters per token, using a hybrid Mamba design to keep inference fast.

Aug 4, 2026
Text / LLMReasoning
Nemotron-3.5-Lightning-30B-A3B
NVIDIA/Text / LLMConsumer GPU

NVIDIA's Nemotron 3.5 Lightning Blends Mamba and MoE

A 30B mixture-of-experts model with just 3B active parameters aims at fast, agentic coding workloads.

Aug 1, 2026
Text / LLMReasoning
Nemotron-3.5-Lightning-30B-A3B
DeepSeek/Text / LLMMulti-GPU server

DeepSeek Ships V4-Flash, a 304B MoE Tuned for Agents

The latest checkpoint in DeepSeek's V4 line leans into agentic workflows while keeping the permissive MIT license.

Jul 31, 2026
Text / LLMReasoning
DeepSeek-V4-Flash-0731
DeepSeek/Text / LLMMajor releaseMulti-GPU server

DeepSeek Refreshes V4-Flash With New 0731 Checkpoint

The MIT-licensed mixture-of-experts model returns in an updated build shipping with FP8 weights for cheaper inference.

Jul 31, 2026
Text / LLMReasoning
DeepSeek-V4-Flash-0731
LGAI EXAONE/Text / LLMDatacenter

LG AI Research debuts K-EXAONE 2.0, a 750B MoE model

The new mixture-of-experts model activates 37B parameters per token and targets English, Korean, and Spanish reasoning tasks.

Jul 29, 2026
Text / LLMReasoning
K-EXAONE 2.0 750B-A37B
Amd/ReasoningRuns on a laptop

AMD's Instella-MoE Brings Reasoning to ROCm Hardware

A new open mixture-of-experts model with 16B total parameters and just 3B active is tuned to run on AMD's own accelerator stack.

Jul 23, 2026
Text / LLMReasoning
Instella-MoE 16B A3B Think
OpenAI/Any-to-Any

Thinking Machines ships Inkling, its first open model

The Mira Murati-founded lab makes its debut with an open-weights, reasoning-focused language model.

Jul 15, 2026
Text / LLMReasoning
inclusionAI/Reasoning

inclusionAI's Ring-Zero Scales Zero-RL to a Trillion Parameters

A new mixture-of-experts model learns to reason through reinforcement learning alone, without human-annotated chains of thought.

Jul 13, 2026
Text / LLMReasoning
NVIDIA/Any-to-AnyConsumer GPU

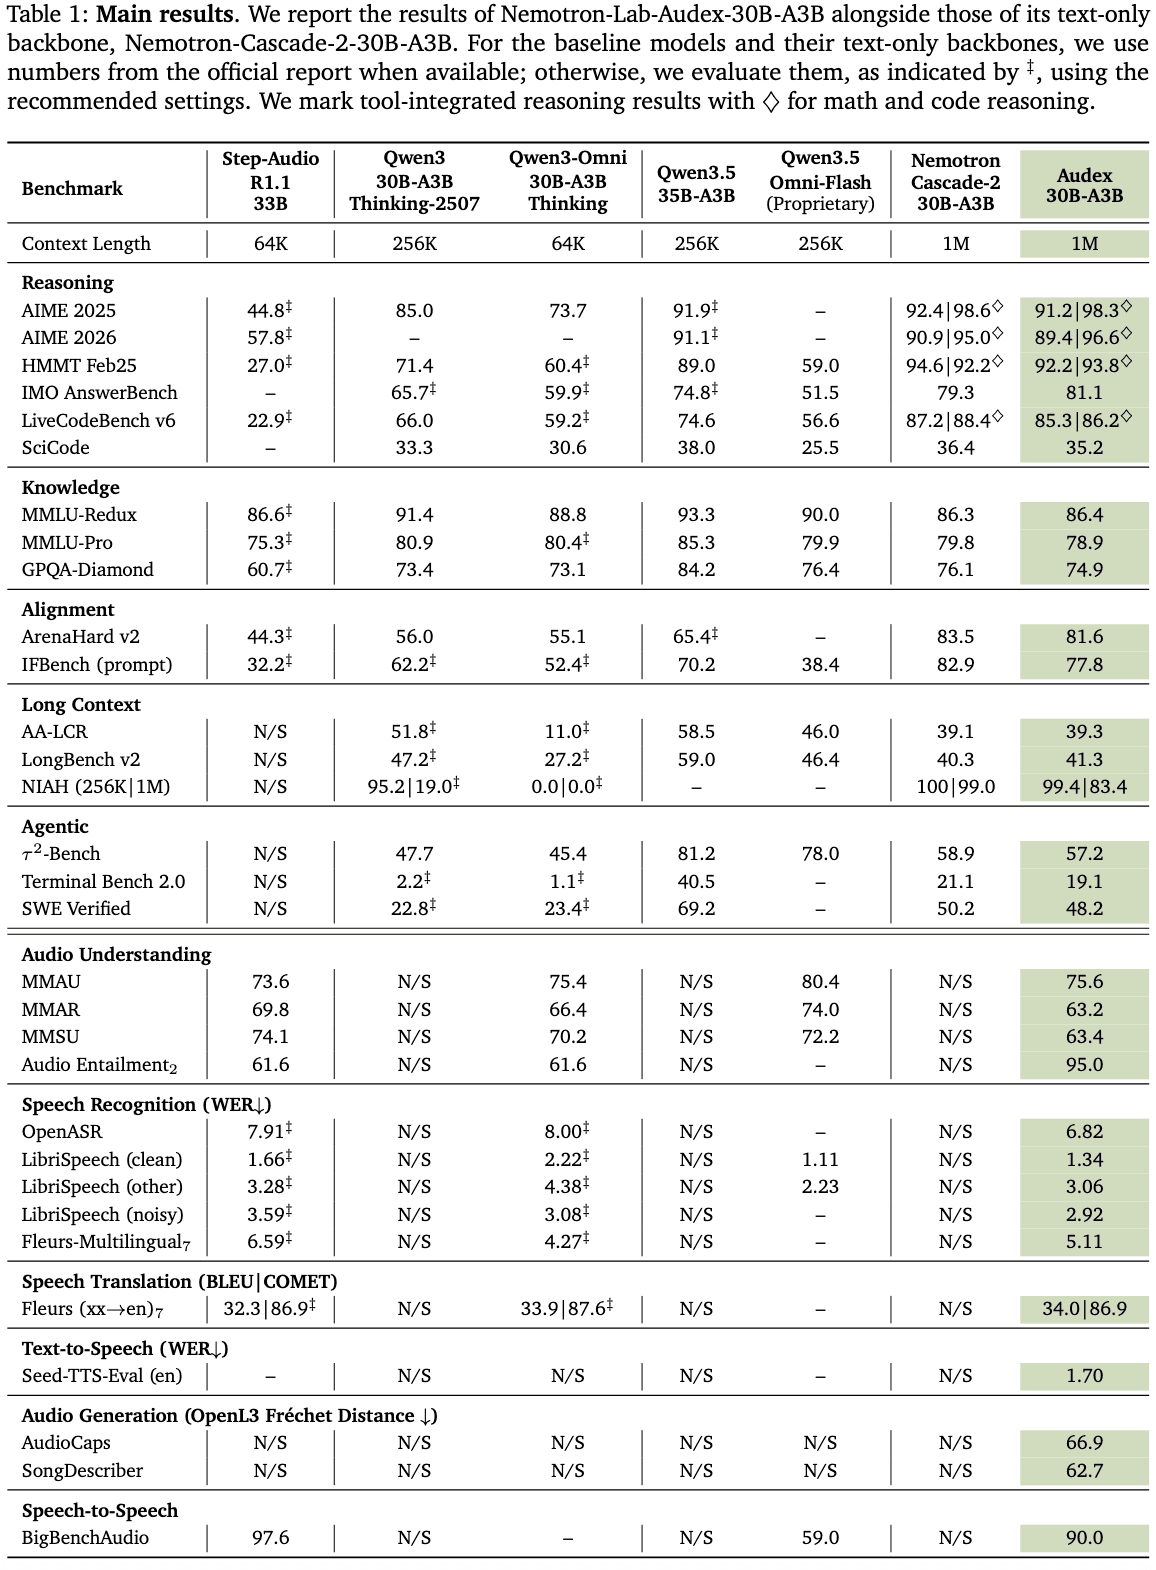
NVIDIA's Audex Unifies Audio Understanding and Speech

A new 30B mixture-of-experts model from NVIDIA handles both listening and speaking within a single audio-text architecture.

Jul 6, 2026
Any-to-AnyReasoning
Nemotron-Labs-Audex-30B-A3B
Google DeepMind/Any-to-AnyMajor release

Google DeepMind's Gemma 4 Goes Multimodal and MoE

The new open-weights family adds a mixture-of-experts design, encoder-free multimodal inputs, and an optional thinking mode.

Jul 1, 2026
Text / LLMAny-to-Any
Mistral AI/Text / LLMWorkstation GPU

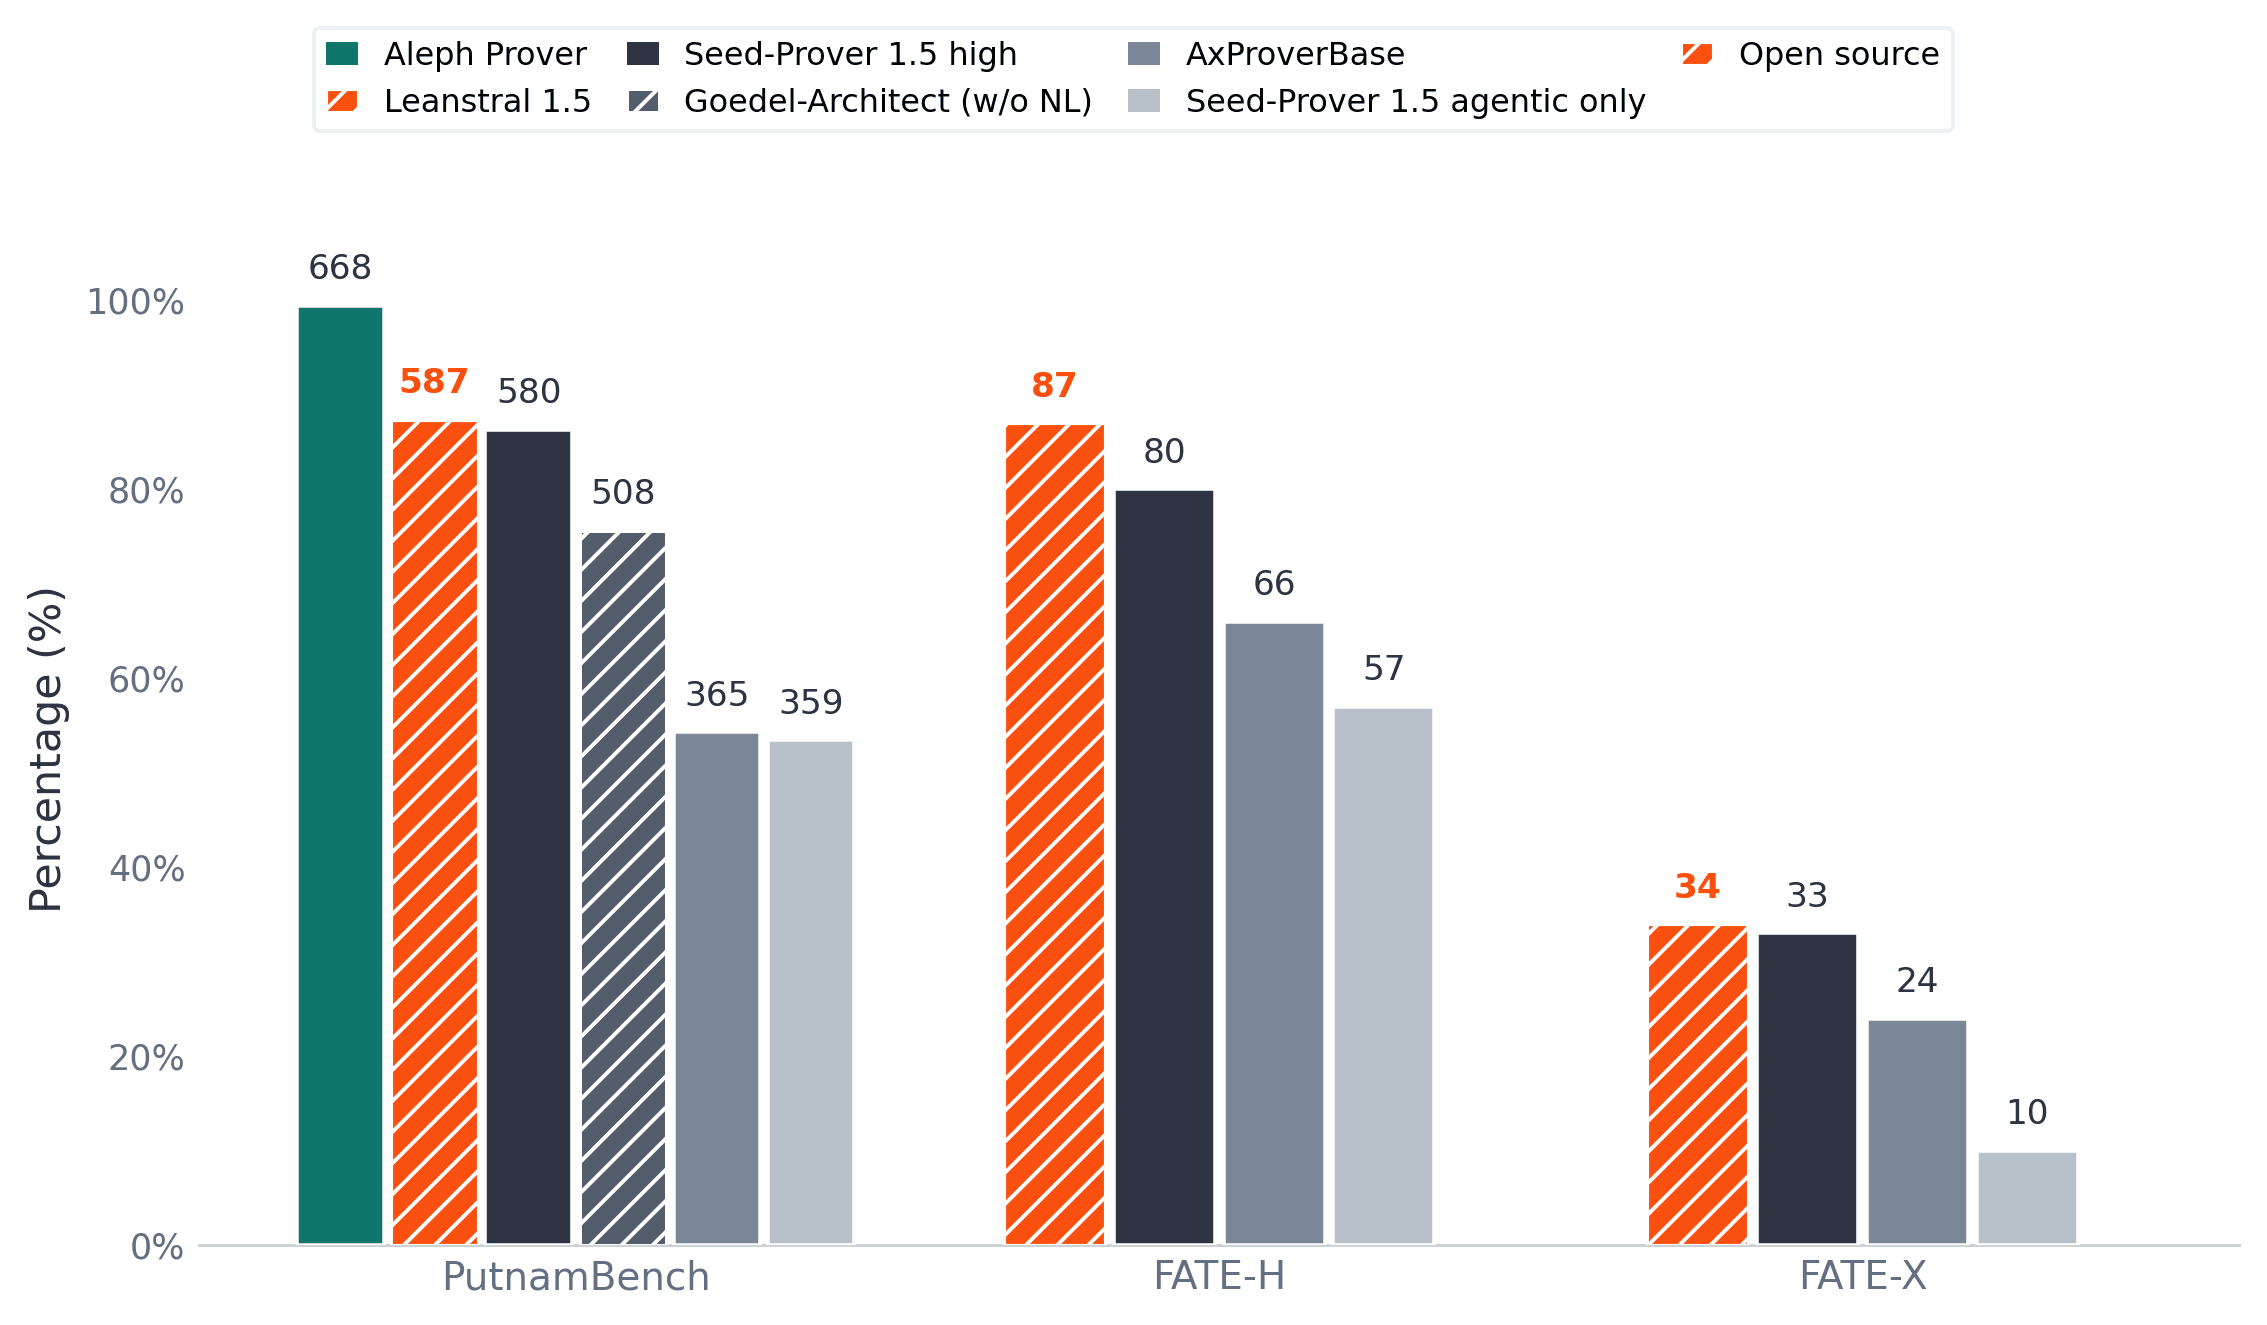
Mistral's Leanstral 1.5 puts 119B in a lean MoE

The new Apache-2.0 mixture-of-experts model activates just 6B parameters per token, trading raw density for cheaper inference.

Jul 1, 2026
Text / LLMReasoning
Leanstral-1.5-119B-A6B
DeepSeek/Text / LLMMajor releaseDatacenter

DeepSeek Releases V4-Pro, an MIT-Licensed MoE Model

The new flagship arrives as a mixture-of-experts system with FP8 weights and open reasoning capabilities under a permissive license.

Jun 27, 2026
Text / LLMReasoning
DeepSeek-V4-Pro
Deepreinforce Ai/Text / LLMConsumer GPU

DeepReinforce Releases Ornith 1.0, a 35B Reasoning Model

The new dense model ships in GGUF format under a permissive MIT license, aimed at local and self-hosted deployment.

Jun 25, 2026
Text / LLMReasoning
Ornith-1.5-122B
NVIDIA/Text / LLMWorkstation GPU

NVIDIA's Nemotron 3 Puzzle Runs Big on a Lean Budget

A 75-billion-parameter mixture-of-experts reasoning model that activates just 9 billion parameters per token.

Jun 24, 2026
Text / LLMReasoning
Nemotron-Labs-3-Puzzle-75B-A9B
NVIDIA/Text / LLMWorkstation GPU

NVIDIA's Nemotron-3 Puzzle Brings a Lean MoE to Reasoning

The 75B-parameter model activates just 9B per token and ships in NVIDIA's NVFP4 format for efficient inference.

Jun 24, 2026
Text / LLMReasoning
Nemotron-3 Puzzle 75B-A9B
Deepreinforce Ai/Text / LLMMulti-GPU server

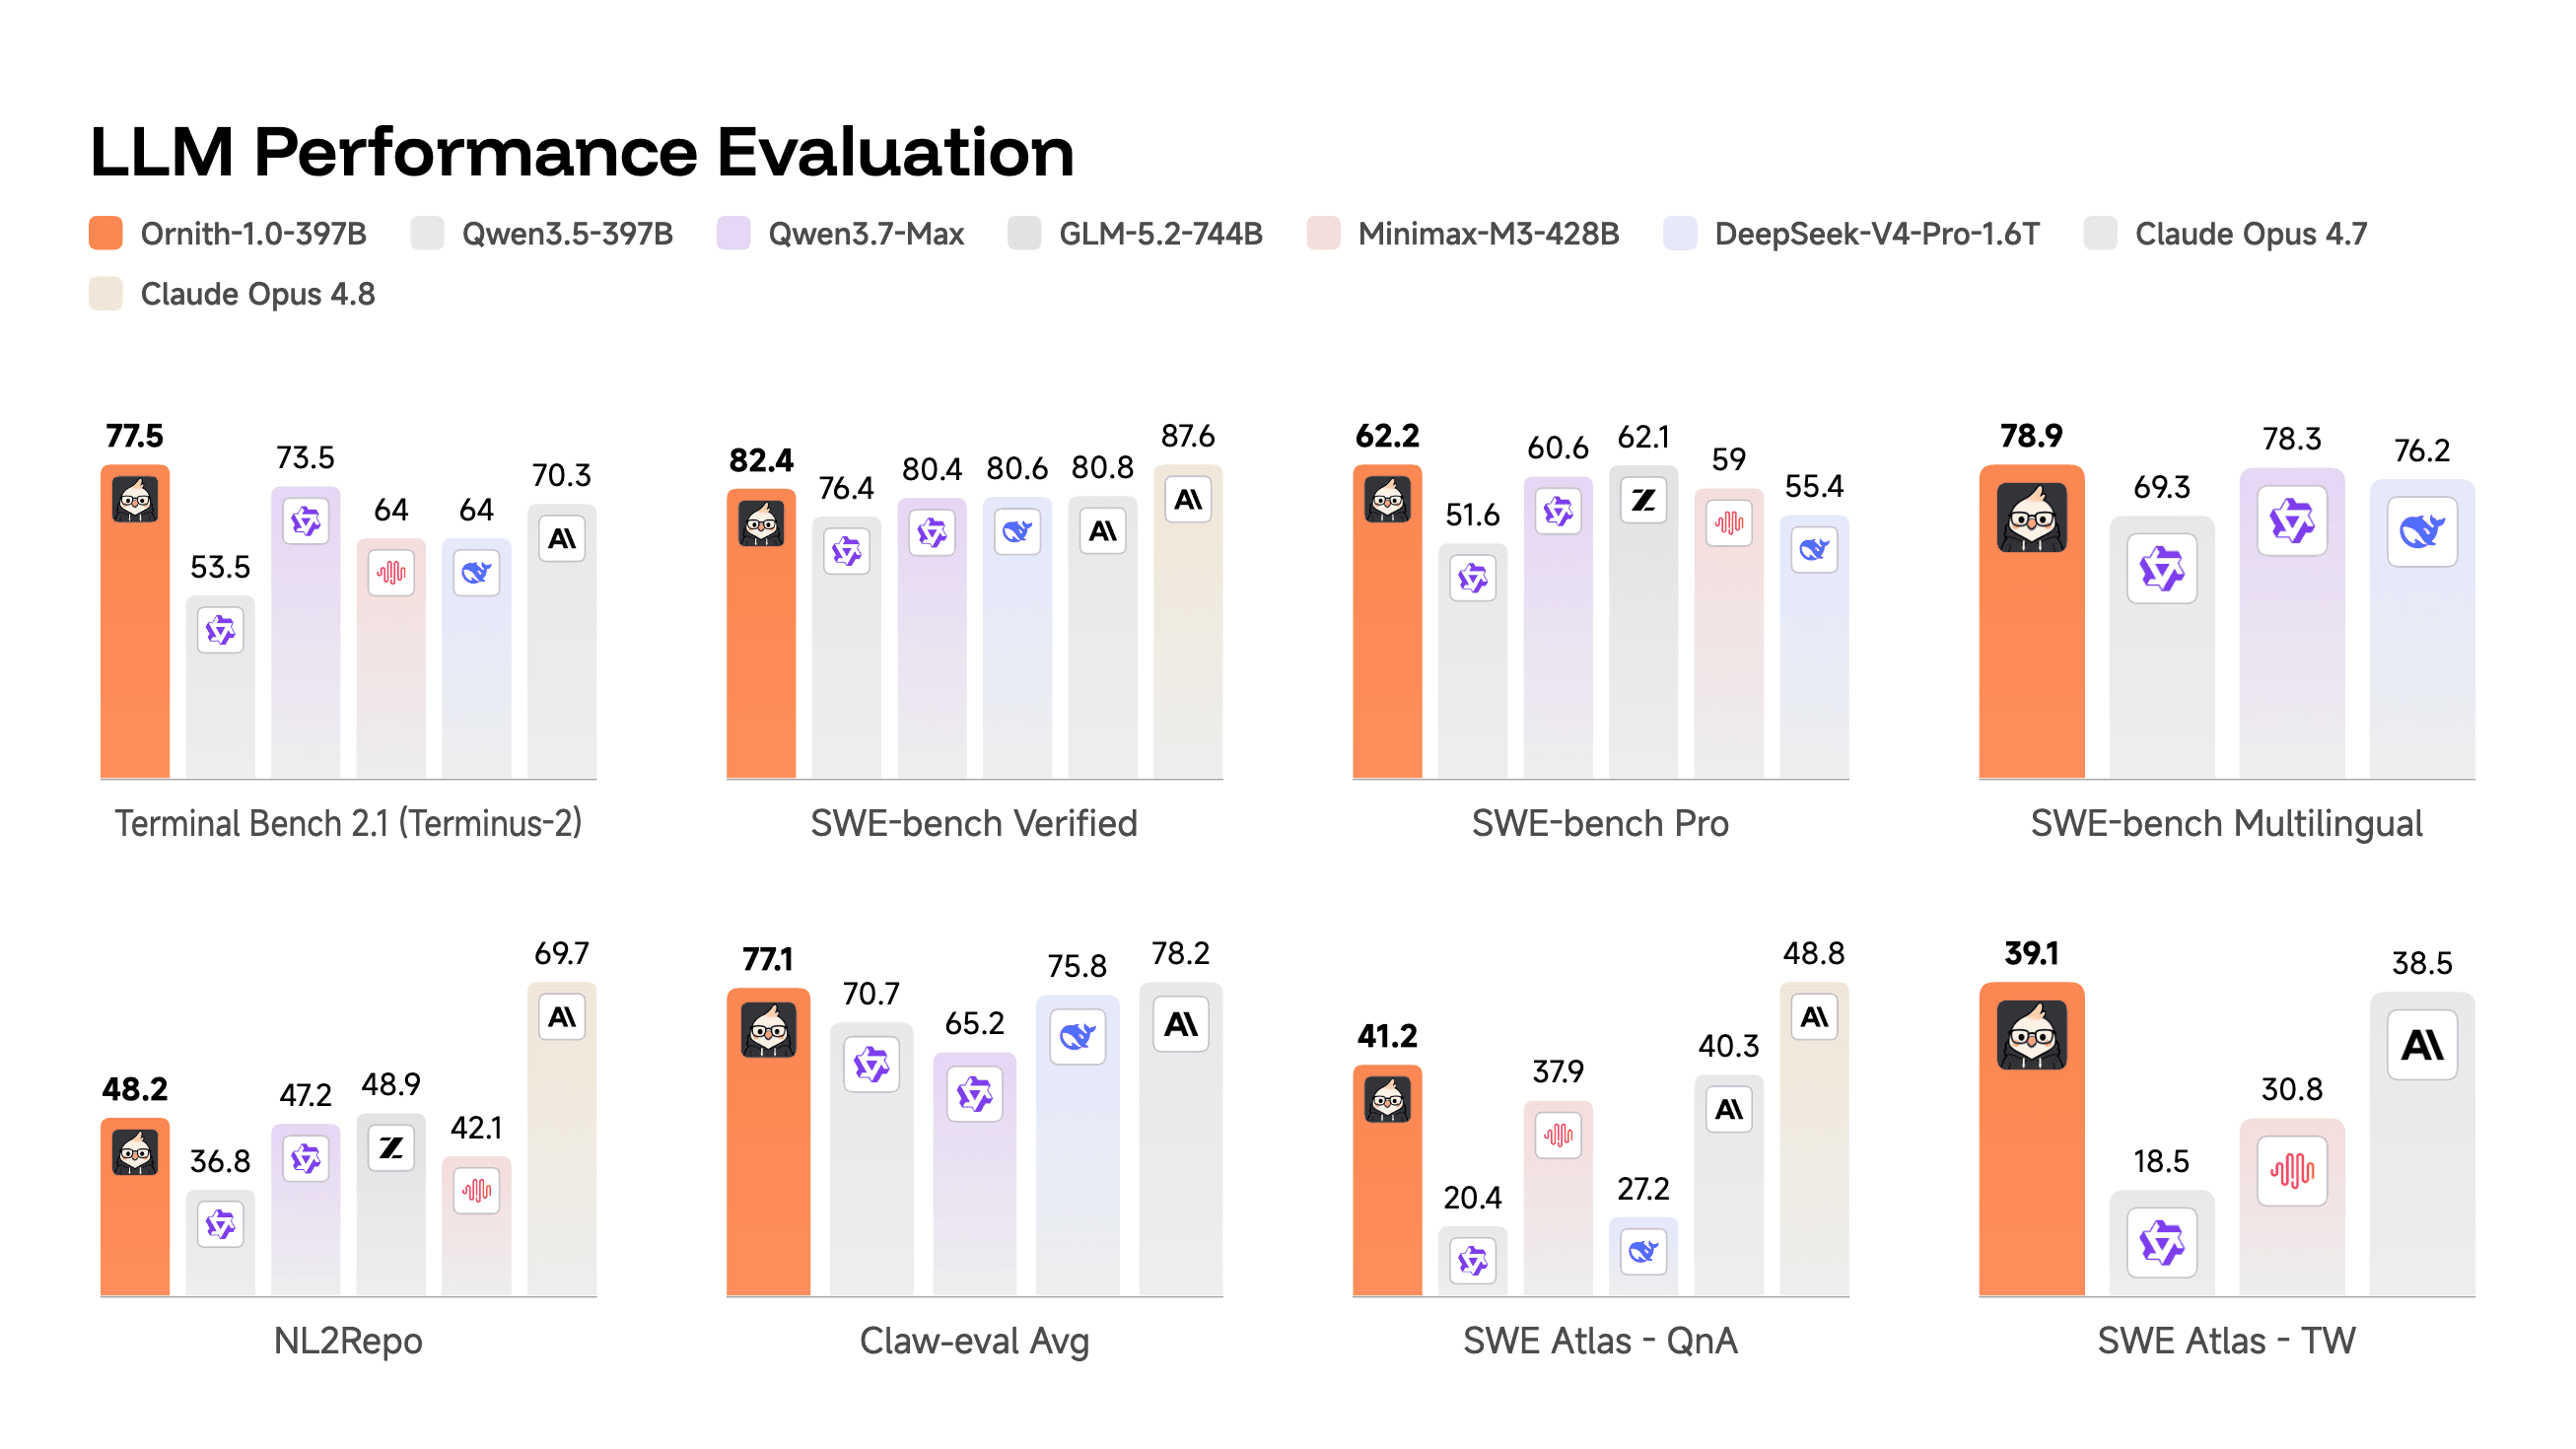
DeepReinforce debuts Ornith-1.0, a 397B MoE model

The flagship of a new open model family arrives under a permissive MIT license, with reasoning among its stated strengths.

Jun 23, 2026
Text / LLMReasoning
Ornith-1.5-122B
Qwen · Alibaba/Text / LLMConsumer GPU

Qwen's AgentWorld Simulates Worlds for AI Agents

Alibaba's new MoE model acts as a language world model, generating the environments that agents act within.

Jun 22, 2026
Text / LLMReasoning
Qwen-AgentWorld-35B-A3B
InternScience/ReasoningConsumer GPU

Agents-A1: A 35B MoE Built for Agentic Scaling

InclusionAI's new mixture-of-experts model bets that agent-horizon scaling can rival far larger systems on long-running tasks.

Jun 22, 2026
Text / LLMReasoning
Agents-A1
Zhipu AI/Text / LLMMajor releaseDatacenter

Zhipu AI Releases MIT-Licensed GLM-5.2 MoE Model

The new bilingual model from the Chinese AI firm uses a Mixture of Experts architecture and sparse attention under a fully permissive license.

Jun 17, 2026
Text / LLMReasoning
GLM-5.3
Moonshot AI/Text / LLMMajor releaseDatacenter

Moonshot AI releases Kimi K3, a 2.8T-parameter MoE model

The open-weights multimodal model leans into coding and agentic tasks, extending Moonshot's Kimi line into a new scale bracket.

Jun 13, 2026
Text / LLMReasoning
Kimi K3
WeiboAI/ReasoningRuns anywhere

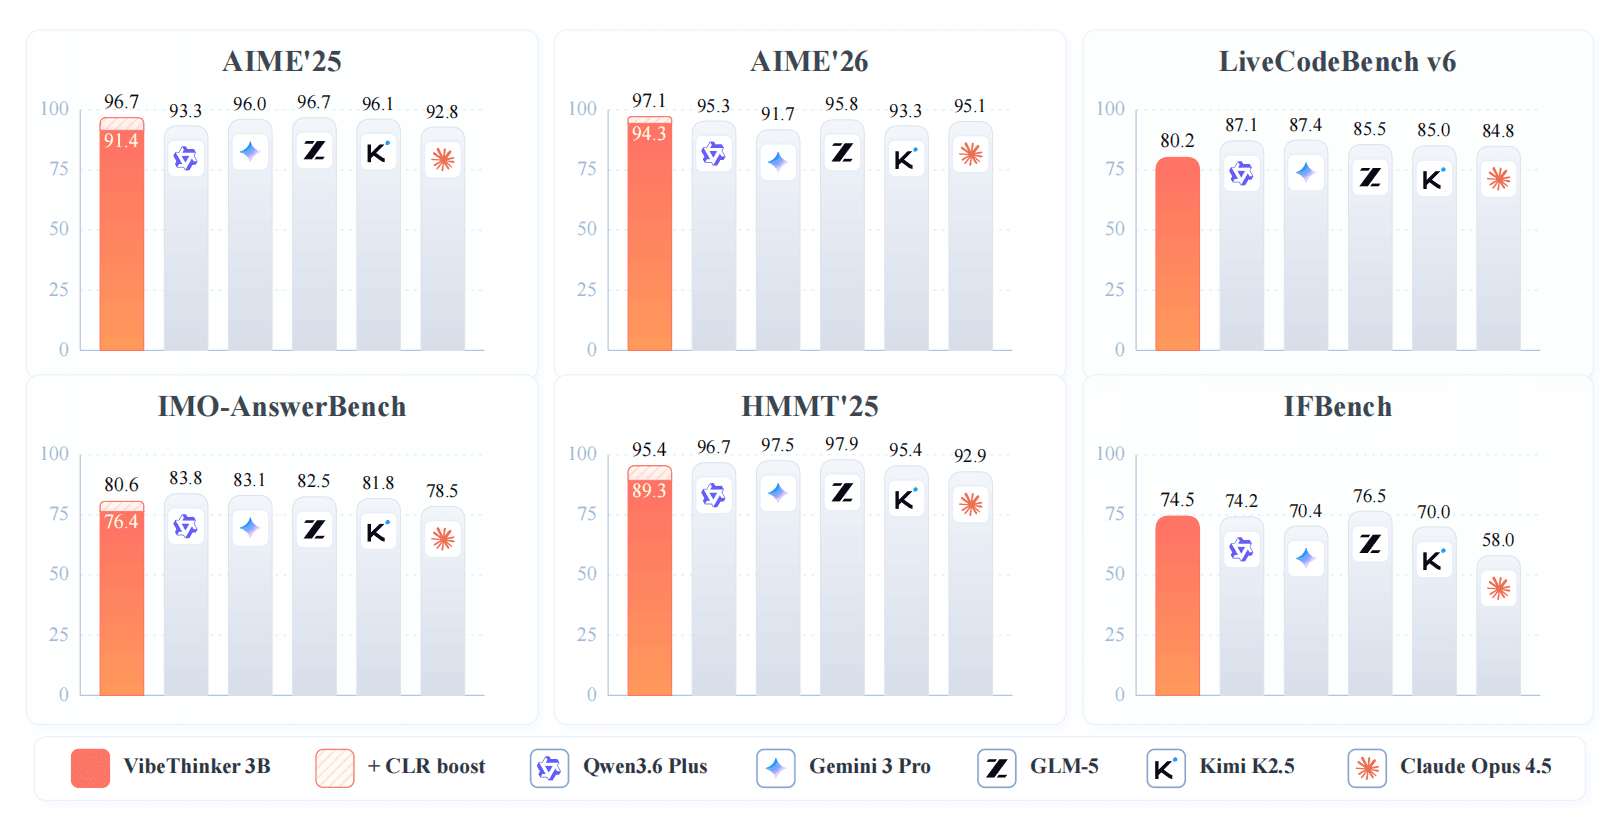
Weibo AI Releases VibeThinker-3B, a Compact Reasoning Model

The new 3-billion-parameter model from the Chinese tech giant focuses on challenging benchmarks in mathematics, coding, and graduate-level questions.

Jun 12, 2026
CodeText / LLM
VibeThinker-3B
MiniMax/Vision-LanguageMajor releaseMulti-GPU server

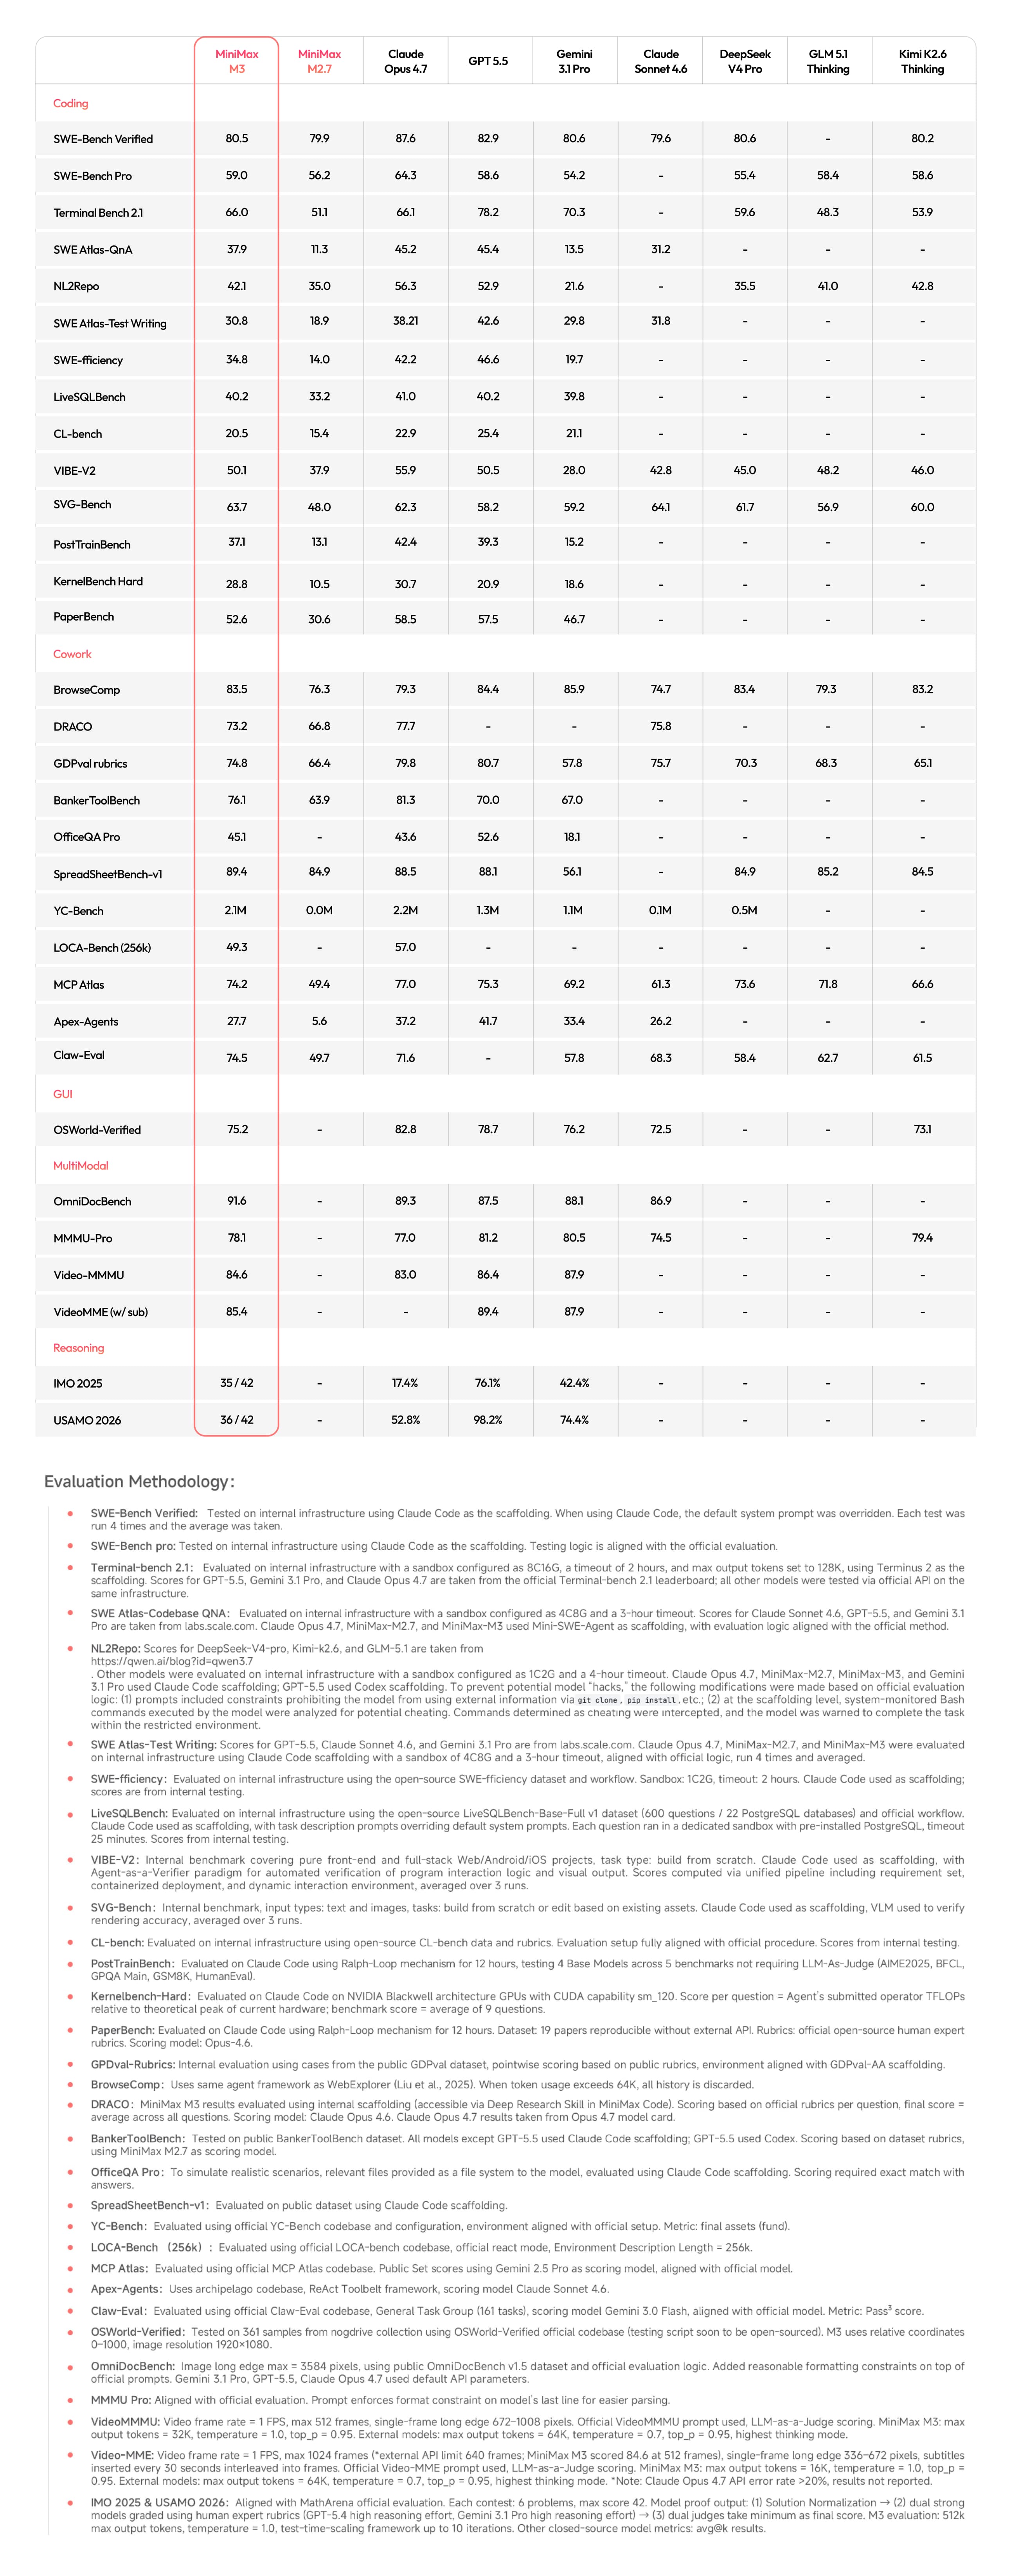
MiniMax Releases M3, a Multimodal MoE Model

The new open-weight model from MiniMax AI combines vision, coding, and reasoning using a Mixture-of-Experts architecture.

Jun 2, 2026
CodeAny-to-Any
MiniMax-M3
Moonshot AI/Vision-LanguageMajor release

Kimi K2.6 tops closed models in coding test

Moonshot AI's open-weights mixture-of-experts model reportedly outperformed Claude, GPT-5.5, and Gemini on a programming challenge.

May 3, 2026
CodeText / LLM
NVIDIA/Any-to-AnyRuns on a laptop

NVIDIA Releases Efficient Nemotron-3 Multimodal MoE

The new 30-billion parameter Mixture-of-Experts model handles text and images while using only 3 billion active parameters for inference.

Apr 24, 2026
Any-to-AnyReasoning
Nemotron-3 Nano Omni 30B-A3B Reasoning
DeepSeek/Text / LLMMajor releaseDatacenter

DeepSeek Releases V4-Pro, an Open MoE Contender

The new flagship model combines a Mixture-of-Experts architecture with a permissive MIT license, positioning it for wide commercial adoption.

Apr 22, 2026
CodeText / LLM
DeepSeek-V4-Pro
DeepSeek/Text / LLMMajor releaseMulti-GPU server

DeepSeek Releases V4-Flash, a Fast MIT-Licensed MoE Model

The new Mixture of Experts model from the Beijing-based AI lab is optimized for fast, efficient conversational AI and carries a fully permissive license.

Apr 22, 2026
Text / LLMReasoning
DeepSeek V4.1 Flash
NVIDIA/Any-to-AnyConsumer GPU

NVIDIA Releases Nemotron-3-Nano Omni-Modal MoE

The new 30-billion-parameter Mixture-of-Experts model handles any combination of modalities with just 3 billion active parameters.

Apr 20, 2026
Any-to-AnyReasoning
Nemotron-3 Nano Omni 30B-A3B Reasoning
Qwen · Alibaba/Vision-LanguageMajor releaseConsumer GPU

Qwen Releases 35B Multimodal Mixture-of-Experts Model

The new Qwen3.6-35B-A3B from Alibaba's Qwen team combines vision and language capabilities using an efficient sparse architecture.

Apr 15, 2026
Text / LLMReasoning
Qwen3.8-27B
MiniMax/Text / LLMMulti-GPU server

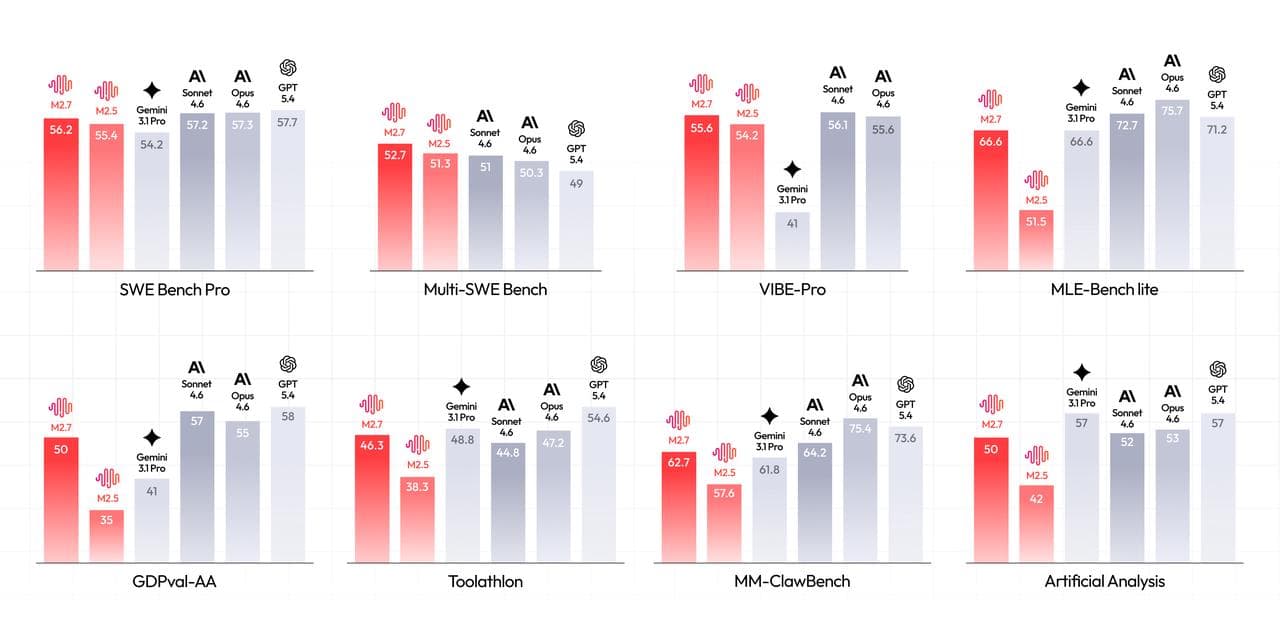
MiniMax Releases M2.7, an MoE Model with FP8 Weights

The new conversational language model from the Chinese AI company uses a Mixture-of-Experts architecture and 8-bit weights, but is released under a restrictive custom license.

Apr 9, 2026
Text / LLMReasoning
MiniMax-M2.7
Zhipu AI/Text / LLMMajor releaseDatacenter

Zhipu AI Releases Open-Source GLM-5.1 MoE Model

The new bilingual model from the Chinese AI firm features an efficient Mixture-of-Experts architecture and a fully permissive MIT license.

Apr 3, 2026
Text / LLMReasoning
GLM-5.3
Zhipu AI/Text / LLMMajor releaseDatacenter

Zhipu AI Releases Open-Source GLM-5 MoE Model

The new Mixture-of-Experts model from the Chinese AI company combines an advanced architecture with a fully permissive MIT license for commercial use.

Feb 11, 2026
Text / LLMReasoning
GLM-5.3
Google DeepMind/Vision-LanguageRuns on a laptop

Google's MedGemma brings open vision AI to medicine

The new 4-billion-parameter vision-language model is specialized for tasks in radiology, pathology, and complex clinical reasoning.

Jan 7, 2026
ReasoningVision-Language
MedGemma 1.5 4B IT
Moonshot AI/Vision-LanguageMajor releaseDatacenter

Moonshot AI Releases Kimi K2.5 Multimodal Model

The new vision-language model from the Chinese AI firm uses a Mixture-of-Experts architecture and is now available on Hugging Face.

Jan 1, 2026
Text / LLMReasoning
Kimi K2.6
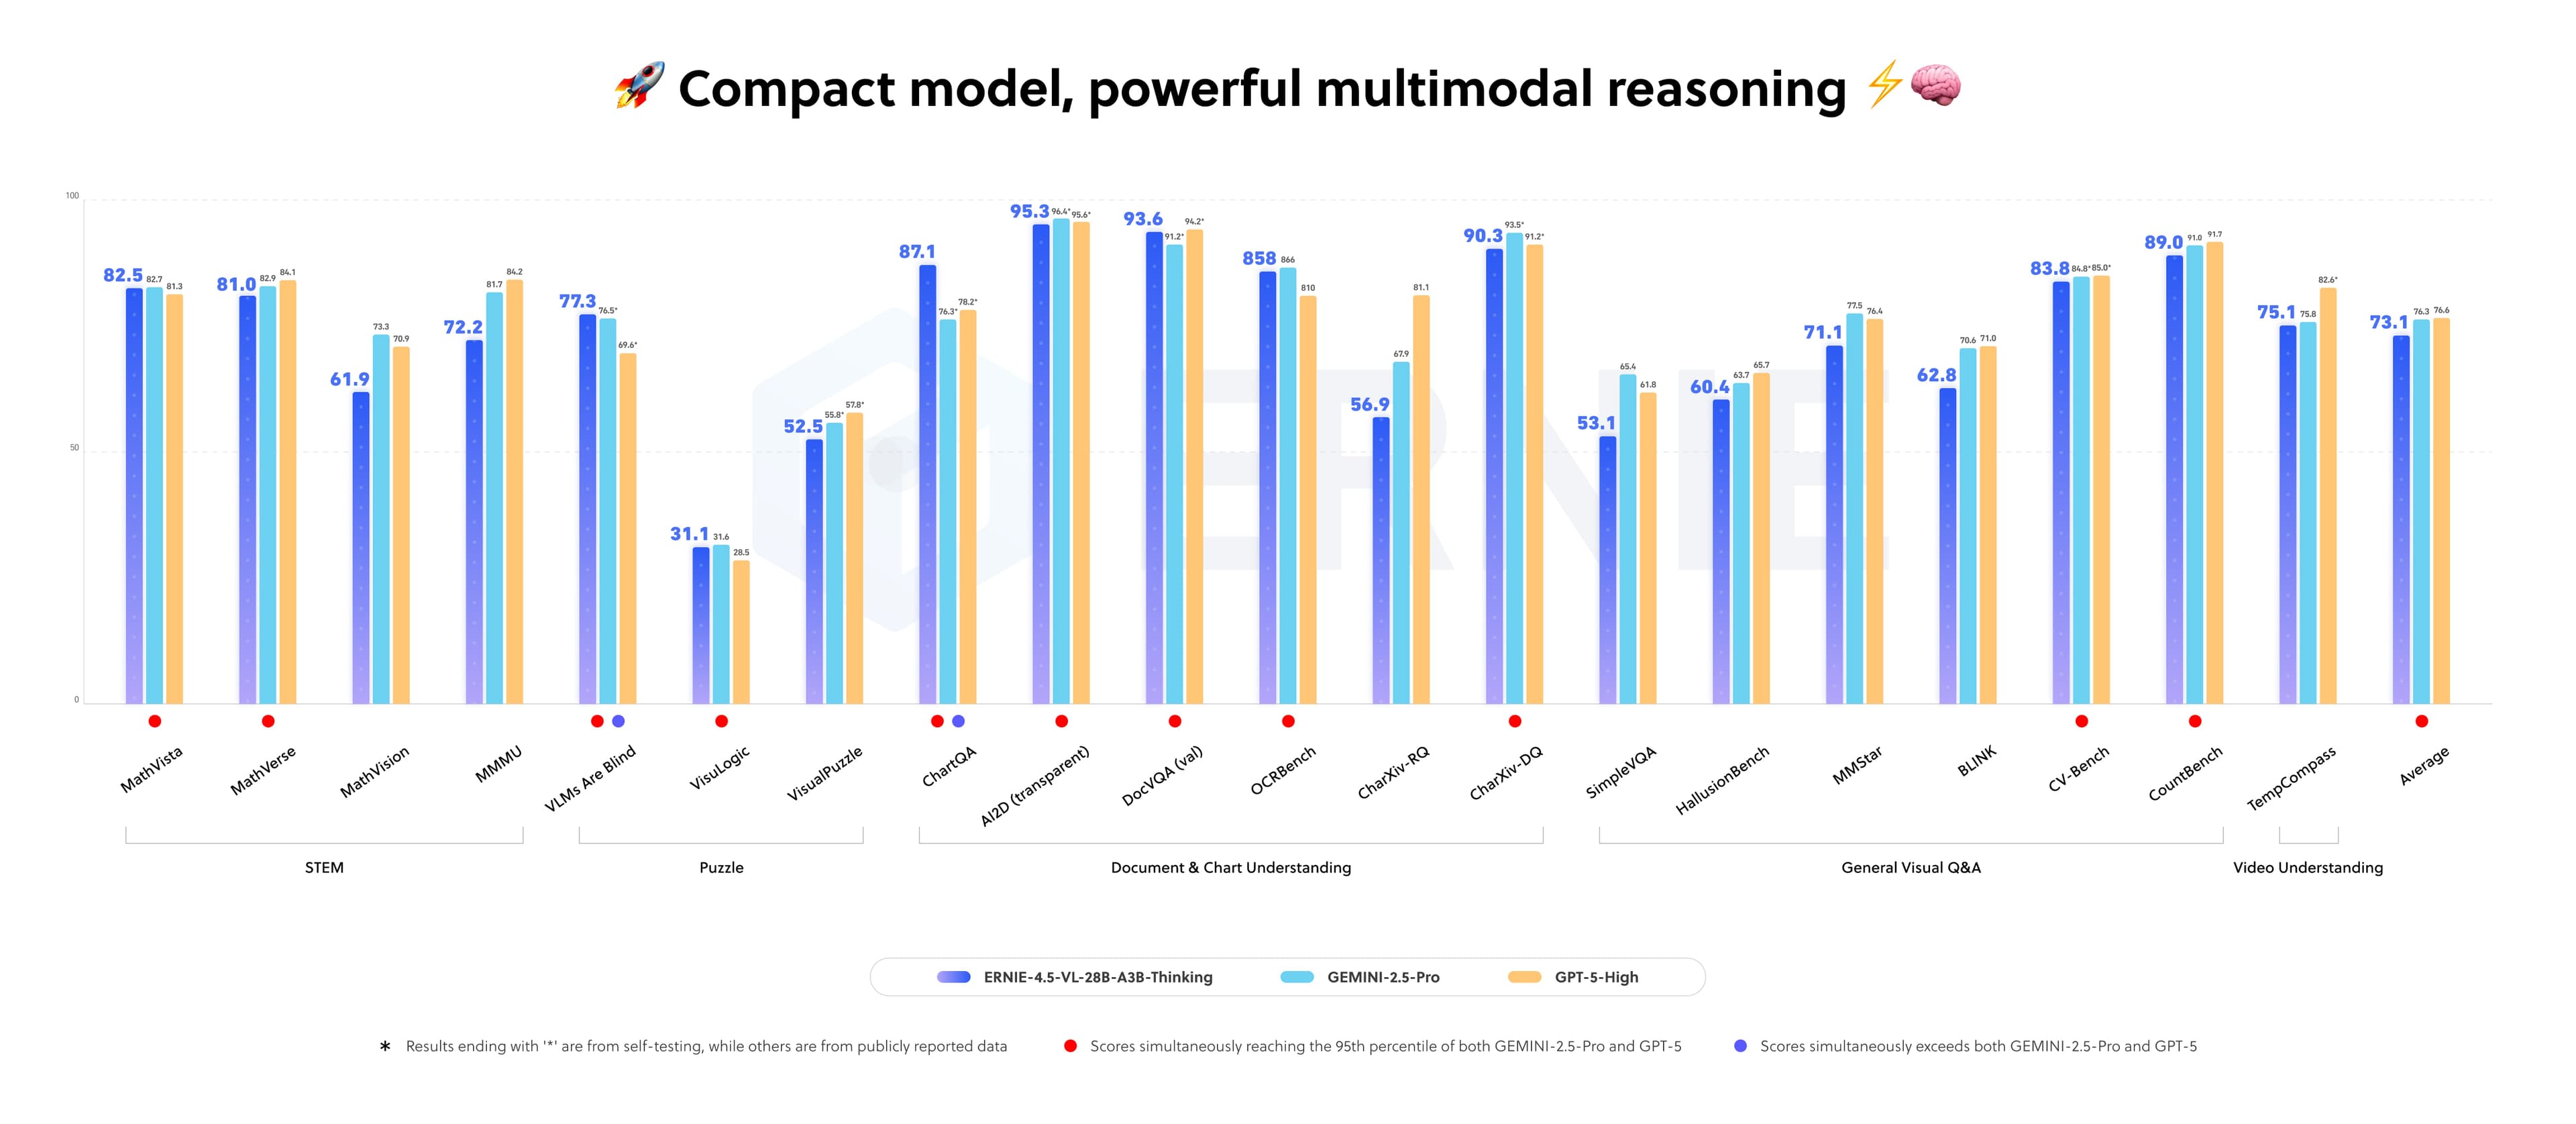
Baidu/Vision-LanguageConsumer GPU

Baidu Releases Open Vision-Language MoE Model

The new ERNIE 4.5 VL model brings advanced multimodal reasoning to the open-source community with an efficient Mixture-of-Experts architecture.

Nov 7, 2025
ReasoningVision-Language
ERNIE 4.5 VL 28B A3B Thinking
Moonshot AI/ReasoningMajor releaseDatacenter

Moonshot AI Releases Kimi-K2 Reasoning Model

The new Mixture-of-Experts model is designed for complex tasks but arrives in a custom compressed format with a restrictive license.

Nov 4, 2025
Text / LLMReasoning
Kimi K2 Thinking
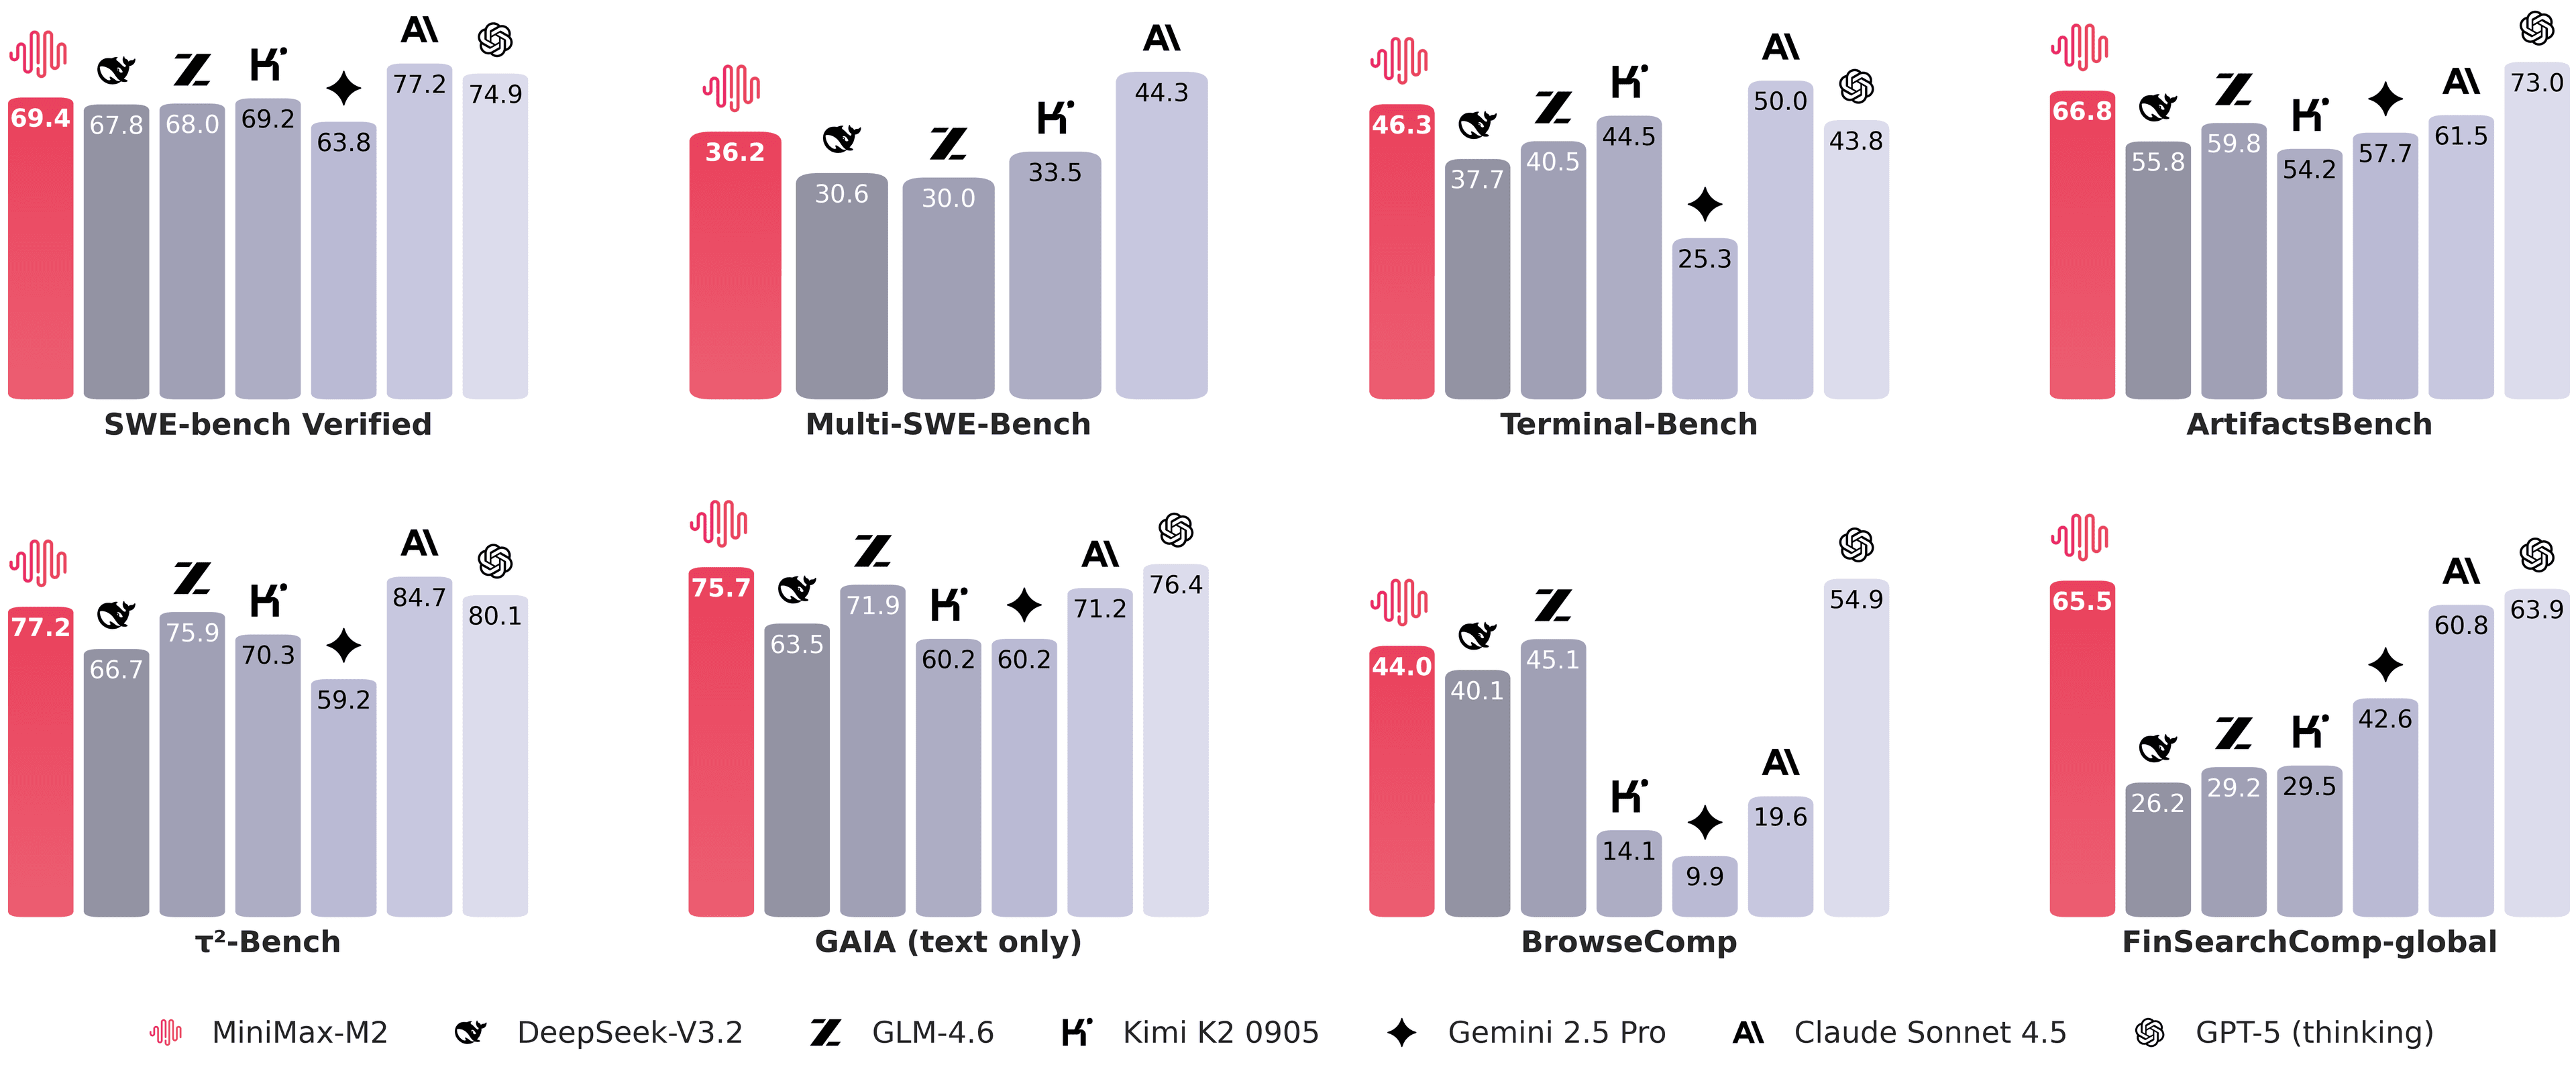
MiniMax/Text / LLMMajor releaseMulti-GPU server

MiniMax Releases M2, an Open-Weight MoE for Agents

The Shanghai-based AI startup has released a new Mixture-of-Experts model focused on complex reasoning, coding, and agentic tasks.

Oct 22, 2025
CodeText / LLM
MiniMax-M2.7
Zhipu AI/Text / LLMMajor releaseMulti-GPU server

Zhipu AI Releases Open-Weight MoE Model GLM-4.6

The new Mixture-of-Experts model is available under a permissive MIT license and is optimized for complex reasoning and coding tasks.

Sep 29, 2025
Text / LLMReasoning
GLM-4.6
Qwen · Alibaba/Any-to-AnyConsumer GPU

Qwen Releases 'Thinking' Multimodal MoE Model

The new 30-billion-parameter Mixture-of-Experts model from Alibaba's Qwen team is designed to show its reasoning process for complex multimodal tasks.

Sep 15, 2025
Any-to-AnyReasoning
Qwen3-Omni-30B-A3B-Thinking
DeepSeek/Text / LLMMajor releaseDatacenter

DeepSeek Releases 671B MoE Model Under MIT License

The new DeepSeek-V3.1-Base is a massive 671-billion-parameter Mixture-of-Experts model designed for efficient, large-scale research and development.

Aug 19, 2025
Text / LLMReasoning
DeepSeek-V3.2
Zhipu AI/Vision-LanguageMajor releaseWorkstation GPU

Zhipu AI Releases Open Vision Model GLM-4.5V

The new Mixture-of-Experts model offers strong multimodal reasoning capabilities under a permissive MIT license.

Aug 10, 2025
ReasoningVision-Language
GLM-4.5V
OpenAI/ReasoningMajor releaseRuns on a laptop

OpenAI Releases 21B Open-Weight MoE Model

The new `gpt-oss-20b` is an Apache 2.0-licensed Mixture-of-Experts model designed to run efficiently on consumer-grade hardware.

Aug 4, 2025
Text / LLMReasoning
gpt-oss-20b
OpenAI/ReasoningMajor releaseWorkstation GPU

OpenAI Releases Its First Open-Source MoE Model

The new 117-billion-parameter `gpt-oss-120b` is a Mixture-of-Experts model focused on reasoning, released under a permissive Apache 2.0 license.

Aug 4, 2025
Text / LLMReasoning
gpt-oss-20b
Zhipu AI/Text / LLMMajor releaseMulti-GPU server

Z.ai Releases 355B Parameter GLM-4.5 Under MIT License

The new Mixture-of-Experts model combines massive scale with a fully permissive license, targeting complex reasoning and agentic applications.

Jul 20, 2025
CodeText / LLM
GLM-4.6
Moonshot AI/Vision-LanguageMajor releaseDatacenter

Moonshot AI Releases Trillion-Parameter Kimi-K2 Model

The new Mixture-of-Experts model brings massive scale to the open-weights community, focusing on complex reasoning and coding tasks with a 128K context window.

Jul 11, 2025
Text / LLMReasoning
Kimi K2.6
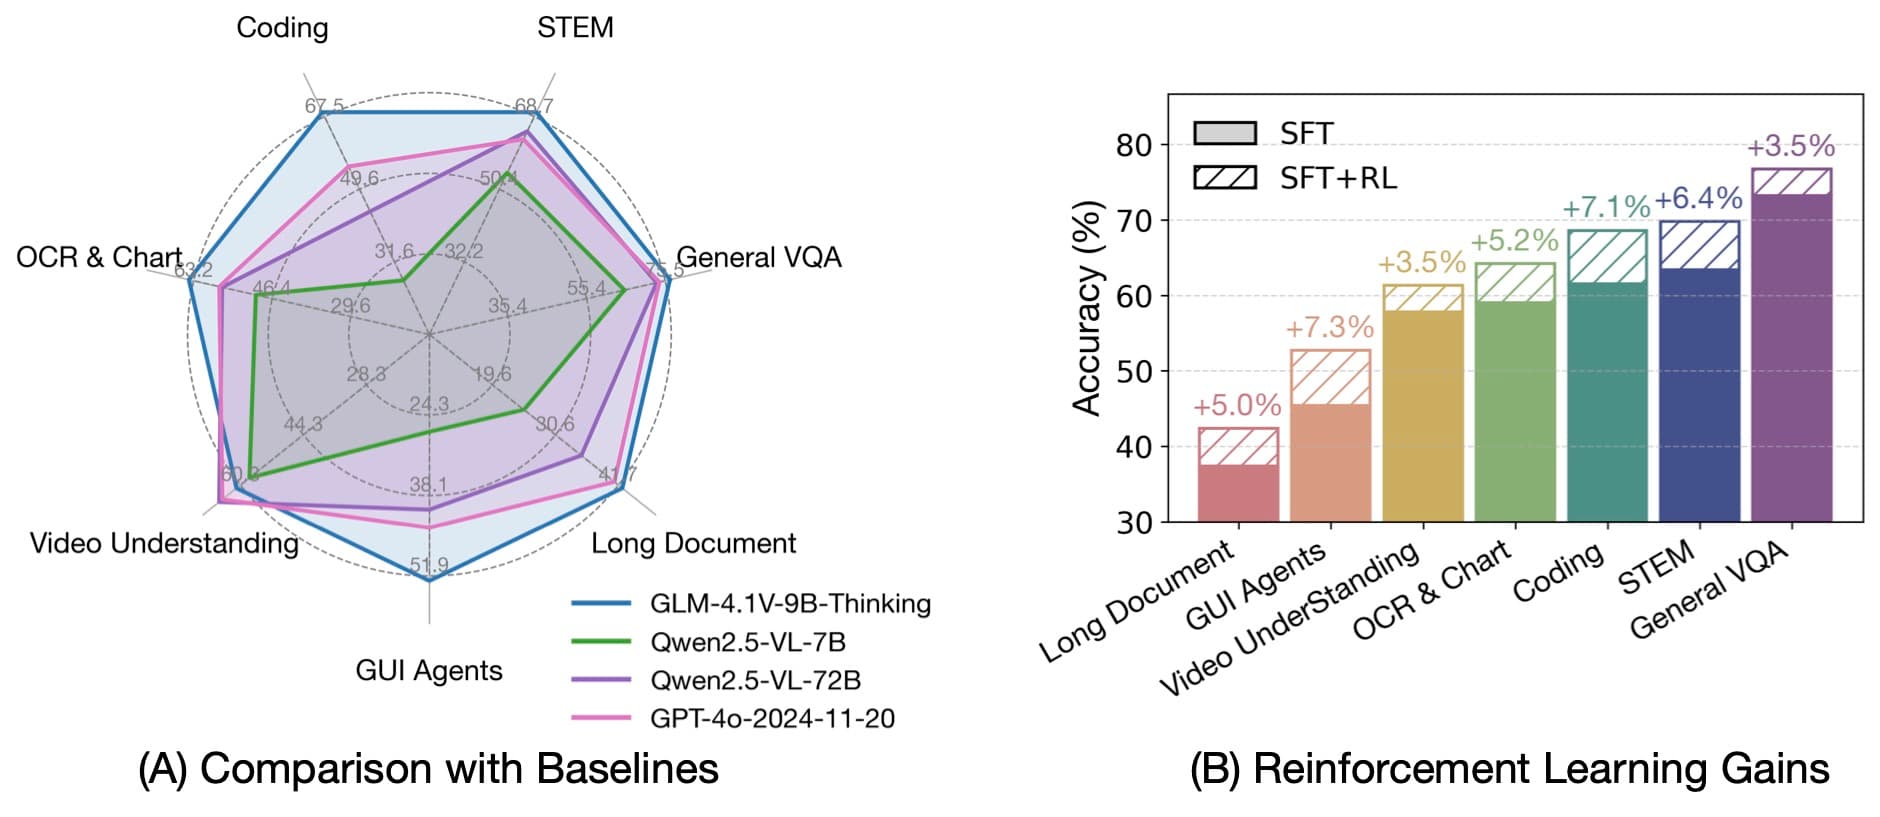
Zhipu AI/Vision-LanguageRuns on a laptop

Zhipu AI Open-Sources 9B Vision Model with 'Thinking' Mode

The new GLM-4.1V-9B-Thinking model makes its vision and chain-of-thought reasoning capabilities available under a permissive MIT license.

Jun 28, 2025
ReasoningVision-Language
GLM-4.1V-9B-Thinking