Xiaomi's MiMo V2.6-Pro-RL Targets Agentic Multimodal Work
An RL-tuned model that reads images, audio, and video while handling long context, aimed at agentic tasks.
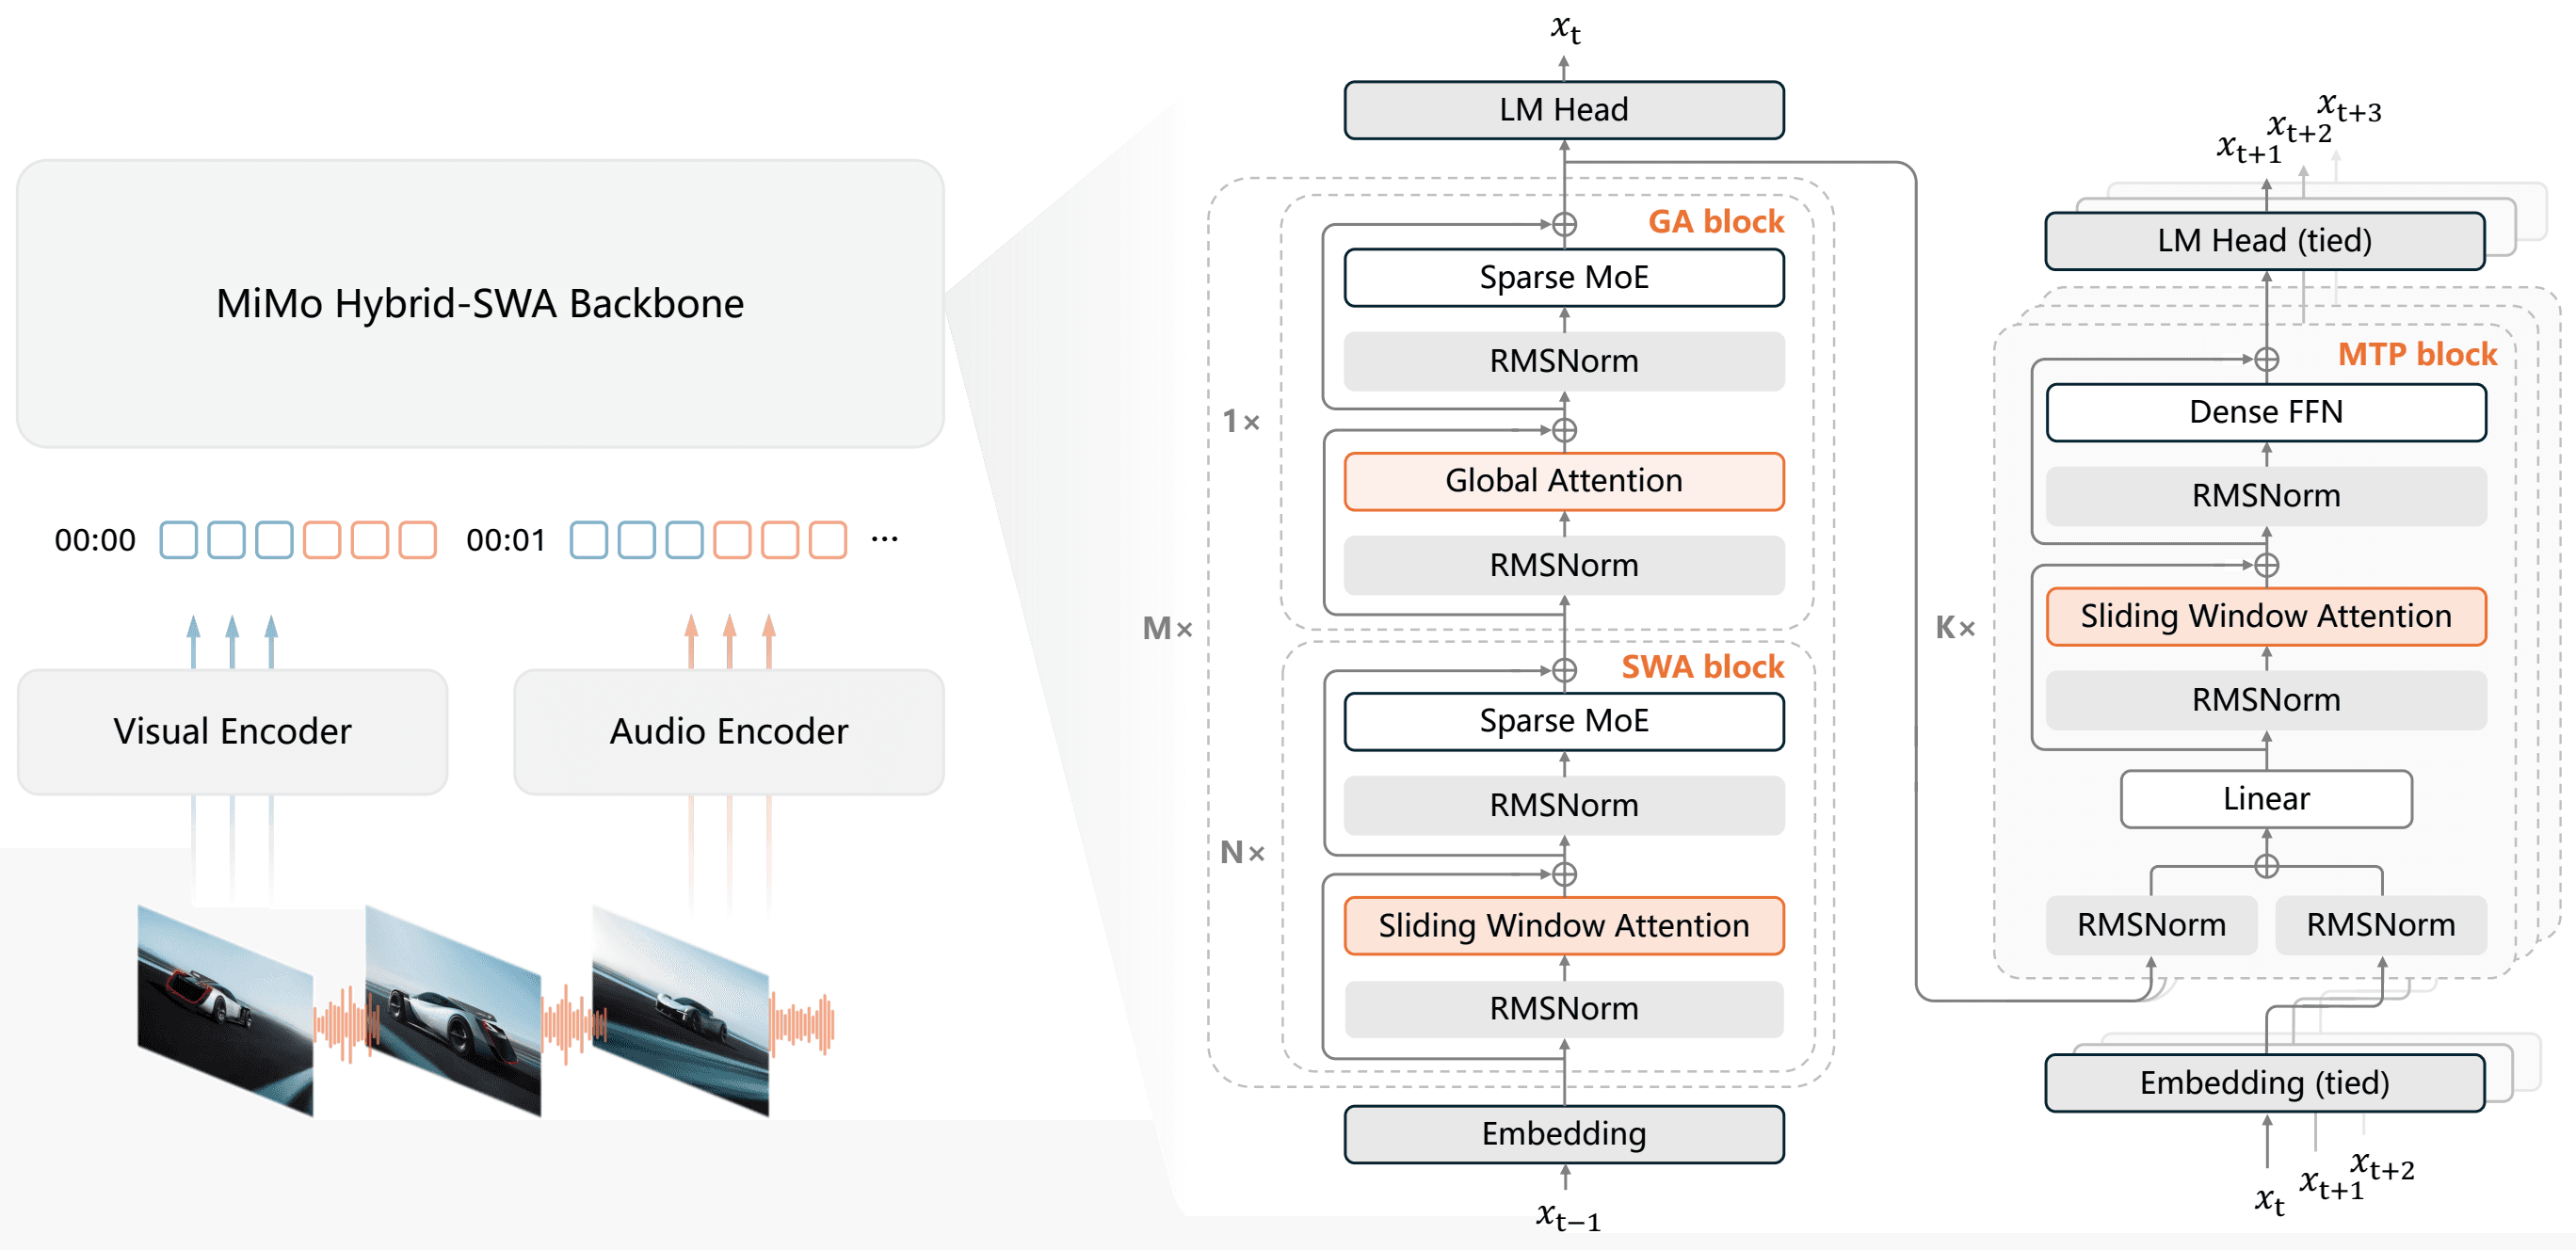
Xiaomi has released MiMo-V2.6-Pro-RL, a multimodal model tuned with reinforcement learning and positioned for agentic tasks. According to the model's Hugging Face page, it combines vision-language capabilities with audio and video understanding, plus support for long-context inputs.
The "RL" in the name points to reinforcement learning as part of the post-training recipe, an increasingly common approach for sharpening reasoning and tool-use behavior. Xiaomi frames the model as agentic, suggesting it is built to plan and act across multi-step workflows rather than simply answer one-off prompts.
Why it matters
MiMo has been Xiaomi's push into capable open-weight models, and a multimodal, RL-tuned entry signals the company wants to compete on the same terrain as other labs chasing agents that can see, hear, and reason. Bundling vision, audio, and video into a single reasoning-oriented model is a meaningful bet on unified perception.
A few things to keep in mind:
- Parameter count, context length, and detailed specs were not disclosed in the release record.
- The model ships under a non-standard "other" license, so teams should read the terms before deploying commercially.
- Independent benchmarks aren't yet available to verify the agentic and multimodal claims.
For developers, the immediate value is a fresh open-weight option for multimodal experiments; the open question is how it stacks up against established VLMs once the community puts it through real testing.
Sources
- Visit
XiaomiMiMo/MiMo-V2.6-Pro-RL
Hugging Face
More from Xiaomi
All Xiaomi releases →Xiaomi's MiMo-V2.6 bets on RL for self-improvement
The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.
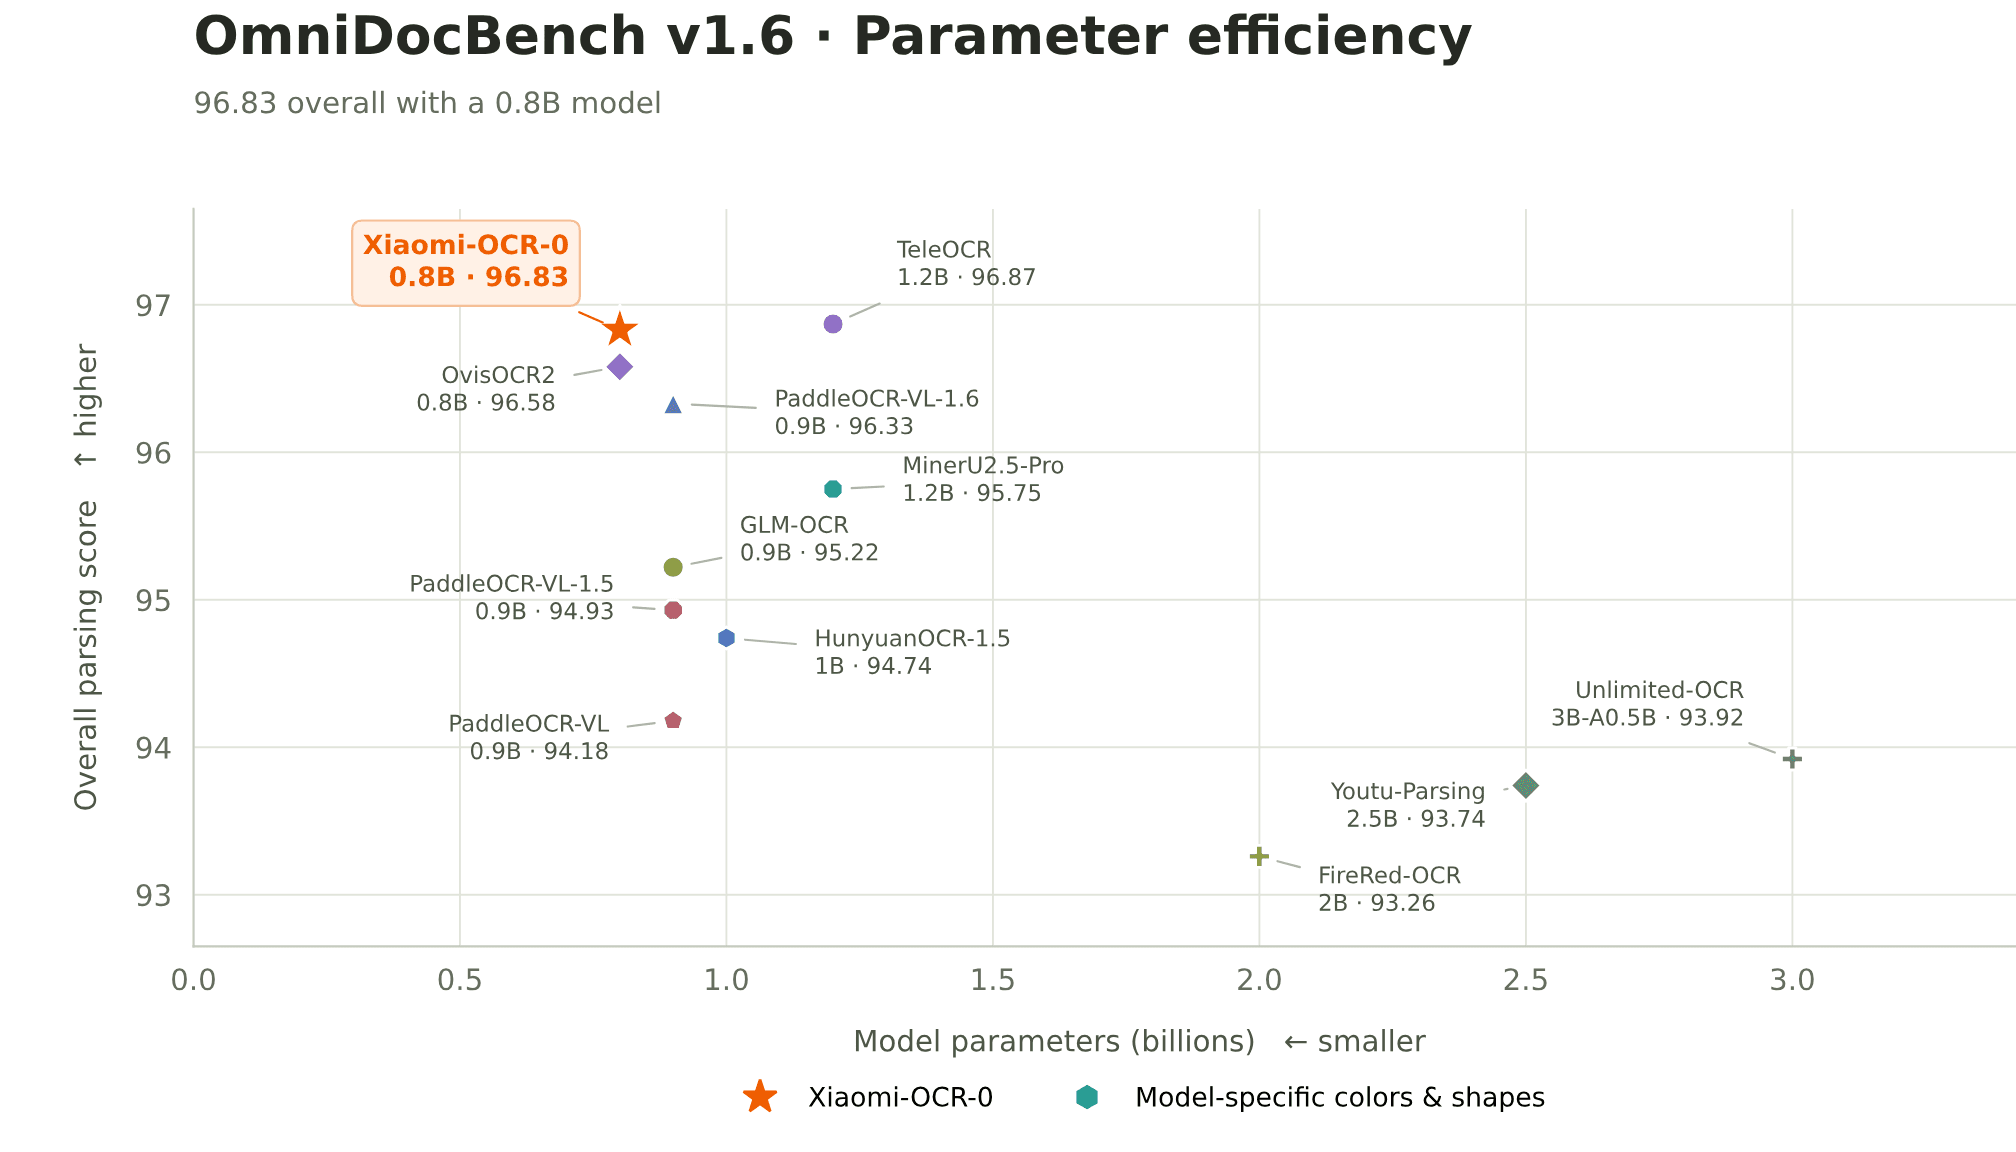
Xiaomi Enters Document OCR With New Vision Model
The company's research arm releases Xiaomi-OCR-0, a document-parsing vision-language model built on a Qwen3.5 backbone.

Xiaomi distills MiMo V2.6 into a 9B model
The new MiMo-V2.6-Distill-Qwen-9B targets agentic workloads, coding, and tool use in a size that fits on modest hardware.
More in Vision-Language
All Vision-Language →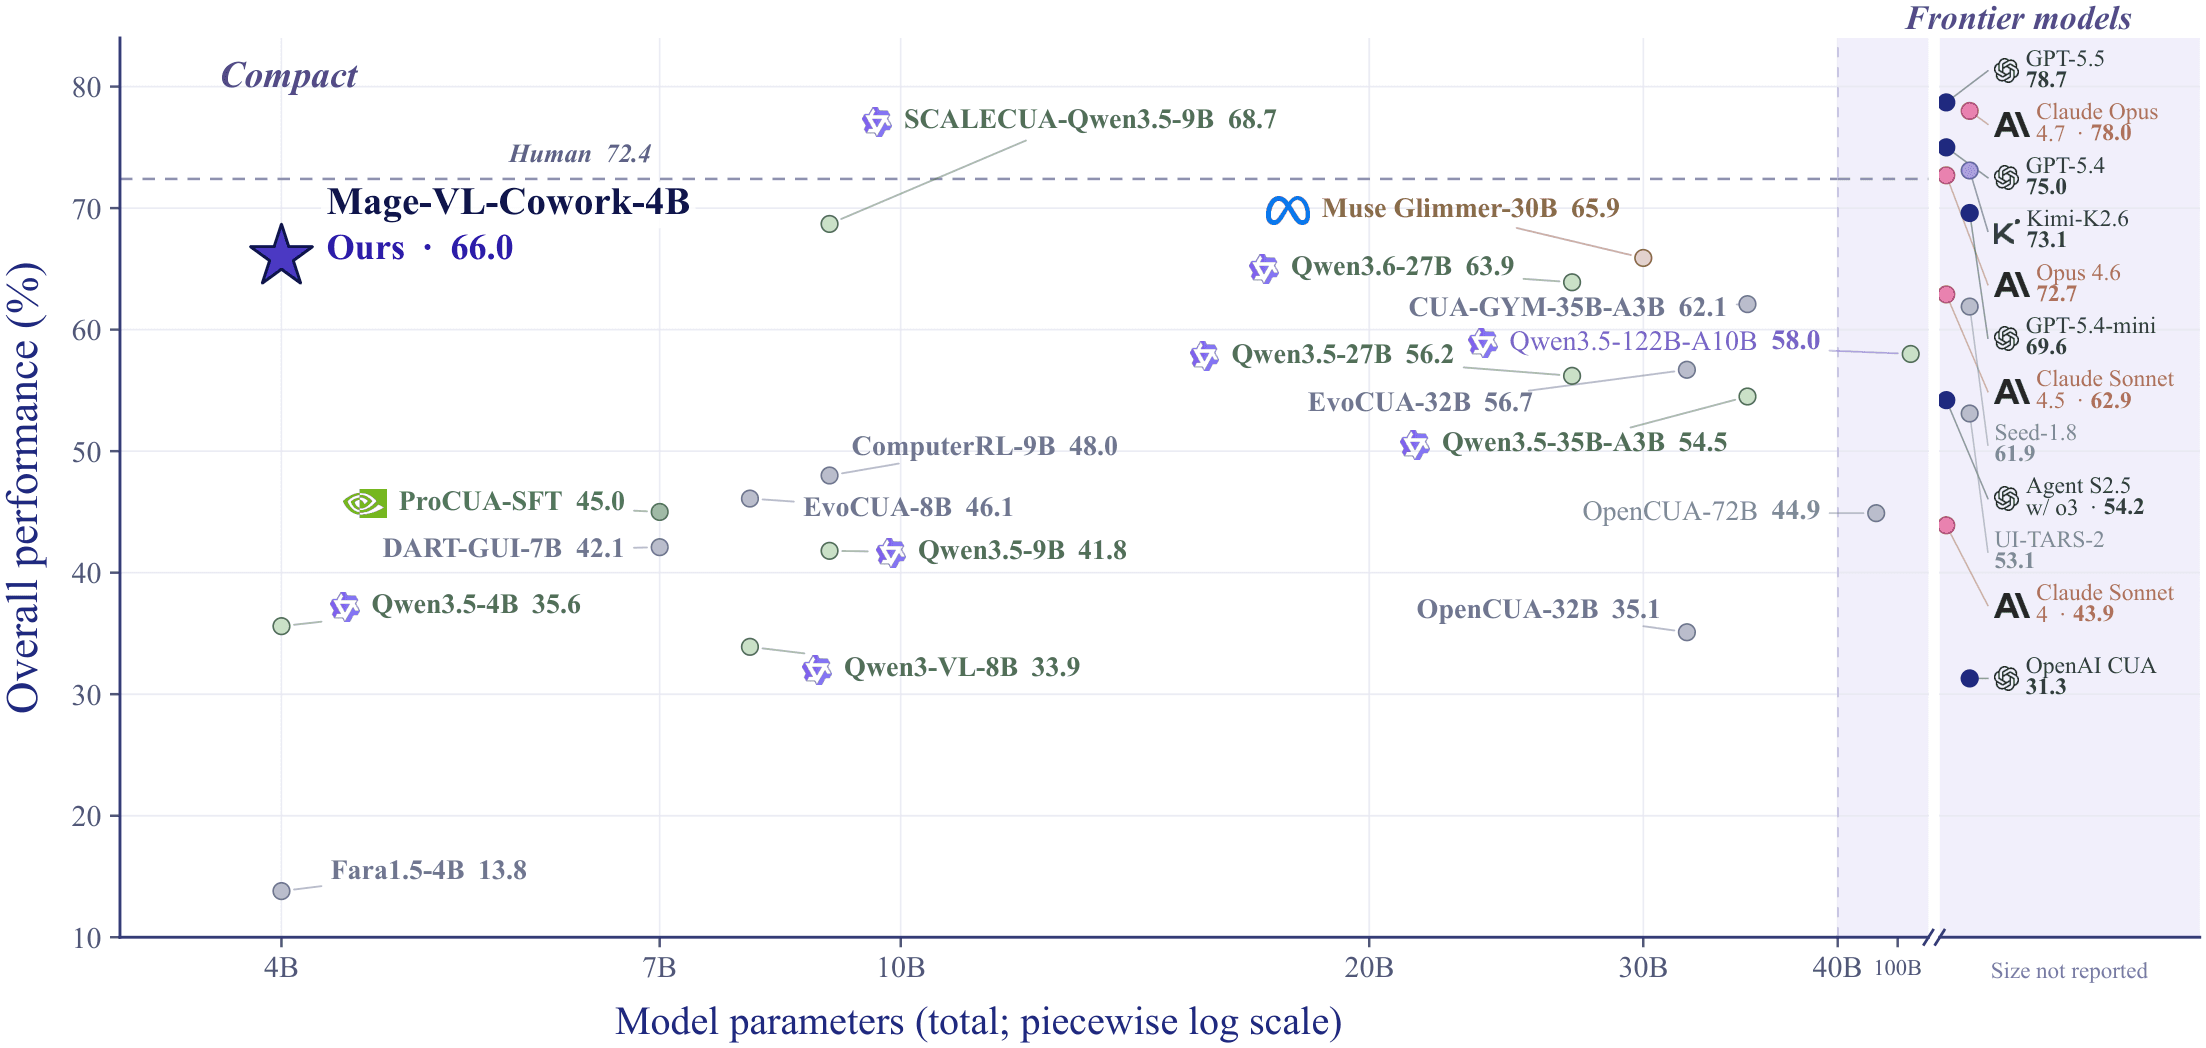
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.
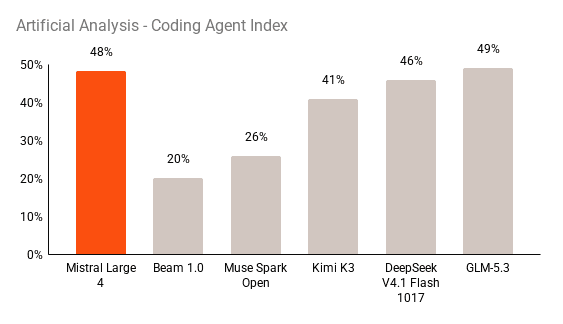
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.
SenseTime previews a 9B looped-transformer VLM
SenseNova-Loop-9B-Preview puts a recurrent-depth architecture to work on multimodal reasoning.
0 comments
No comments yet. Be the first to weigh in.