Xiaomi Enters Document OCR With New Vision Model
The company's research arm releases Xiaomi-OCR-0, a document-parsing vision-language model built on a Qwen3.5 backbone.
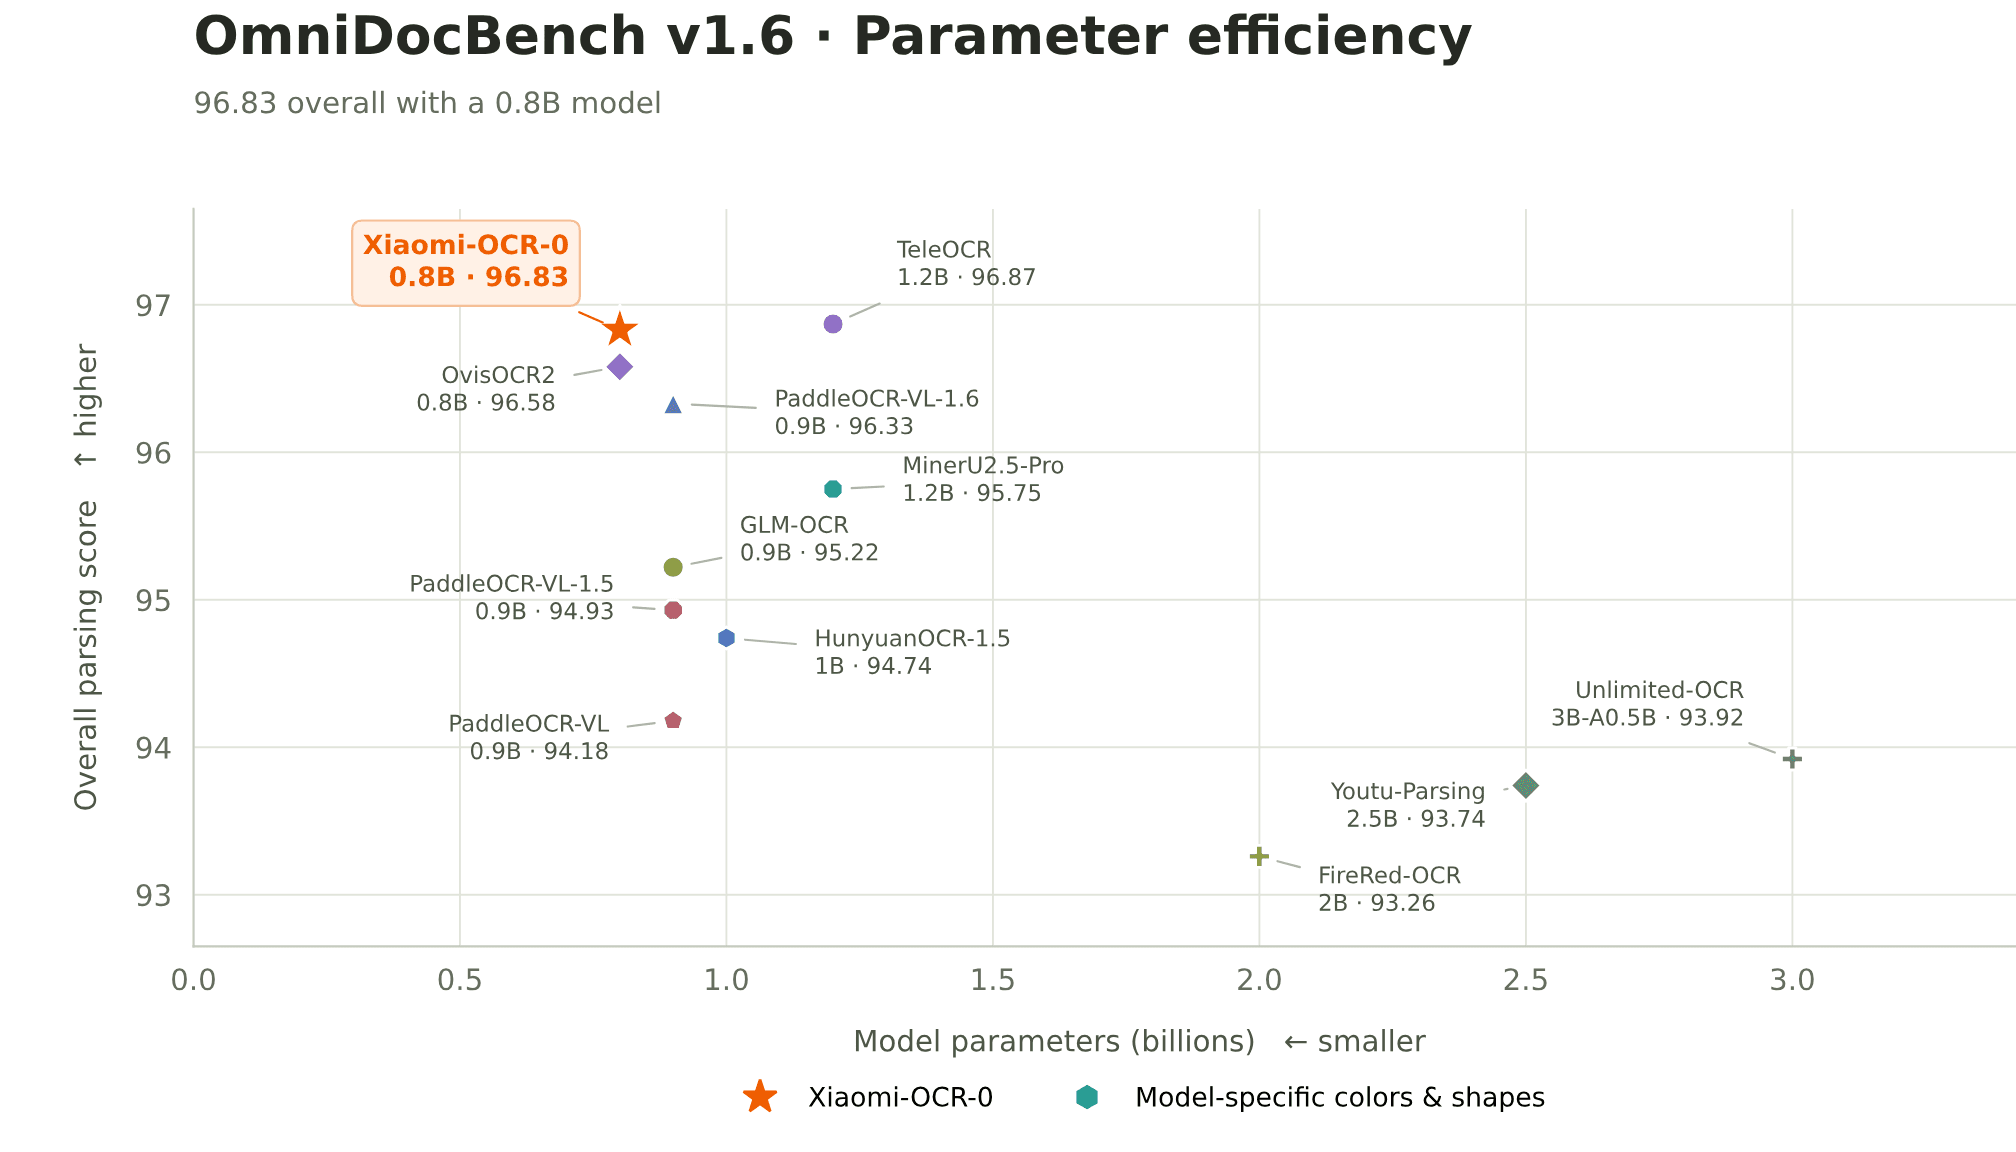
Xiaomi's research group has published Xiaomi-OCR-0, a vision-language model aimed squarely at document understanding. According to the release, the model handles optical character recognition and structured document parsing, and is built on a Qwen3.5 backbone — reflecting the growing practice of adapting strong open foundation models rather than training from scratch.
Document OCR has become one of the most practical frontiers for multimodal AI. Beyond simply reading text from images, modern systems are expected to preserve layout, extract tables, and output structured representations that downstream software can consume. That makes a dedicated parsing model more useful than a general-purpose chatbot for enterprises digitizing invoices, forms, and reports.
Why it matters
The release signals Xiaomi's continued investment in applied AI research and adds another option to a field that already includes capable open OCR models from other labs. A few points stand out:
- It targets both OCR and document parsing, not just raw text extraction.
- It leverages the Qwen3.5 family as its foundation.
- It ships under a custom license, so teams should review the terms before commercial use.
As an initial "0" release, Xiaomi-OCR-0 reads more like a starting point than a finished product line. Key details such as parameter count and context length are not specified in the listing, so practitioners will want to test it against their own document workloads before committing. The model and its documentation are available now on Hugging Face.
Sources
- Visit
xiaomi-research/Xiaomi-OCR-0
Hugging Face
More from Xiaomi
All Xiaomi releases →Xiaomi's MiMo-V2.6 bets on RL for self-improvement
The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.

Xiaomi distills MiMo V2.6 into a 9B model
The new MiMo-V2.6-Distill-Qwen-9B targets agentic workloads, coding, and tool use in a size that fits on modest hardware.
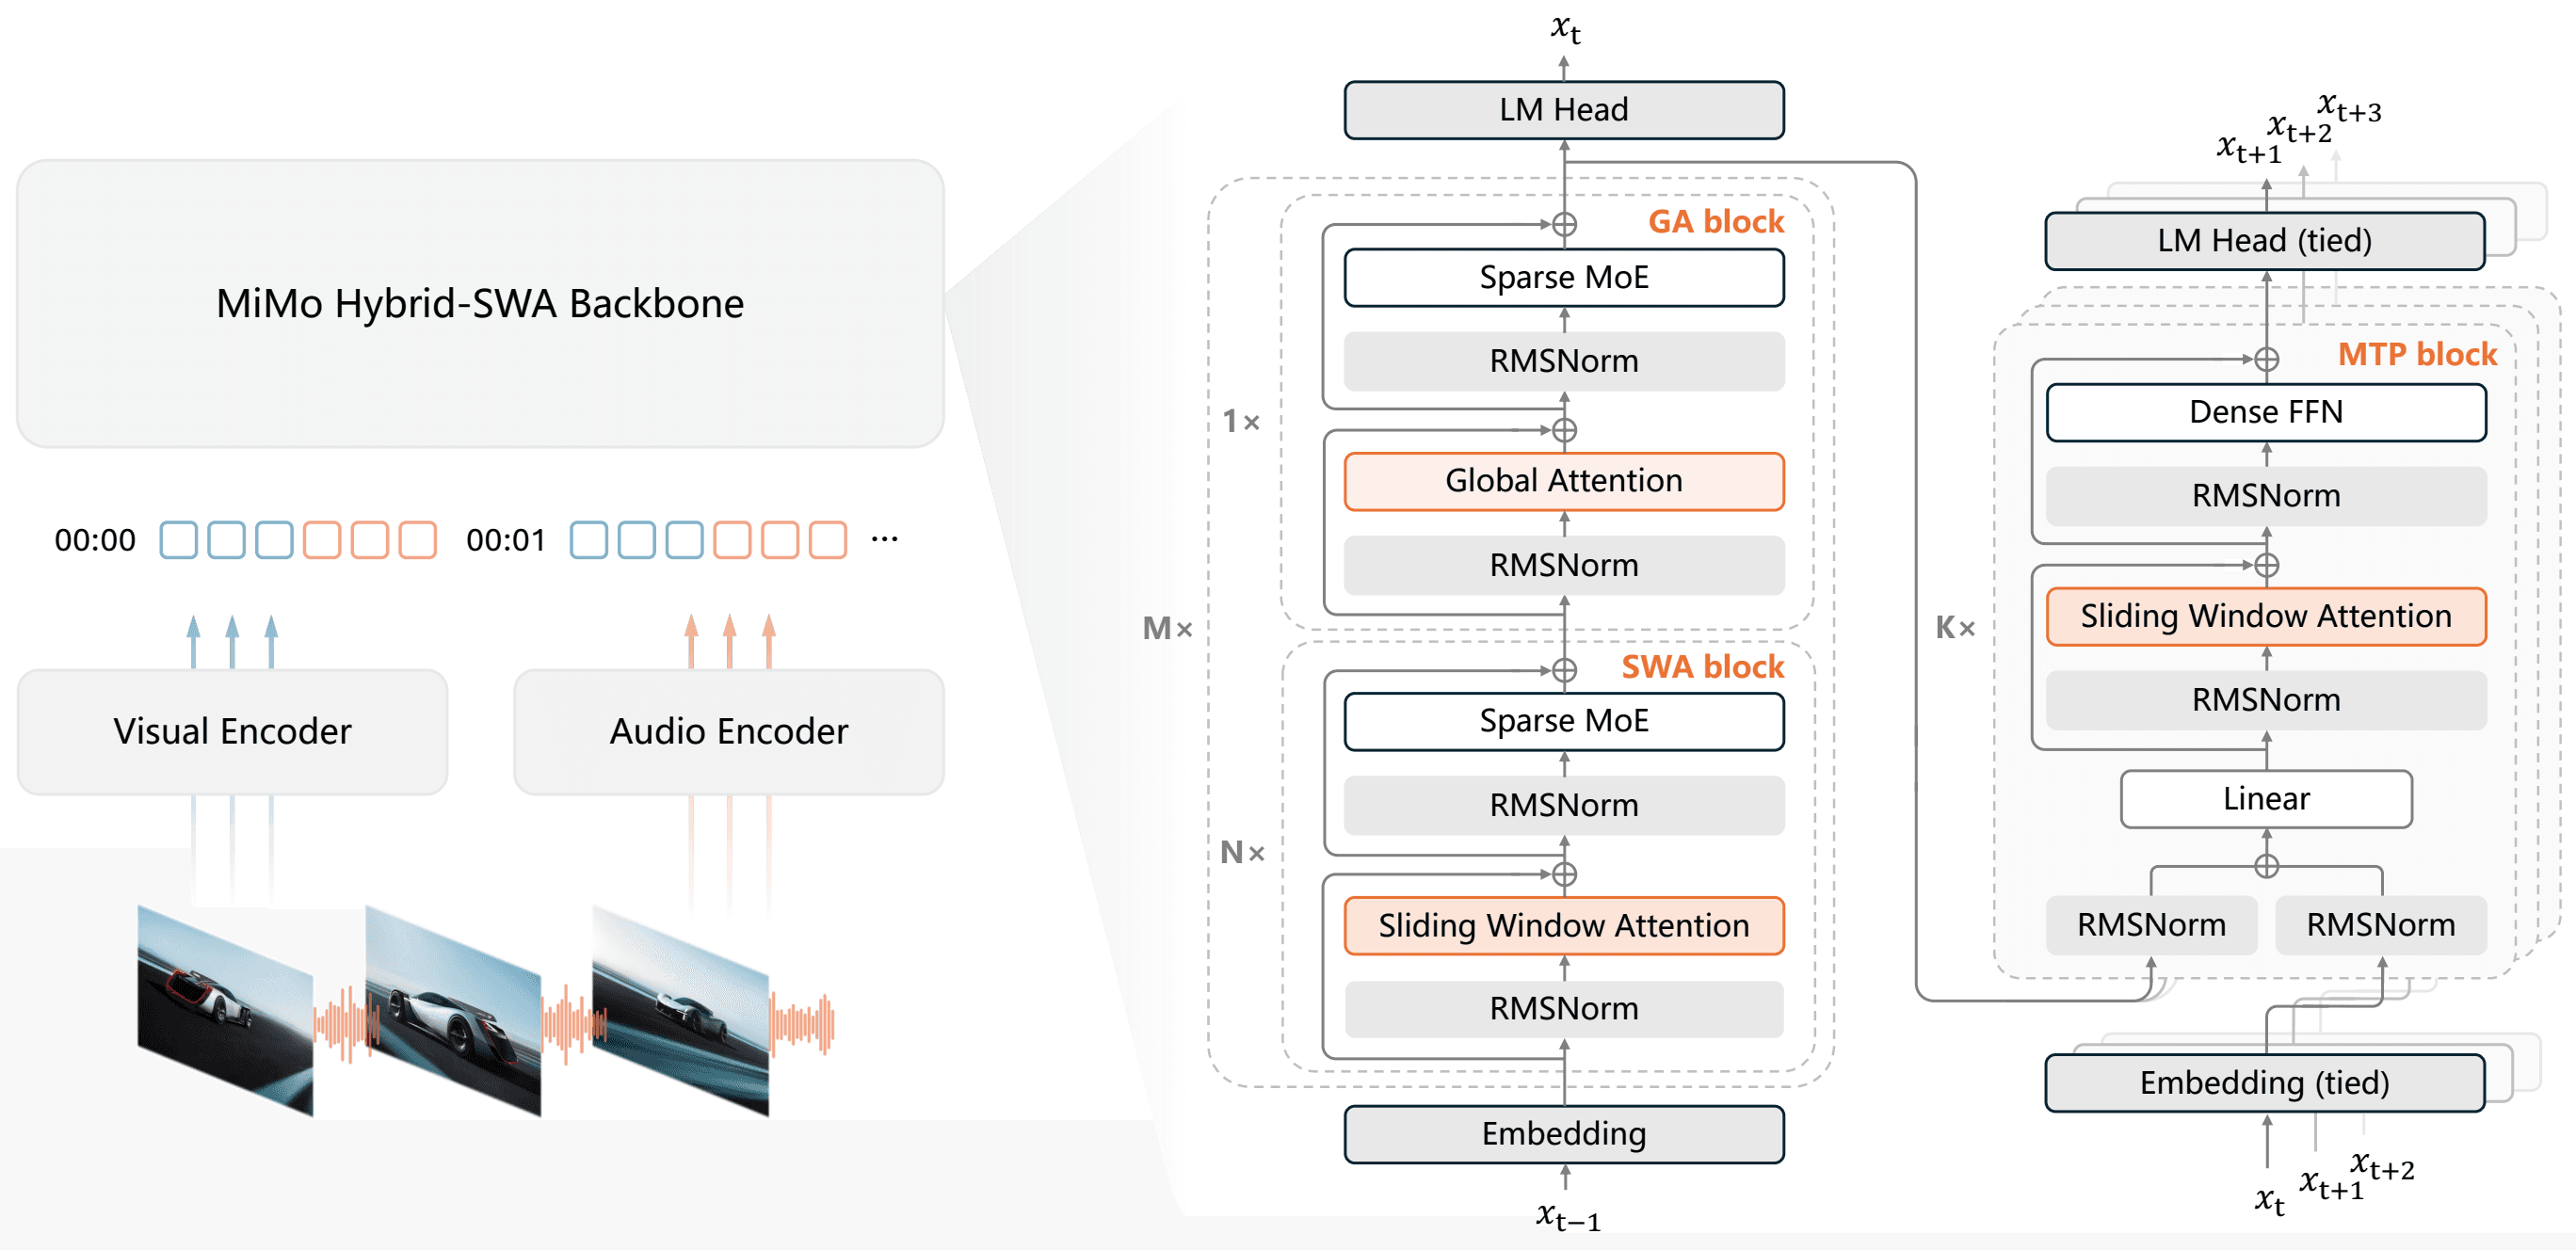
Xiaomi expands MiMo line with V2.6 multimodal models
The new Flash, Pro, and Distill variants add vision, audio, agentic behavior, and long-context handling to Xiaomi's open MiMo family.
More in Vision-Language
All Vision-Language →
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
0 comments
No comments yet. Be the first to weigh in.