Xiaomi's MiMo-V2.6 bets on RL for self-improvement
The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.
Xiaomi has introduced MiMo-V2.6, an omni-modal model family that the company frames as a step toward models that improve themselves through reinforcement learning rather than relying solely on ever-larger supervised datasets. The release is detailed in a paper titled MiMo-V2.6: Scaling Reinforcement Learning Towards Self-Improvement, published on Hugging Face.
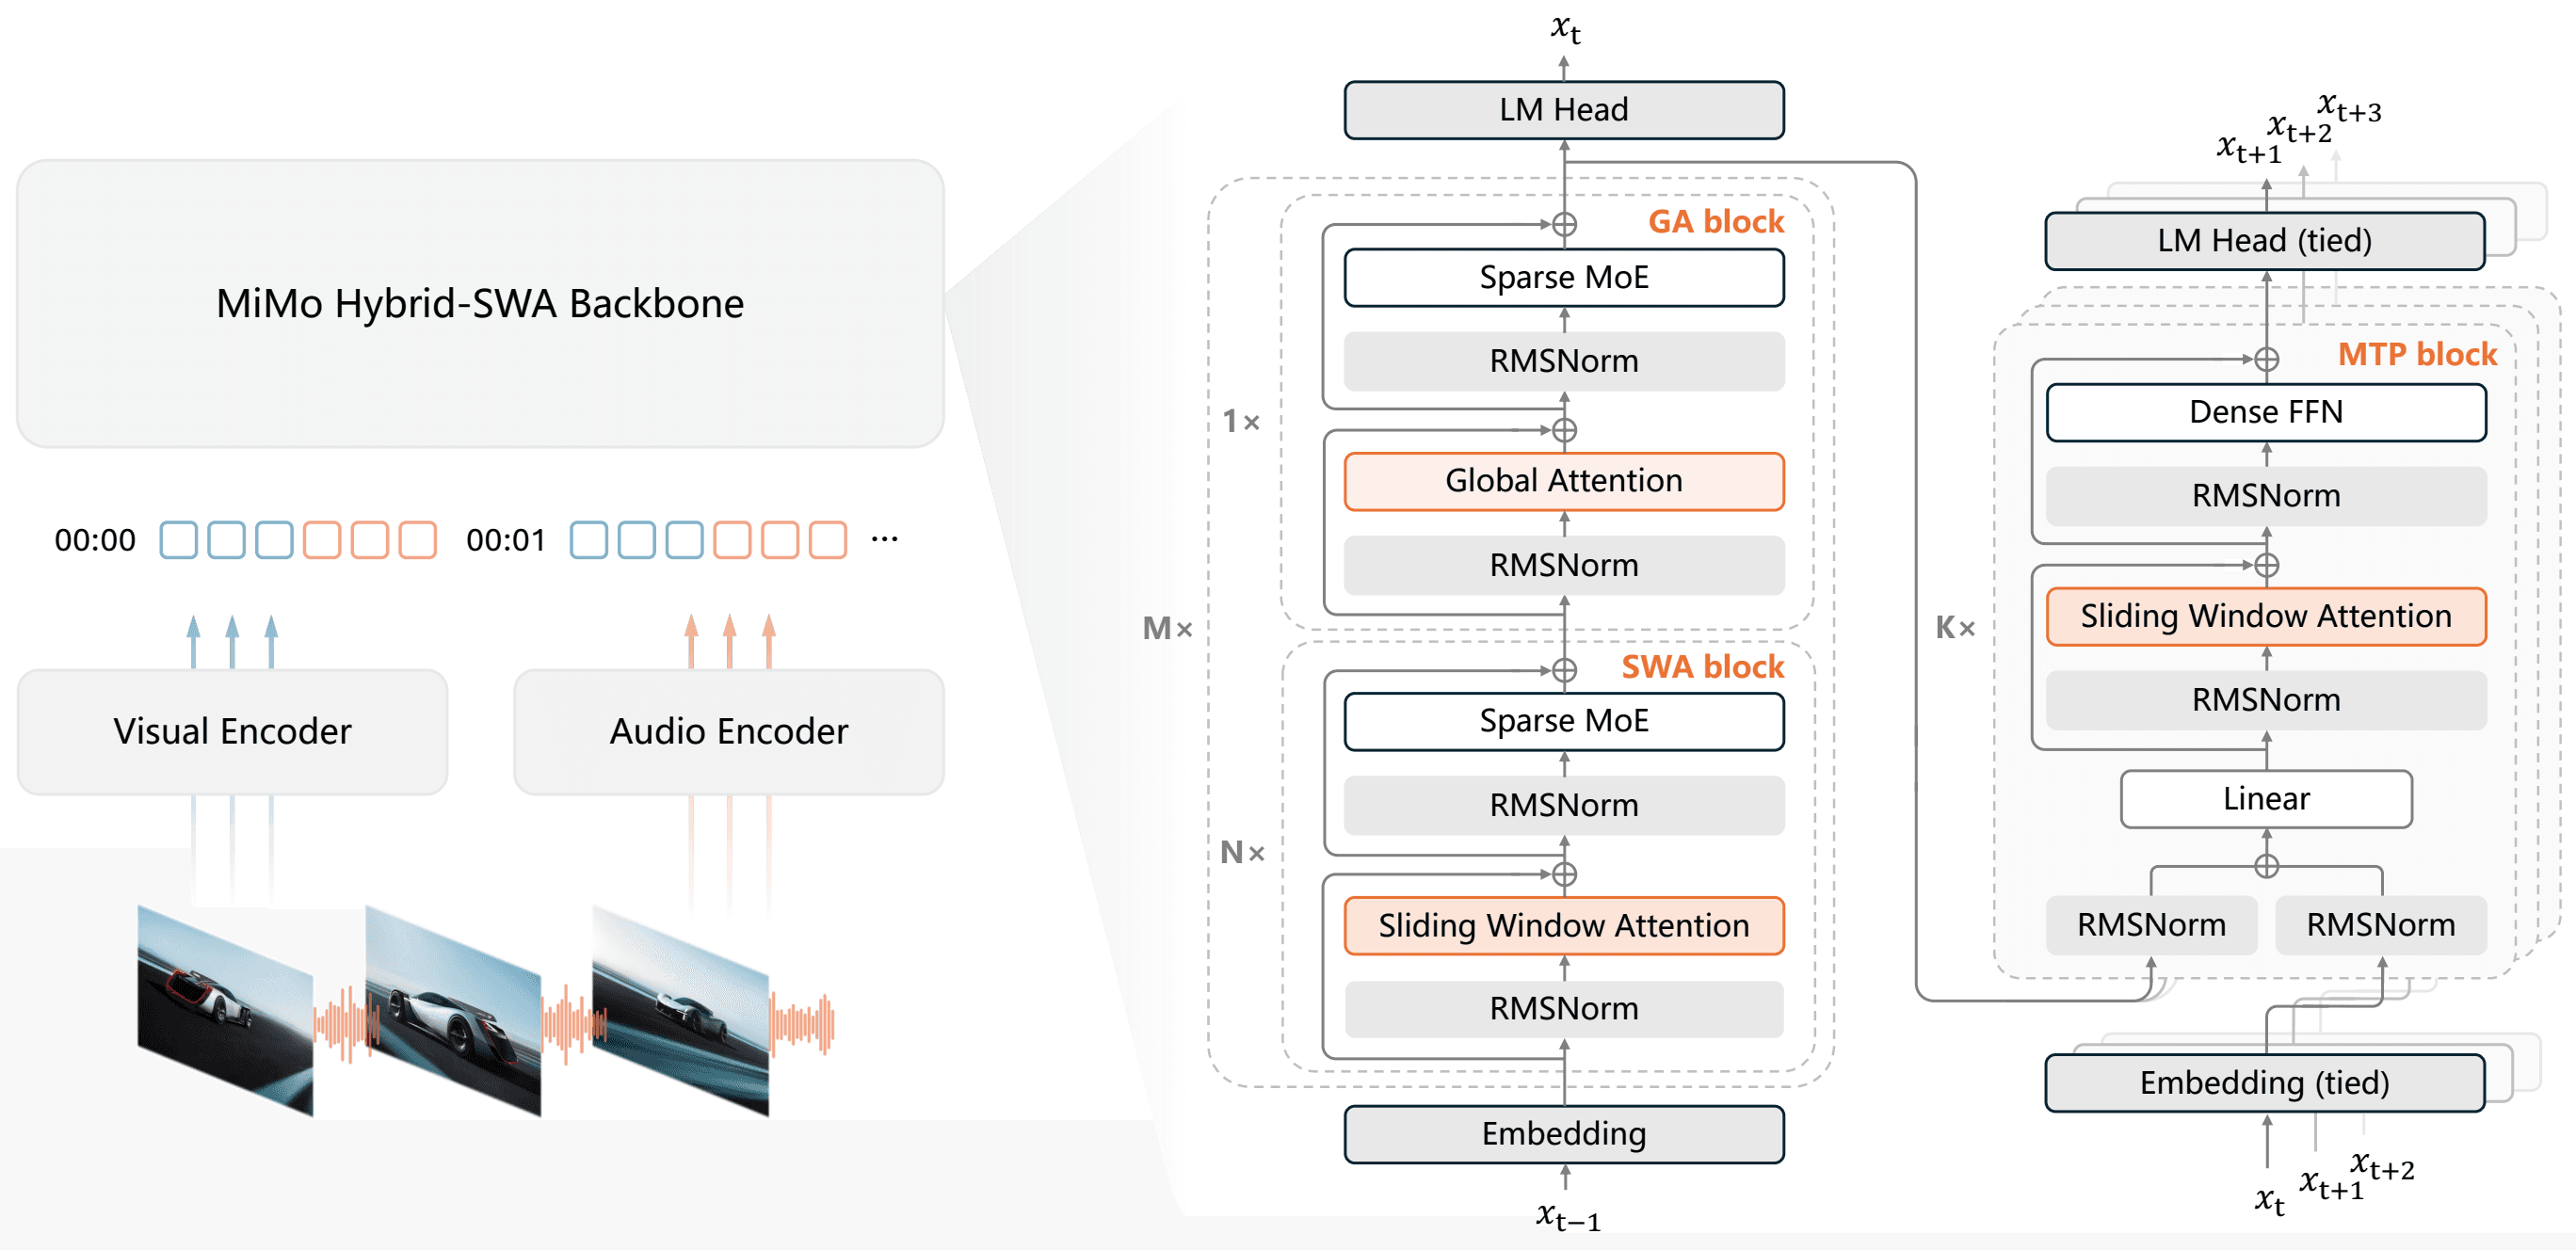
The model is pitched as handling multiple modalities and as a reasoning engine, placing it in the increasingly crowded category of systems meant to work across text, images, and other inputs while thinking through multi-step problems. The central idea is scale applied to reinforcement learning, a training approach where the model learns from feedback on its own outputs.
Why it matters
Reinforcement learning has become the dominant lever for improving reasoning in frontier models, but much of that work happens behind closed doors at the largest labs. A detailed account from Xiaomi adds to the public literature on how to make RL-driven self-improvement practical at scale.
- Omni-modal design aimed at handling varied inputs
- Reasoning as the primary focus
- Reinforcement learning positioned as the engine for self-improvement
The paper's license is listed as "other," and key specifics such as parameter count and context length were not disclosed in the record, so prospective users will want to consult the source directly before building on it. Still, the arrival of another serious reasoning effort from a major consumer-electronics company underscores how widely the RL-for-reasoning playbook is now spreading.
Sources
- Visit
MiMo-V2.6: Scaling Reinforcement Learning Towards Self-Improvement
HF Papers
More from Xiaomi
All Xiaomi releases →
Xiaomi distills MiMo V2.6 into a 9B model
The new MiMo-V2.6-Distill-Qwen-9B targets agentic workloads, coding, and tool use in a size that fits on modest hardware.
Xiaomi expands MiMo line with V2.6 multimodal models
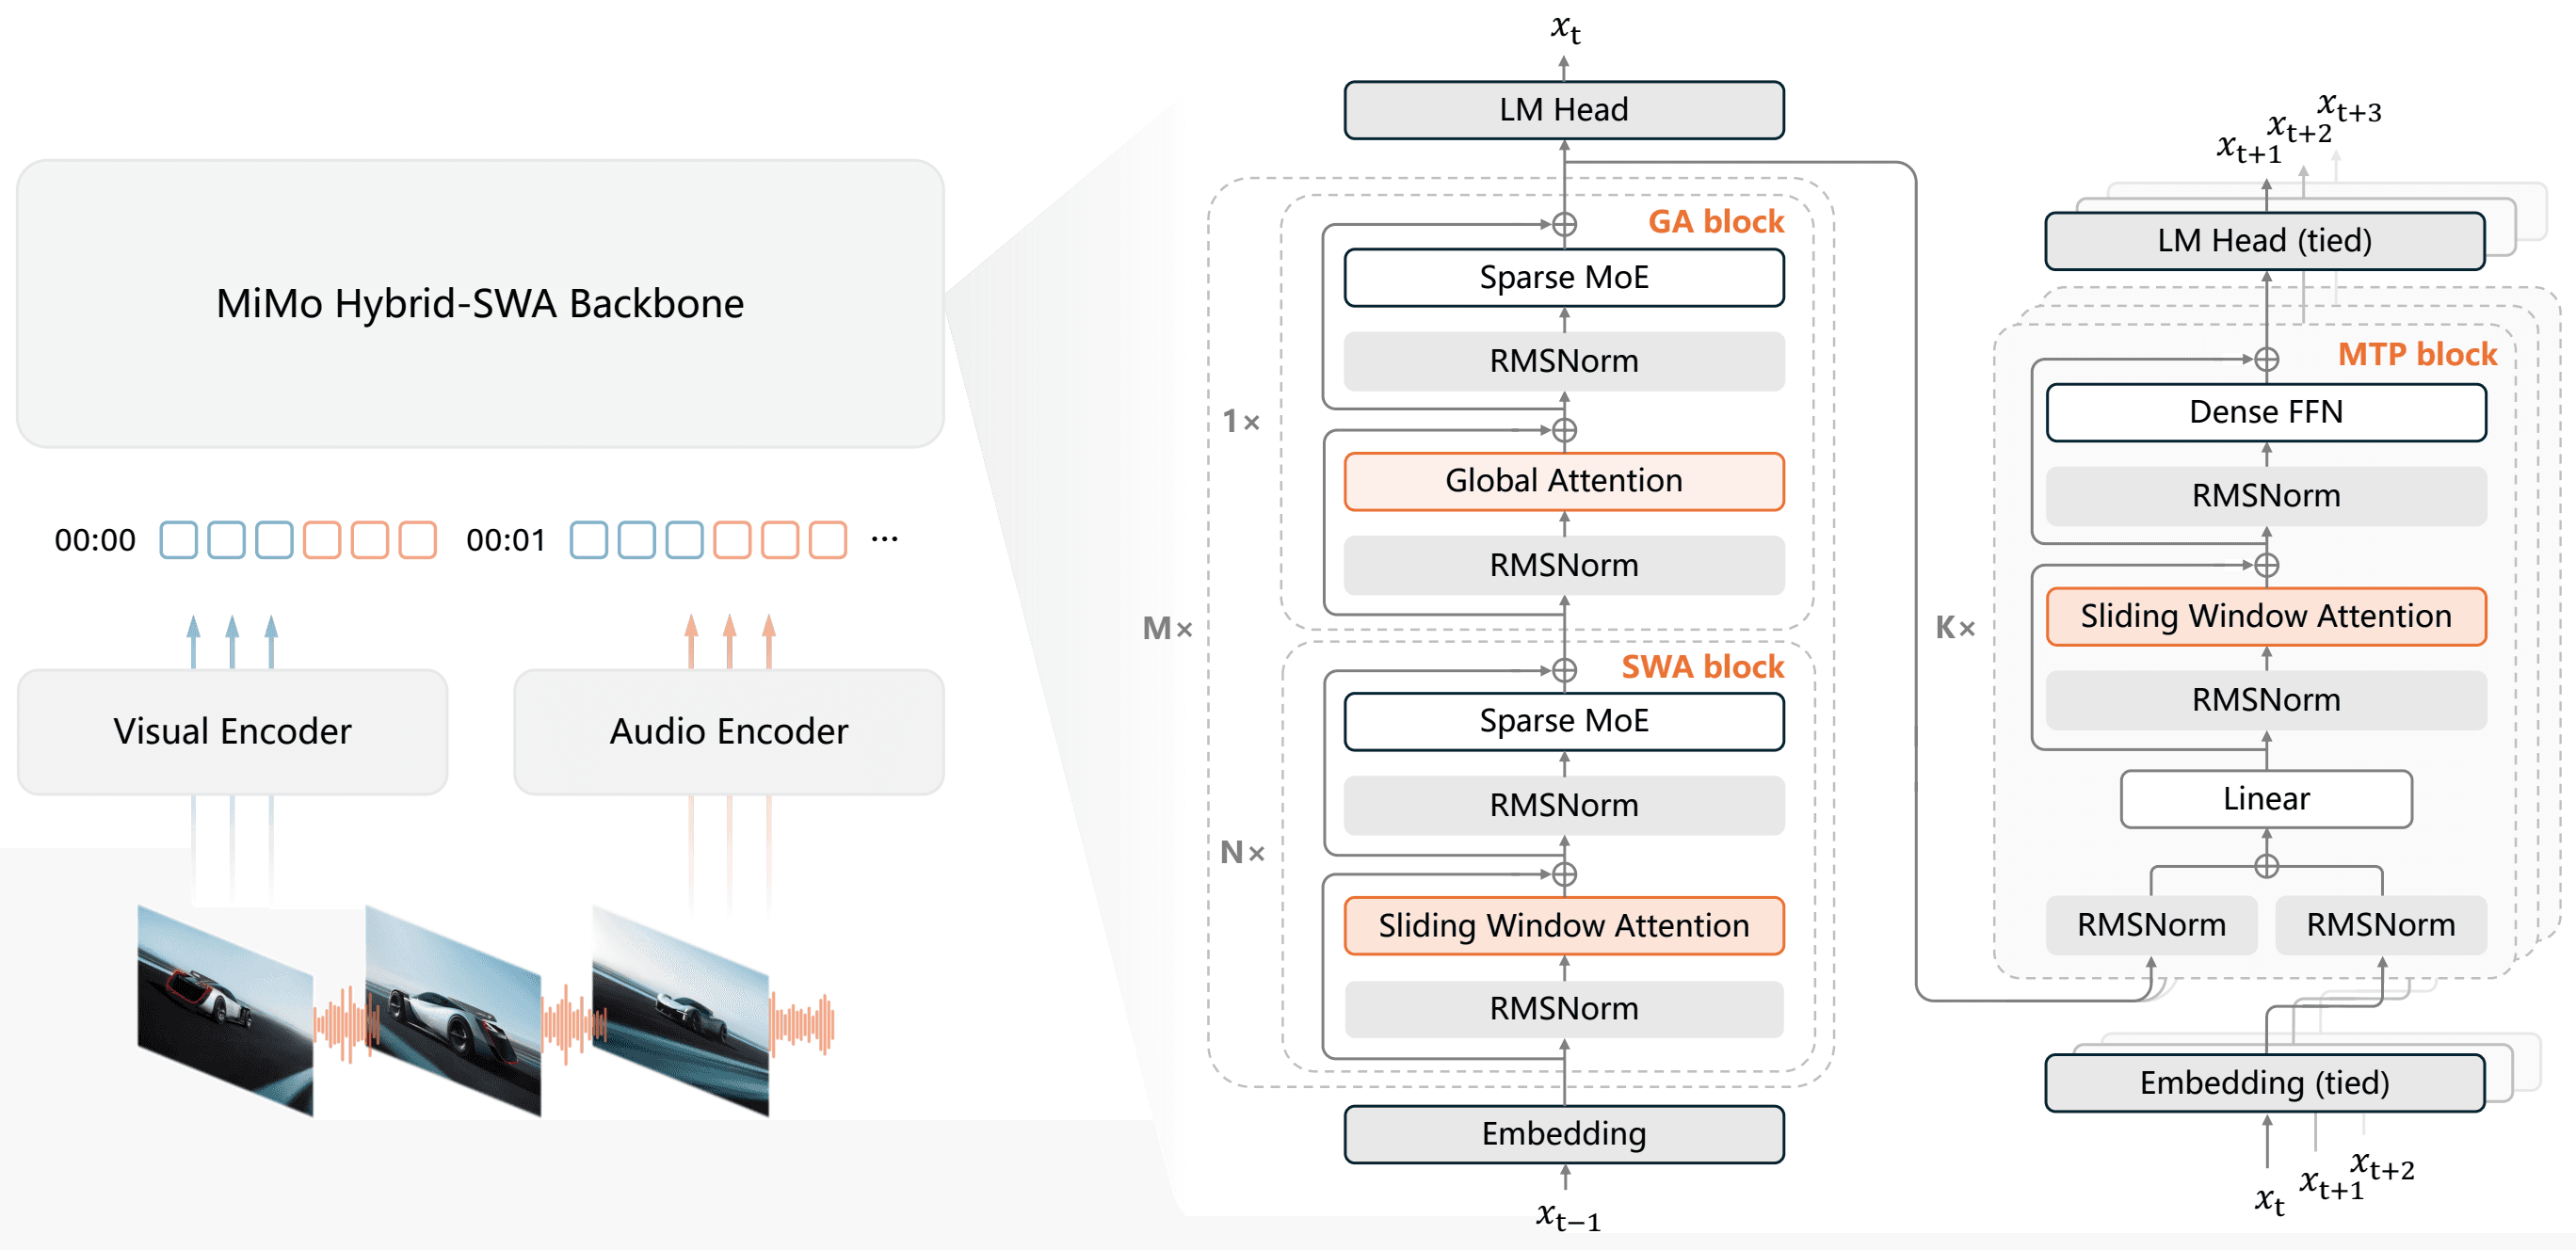
The new Flash, Pro, and Distill variants add vision, audio, agentic behavior, and long-context handling to Xiaomi's open MiMo family.
Xiaomi's MiMo V2.6-Pro-RL Targets Agentic Multimodal Work
An RL-tuned model that reads images, audio, and video while handling long context, aimed at agentic tasks.
More in Vision-Language
All Vision-Language →
Liquid AI's d1-3B brings multimodal models to the edge
The new LFM2-based d1-3B is a compact vision-language model aimed at running decisions directly on-device.

Perplexity releases a 27B model for multimodal routing
The open-weight 'decider' model is designed to classify queries and route them inside Perplexity's stack.
Cloudflare's Clef brings structured decisions to open models
The new open-weight vision-language family outputs typed, structured results and arrives alongside a reinforcement-learning fine-tuning platform.
0 comments
No comments yet. Be the first to weigh in.