SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

SenseTime has published SenseNova-Loop-9B on Hugging Face, a 9-billion-parameter multimodal model that handles both image-and-text understanding and plain text generation. The release marks the debut of the company's Loop line, which leans on a looped-transformer design paired with what SenseTime calls an MHC architecture.
The looped-transformer approach is the notable idea here. Rather than stacking an ever-deeper tower of unique layers, looped designs reuse a smaller block of weights across repeated passes, effectively trading parameter count for recurrent depth at inference. That can let a comparatively modest model reason over more steps without ballooning its footprint.
Why it matters
- At 9B parameters, the model sits in a size range that runs on a single workstation GPU, keeping it accessible to developers and researchers.
- It is a vision-language model first, so it targets tasks that combine images and text rather than text alone.
- The architecture is a departure from the standard dense-transformer recipe most open releases follow, giving the community a concrete artifact to test looped designs against.
The model ships under a custom license, so teams planning commercial use should read the terms on the repository before building on it. SenseTime has not published a context-length figure alongside the initial release, and independent benchmarks will be the real measure of whether the looped design pays off in practice.
Sources
- Visit
sensenova/SenseNova-Loop-9B
Hugging Face
More from SenseTime
All SenseTime releases →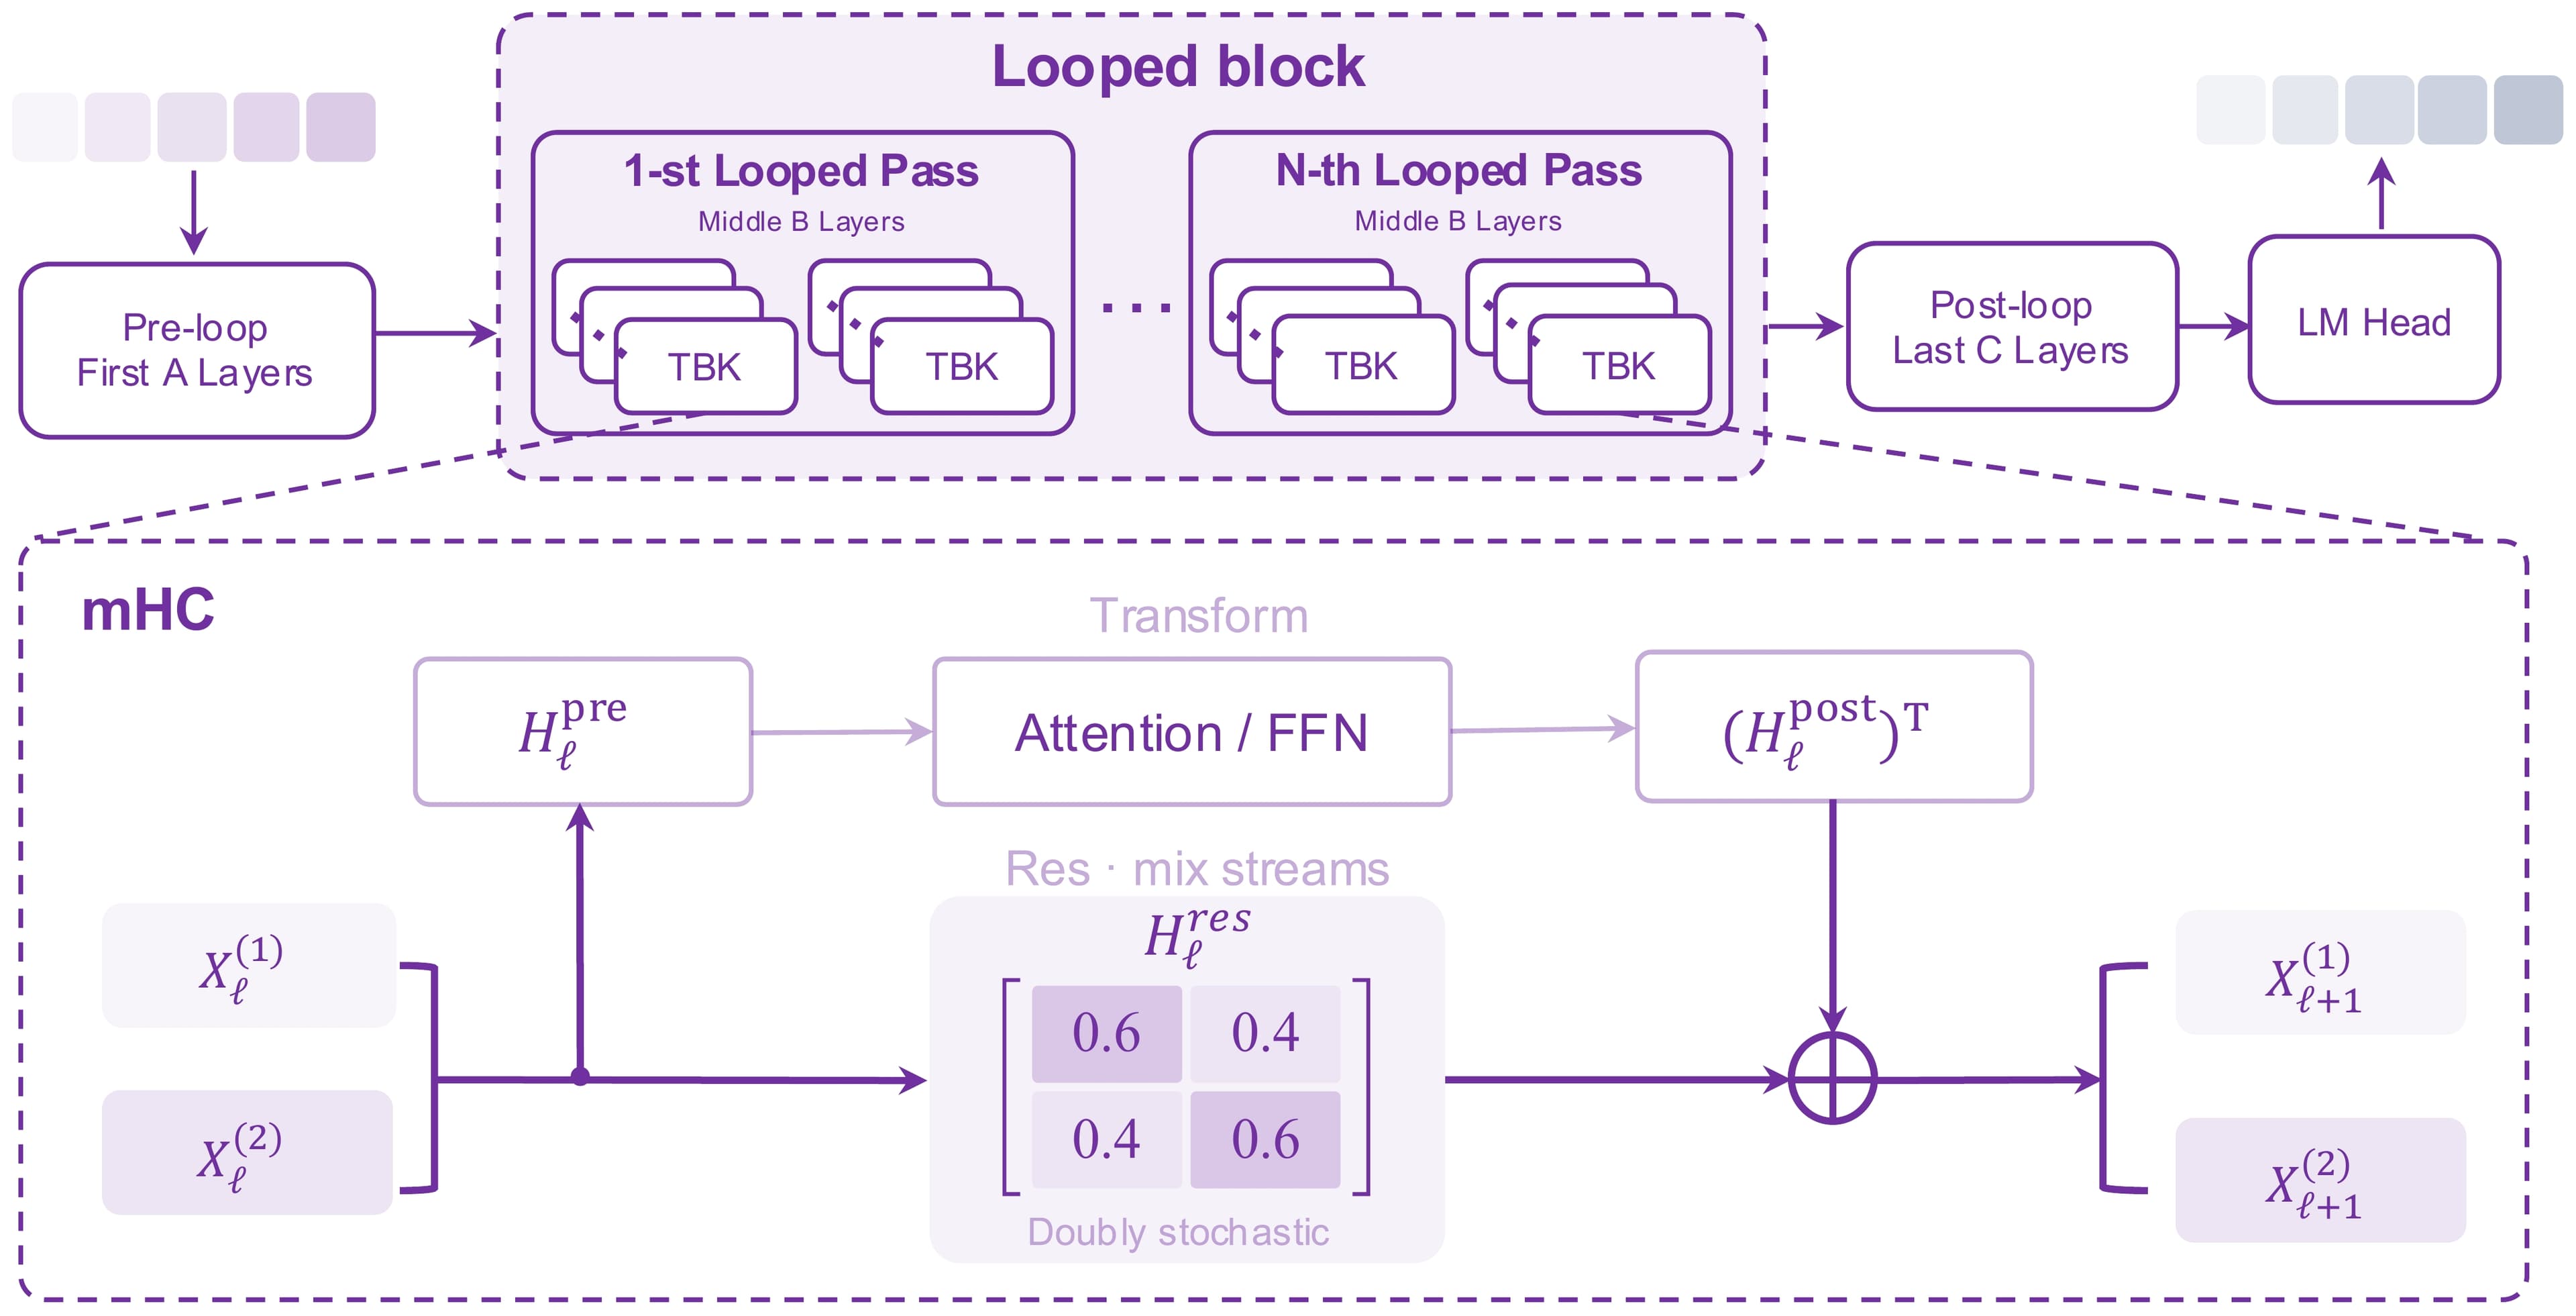
SenseTime previews a 9B looped-transformer VLM
SenseNova-Loop-9B-Preview puts a recurrent-depth architecture to work on multimodal reasoning.
SenseTime's SenseNova-U1.5 Unifies Vision Tasks
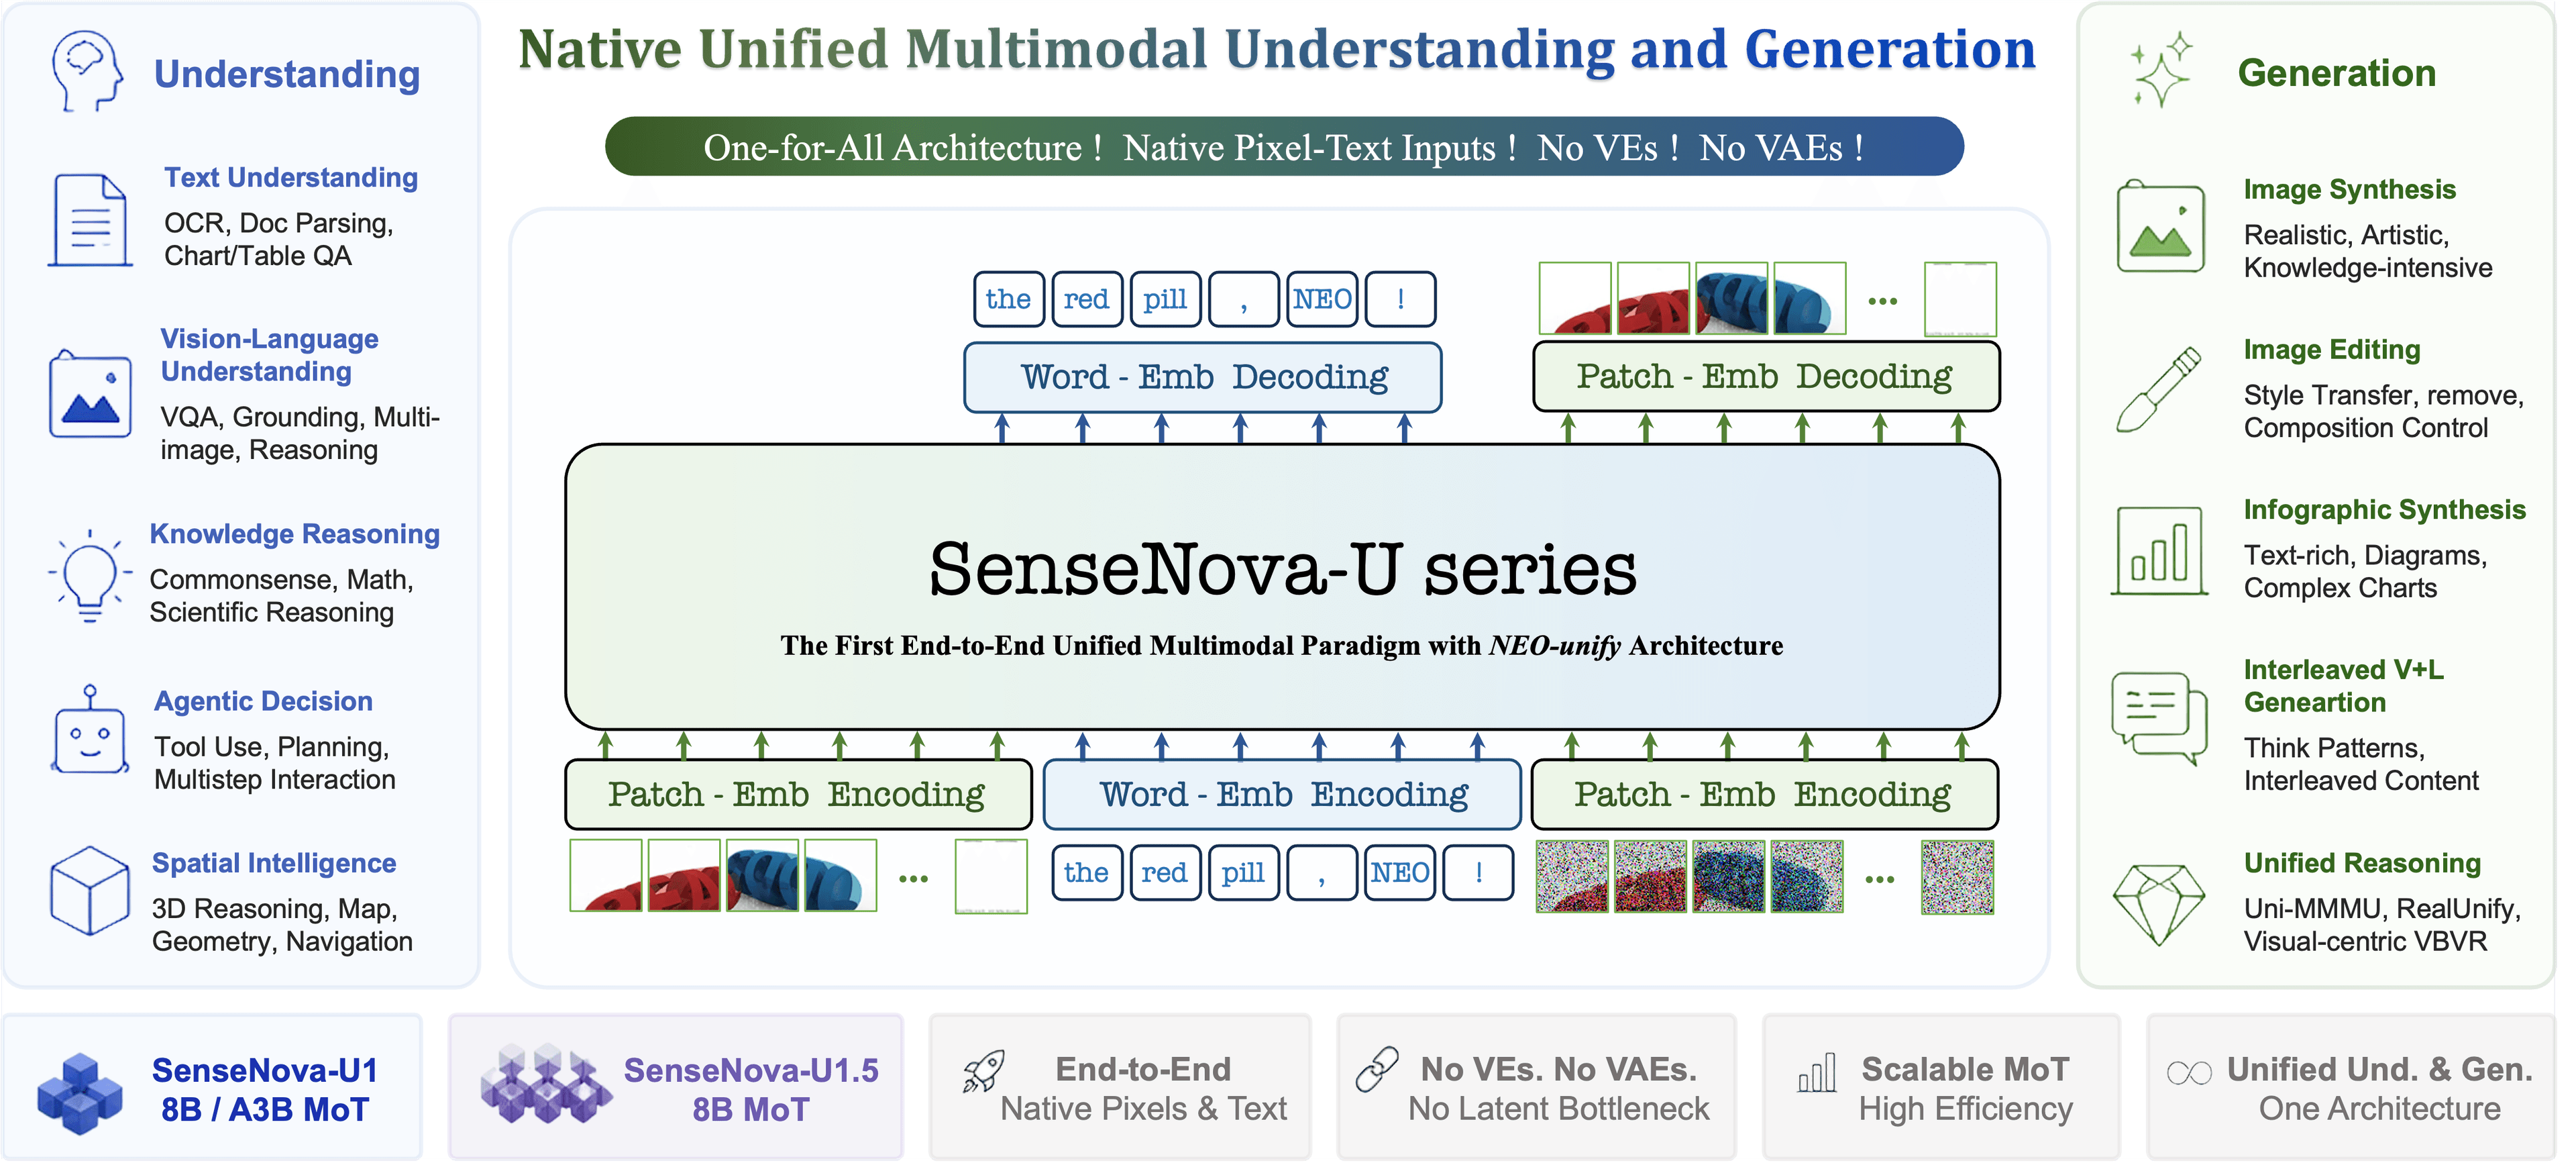
An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.
SenseTime Releases SenseNova U1.5 8B Any-to-Any Model
The new 8B multimodal model handles text, images, and image editing within a single native architecture.
More in Vision-Language
All Vision-Language →
Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
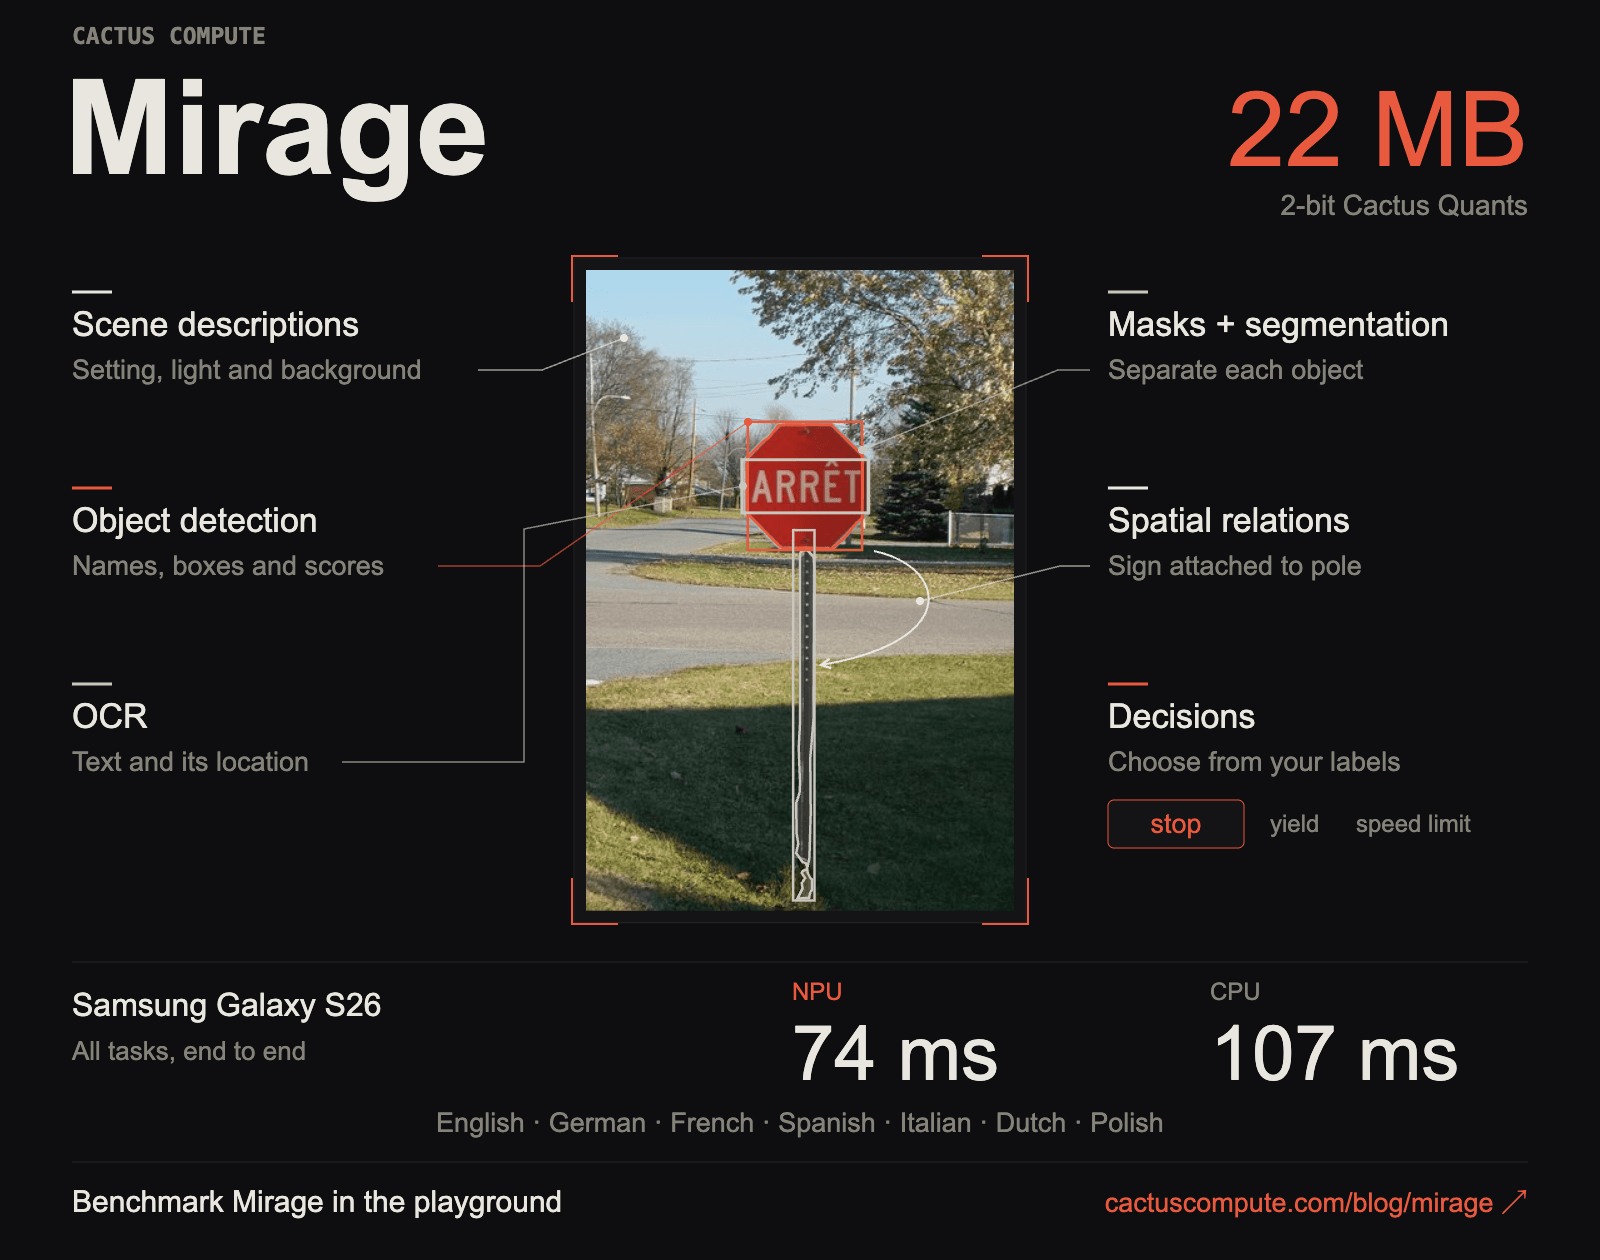
Cactus Compute's Mirage brings vision tasks on-device
The new open vision-language model targets detection, segmentation, and visual Q&A without relying on the cloud.
Thinking Machines ships Inkling-2-Small, an open MoE VLM
The Apache-2.0 vision-language model uses a mixture-of-experts design and lands openly on Hugging Face.
0 comments
No comments yet. Be the first to weigh in.