SenseTime's SenseNova-U1.5 Unifies Vision Tasks
An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.
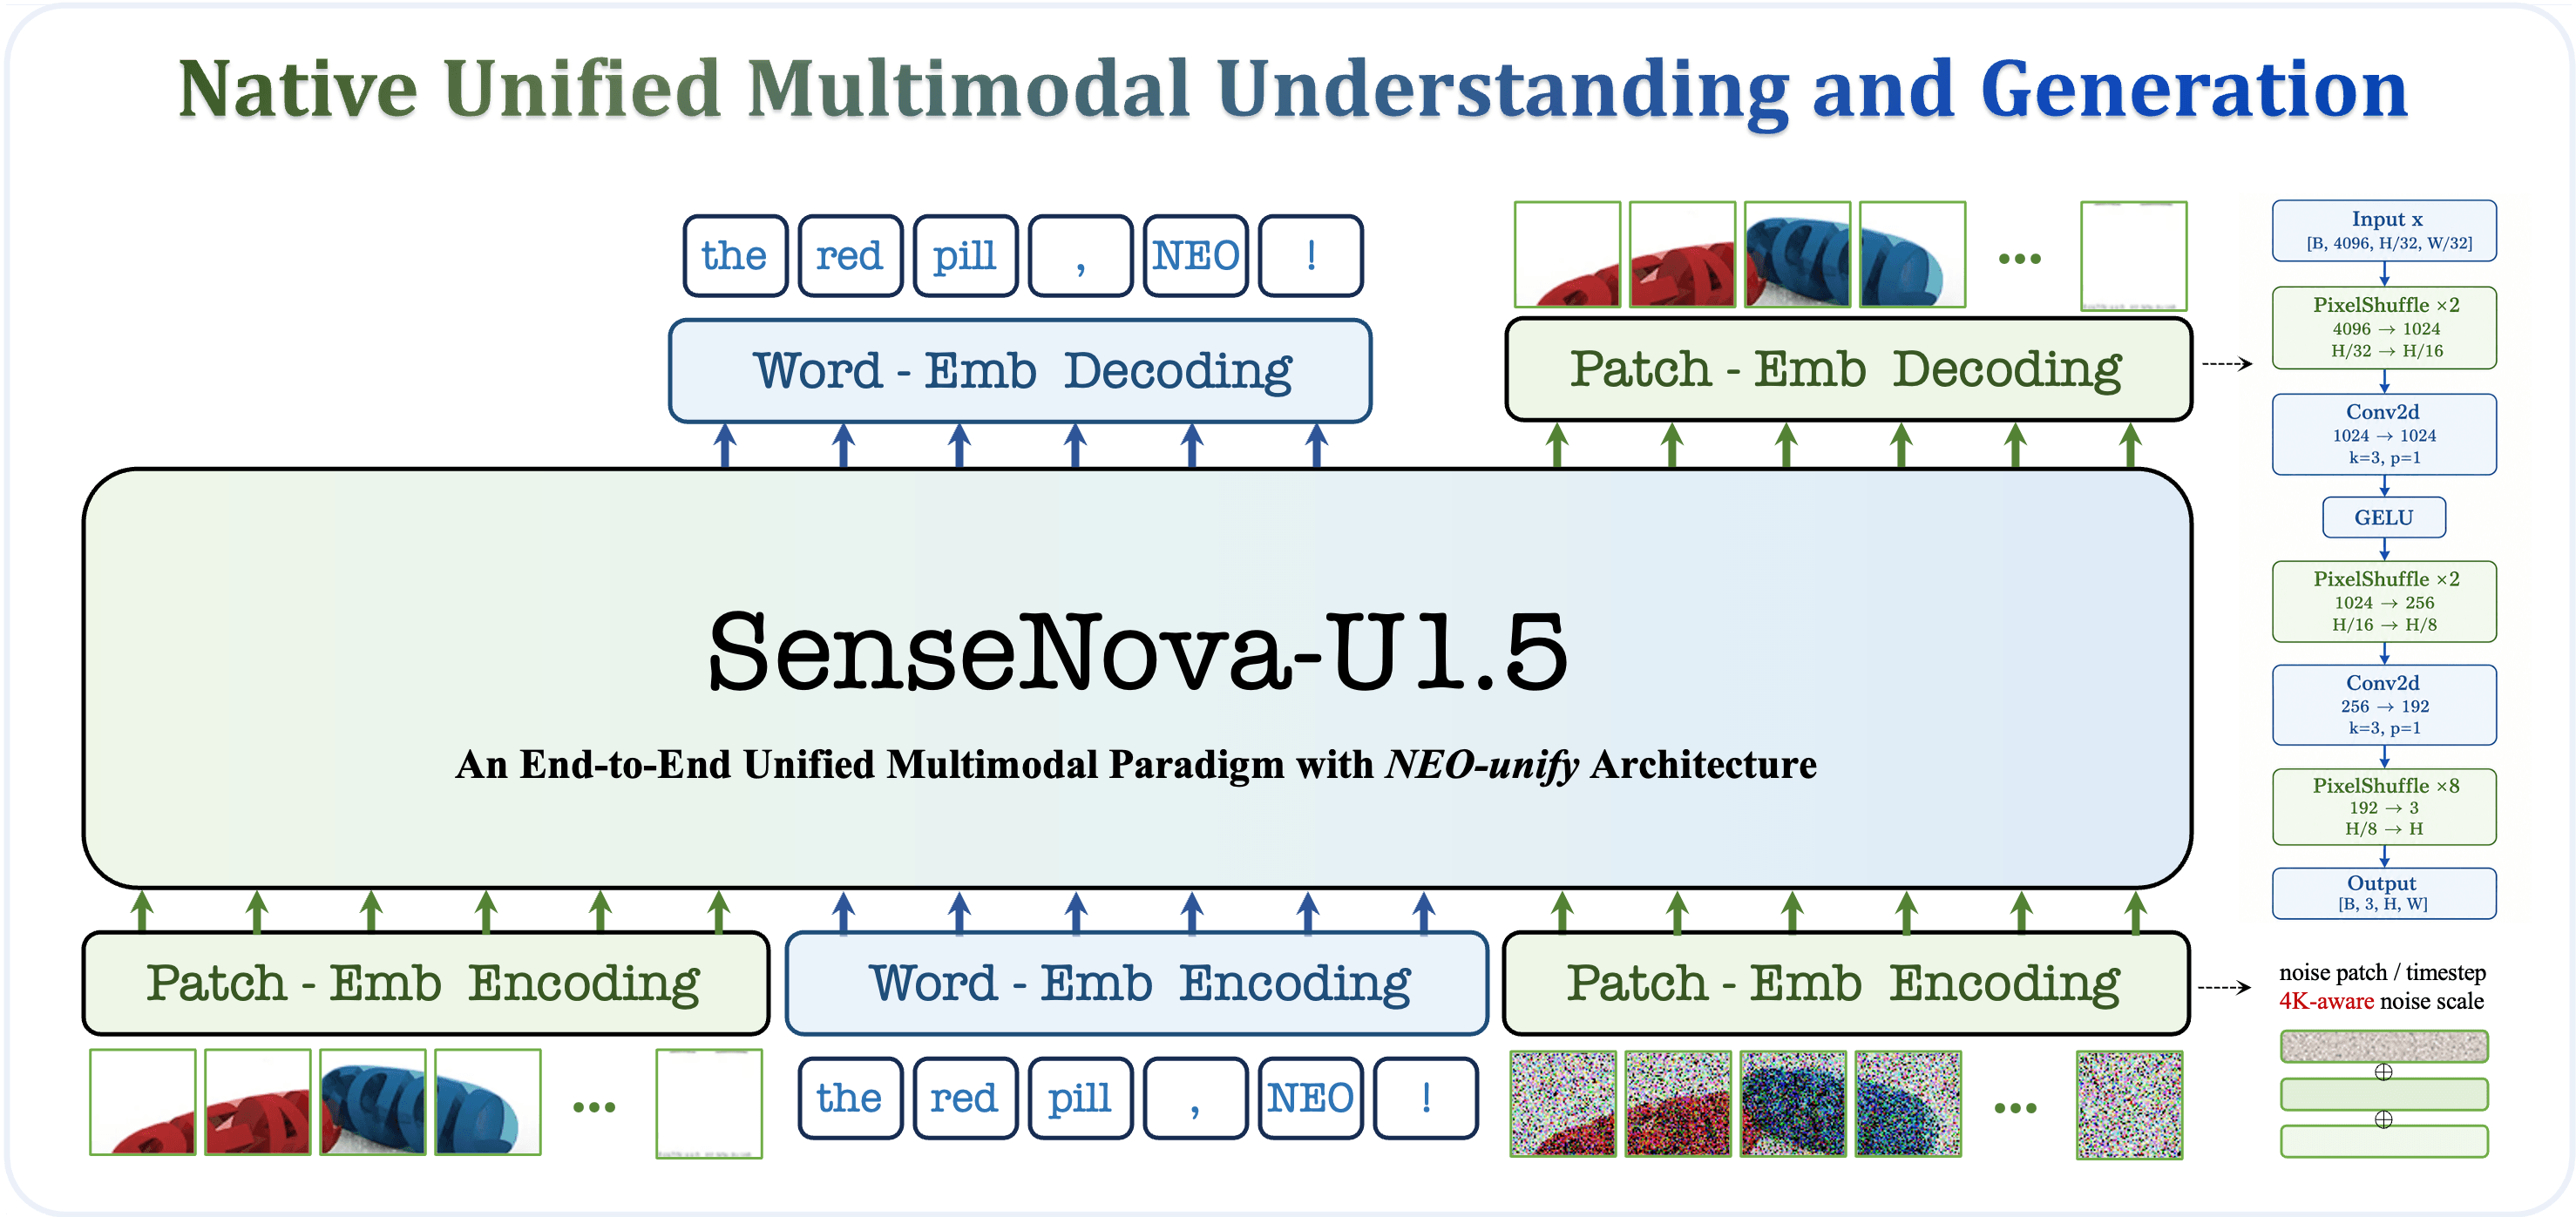
SenseTime has introduced SenseNova-U1.5, an 8-billion-parameter model that aims to fold visual understanding, reasoning, and image generation into a single native architecture. According to the research paper, the model is both encoder-free and VAE-free — a notable departure from the standard multimodal recipe.
Most vision-language systems today lean on a separate image encoder to interpret pictures, and text-to-image systems typically rely on a variational autoencoder (VAE) to compress images into a latent space. SenseNova-U1.5 discards both, processing modalities natively within one model rather than stitching together specialized components.
Why it matters
The promise of a truly unified model is architectural simplicity: one system that can read an image, reason about it, and generate a new one without handing tasks off between subsystems. That approach can reduce the friction and information loss that comes from bolting separate modules together.
- Handles understanding, reasoning, and generation in a single 8B model
- No image encoder and no VAE, unlike most multimodal stacks
- Spans vision-language input and text-to-image output
At 8B parameters, the model sits in a practical size range for deployment while pursuing the "native unified" design the paper describes. The full details, including how the architecture performs across its target tasks, are laid out in SenseTime's paper on Hugging Face.
Sources
- Visit
SenseNova-U1.5: Towards Native Unified Visual Intelligence
HF Papers
More from SenseTime
All SenseTime releases →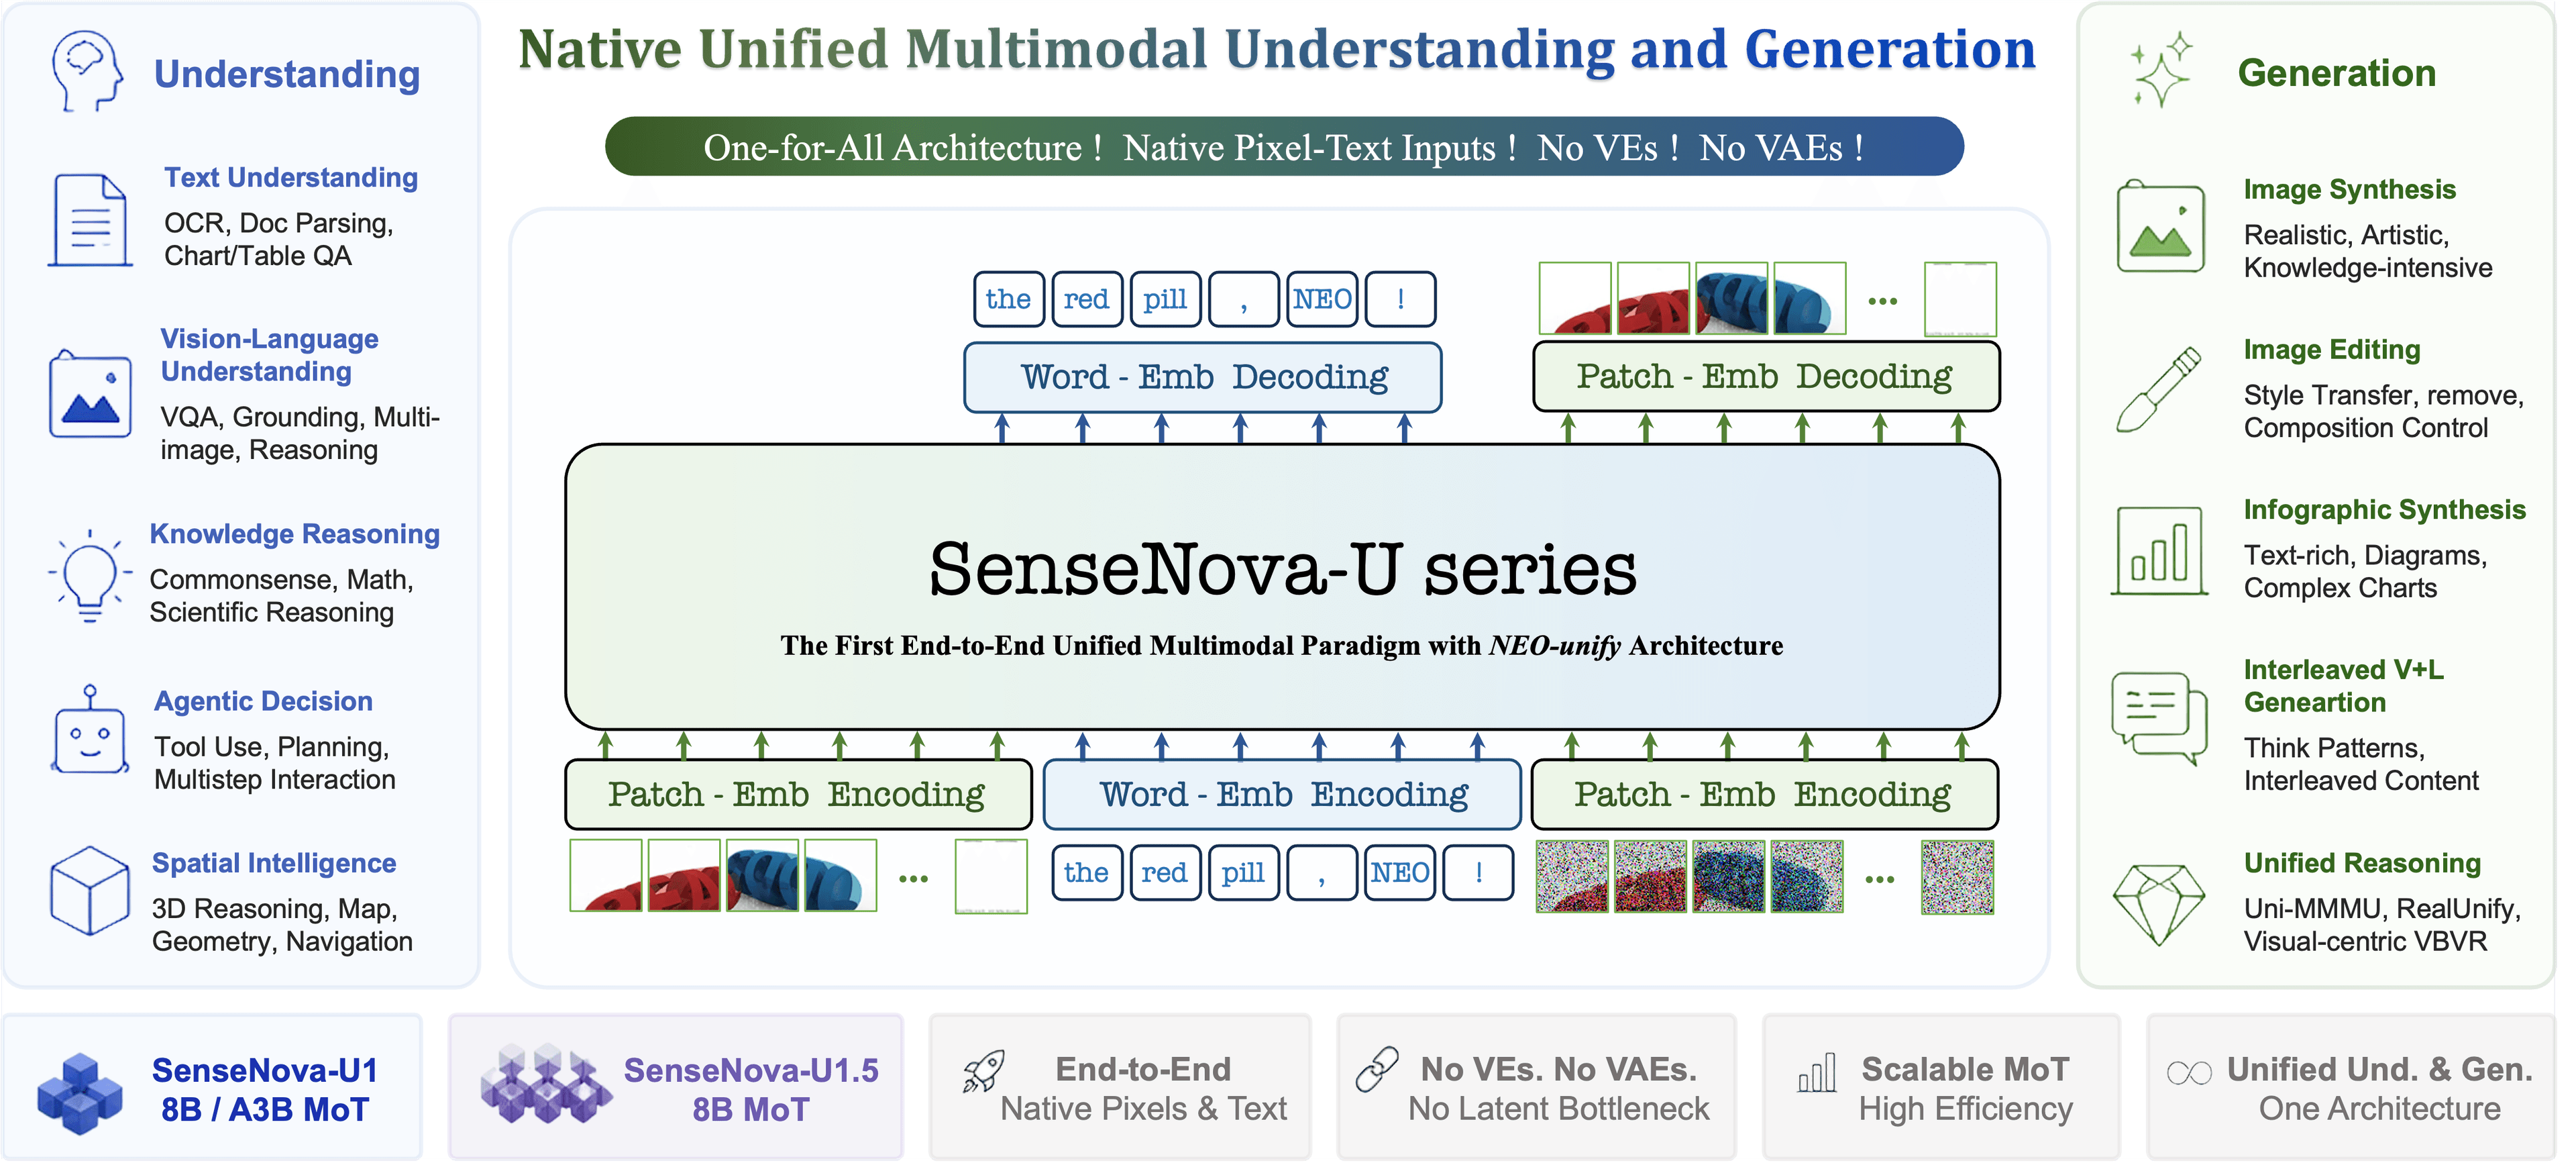
SenseTime Releases SenseNova U1.5 8B Any-to-Any Model
The new 8B multimodal model handles text, images, and image editing within a single native architecture.
SenseTime Debuts SenseNova U1.5 8B Multimodal Preview
An 8B any-to-any model that reads, generates, and edits images at up to 4K resolution, released as an early preview.
SenseTime's SenseNova-Vision-7B-MoT Goes Any-to-Any
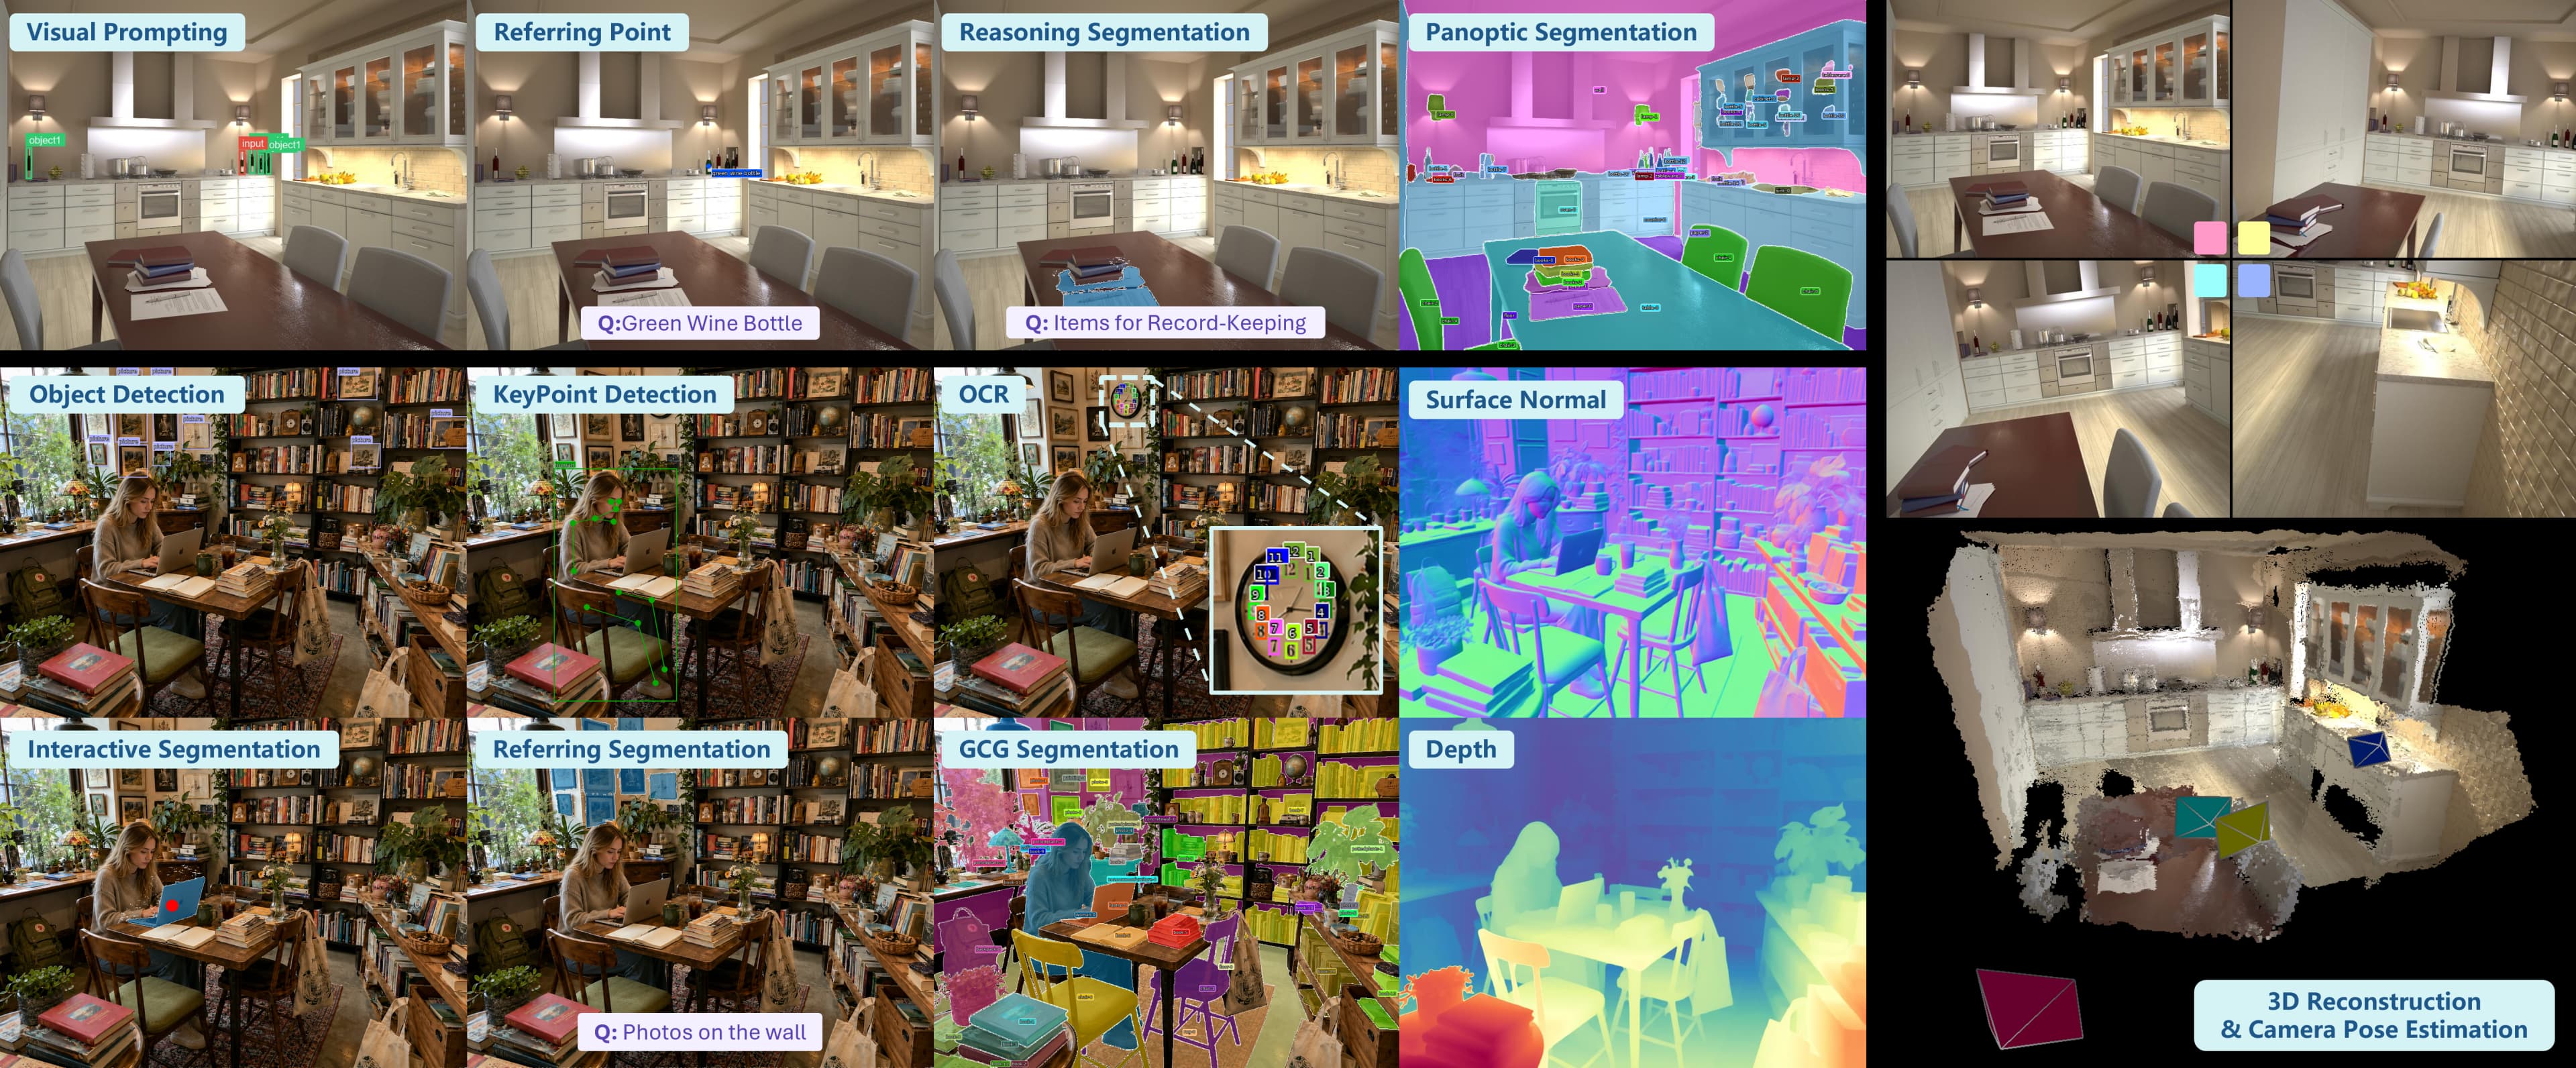
A single 7B model from SenseTime folds vision-language understanding, image generation, editing, and perception into one system.
More in Any-to-Any
All Any-to-Any →
MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
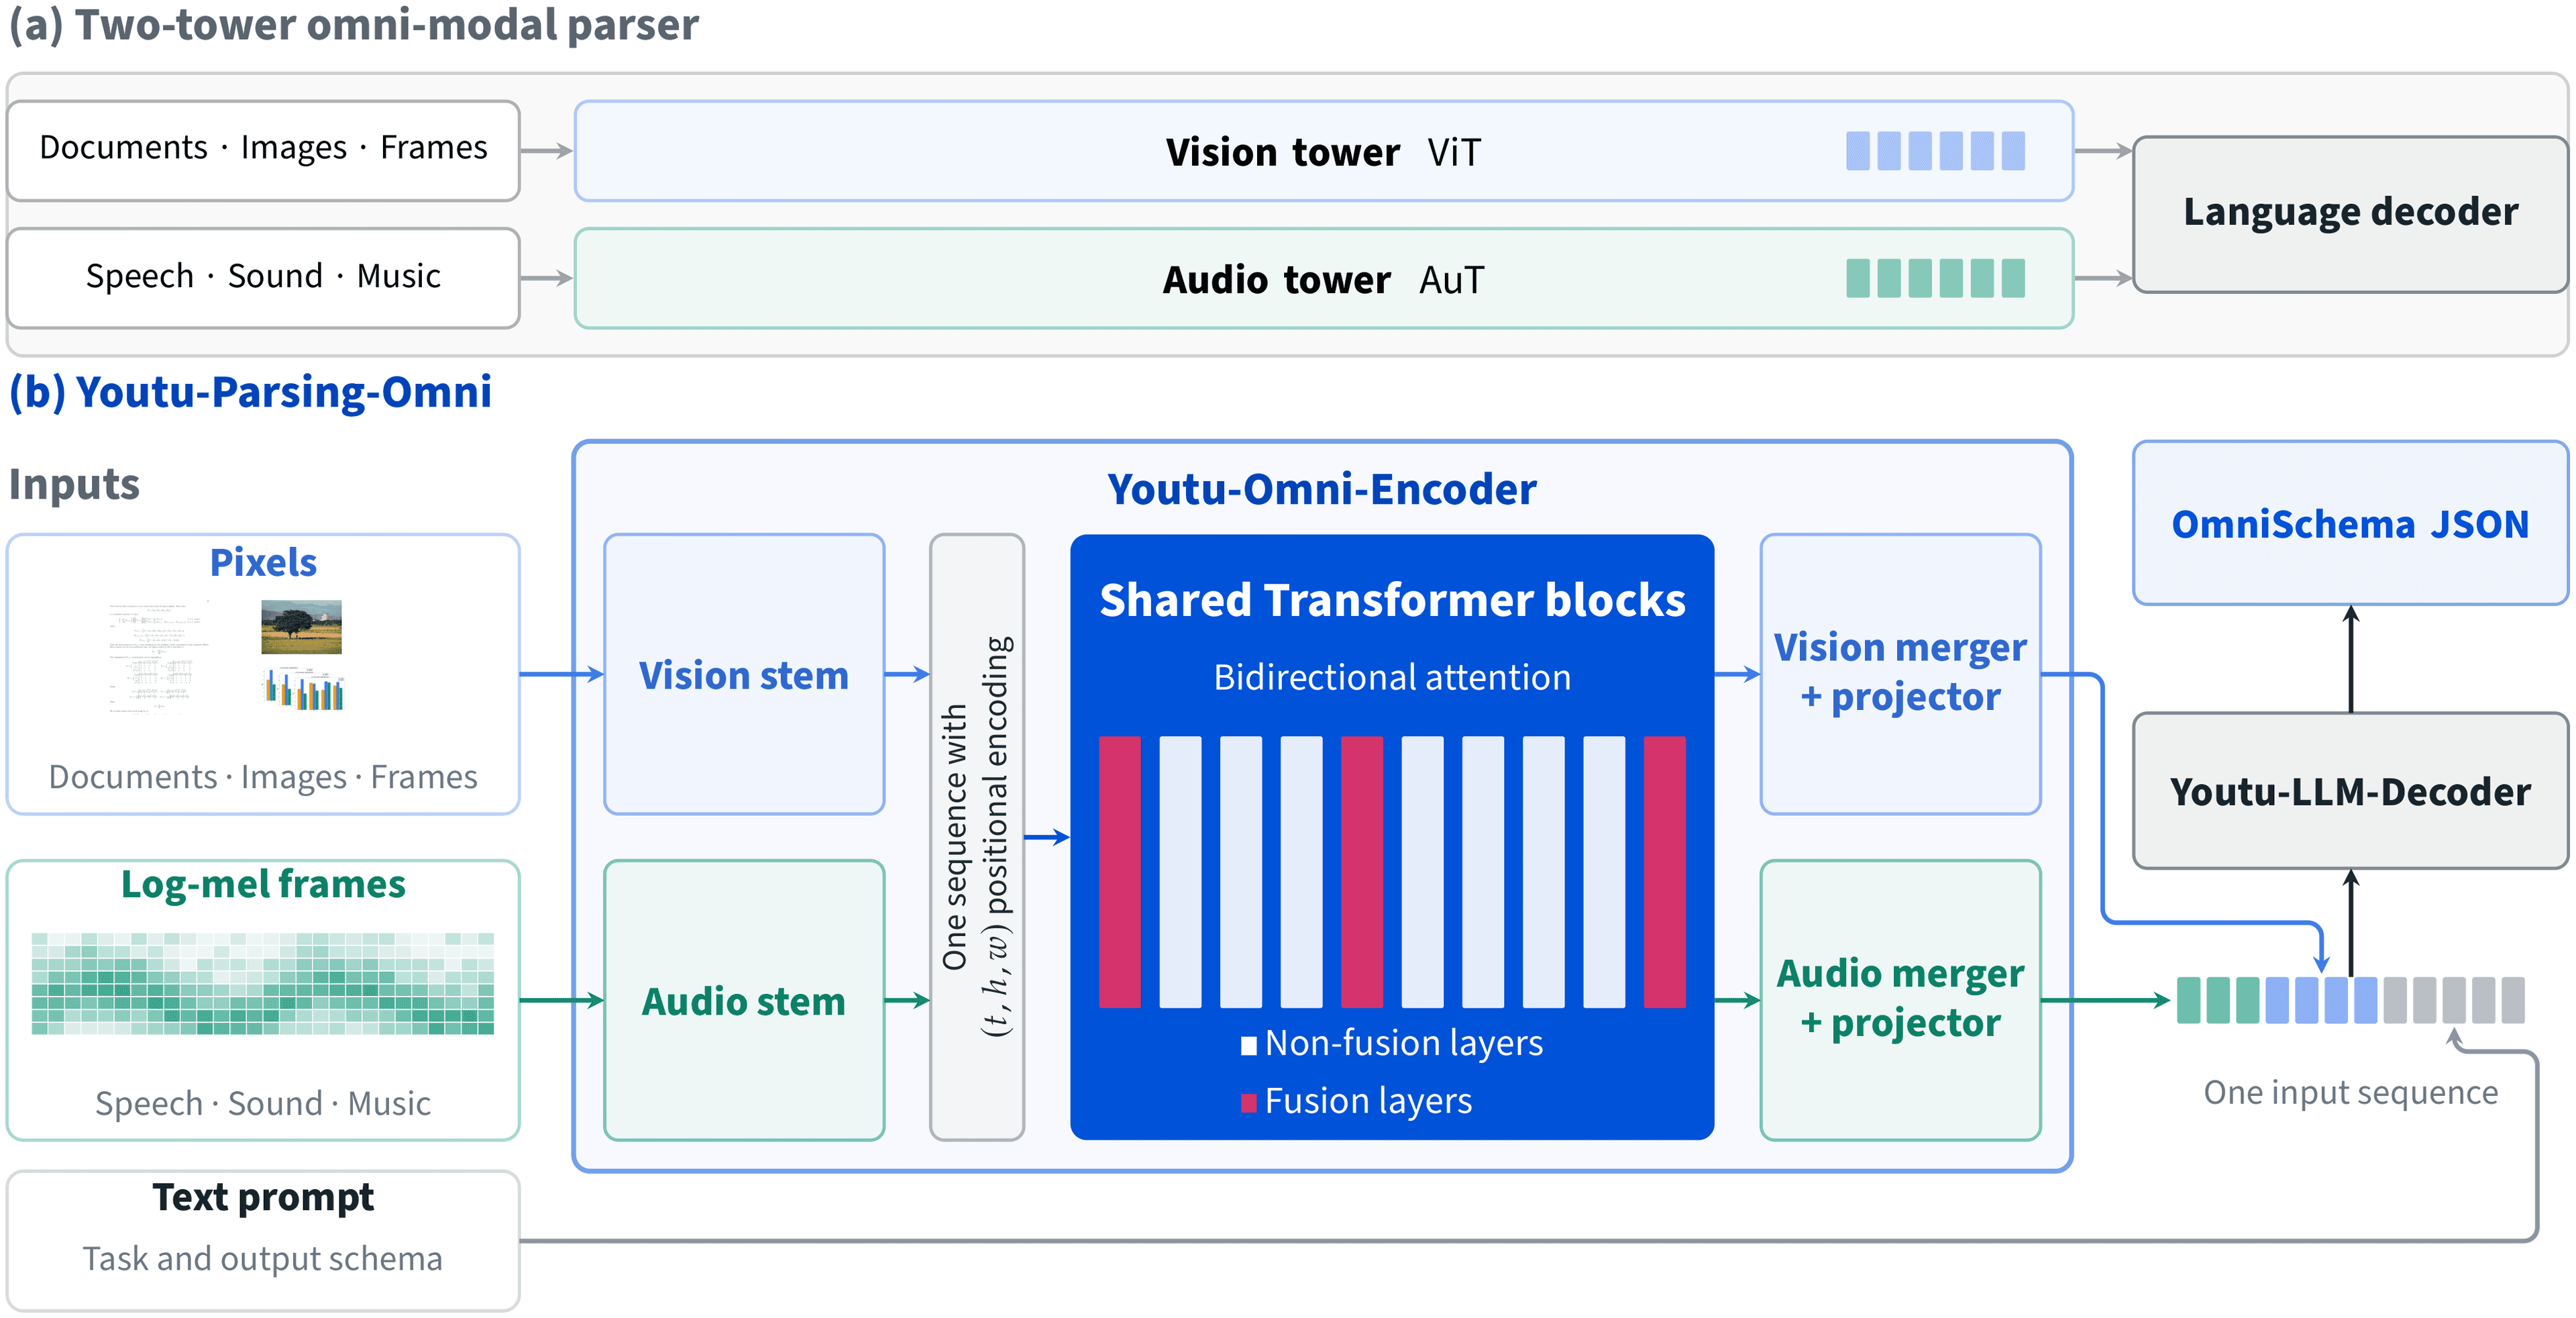
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
0 comments
No comments yet. Be the first to weigh in.