SenseTime Debuts SenseNova U1.5 8B Multimodal Preview
An 8B any-to-any model that reads, generates, and edits images at up to 4K resolution, released as an early preview.
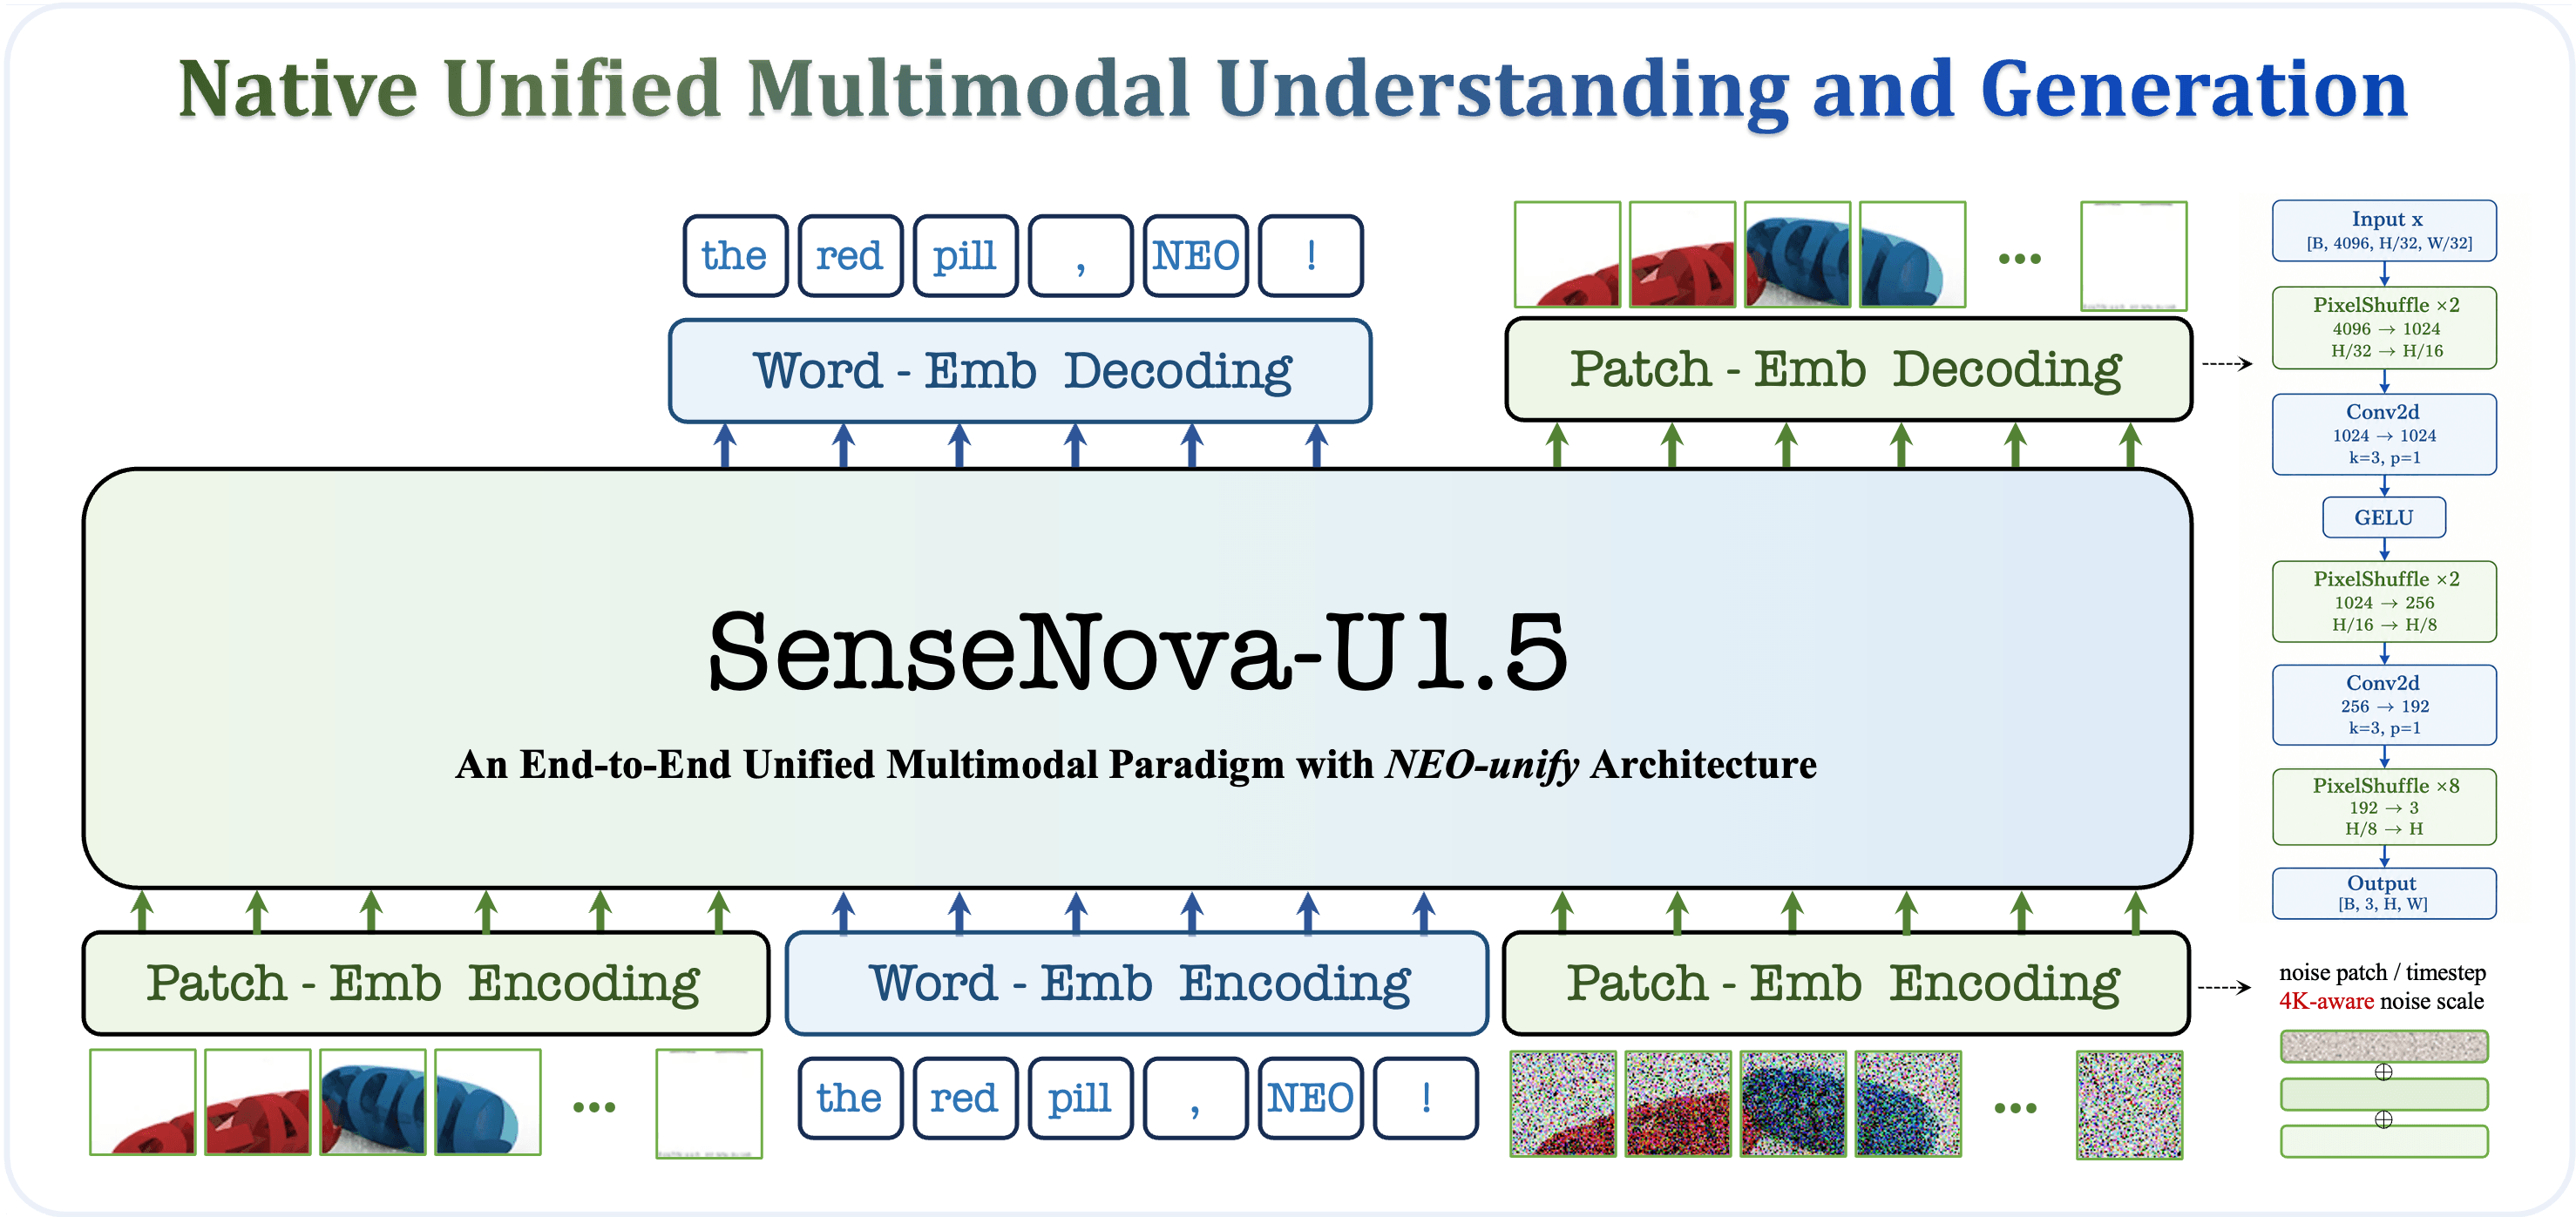
SenseTime has released a preview of SenseNova U1.5 8B MoT, an 8-billion-parameter multimodal model designed to handle a wide range of inputs and outputs in a single system. According to the model page on Hugging Face, the model spans any-to-any multimodal tasks, vision-language understanding, text-to-image generation, and image editing.
The standout claim is 4K image generation and editing, a resolution tier that many open multimodal models still struggle to reach. Paired with vision-language comprehension, that positions U1.5 as a unified tool rather than a collection of separate specialist models — the kind of consolidation that has become a design goal across the field.
Why it matters
At 8B parameters and with a dense (non-MoE) architecture, the model sits in a size class that's practical for teams without large clusters, while still targeting generation-heavy workloads. Bundling understanding, creation, and editing into one checkpoint lowers the integration burden for developers building creative or assistant-style applications.
- Any-to-any multimodal I/O in a single 8B model
- 4K image generation and editing
- Vision-language understanding alongside image synthesis
- Released under a custom ("other") license
As a preview, the release is best treated as an early look rather than a finished product; licensing terms and full capabilities warrant a close read before production use. Still, it's a notable entry from a major Chinese AI lab into the crowded but fast-moving unified-multimodal space.
Sources
- Visit
sensenova/SenseNova-U1.5-8B-MoT-Preview
Hugging Face
More from SenseTime
All SenseTime releases →SenseTime's SenseNova-U1.5 Unifies Vision Tasks
An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.
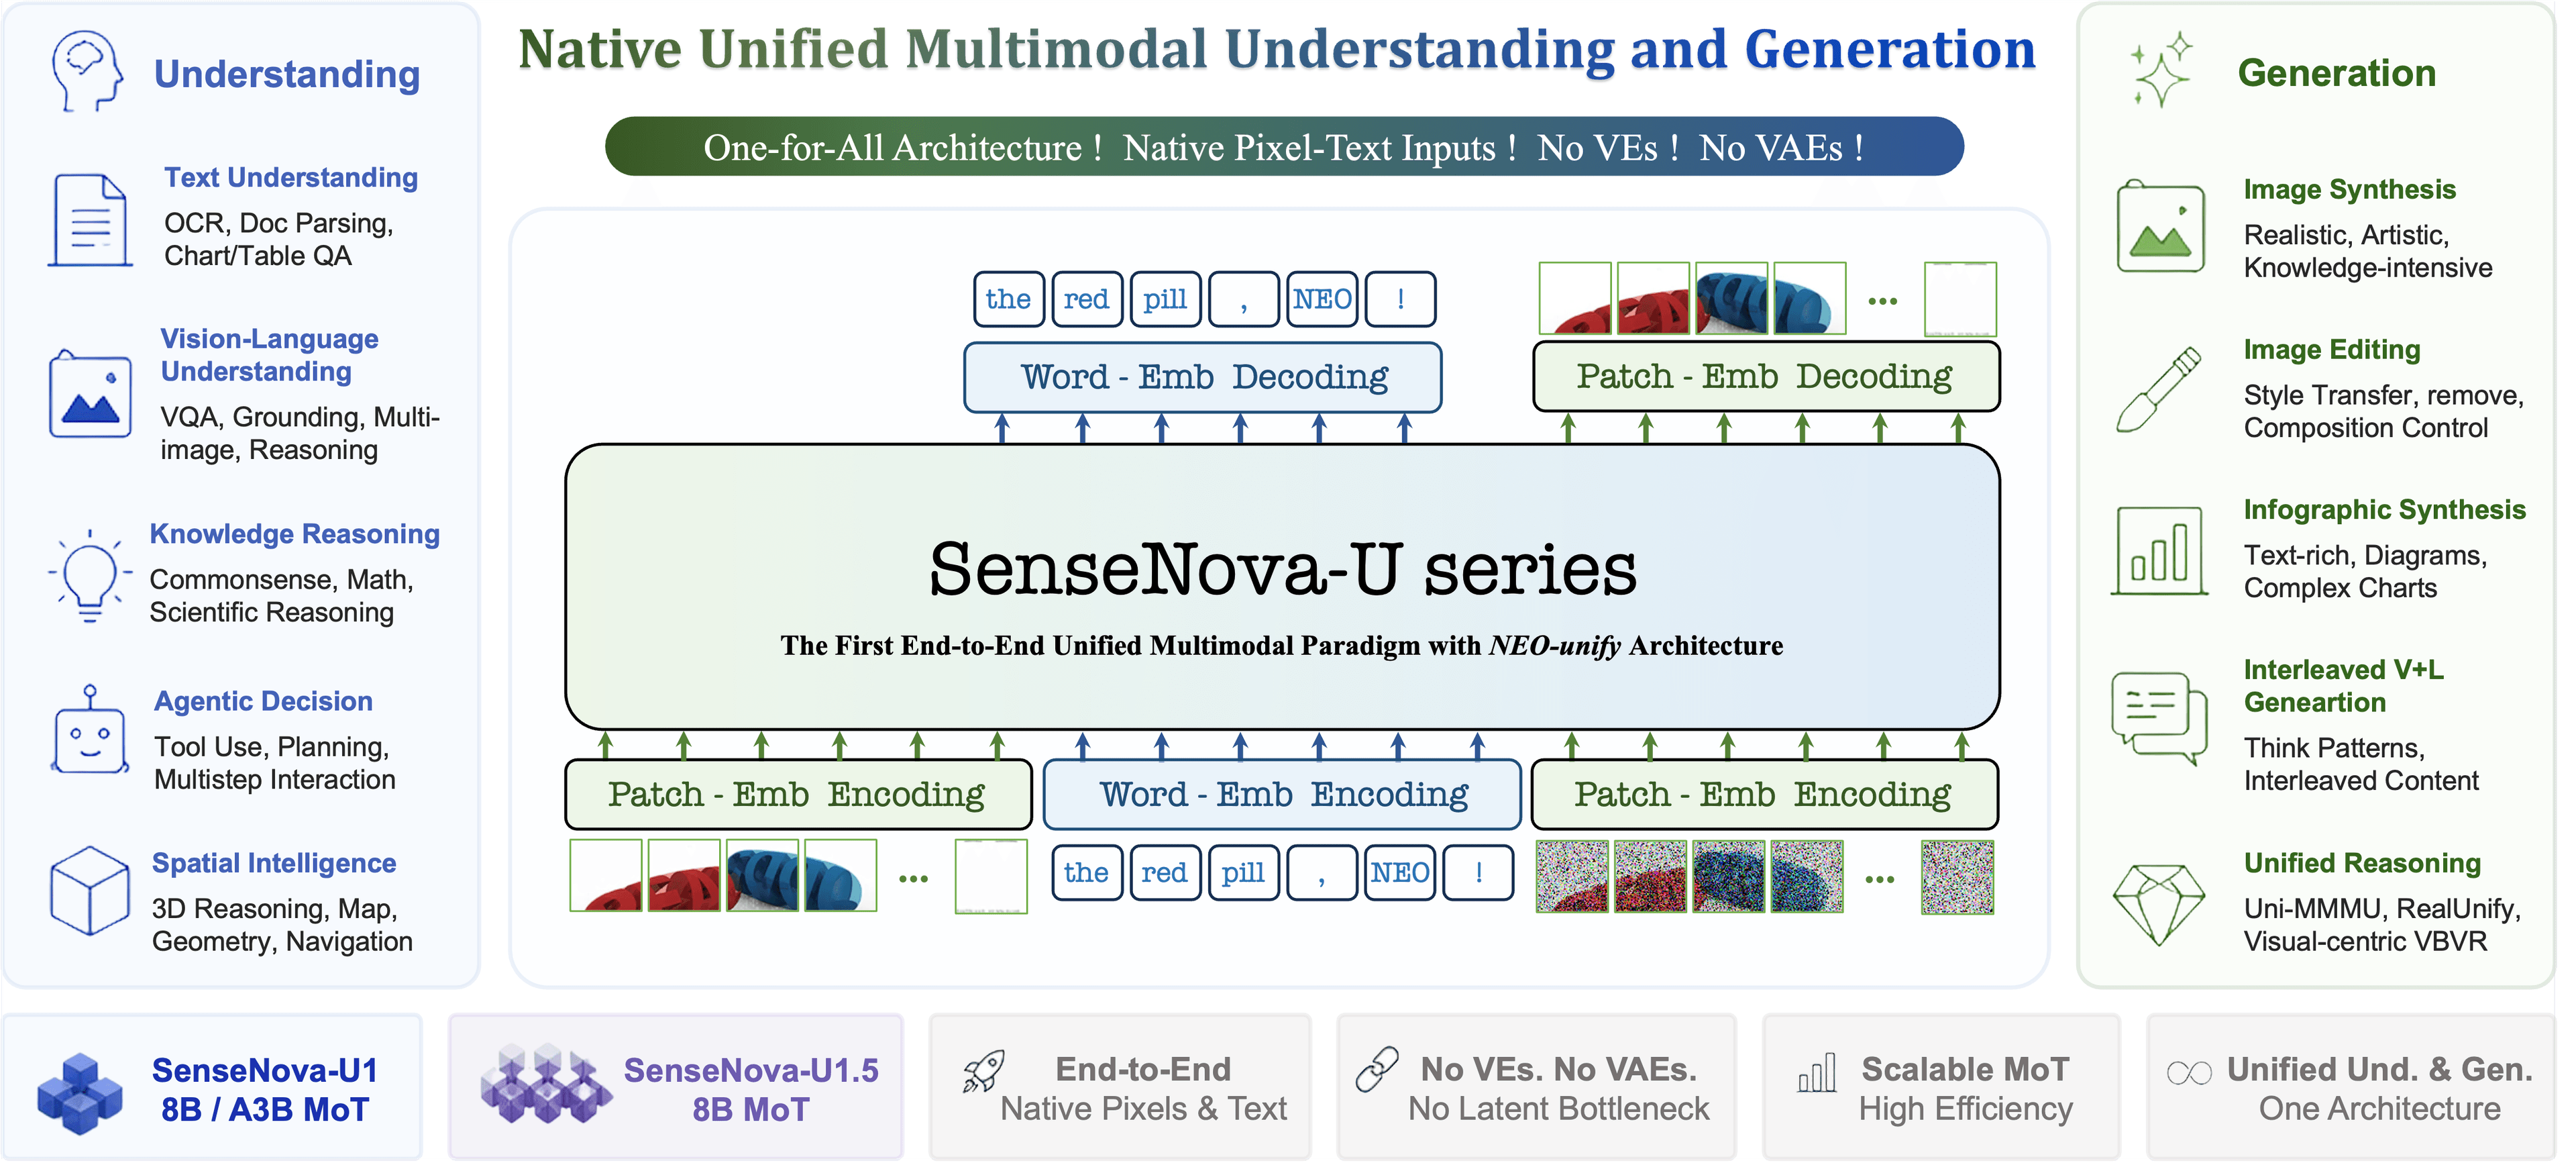
SenseTime Releases SenseNova U1.5 8B Any-to-Any Model
The new 8B multimodal model handles text, images, and image editing within a single native architecture.
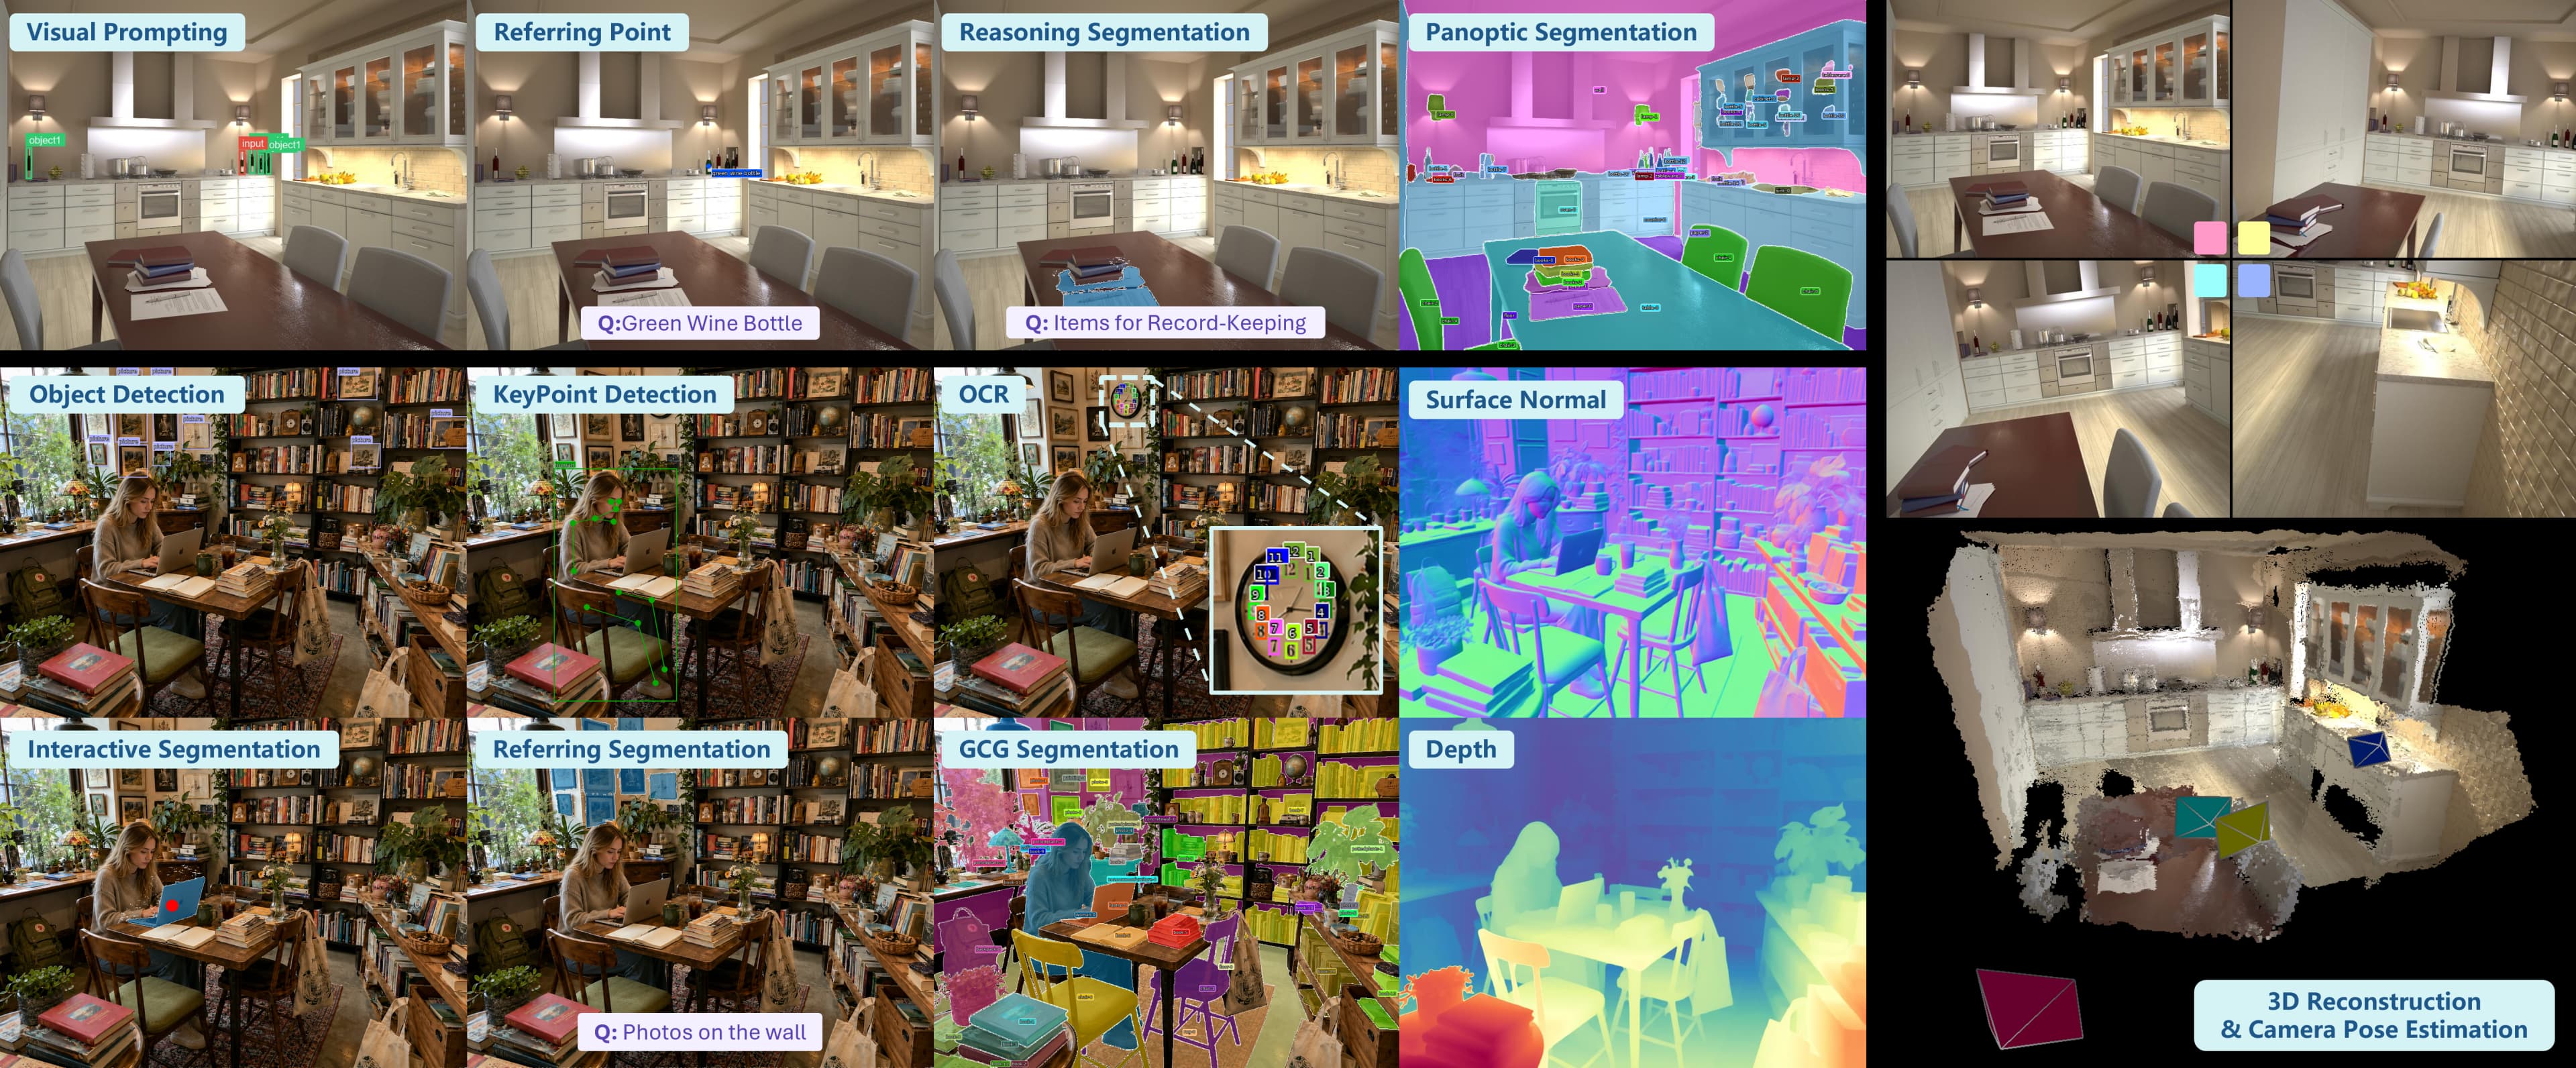
SenseTime's SenseNova-Vision-7B-MoT Goes Any-to-Any
A single 7B model from SenseTime folds vision-language understanding, image generation, editing, and perception into one system.
More in Any-to-Any
All Any-to-Any →
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.