Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.

Liquid AI has released LFM3-Omni-2B, a compact multimodal model that aims to pack a wide range of input and output types into a footprint suited for edge hardware. At roughly 2 billion parameters, it is designed to run where cloud-scale models cannot.
The model is described as "any-to-any," meaning it can take in and produce across multiple modalities. According to the release, that includes vision and audio understanding alongside text, plus speech-to-speech capability — a notable combination for a model of this size.
Why it matters
Most multimodal systems that handle both vision and real-time speech remain large and tethered to datacenter inference. A 2B model that spans these tasks fits Liquid AI's broader focus on efficient architectures intended for on-device use. Smaller any-to-any models open the door to:
- Local voice assistants that respond without a network round-trip
- Privacy-sensitive applications where audio and images stay on the device
- Lower-cost deployment on consumer and embedded hardware
The model is published under a custom license, so teams evaluating it for production should review the terms on the model page before building on it. As with any early release, real-world performance on vision, audio and speech tasks will be the measure of how far a model this compact can stretch.
Sources
- Visit
LiquidAI/LFM3-Omni-2B
Hugging Face
More from LiquidAI
All LiquidAI releases →Liquid AI debuts LFM3-1.7B for edge deployment
A compact 1.7B-parameter multilingual model built to run locally and serve as the base for specialized multimodal variants.
Liquid AI's LFM2.5 Puts a 24B MoE on Your Device
The new mixture-of-experts model keeps total capacity high while activating only about 2B parameters per token for edge agents.
Liquid AI's d1-3B brings multimodal models to the edge
The new LFM2-based d1-3B is a compact vision-language model aimed at running decisions directly on-device.
More in Any-to-Any
All Any-to-Any →
MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
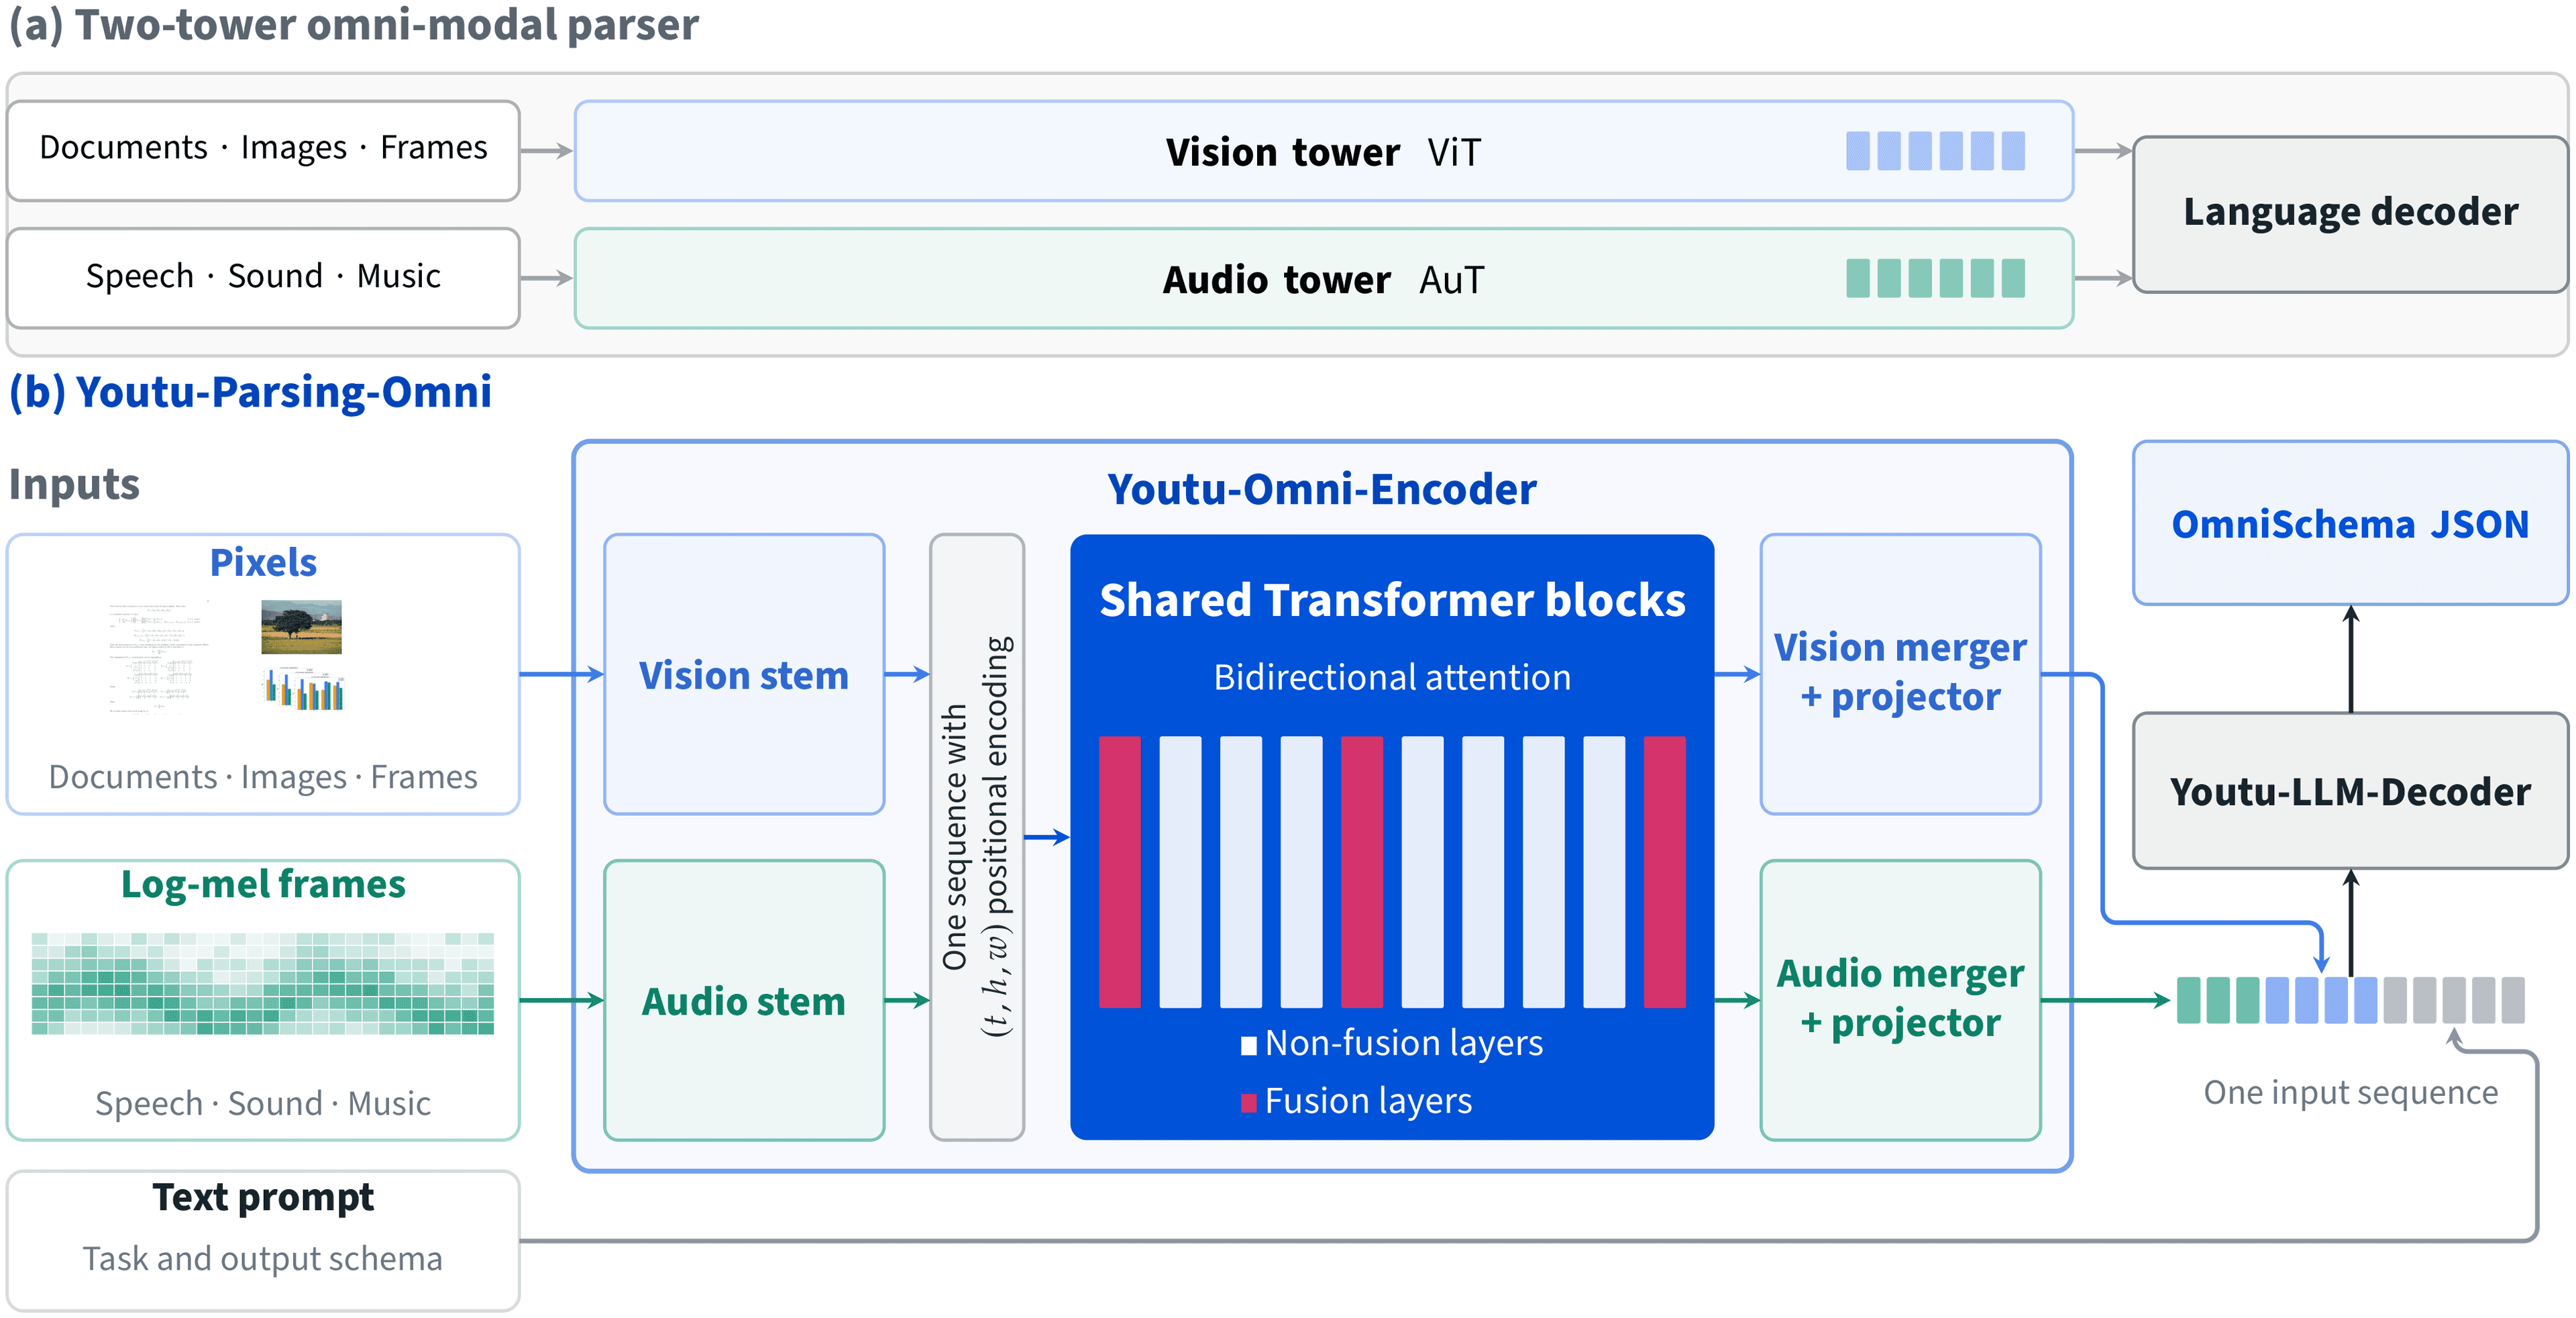
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
0 comments
No comments yet. Be the first to weigh in.