Liquid AI's d1-3B brings multimodal models to the edge
The new LFM2-based d1-3B is a compact vision-language model aimed at running decisions directly on-device.
Liquid AI has introduced d1-3B, part of a new line of open multimodal "decision" models built on the company's LFM2 architecture and designed to run at the edge. At roughly 3 billion parameters, the model is small enough to deploy on constrained hardware while handling vision-language tasks, according to the company's announcement on Hugging Face.
The pitch here is less about chasing frontier benchmarks and more about placement. By keeping the parameter count modest and targeting on-device inference, d1-3B is positioned for scenarios where sending data to the cloud is impractical — think robotics, cameras, and other latency- or privacy-sensitive applications that need to interpret images and text locally.
Why it matters
The open-weights landscape has been dominated by ever-larger models, but a growing share of real-world demand sits at the opposite end: compact systems that run where the data is generated. A multimodal model in the 1B–7B range that can actually fit on edge hardware fills a practical gap.
- Multimodal: handles both vision and language inputs
- Compact: around 3B parameters, sized for edge deployment
- Open: weights published on Hugging Face under the company's license
Liquid AI frames d1 as a family rather than a one-off, suggesting more variants may follow. For developers building on-device applications, the release offers a lightweight option worth evaluating against existing small multimodal models. Full details are available in Liquid AI's blog post.
Sources
- Visit
Multimodal open d1 decision models for the edge
Announcement
More from LiquidAI
All LiquidAI releases →Liquid AI's LFM2.5-VL-3B targets on-device vision
The 3-billion-parameter vision-language model is tuned for faster multimodal work on edge hardware.
Liquid AI ships LFM2.5, a 2.6B on-device model
The latest Liquid Foundation Model targets multilingual text generation on laptops and phones, packaged in GGUF for local runtimes.
Liquid AI's LFM2.5-2.6B targets on-device agents
A compact 2.6-billion-parameter model built to run local, multilingual agents without leaning on the cloud.
More in Vision-Language
All Vision-Language →
Perplexity releases a 27B model for multimodal routing
The open-weight 'decider' model is designed to classify queries and route them inside Perplexity's stack.
Cloudflare's Clef brings structured decisions to open models
The new open-weight vision-language family outputs typed, structured results and arrives alongside a reinforcement-learning fine-tuning platform.
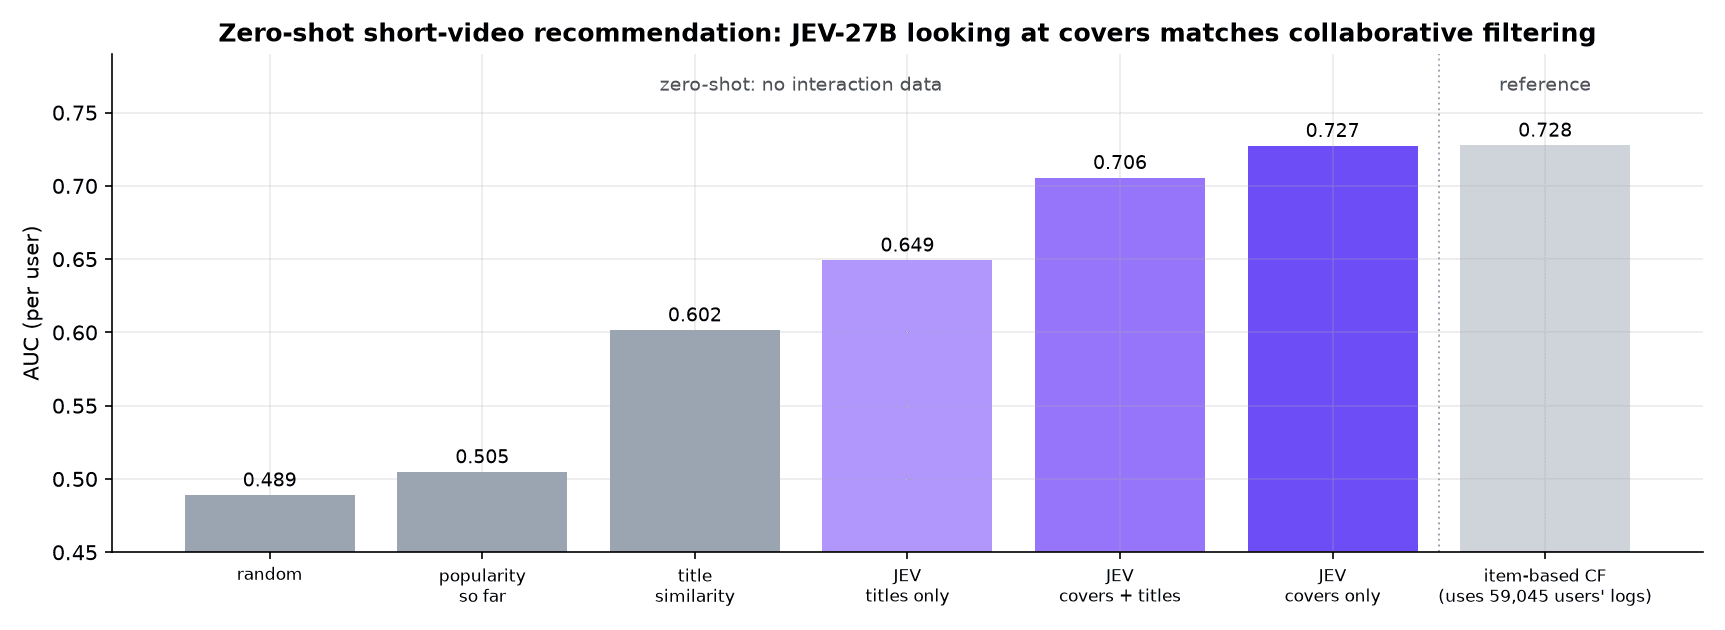
JEV-27B-VL Pairs Vision-Language With Calibrated Odds
A 27B vision-language model from autotrust aims to output typed decisions with probabilities you can actually trust.
0 comments
No comments yet. Be the first to weigh in.