Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.

Tencent has quietly released Hunyuan Hy4-flash, a new multimodal model in its Hunyuan family, now available on Hugging Face. The "flash" branding signals a model tuned for speed and efficiency, aimed at latency-sensitive workloads rather than maximum capability.
The release is built around a mixture-of-experts (MoE) architecture, which activates only a portion of the model's parameters for any given input. That approach lets developers tap a large total parameter pool while keeping inference costs closer to those of a smaller dense model — a practical fit for the "flash" positioning.
What it does
Hy4-flash is a vision-language model with text capabilities, meaning it can take in both images and text and respond to instructions. Key points from the record:
- Primary modality is vision-language, with text handling alongside
- MoE design for efficient inference
- Released as an instruction-tuned model under a custom (non-standard) license
Specifics such as parameter counts and context length were not detailed in the release metadata, so teams evaluating the model will want to check the model card directly for configuration and usage terms.
Why it matters: Tencent is one of several large Chinese labs steadily shipping open-weight models, and a fast multimodal MoE broadens the options for developers who need image understanding without the overhead of a frontier-scale system. As always, the custom license means the details of commercial use deserve a close read before deployment.
Sources
- Visit
tencent/Hy4-flash
Hugging Face
More from Tencent
All Tencent releases →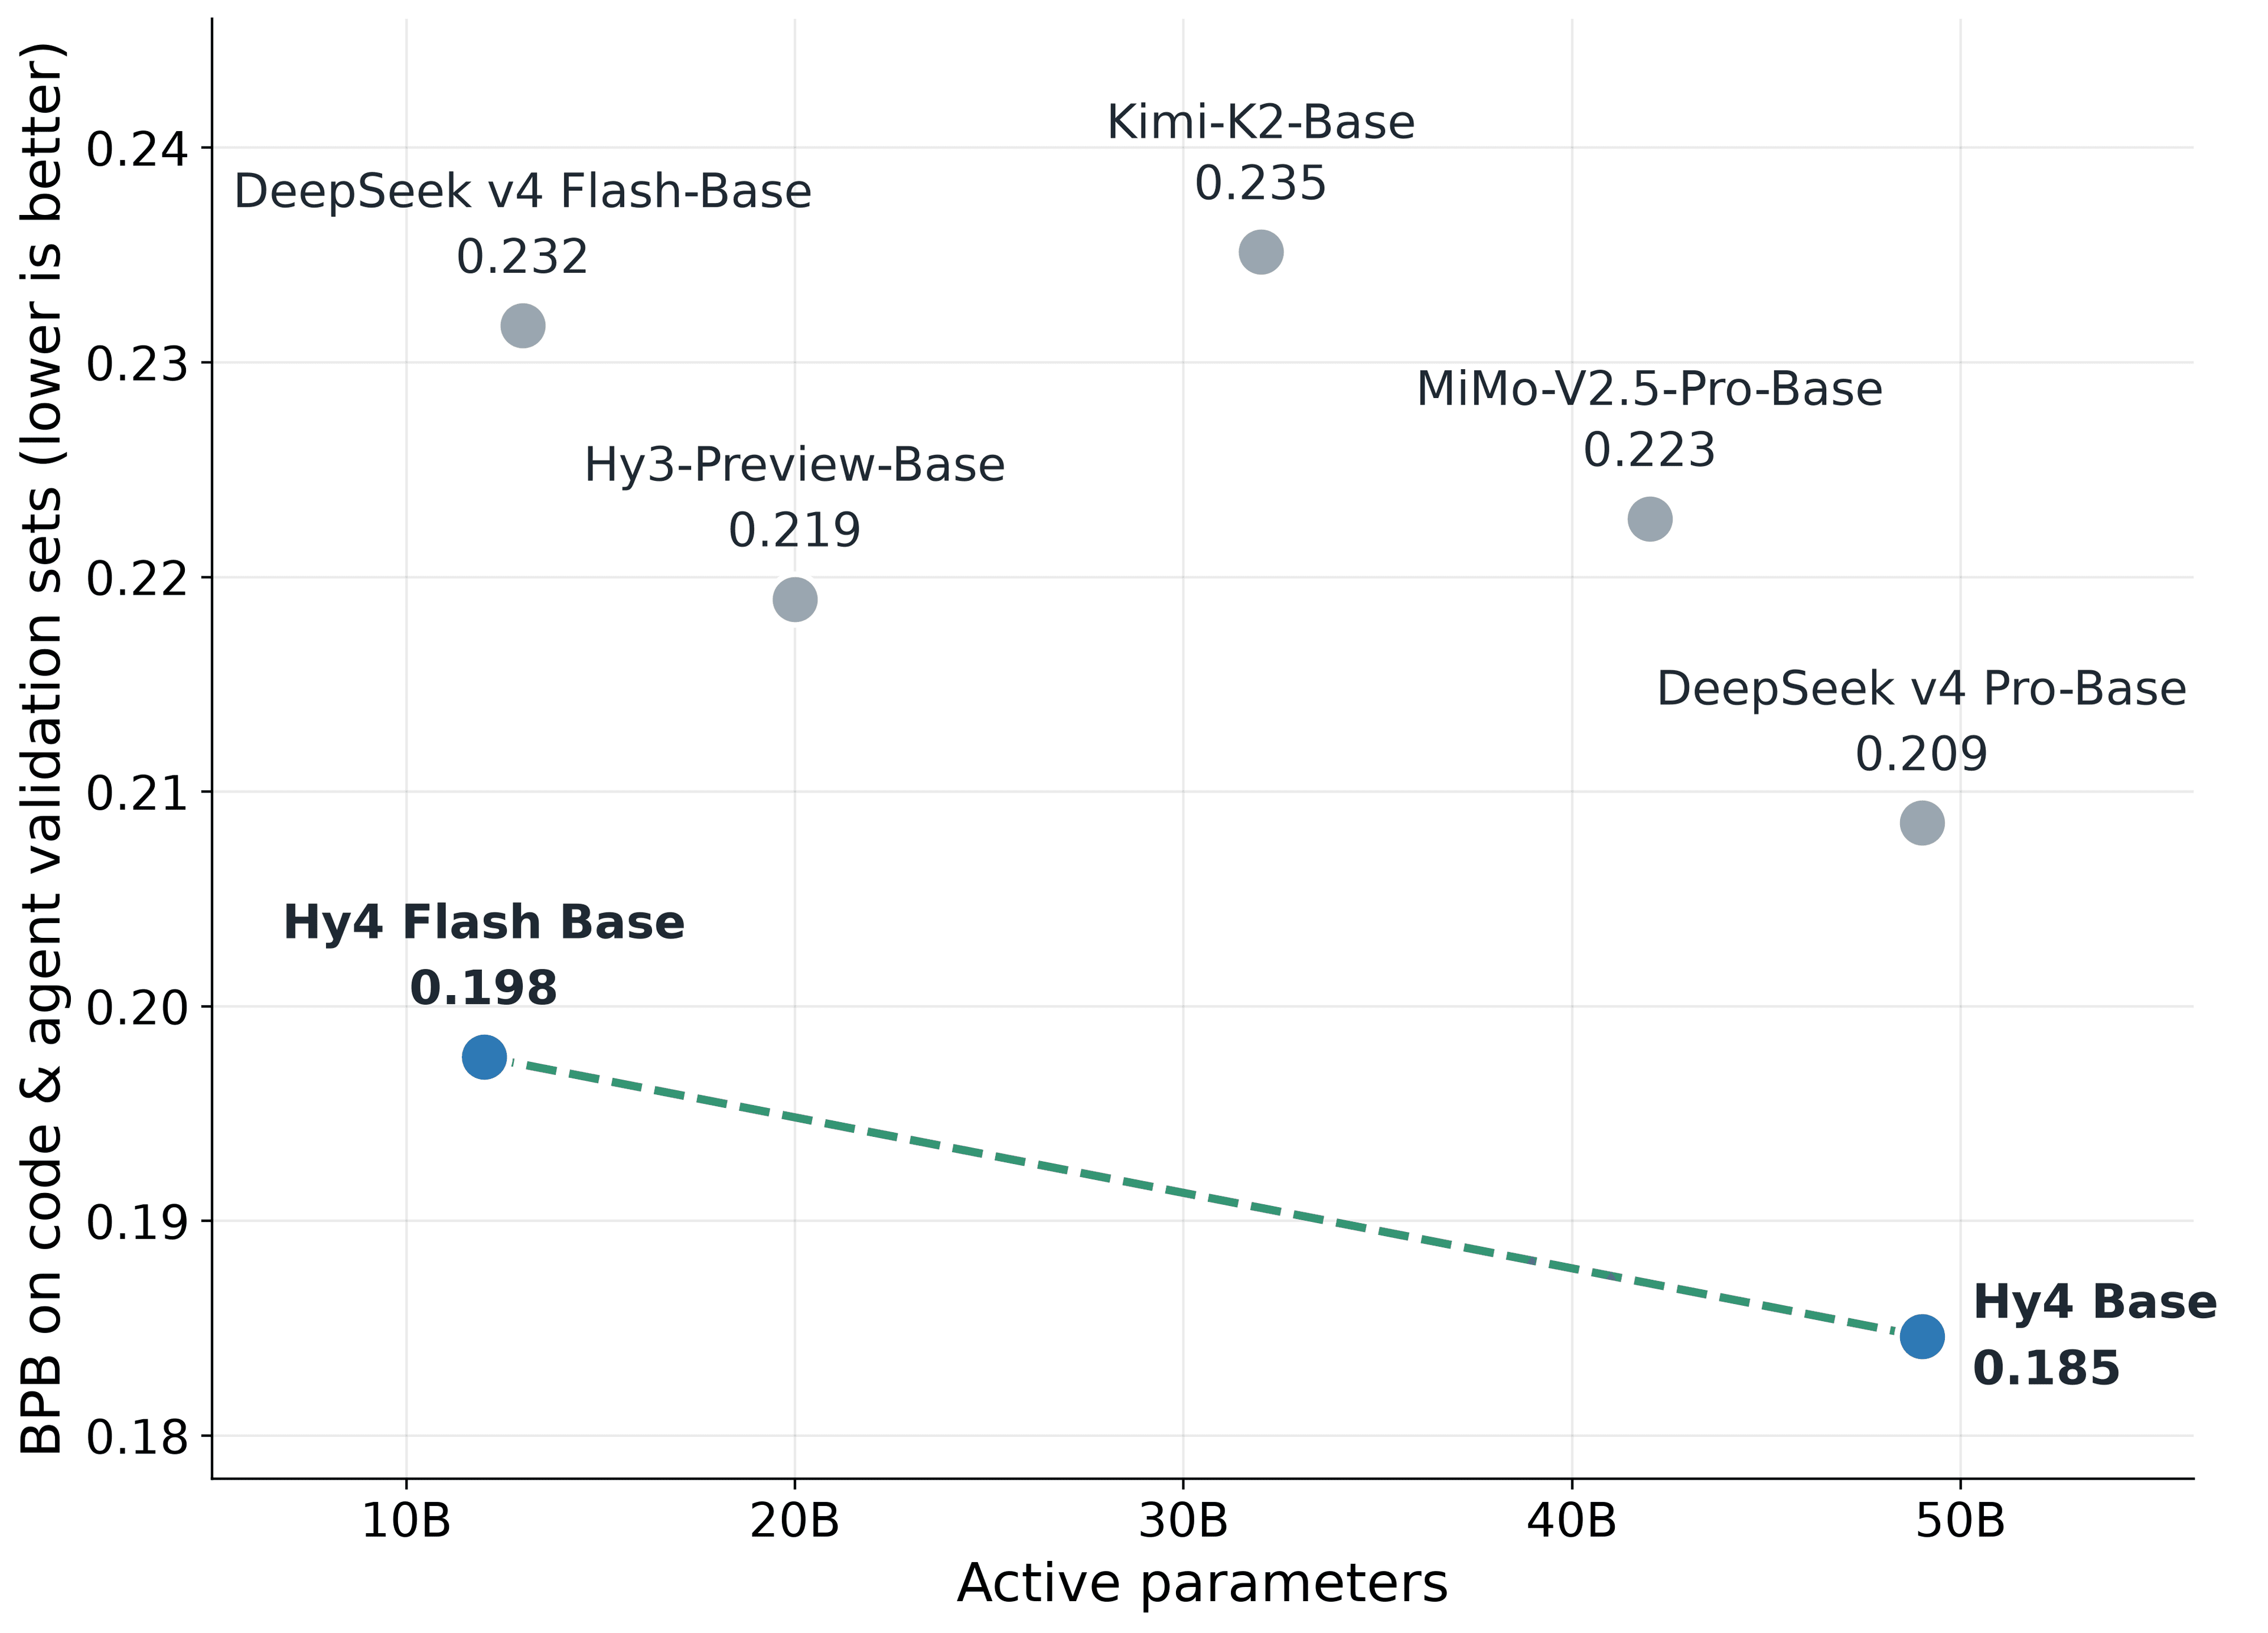
Tencent releases Hunyuan Hy4, an MoE vision-language model
The instruction-tuned, mixture-of-experts model handles both images and text under an open weights listing on Hugging Face.
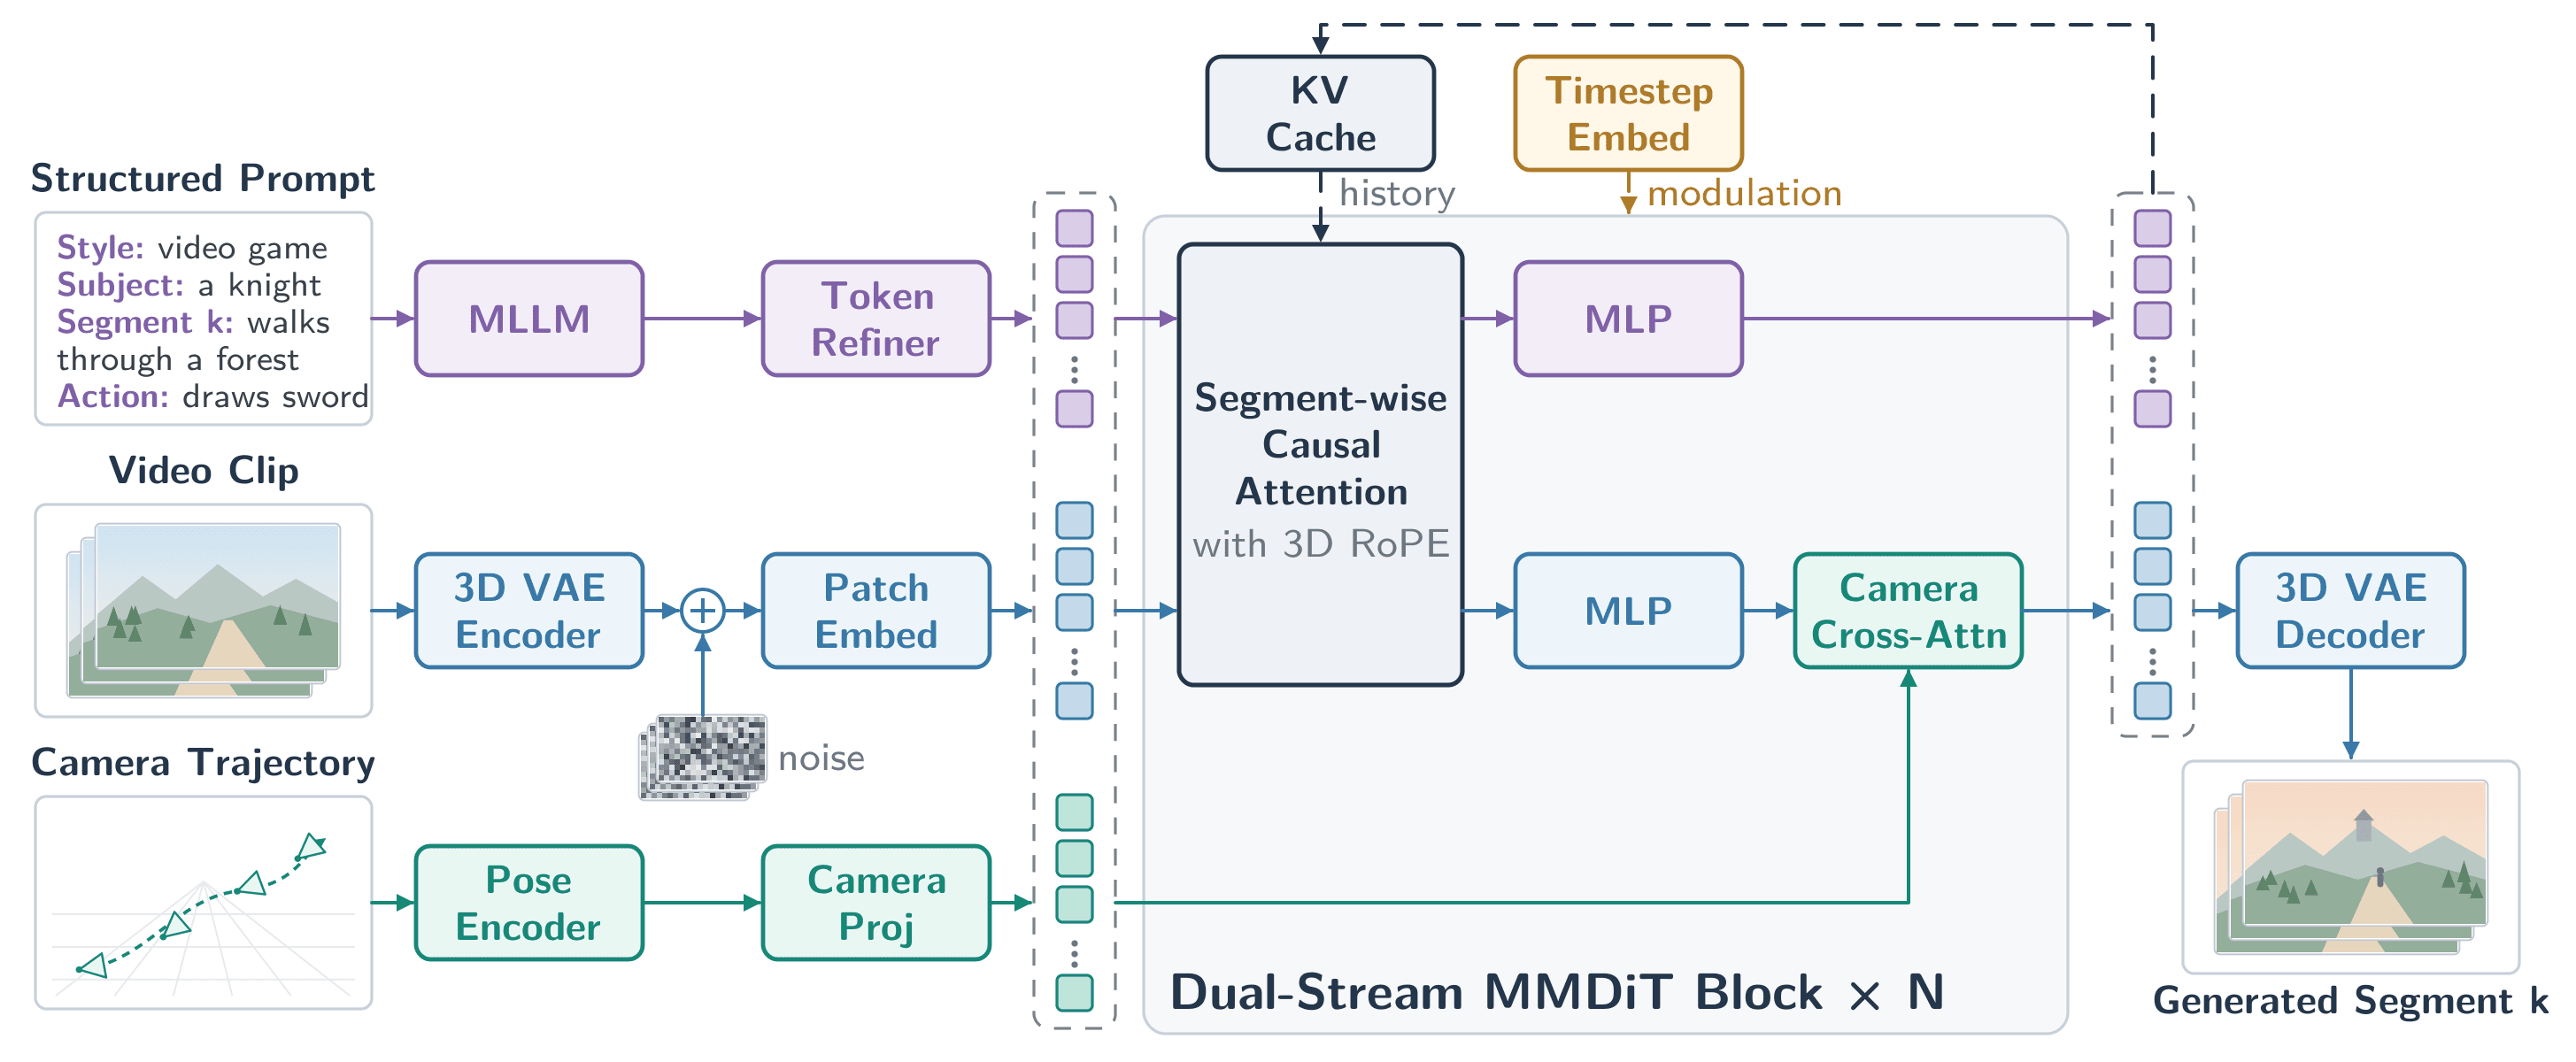
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
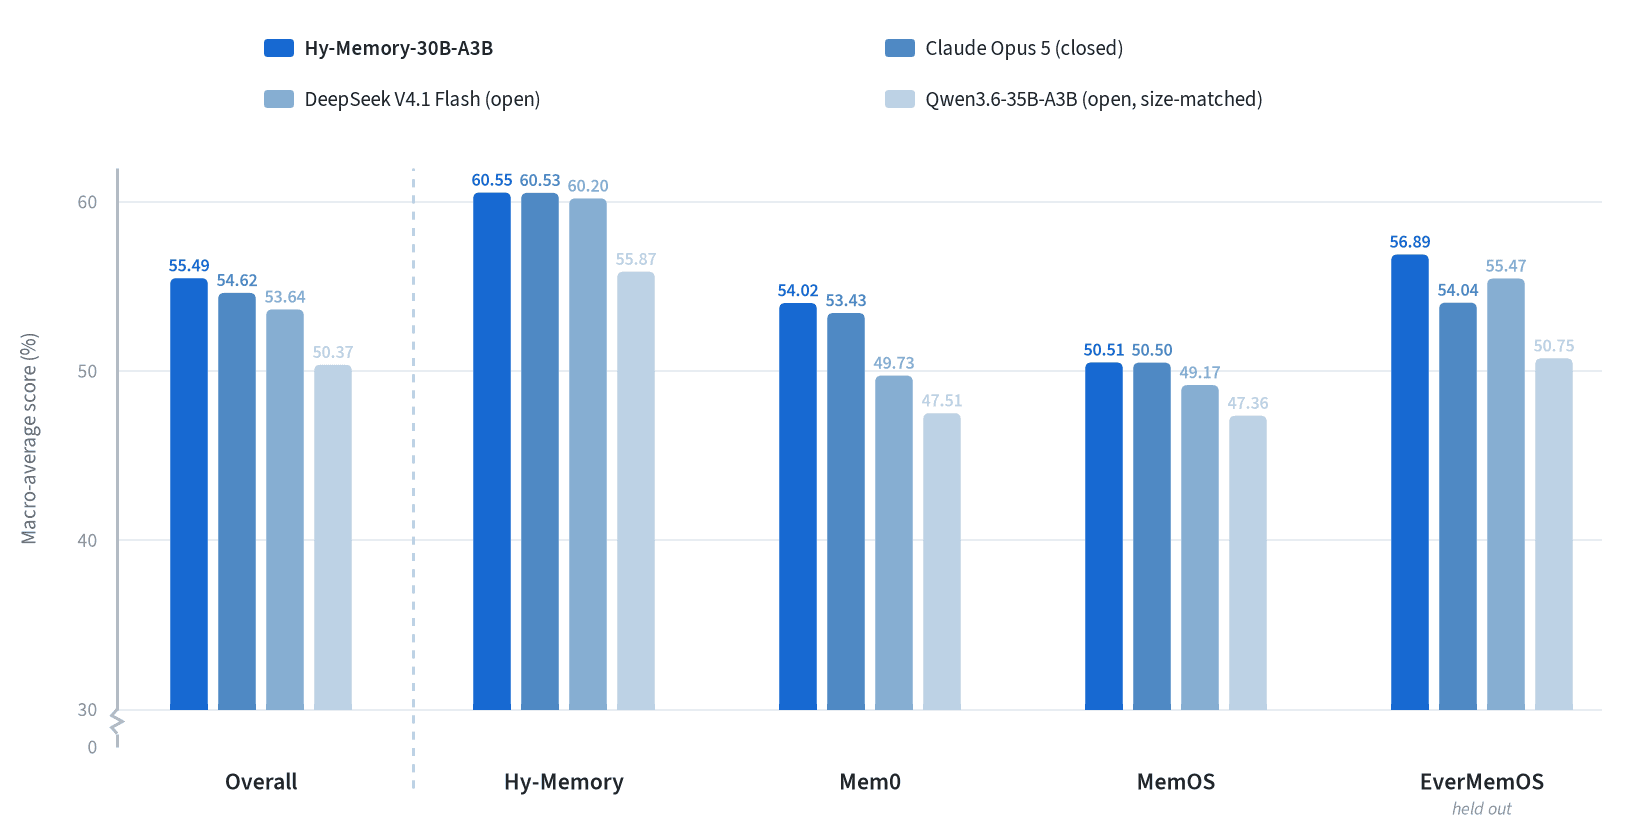
Tencent releases Hy-Memory 30B-A3B under Apache 2.0
A memory-focused mixture-of-experts model activates just 3B of its 30B parameters per token, and ships with a permissive license.
More in Vision-Language
All Vision-Language →
SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.
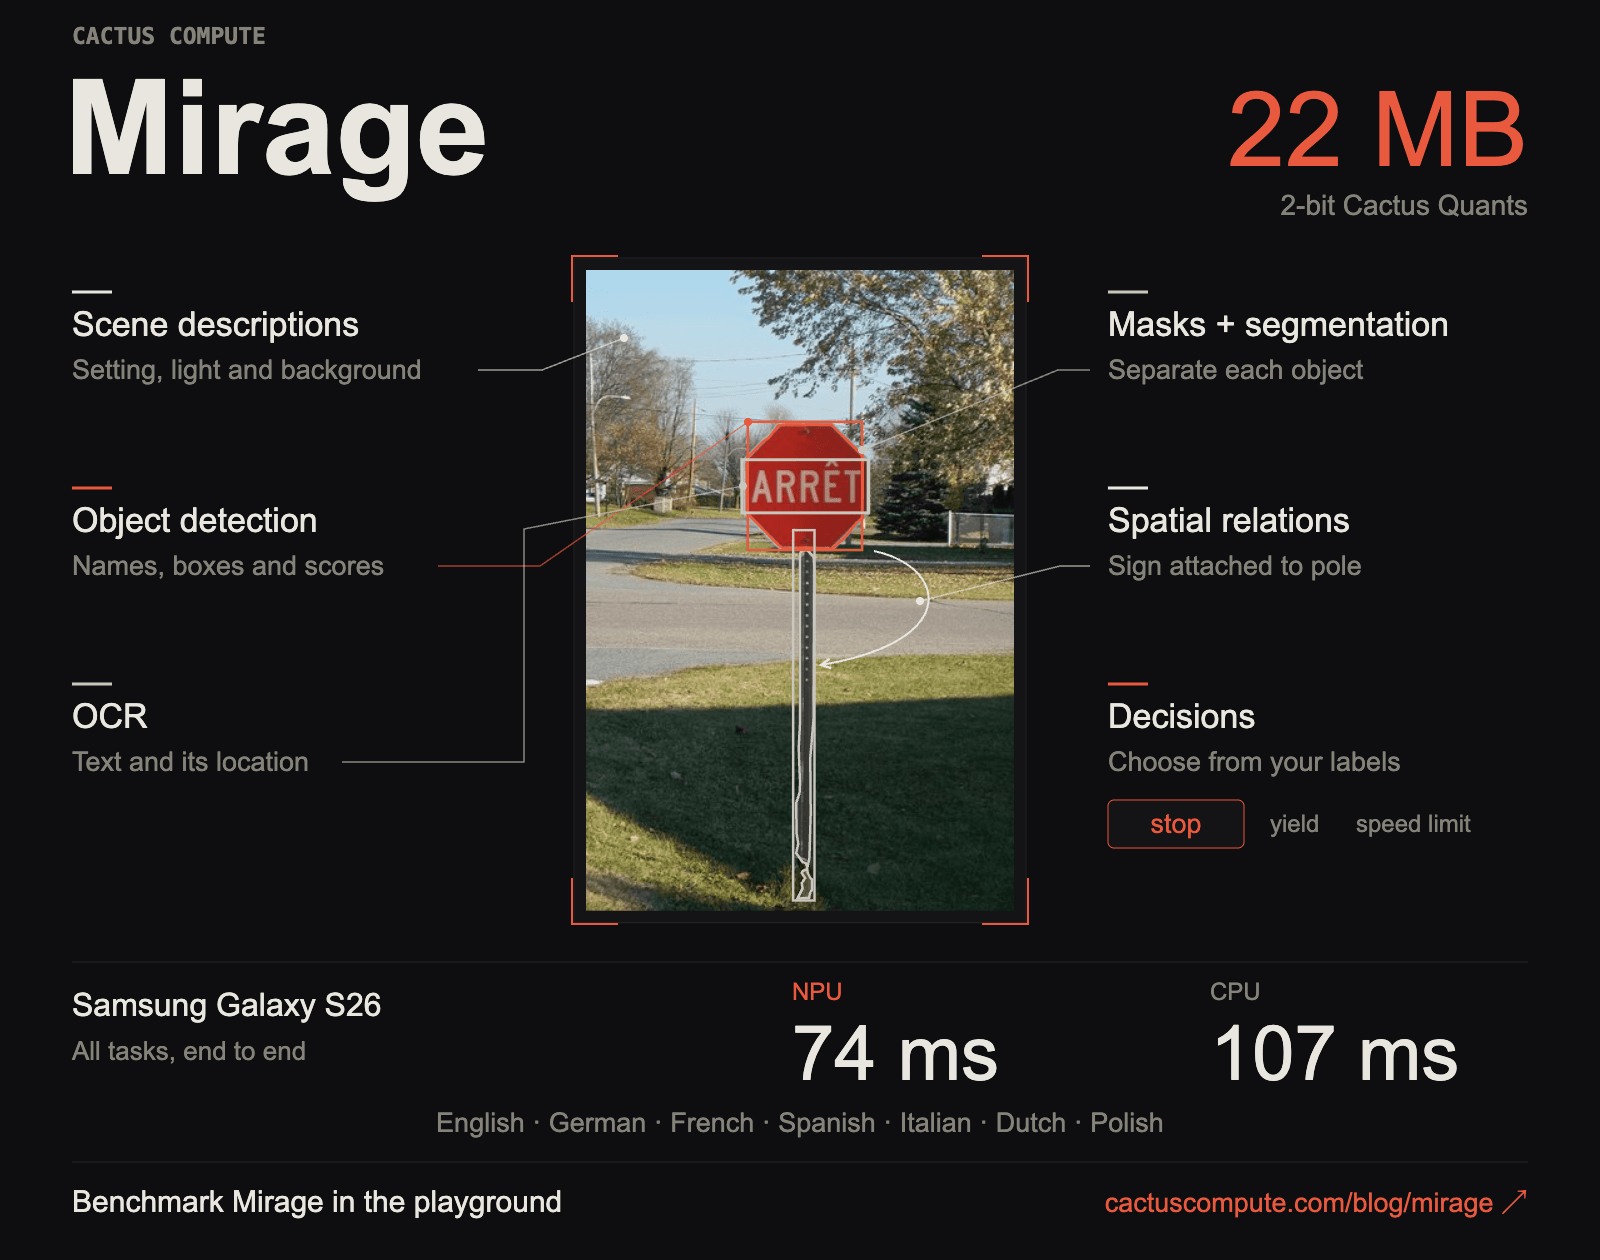
Cactus Compute's Mirage brings vision tasks on-device
The new open vision-language model targets detection, segmentation, and visual Q&A without relying on the cloud.
Thinking Machines ships Inkling-2-Small, an open MoE VLM
The Apache-2.0 vision-language model uses a mixture-of-experts design and lands openly on Hugging Face.
0 comments
No comments yet. Be the first to weigh in.