Apple's FastFrames-L Targets Real-Time Video Generation
The company's new autoregressive text-to-video model aims for interactive latency, a notable shift for a field still dominated by slow batch rendering.
Apple has published FastFrames-L on Hugging Face, an autoregressive text-to-video model designed to generate frames at interactive latency rather than in slow, offline batches. The release marks a visible step by Apple into the increasingly crowded open video generation space.
The headline idea is responsiveness. Most diffusion-based video systems produce a clip after a lengthy denoising process, which makes them unsuitable for anything resembling real-time interaction. By contrast, FastFrames-L uses an autoregressive approach—predicting video sequentially—with the stated goal of keeping latency low enough to feel interactive.
Why it matters
Interactive-latency generation opens doors that pre-rendered clips cannot:
- Live or responsive applications where a user steers output as it unfolds
- On-device or latency-sensitive scenarios that fit Apple's broader hardware ambitions
- A foundation for research into streaming, controllable video models
Several specifics remain unstated in the initial listing, including resolution, frame rate, maximum clip duration, and parameter count. The model carries a custom license, so teams planning to build on it should read the terms closely before committing.
For now, FastFrames-L reads as a research-forward release that signals where Apple sees video generation heading: away from slow rendering and toward systems fast enough to respond in the moment. Full details are available on the model's Hugging Face page.
Sources
- Visit
apple/FastFrames-L
Hugging Face
More from Apple
All Apple releases →
Apple's LensVLM-9B targets long-context vision tasks
A 9-billion-parameter vision-language model built on Qwen3.5-9B leans on visual-text compression to stretch its usable context.
More in Text → Video
All Text → Video →NVIDIA's Cosmos 3 Brings Open Interactive World Models
The new open release pushes beyond passive video generation toward simulated worlds that respond to input.
NVIDIA Releases Cosmos 3 for World Simulation
The new open models push NVIDIA's world-foundation effort toward interactive, real-time video generation.
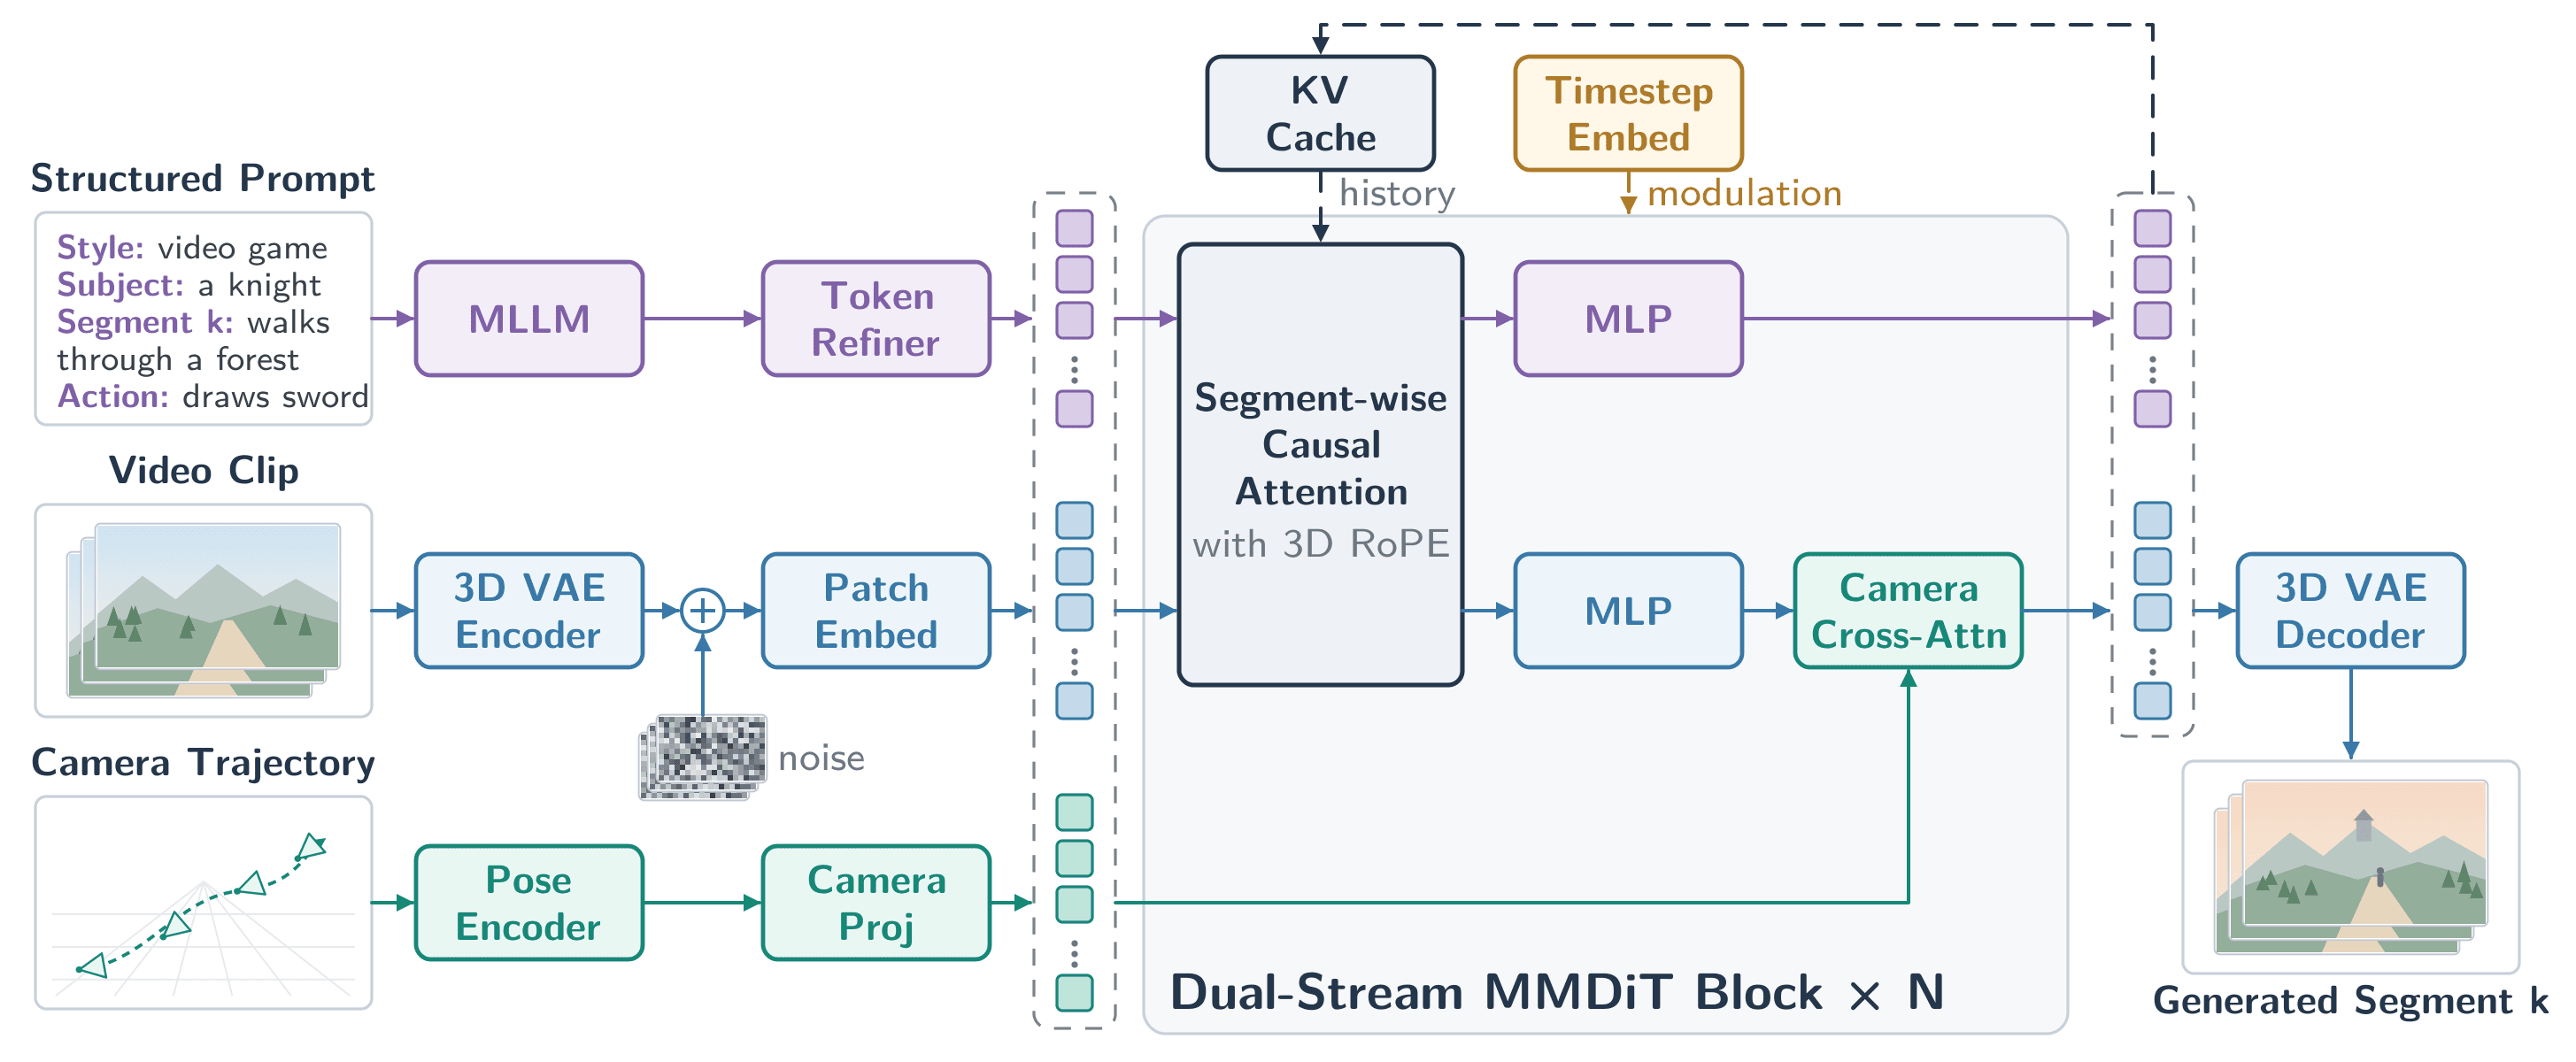
Tencent Releases Hy-Nomas, an Interactive Video World Model
The open-weights model pairs text- and image-to-video generation with action-aware causal attention and explicit camera control.
0 comments
No comments yet. Be the first to weigh in.