Apple's LensVLM-9B targets long-context vision tasks
A 9-billion-parameter vision-language model built on Qwen3.5-9B leans on visual-text compression to stretch its usable context.
Apple has published LensVLM-9B, a vision-language model that pairs image understanding with text generation and is aimed squarely at long-context multimodal workloads. The model is available on Hugging Face at apple/LensVLM-9B.
At 9 billion parameters, LensVLM sits in the increasingly crowded mid-size tier where capability and deployability meet. It is a dense model — not a mixture-of-experts design — built on the Qwen3.5-9B foundation, a common pattern as labs adapt strong open text backbones for multimodal use rather than training from scratch.
Why it matters
The headline feature is visual-text compression, a technique meant to pack more visual and textual information into the same context budget. For document-heavy and multi-image tasks, that compression is what makes long-context vision practical without runaway memory costs.
- Modality: vision-language (VLM)
- Base model: Qwen3.5-9B
- Size: 9B parameters, dense
- Focus: long context and visual-text compression
Apple has released the model under an "other" license, so teams will want to read the terms on the model card before building on it. Key specifics such as context length and benchmark results aren't detailed in the release record, and the Hugging Face page remains the authoritative reference as those details firm up.
Sources
- Visit
apple/LensVLM-9B
Hugging Face
More in Vision-Language
All Vision-Language →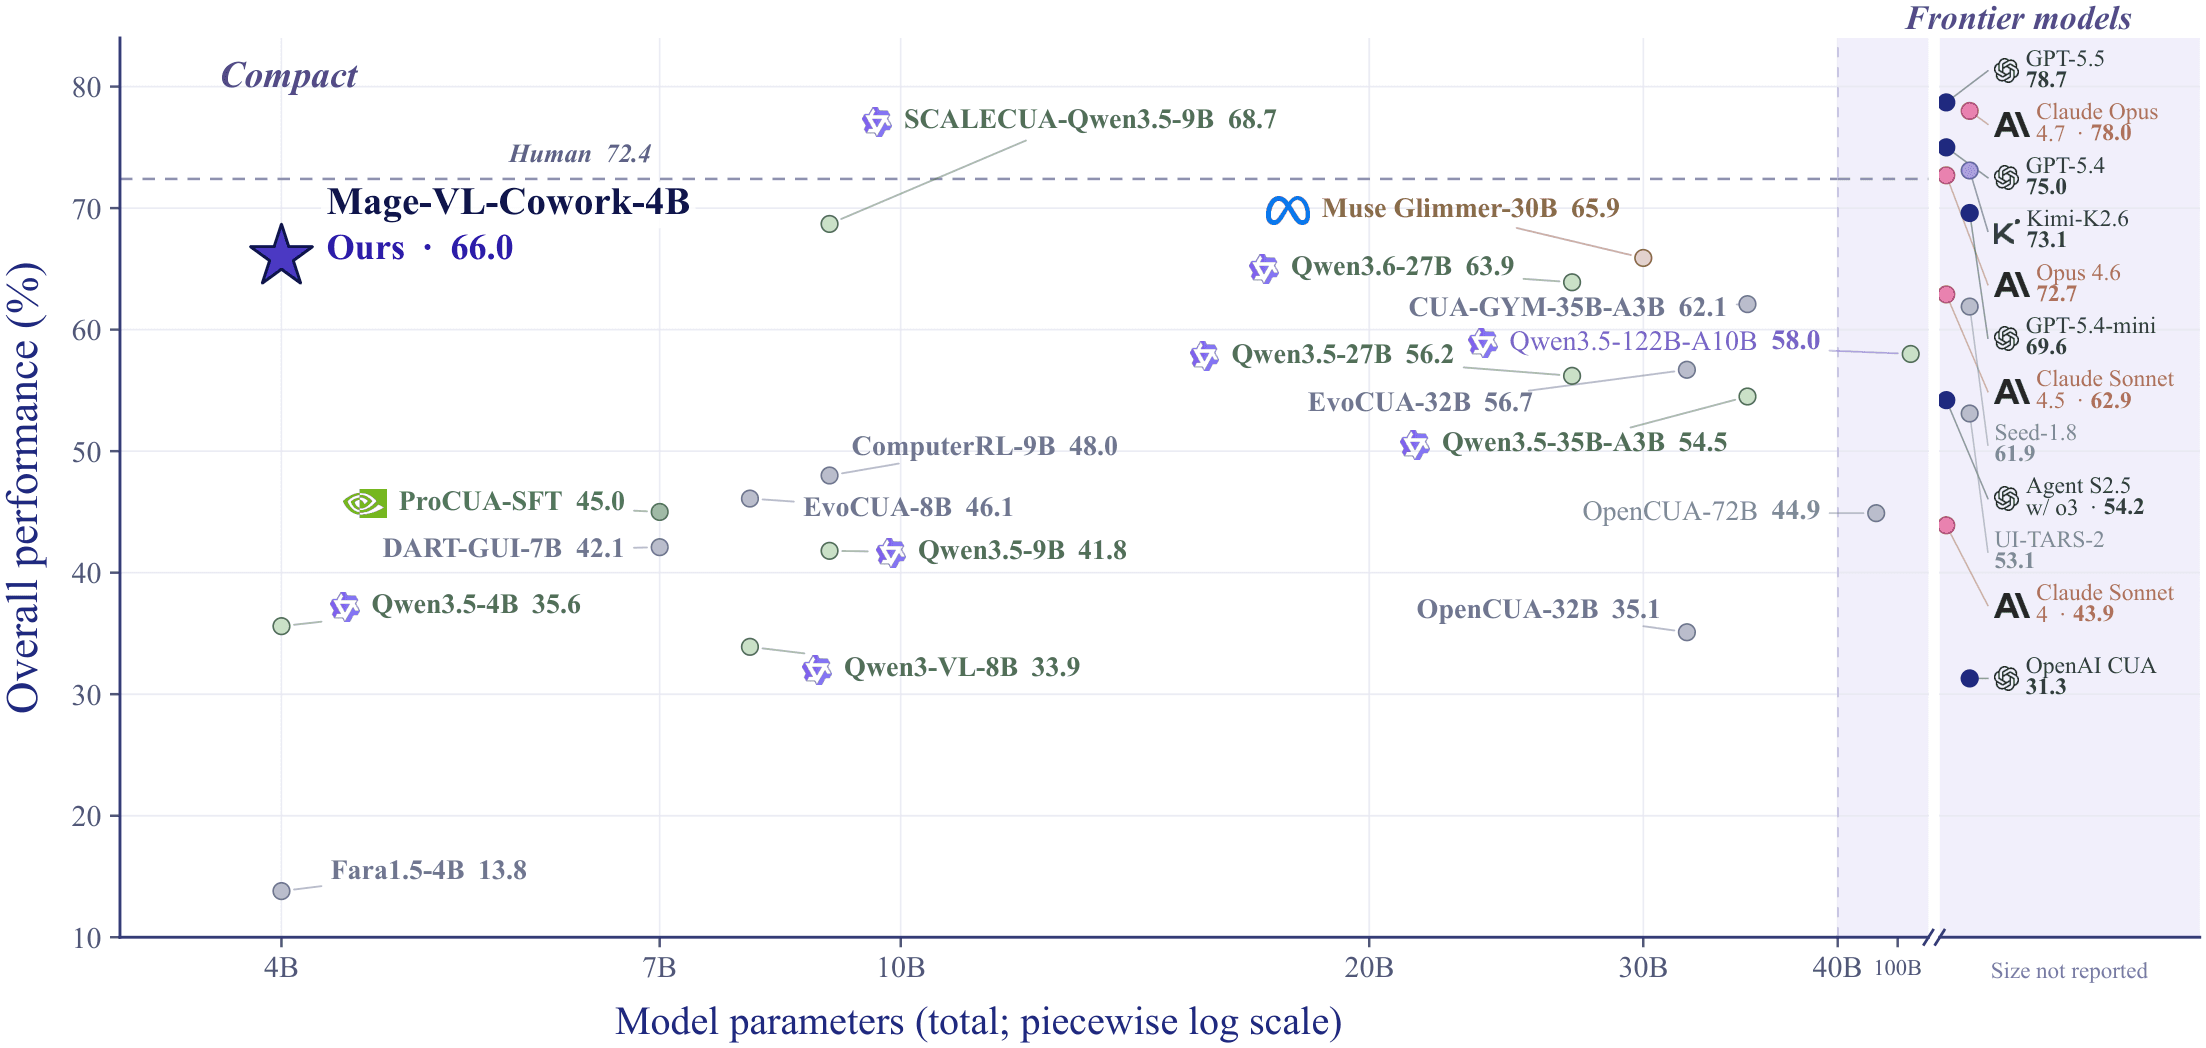
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.
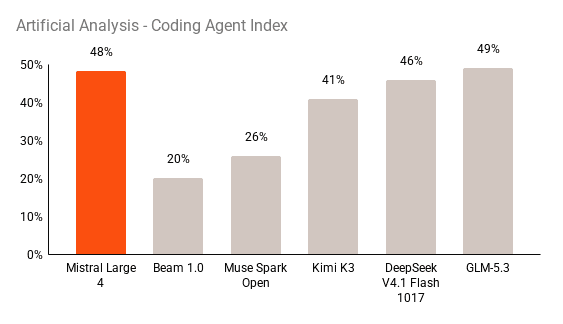
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.
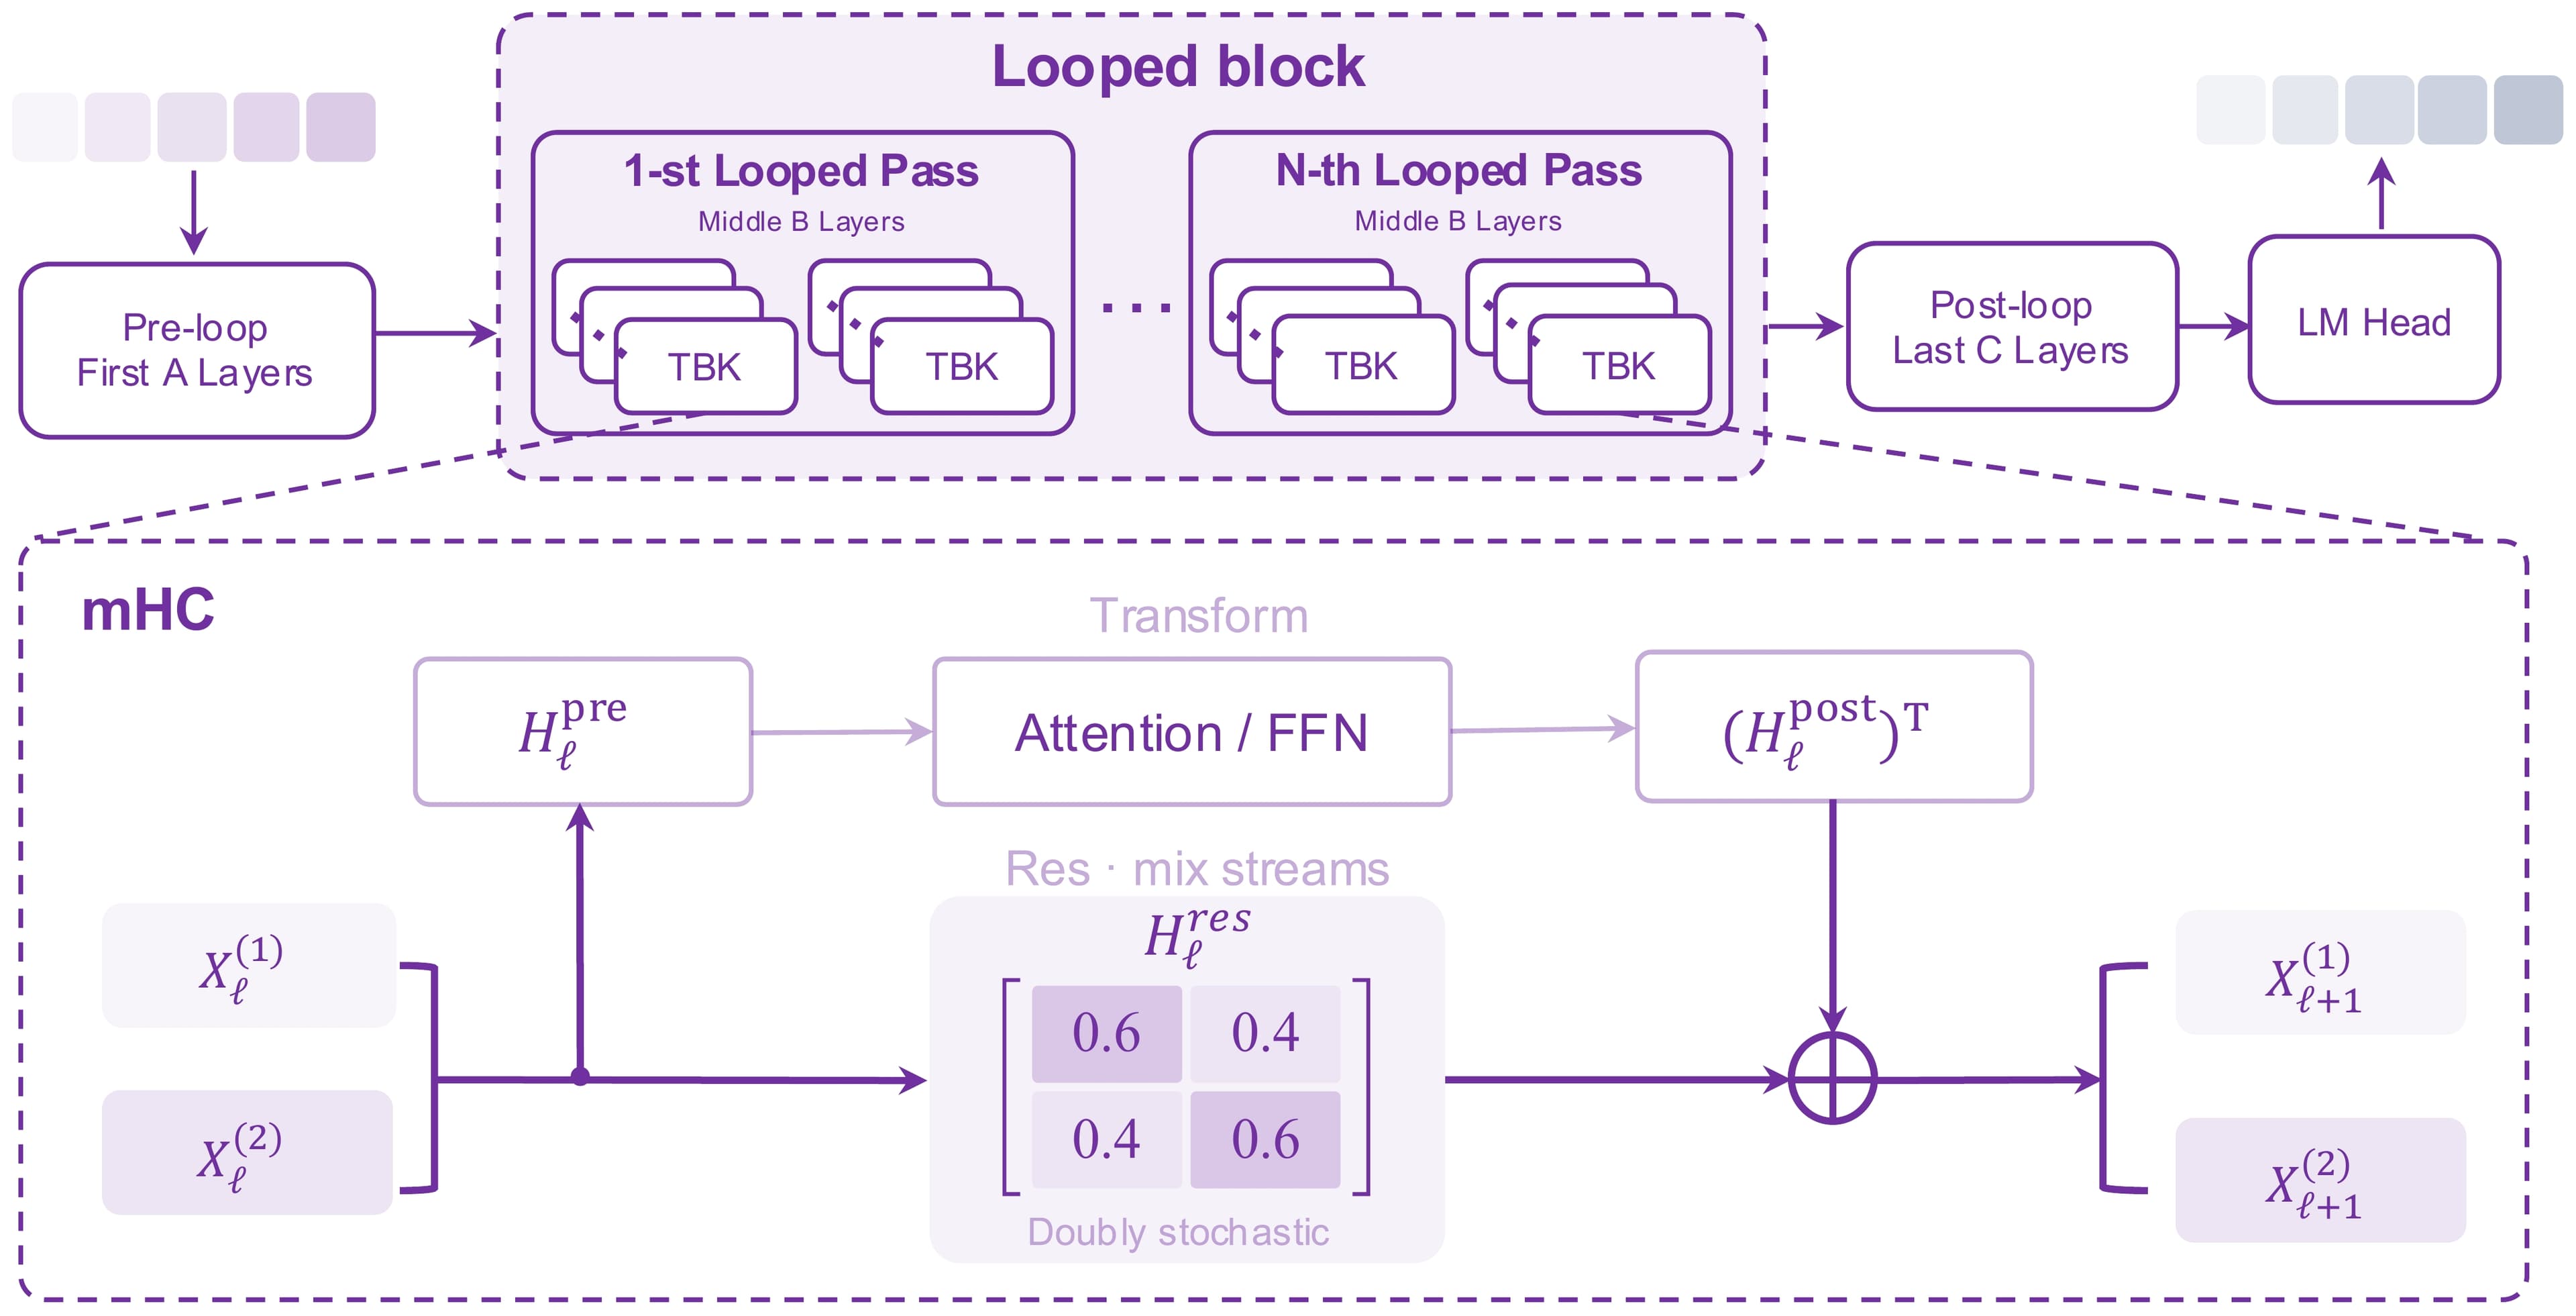
SenseTime previews a 9B looped-transformer VLM
SenseNova-Loop-9B-Preview puts a recurrent-depth architecture to work on multimodal reasoning.
0 comments
No comments yet. Be the first to weigh in.