Xiaomi distills MiMo V2.6 into a 9B model
The new MiMo-V2.6-Distill-Qwen-9B targets agentic workloads, coding, and tool use in a size that fits on modest hardware.

Xiaomi has published MiMo-V2.6-Distill-Qwen-9B, a nine-billion-parameter model distilled from the company's larger MiMo V2.6 system. The release is aimed squarely at agentic behavior, coding, and tool-use scenarios rather than general chat, and it builds on a Qwen base to reach that footprint.
Distillation is the core idea here: instead of training a small model from scratch, Xiaomi transfers behavior from a stronger teacher model into a more compact student. The payoff is a model that can run on far less demanding hardware while retaining a slice of the capabilities that make bigger systems useful for multi-step tasks.
Why it matters
Much of the practical demand for open models sits in the 7B–13B range, where a single consumer or workstation GPU is enough to serve real workloads. A 9B model tuned for agents and tool calling slots neatly into that gap.
- Sized for accessible hardware in the 7B–13B tier
- Focused on agentic, coding, and tool-use tasks
- Distilled from Xiaomi's MiMo V2.6 rather than trained fresh
- Built on a Qwen base and released on Hugging Face
The model is distributed under a custom license, so teams planning to build on it should check the terms on the model page before deploying. As with any distilled release, the real test will be how much of the parent model's agentic strength survives the shrink.
Sources
- Visit
XiaomiMiMo/MiMo-V2.6-Distill-Qwen-9B
Hugging Face
More from Xiaomi
All Xiaomi releases →Xiaomi's MiMo-V2.6 bets on RL for self-improvement
The omni-modal model family leans on reinforcement learning to push reasoning without endless new supervised data.
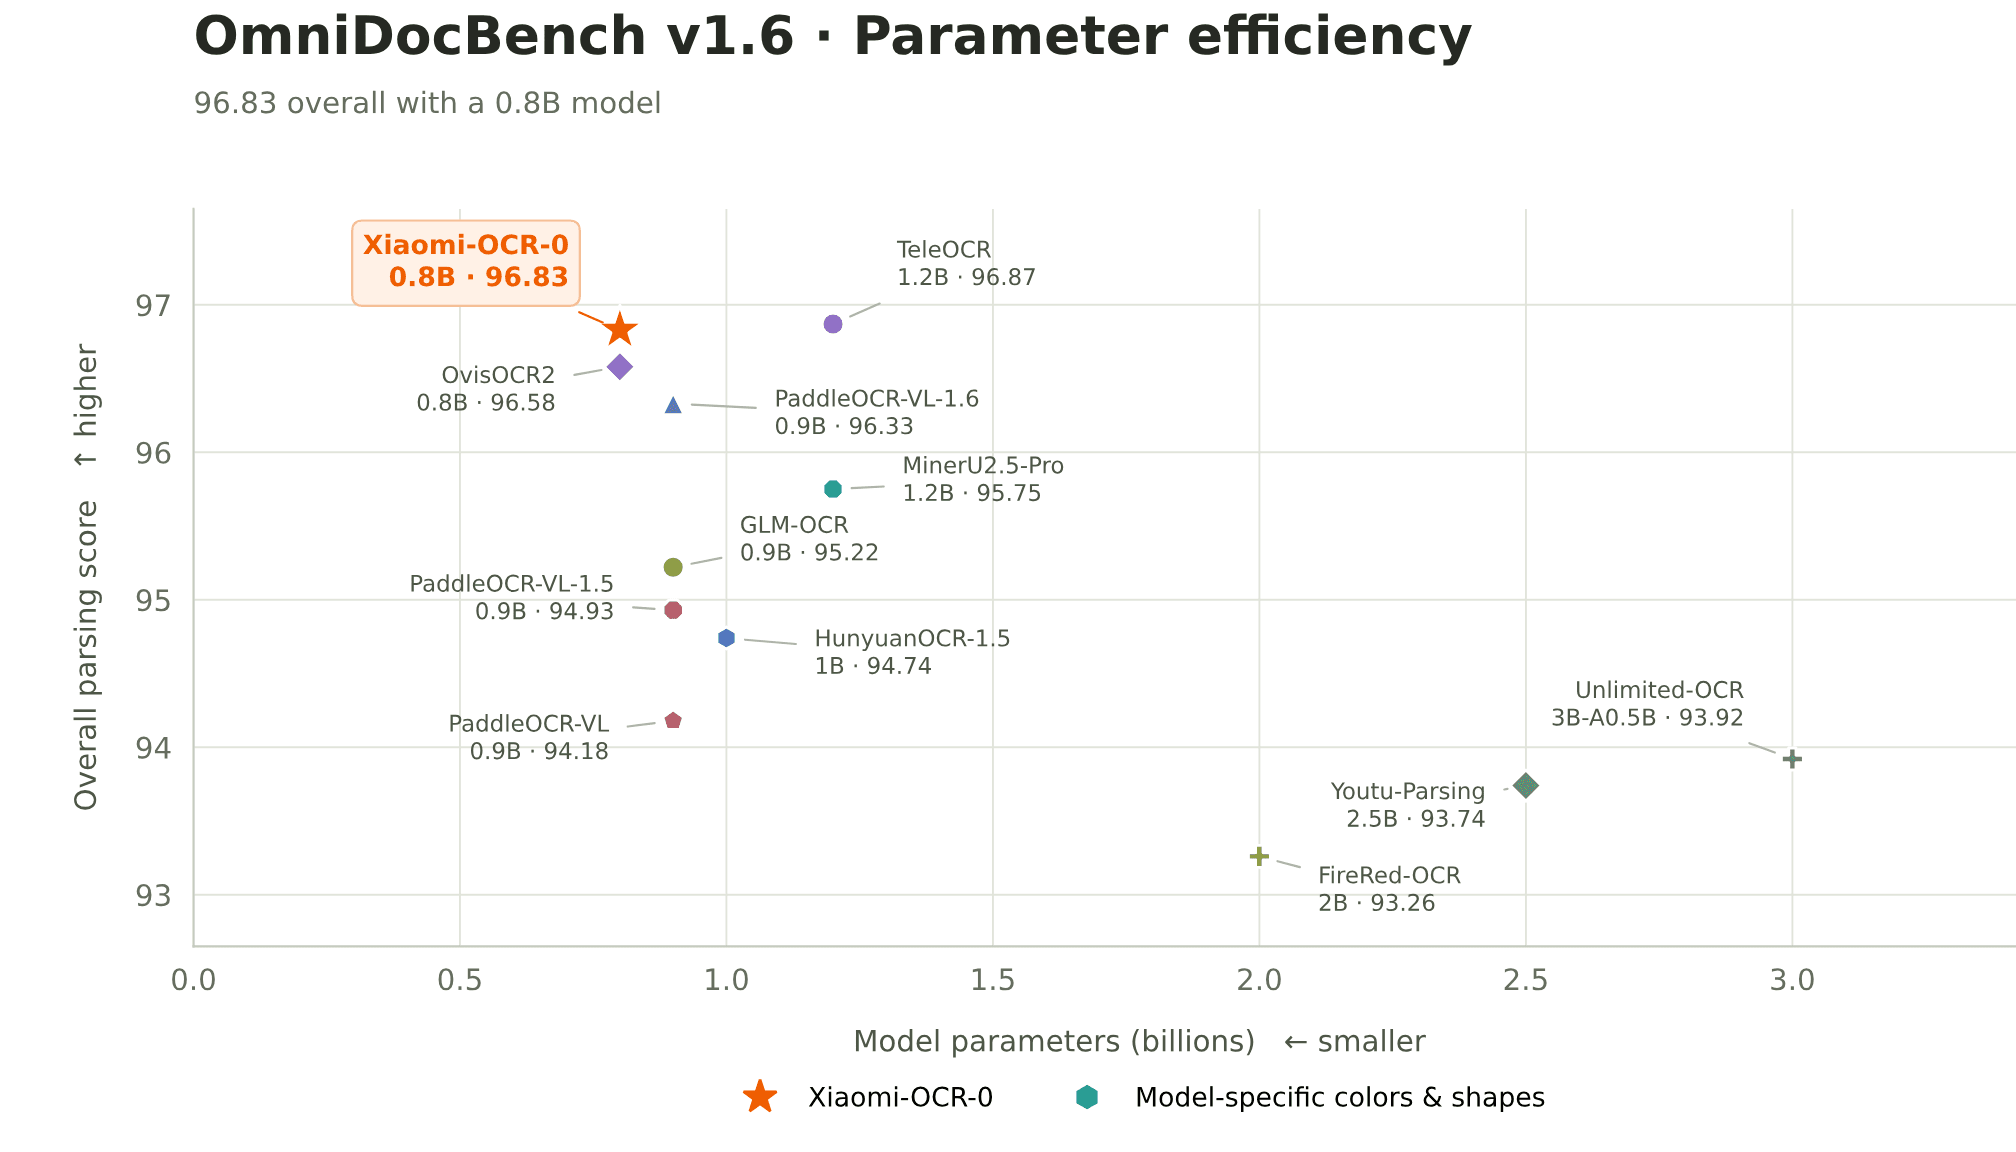
Xiaomi Enters Document OCR With New Vision Model
The company's research arm releases Xiaomi-OCR-0, a document-parsing vision-language model built on a Qwen3.5 backbone.
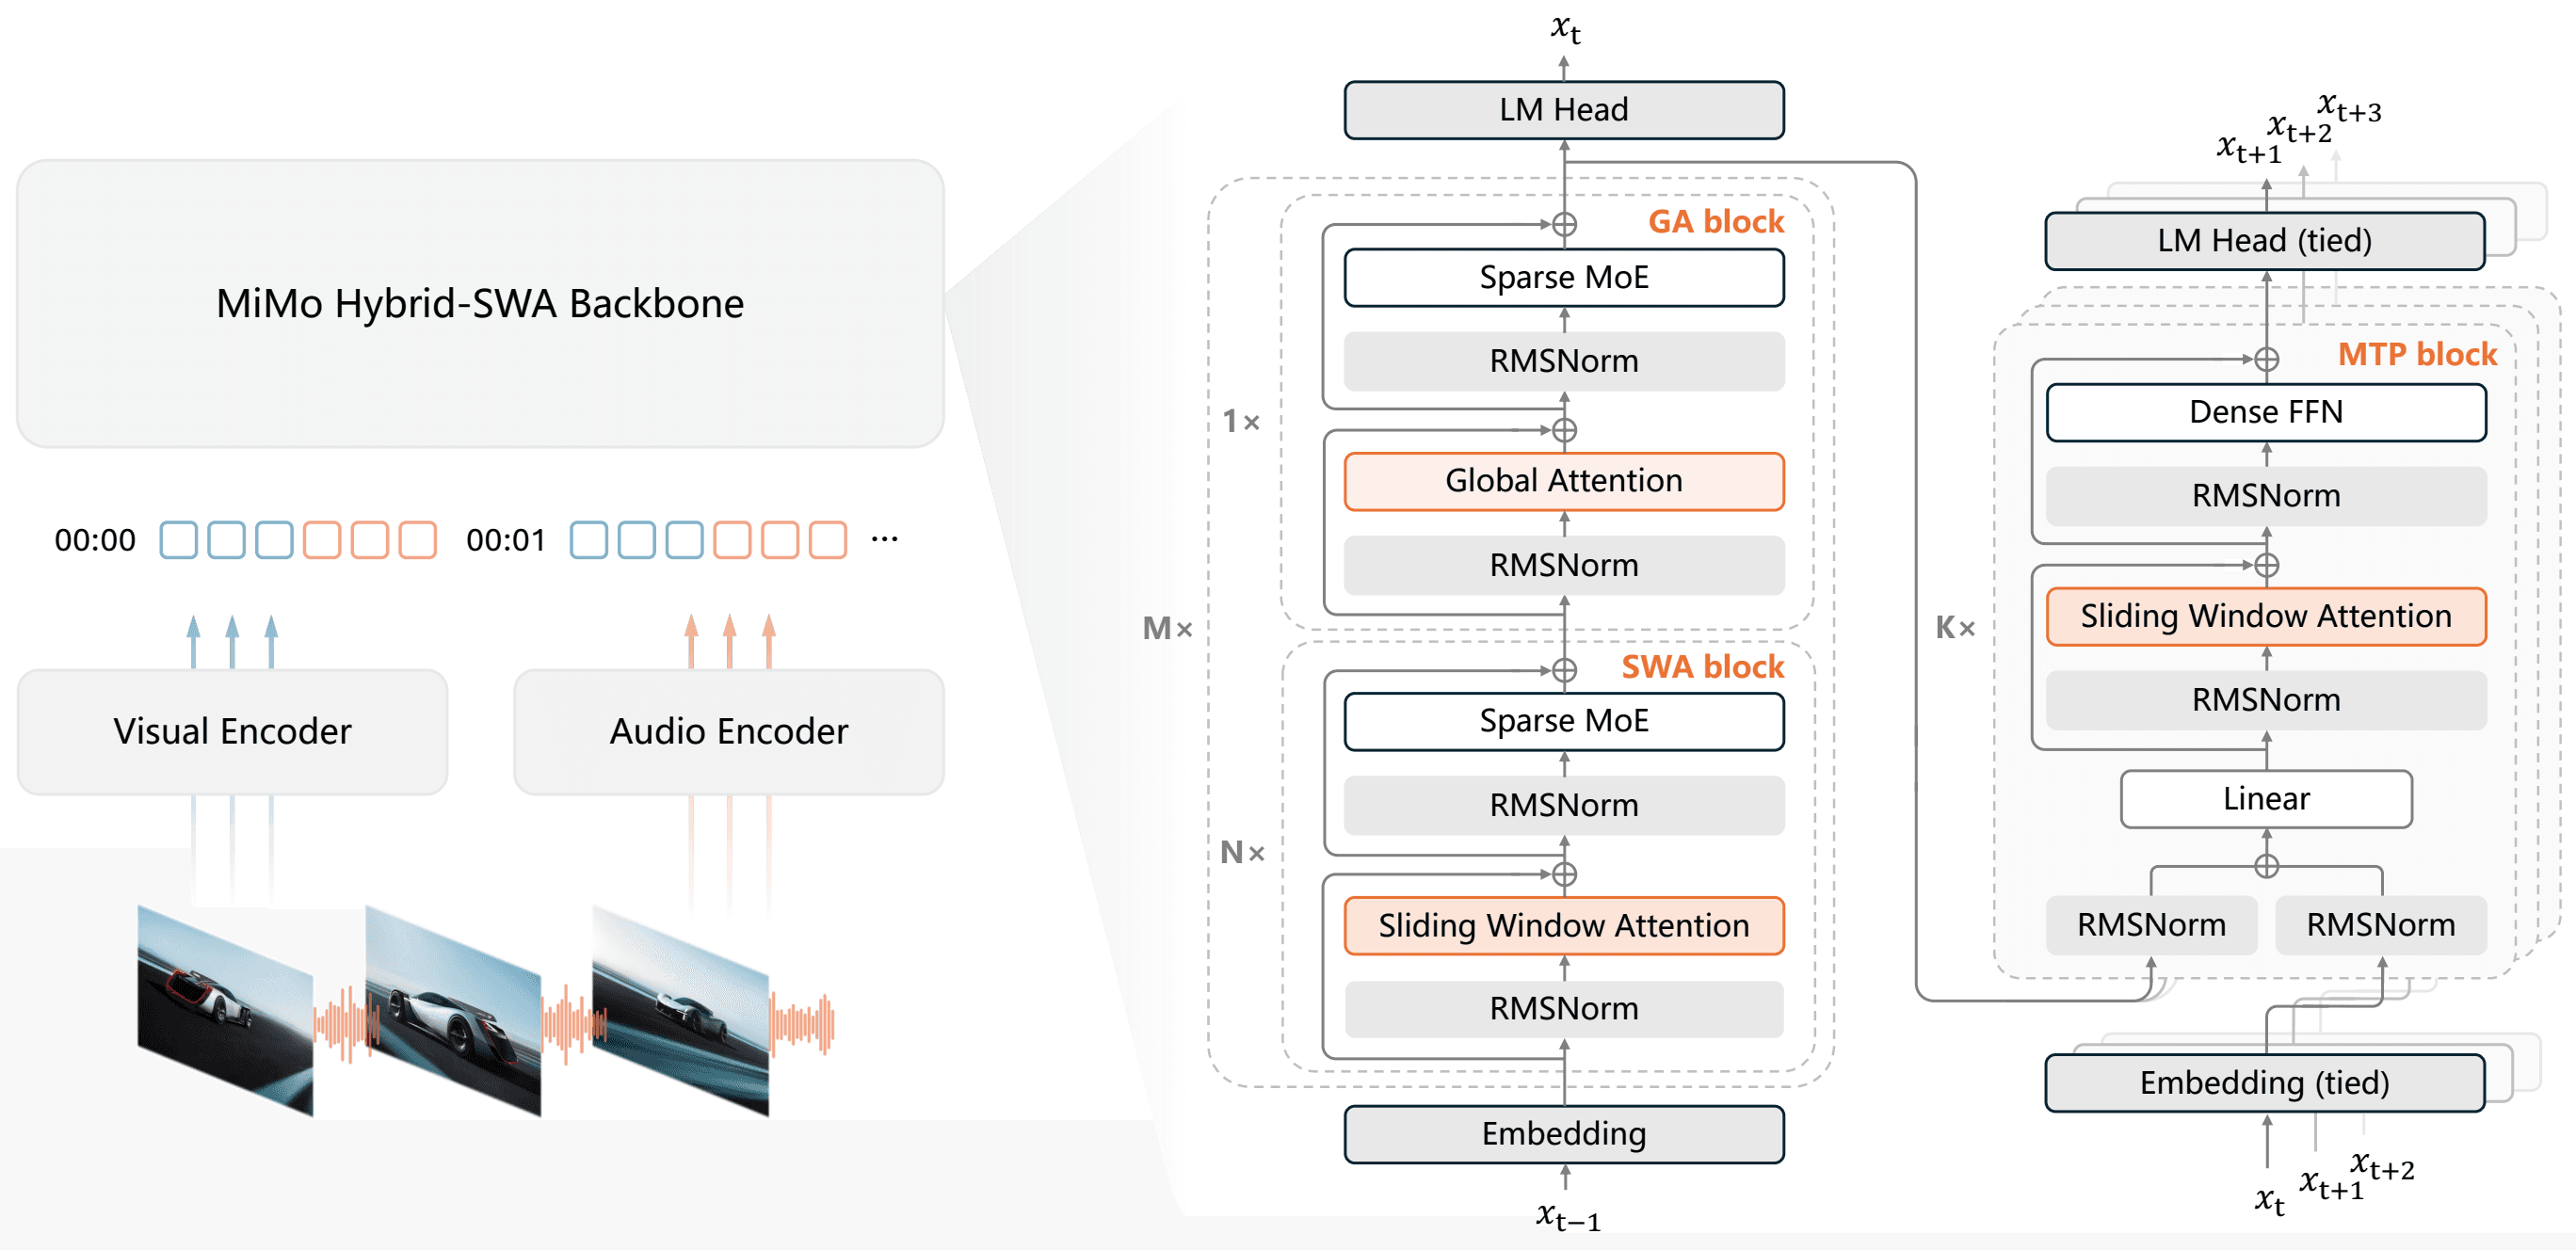
Xiaomi expands MiMo line with V2.6 multimodal models
The new Flash, Pro, and Distill variants add vision, audio, agentic behavior, and long-context handling to Xiaomi's open MiMo family.
More in Vision-Language
All Vision-Language →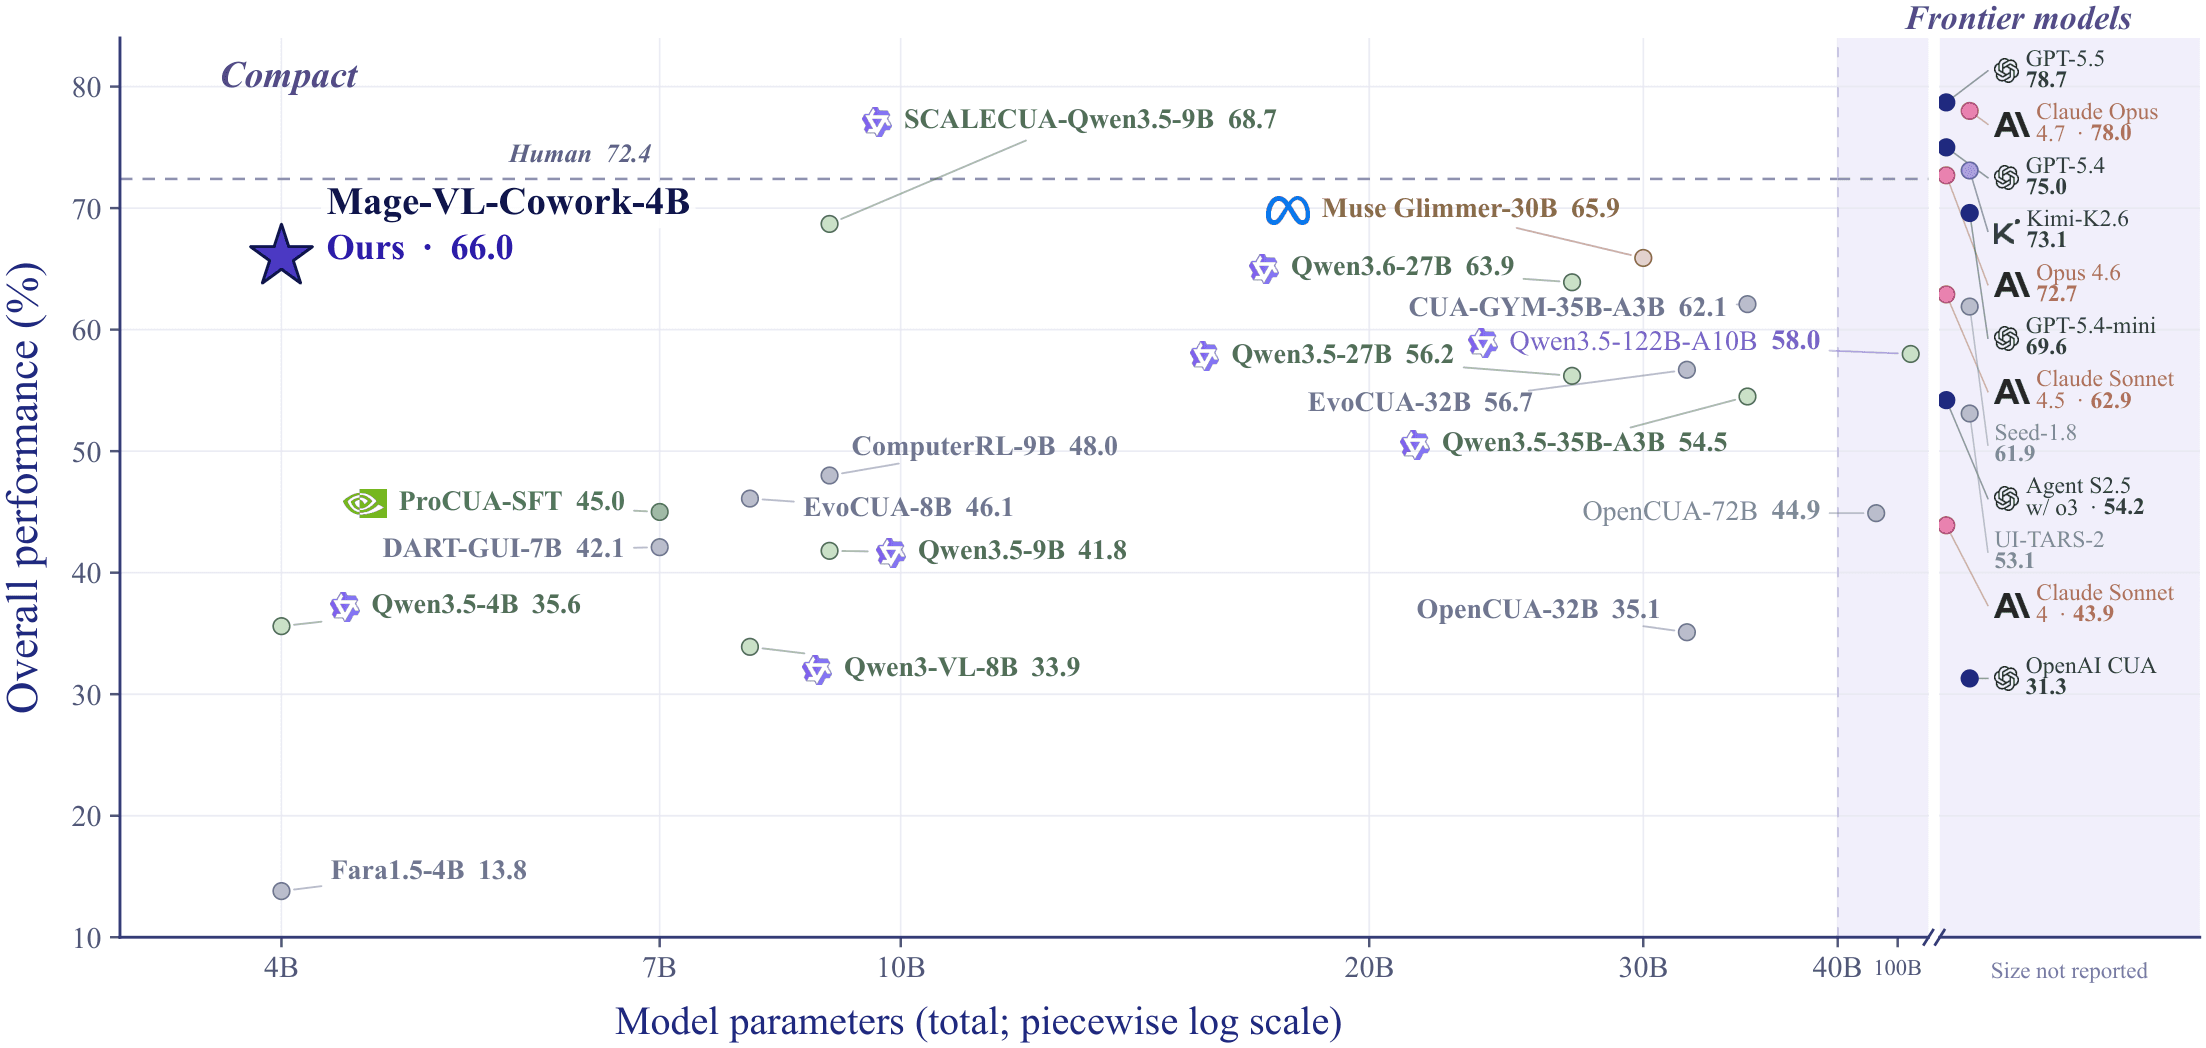
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.
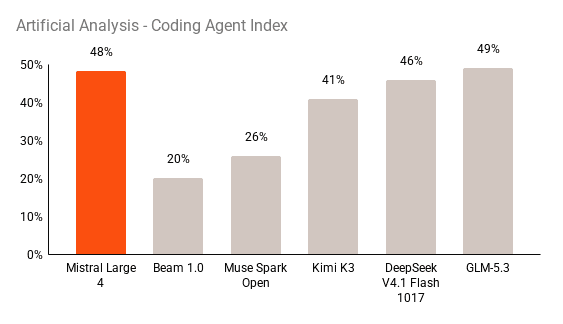
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.
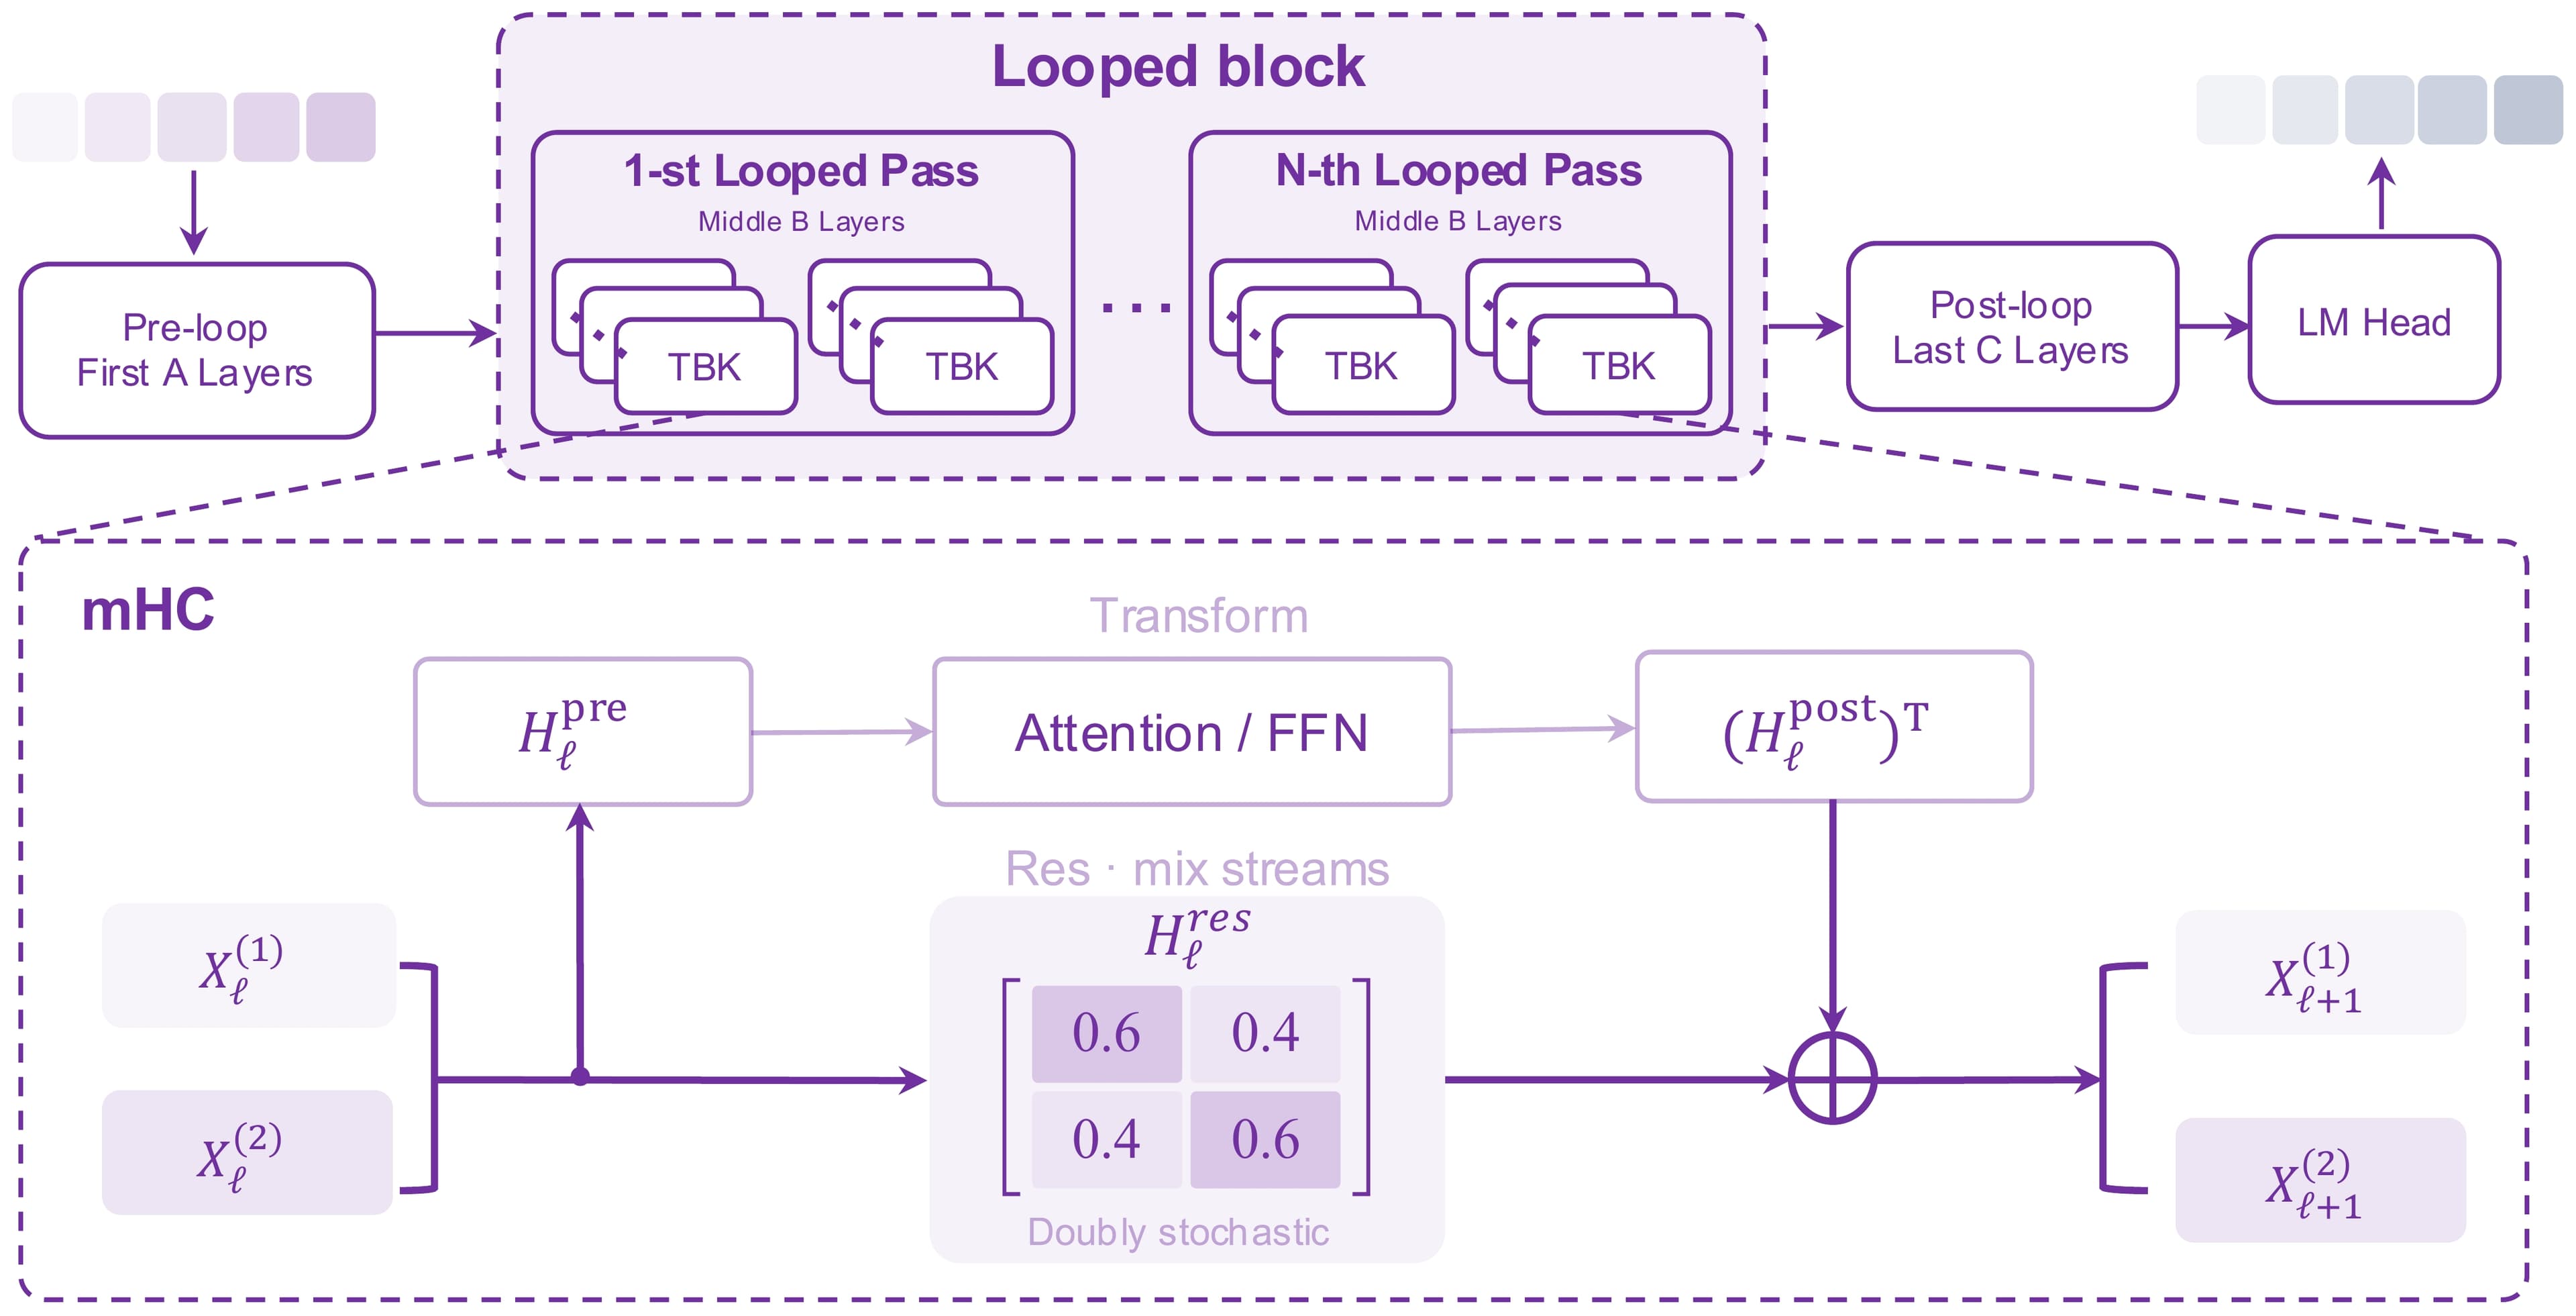
SenseTime previews a 9B looped-transformer VLM
SenseNova-Loop-9B-Preview puts a recurrent-depth architecture to work on multimodal reasoning.
0 comments
No comments yet. Be the first to weigh in.