SenseTime previews a 9B looped-transformer VLM
SenseNova-Loop-9B-Preview puts a recurrent-depth architecture to work on multimodal reasoning.
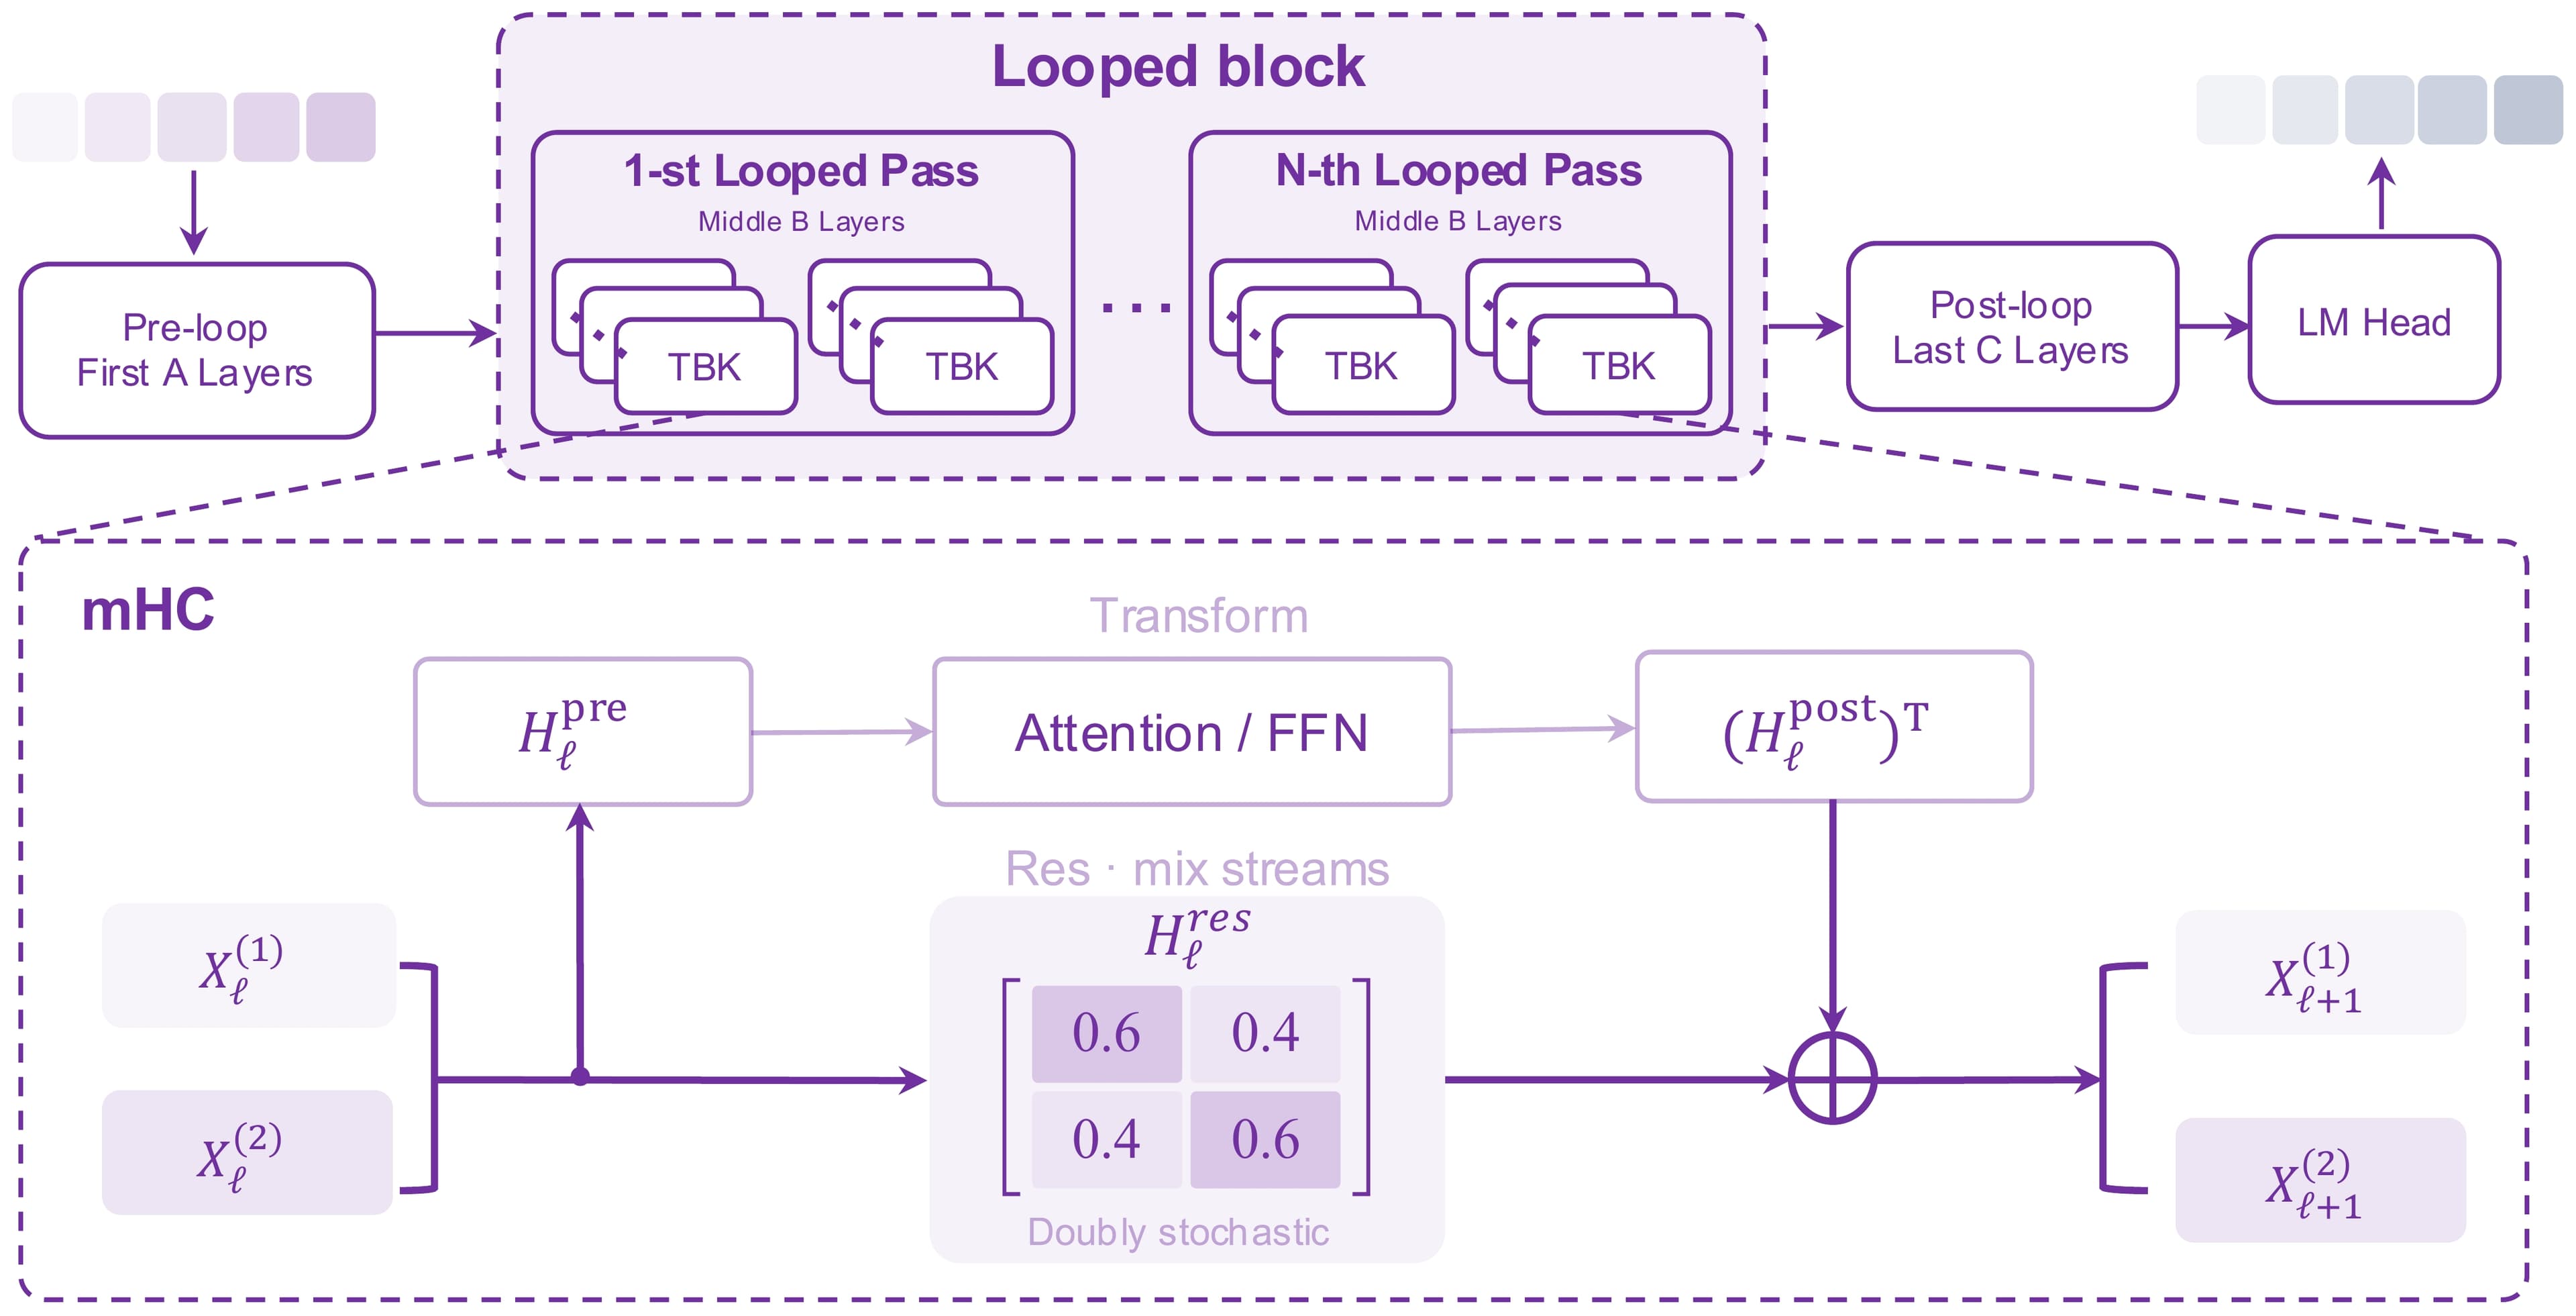
SenseTime has released an early look at SenseNova-Loop-9B-Preview, a 9-billion-parameter vision-language model that leans on a "looped" transformer design. The model is available now on Hugging Face, carrying a preview label that signals the work is still maturing.
The headline idea is architectural. Rather than simply stacking more layers, a looped transformer reuses a block of weights across multiple passes, trading raw parameter count for repeated computation at inference time. That approach can let a comparatively small model spend more effort on hard problems, which fits neatly with the model's billing as a multimodal reasoning system.
Why it matters
Most of the attention in open multimodal models has gone to scaling parameters and context windows. A recurrent-depth design points at a different lever:
- A dense 9B footprint that stays practical to run
- Extra reasoning capacity drawn from looping rather than size
- A focus on vision-language tasks that reward deliberate, multi-step inference
As a preview, the release is best read as a statement of direction from SenseTime rather than a finished product. Key details such as context length and formal benchmarks aren't spelled out in the record, and the model ships under a custom license, so teams will want to check the terms before building on it. Still, it is a concrete entry in the growing experiment around making smaller models think harder.
Sources
- Visit
sensenova/SenseNova-Loop-9B-Preview
Hugging Face
More from SenseTime
All SenseTime releases →SenseTime's SenseNova-U1.5 Unifies Vision Tasks
An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.
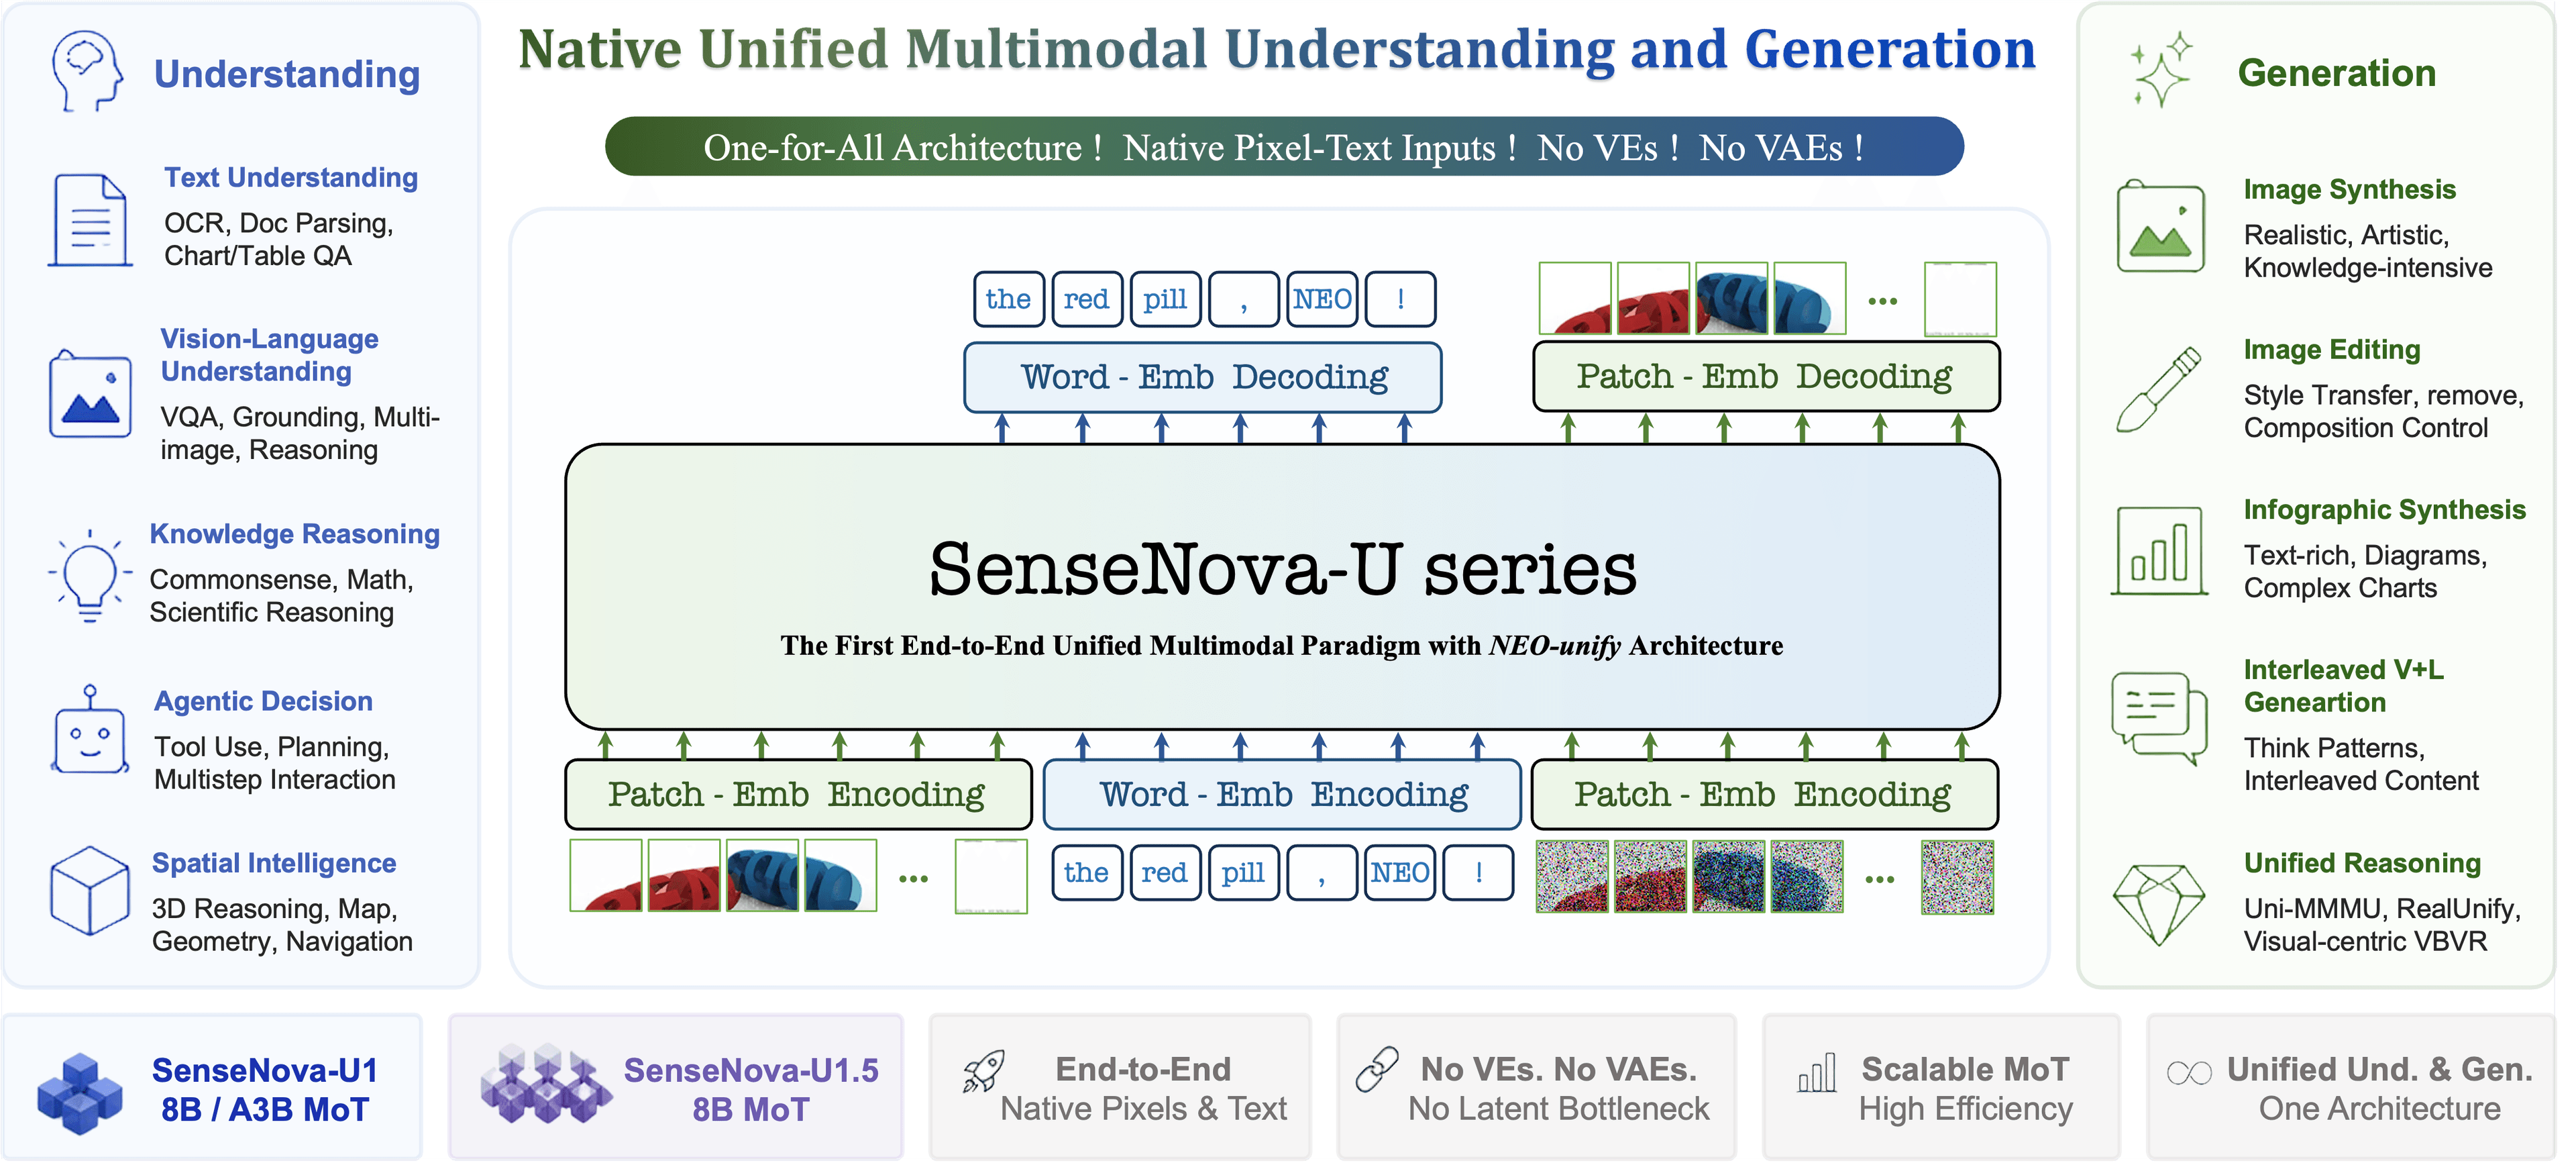
SenseTime Releases SenseNova U1.5 8B Any-to-Any Model
The new 8B multimodal model handles text, images, and image editing within a single native architecture.
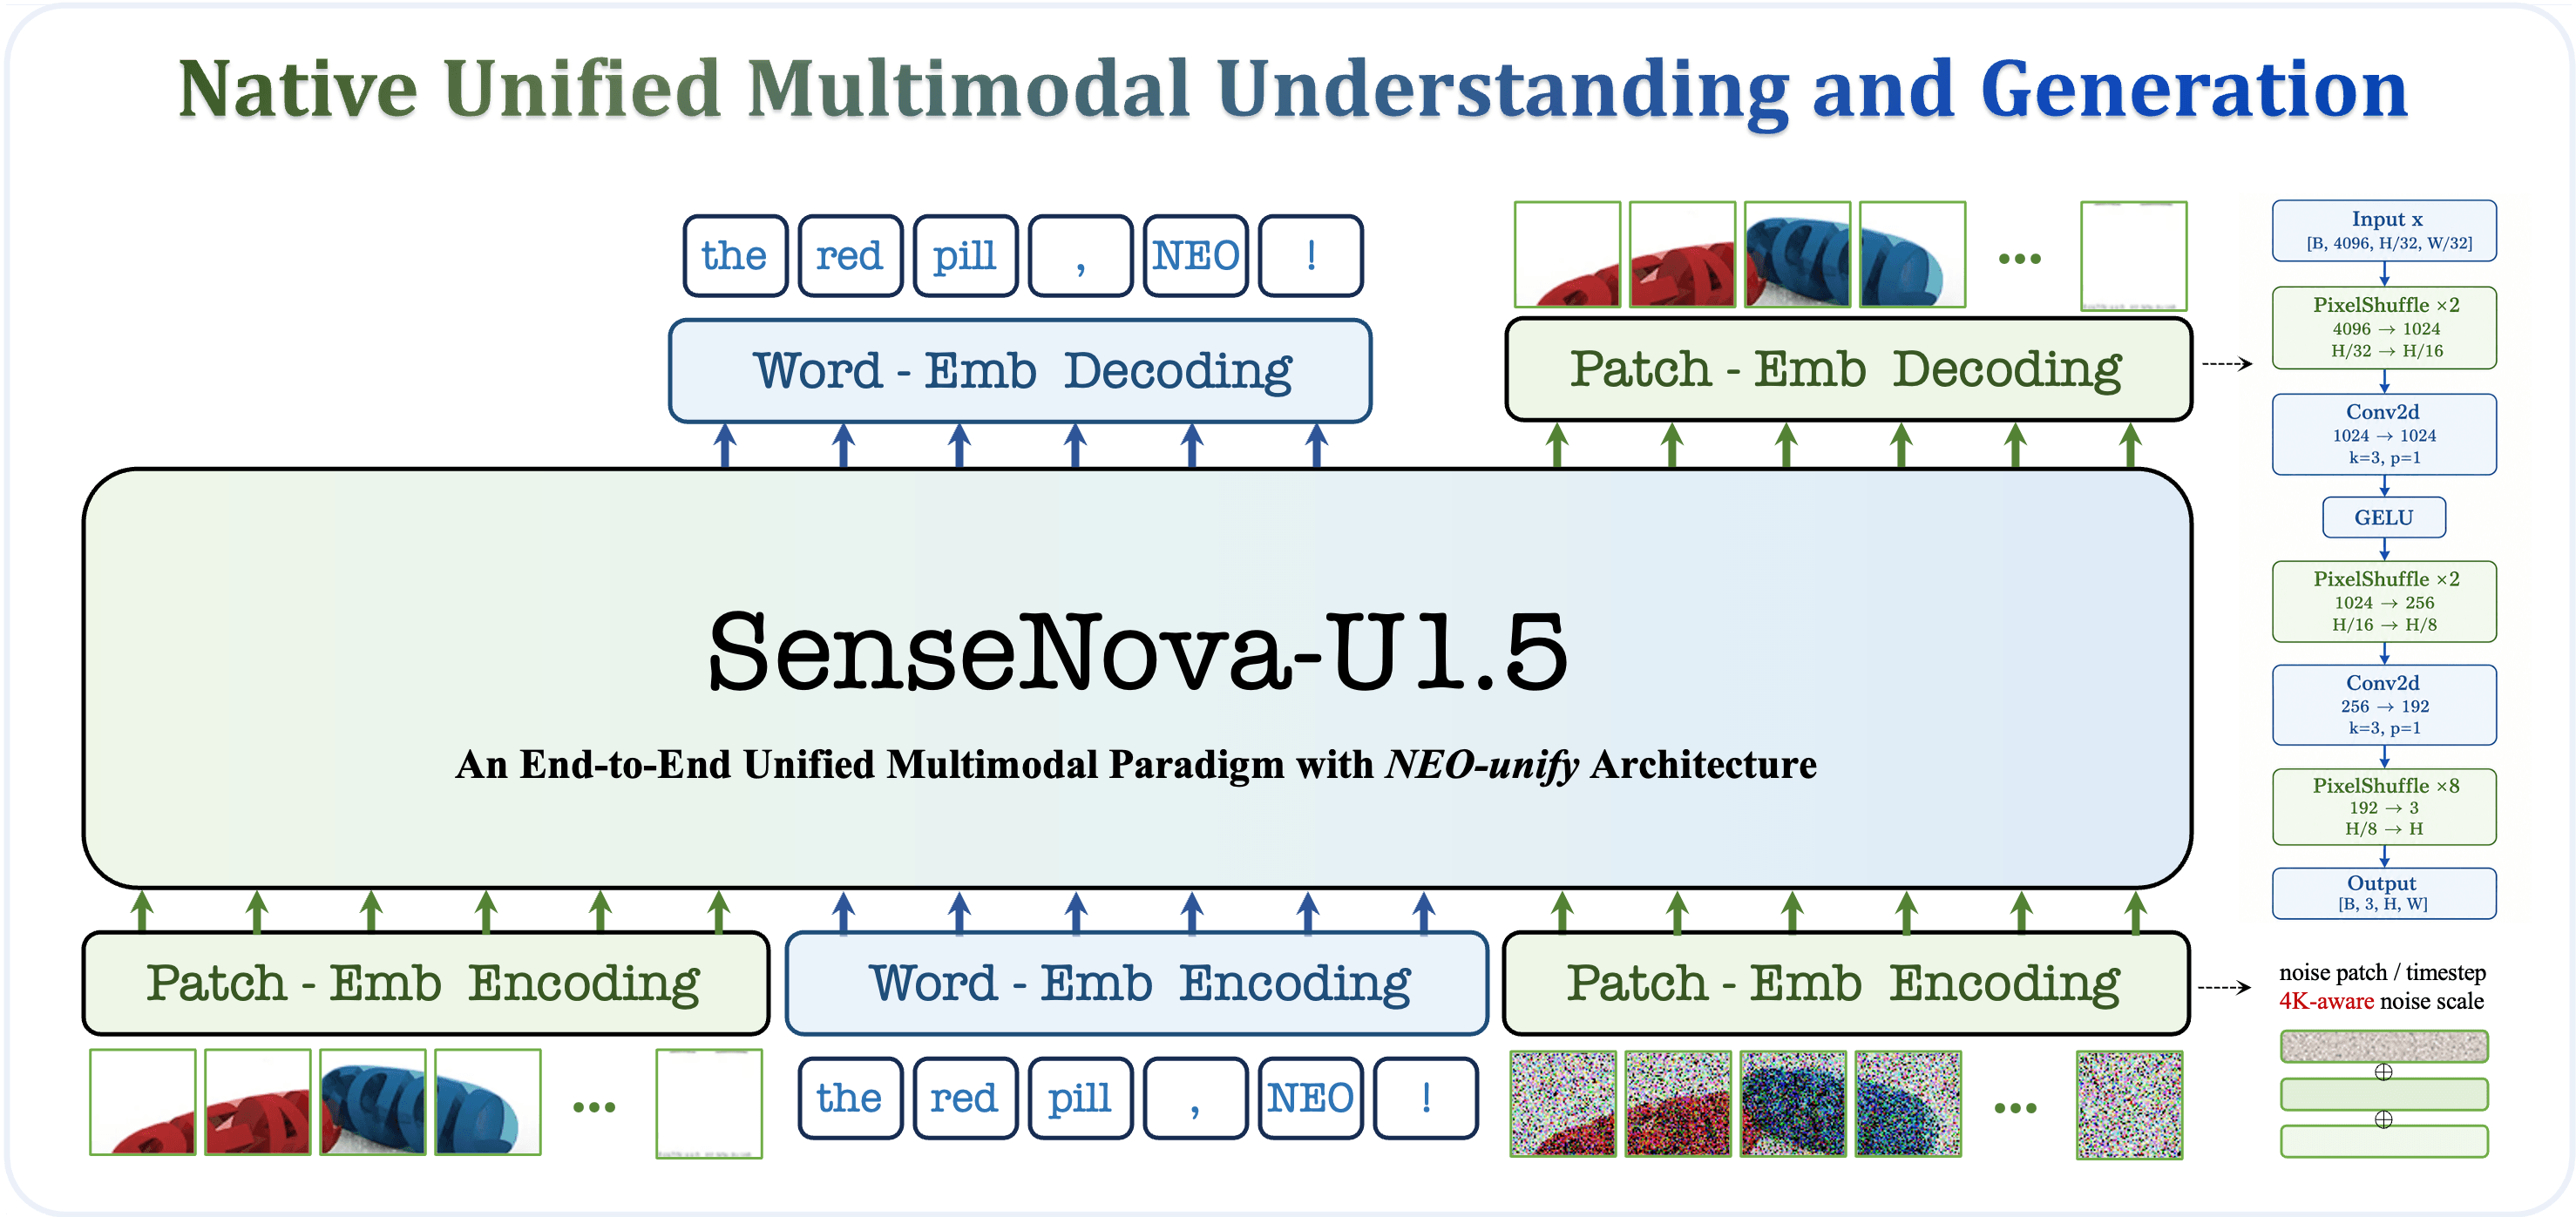
SenseTime Debuts SenseNova U1.5 8B Multimodal Preview
An 8B any-to-any model that reads, generates, and edits images at up to 4K resolution, released as an early preview.
More in Vision-Language
All Vision-Language →
Microsoft's Mage-VL-Cowork takes on computer-use tasks
A new vision-language agent model aims to operate GUIs, write code, and work the terminal.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.
0 comments
No comments yet. Be the first to weigh in.