Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.

Baidu has published Unlimited-OCR 2, a vision-language model aimed at optical character recognition, on Hugging Face. The model is released under the MIT license, one of the most permissive options available, which clears the way for both research and commercial deployment without the usage restrictions attached to many other open releases.
As a vision-language model built for OCR, Unlimited-OCR 2 is designed to read text from images rather than generate open-ended conversation. Baidu describes the model as multilingual, suggesting it targets document understanding across more than one writing system — a practical requirement for enterprises processing invoices, forms, and scanned archives in mixed-language environments.
Why it matters
OCR has become a quiet but critical layer in modern AI pipelines, feeding clean text into retrieval systems, translation tools, and document agents. A few points stand out:
- The MIT license removes friction for teams that need to fine-tune or embed the model in products.
- A multilingual focus broadens its usefulness beyond English-centric document workflows.
- Baidu's continued output of open models adds another option alongside the growing field of open OCR and document-parsing systems.
Baidu has not published detailed specifications such as parameter count or context length alongside this release, so teams evaluating the model will want to benchmark it against their own document sets. The weights and model card are available now on Hugging Face.
Sources
- Visit
baidu/Unlimited-OCR-2
Hugging Face
More from Baidu
All Baidu releases →Baidu's PP-OCRv6 packs 50-language OCR into tiny models
The latest release of PaddlePaddle's optical character recognition suite spans models from 1.5M to 34.5M parameters under an Apache 2.0 license.
Baidu releases Unlimited-OCR under permissive MIT license
The Chinese tech giant's multilingual vision-language model targets text extraction across languages and document types.
PaddleOCR's PP-OCRv6 Adds a Medium Detection Model
Baidu's open-source OCR toolkit ships an Apache-licensed text-line detector in safetensors format, tuned for a balance of accuracy and speed.
More in Vision-Language
All Vision-Language →
MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.

DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
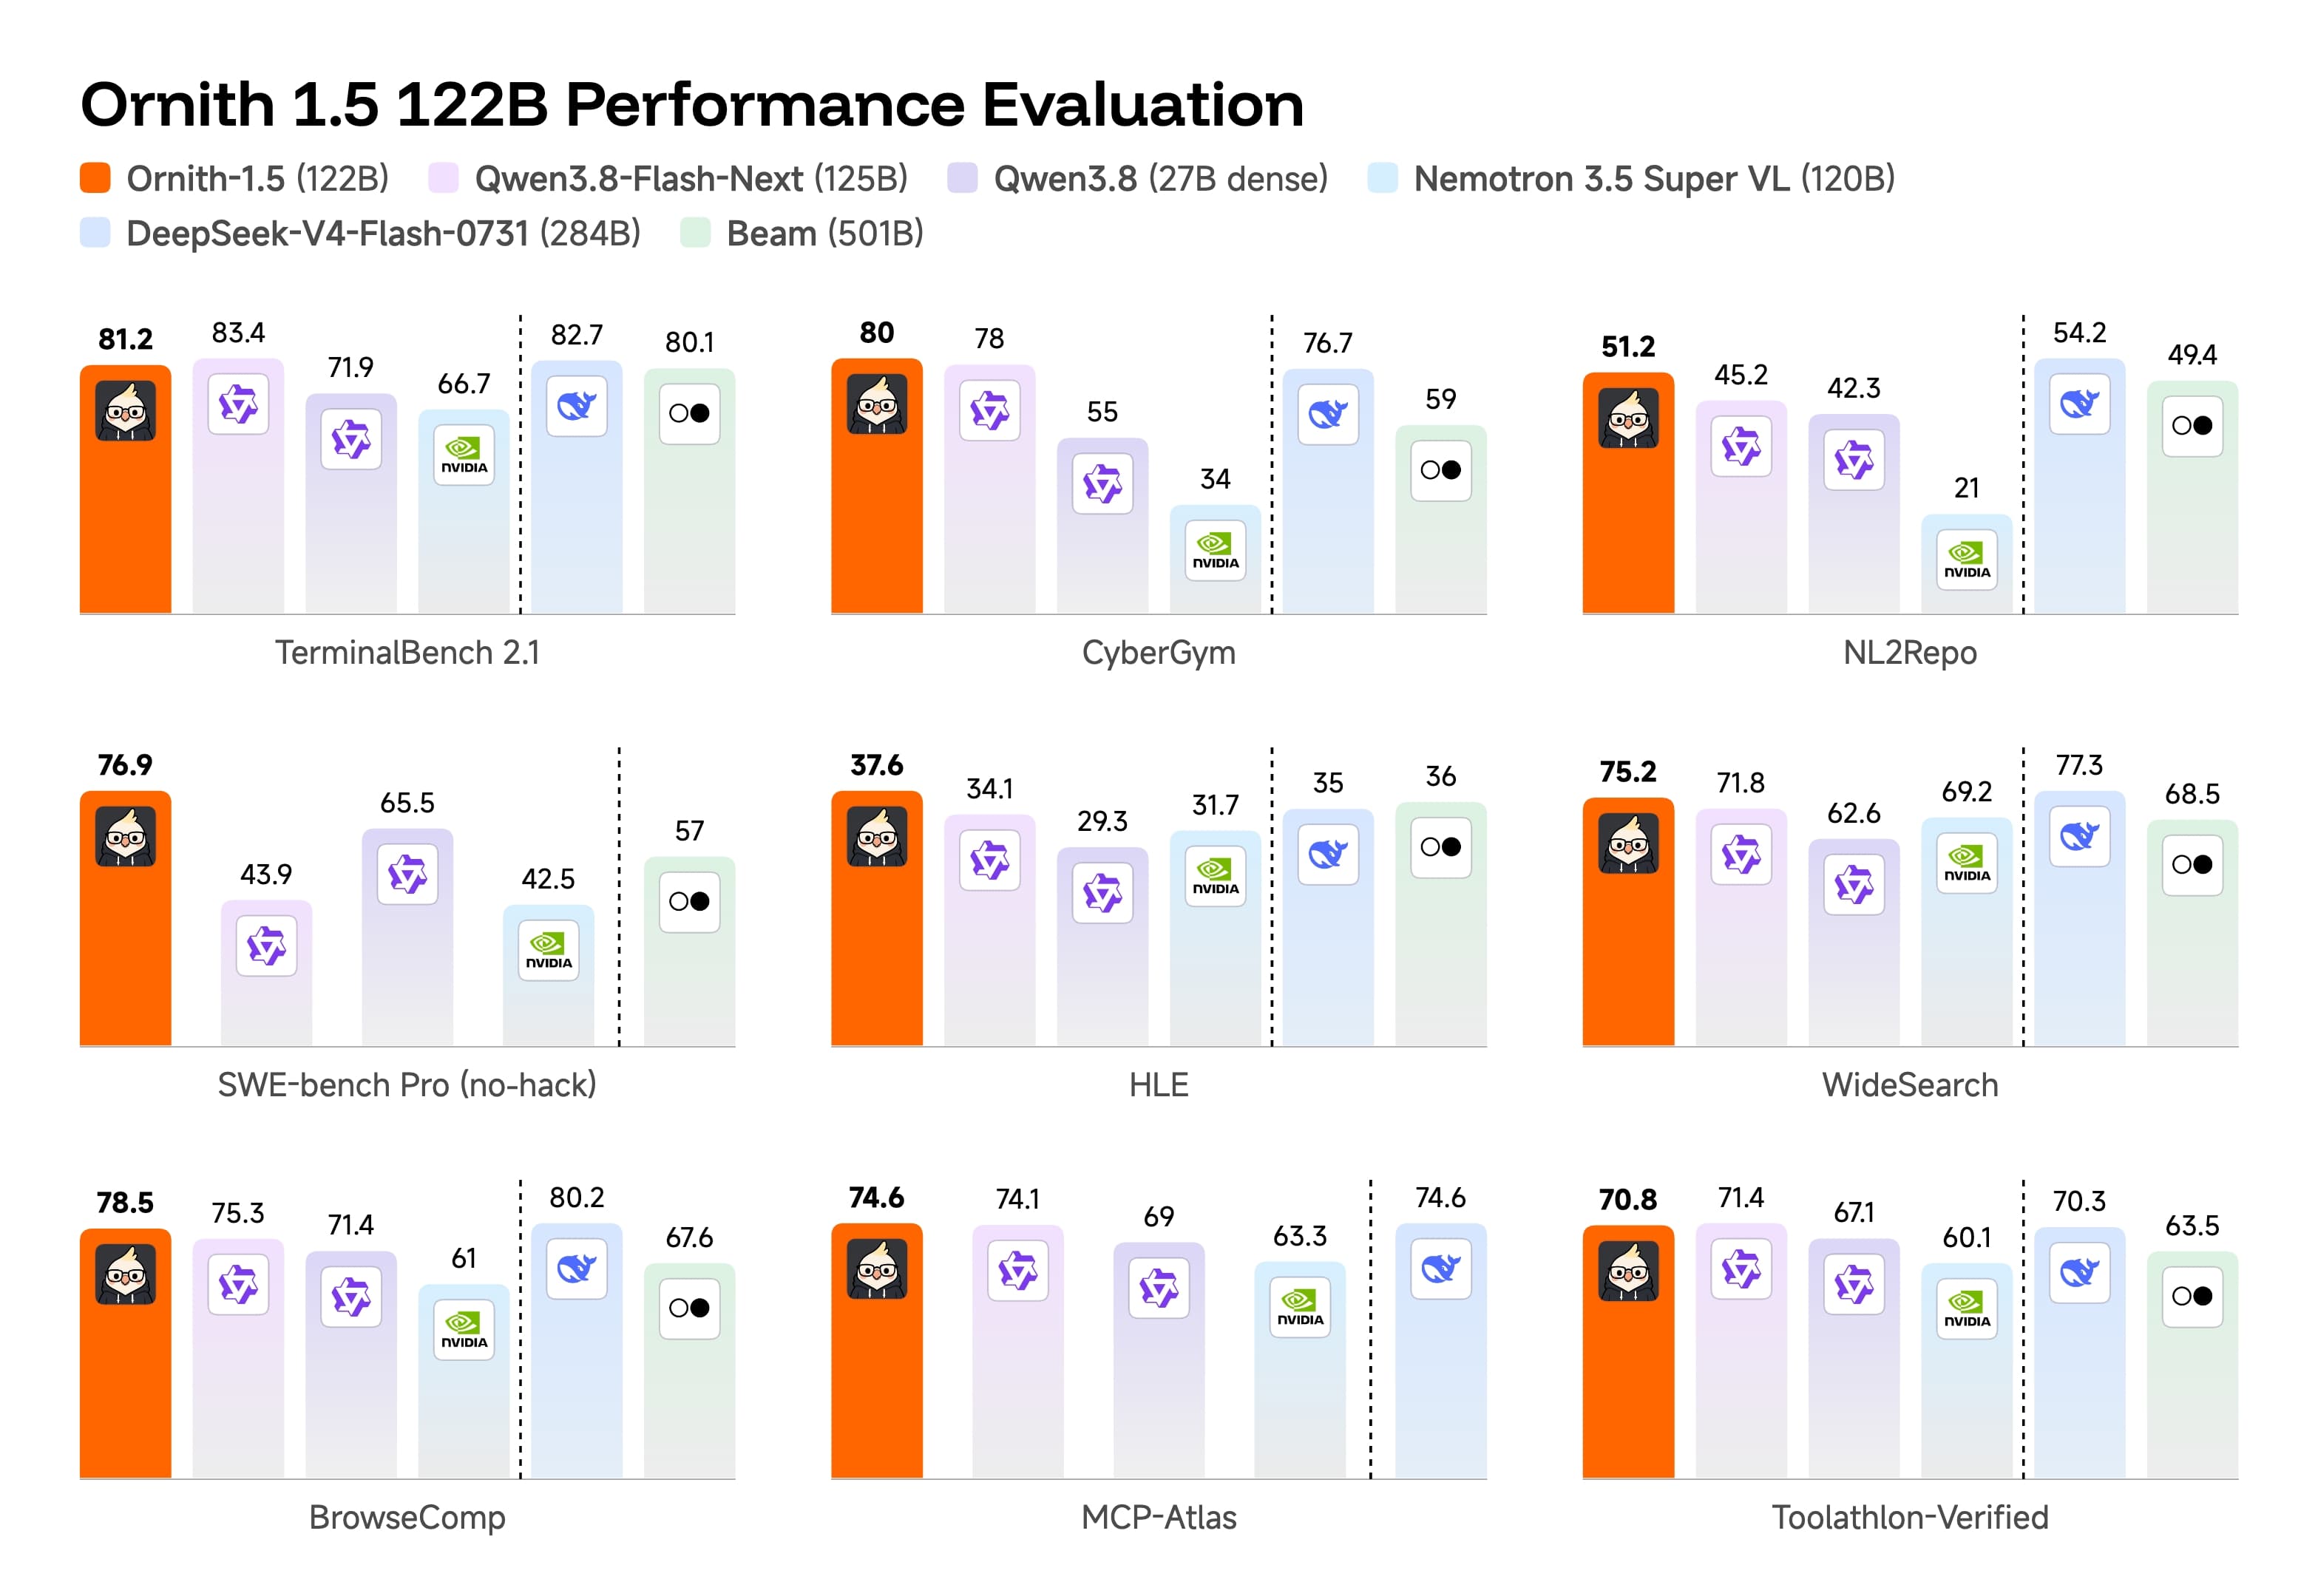
Ornith AI releases 122B MoE multimodal model under MIT
The Qwen3.5-based Ornith-1.5 pairs a mixture-of-experts design with vision support and an unusually permissive license.
0 comments
No comments yet. Be the first to weigh in.