PaddleOCR's PP-OCRv6 Adds a Medium Detection Model
Baidu's open-source OCR toolkit ships an Apache-licensed text-line detector in safetensors format, tuned for a balance of accuracy and speed.
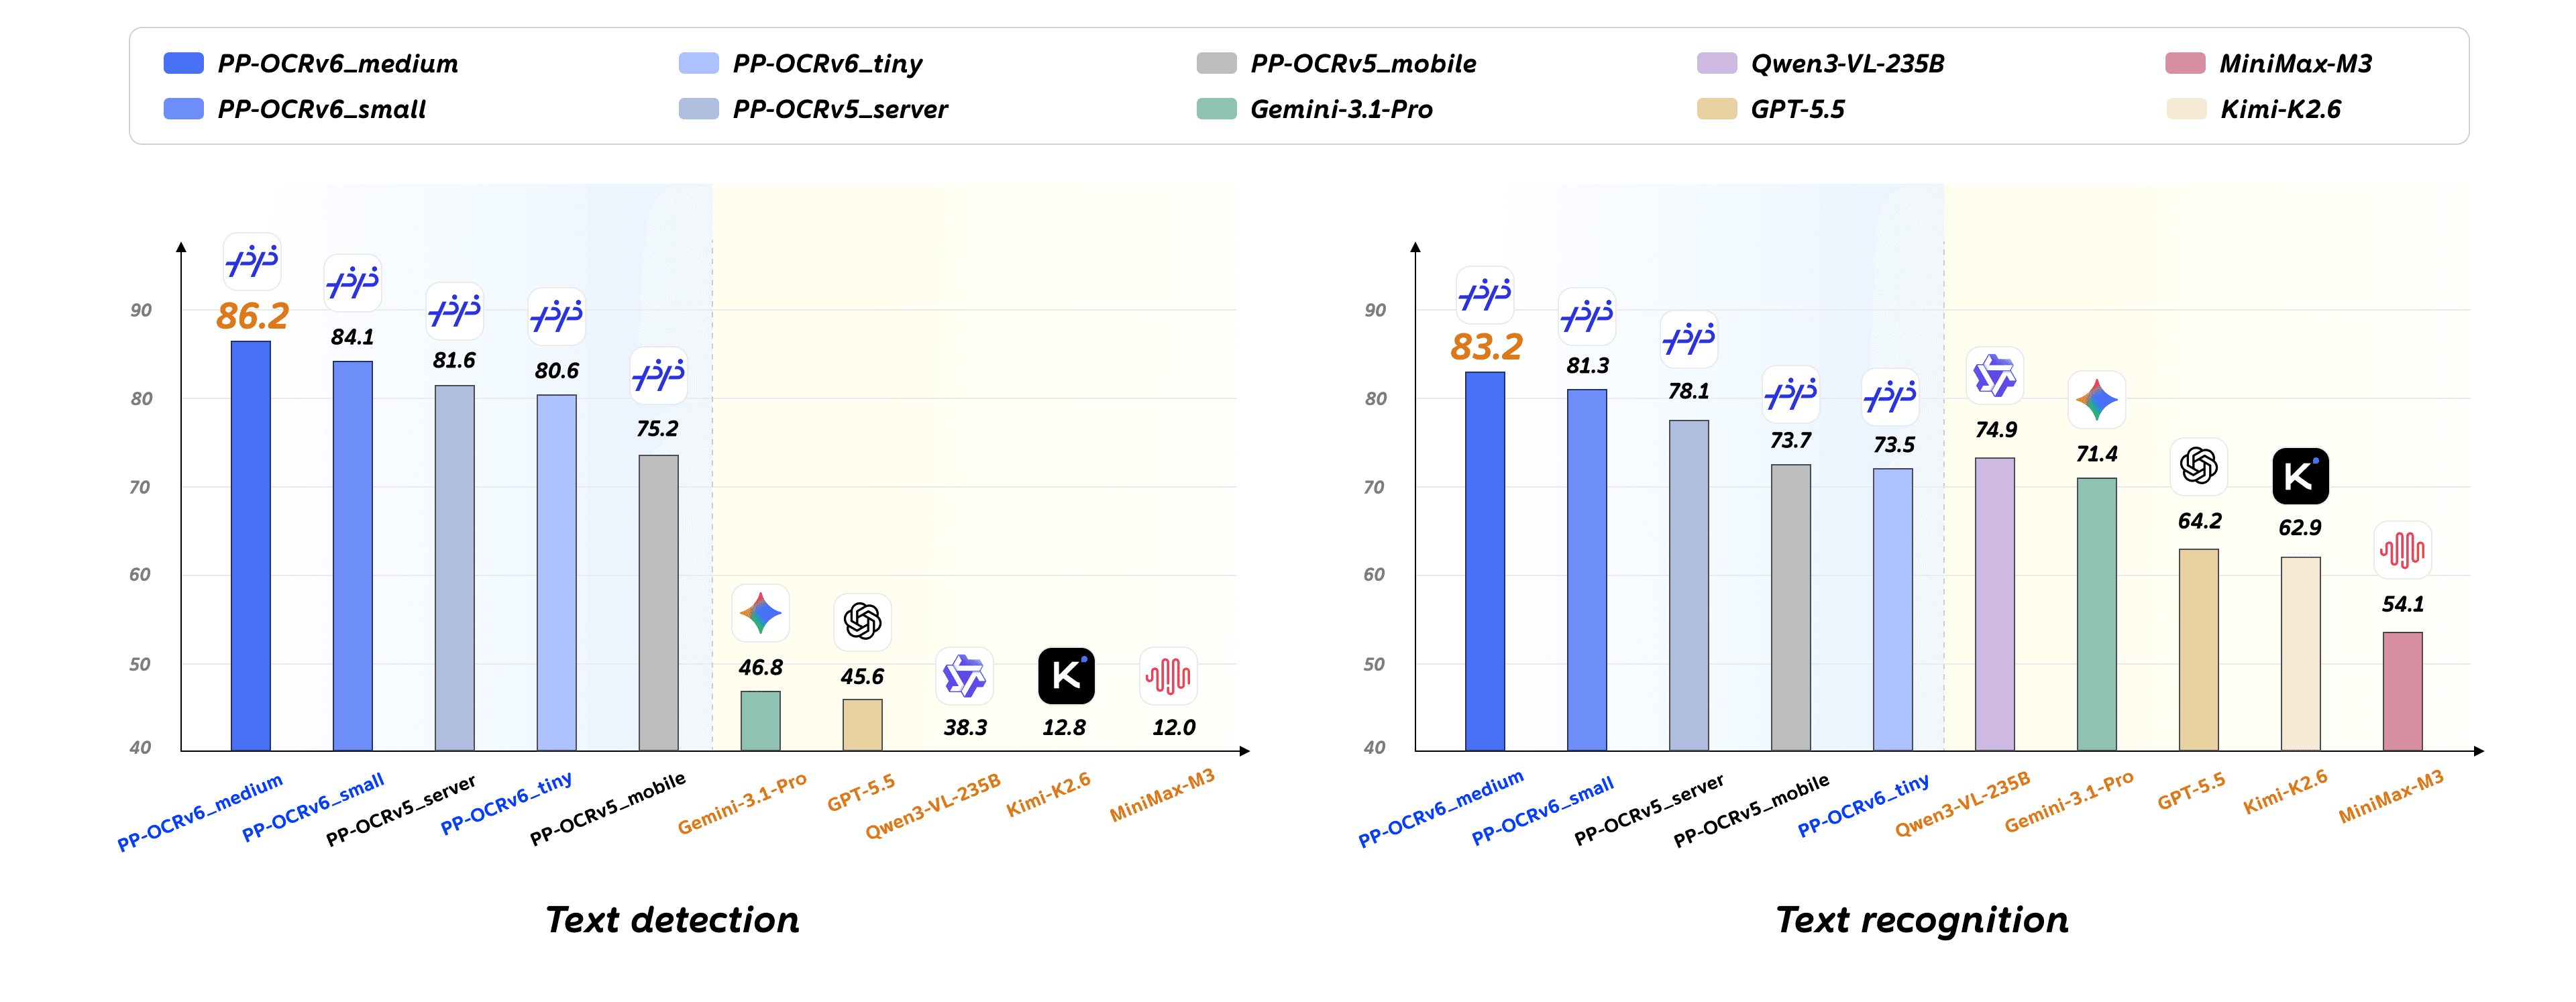
Baidu has published PP-OCRv6 Medium Detection, the text-line detection component of the latest generation of its widely used PaddleOCR toolkit. The model is available on Hugging Face in safetensors format under a permissive Apache-2.0 license.
Text detection is the first stage in most OCR pipelines: before any characters can be read, a model has to locate where text actually sits on the page. This "medium" variant targets the practical middle ground between lightweight mobile-friendly detectors and heavier, higher-accuracy ones, making it a reasonable default for documents, receipts, and natural-scene imagery.
Why it matters
PaddleOCR has become one of the more popular open OCR stacks, particularly for Chinese and multilingual text, and a modular detection model lets developers swap stages without committing to the full framework.
- Apache-2.0 licensing allows commercial use and redistribution.
- The safetensors format improves loading safety and interoperability.
- A sub-1B parameter footprint keeps inference costs modest.
As an early v6-generation release, the model signals continued investment in PaddleOCR's pipeline approach rather than a single end-to-end system. Teams already building on PaddleOCR can treat it as a drop-in detection upgrade, while others may find it a useful standalone building block for document-processing workflows.
Sources
- Visit
PaddlePaddle/PP-OCRv6_medium_det_safetensors
Hugging Face
More from Baidu
All Baidu releases →
Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.
Baidu's PP-OCRv6 packs 50-language OCR into tiny models
The latest release of PaddlePaddle's optical character recognition suite spans models from 1.5M to 34.5M parameters under an Apache 2.0 license.
Baidu releases Unlimited-OCR under permissive MIT license
The Chinese tech giant's multilingual vision-language model targets text extraction across languages and document types.
More in Vision-Language
All Vision-Language →
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
OpenBMB's MiniCPM-OCR 1.0 Targets Document Parsing
A compact vision-language model built to read tables, formulas, and complex page layouts arrives on Hugging Face.
0 comments
No comments yet. Be the first to weigh in.