StepFun/Text → Speech
StepFun's StepAudio 3 Realtime targets live voice AI
The audio-language foundation model builds a listen-converse-think-act loop aimed at natural, low-latency spoken interaction.
The feed
Every new open-source model release and major update — aggregated from across the ecosystem, deduplicated, and refreshed every 12 hours.
431 releases
The audio-language foundation model builds a listen-converse-think-act loop aimed at natural, low-latency spoken interaction.
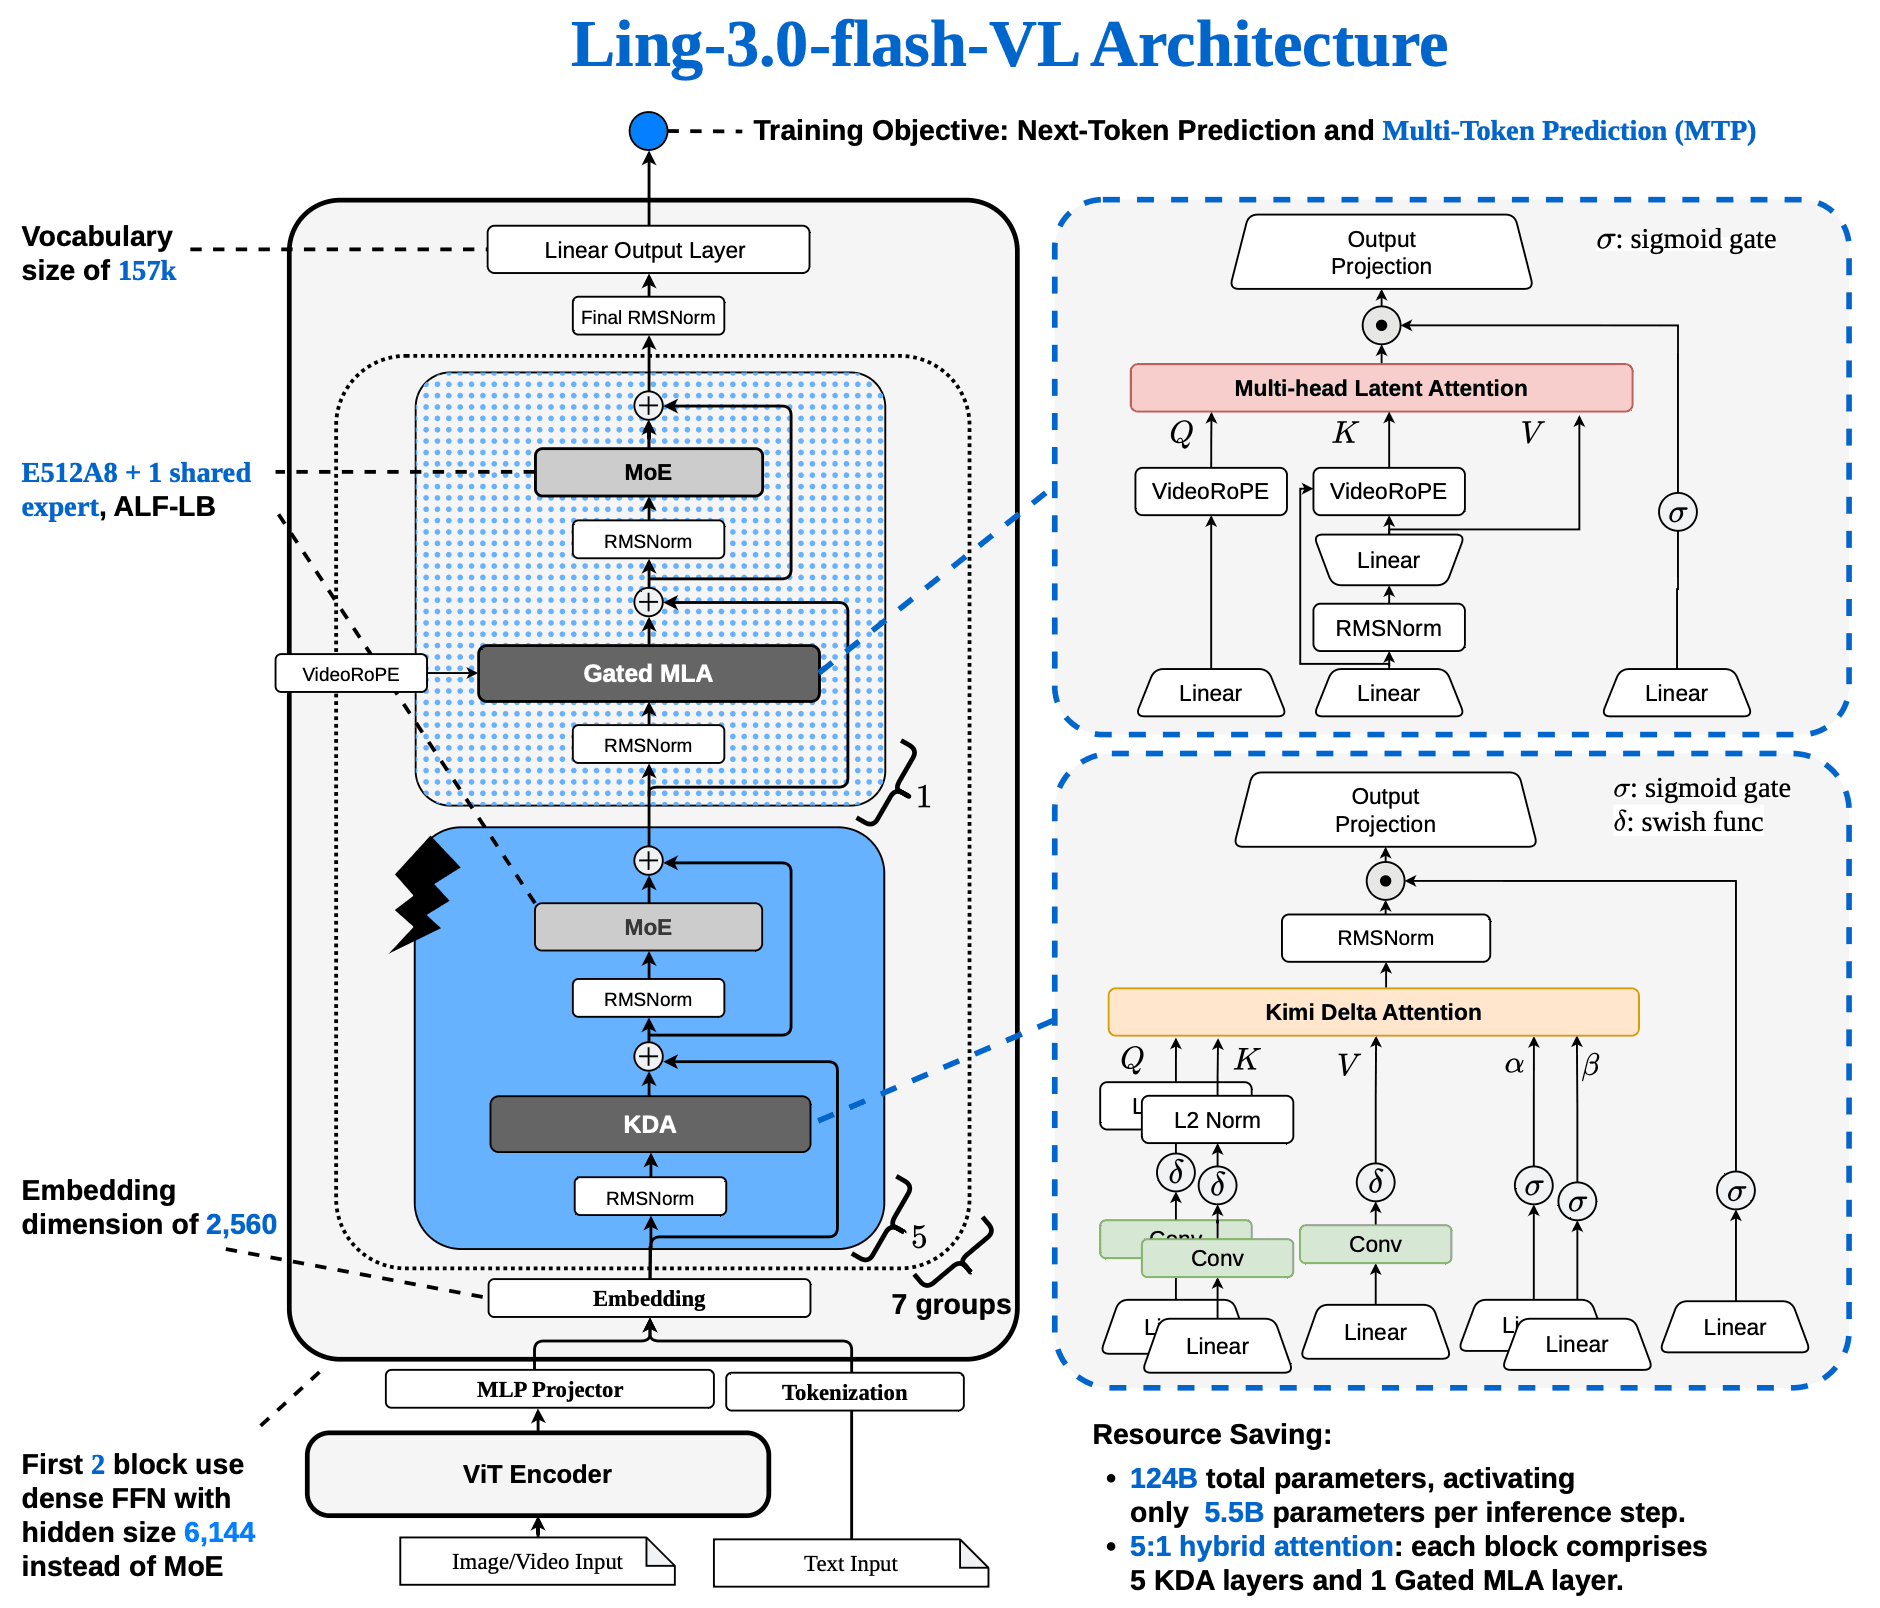
The new release pairs vision-language understanding with a hybrid-attention design aimed at long-context reasoning.
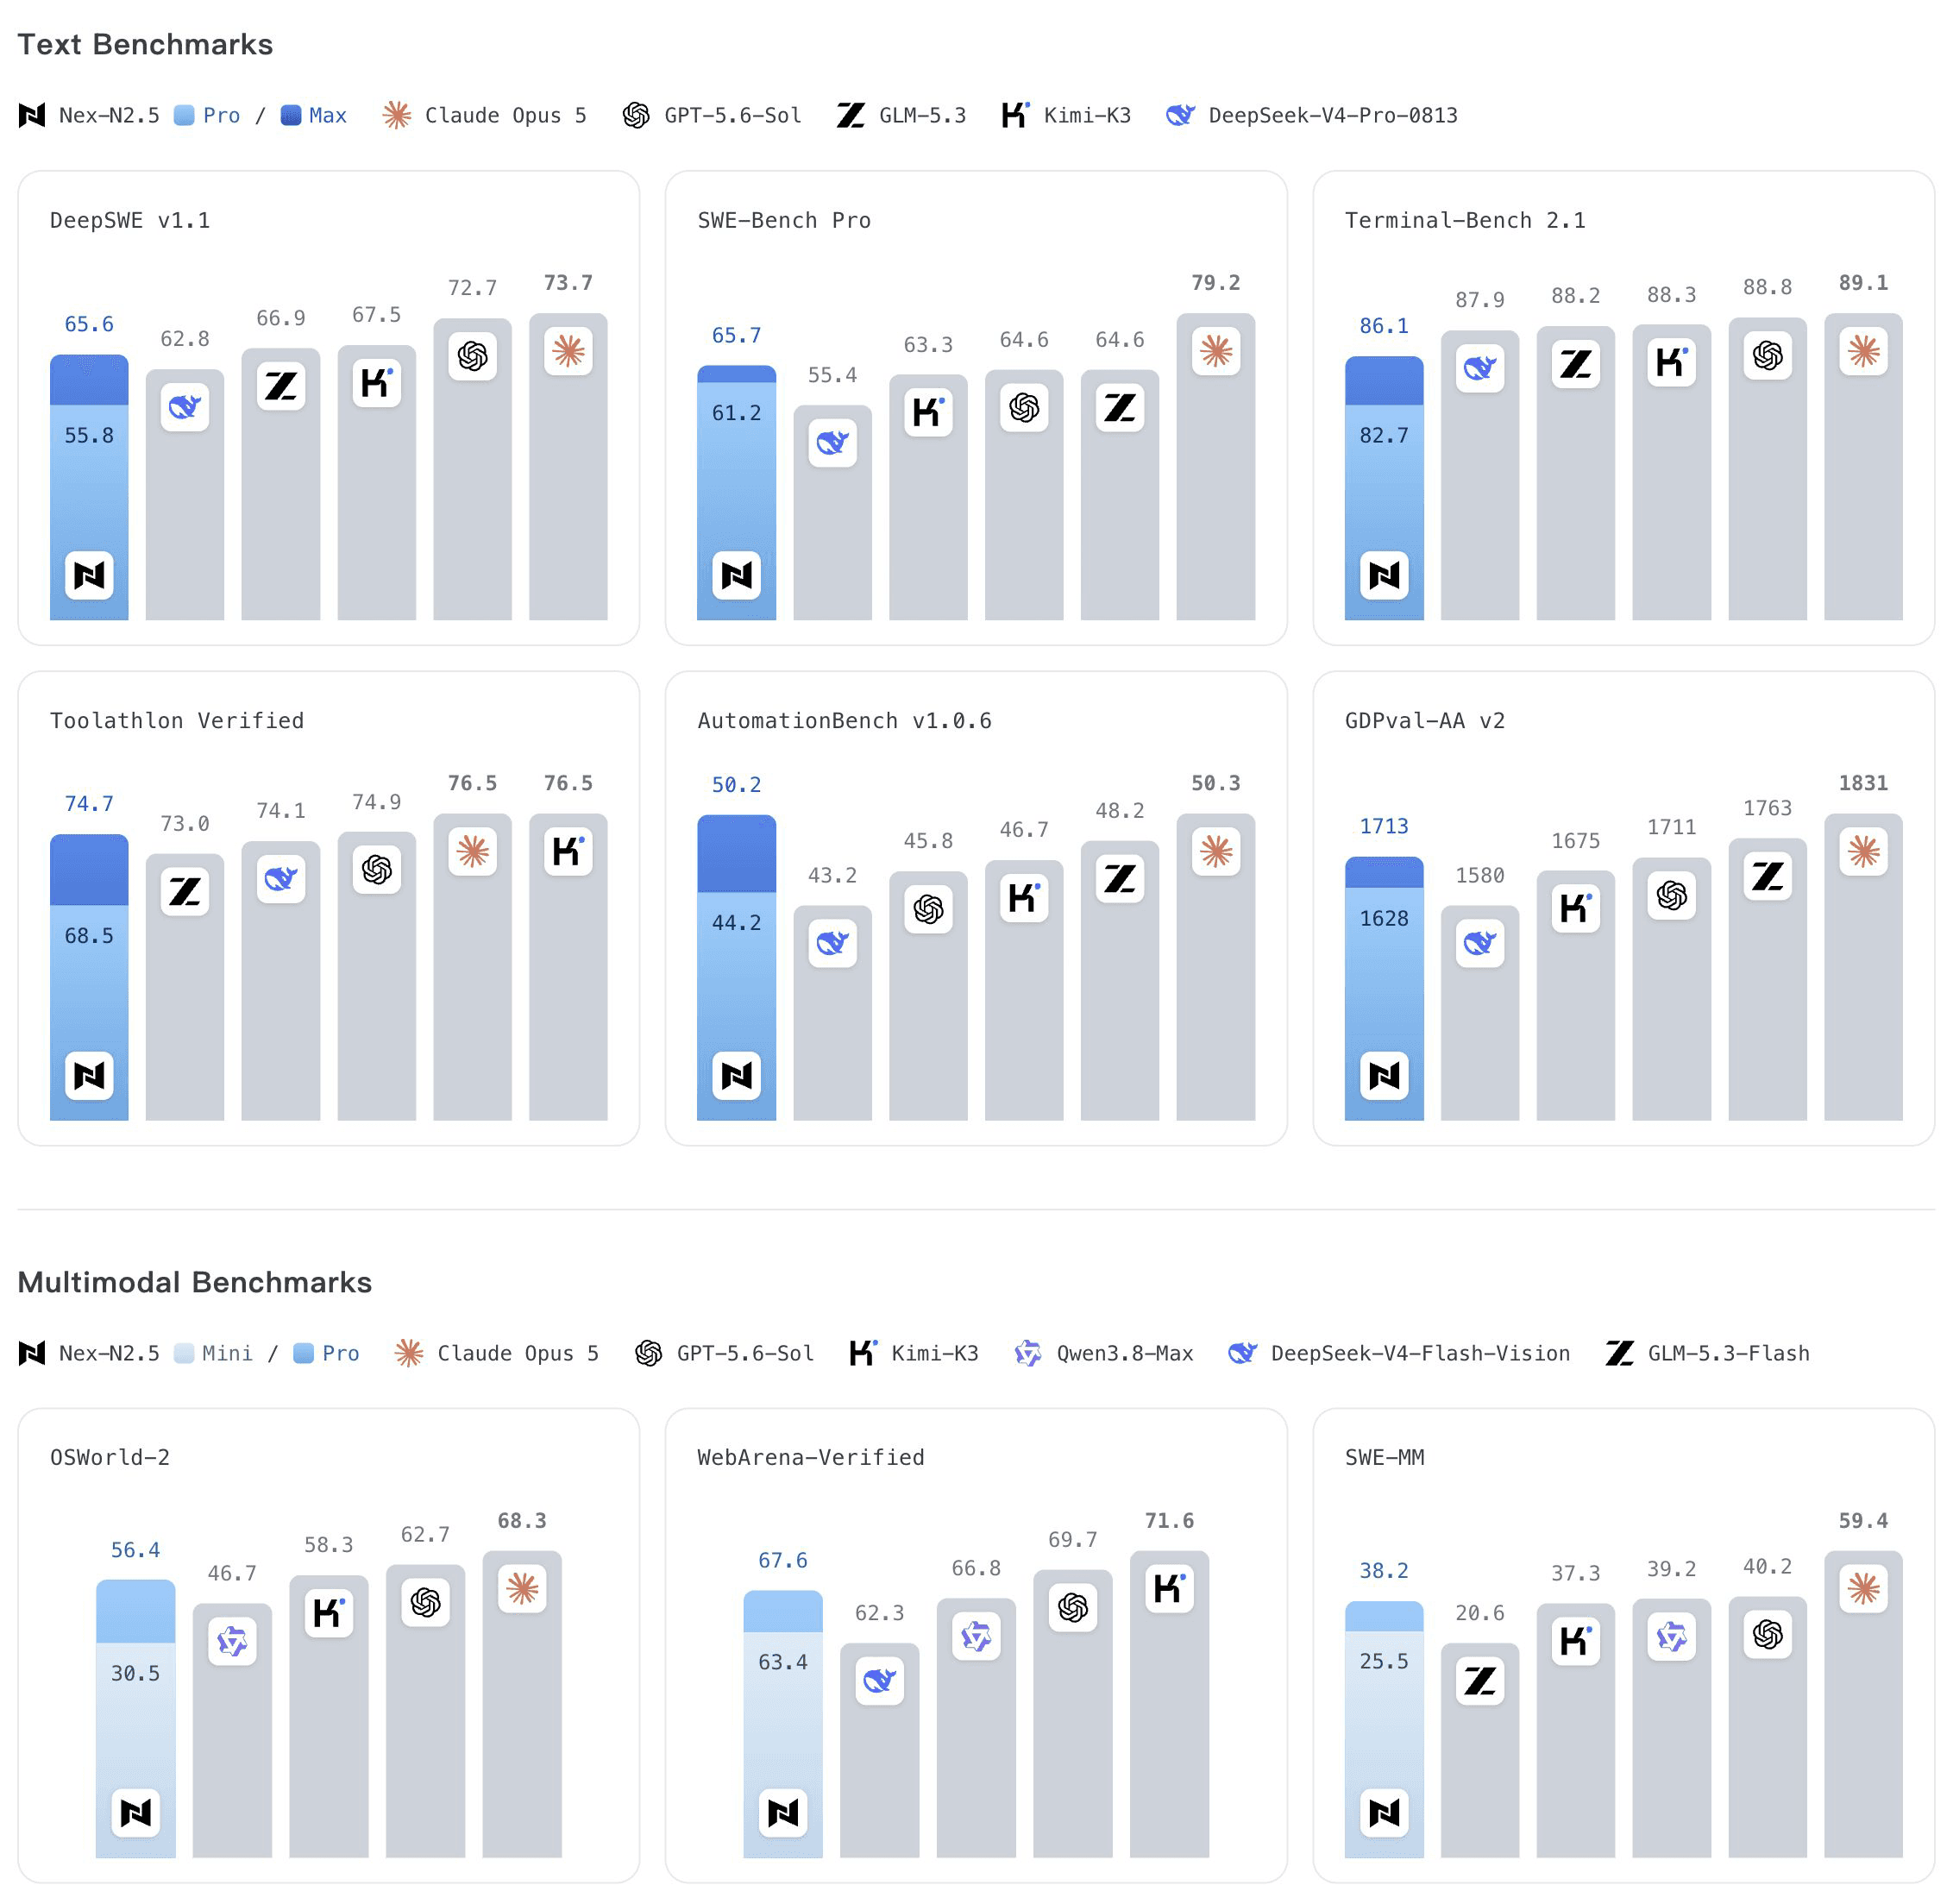
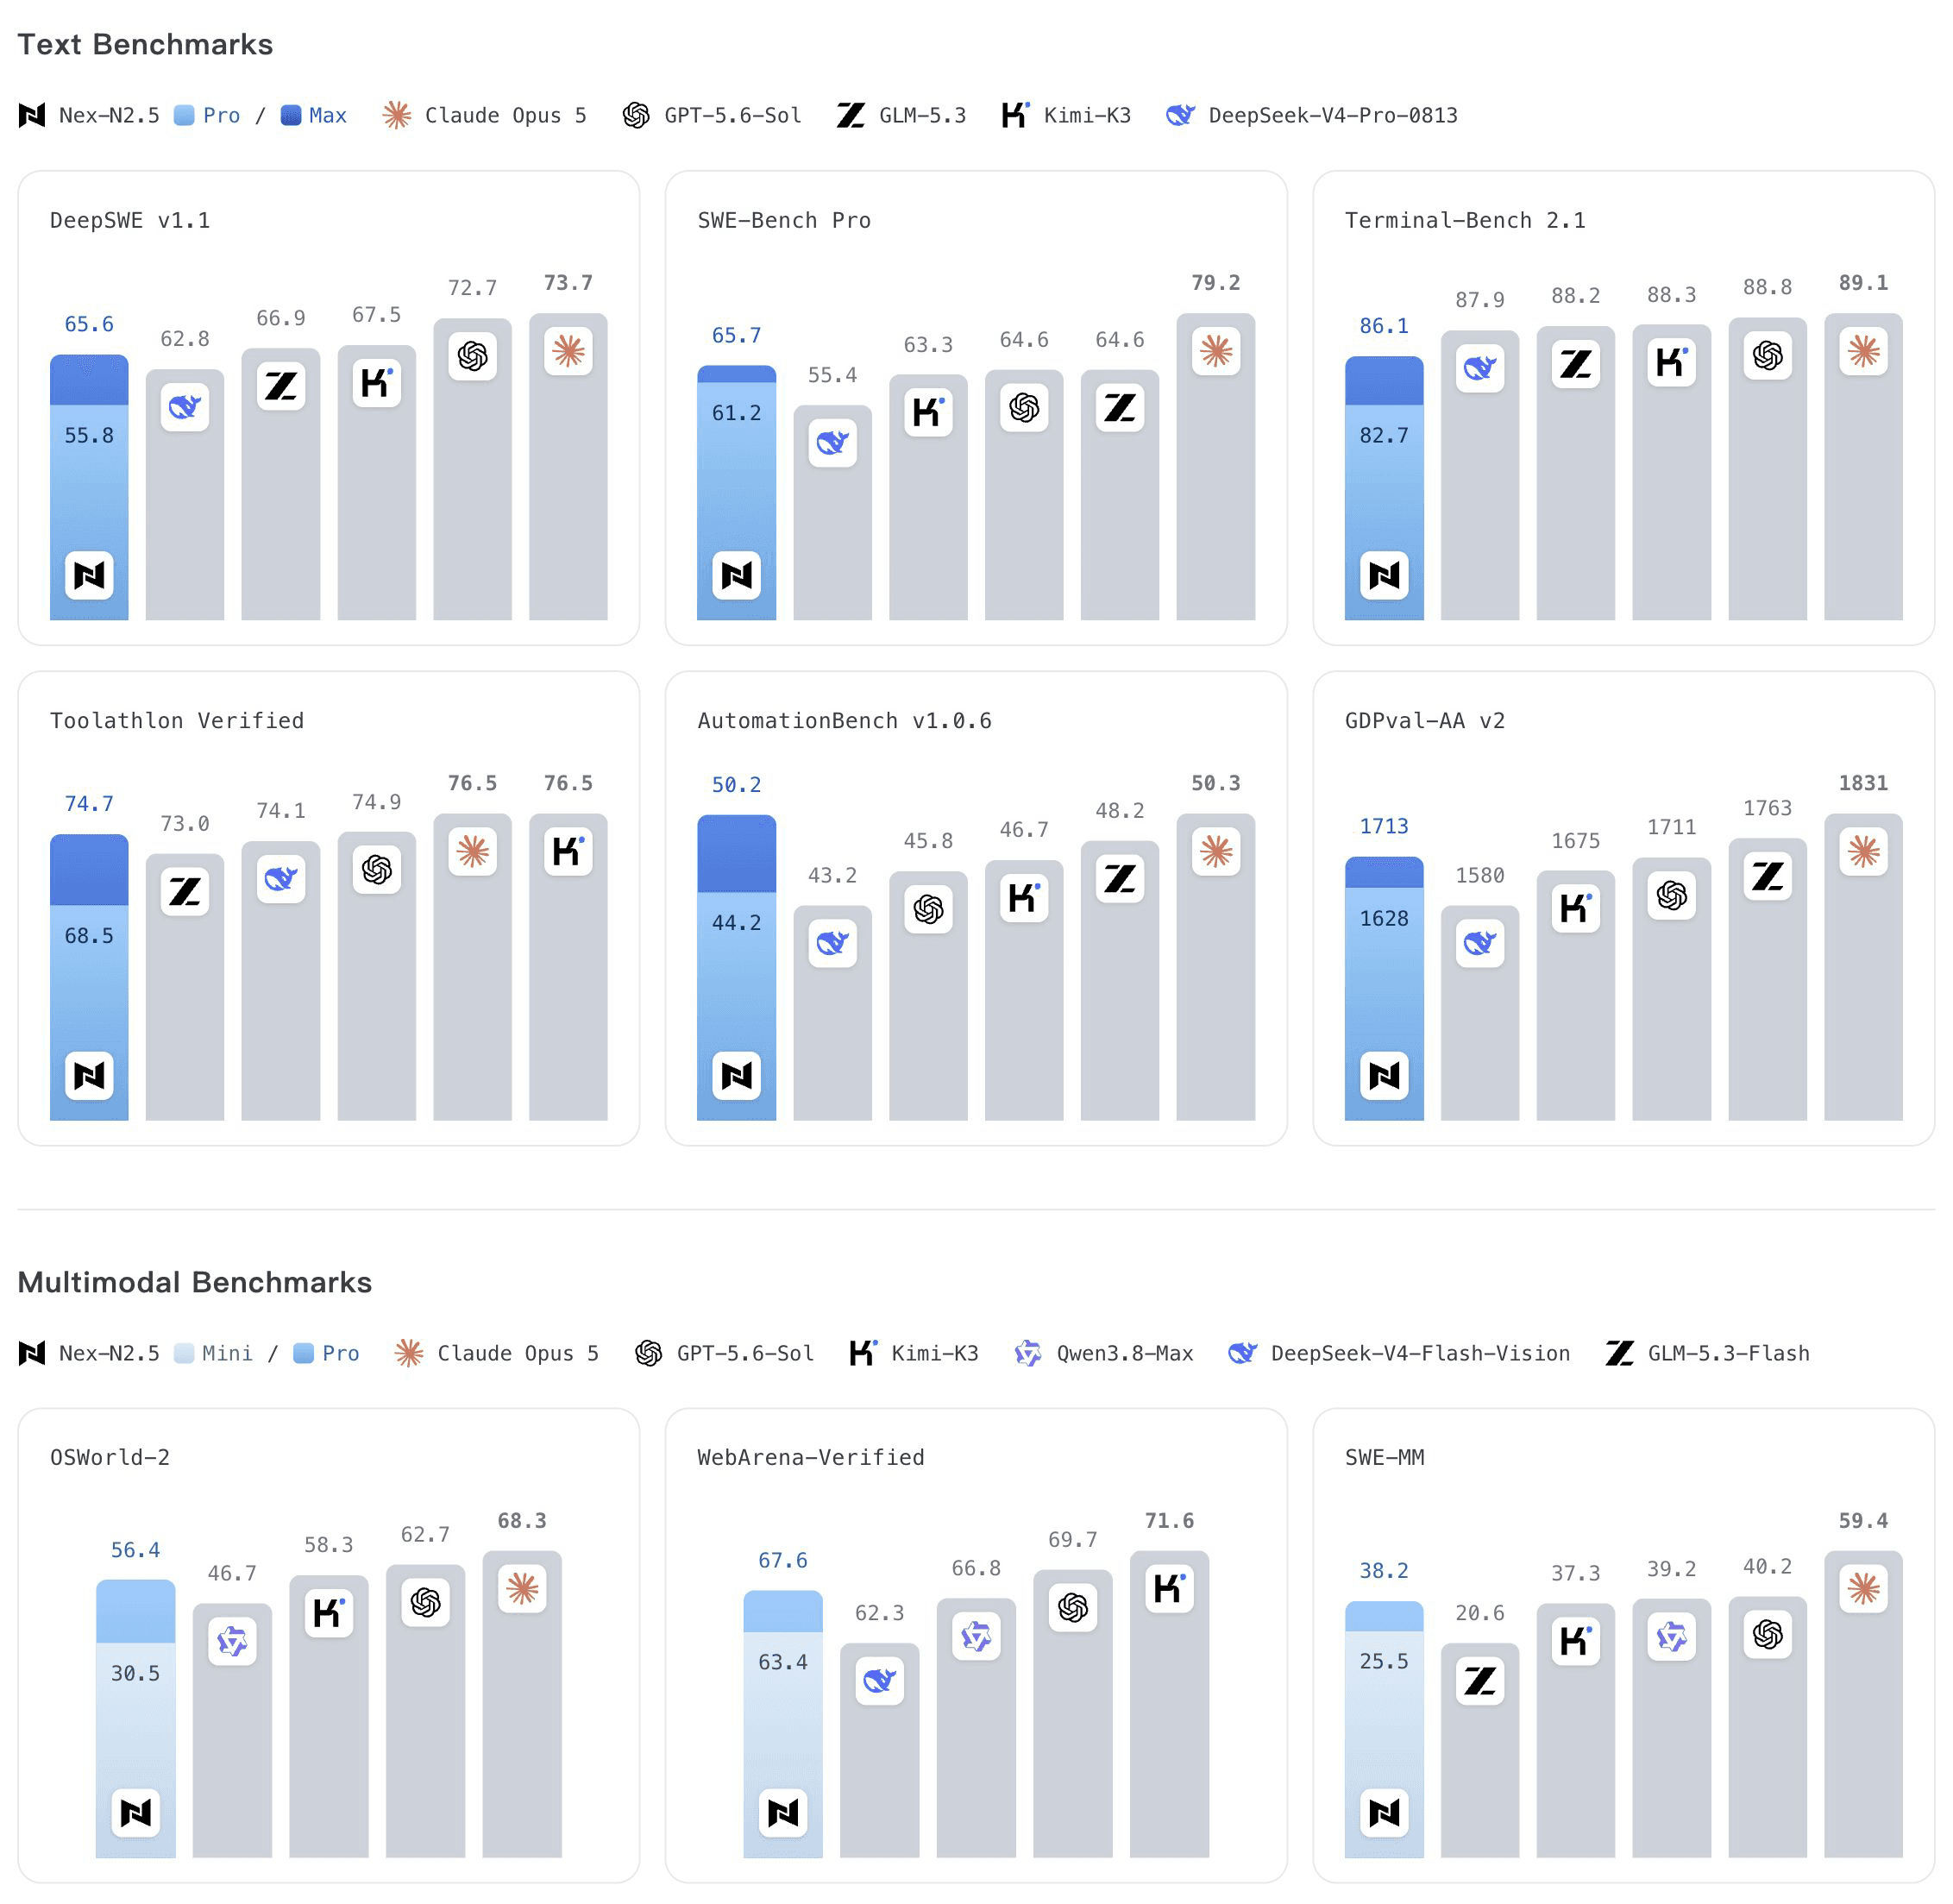
A new mixture-of-experts model trained on verified tool interactions arrives as an early preview under an MIT license.
A single discrete autoregressive model handles speech, voice design, sound effects, and music generation.
A compact foundation model targets math reasoning and agentic search with tool use, and its makers are releasing it fully open.
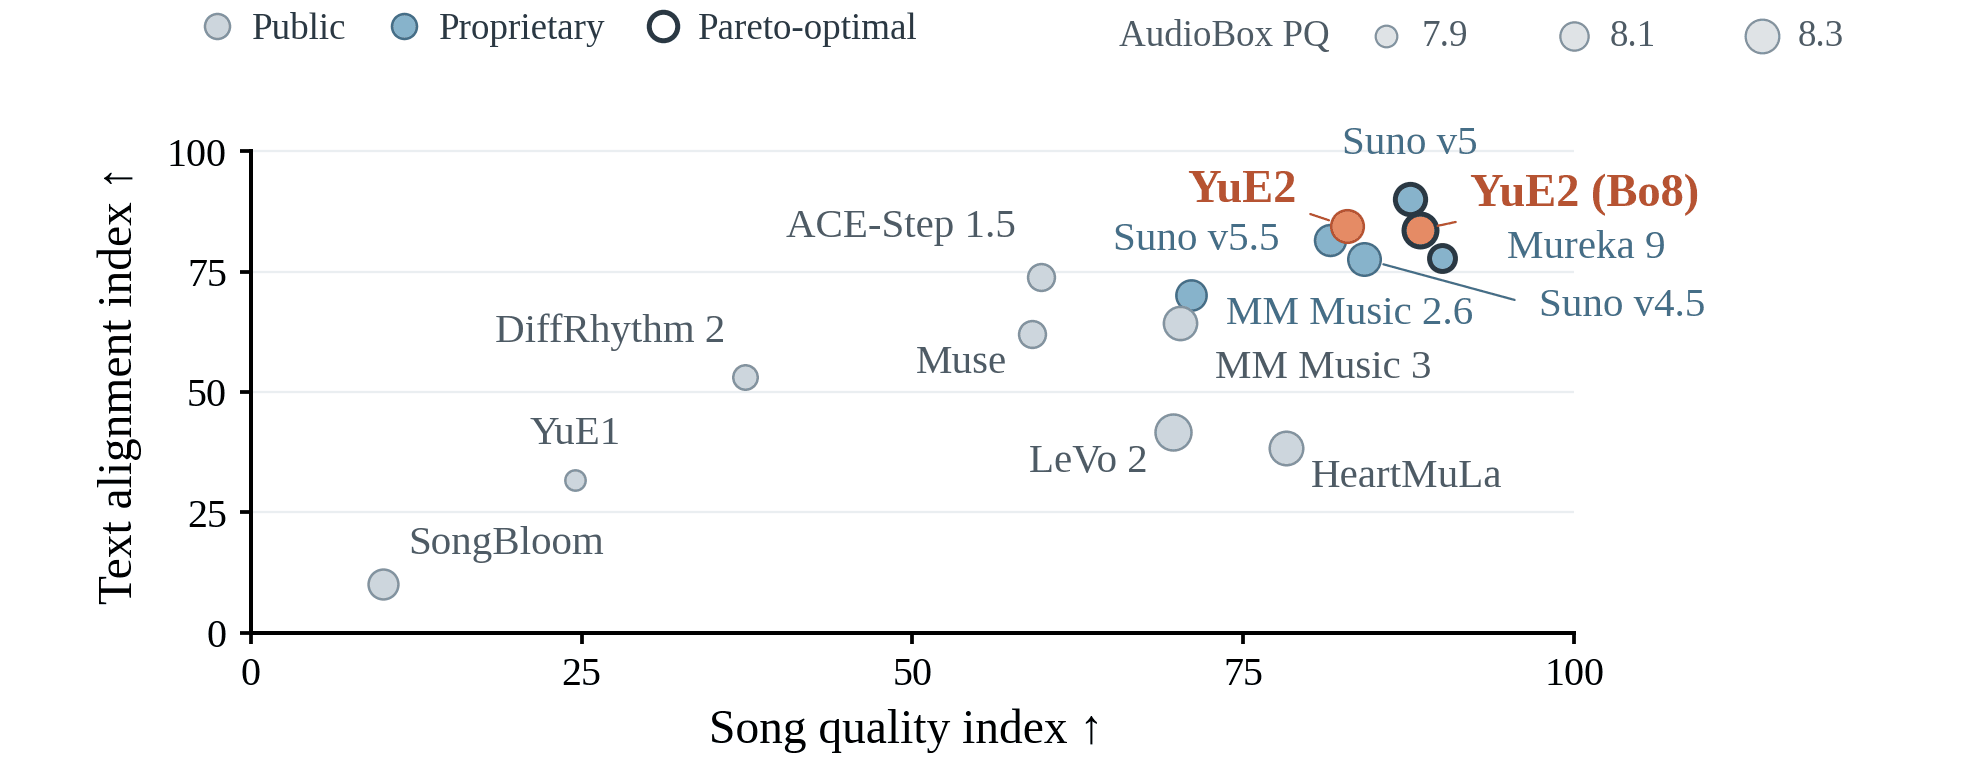
The new open model separates musical structure from sound, generating long-form tracks from text prompts with an explicit planning stage.
The AliceAI-T5-35B-A0.6B is an encoder-decoder mixture-of-experts model that keeps only a sliver of its 35B parameters active per token.
The 3-billion-parameter model adds symbolic planning and agentic editing to open-source music generation.
A 122B mixture-of-experts model trained with reinforcement learning claims state-of-the-art results on Terminal-Bench.
An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.
The 3-billion-parameter model pairs symbolic planning with agentic editing to generate and refine full songs in English and Chinese.
inclusionAI's 16.7B MoE vision-language model uses block-wise diffusion to drive graphical interface tasks.
A preview mixture-of-experts model uses trained routing prediction to run on machines that can't hold it all in memory.
A permissively licensed multimodal mixture-of-experts model built on a Qwen3-style MoE backbone.
The compact mixture-of-experts model handles both text and vision, and ships under a permissive Apache-2.0 license.
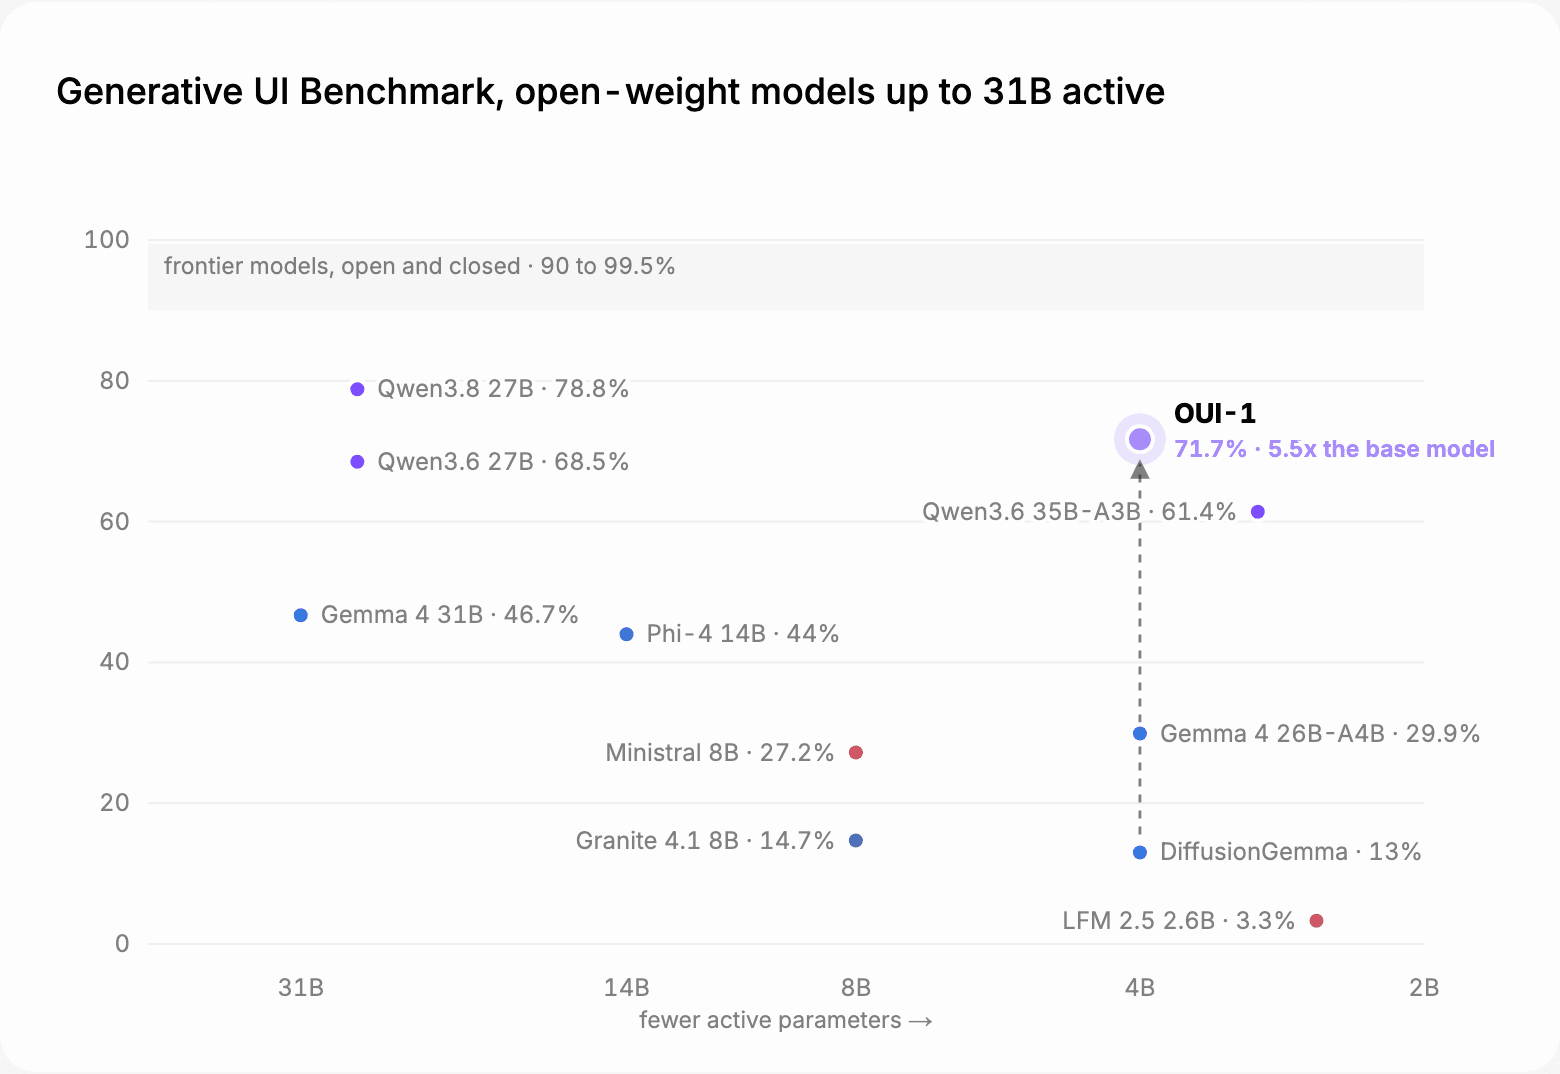
Thesys releases an experimental diffusion language model aimed at turning prompts into user interfaces, built atop Google's Gemma.
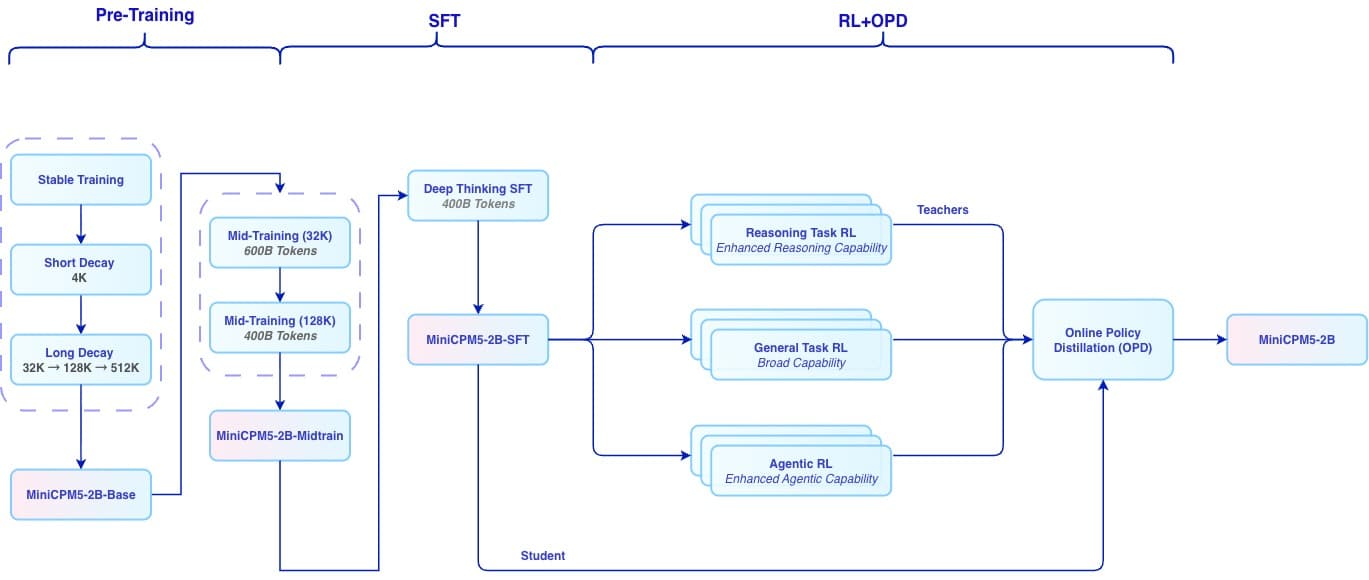
The compact 2-billion-parameter model adds long-context handling and tool-calling in a footprint small enough to run locally.
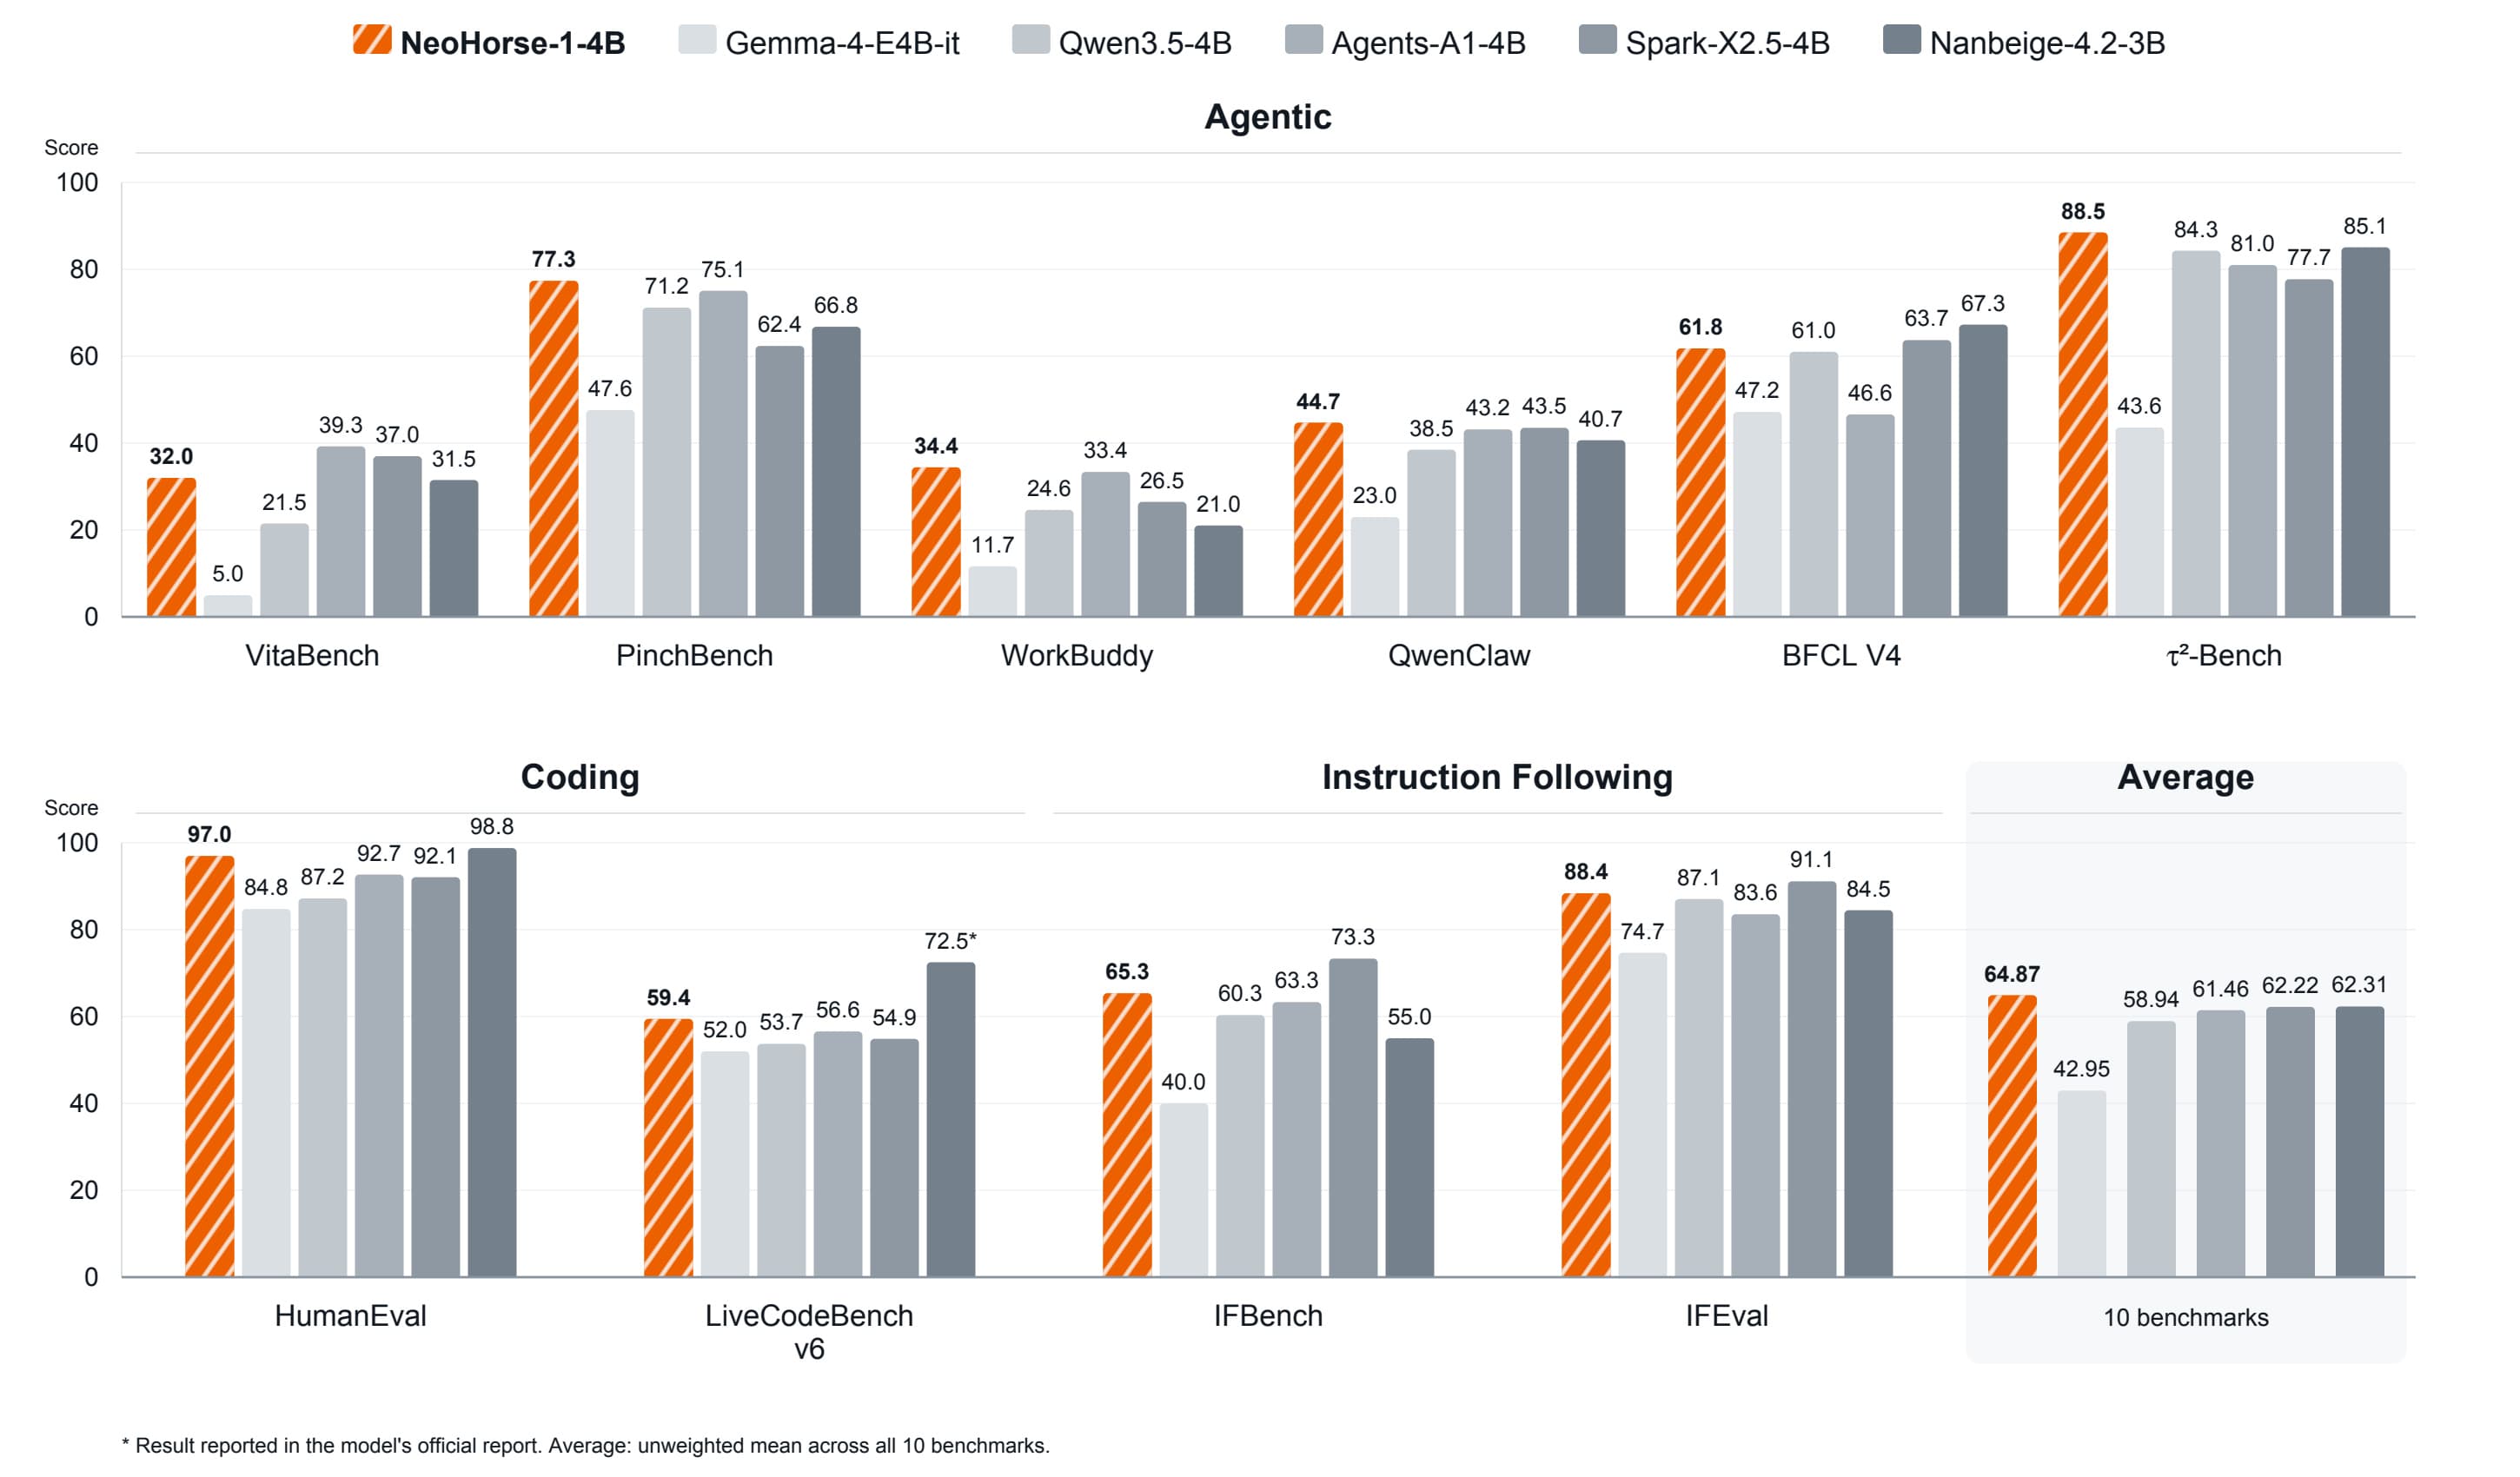
A compact 4-billion-parameter model built for tool use, coding, and multi-step reasoning arrives from TokenRhythm.
The new Ling-3.0-flash-VL brings a mixture-of-experts vision-language model to inclusionAI's open lineup under a permissive MIT license.
The compact multimodal model targets spatial reasoning, video understanding, and agent-style tasks.