OpenBMB's MiniCPM-OCR 1.0 Targets Document Parsing
A compact vision-language model built to read tables, formulas, and complex page layouts arrives on Hugging Face.
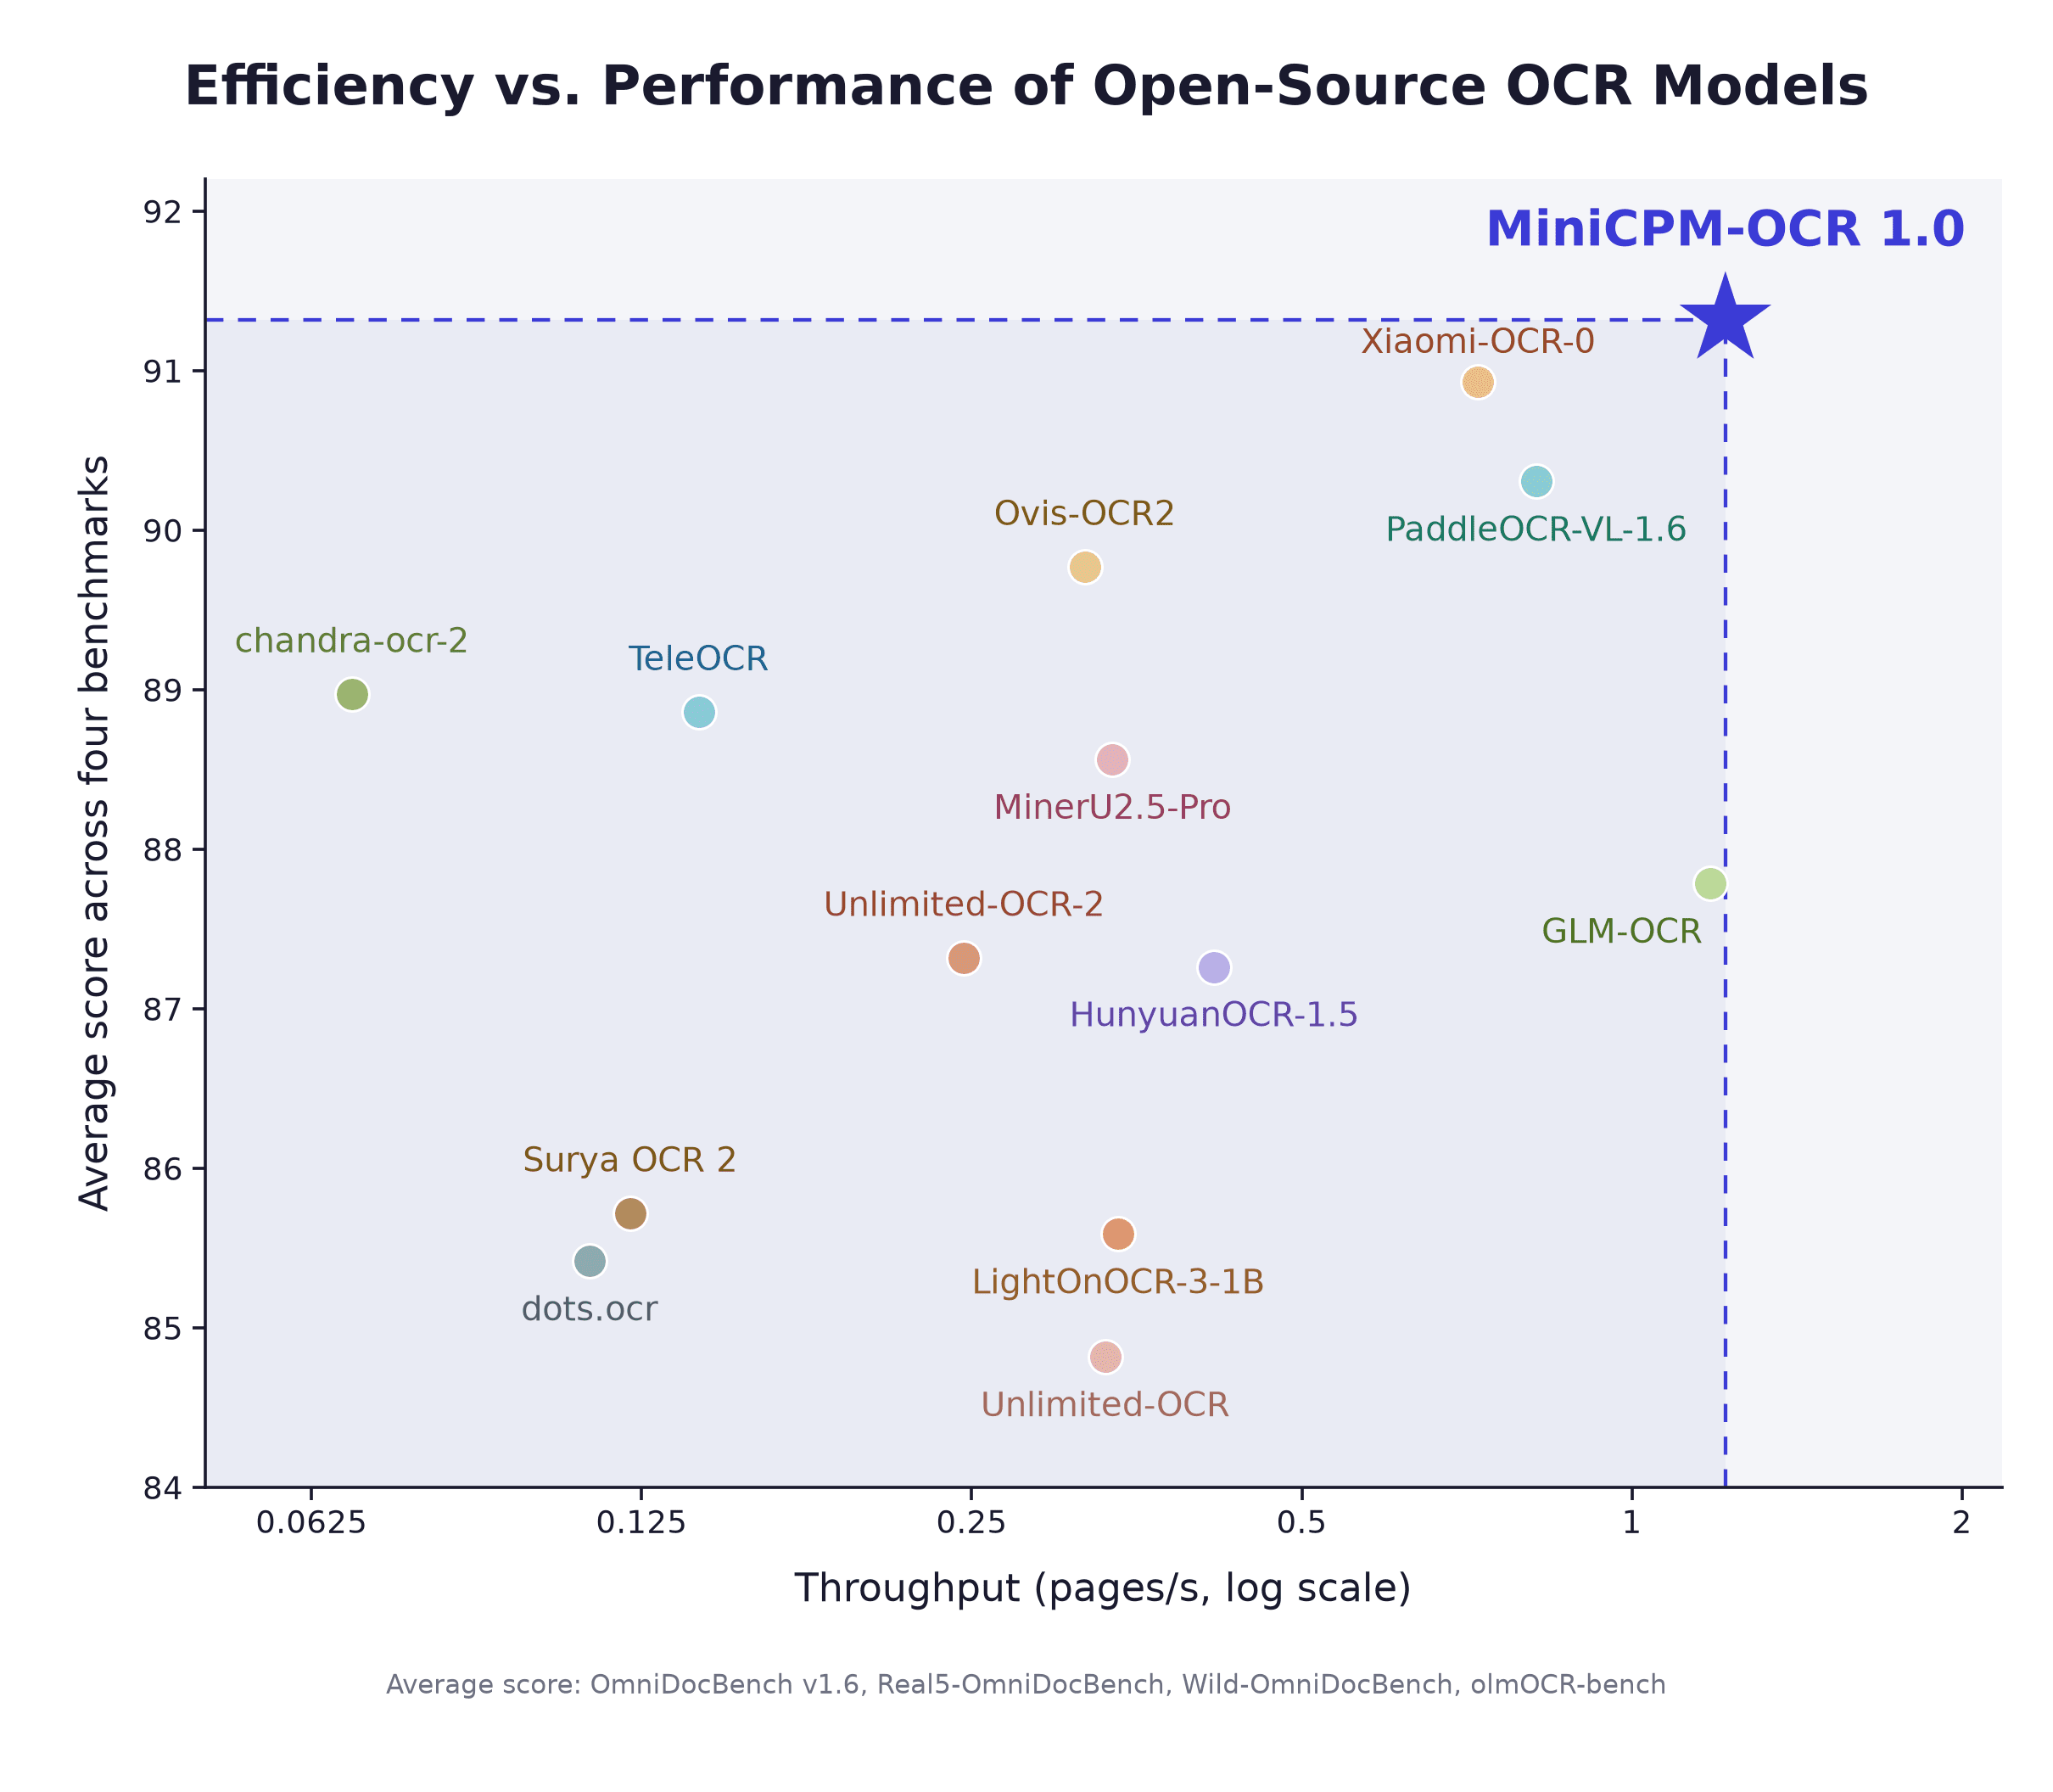
OpenBMB has released MiniCPM-OCR 1.0, a vision-language model aimed squarely at document understanding rather than general image chat. The model is built to parse pages the way a human reader does — extracting text while preserving structure like tables and mathematical formulas.
OCR has quietly become one of the most practical uses of multimodal models. Turning scanned reports, invoices, and academic papers into clean, structured text is a common bottleneck for enterprise pipelines, and models that handle layout well can replace brittle rule-based tooling.
What it does
- Parses document images into text with layout awareness
- Recognizes tables and reconstructs their structure
- Handles mathematical formula recognition
MiniCPM-OCR follows OpenBMB's broader MiniCPM line, which has emphasized small, efficient models that run on modest hardware. That focus matters here: document processing is often done at scale, where a lighter model can meaningfully cut cost and latency compared with calling a large general-purpose system.
The release carries a custom license, so teams evaluating it for commercial use should review the terms on the model page. As an initial 1.0 release, it establishes a baseline the project can iterate on, and signals that specialized OCR remains a lively corner of the open-weights ecosystem.
Sources
- Visit
openbmb/MiniCPM-OCR-1.0
Hugging Face
More from OpenBMB
All OpenBMB releases →
OpenBMB's MiniCPM-V 4.7 brings MoE to vision models
The new 35B-parameter vision-language model activates just 3B parameters per pass, aiming for efficiency without sacrificing capability.
MiniCPM-V 4.7 brings a 35B MoE vision model on-device
OpenBMB's latest multimodal release activates just 3B parameters per token, aiming to keep capable image understanding local.
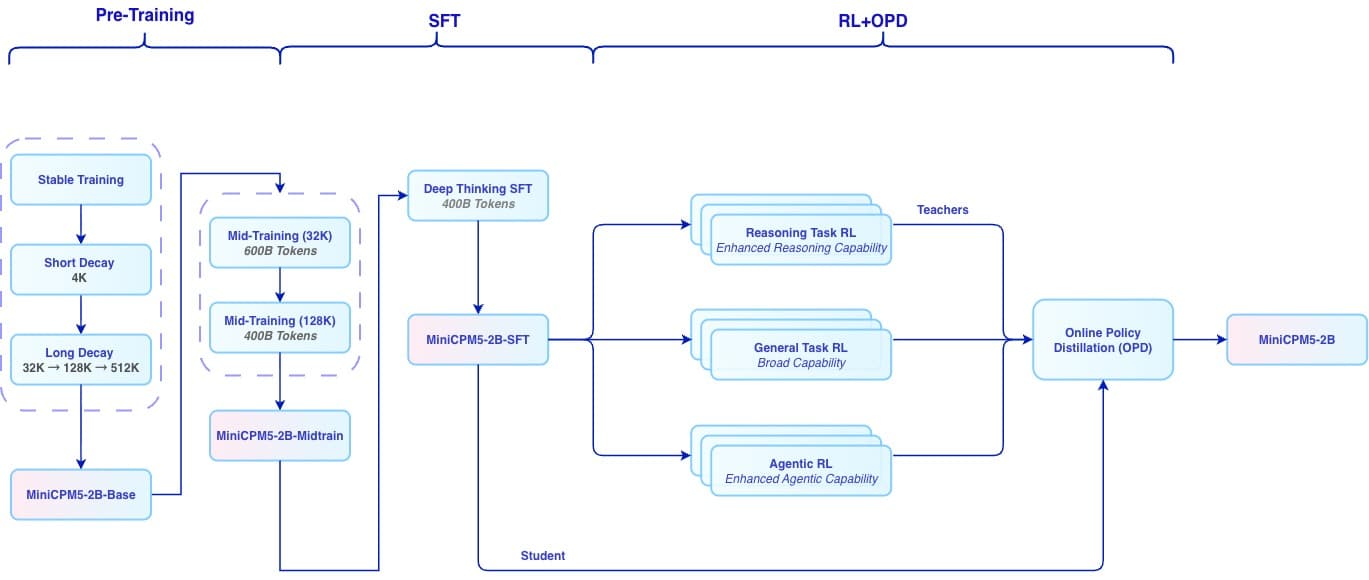
OpenBMB's MiniCPM5-2B targets on-device AI
The compact 2-billion-parameter model adds long-context handling and tool-calling in a footprint small enough to run locally.
More in Vision-Language
All Vision-Language →
Baidu releases Unlimited-OCR 2 under MIT license
The multilingual vision-language model targets document text recognition and ships with a permissive license for commercial use.

MiniMax Debuts M3.1 Flash, a Multimodal MoE Model
The new release pairs a mixture-of-experts design with agentic, coding, and video-understanding abilities in a single open model.

DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
0 comments
No comments yet. Be the first to weigh in.