OpenBMB's MiniCPM-V 4.7 brings MoE to vision models
The new 35B-parameter vision-language model activates just 3B parameters per pass, aiming for efficiency without sacrificing capability.
OpenBMB has released MiniCPM-V-4.7-35B-A3B, the latest entry in its MiniCPM-V line of multimodal models. The headline detail is architectural: this is a mixture-of-experts (MoE) vision-language model with 35 billion total parameters but only about 3 billion active on any given forward pass.
That design is the whole point. MoE lets a model hold a large pool of specialized parameters while routing each input through a small fraction of them, keeping inference costs closer to a 3B dense model than a 35B one. For a vision-language system, where image understanding typically adds significant compute, that efficiency can be the difference between a model that runs comfortably on modest hardware and one that doesn't.
Why it matters
The MiniCPM-V series has built a reputation for packing strong multimodal performance into compact footprints, and version 4.7 extends that philosophy with an MoE twist. Key points from the release:
- 35B total parameters with roughly 3B active per inference
- A vision-language focus, handling image and text inputs together
- Permissive Apache 2.0 licensing, allowing commercial use
The permissive license is notable for teams weighing deployment. Apache 2.0 removes much of the friction that accompanies more restrictive open-weight releases, making MiniCPM-V 4.7 a candidate for products as well as research.
OpenBMB has not published full benchmark details in the record here, so real-world evaluation will determine how the sparse-activation approach compares to dense peers. But the direction is clear: efficient multimodal models that trade raw size for smart routing. The weights are available now on Hugging Face.
Sources
- Visit
openbmb/MiniCPM-V-4.7-35B-A3B
Hugging Face
More from OpenBMB
All OpenBMB releases →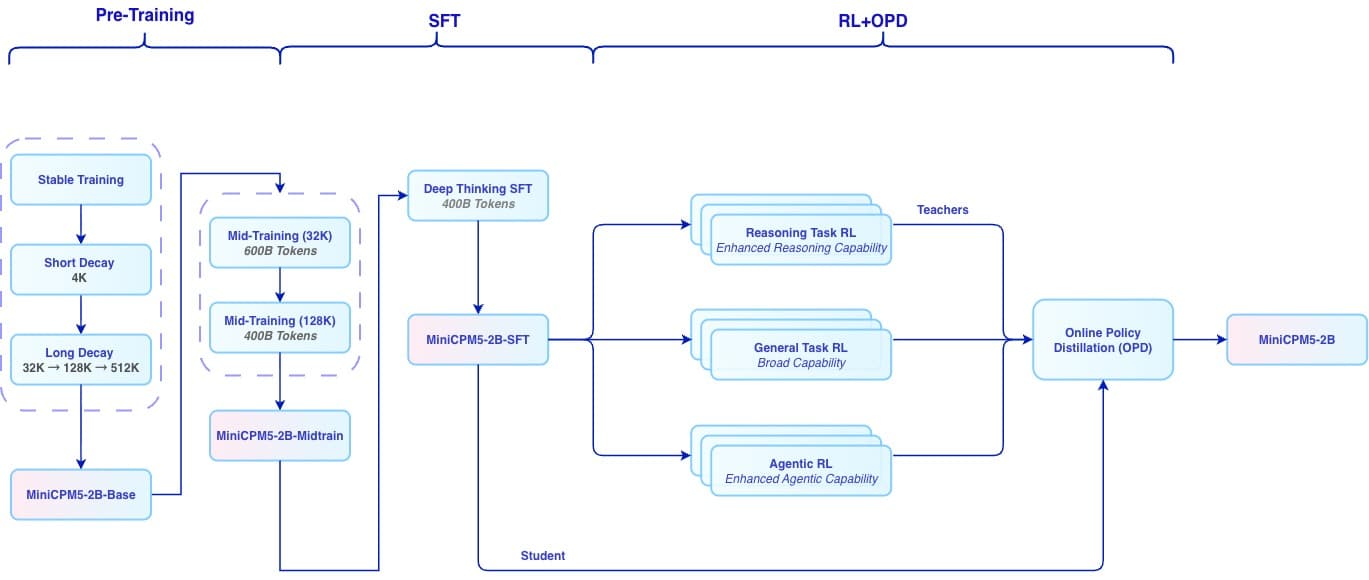
OpenBMB's MiniCPM5-2B targets on-device AI
The compact 2-billion-parameter model adds long-context handling and tool-calling in a footprint small enough to run locally.
NeoMME: a single-tower multilingual multimodal encoder
A new open encoder aims to make document retrieval faster by treating text and images natively in one model.
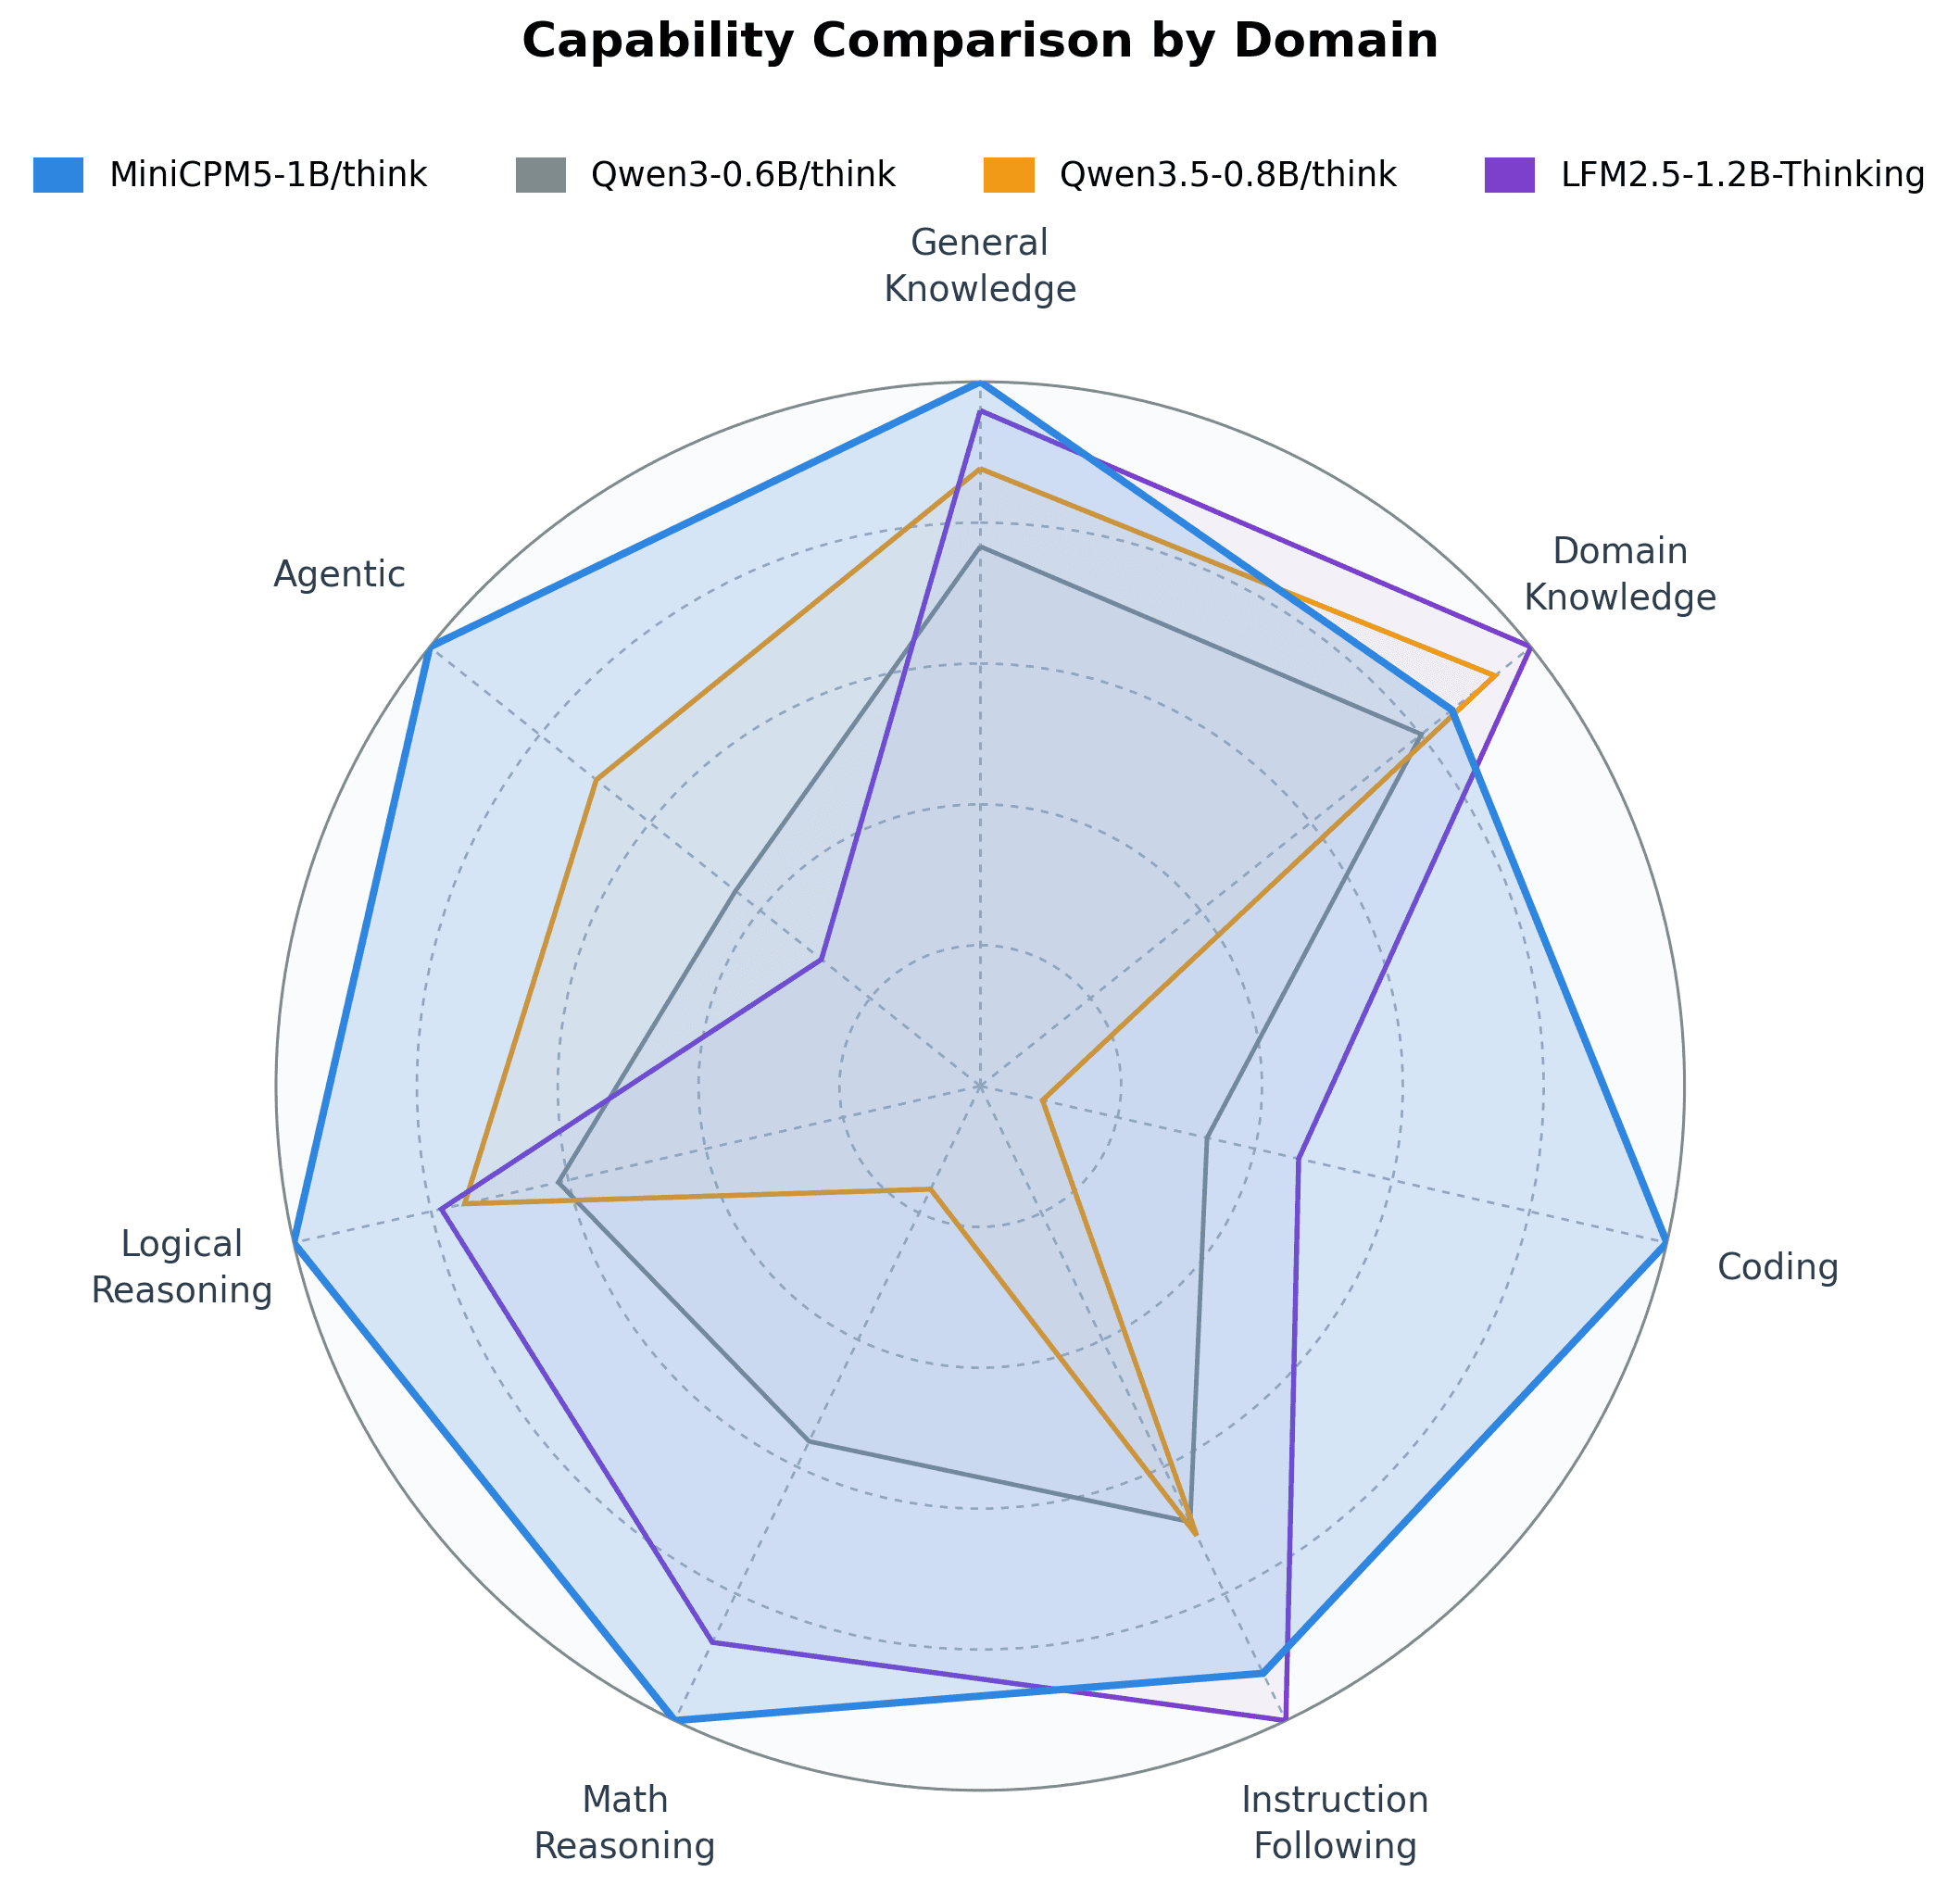
OpenBMB's MiniCPM5-1B targets on-device AI
The compact 1B-parameter model brings long-context handling and tool-calling to phones and laptops.
More in Vision-Language
All Vision-Language →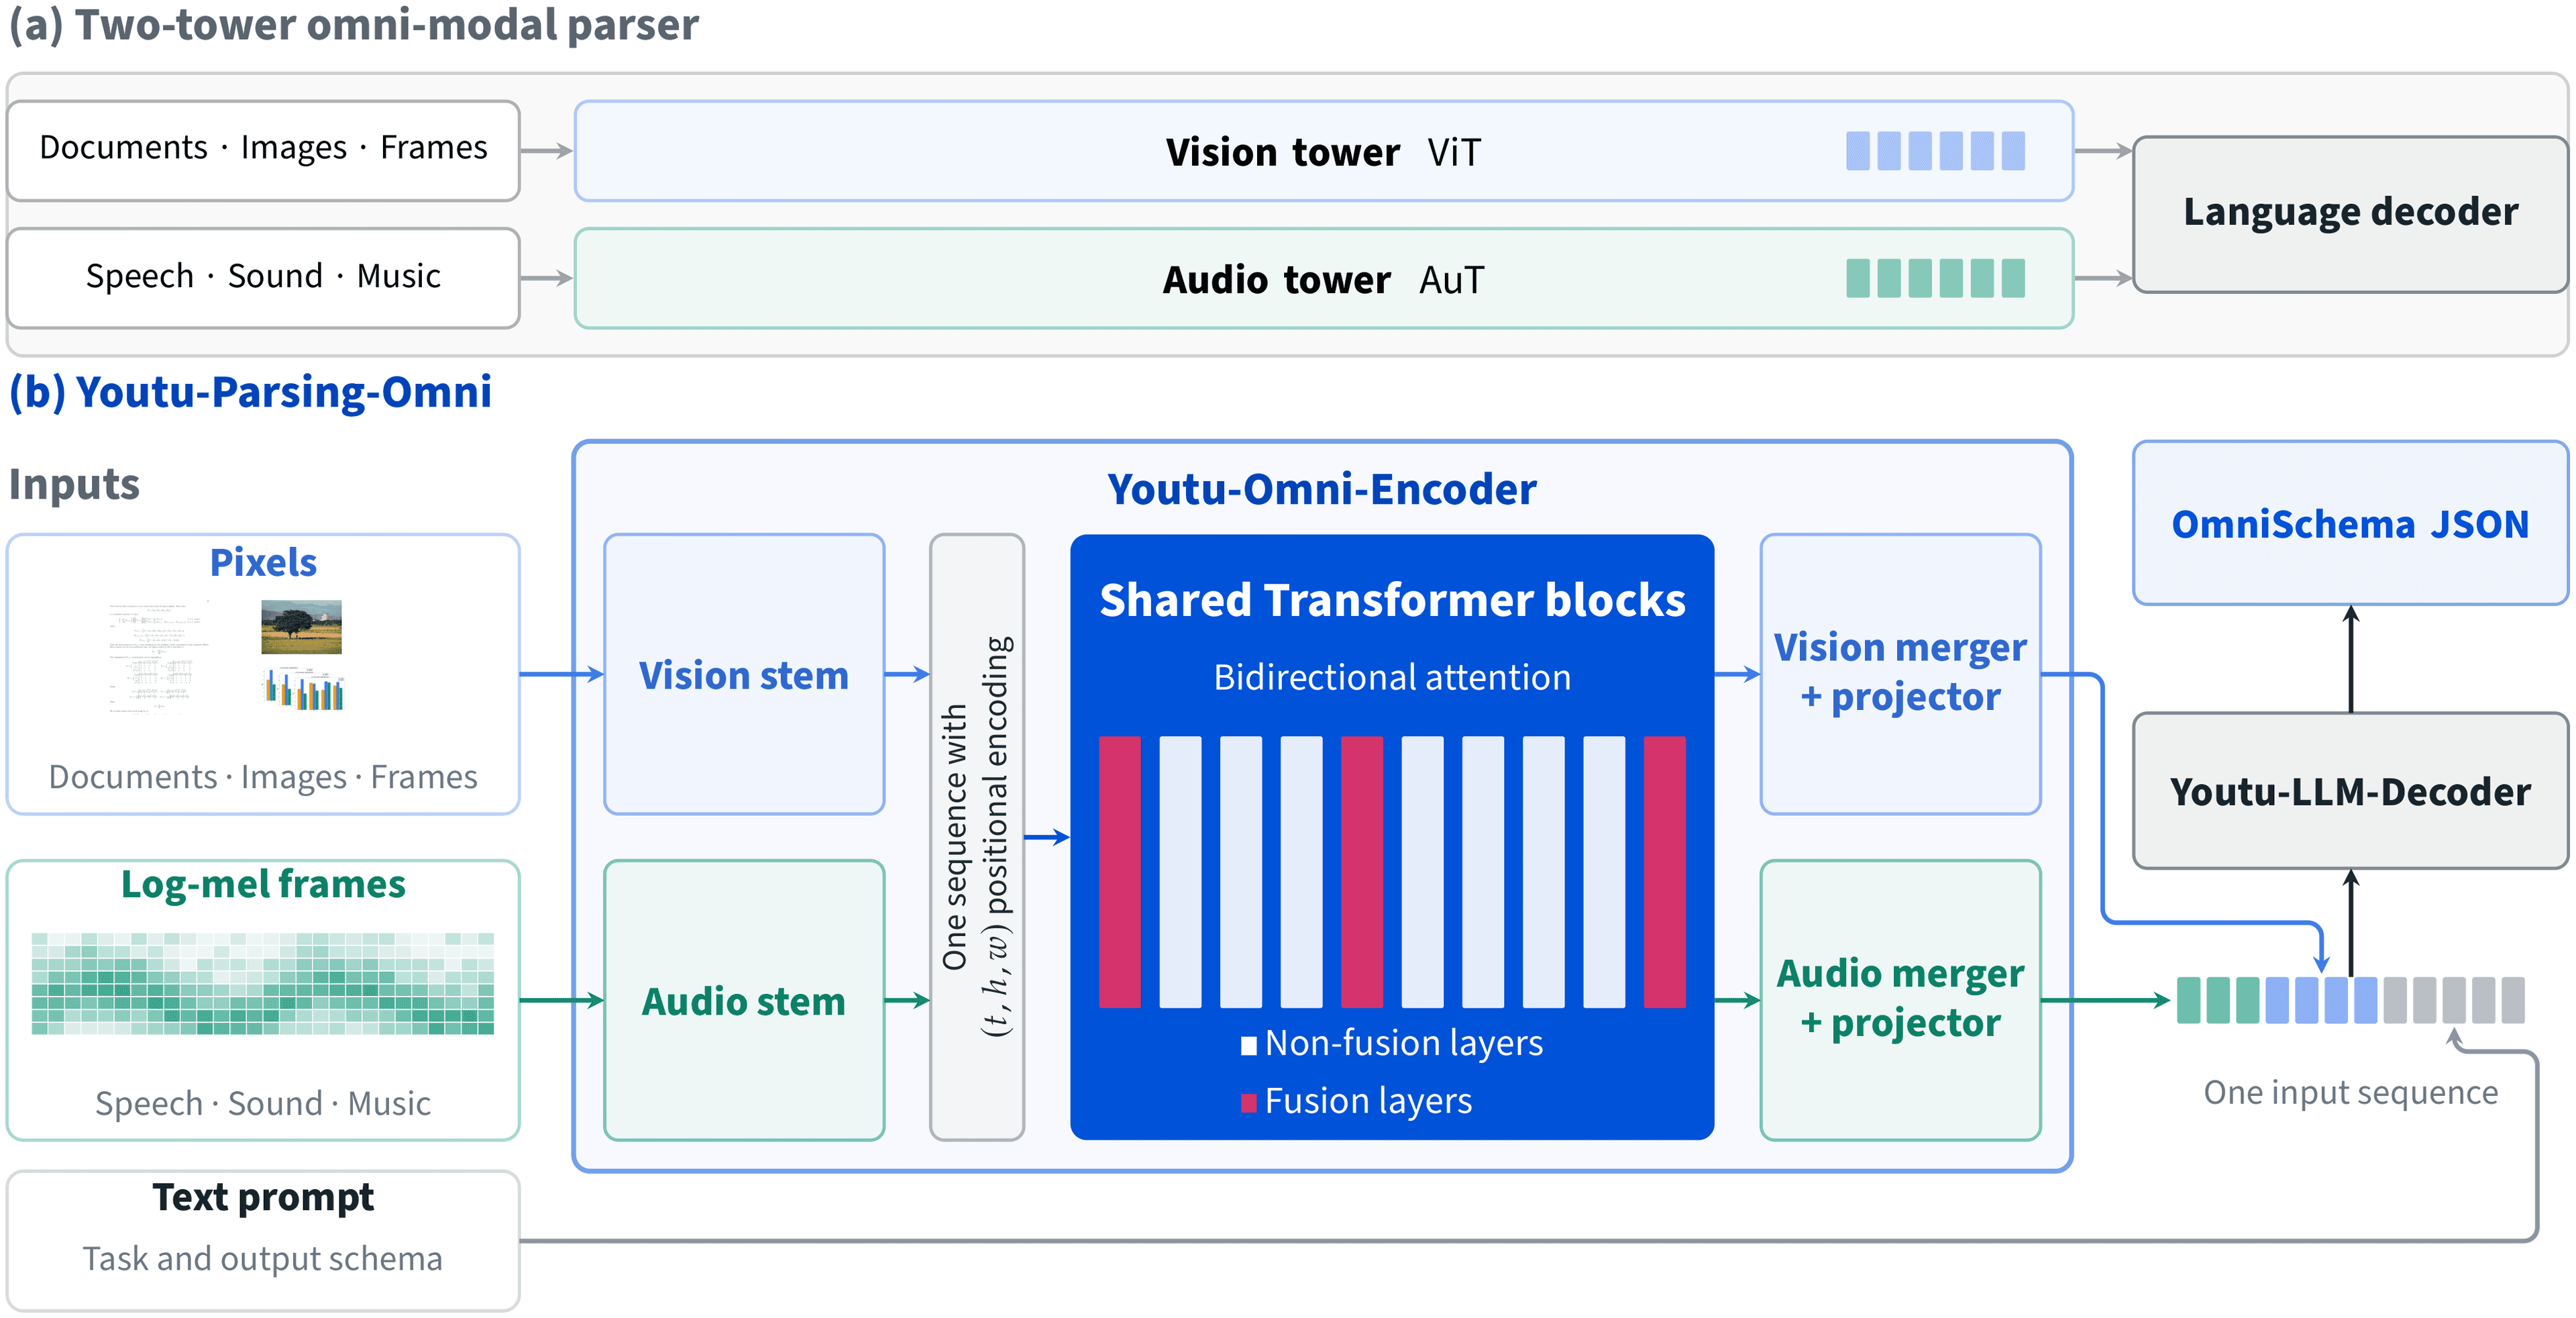
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
Liquid AI's d1-3B brings multimodal models to the edge
The new LFM2-based d1-3B is a compact vision-language model aimed at running decisions directly on-device.
LightOn ships a 4B OCR model with visual grounding
LightOnOCR-3-4B pairs document transcription with the ability to point back to where text sits on the page.
0 comments
No comments yet. Be the first to weigh in.