OpenBMB's Phonon Brings High-Quality TTS On-Device
The new text-to-speech model promises benchmark-topping voice synthesis that runs locally rather than in the cloud.
OpenBMB has introduced Phonon, a text-to-speech model designed to run directly on-device while delivering what the team describes as benchmark-leading audio quality. The release, detailed on Hugging Face, positions Phonon as an alternative to the cloud-hosted speech systems that dominate most voice applications today.
The pitch centers on a familiar tension in speech AI: the best-sounding models typically require server-side inference, which adds latency, cost, and privacy trade-offs. By targeting on-device deployment, Phonon aims to keep synthesis local — useful for applications where connectivity, responsiveness, or data sensitivity matter.
Why it matters
On-device speech has lagged cloud systems on naturalness, so a model that claims to top benchmarks while running locally is worth watching. Practical benefits of the local-first approach include:
- Lower latency, since audio is generated without a round trip to a server
- Better privacy, as text and voice data can stay on the device
- Offline capability for apps that can't rely on a constant connection
As with any new release, the benchmark claims deserve independent verification, and the model ships under a non-standard license that developers should review before building on it. Still, Phonon adds to OpenBMB's growing catalog of efficiency-focused models and reflects a broader push to move capable AI off the cloud and onto the hardware people already own.
Sources
- Visit
A Closer Look at Phonon TTS. Launching High-Quality On-Device Speech That Tops the Benchmarks.
Announcement
More from OpenBMB
All OpenBMB releases →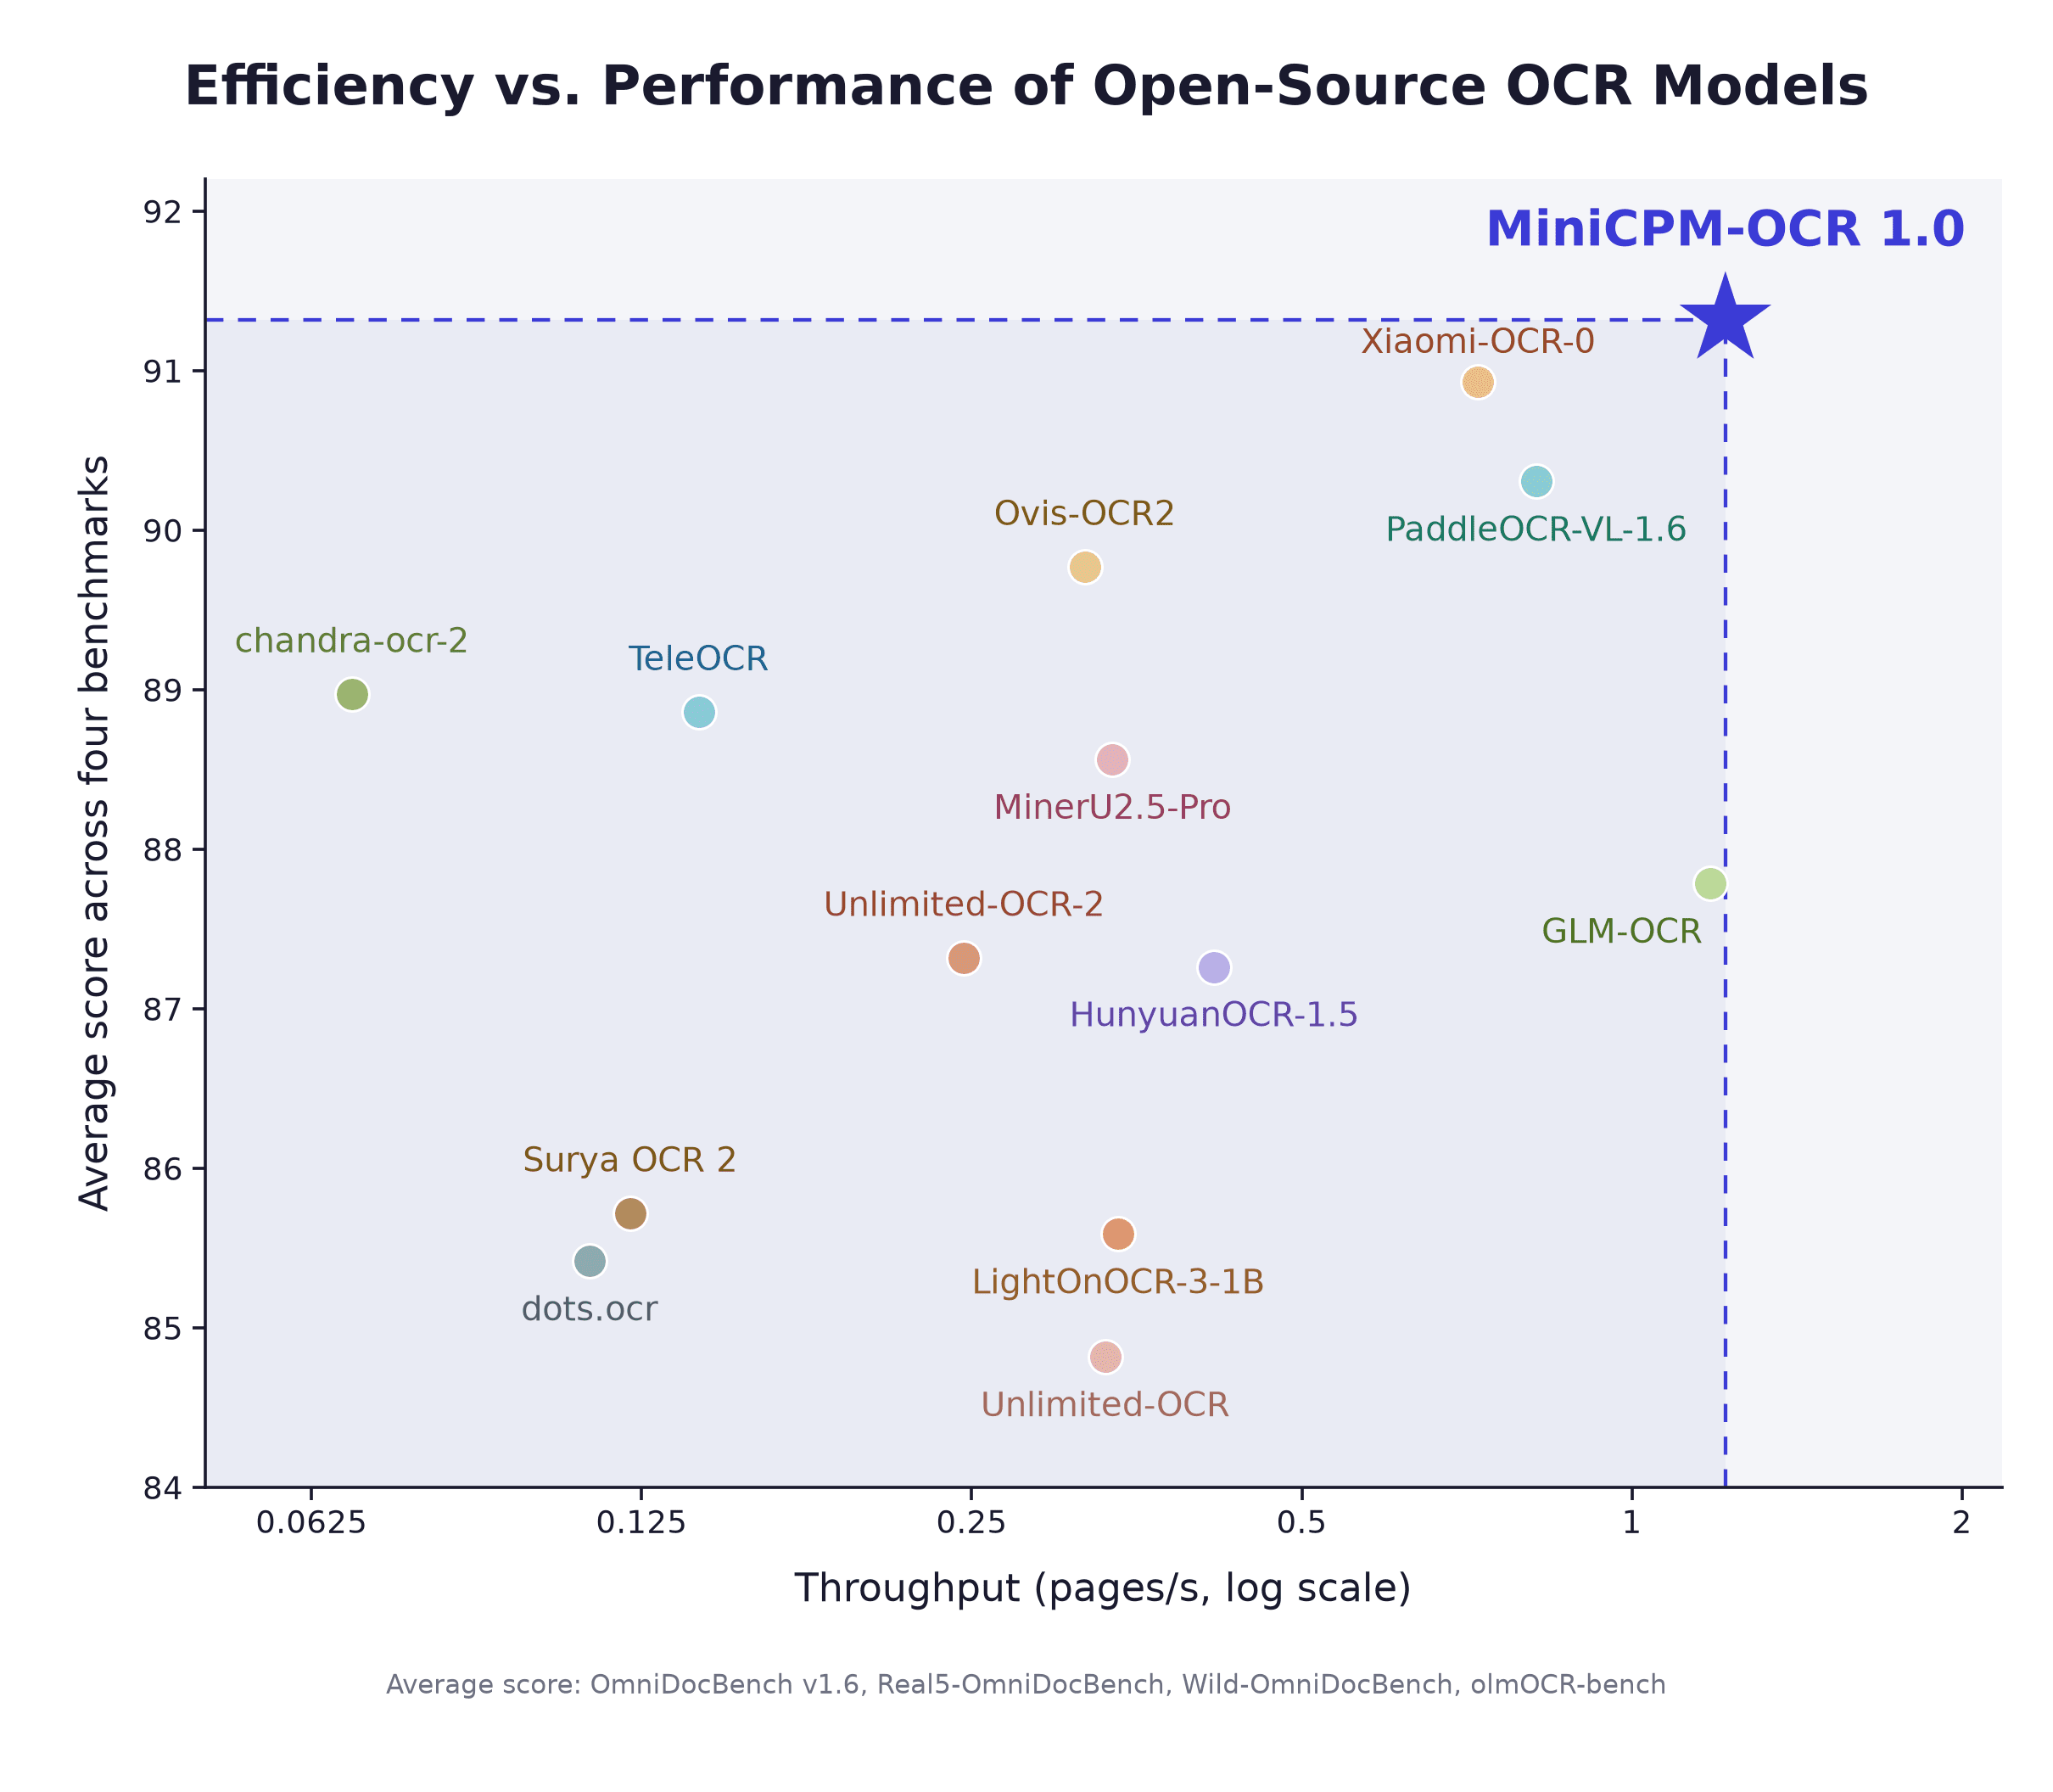
OpenBMB's MiniCPM-OCR 1.0 Targets Document Parsing
A compact vision-language model built to read tables, formulas, and complex page layouts arrives on Hugging Face.
OpenBMB's MiniCPM-V 4.7 brings MoE to vision models
The new 35B-parameter vision-language model activates just 3B parameters per pass, aiming for efficiency without sacrificing capability.
MiniCPM-V 4.7 brings a 35B MoE vision model on-device
OpenBMB's latest multimodal release activates just 3B parameters per token, aiming to keep capable image understanding local.
More in Text → Speech
All Text → Speech →ServiceNow Debuts Apriel Voice 27B, an Open Speech Model
The 27-billion-parameter preview unifies text-to-speech, transcription, and reasoning in a single open model.
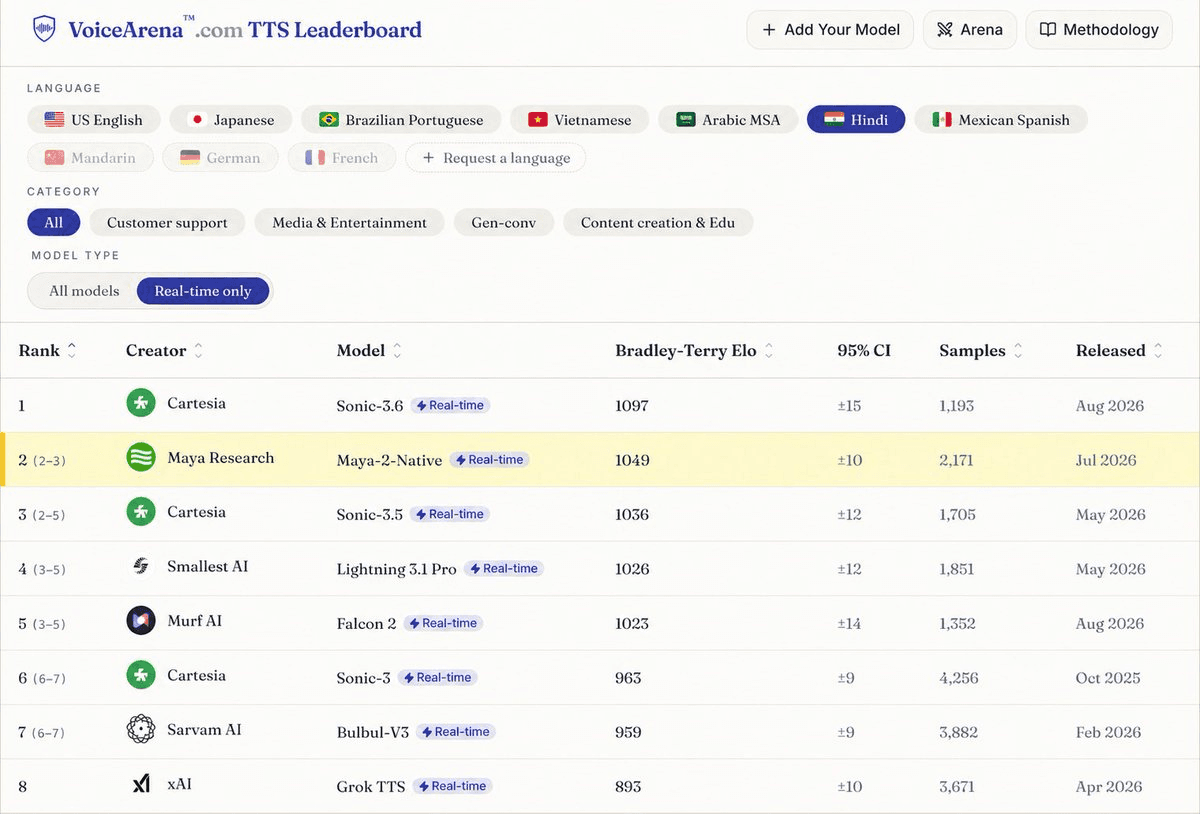
Maya2 Native brings streaming TTS to Indic languages
Maya Research's new open text-to-speech model targets Indian languages with voice cloning and real-time streaming output.
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
0 comments
No comments yet. Be the first to weigh in.