Maya2 Native brings streaming TTS to Indic languages
Maya Research's new open text-to-speech model targets Indian languages with voice cloning and real-time streaming output.
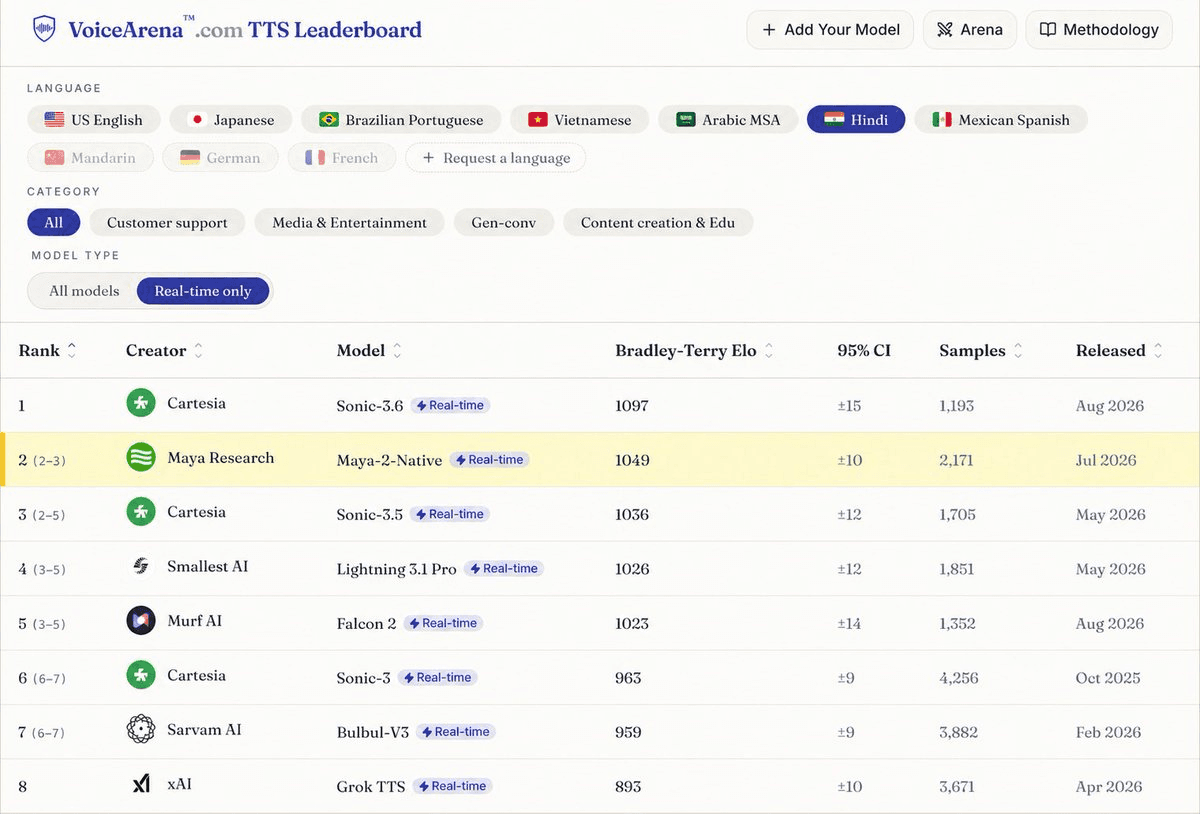
Maya Research has released Maya2 Native, an open text-to-speech model built for streaming audio generation with a clear emphasis on Indian languages. The model supports voice cloning and multilingual synthesis, with its stated focus on the Indic language family.
Streaming is the practical centerpiece here. Rather than producing an entire clip before playback, a streaming TTS system emits audio incrementally, which keeps latency low enough for conversational and interactive applications. Paired with voice cloning, that makes the model a candidate for assistants, dubbing, and accessibility tools that need to speak naturally in regional languages.
Why it matters
High-quality speech synthesis has long skewed toward English and a handful of global languages, leaving India's many widely spoken tongues underserved. A model that treats Indic languages as a first-class target helps close that gap:
- Streaming output for low-latency, real-time use
- Voice cloning from reference audio
- Multilingual coverage anchored in Indian languages
The release is distributed on Hugging Face under a non-standard license, so teams should review the terms before building on it. As an initial entry in the Maya2 line, it will be worth watching how the model's voice quality and language coverage hold up against established open TTS systems in real deployments.
Sources
- Visit
maya-research/maya2-native
Hugging Face
More from Maya Research
All Maya Research releases →
Maya Research Releases Maya1, an Expressive TTS Model
The new Apache 2.0 licensed model uses a Llama-based architecture to generate more natural and emotionally nuanced speech from text.
Veena TTS Model Targets Indian Languages with Llama Base
Maya Research has released a 3-billion-parameter model designed to generate natural-sounding speech in Hindi and English.
More in Text → Speech
All Text → Speech →ServiceNow Debuts Apriel Voice 27B, an Open Speech Model
The 27-billion-parameter preview unifies text-to-speech, transcription, and reasoning in a single open model.

Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
IBM's Granite Switch 4.1 Unifies Chat, Logic, Speech
A single endpoint now routes text conversation, decision-making, and speech synthesis across IBM's Apache-licensed Granite line.
0 comments
No comments yet. Be the first to weigh in.