The Open Weights
LatestModelsLeaderboardsCompanies
Subscribe
The Open Weights

The daily record of open-source AI. New model releases, leaderboards, and what's coming next — written for people who ship.

Refreshed every 12 hours

Discover

  • Latest releases
  • New today
  • Trending models

Browse

  • All models
  • Companies
  • Categories
  • Leaderboards

About

  • About
  • Editorial policy
  • Hardware estimates
  • RSS feed
  • llms.txt
  • Newsletter

© 2026 The Open Weights. An independent publication.

PrivacyTermsSMSAggregated by Claude · curated by humans.

Category · audio

Latest Speech → Text models

Open speech-recognition models that transcribe audio to text across languages — for captioning, voice interfaces, and pipelines you run on your own infrastructure.

Filter

51 releases

IBM/Speech → Text

IBM's Granite Speech 5.0 Adds Speaker Attribution

The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.

Oct 21, 2026
Speech → Text
Qwen · Alibaba/Speech → Text

Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription

Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.

Oct 19, 2026
Speech → Text
NVIDIA/Speech → TextWorkstation GPU

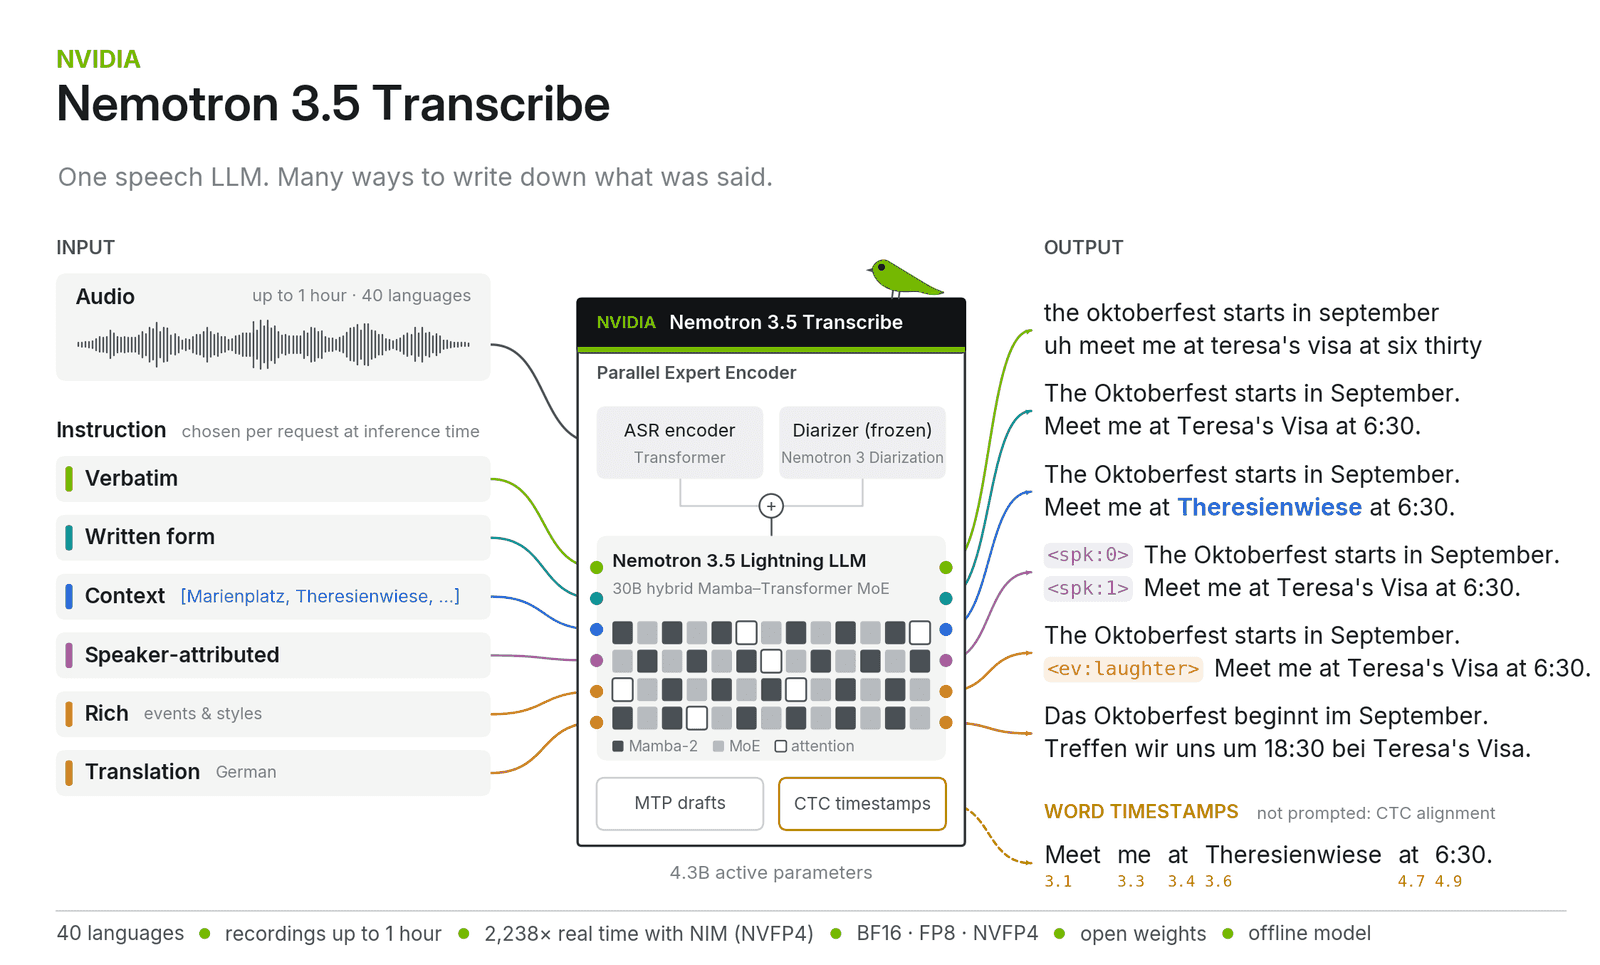
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR

A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.

Oct 7, 2026
Speech → Text
Nemotron 3.5 Transcribe 30B-A4B
NVIDIA/Speech → Text

TII Brings Falcon to Speech With New ASR Model

The team behind the Falcon language models expands into speech-to-text with its first automatic speech recognition release.

Oct 7, 2026
Speech → Text
IBM/Speech → Text

TII extends the Falcon family into speech recognition

The Abu Dhabi lab behind the Falcon language models releases Falcon ASR, an open speech-to-text system.

Oct 7, 2026
Speech → Text
Cactus Compute/Speech → Text

Cactus Compute's Whistle brings speech-to-text to the edge

A compact on-device ASR model built for edge hardware and WebAssembly, with early support for English, German, and French.

Sep 30, 2026
Speech → Text
Whistle
FermionResearch/Speech → TextRuns anywhere

Phonon-2 brings on-device ASR to Apple Silicon

A low-bit quantized, Parakeet-based speech recognizer built to run locally on Mac hardware.

Sep 28, 2026
Speech → Text
Phonon-2
Edge0/Speech → TextRuns on a laptop

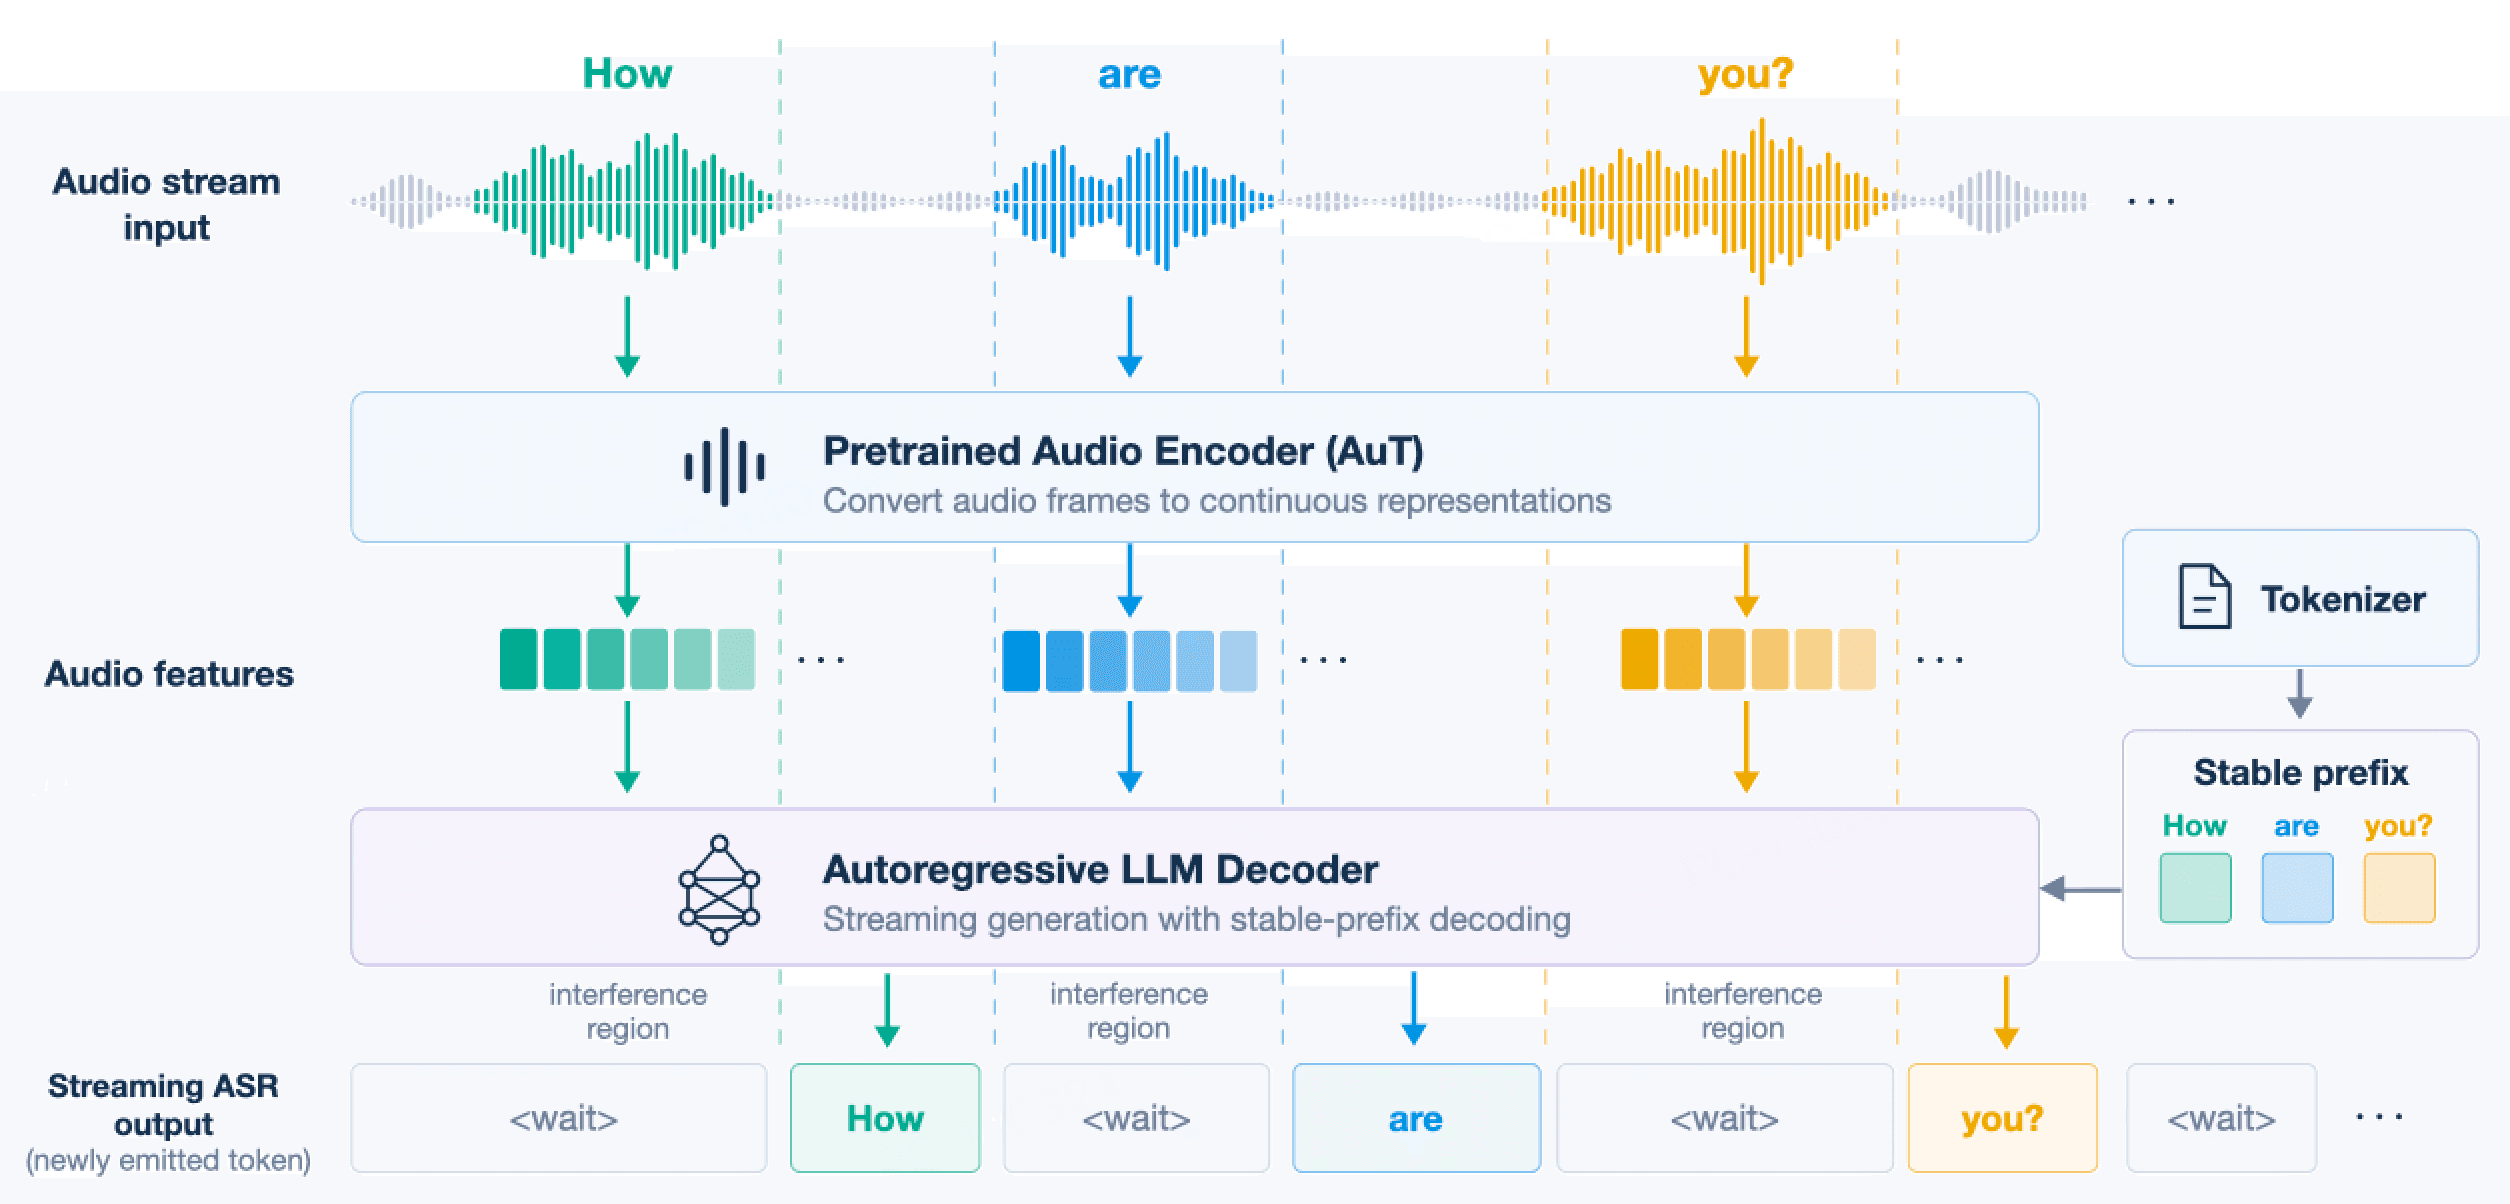
Audio8-ASR-Infinite brings streaming bilingual speech recognition

A new open model targets real-time transcription for Chinese and English audio.

Sep 21, 2026
Speech → Text
Audio8-ASR-Infinite
moondream/Speech → TextRuns anywhere

Moondream shrinks Parakeet ASR for CPUs

A ternary-quantized take on the Parakeet TDT speech model aims to run transcription without a GPU.

Sep 18, 2026
Speech → Text
Parakeet Redux
Unknown/Text → Speech

Nari Labs Ships Qwen3-Based TTS and ASR Models

The startup pairs speech synthesis and recognition built on Qwen3, pitching accuracy, low latency, and lower cost.

Sep 14, 2026
Speech → TextText → Speech
StepFun/Text → Speech

StepFun's StepAudio 3 Realtime targets live voice AI

The audio-language foundation model builds a listen-converse-think-act loop aimed at natural, low-latency spoken interaction.

Sep 11, 2026
Speech → TextAny-to-Any
Netease Youdao/Speech → TextRuns anywhere

NetEase Youdao debuts Confucius4-R2T2 streaming ASR

The multilingual speech-to-text model targets low latency and ships with vLLM support for production deployments.

Sep 10, 2026
Speech → Text
Confucius4-R2T2
Microsoft/Speech → TextRuns on a laptop

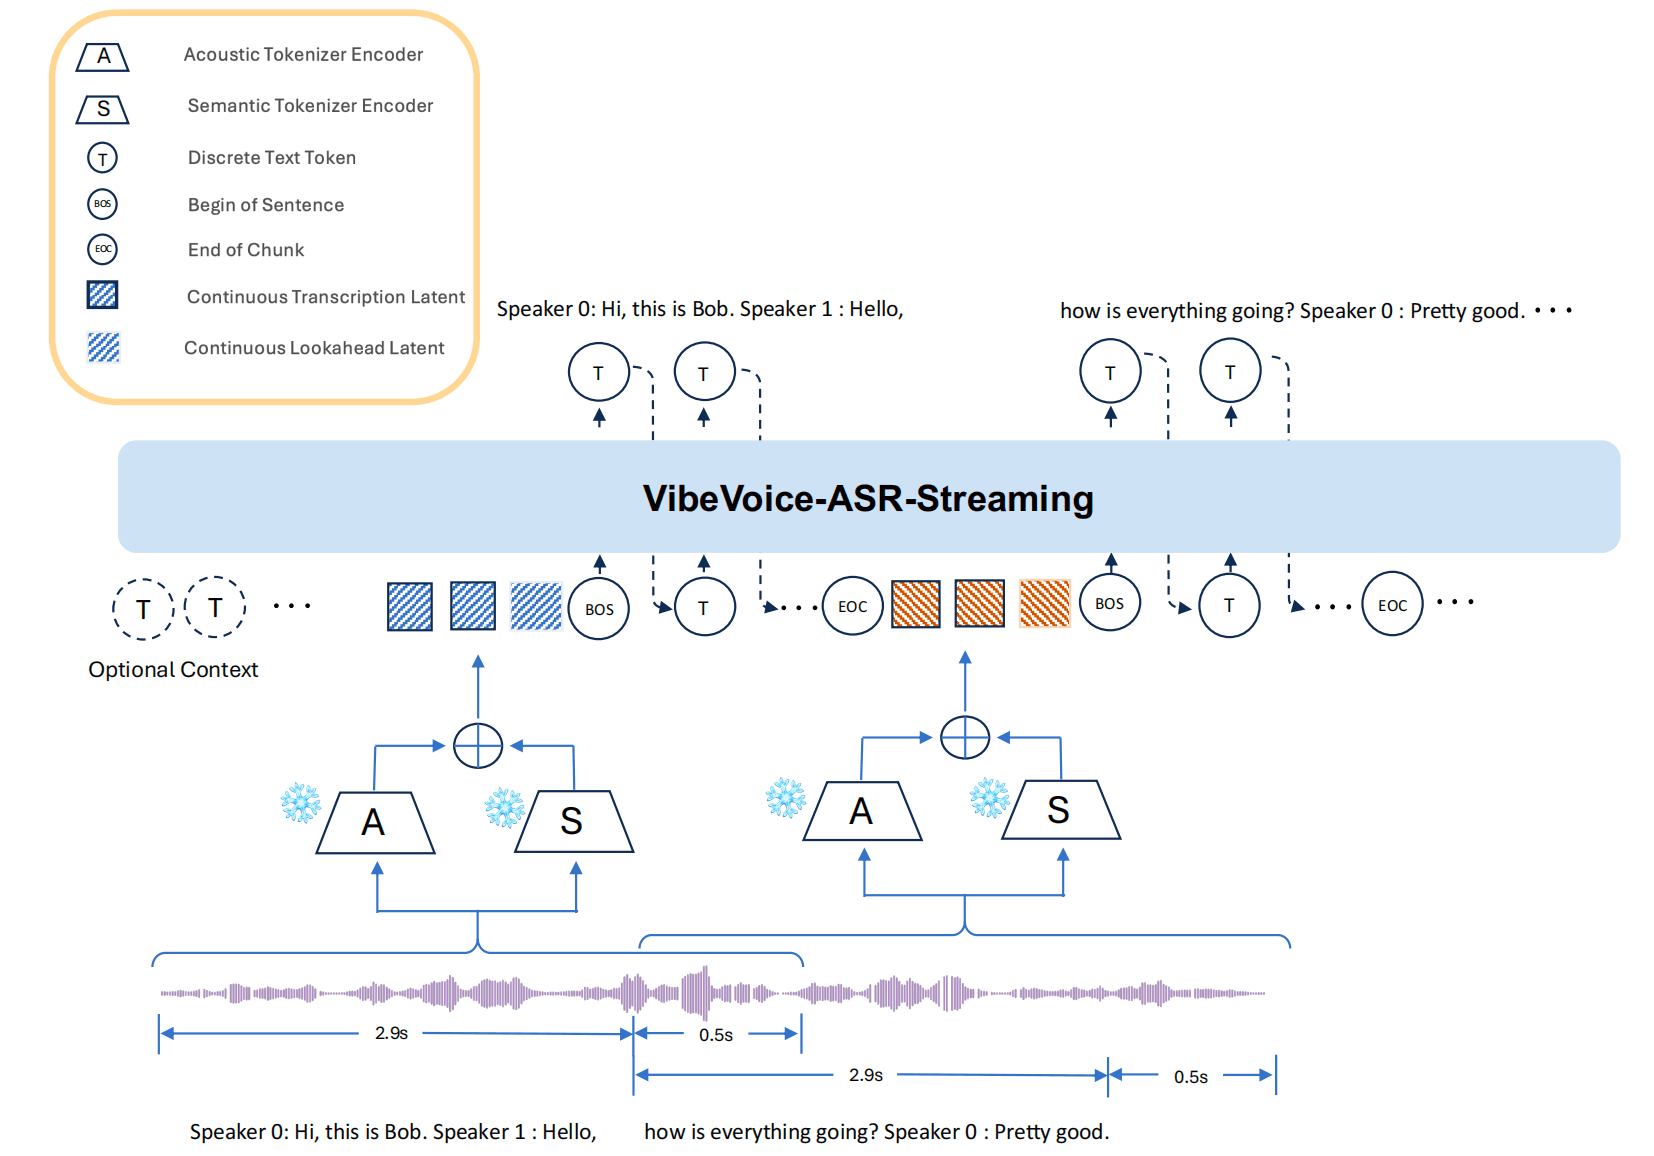
Microsoft's VibeVoice ASR brings streaming speech-to-text

A 7-billion-parameter model targets real-time, multilingual transcription with an open release on Hugging Face.

Sep 2, 2026
Speech → Text
VibeVoice-ASR-Streaming-7B
NVIDIA/Speech → TextRuns anywhere

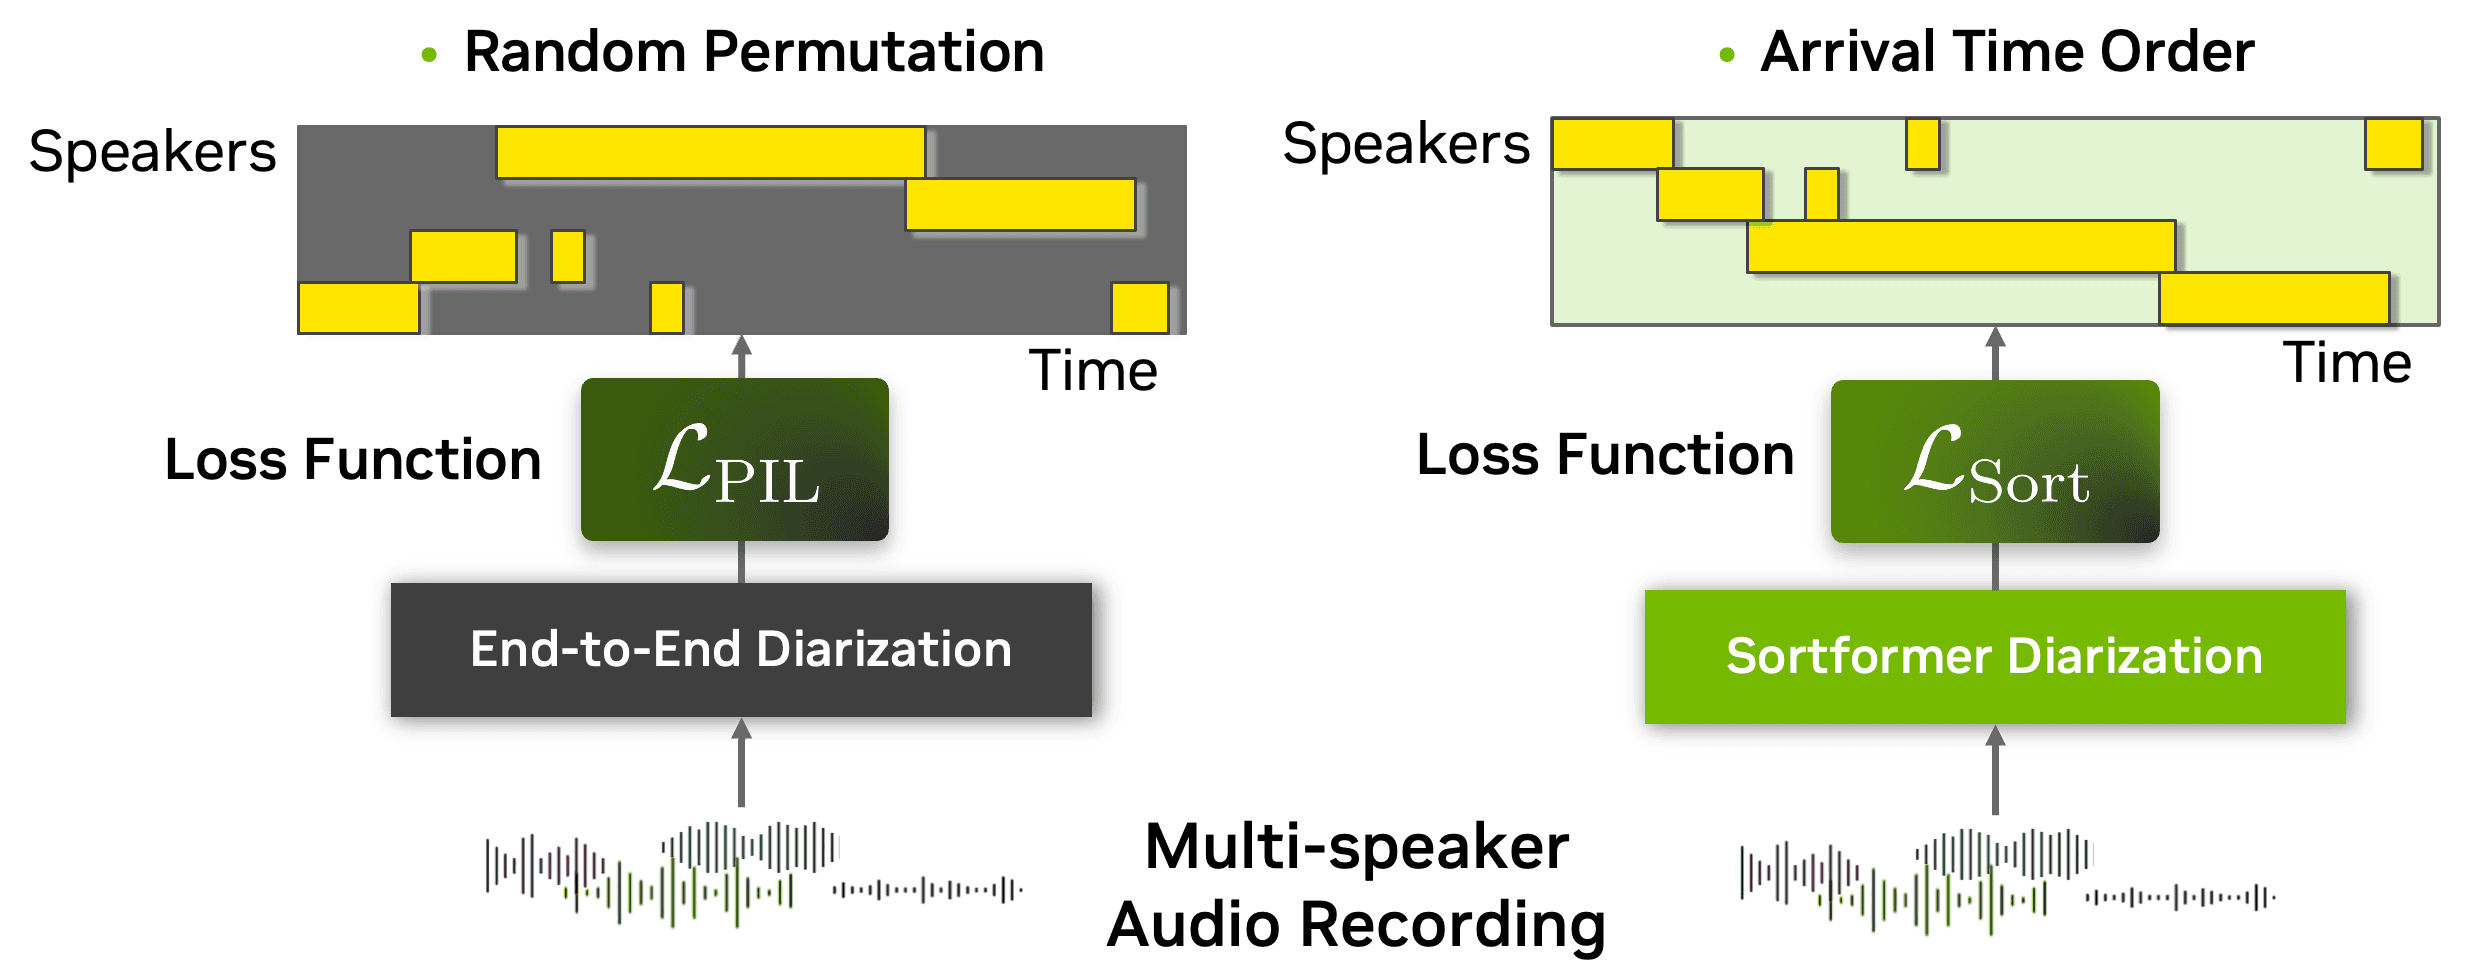
NVIDIA's Nemotron-3 Brings Streaming Speaker Diarization

The new open model applies NVIDIA's Sortformer approach to identify who's speaking, in real time.

Sep 1, 2026
Speech → Text
Nemotron-3-Diarization
Superwhisper/Speech → TextRuns anywhere

Superwhisper's s1-mini polishes raw speech-to-text output

A compact Qwen3-based model tackles the unglamorous cleanup work that makes transcripts readable.

Aug 12, 2026
Speech → Text
s1-mini
Shunyalabs/Speech → Text

Vak Conformer targets speech recognition in six Indic languages

Shunya Labs releases a Conformer-based ASR model aimed at India's underserved language landscape.

Aug 10, 2026
Speech → Text
Vak Conformer
KRAFTON/Any-to-AnyRuns on a laptop

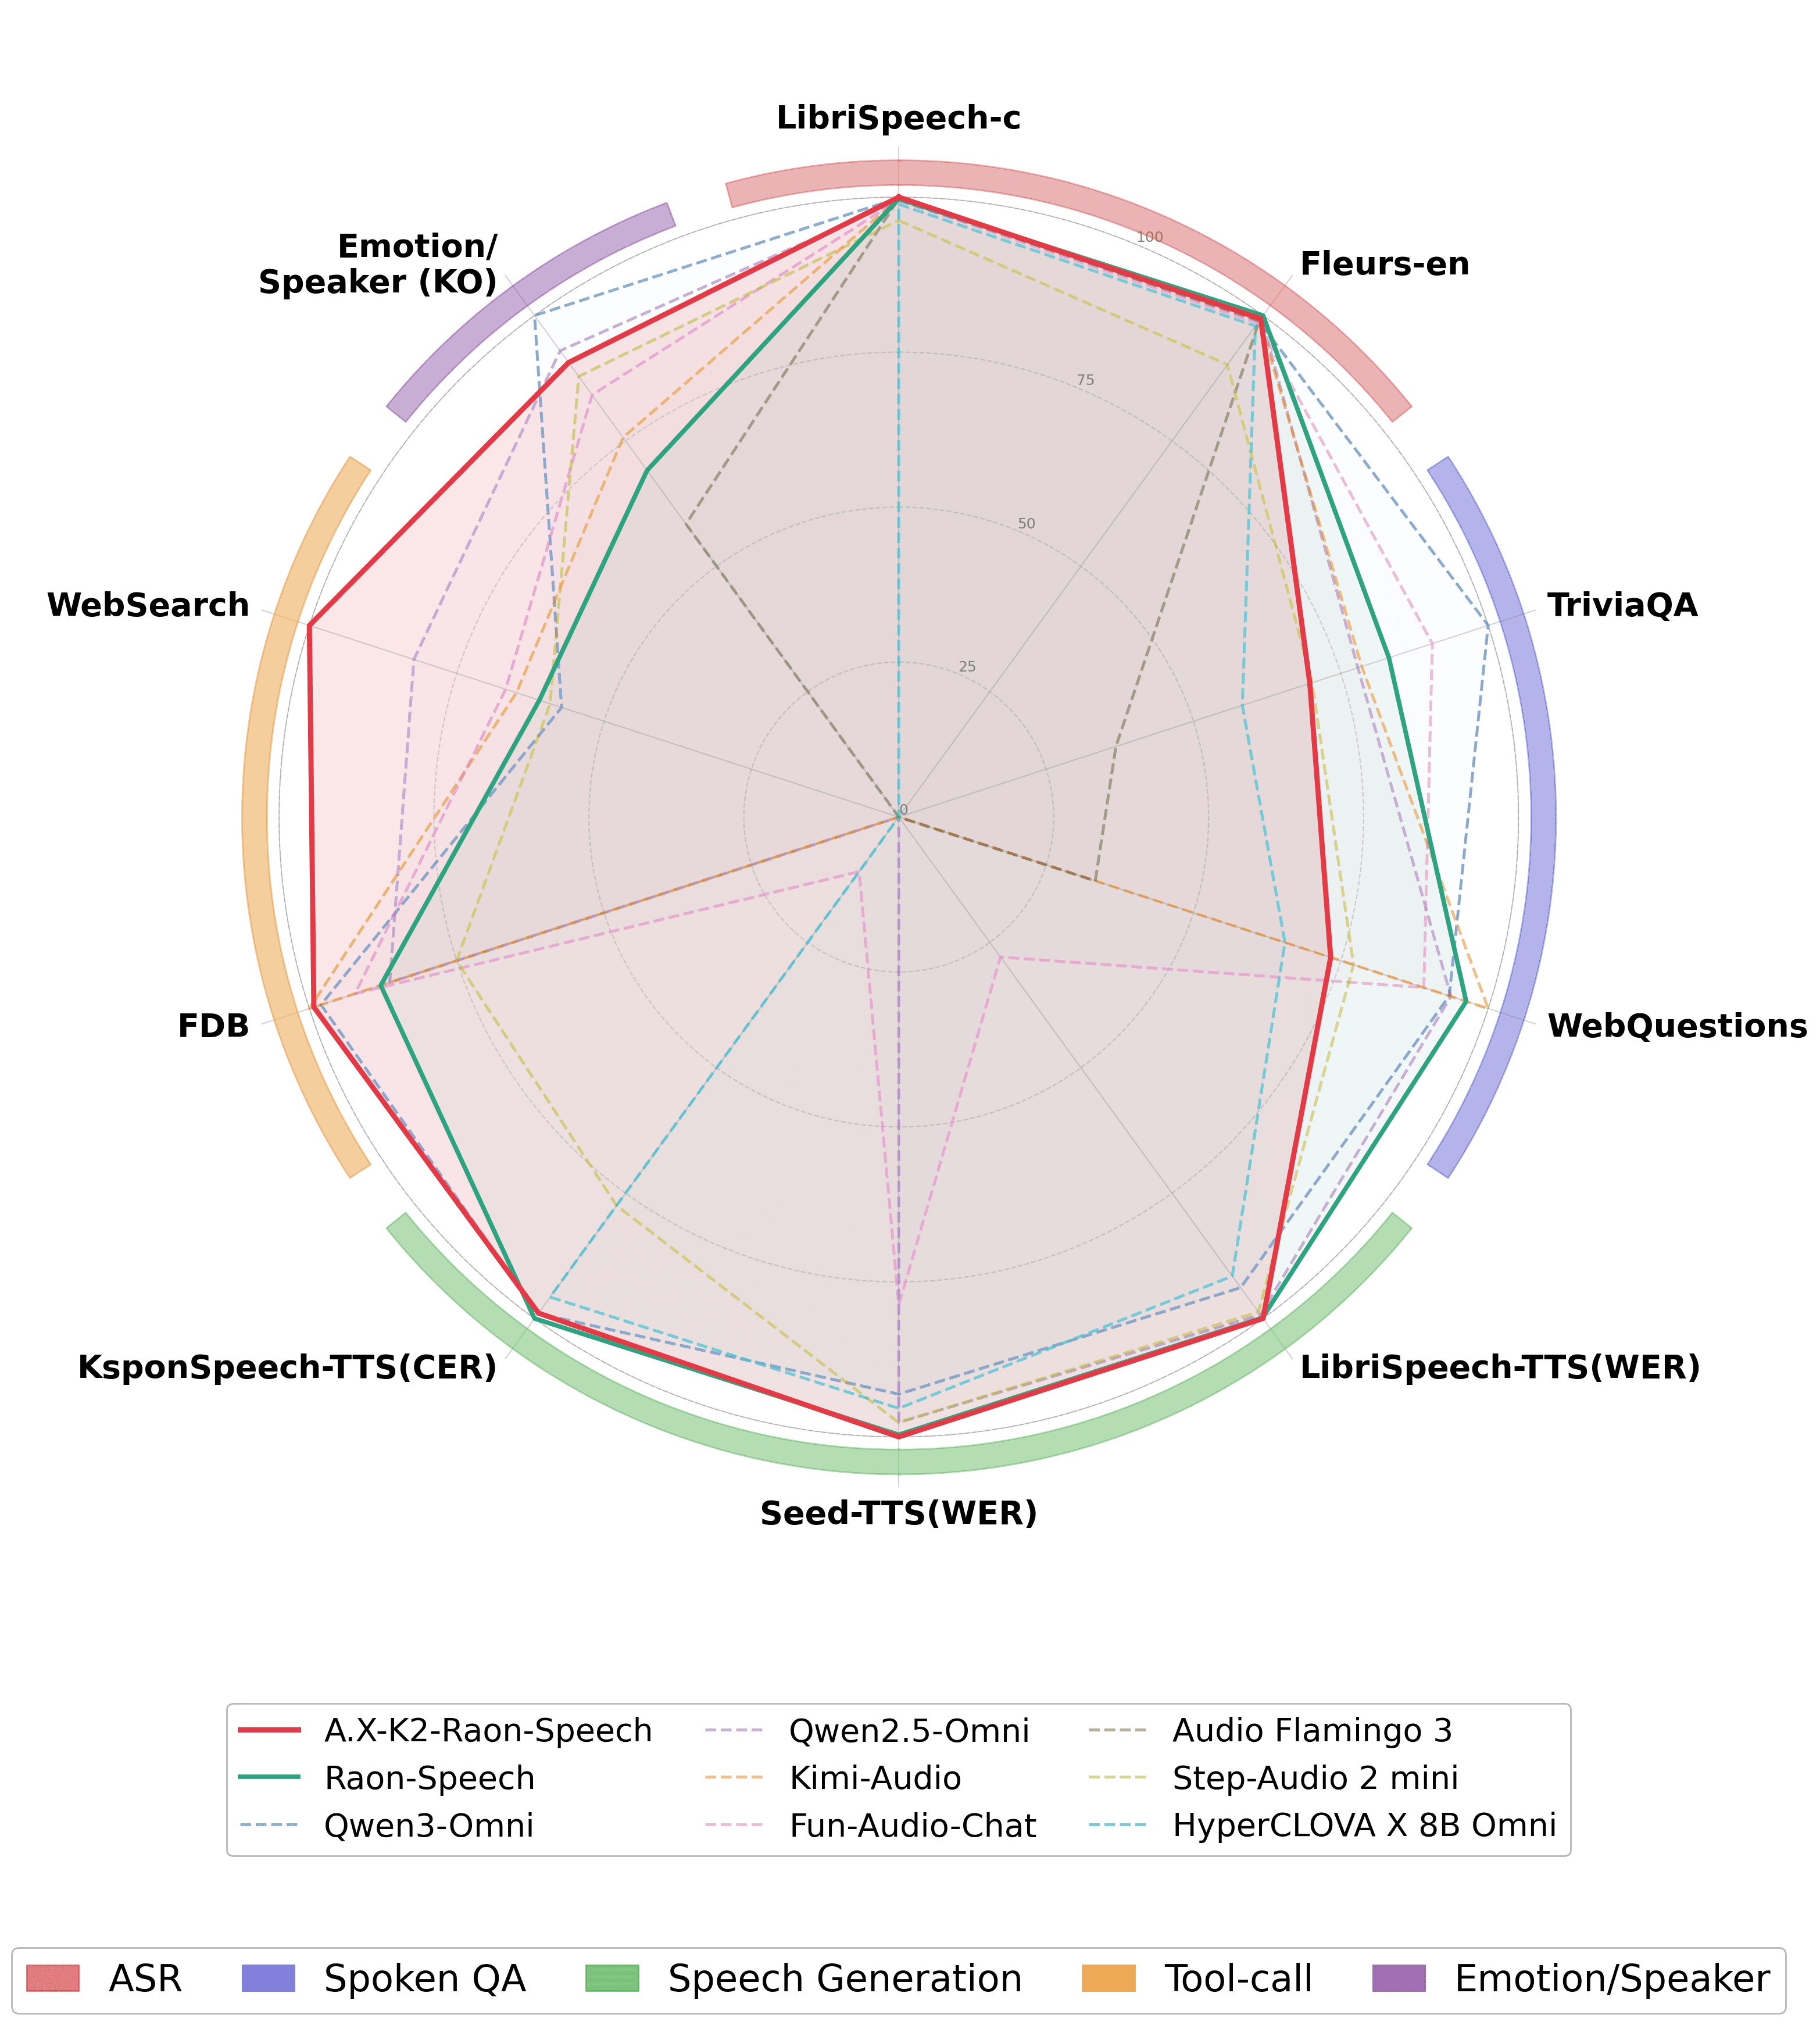
KRAFTON releases A.X-K2 Raon speech MoE model

The game maker's new open model blends text-to-speech and speech recognition in a single 21B mixture-of-experts system with just 3B active parameters.

Jul 27, 2026
Speech → TextAny-to-Any
A.X-K2 Raon Speech 21B-A3B
Microsoft/Speech → TextRuns anywhere

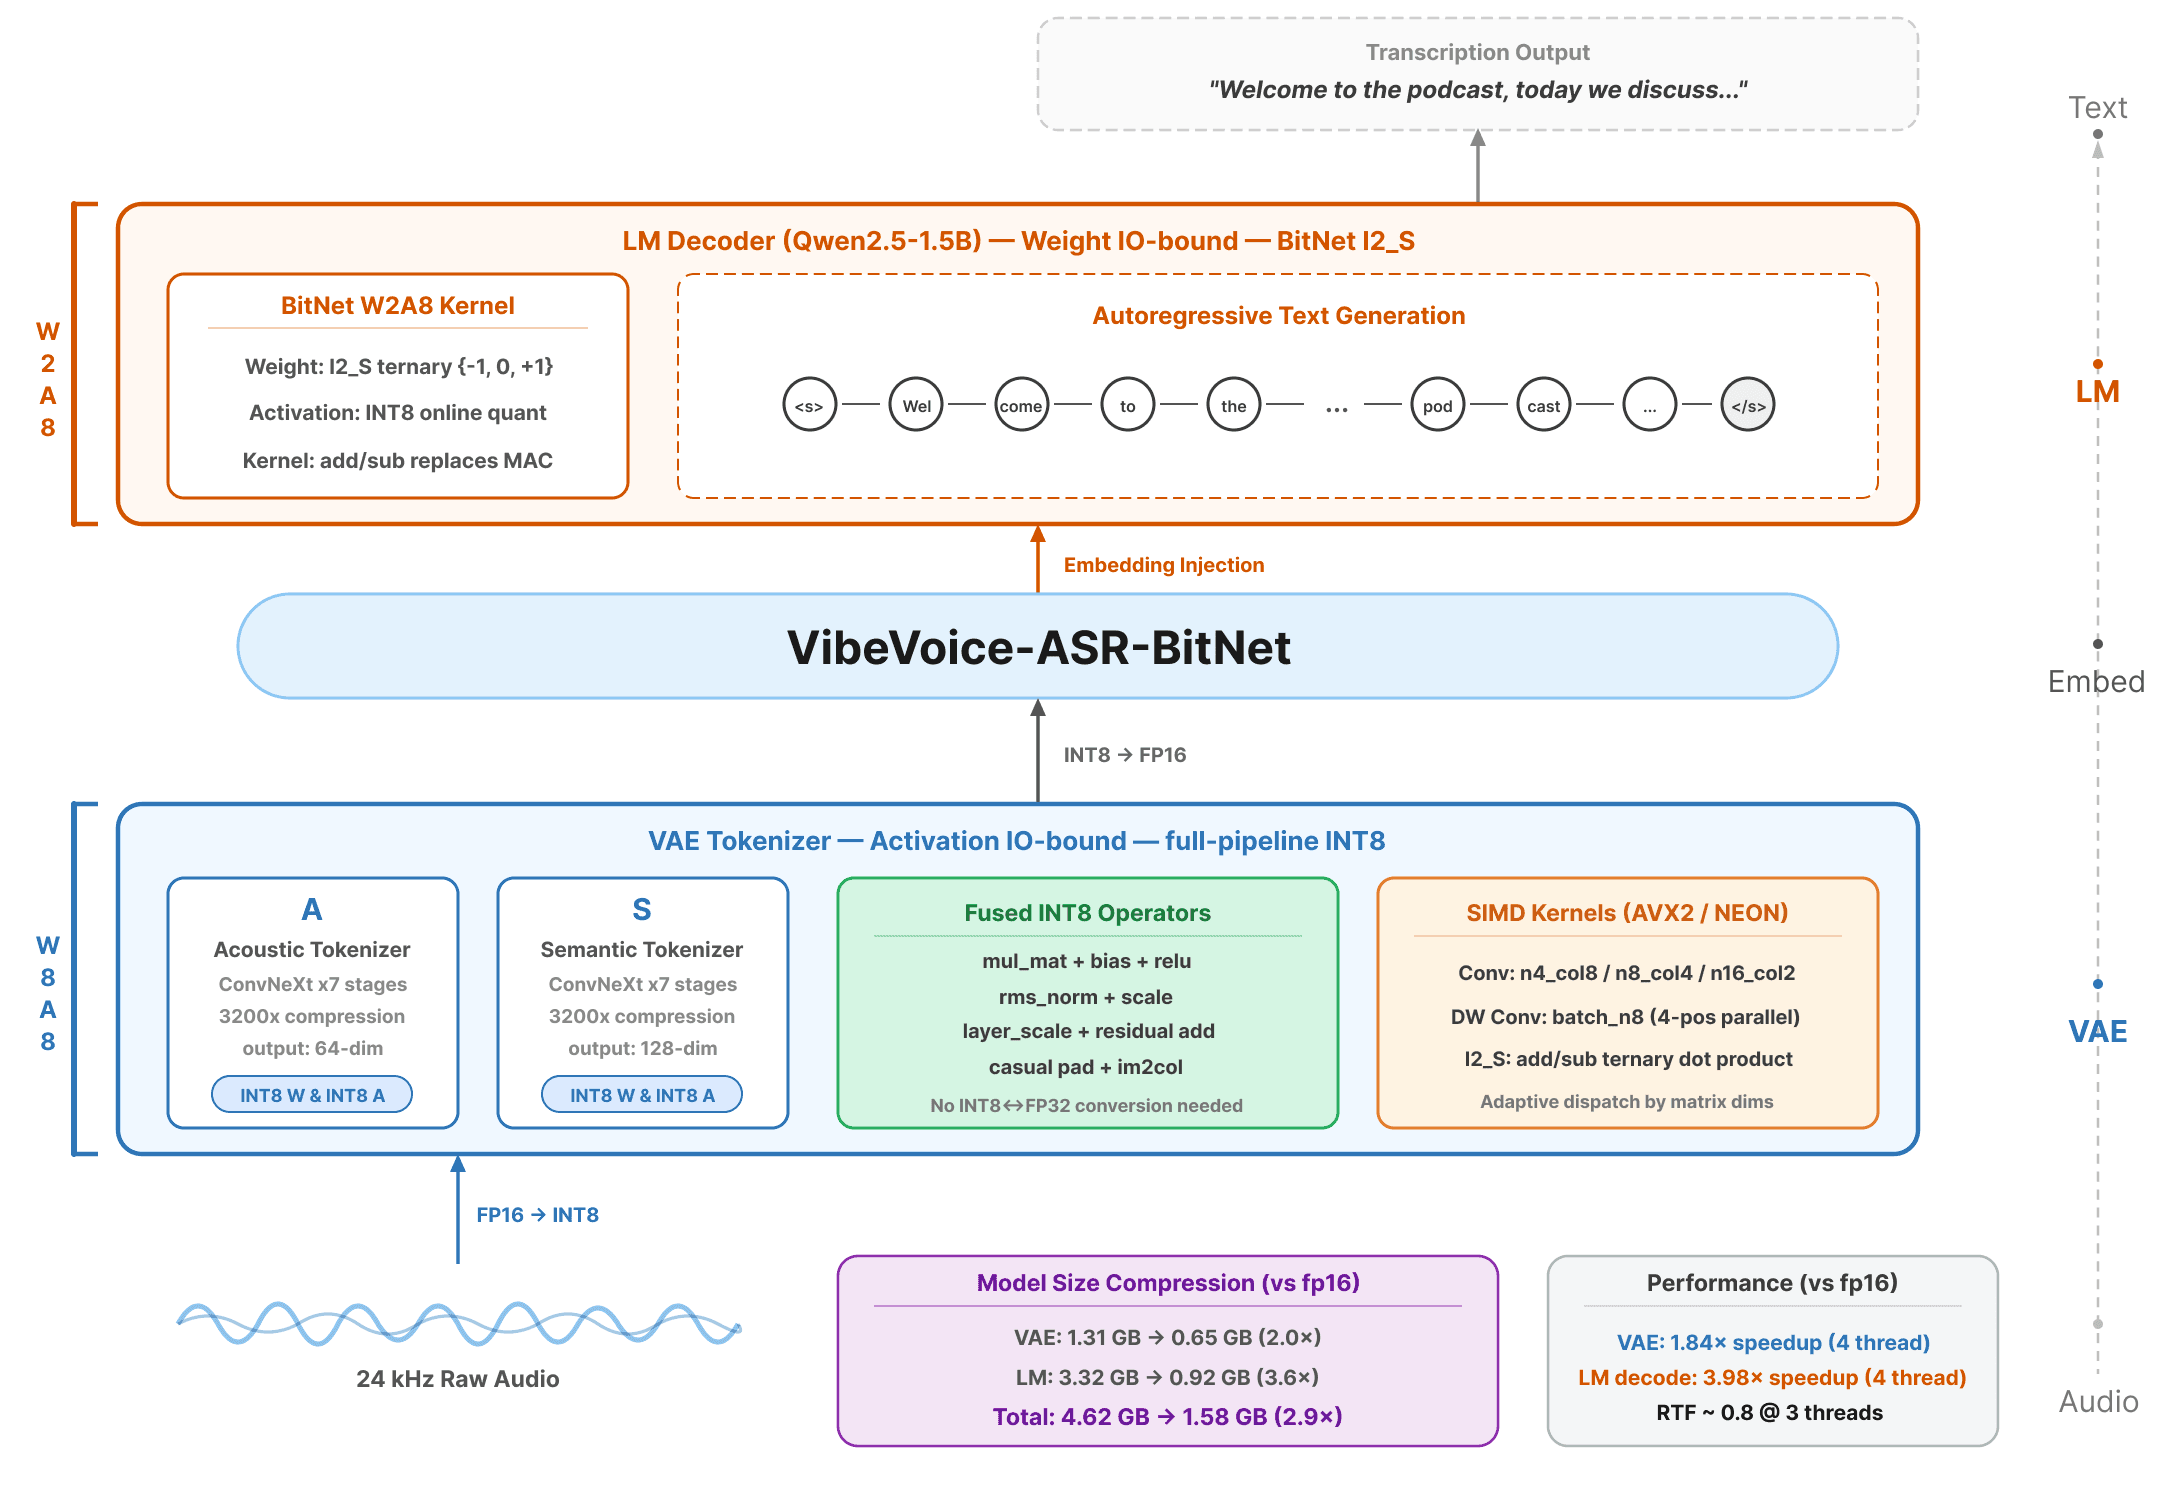
Microsoft's VibeVoice ASR Goes BitNet for CPU Speech

A BitNet-quantized speech recognition model trades GPU dependence for efficient CPU inference in English and Chinese.

Jul 24, 2026
Speech → Text
VibeVoice ASR BitNet
Nyralabs/Speech → TextRuns anywhere

CrisperWhisper 2.0 Large targets verbatim transcription

A Whisper-based ASR model that keeps every filler word and stamps timestamps to the individual word, now covering English and German.

Jul 15, 2026
Speech → Text
CrisperWhisper 2.0 Large
Ai Sage/Speech → Text

SberDevices releases GigaAM Multilingual ASR model

An MIT-licensed speech recognition model targeting Russian, English, and Kazakh arrives on Hugging Face.

Jul 14, 2026
Speech → Text
GigaAM Multilingual
Cohere/Speech → TextRuns anywhere

Cohere releases Apache-licensed Arabic speech model

The Cohere Labs transcription model targets Arabic and English audio under a permissive open license.

Jun 18, 2026
Speech → Text
Cohere Transcribe Arabic
zhifeixie/Speech → TextRuns anywhere

Mega-ASR Improves on Qwen for Speech Recognition

Researcher Zhifei Xie has released a 1.7B-parameter model that refines Alibaba's Qwen3-ASR, showing improved performance on English and Chinese transcription benchmarks.

May 19, 2026
Speech → Text
Mega-ASR
OpenMOSS/Speech → TextRuns anywhere

OpenMOSS Releases Transcribe-Diarize ASR Model

The open-weights team behind MOSS turns to long-form speech recognition with built-in speaker diarization and timestamps.

May 19, 2026
Speech → Text
MOSS Transcribe-Diarize
NVIDIA/Speech → TextRuns anywhere

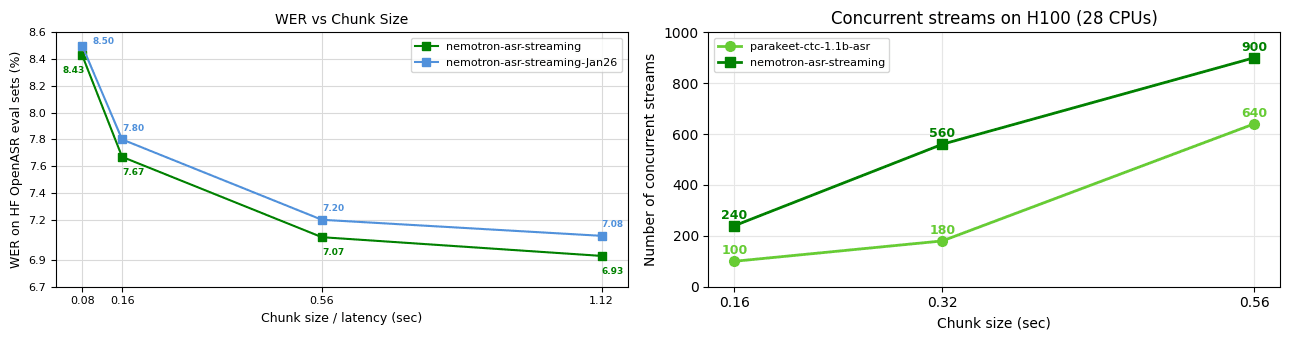
NVIDIA Releases Nemotron-3.5 Streaming ASR Model

The 600-million-parameter model uses a FastConformer architecture for real-time, multilingual speech-to-text applications.

May 15, 2026
Speech → Text
Nemotron 3.5 ASR Streaming 0.6B
Xiaomi/Speech → TextRuns on a laptop

Xiaomi Releases MiMo Model for Speech Recognition

The new open-source model from the Chinese tech giant offers automatic speech recognition for Mandarin, Cantonese, and English under a permissive MIT license.

Apr 23, 2026
Speech → Text
MiMo-V2.5-ASR
IBM/Speech → TextRuns anywhere

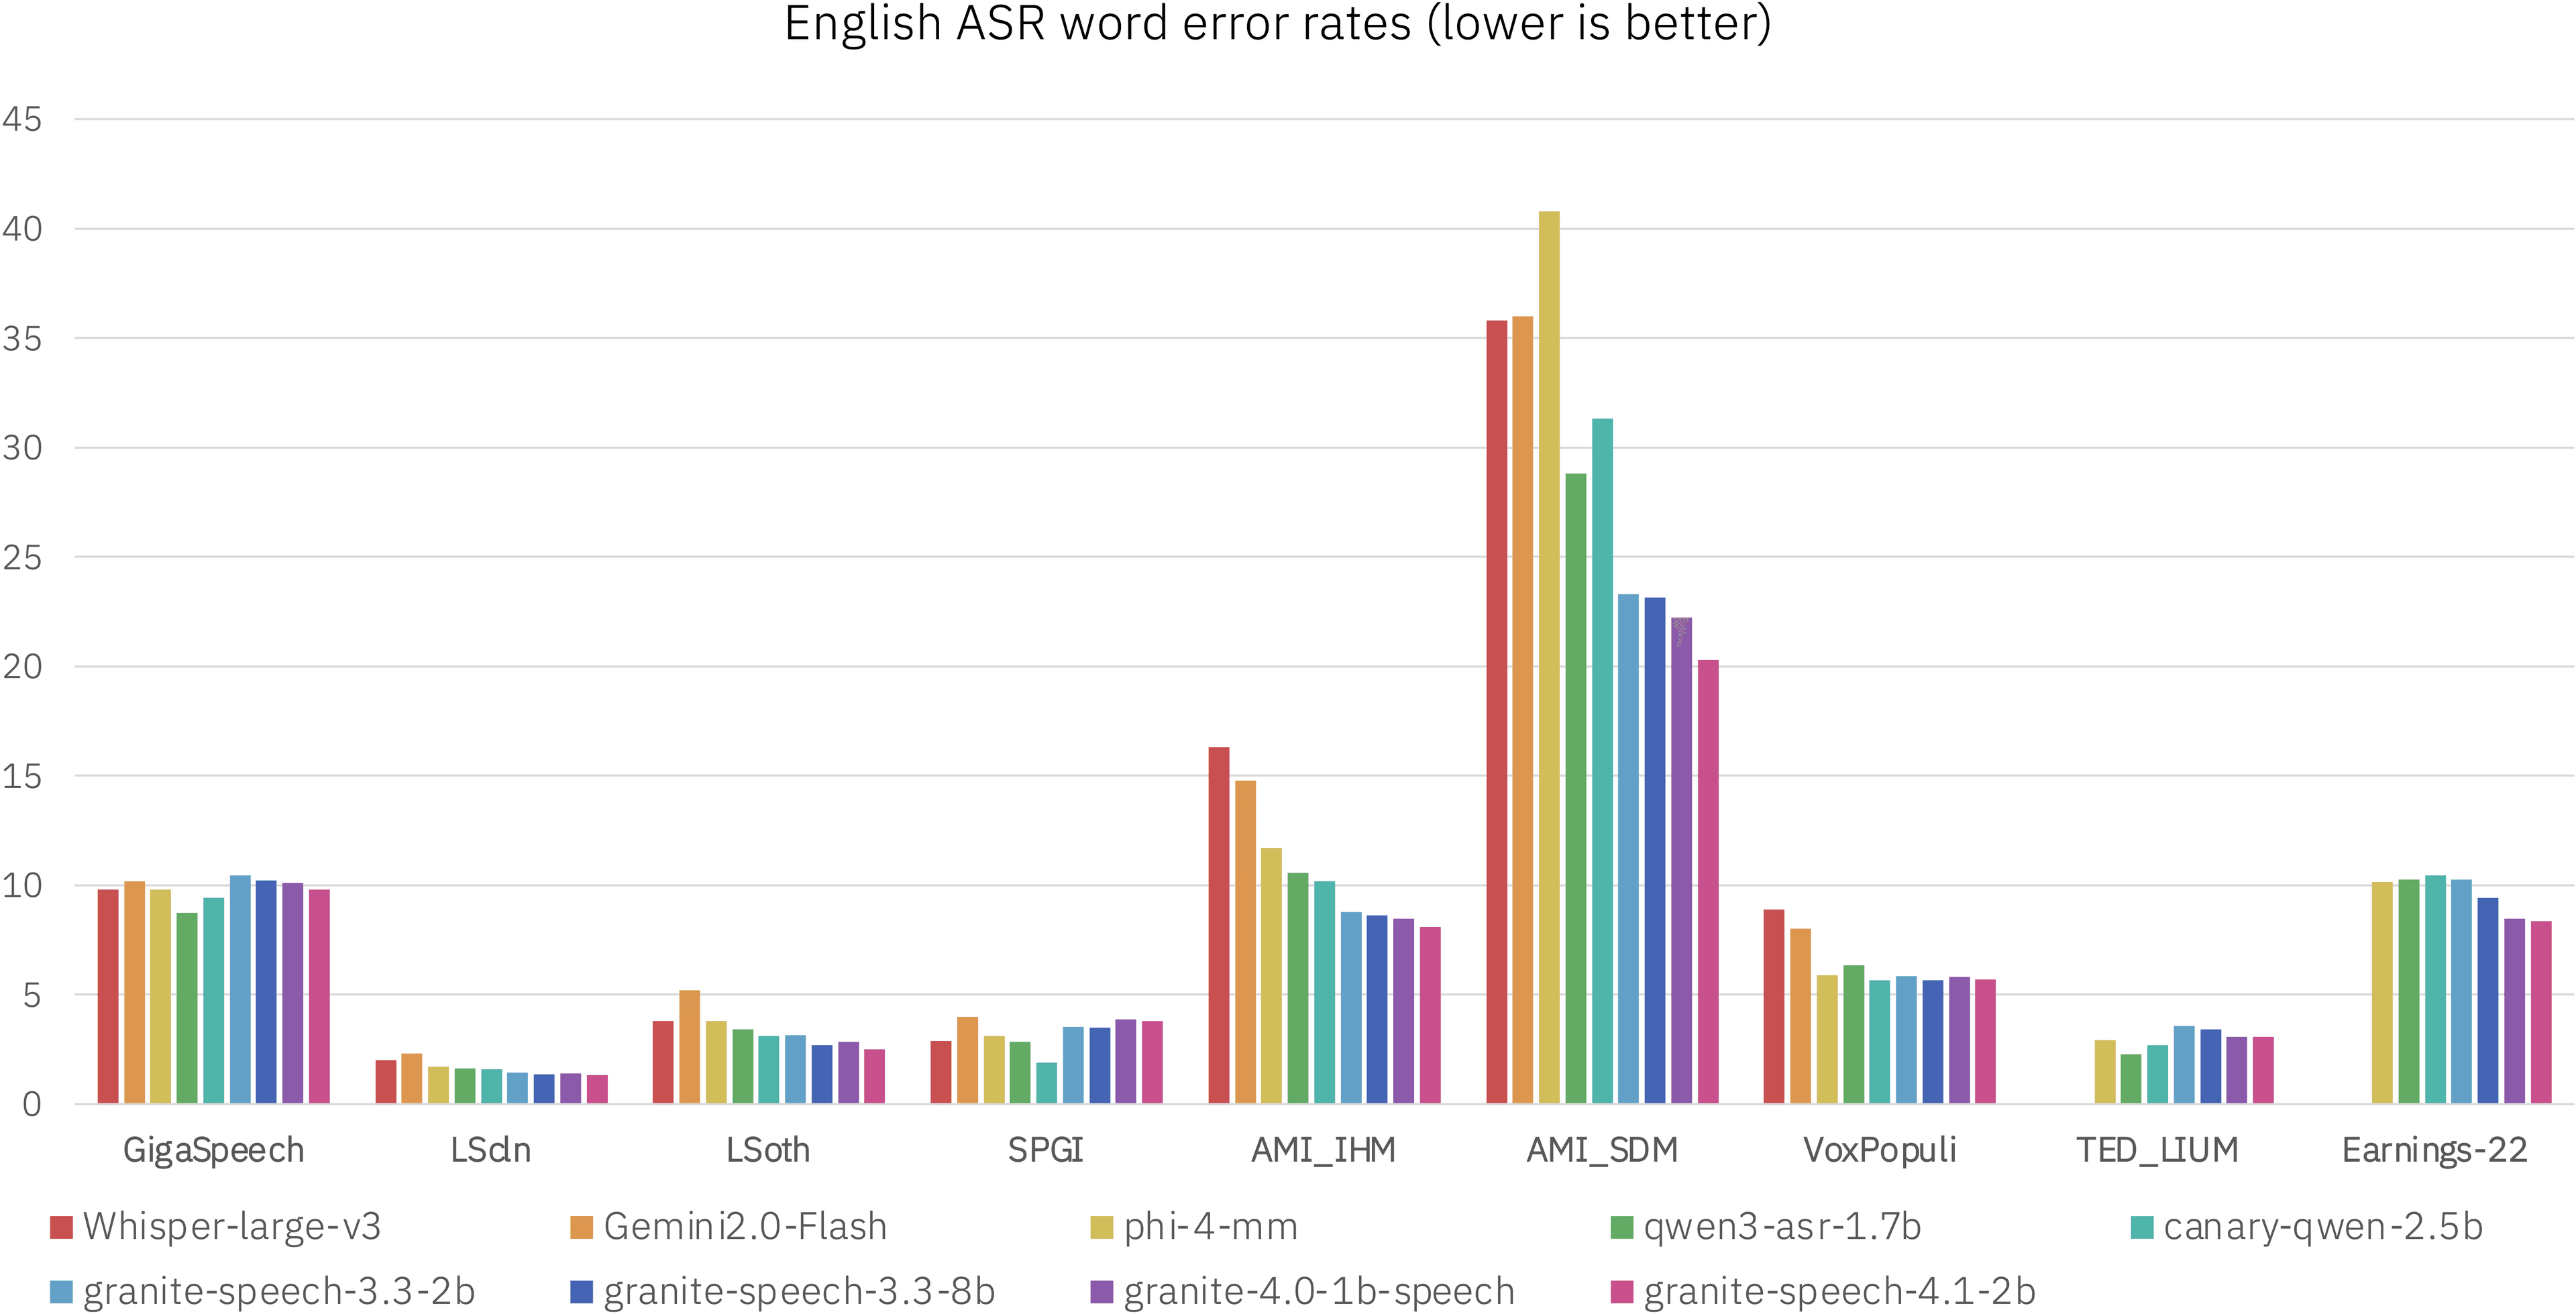
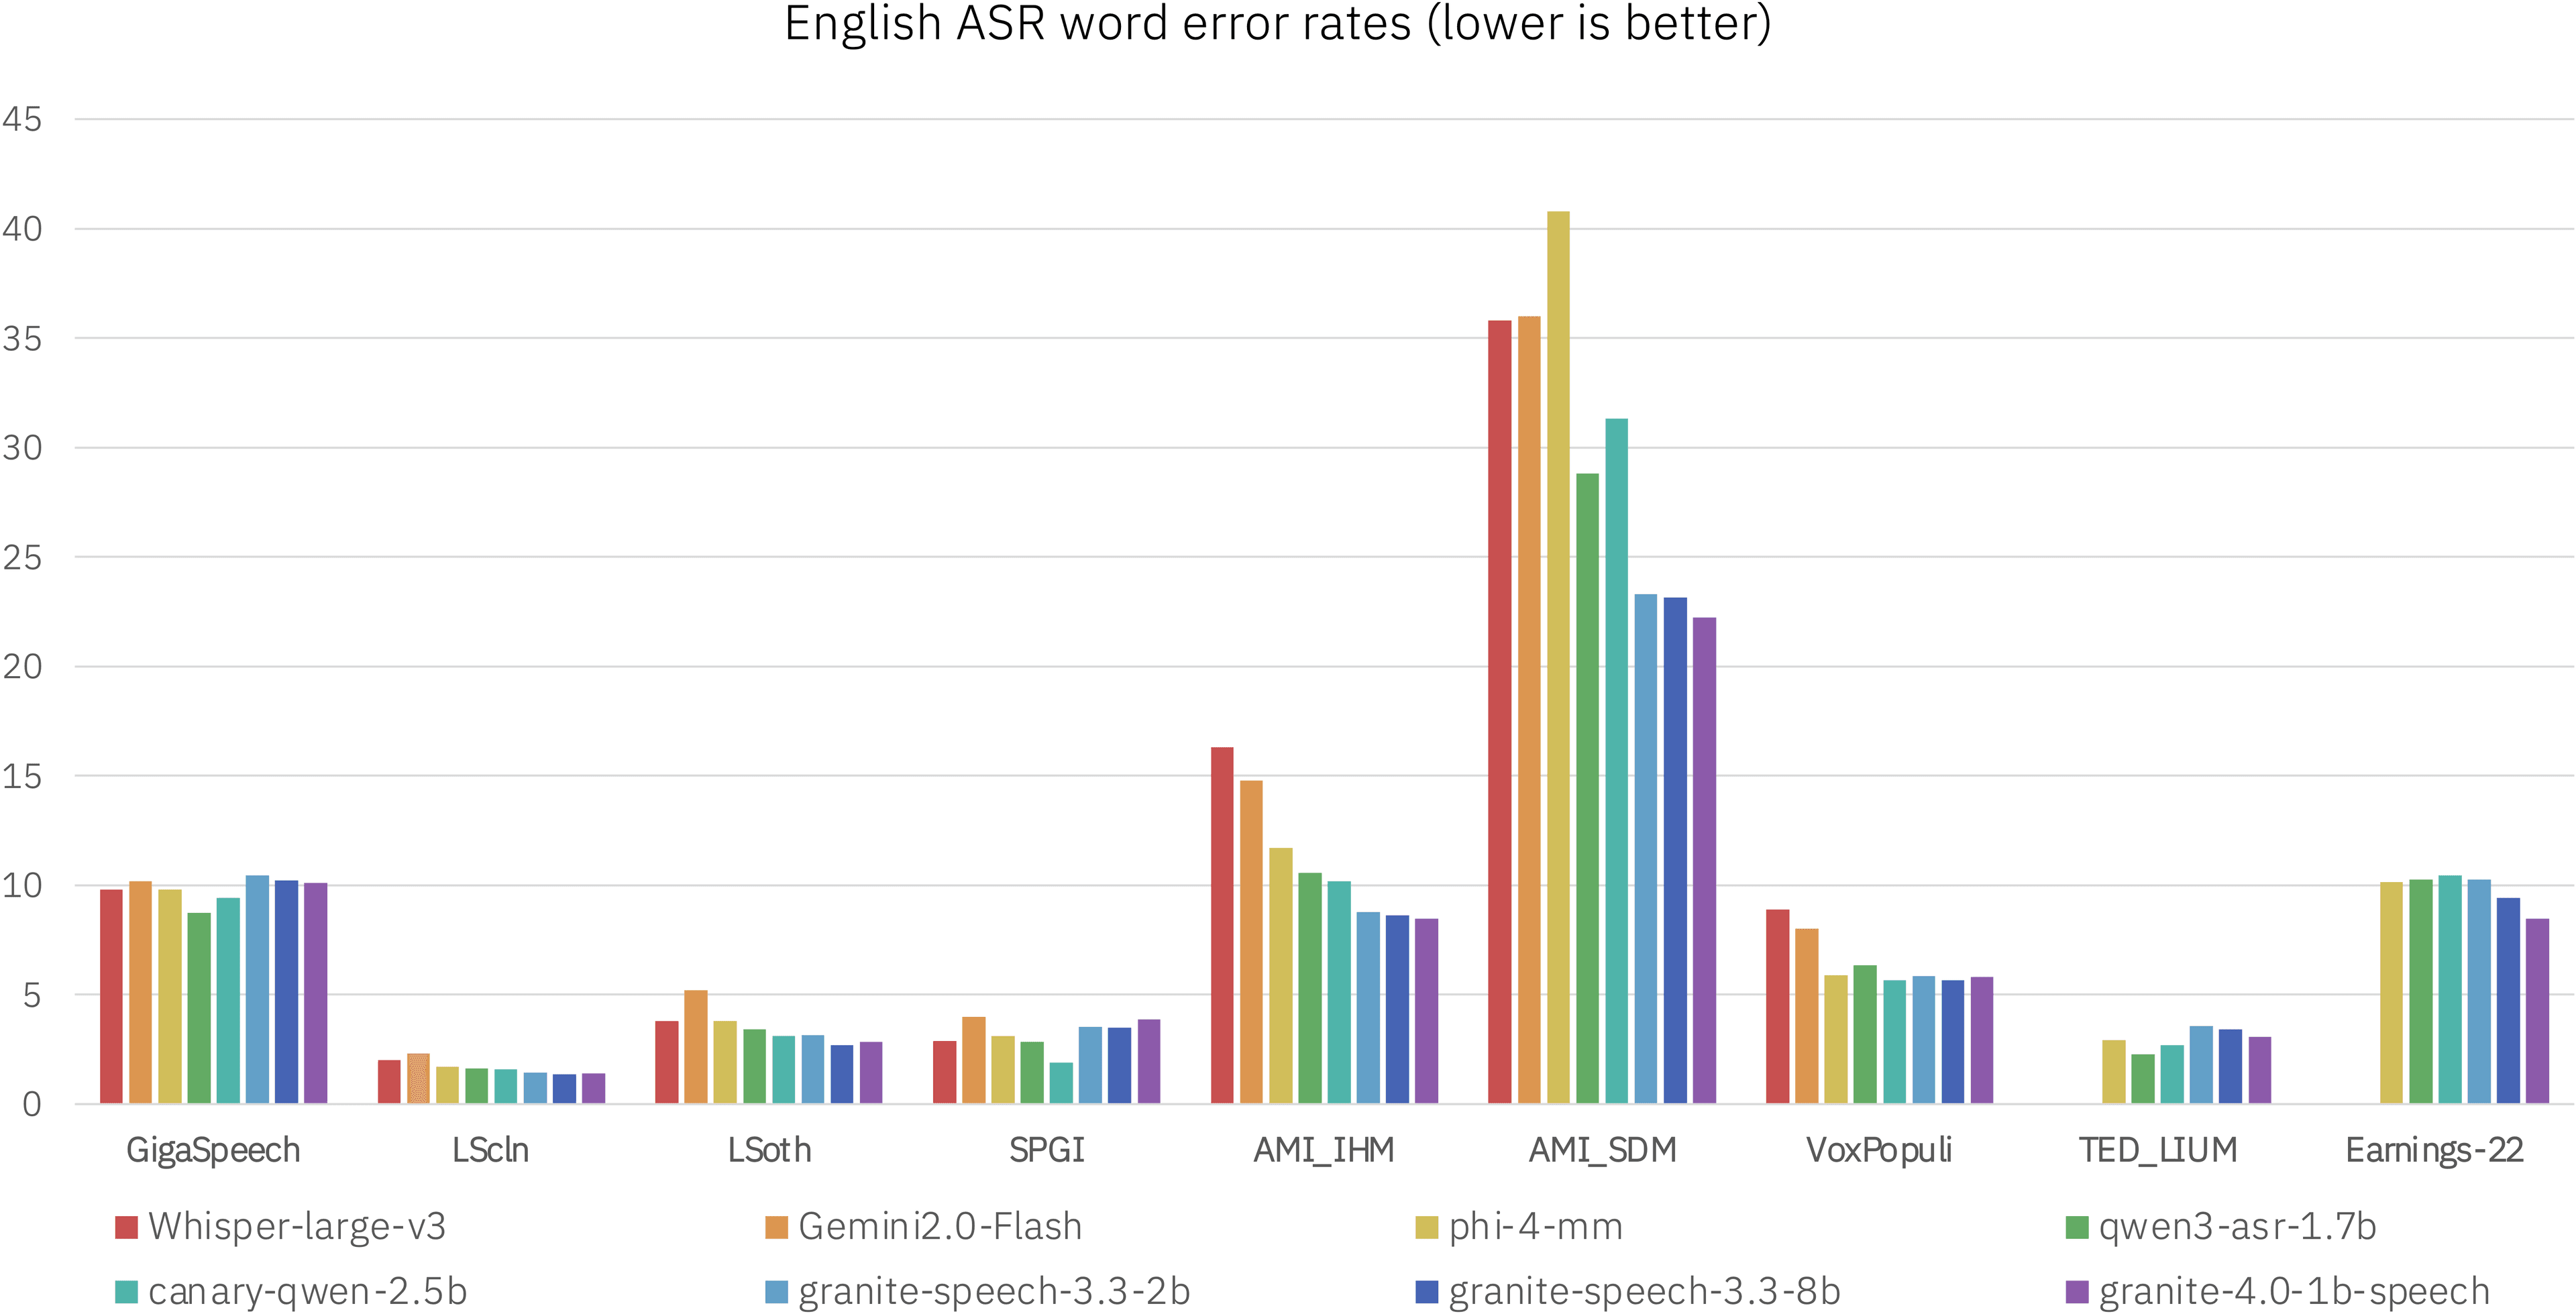
IBM Releases 2B Granite Model for Multilingual Speech

The new two-billion-parameter model offers transcription capabilities for at least five major languages under a permissive Apache 2.0 license.

Apr 16, 2026
Speech → Text
Granite Speech 4.1 2B
KRAFTON/Any-to-AnyRuns on a laptop

KRAFTON Releases 9B Bilingual Speech Model

The gaming giant behind 'PUBG' has released Raon-Speech-9B, a multimodal model for English and Korean speech recognition and synthesis.

Mar 30, 2026
Speech → TextAny-to-Any
Raon-Speech-9B
Cohere/Speech → TextRuns anywhere

Cohere Releases Top-Ranked Multilingual Transcription Model

The new automatic speech recognition model from Cohere Labs sets a new benchmark on the Hugging Face Open ASR Leaderboard for multilingual performance.

Mar 24, 2026
Speech → Text
Cohere Transcribe 03-2026
IBM/Speech → TextRuns anywhere

IBM Releases 1B Granite Model for Multilingual Speech

The new Apache 2.0-licensed model is part of the company's Granite family and aims to provide high-quality speech-to-text across several languages.

Feb 27, 2026
Speech → Text
Granite 4.0 1B Speech
Resemble AI/Speech → Text

Moonshine: Open STT Models Aim to Beat Whisper

Resemble AI releases MIT-licensed speech-to-text models that claim higher accuracy than OpenAI's Whisper Large v3.

Feb 24, 2026
Speech → Text
Qwen · Alibaba/Speech → TextRuns anywhere

Qwen Releases 0.6B Model for Audio-Text Alignment

The new open-source tool, based on the Qwen3 architecture, precisely synchronizes audio recordings with their corresponding text transcripts.

Jan 28, 2026
Speech → Text
Qwen3 ForcedAligner 0.6B
Qwen · Alibaba/Speech → TextRuns anywhere

Qwen3 Family Expands into Speech Recognition

Alibaba's Qwen team has released a new 1.7-billion-parameter model designed specifically for automatic speech recognition.

Jan 28, 2026
Speech → Text
Qwen3-ASR-1.7B
Qwen · Alibaba/Speech → TextRuns anywhere

Qwen open-sources compact model for speech recognition

The new 600-million-parameter Qwen3-ASR model is designed for efficient, high-quality audio transcription under a permissive license.

Jan 28, 2026
Speech → Text
Qwen3-ASR-1.7B
Mistral AI/Speech → TextRuns on a laptop

Mistral Enters Speech AI with Voxtral Mini Model

The company, known for its powerful text models, has released its first open-source speech recognition system designed for real-time, multilingual transcription.

Jan 21, 2026
Speech → Text
Voxtral Mini 4B Realtime
Microsoft/Speech → TextRuns on a laptop

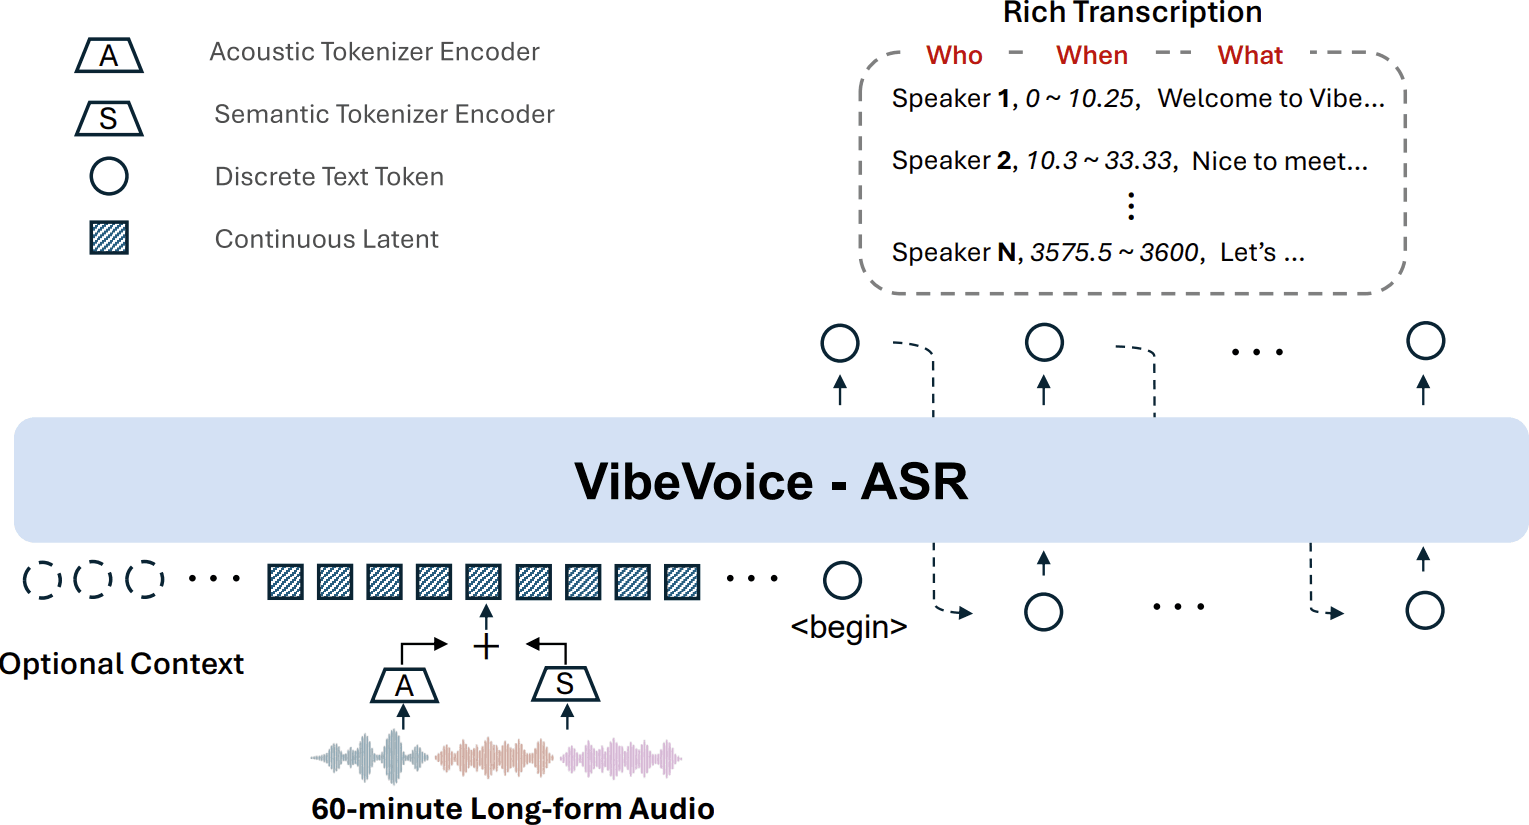
Microsoft Releases VibeVoice for Speech Transcription

The new open-source automatic speech recognition model handles multilingual transcription and speaker identification out of the box.

Jan 21, 2026
Speech → Text
VibeVoice ASR
Qwen · Alibaba/Any-to-AnyRuns on a laptop

Qwen's Fun-Audio-Chat: An Open Speech-to-Speech LLM

The 8-billion-parameter model from Alibaba's Qwen team understands and generates spoken responses, enabling more natural audio-first applications.

Dec 23, 2025
Speech → TextAny-to-Any
Fun-Audio-Chat-8B
Google DeepMind/Speech → TextRuns anywhere

Google Releases MedASR for Medical Transcription

The new speech recognition model from DeepMind is trained specifically on medical dictation, aiming for higher accuracy in clinical notes.

Dec 18, 2025
Speech → Text
MedASR
NVIDIA/Speech → TextRuns anywhere

NVIDIA Releases Streaming Speech-to-Text Model

The 600-million-parameter Nemotron model is designed for real-time English transcription using a cache-aware FastConformer architecture.

Dec 17, 2025
Speech → Text
Nemotron Speech Streaming EN 0.6B
Qwen · Alibaba/Speech → Text

Qwen Releases Compact ASR Model for Streaming Audio

The new Fun-ASR-Nano model from Alibaba's team packs real-time multilingual transcription, speaker diarization, and hotword detection into an efficient package.

Dec 15, 2025
Speech → Text
Fun-ASR-Nano-2512
Zhipu AI/Speech → TextRuns anywhere

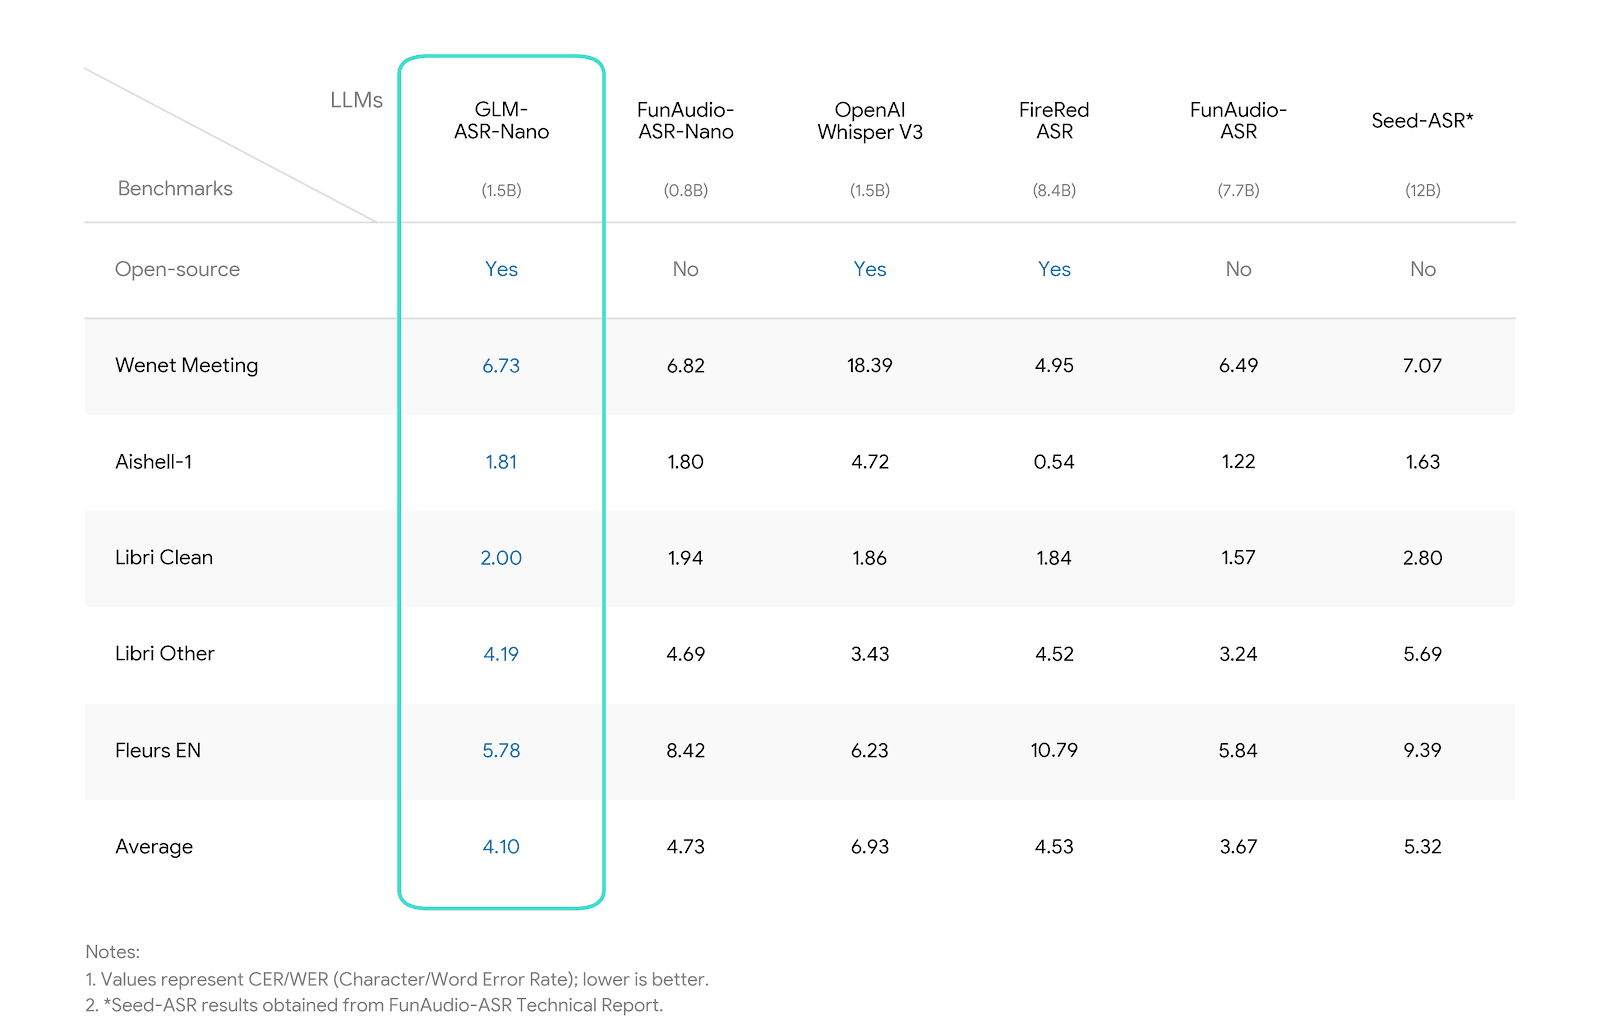
Zhipu AI Releases Compact Bilingual Speech Model

The new GLM-ASR-Nano model is designed for efficient automatic speech recognition in both English and Mandarin Chinese.

Dec 9, 2025
Speech → Text
GLM-ASR-Nano-2512
NVIDIA/Speech → Text

NVIDIA Releases Real-Time Speaker Diarization Model

The new Sortformer-based model is designed for streaming audio, identifying up to four distinct speakers in real time.

Oct 22, 2025
Speech → Text
Streaming Sortformer Diarization 4spk v2.1
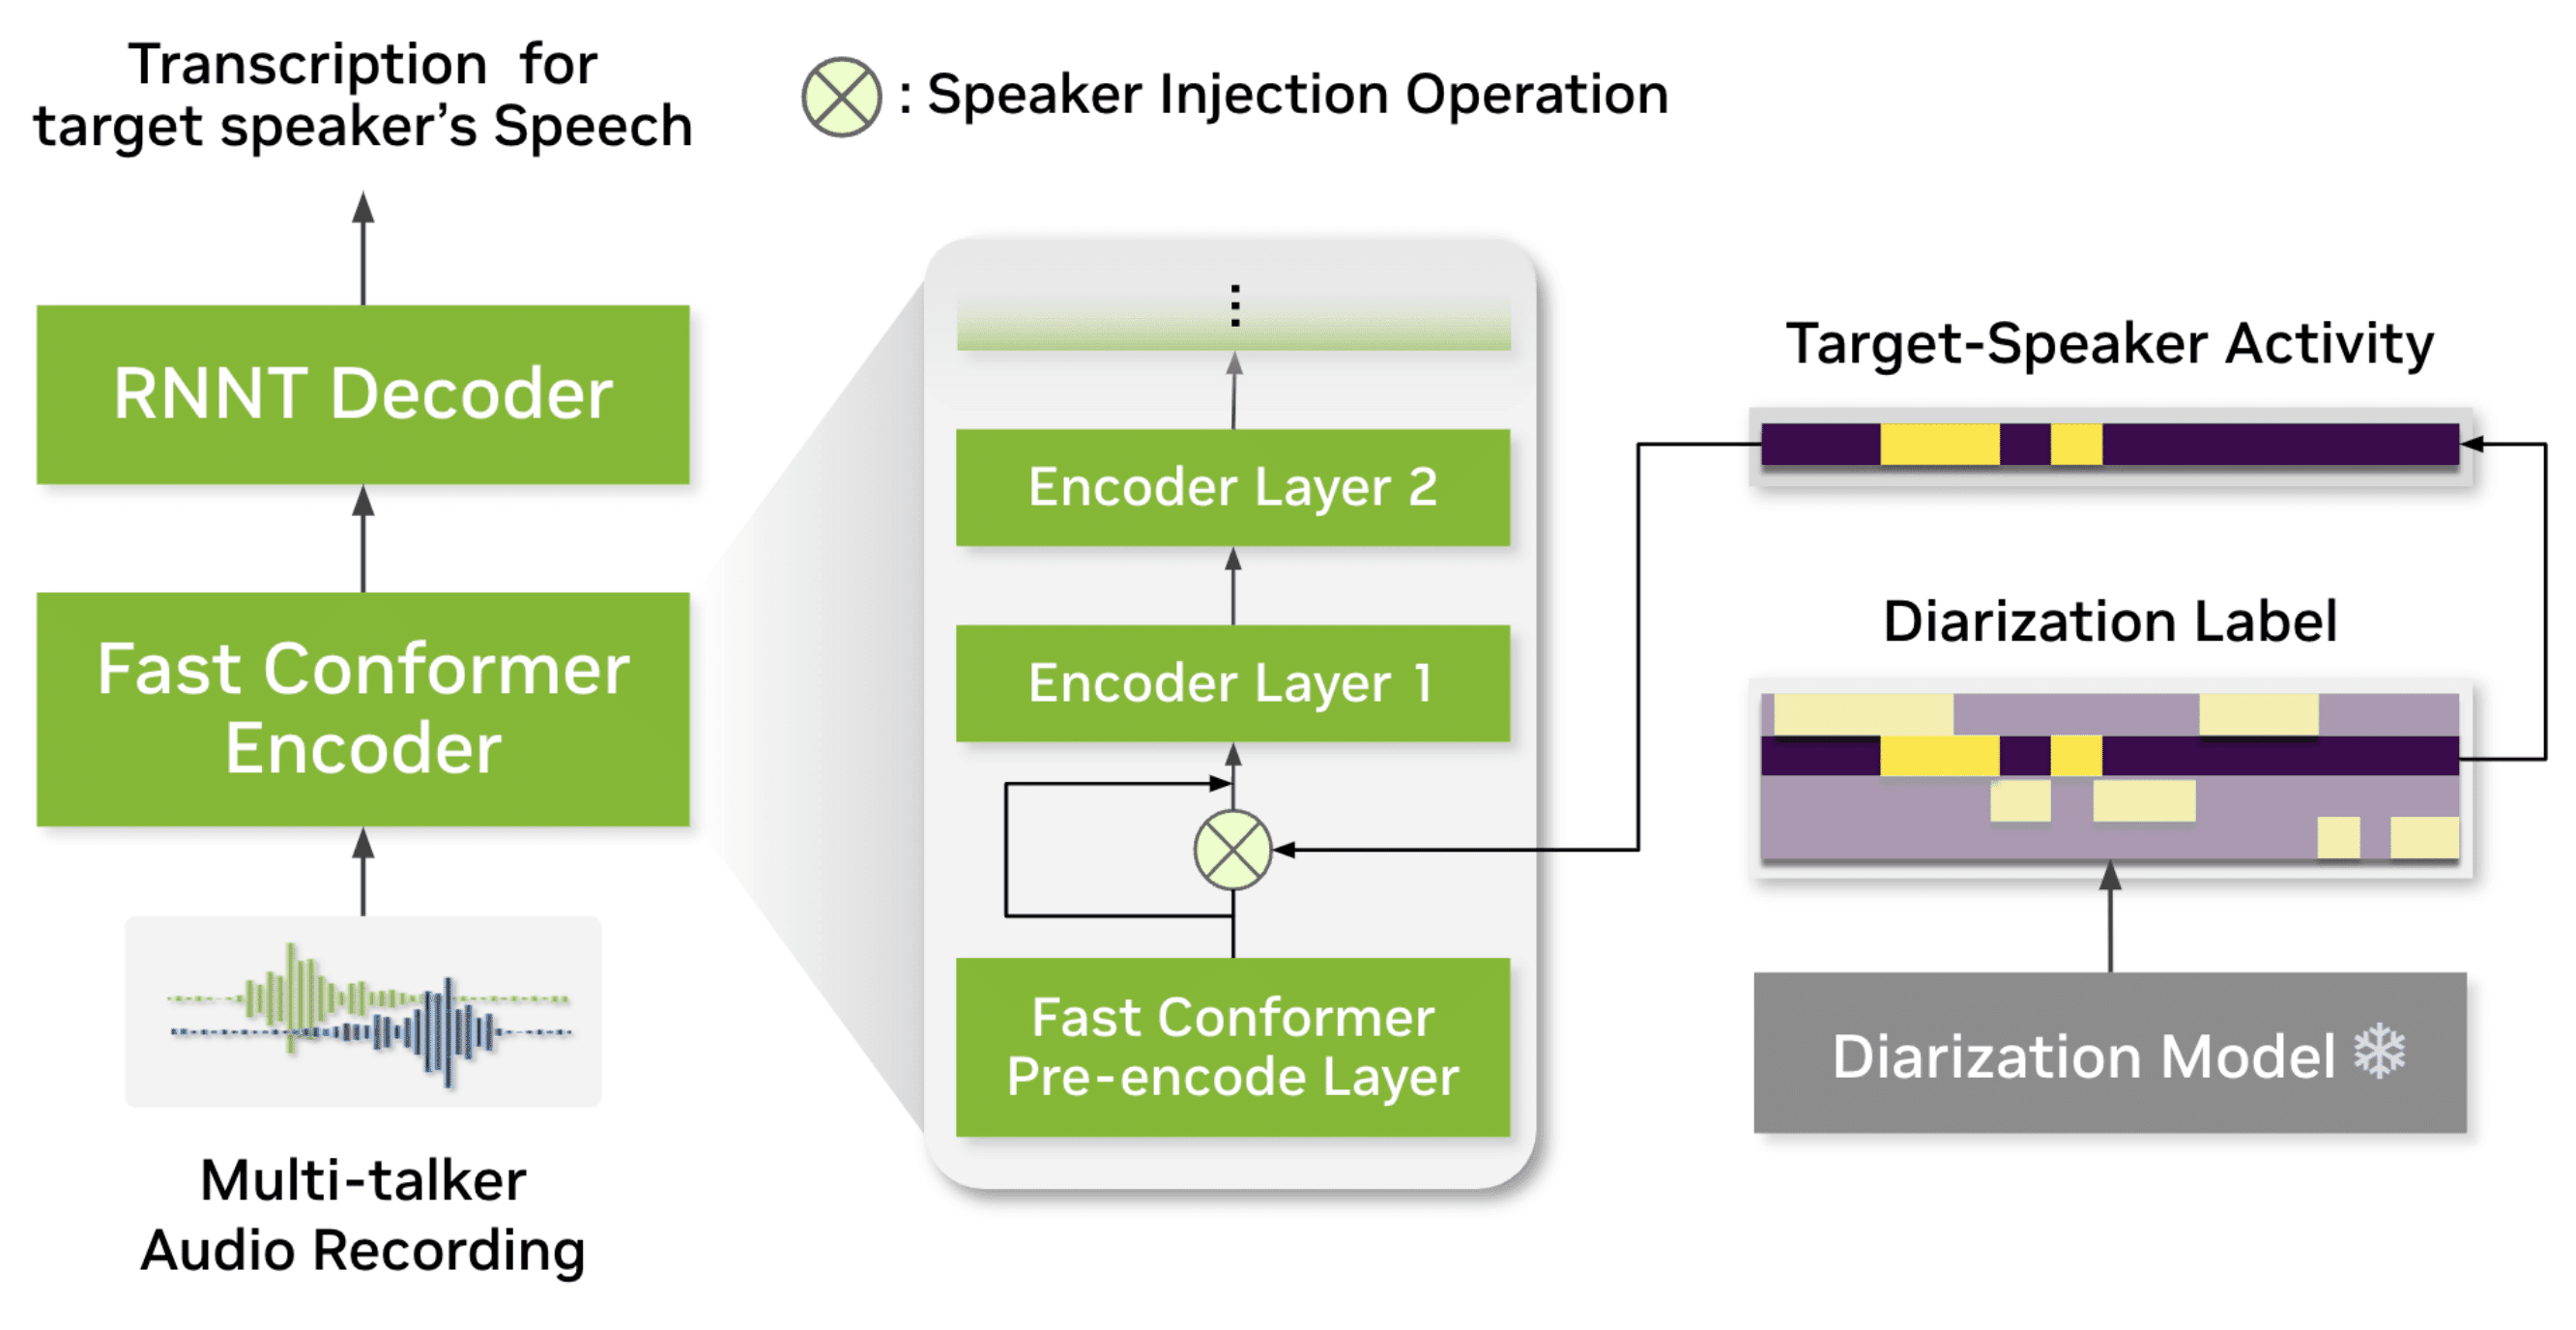
NVIDIA/Speech → TextRuns anywhere

NVIDIA's Parakeet ASR Tackles Multi-Speaker Audio

The 600-million-parameter model offers real-time speech-to-text with speaker diarization, built on the efficient FastConformer architecture.

Oct 15, 2025
Speech → Text
Multitalker Parakeet Streaming 0.6B
inclusionAI/Any-to-AnyRuns on a laptop

Ming-UniAudio Brings MoE to Unified Audio AI

A new 16-billion-parameter model from inclusionAI uses a Mixture-of-Experts architecture to handle a wide range of audio tasks efficiently.

Sep 29, 2025
Speech → TextAny-to-Any
Ming-UniAudio-16B-A3B
Qwen · Alibaba/Any-to-AnyMajor releaseConsumer GPU

Qwen3-Omni Arrives With Any-to-Any Multimodality

The new 30B Mixture-of-Experts model from Alibaba's Qwen team can process and generate content across text, image, and audio formats.

Sep 20, 2025
Speech → TextAny-to-Any
Qwen3-Omni-30B-A3B-Instruct
Xiaomi/Any-to-AnyRuns on a laptop

Xiaomi's MiMo-Audio 7B Tackles Complex Speech Tasks

This new instruction-tuned model from Xiaomi can handle a flexible combination of audio and text inputs and outputs, from transcription to voice synthesis.

Sep 18, 2025
Speech → TextAny-to-Any
MiMo-Audio-7B-Instruct
StepFun/Any-to-AnyRuns on a laptop

StepFun Releases Step-Audio 2 mini, a Unified Audio AI

The new open-source model handles both speech recognition and audio generation in a single, end-to-end architecture.

Aug 28, 2025
Speech → TextAny-to-Any
Step-Audio 2 mini
NVIDIA/Speech → TextRuns anywhere

NVIDIA Releases Canary 1B v2 Multilingual Speech Model

The new 1-billion-parameter model handles both transcription and translation across five languages using the company's efficient FastConformer architecture.

Aug 4, 2025
Speech → Text
Canary 1B v2
NVIDIA/Speech → TextRuns anywhere

NVIDIA Releases 600M Parakeet for Speech Recognition

The new FastConformer model uses a specialized training technique to improve transcription accuracy in noisy, real-world environments.

Aug 4, 2025
Speech → Text
Parakeet TDT 0.6B v3
T-Tech/Speech → TextRuns anywhere

T-Tech Releases T-one for Russian Speech Recognition

The new streaming Conformer model from the Russian digital bank is optimized for real-time transcription of telephone conversations.

Jul 14, 2025
Speech → Text
T-one
NVIDIA/Speech → TextRuns anywhere

NVIDIA Fuses LLM and ASR in Canary-Qwen 2.5B Model

The 2.5 billion-parameter speech model combines a FastConformer encoder with a Qwen LLM decoder, a hybrid approach to transcription.

Jun 26, 2025
Speech → Text
Canary-Qwen 2.5B
Pyannote/Speech → Text

pyannote ships community-1 diarization pipeline

A new community edition of pyannote's open-source speaker diarization model lands on Hugging Face, targeting the "who spoke when" problem.
Apr 15, 2025
Speech → Text
pyannote speaker-diarization-community-1