Cohere Releases Top-Ranked Multilingual Transcription Model
The new automatic speech recognition model from Cohere Labs sets a new benchmark on the Hugging Face Open ASR Leaderboard for multilingual performance.

Cohere has released a new model for automatic speech recognition (ASR), Cohere Transcribe, immediately claiming the top position on the Hugging Face Open ASR Leaderboard. The model demonstrates state-of-the-art performance, particularly on challenging multilingual benchmarks like FLEURS (Few-shot Learning Evaluation of Universal Representations of Speech).
Trained on a large dataset of professionally transcribed audio, the model is designed to accurately convert spoken language into text across multiple languages. This capability makes it a powerful new tool for developers building voice-enabled applications, transcription services, and other features that rely on understanding human speech.
The release of a high-performing ASR model from a major AI lab like Cohere provides a strong alternative to existing leaders in the space, such as OpenAI's Whisper. As more powerful, openly-available models for speech are released, the barrier to creating sophisticated audio-based applications continues to fall for researchers and builders.
While the model's weights are publicly accessible, it is important to note the usage restrictions. Cohere Transcribe is available under a Cohere Non-Commercial License, meaning it is intended for research and non-commercial projects rather than for deployment in production commercial applications.
Sources
- Visit
CohereLabs/cohere-transcribe-03-2026
Hugging Face
More from Cohere
All Cohere releases →
Cohere Labs releases compact North Micro Vision model
A small multilingual vision-language model built for instruction following arrives under a research-only license.

Cohere releases Apache-licensed Arabic speech model
The Cohere Labs transcription model targets Arabic and English audio under a permissive open license.
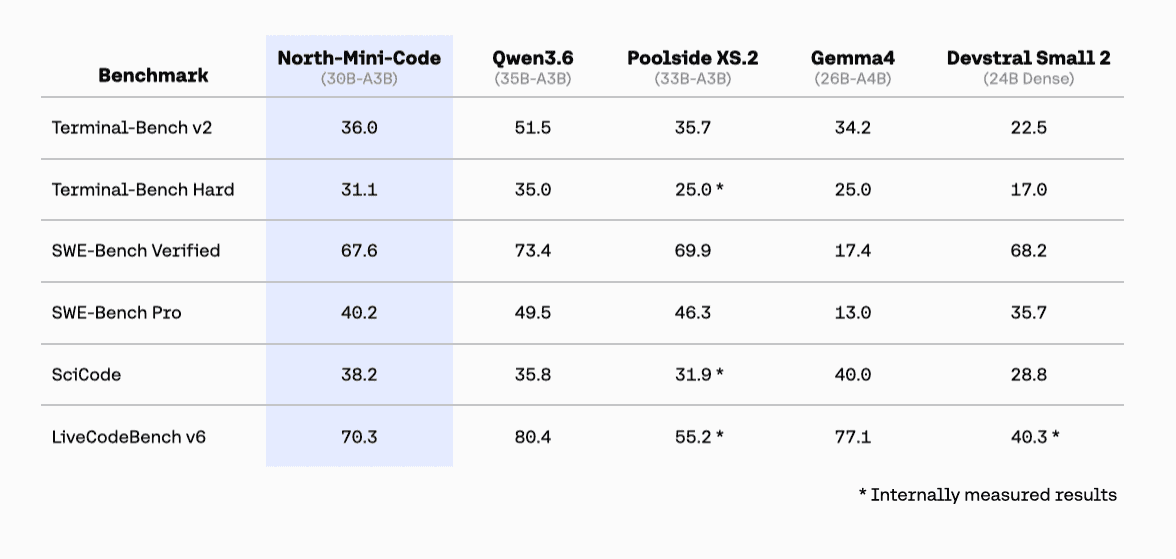
Cohere Releases North-Mini-Code, an Open MoE Model
The new Apache 2.0-licensed model is designed for code generation and agentic chat applications, using a Mixture-of-Experts architecture for efficiency.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
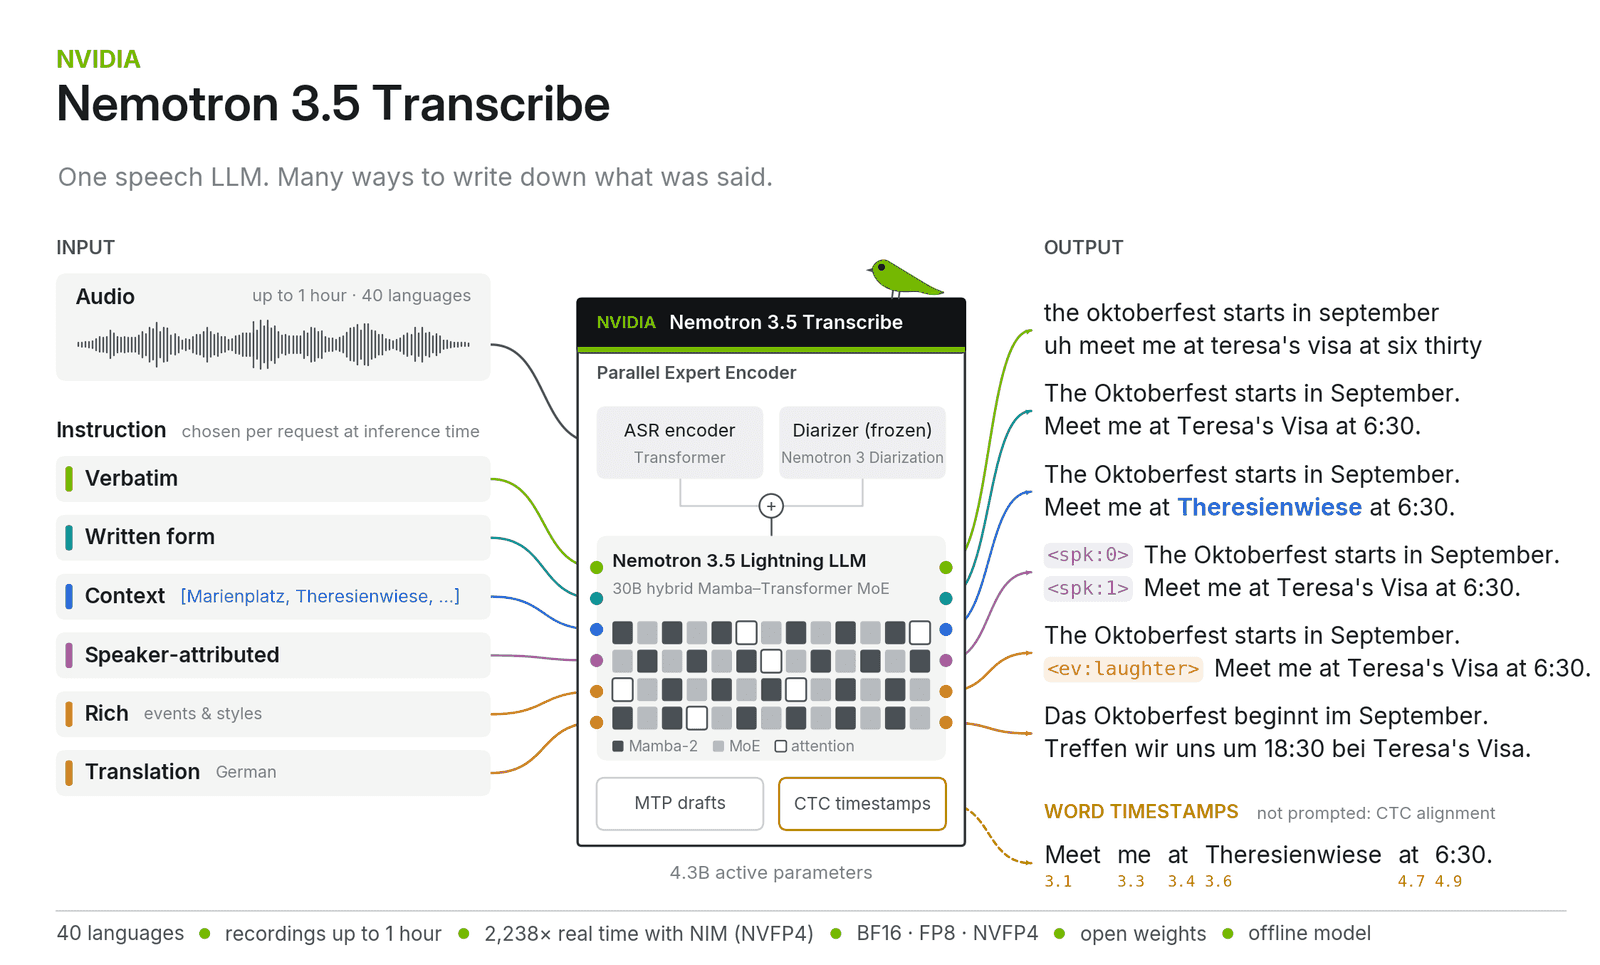
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
0 comments
No comments yet. Be the first to weigh in.