Cohere Labs releases compact North Micro Vision model
A small multilingual vision-language model built for instruction following arrives under a research-only license.
Cohere Labs has published North Micro Vision Instruct, a compact vision-language model tuned to follow instructions across text and images. The release marks the initial 1.0 version of the North Micro Vision family and lands on Hugging Face for researchers to evaluate.
The model is positioned as a small, multilingual entry in the increasingly crowded field of vision-language models (VLMs). Rather than chasing the largest possible parameter counts, North Micro Vision emphasizes a lighter footprint aimed at applications where multilingual understanding and image comprehension matter more than sheer scale.
Why it matters
Compact VLMs are useful precisely because they lower the cost of running multimodal systems, making them practical for teams that cannot dedicate large amounts of compute to inference. A multilingual focus also broadens the model's reach beyond English-centric benchmarks, which remains a persistent gap in many open releases.
A few things to keep in mind about this release:
- It ships under a CC-BY-NC-4.0 license, meaning use is restricted to non-commercial and research settings.
- It is an instruct-tuned model, oriented toward following prompts rather than serving as a raw base checkpoint.
- Cohere Labs has not published detailed parameter counts or context-length specifications alongside the release.
The non-commercial license places North Micro Vision firmly in the research lane, in keeping with much of Cohere Labs' open work. Teams interested in the model's exact capabilities should consult the model card on Hugging Face as further documentation and benchmarks become available.
Sources
- Visit
CohereLabs/North-Micro-Vision-Instruct
Hugging Face
More from Cohere
All Cohere releases →
Cohere releases Apache-licensed Arabic speech model
The Cohere Labs transcription model targets Arabic and English audio under a permissive open license.
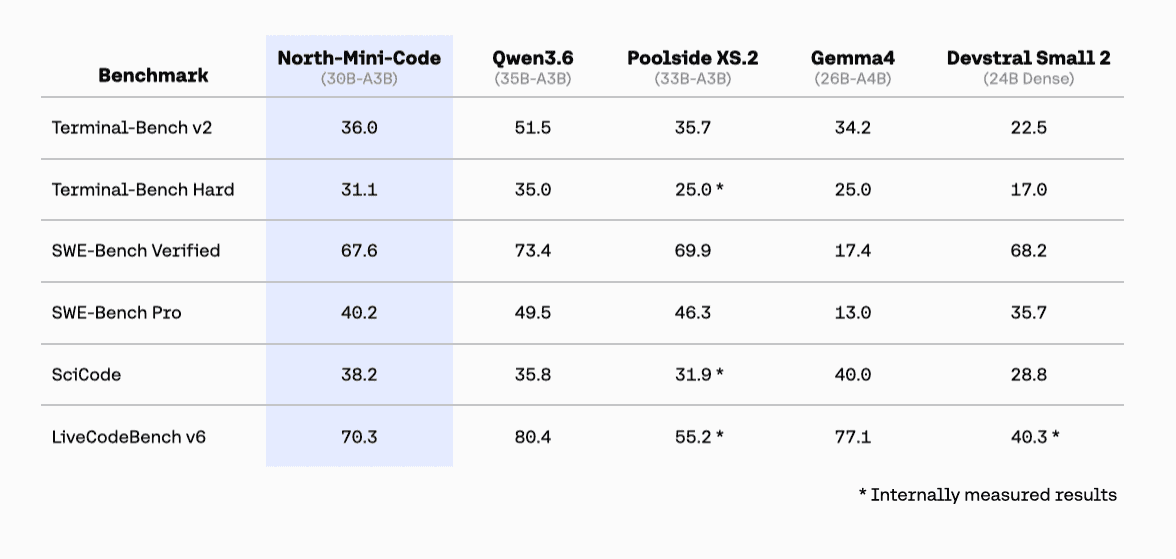
Cohere Releases North-Mini-Code, an Open MoE Model
The new Apache 2.0-licensed model is designed for code generation and agentic chat applications, using a Mixture-of-Experts architecture for efficiency.

Cohere Releases Top-Ranked Multilingual Transcription Model
The new automatic speech recognition model from Cohere Labs sets a new benchmark on the Hugging Face Open ASR Leaderboard for multilingual performance.
More in Vision-Language
All Vision-Language →
SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
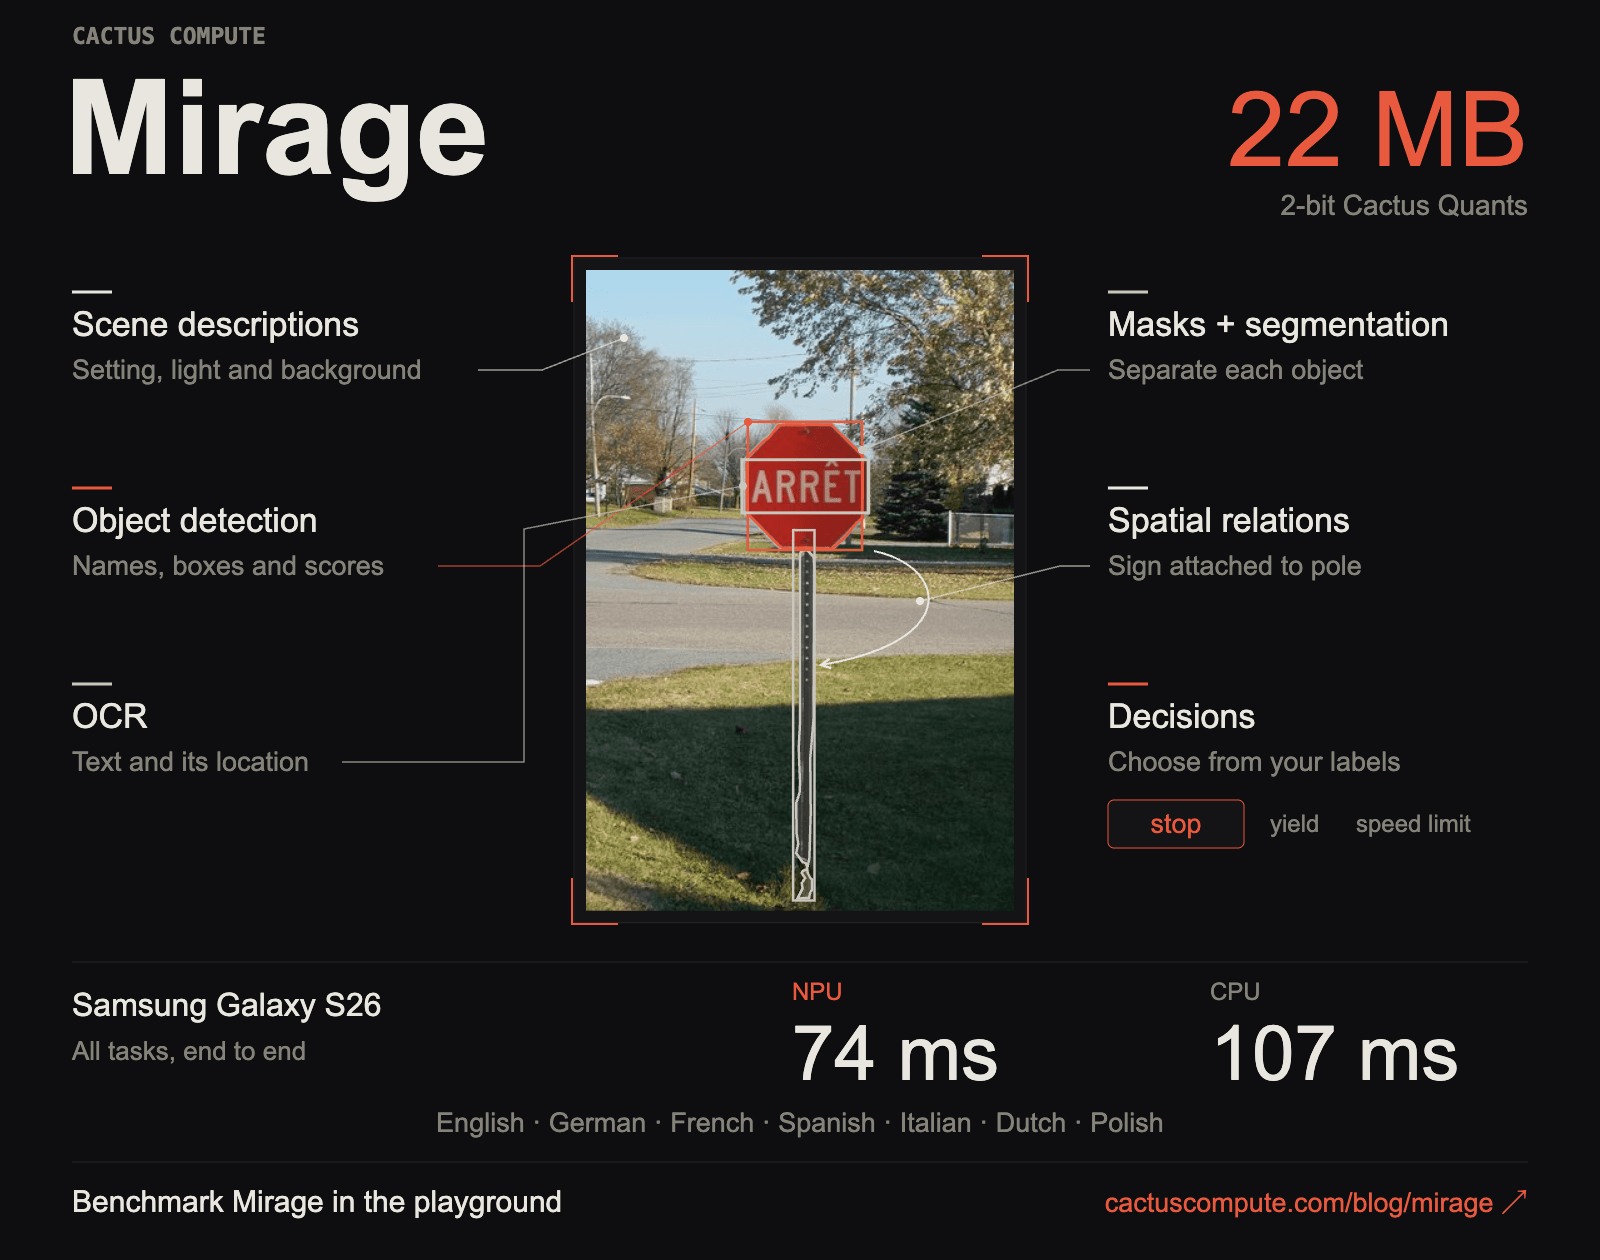
Cactus Compute's Mirage brings vision tasks on-device
The new open vision-language model targets detection, segmentation, and visual Q&A without relying on the cloud.
0 comments
No comments yet. Be the first to weigh in.