OpenMOSS Debuts MOSS-VL for Real-Time Vision Interaction
A new open vision-language model family uses gated cross-attention to enable streaming, low-latency multimodal exchanges.
OpenMOSS has released MOSS-VL, a vision-language model family aimed at real-time, streaming multimodal interaction. According to the group's technical report, the model pairs visual and text understanding with an architecture built for low-latency exchanges rather than one-shot question answering.
The defining choice is a gated cross-attention mechanism, which the team uses to fuse visual signals into the language stream as they arrive. That design is what allows the system to process input continuously and respond while a scene or conversation is still unfolding, instead of waiting for a complete input before generating a reply.
Why it matters
Most open vision-language systems are optimized for static images and full-prompt inference. A model built around streaming interaction points toward more responsive assistants, live video understanding, and agent-style workflows where timing is as important as accuracy.
- Modalities: vision-language plus text generation
- Core technique: gated cross-attention for real-time fusion
- Focus: streaming, low-latency interaction over batch inference
As an initial release, MOSS-VL leaves some open questions—parameter counts, context length, and licensing terms are not fully specified in the record. Still, it extends OpenMOSS's ongoing effort to ship open multimodal systems, and the streaming emphasis distinguishes it from the crowded field of image-first VLMs. The full details are laid out in the report on Hugging Face.
Sources
- Visit
MOSS-VL Technical Report
HF Papers
More from OpenMOSS
All OpenMOSS releases →
OpenMOSS Releases MOSS-Image Under Apache 2.0
The academic team behind the MOSS project moves into text-to-image generation with a permissively licensed model and a fine-tuned SFT variant.
OpenMOSS Releases Apache-2.0 Bilingual Image Model
MOSS-Image Base arrives as a permissively licensed text-to-image foundation with English and Chinese support.
MameLoshnLM Brings Yiddish Into the Open LLM Era
OpenMOSS releases what it calls the first open-source 8B language model built specifically for Yiddish, paired with an evaluation benchmark.
More in Vision-Language
All Vision-Language →
SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
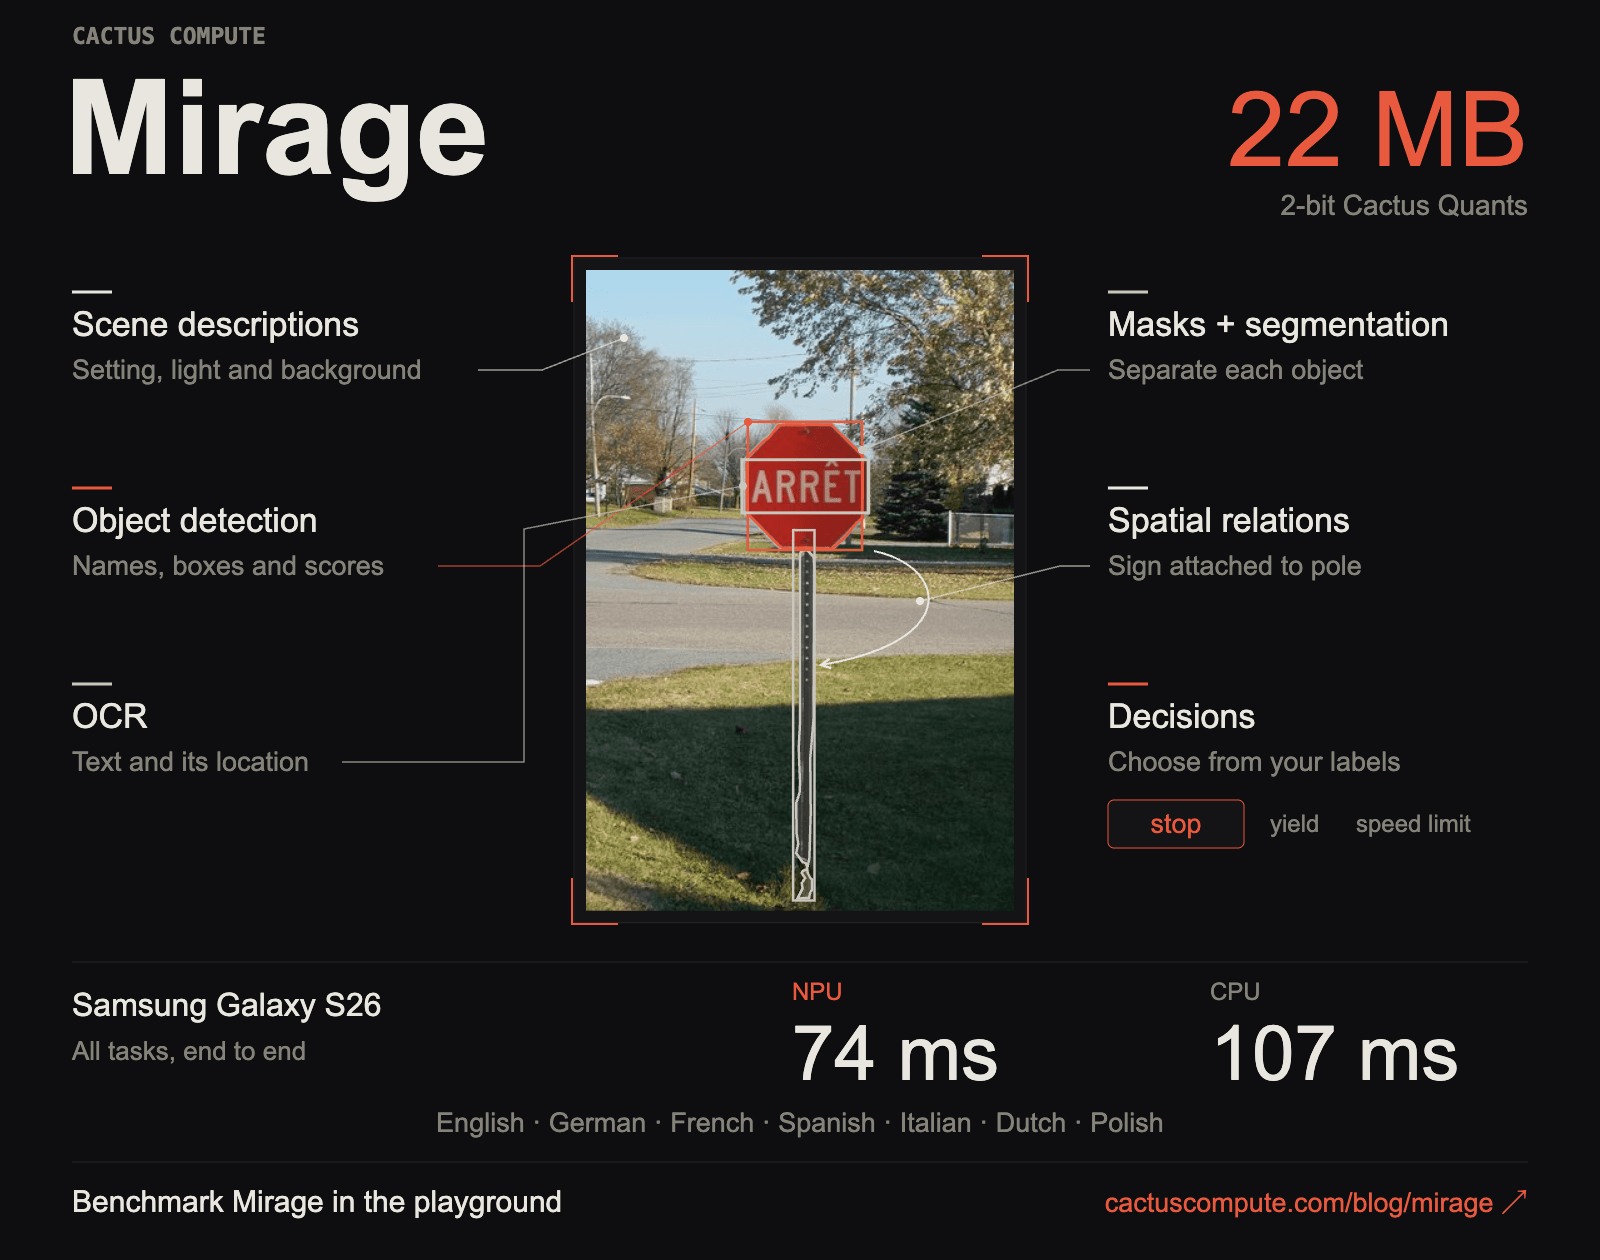
Cactus Compute's Mirage brings vision tasks on-device
The new open vision-language model targets detection, segmentation, and visual Q&A without relying on the cloud.
0 comments
No comments yet. Be the first to weigh in.