Liquid AI's LFM2.5-VL-3B targets on-device vision
The 3-billion-parameter vision-language model is tuned for faster multimodal work on edge hardware.
Liquid AI has released LFM2.5-VL-3B, a compact vision-language model designed to run multimodal workloads directly on edge hardware rather than in the cloud. At roughly 3 billion parameters, the model is small enough to fit on consumer and embedded devices while still handling combined image and text inputs, according to the company's announcement on Hugging Face.
The pitch is speed and locality. Liquid AI frames LFM2.5-VL-3B as an option for developers who want faster vision capabilities without shipping user data to a remote server — a trade-off that matters for latency-sensitive applications, privacy-conscious deployments, and settings with limited connectivity.
Why it matters
Most capable vision-language models are large and cloud-bound, which makes on-device multimodal inference a persistent bottleneck. A 3B model that keeps quality reasonable while improving throughput fits a growing niche:
- Real-time image understanding on phones and embedded systems
- Offline or intermittent-connectivity environments
- Applications where sending images off-device is a non-starter
The model ships under a custom license, so teams evaluating it for production should check the terms before building on top of it. As an entry point for Liquid AI's LFM2.5-VL line, it signals the company's continued focus on efficient models tuned for the edge rather than raw frontier scale.
Sources
More from LiquidAI
All LiquidAI releases →
Liquid AI debuts LFM3-1.7B for edge deployment
A compact 1.7B-parameter multilingual model built to run locally and serve as the base for specialized multimodal variants.
Liquid AI's LFM3-Omni-2B brings any-to-any AI to the edge
The 2-billion-parameter model combines vision, audio and speech-to-speech in a package small enough to run on device.
Liquid AI's LFM2.5 Puts a 24B MoE on Your Device
The new mixture-of-experts model keeps total capacity high while activating only about 2B parameters per token for edge agents.
More in Vision-Language
All Vision-Language →
SenseTime Releases Looped 9B Multimodal Model
The company's new SenseNova-Loop-9B pairs vision-language capabilities with a recurrent looped-transformer design.

Tencent releases Hunyuan Hy4-flash multimodal MoE
The lightweight, mixture-of-experts model adds vision and text instruction-following to Tencent's open Hunyuan lineup.
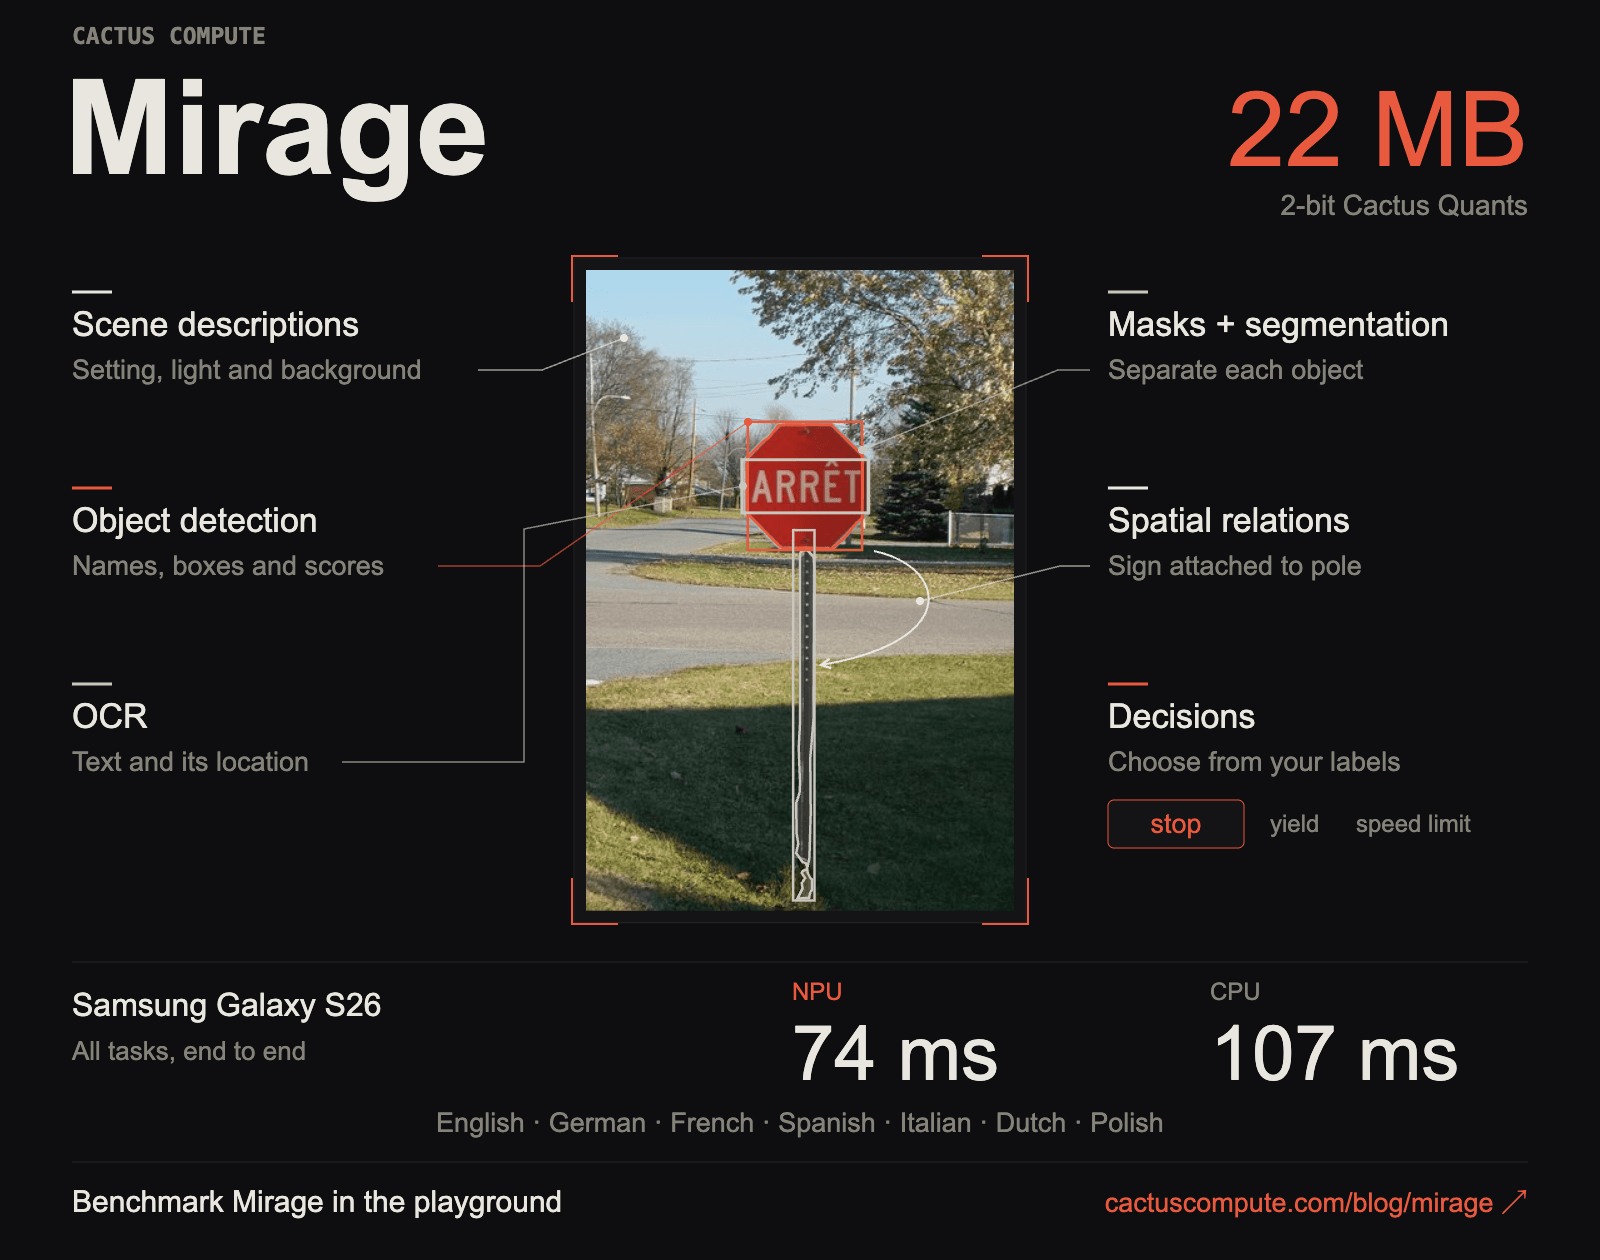
Cactus Compute's Mirage brings vision tasks on-device
The new open vision-language model targets detection, segmentation, and visual Q&A without relying on the cloud.
0 comments
No comments yet. Be the first to weigh in.