Cohere releases Apache-licensed Arabic speech model
The Cohere Labs transcription model targets Arabic and English audio under a permissive open license.

Cohere Labs has published a new speech recognition model built for Arabic, released on Hugging Face under the permissive Apache 2.0 license. The model, labeled "Transcribe Arabic 07-2026," handles automatic speech-to-text and supports both Arabic and English audio, according to the model page.
Arabic remains an underserved language in the automatic speech recognition space. Its rich morphology, wide range of regional dialects, and the gap between spoken vernaculars and Modern Standard Arabic make transcription notably harder than for English. A model tuned specifically for Arabic, rather than one where the language is an afterthought in a massive multilingual system, is a meaningful addition for developers working in the region.
Why it matters
The Apache 2.0 license is the practical headline here. It allows commercial use, modification, and redistribution with minimal friction, which lowers the barrier for startups, researchers, and public-sector teams that want to build Arabic voice applications without licensing negotiations.
- Primary focus on Arabic transcription, with English support alongside
- Released openly under Apache 2.0
- Aimed at ASR and speech-to-text workloads
Cohere Labs, the research arm behind Cohere's open model efforts, has increasingly leaned into releasing artifacts for languages beyond English. This release fits that pattern, and its real test will come as developers benchmark it against existing multilingual systems on dialectal Arabic audio in the wild.
Sources
- Visit
CohereLabs/cohere-transcribe-arabic-07-2026
Hugging Face
More from Cohere
All Cohere releases →
Cohere Labs releases compact North Micro Vision model
A small multilingual vision-language model built for instruction following arrives under a research-only license.
Cohere Releases North-Mini-Code, an Open MoE Model
The new Apache 2.0-licensed model is designed for code generation and agentic chat applications, using a Mixture-of-Experts architecture for efficiency.

Cohere Releases Top-Ranked Multilingual Transcription Model
The new automatic speech recognition model from Cohere Labs sets a new benchmark on the Hugging Face Open ASR Leaderboard for multilingual performance.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
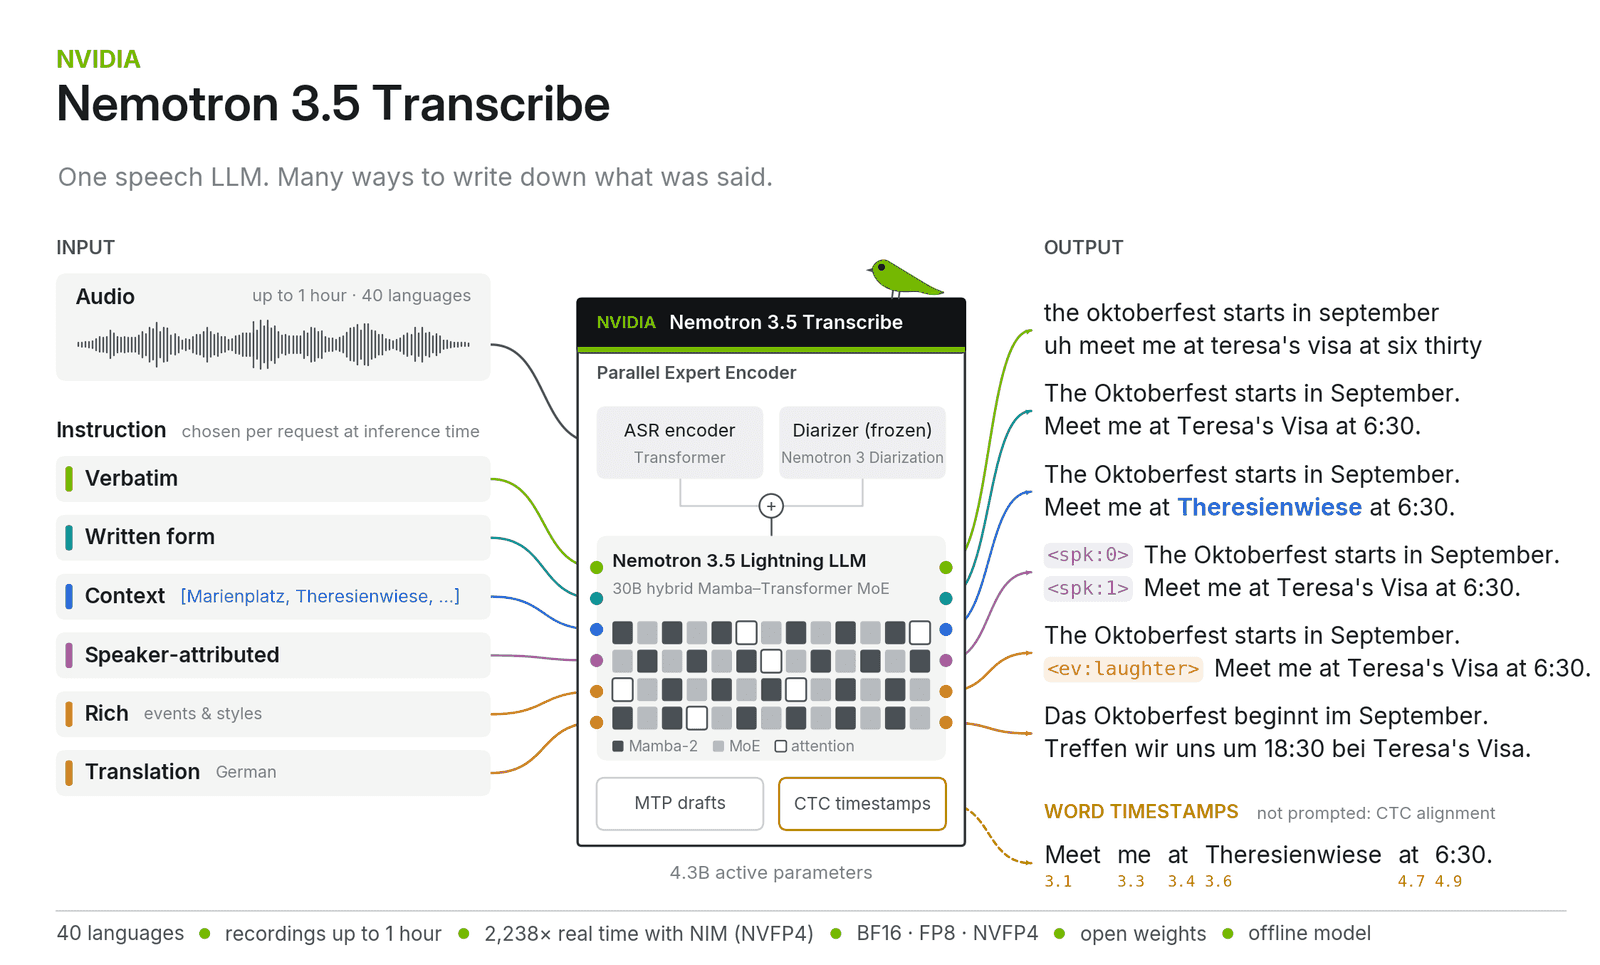
NVIDIA's Nemotron 3.5 Transcribe Brings Promptable ASR
A sparse 30B mixture-of-experts model handles multilingual transcription, translation, and speaker diarization from a single system.
0 comments
No comments yet. Be the first to weigh in.