Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
Alibaba's Qwen team has introduced Qwen-Audio-3.1-ASR, an audio-language model focused on automatic speech recognition that pairs transcription with speaker diarization across 30 languages. The release is documented in a technical report on Hugging Face and carries a permissive Apache 2.0 license.
The headline capability is combining who-spoke-when with what-was-said. Rather than producing a flat transcript, the model attributes speech to distinct speakers — a feature that is often bolted on separately in traditional ASR pipelines but is increasingly expected in a single system.
Why it matters
Speaker-diarized, multilingual ASR is the connective tissue for a lot of practical tooling, and having it in an openly licensed model lowers the barrier for teams building on top of it.
- Coverage spans 30 languages, widening its reach beyond English-centric systems.
- Built-in diarization suits meeting notes, interviews, and call transcription.
- Apache 2.0 allows commercial use and modification without heavy restrictions.
The technical report does not detail parameter counts or context limits, so some specifics remain to be filled in. Still, as part of the broader Qwen audio-language effort, the 3.1-ASR line signals continued investment in open speech models that handle real-world, multi-speaker audio rather than clean single-voice recordings.
Sources
- Visit
Qwen-Audio-3.1-ASR Technical Report
HF Papers
More from Qwen · Alibaba
All Qwen · Alibaba releases →
Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.
Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
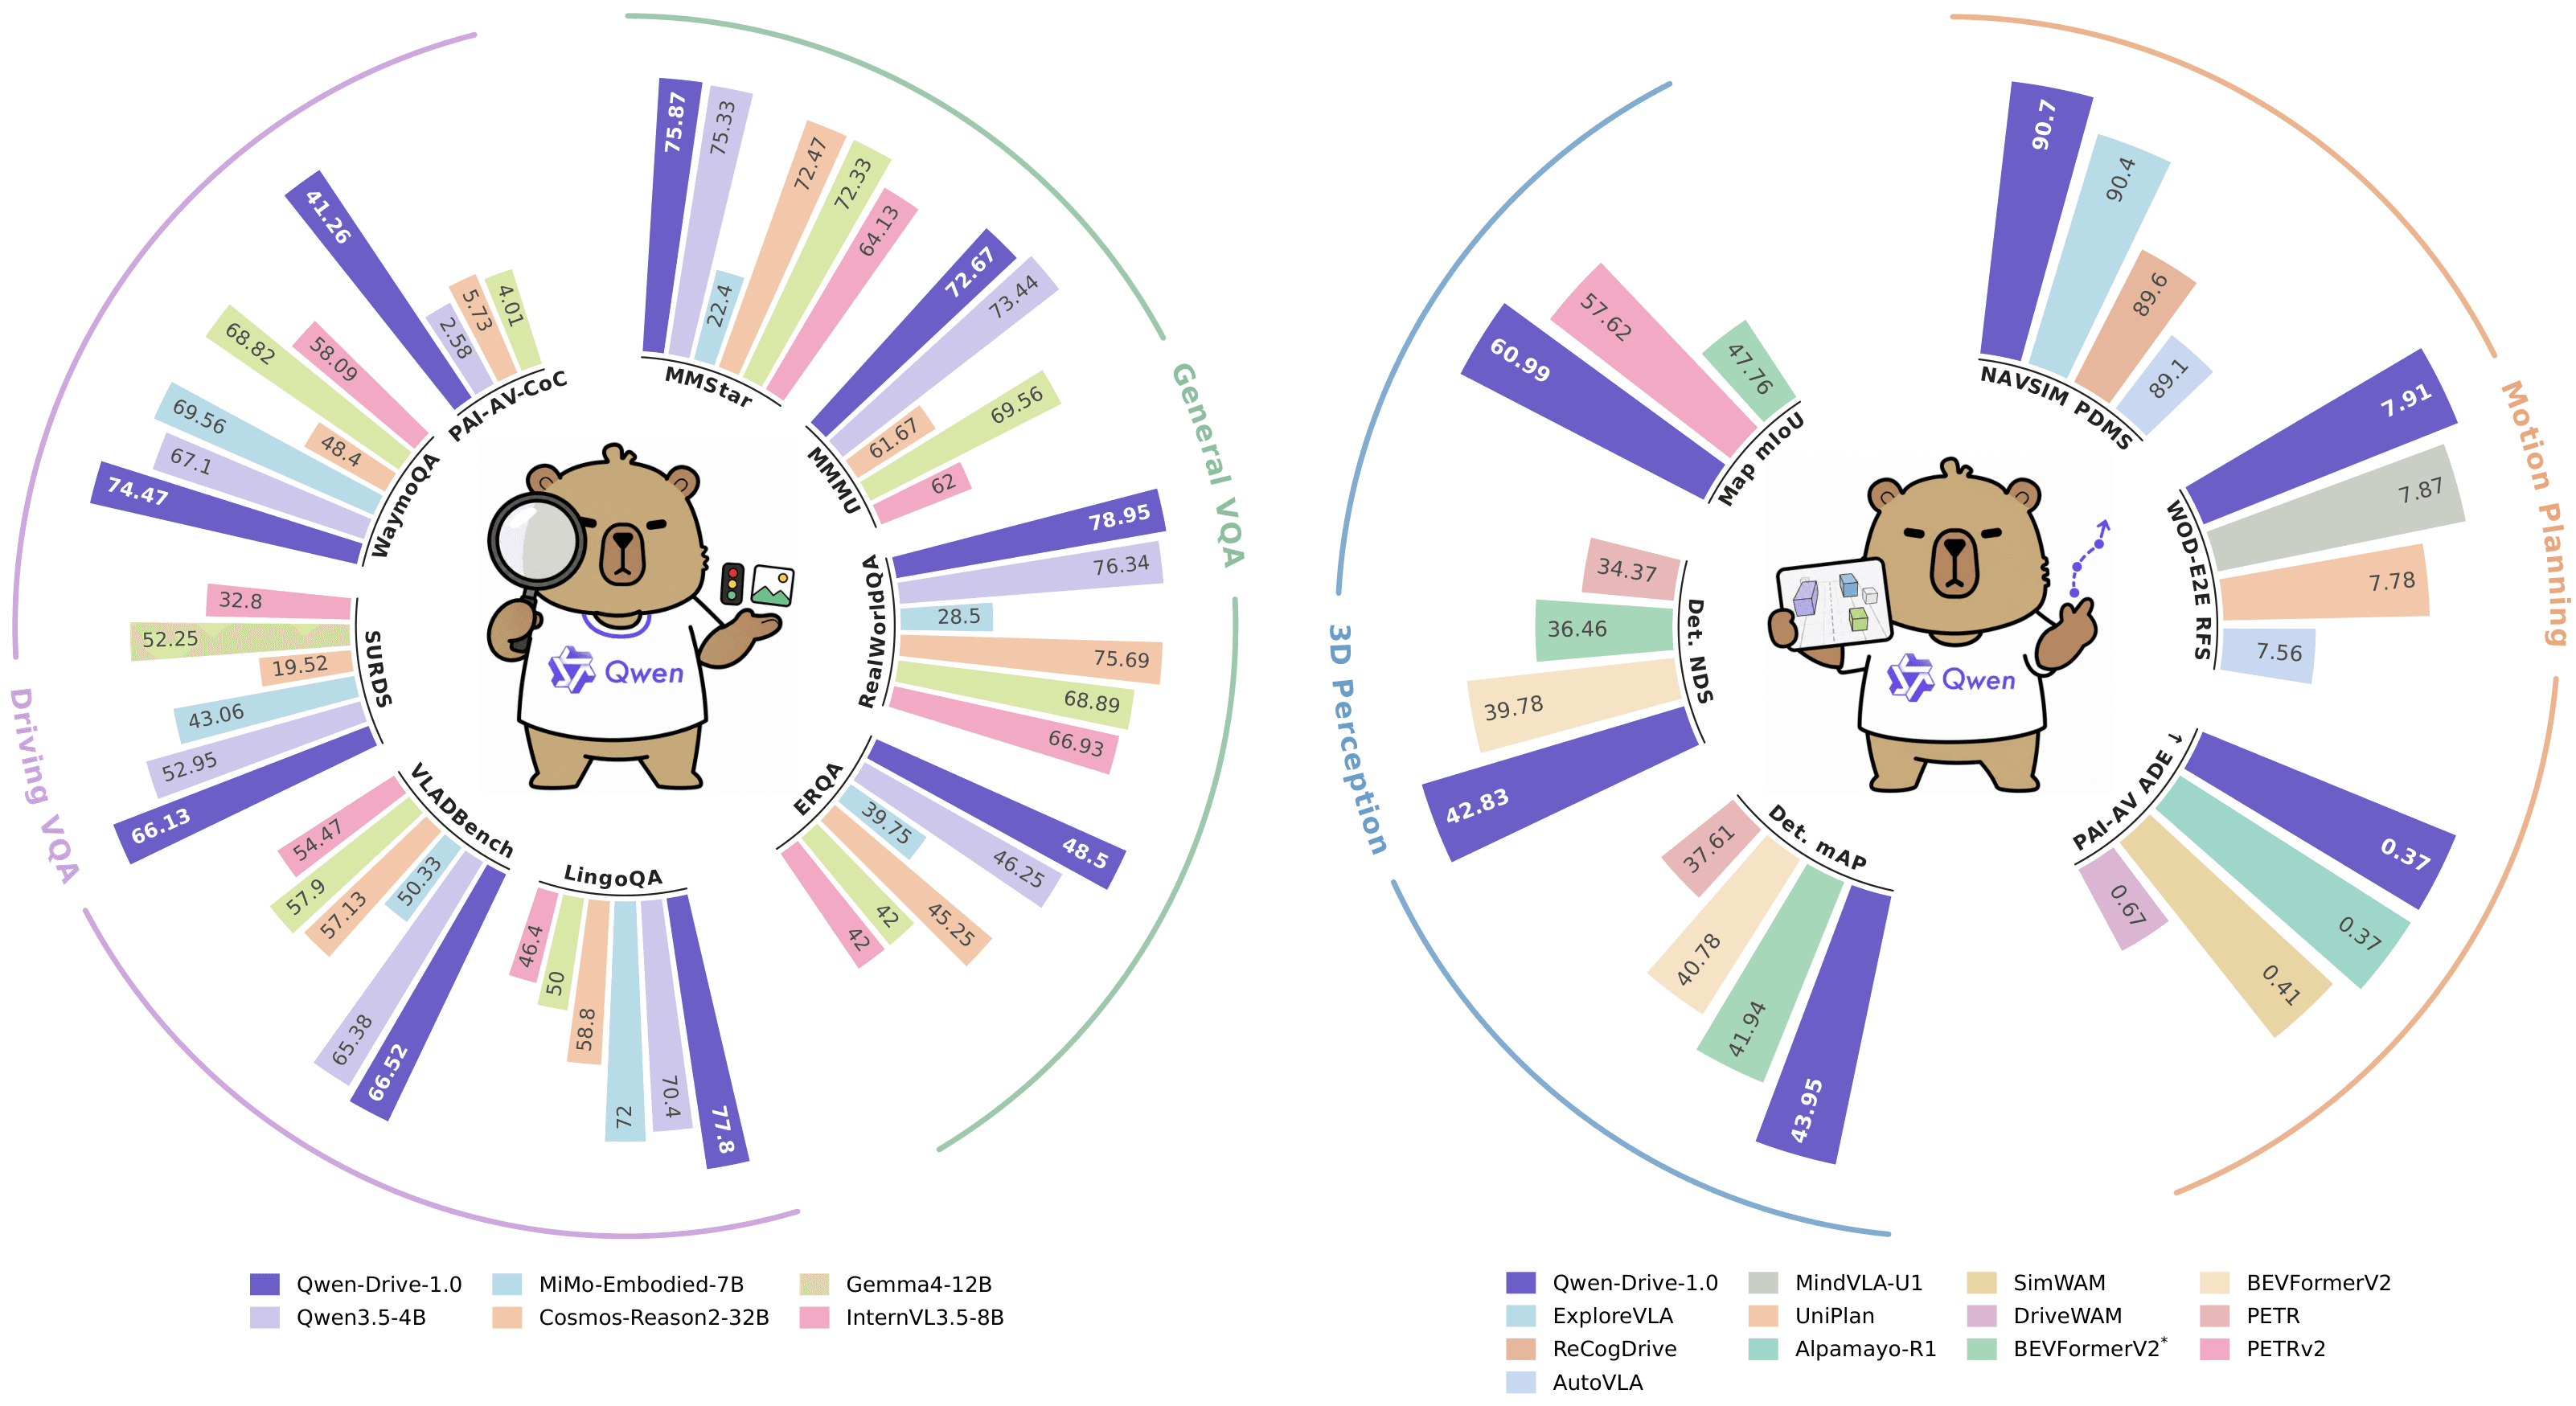
Qwen-Drive 1.0 targets autonomous driving with a 4B VLM
Alibaba's Qwen team brings its vision-language stack to the road with a compact model built for perception and motion planning.
More in Speech → Text
All Speech → Text →IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
TII Brings Falcon to Speech With New ASR Model
The team behind the Falcon language models expands into speech-to-text with its first automatic speech recognition release.
TII extends the Falcon family into speech recognition
The Abu Dhabi lab behind the Falcon language models releases Falcon ASR, an open speech-to-text system.
0 comments
No comments yet. Be the first to weigh in.