Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
Alibaba's Qwen team has published Qwen-Image-2.1 on Hugging Face, an image model that handles both text-to-image generation and image editing in a single package. The headline addition this time is RGBA support, meaning the model can produce images with a genuine alpha channel rather than flat, opaque frames.
That transparency capability is more consequential than it sounds. Most open image generators output solid backgrounds, forcing designers to run a separate cutout or masking step. Native RGBA lets the model emit assets — logos, icons, product shots, UI elements — that drop cleanly onto other layers.
Why it matters
Qwen has been steadily building out an open multimodal stack, and combining generation with editing in one model lowers the barrier for developers who want a single dependency rather than a pipeline of specialized tools. Key points from the release:
- Covers both text-to-image and image editing workflows
- Adds RGBA / transparency output
- Distributed openly through Hugging Face under a custom license
As always with open weights, the practical details — resolution ceilings, hardware requirements, and the exact license terms — are worth checking on the model card before building it into production. But the direction is clear: Qwen is positioning its image model as a self-contained creative tool rather than a raw research artifact.
Sources
- Visit
Qwen/Qwen-Image-2.1
Hugging Face
More from Qwen · Alibaba
All Qwen · Alibaba releases →Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.
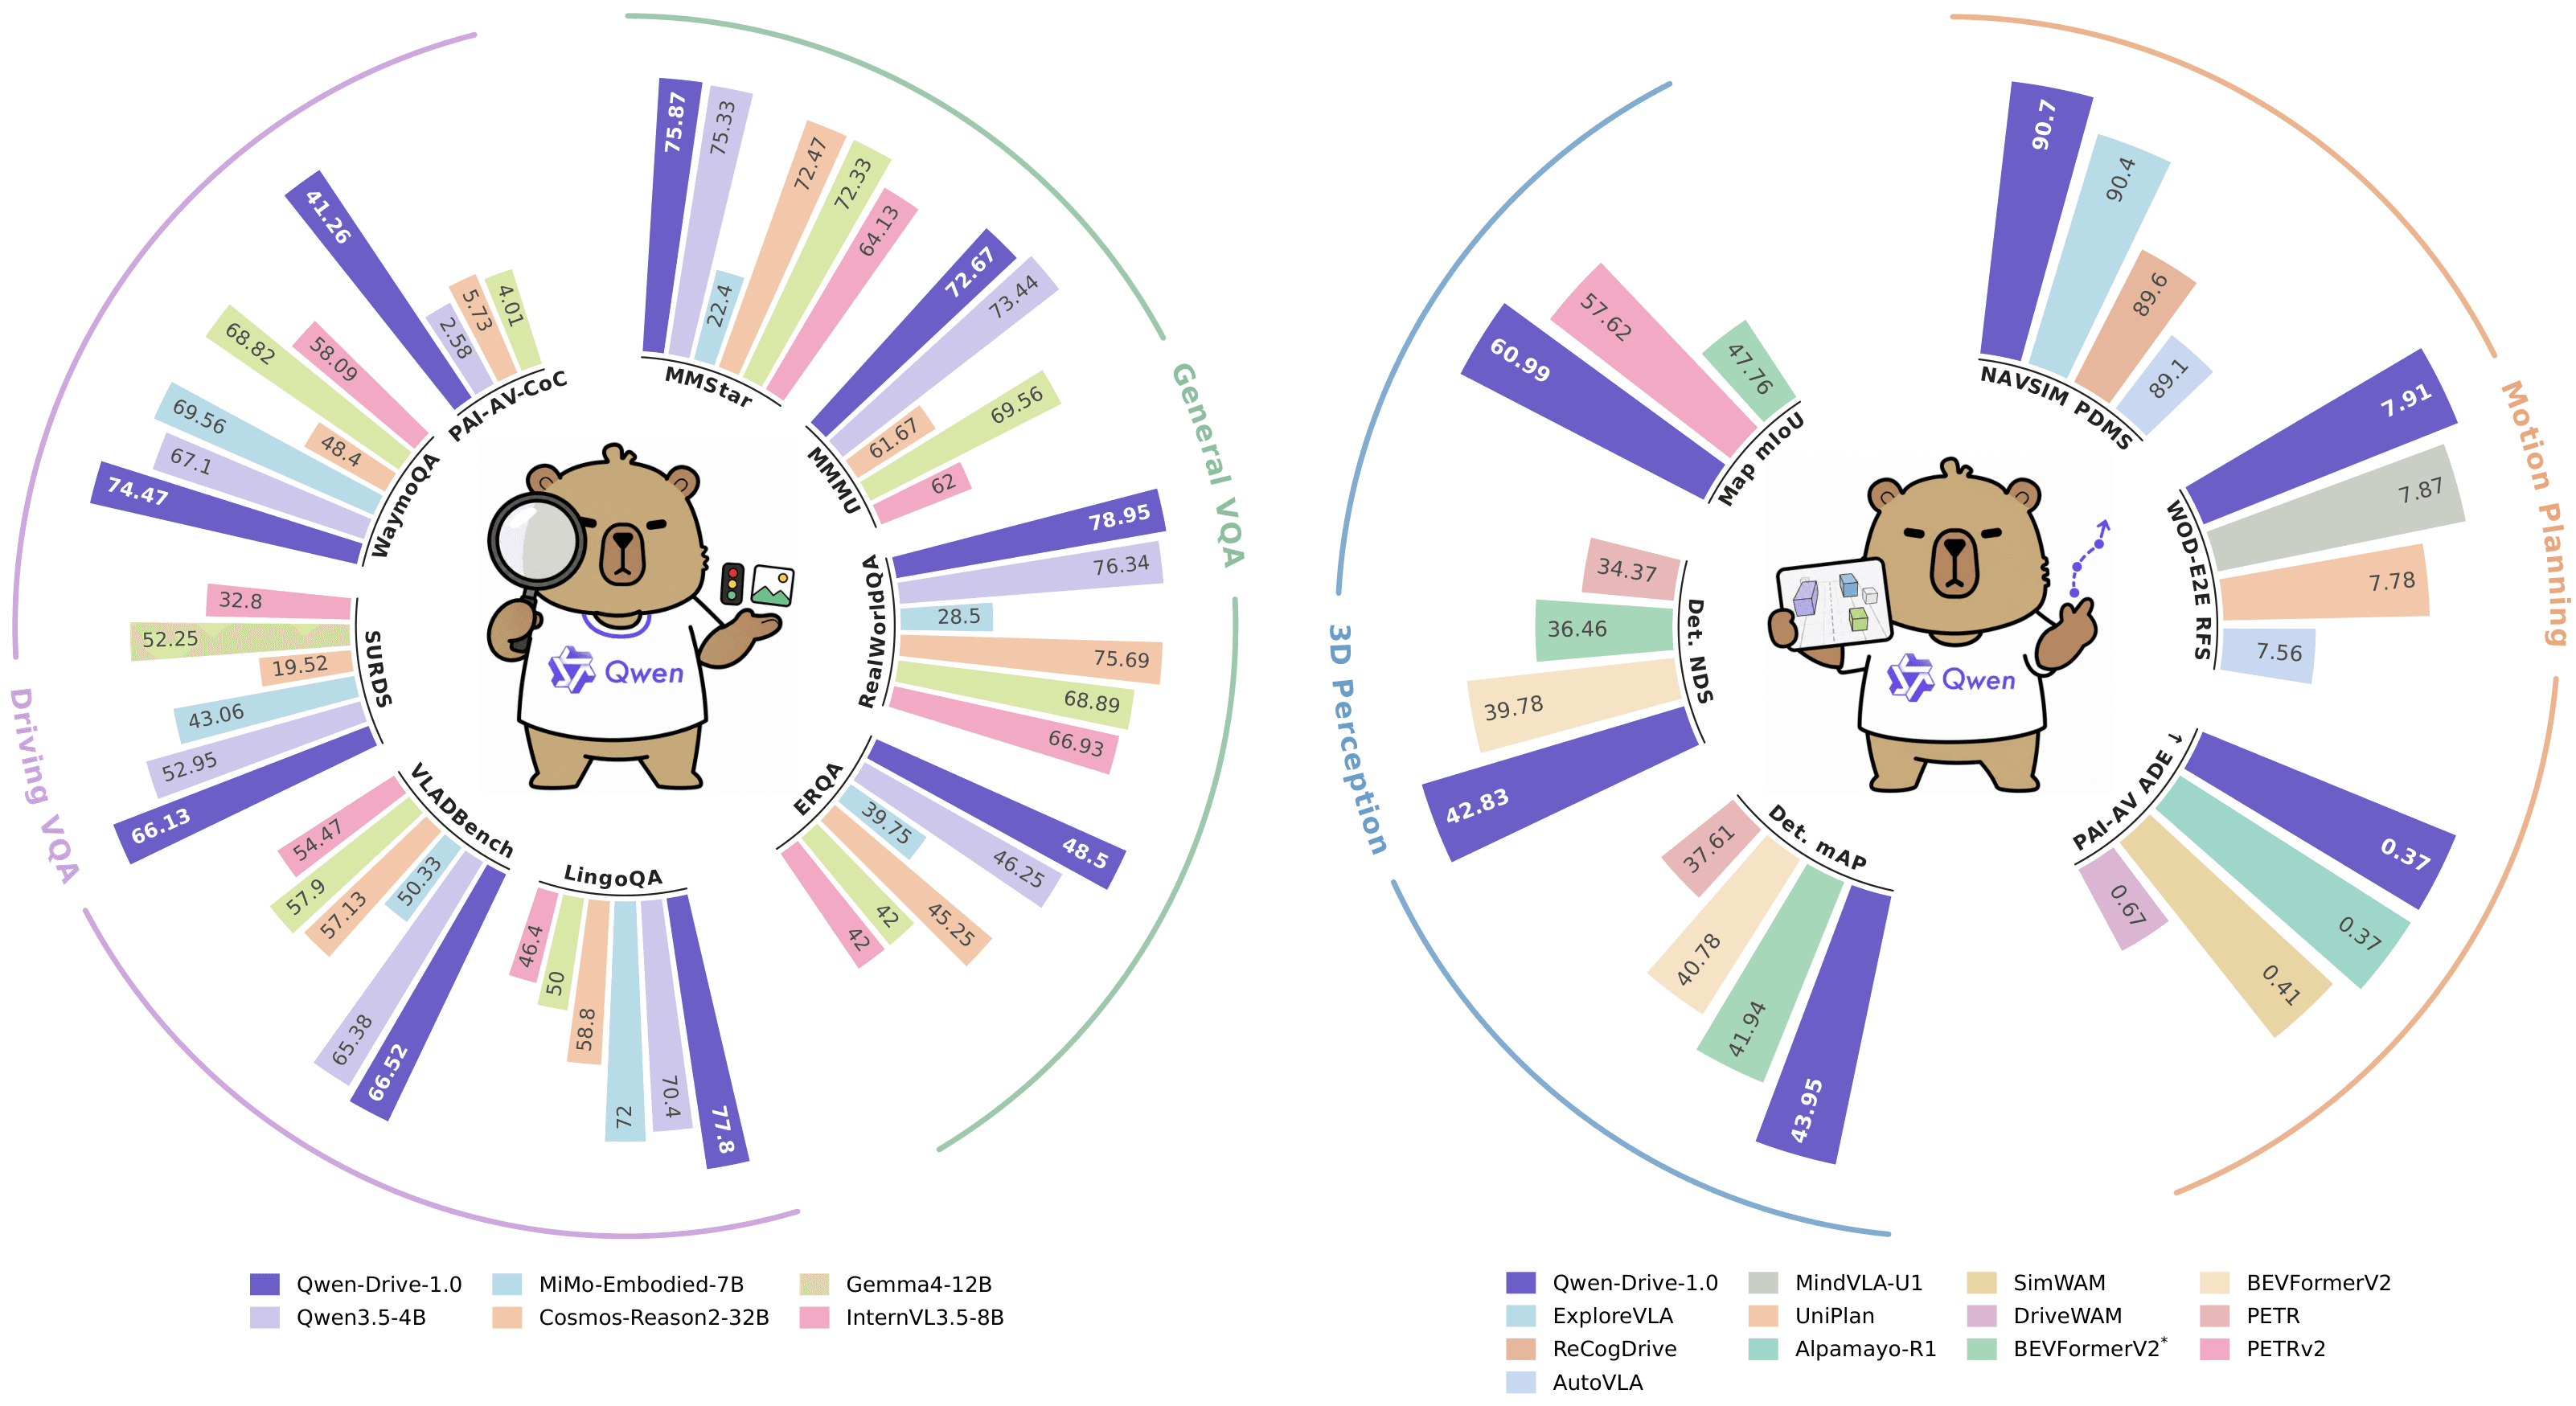
Qwen-Drive 1.0 targets autonomous driving with a 4B VLM
Alibaba's Qwen team brings its vision-language stack to the road with a compact model built for perception and motion planning.
More in Text → Image
All Text → Image →
Bria's Fibo 2.0 Brings Structured Prompts to Open Image AI
The new text-to-image and editing model leans on structured prompts and multi-reference inputs for more controllable generation.

Black Forest Labs ships FLUX.3 Image Klein for ComfyUI
The lab's latest open image model arrives packaged for ComfyUI with both generation and editing built in.

Black Forest Labs ships FLUX.3 Image Klein
The latest open image model from the FLUX team handles both text-to-image generation and editing, and arrives ready to run in Diffusers.
0 comments
No comments yet. Be the first to weigh in.