Yandex releases 80B MoE base model under Apache 2.0
AliceAI-Foundation is a sparse mixture-of-experts model with just 3B active parameters, aimed at Russian and English text.
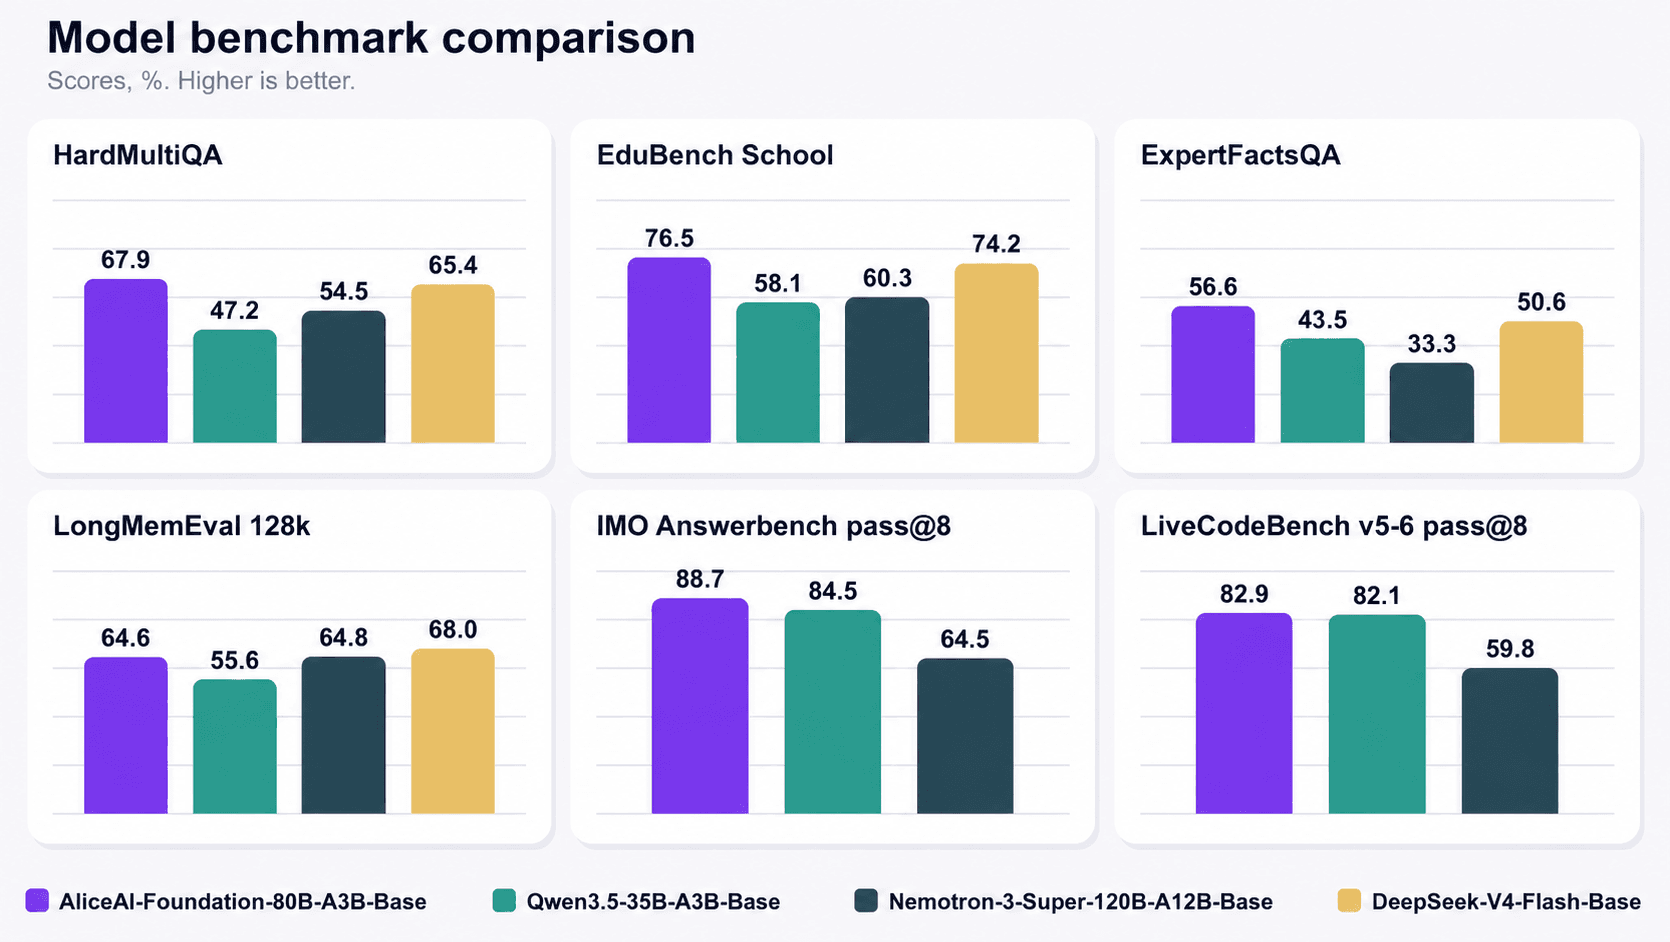
Yandex has published AliceAI-Foundation-80B-A3B-Base, an 80-billion-parameter mixture-of-experts (MoE) language model released under the permissive Apache 2.0 license. The model is available now on Hugging Face.
Despite its 80B total size, the model activates only about 3B parameters per token — the "A3B" in its name. That sparse design is the core appeal of MoE architectures: they aim to deliver the knowledge capacity of a large model while keeping inference costs closer to those of a much smaller dense one. It targets text in Russian and English.
Why it matters
This is a base model rather than an instruction-tuned chat variant, which makes it a foundation for developers who want to fine-tune for their own tasks. A few reasons it stands out:
- The Apache 2.0 license permits commercial use and modification with minimal restrictions.
- Strong Russian-language capability is comparatively rare among openly licensed frontier-scale models.
- The MoE design lowers the practical compute barrier for teams that want large-model quality.
As an initial release, the model arrives without a stated context length or published benchmark results in the record, so real-world evaluation will depend on the community putting it through its paces. Still, the combination of scale, an efficient architecture, and a genuinely open license makes AliceAI-Foundation a notable entry from a major player outside the usual US and Chinese labs.
Sources
- Visit
yandex/AliceAI-Foundation-80B-A3B-Base
Hugging Face
More from Yandex
All Yandex releases →
Yandex releases a sparse T5 model with 0.6B active params
The AliceAI-T5-35B-A0.6B is an encoder-decoder mixture-of-experts model that keeps only a sliver of its 35B parameters active per token.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.
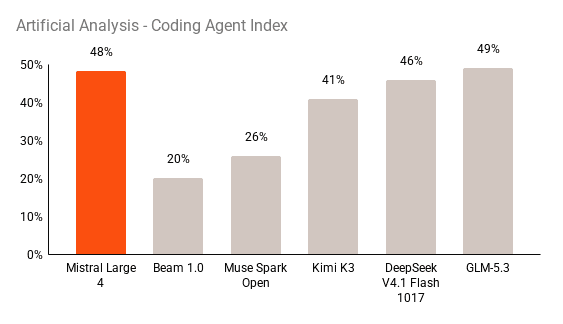
Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.
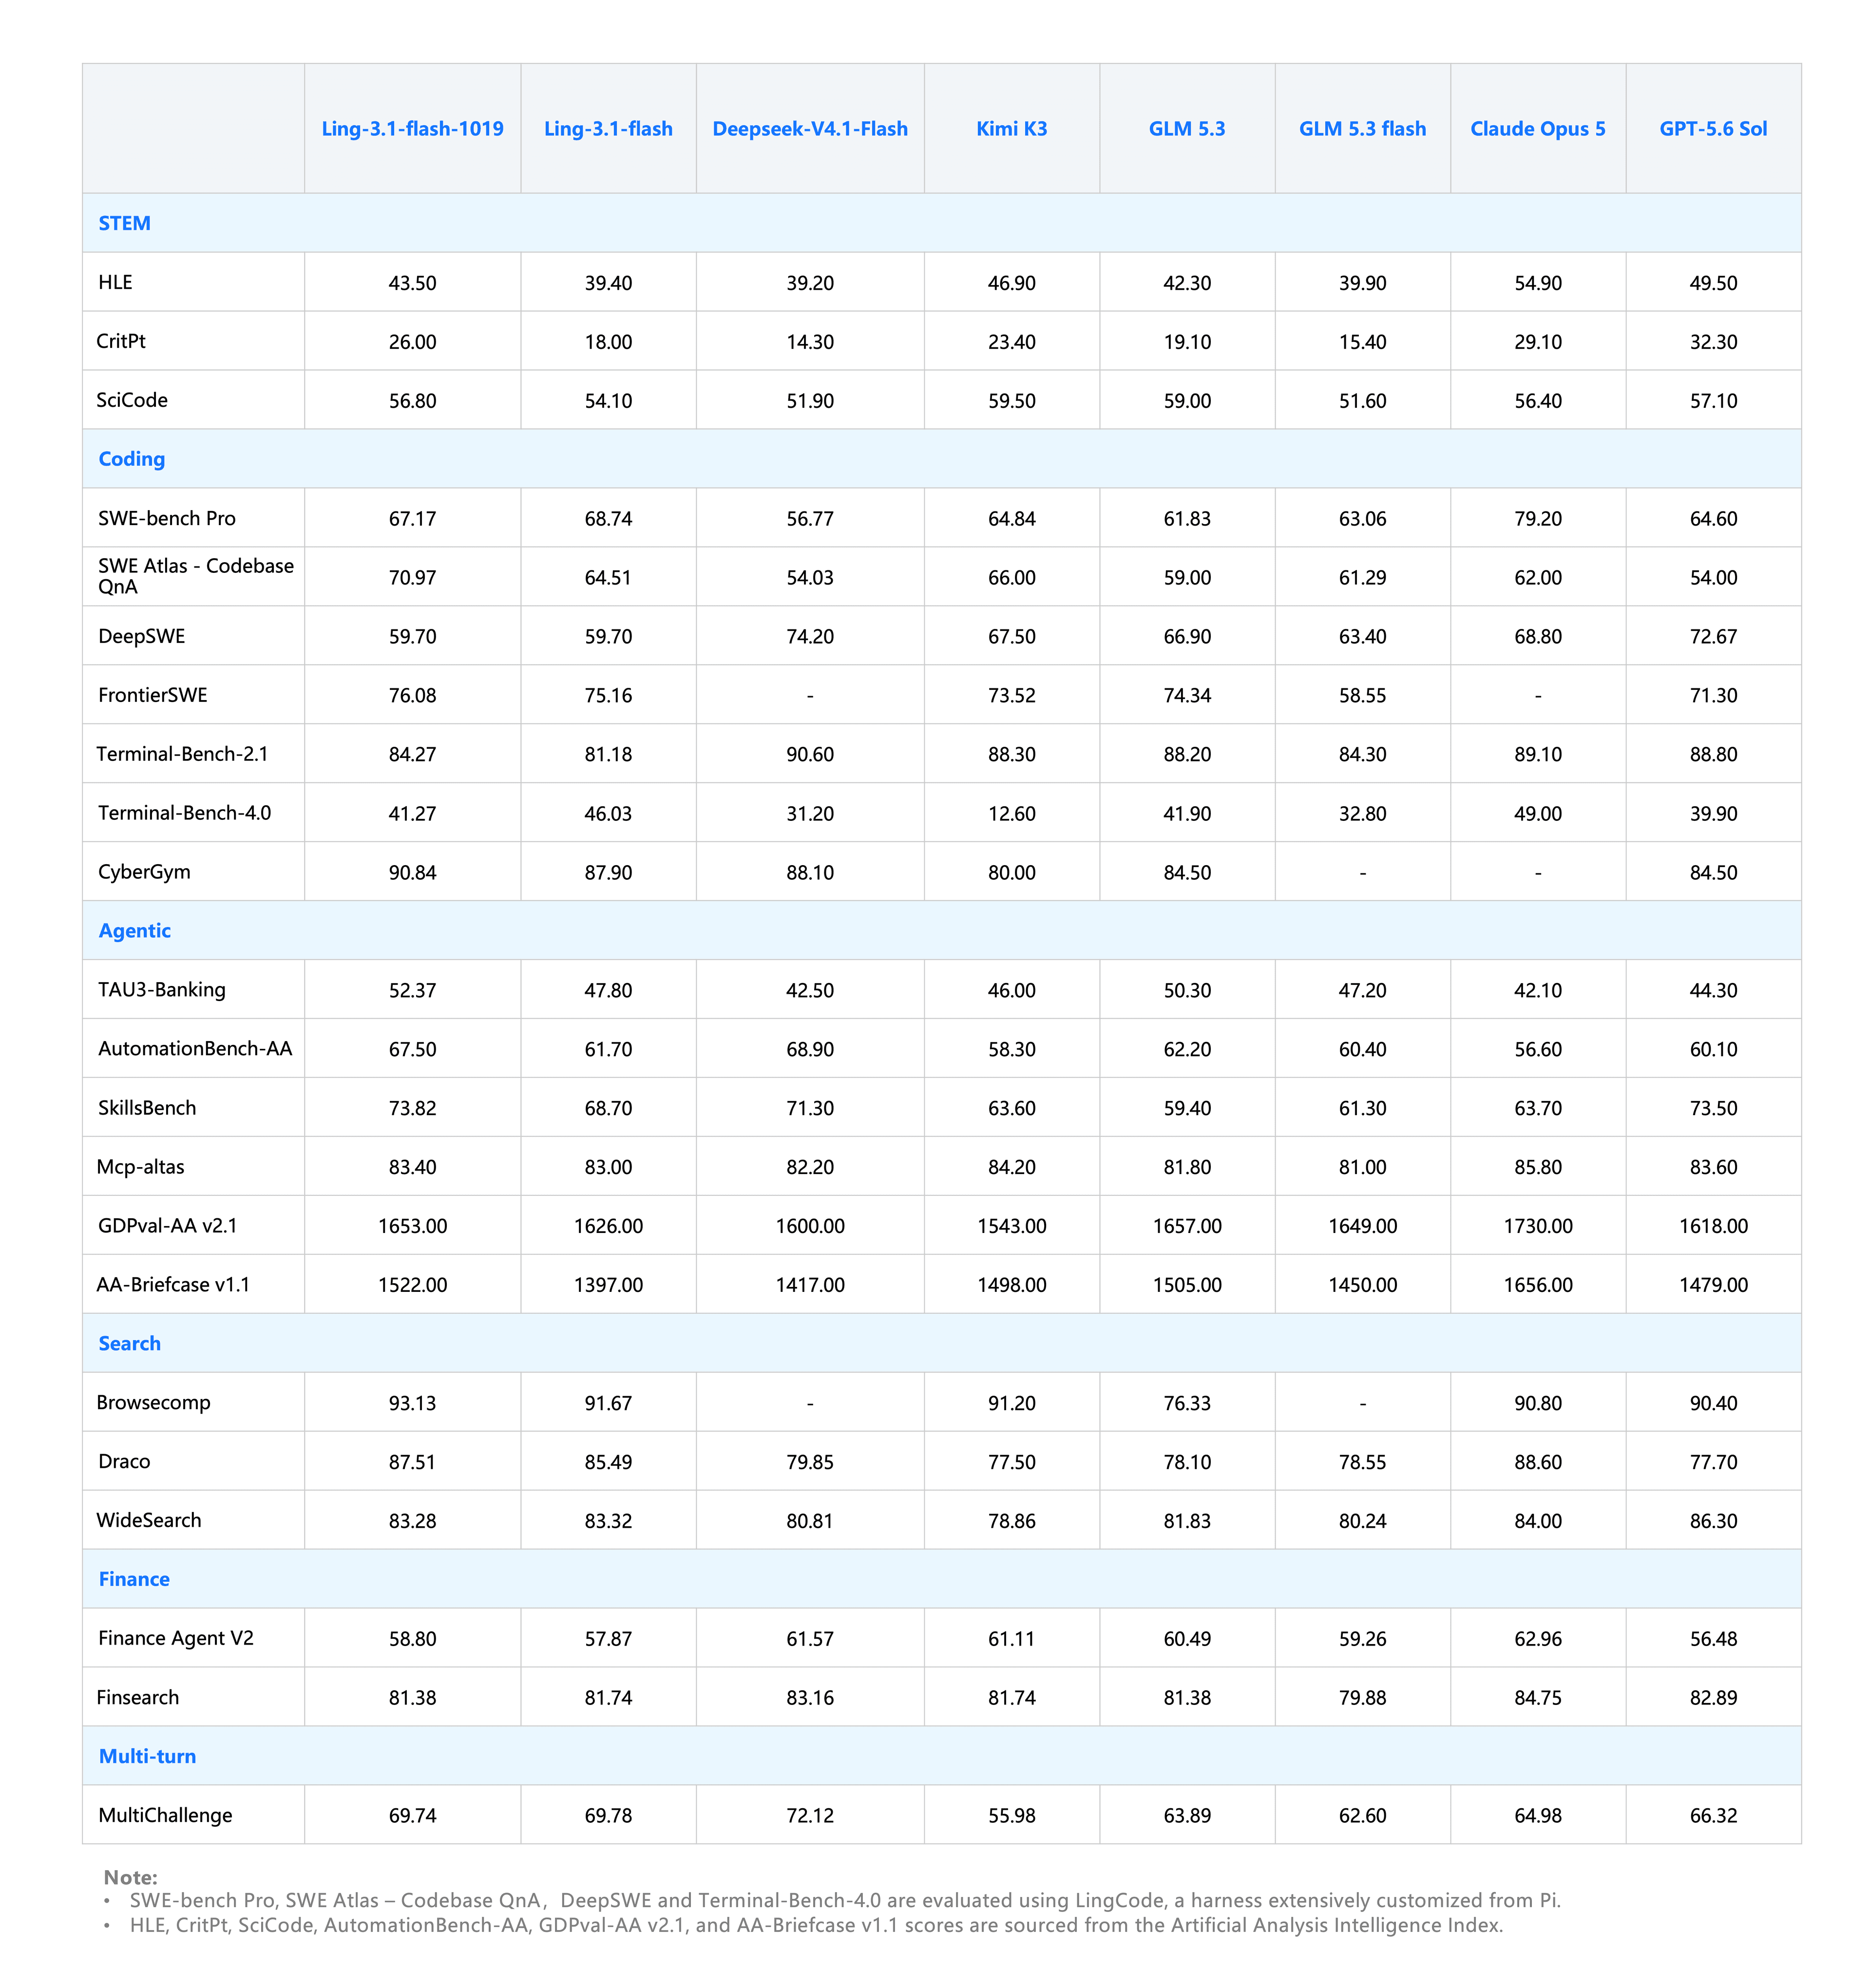
inclusionAI releases Ling-3.1-flash, an MIT MoE model
The new text model pairs a hybrid mixture-of-experts design with FP8 weights under a permissive license.
0 comments
No comments yet. Be the first to weigh in.