Yandex releases a sparse T5 model with 0.6B active params
The AliceAI-T5-35B-A0.6B is an encoder-decoder mixture-of-experts model that keeps only a sliver of its 35B parameters active per token.
Yandex has published AliceAI-T5-35B-A0.6B on Hugging Face, a text model that revisits a design most of the field has drifted away from: the encoder-decoder, or T5-style, architecture. What makes this release notable is the combination — it pairs that architecture with a mixture-of-experts (MoE) layout, totaling 35 billion parameters but activating only about 0.6 billion for any given token (model card).
The model is trained with a UL2 objective, a unified pretraining recipe that mixes different span-corruption and language-modeling tasks so a single encoder-decoder can handle both understanding and generation. That framing sets it apart from the decoder-only transformers that dominate today's open-weight releases.
Why it matters
The headline figure is the activation ratio. An extremely sparse MoE that fires roughly 0.6B of its 35B parameters per token is a bet on efficiency:
- Total capacity of a 35B model, with the per-token compute closer to a sub-billion-parameter model.
- An encoder-decoder backbone that can be well-suited to structured tasks like summarization, translation, and retrieval-style workloads.
- A UL2 training mix aimed at flexibility across generation and comprehension.
A few practical details are not spelled out in the record, including the context length and the specific license terms, so teams evaluating the model for production should check the repository directly. Still, seeing a major lab lean into a sparse encoder-decoder is a useful reminder that the design space for open models is wider than the decoder-only mainstream suggests.
Sources
- Visit
yandex/AliceAI-T5-35B-A0.6B
Hugging Face
More from Yandex
All Yandex releases →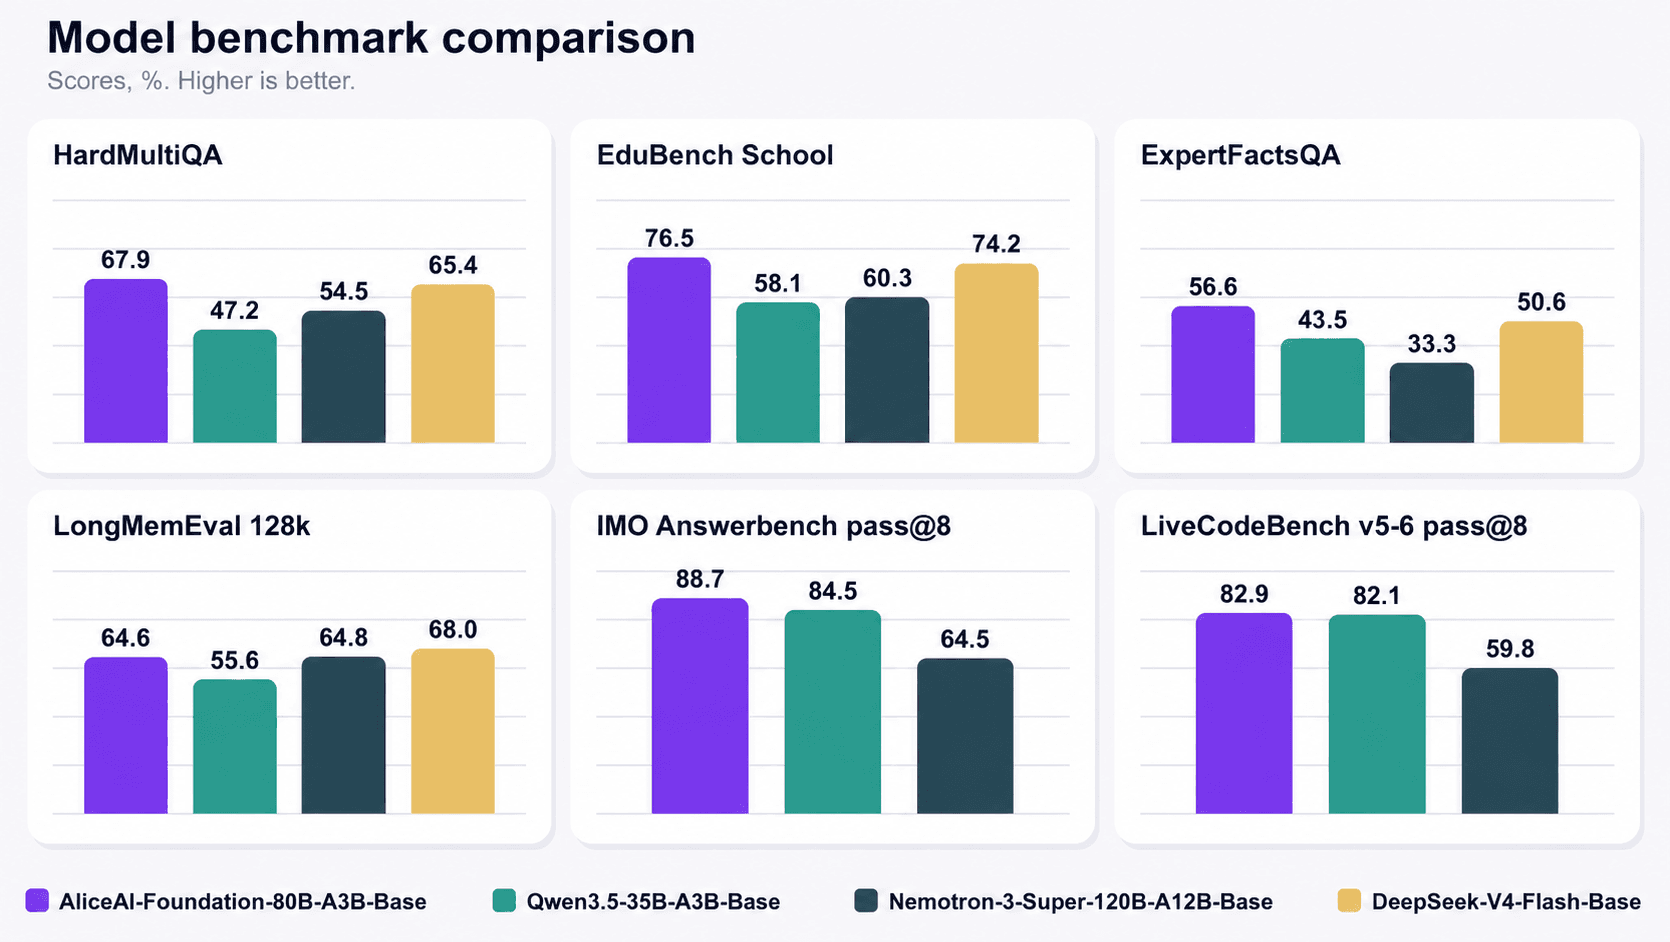
Yandex releases 80B MoE base model under Apache 2.0
AliceAI-Foundation is a sparse mixture-of-experts model with just 3B active parameters, aimed at Russian and English text.
More in Text / LLM
All Text / LLM →IBM's Granite Switch Treats Models Like Software
A new Apache-2.0 release reframes enterprise LLMs as components you can swap and update in place.

Mistral Large 4 Arrives as a 1T-Parameter MoE
The new flagship pairs a trillion total parameters with 52B active per token and adds vision alongside multilingual text.

Nanbeige 4.3 Arrives as a 33B Bilingual Model
A dense English–Chinese language model lands under Apache 2.0, aimed at teams that want permissive licensing at mid-size scale.
0 comments
No comments yet. Be the first to weigh in.