NetEase Youdao debuts Confucius4-R2T2 streaming ASR
The multilingual speech-to-text model targets low latency and ships with vLLM support for production deployments.
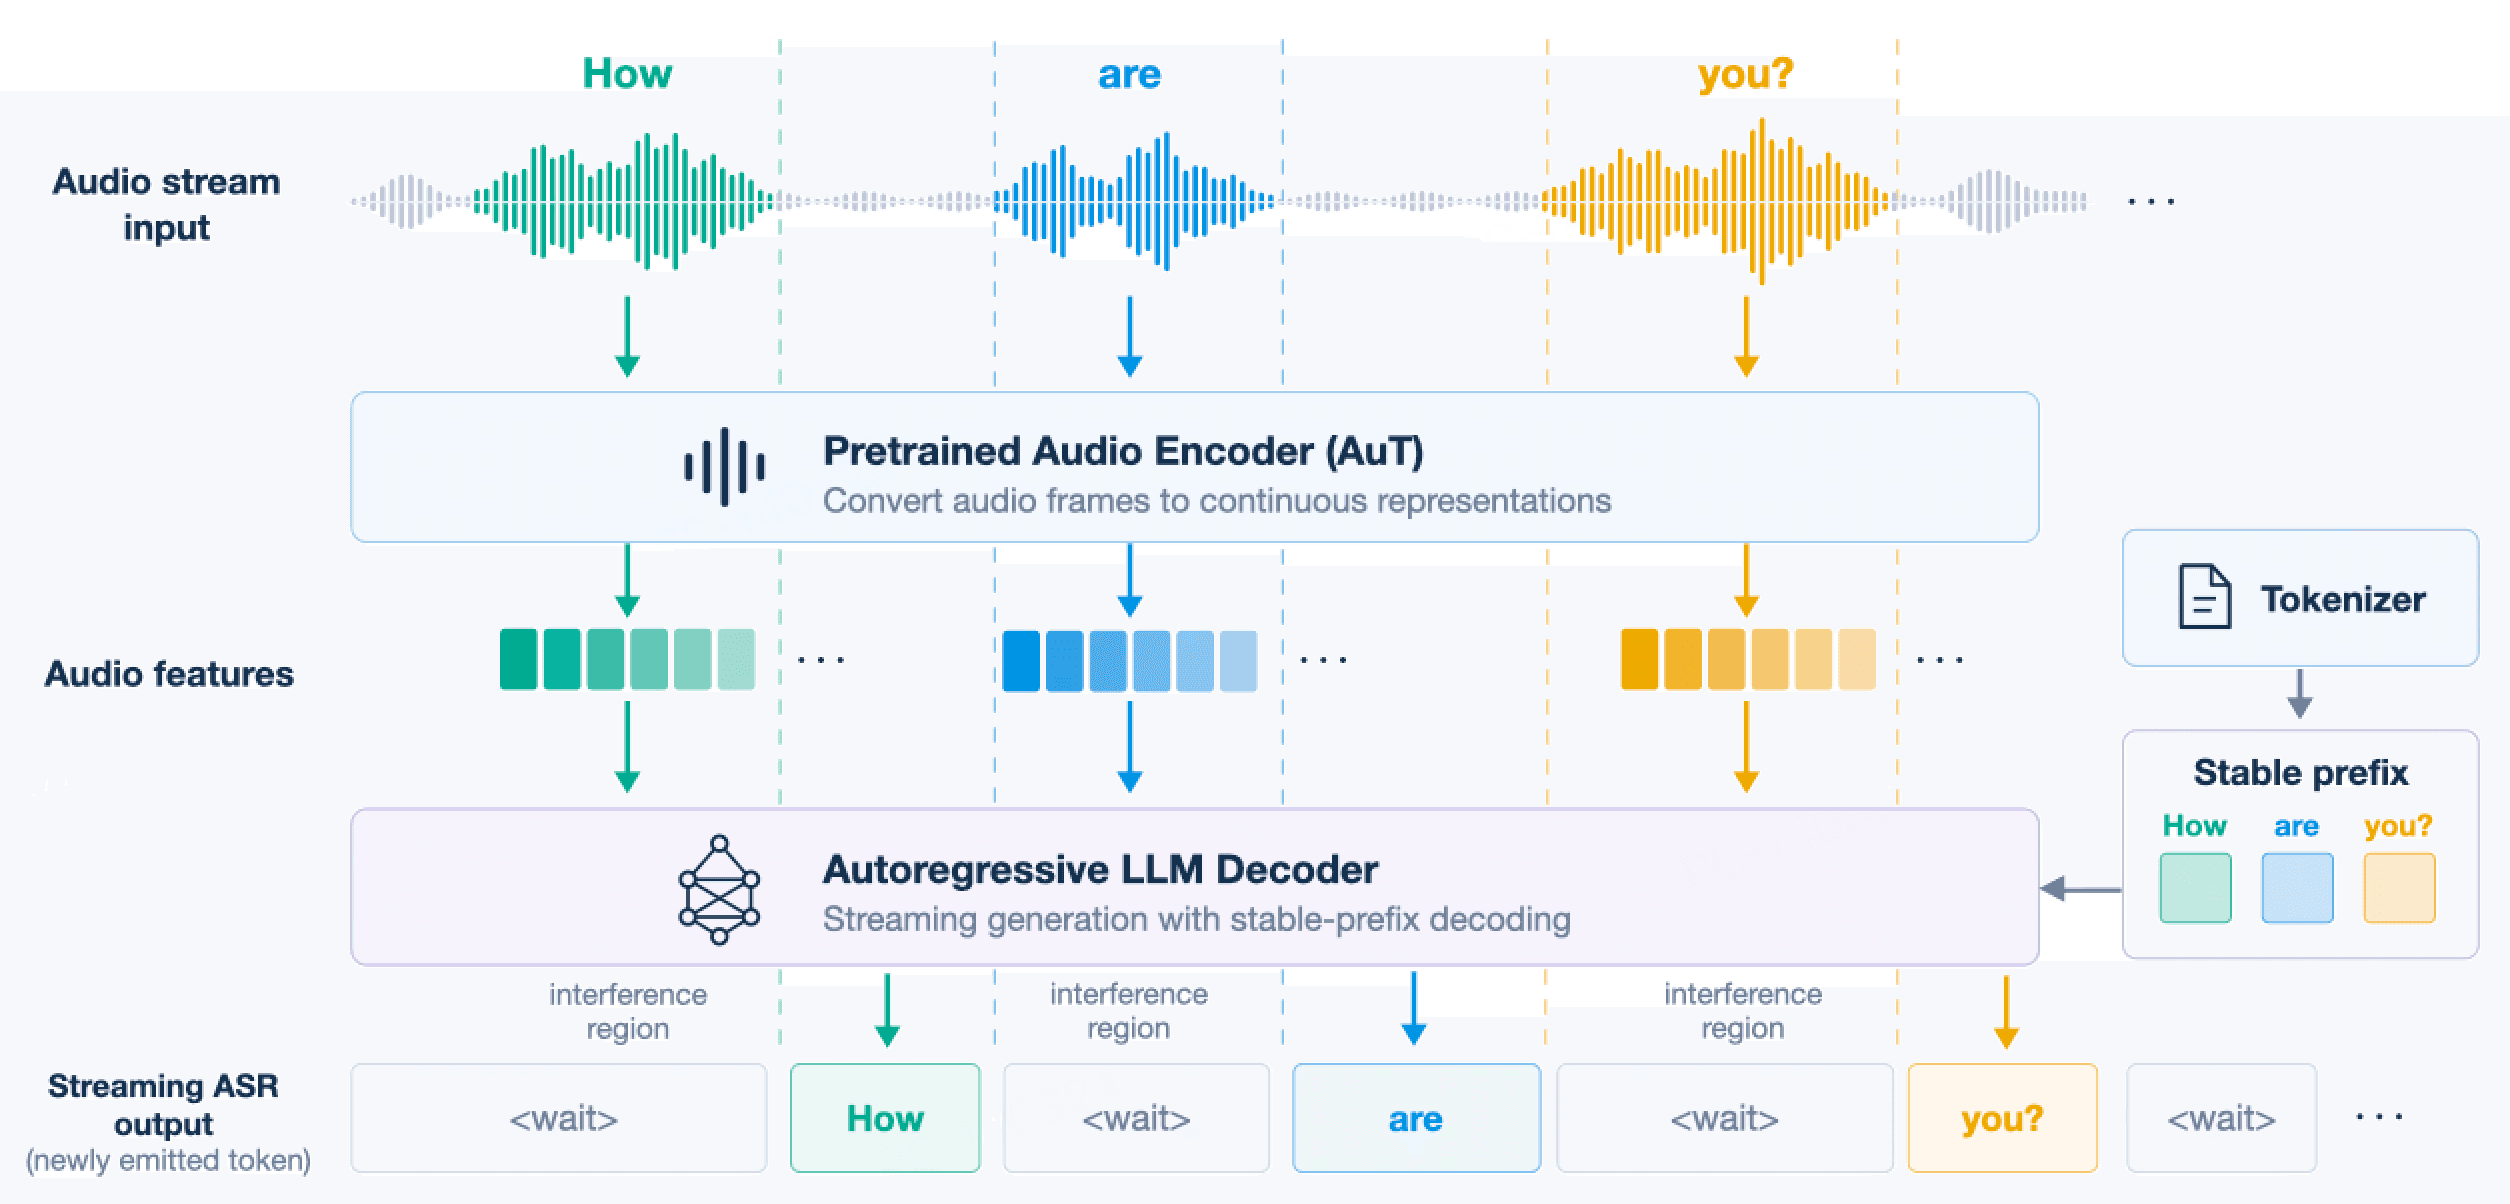
NetEase Youdao has released Confucius4-R2T2, a multilingual automatic speech recognition model built for streaming, low-latency transcription. The model is available on Hugging Face under a custom license.
The headline feature is real-time behavior: rather than waiting for a complete audio clip, a streaming ASR system emits text as speech arrives, which matters for live captioning, voice assistants, and interactive agents where perceived responsiveness is as important as raw accuracy. Youdao pairs that with multilingual coverage, extending the model's usefulness beyond a single language market.
Why it matters
The release also ships with vLLM support, a notable choice for a speech model. vLLM has become a standard serving layer in the open-source LLM world, and wiring ASR into that same inference stack simplifies deployment for teams already running vLLM-based infrastructure.
- Streaming design for low-latency, incremental transcription
- Multilingual recognition across languages
- vLLM integration for efficient serving
As an ASR entry from NetEase Youdao, a company with a long history in language and education products, Confucius4-R2T2 reflects a broader trend of speech models being packaged for the same tooling and workflows that power text generation. Details on parameter count and supported language list were not specified in the release; prospective users should consult the model card for licensing terms and integration notes.
Sources
- Visit
netease-youdao/Confucius4-R2T2
Hugging Face
More in Speech → Text
All Speech → Text →ServiceNow Debuts Apriel Voice 27B, an Open Speech Model
The 27-billion-parameter preview unifies text-to-speech, transcription, and reasoning in a single open model.
IBM's Granite Speech 5.0 Adds Speaker Attribution
The Apache-2.0 speech model handles transcription, translation, and figuring out who said what.
Qwen-Audio-3.1-ASR Adds Speaker-Aware Transcription
Alibaba's new open audio-language model transcribes and diarizes speech across 30 languages under an Apache 2.0 license.
0 comments
No comments yet. Be the first to weigh in.