Qwen-Image-2.1-Turbo targets faster generation
Alibaba's Qwen team ships a distilled, few-step variant of its image model built for speed.
Alibaba's Qwen team has published Qwen-Image-2.1-Turbo, an official turbo variant of its Qwen-Image 2.1 model aimed squarely at faster image generation. The release lands on Hugging Face and supports both text-to-image and image editing workflows.
The "Turbo" label points to distillation: the model is designed to produce results in far fewer sampling steps than a standard diffusion pass. That matters because step count is one of the biggest levers on both latency and compute cost for image models, so a few-step variant can meaningfully cut inference time without requiring users to switch families.
Why it matters
Fast, open image models are increasingly the workhorses behind real products, from design tools to automated content pipelines. A distilled variant offers a few practical advantages:
- Lower latency per image, useful for interactive editing
- Reduced GPU cost at scale
- Drop-in alignment with the existing Qwen-Image 2.1 ecosystem
As with other recent Qwen vision releases, the weights ship under a custom license rather than a standard permissive one, so teams planning commercial deployment should read the terms on the model card closely. The trade-off common to turbo distillations — some loss of fine detail or prompt fidelity versus the full model — will be worth testing against specific workloads before committing.
Sources
- Visit
Qwen/Qwen-Image-2.1-Turbo
Hugging Face
More from Qwen · Alibaba
All Qwen · Alibaba releases →
Qwen-Image-2.1 Adds RGBA to Image Generation
Alibaba's Qwen team updates its open image model with transparency support and joint text-to-image and editing capabilities.
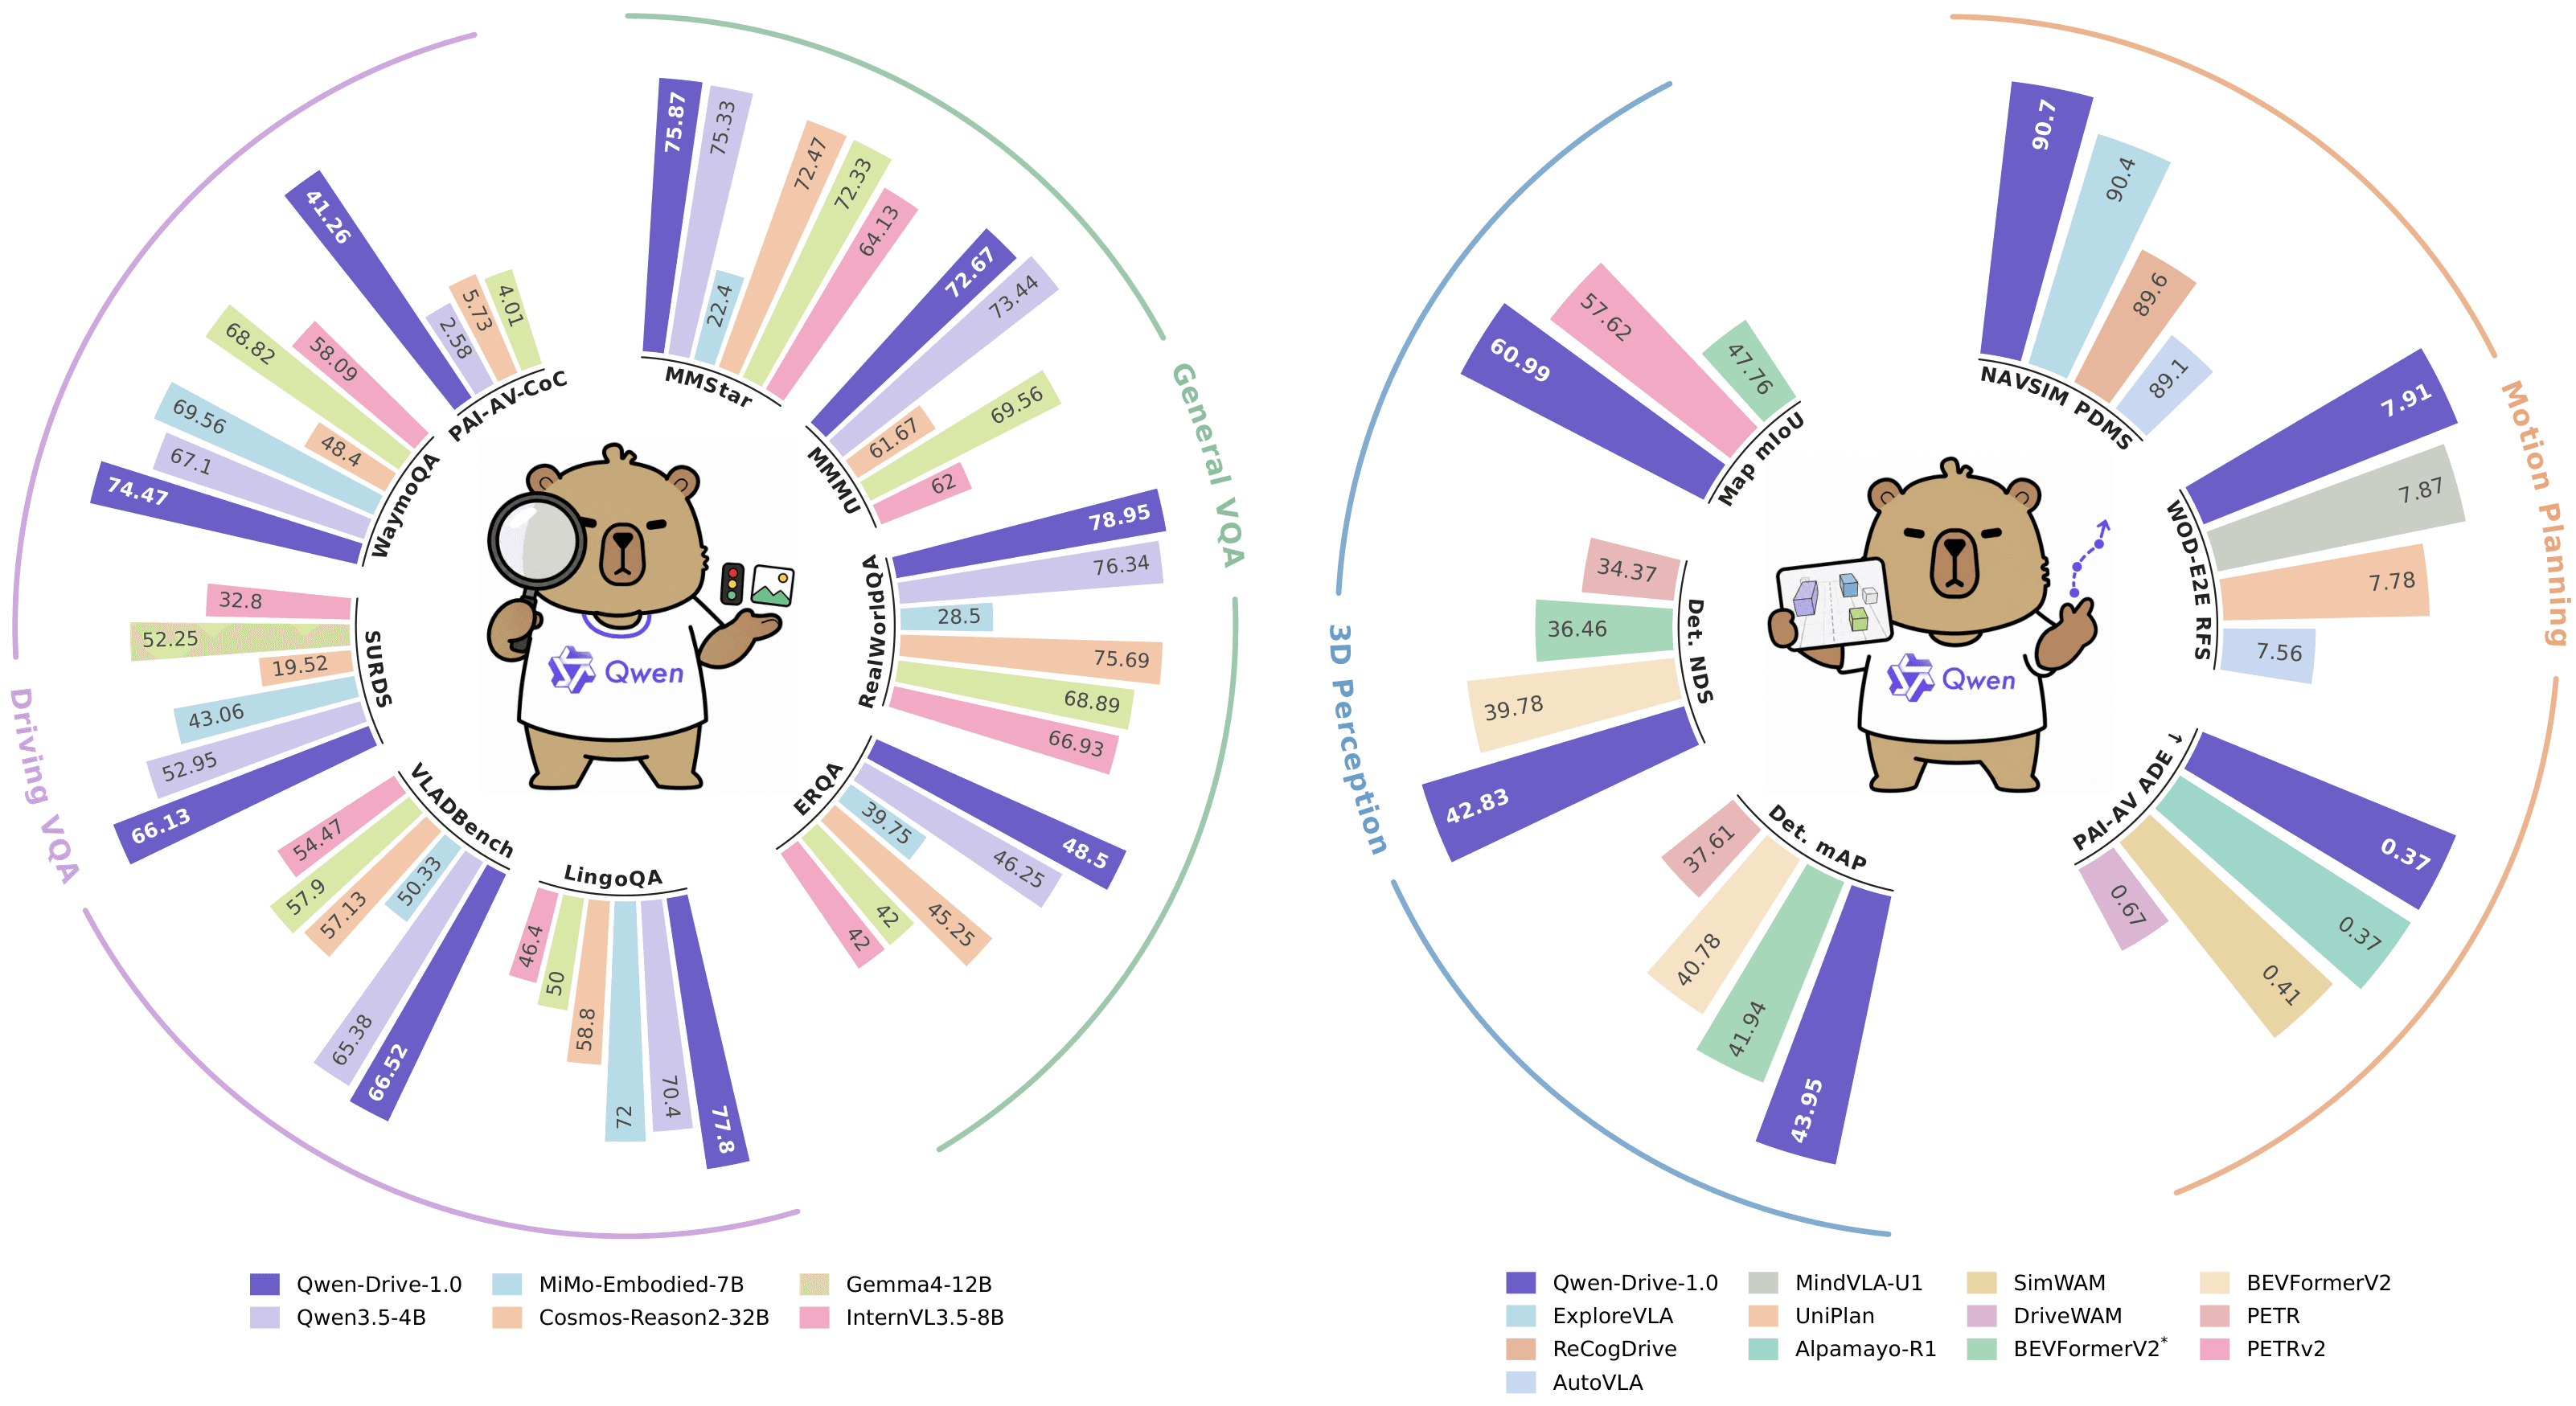
Qwen-Drive 1.0 targets autonomous driving with a 4B VLM
Alibaba's Qwen team brings its vision-language stack to the road with a compact model built for perception and motion planning.

Qwen releases 2.4T-parameter open MoE with 95B active
Alibaba's Qwen team pushes its largest sparse model yet, activating 95 billion parameters per token from a 2.4-trillion-parameter pool.
More in Text → Image
All Text → Image →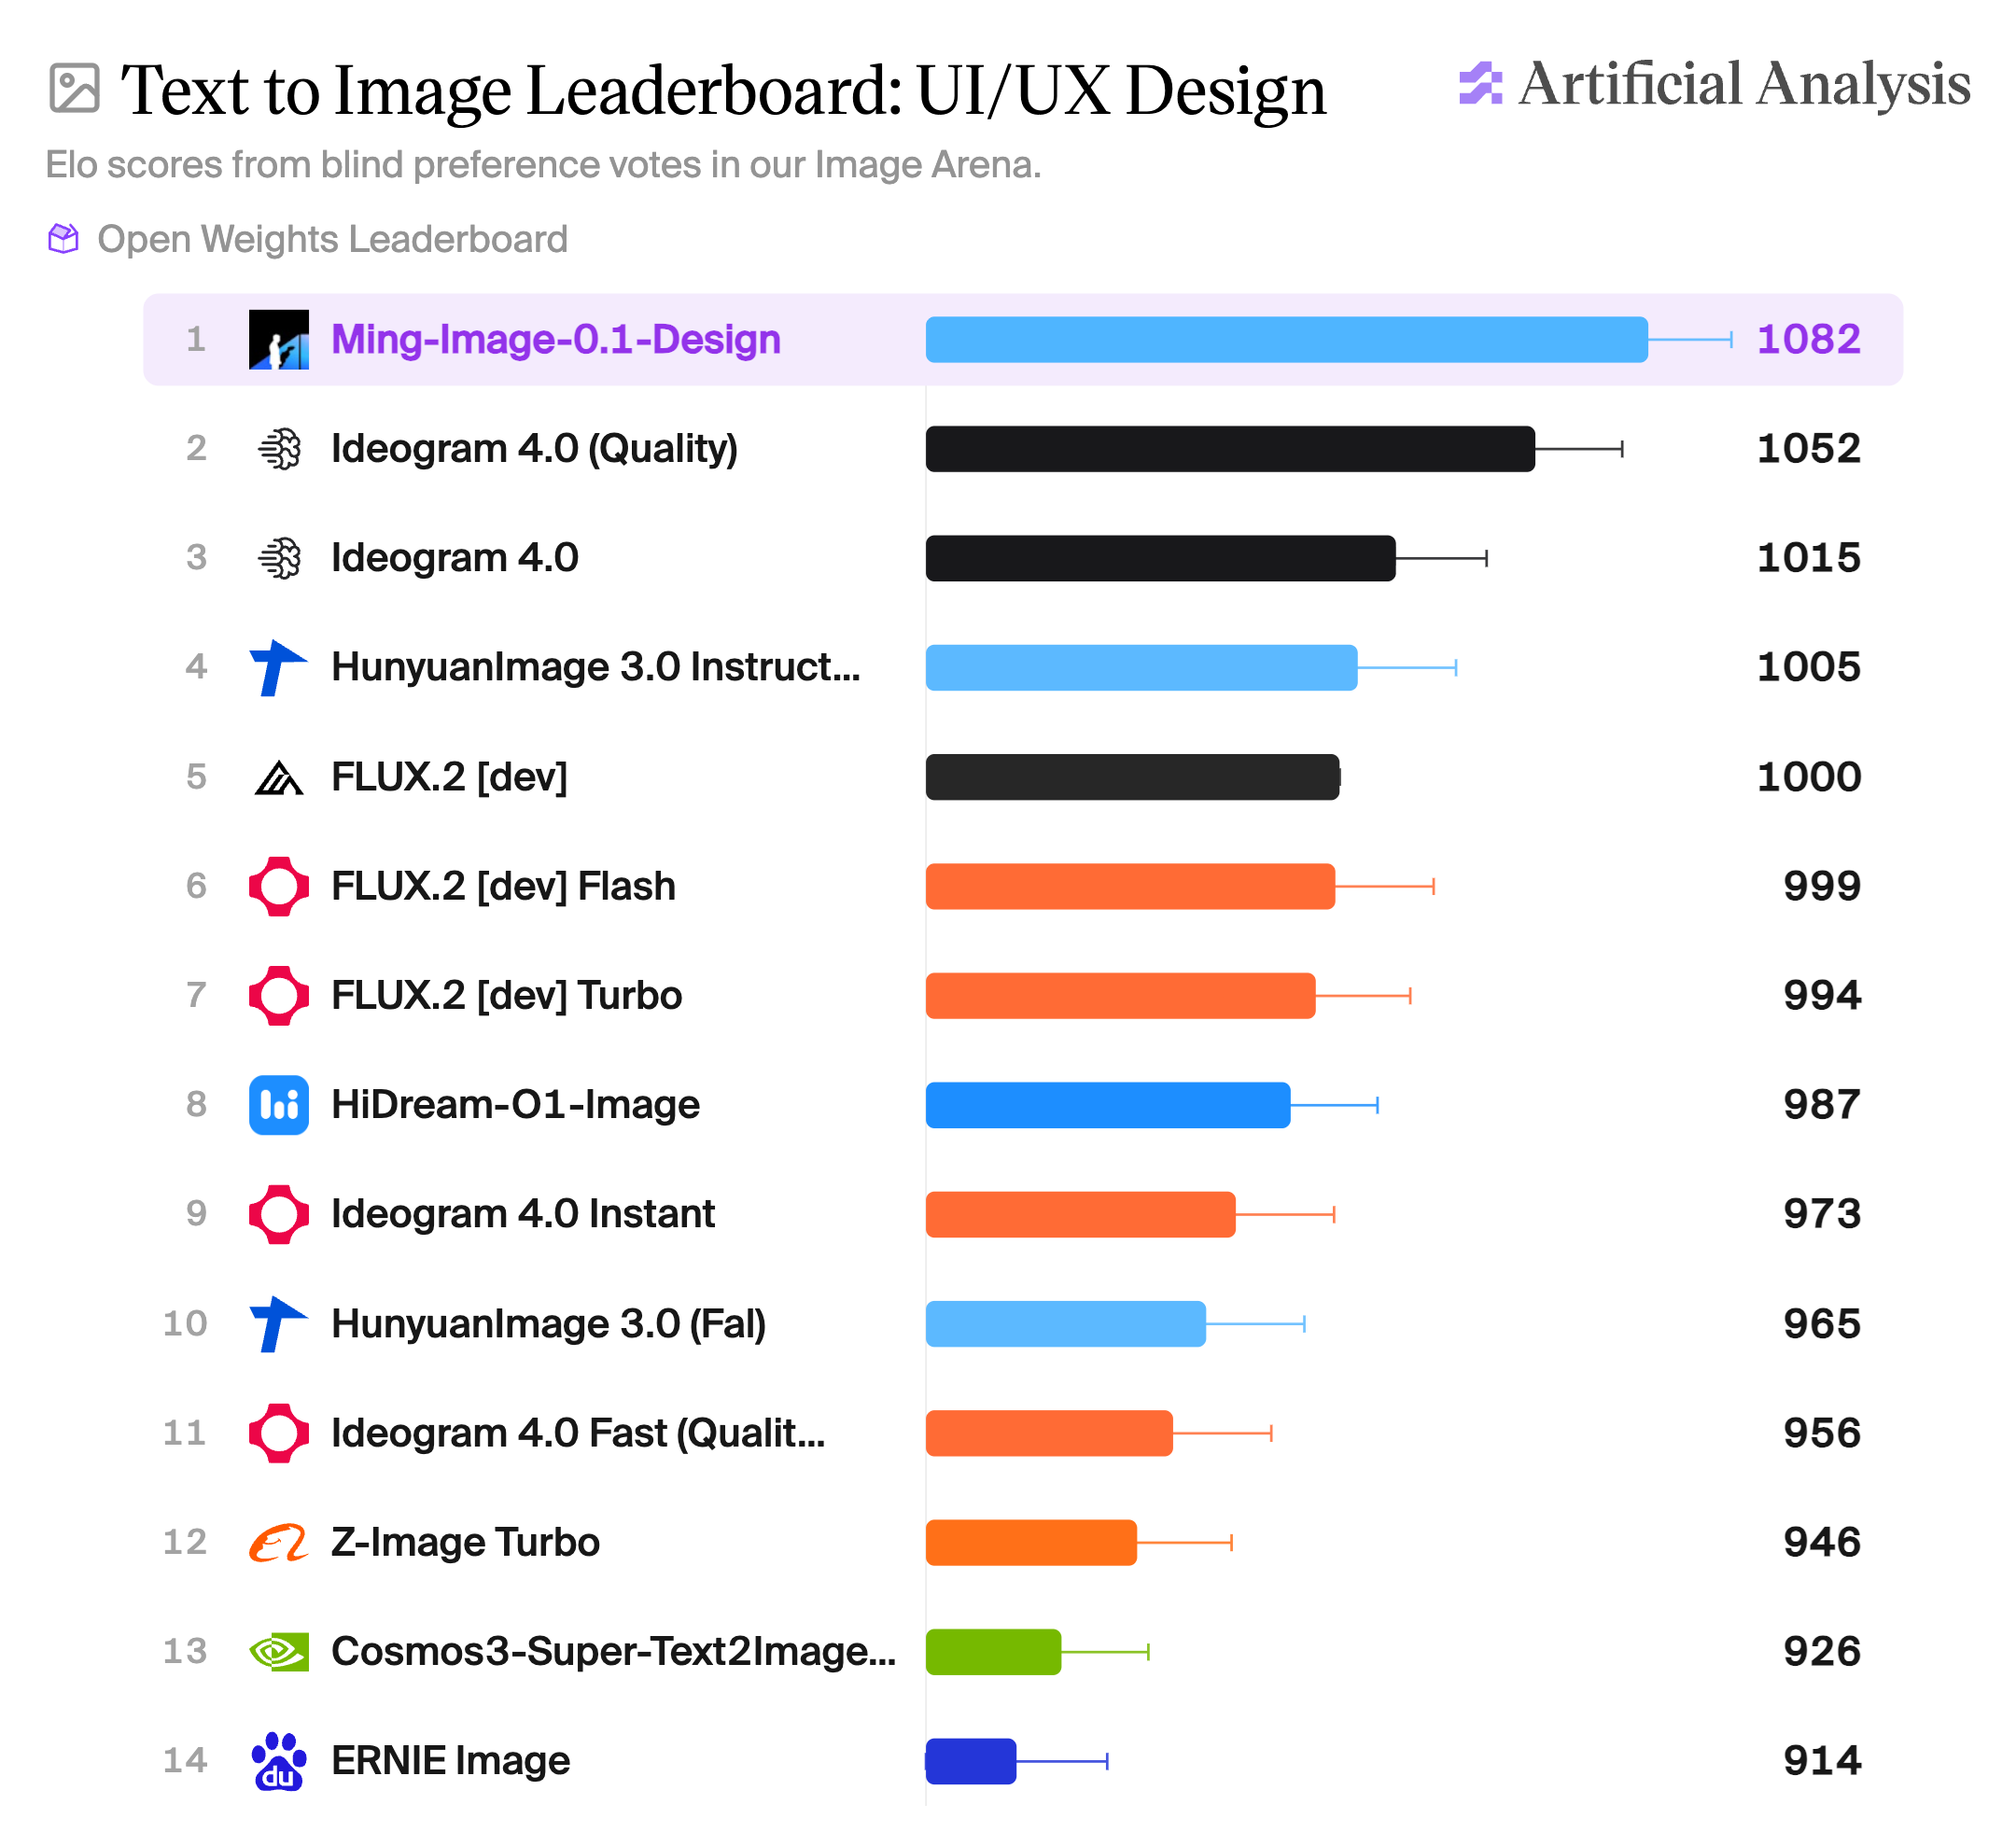
inclusionAI's Ming-Image targets graphic design
A new MIT-licensed text-to-image model leans into legible text rendering and transparent RGBA output for design work.
SenseTime's SenseNova-U1.5 Unifies Vision Tasks
An 8B model drops the usual encoder and VAE in favor of a single native architecture spanning understanding, reasoning, and image generation.
LLaDA-Image: A Fully Open 6B Image Generator
inclusionAI pairs a diffusion transformer with a frozen vision-language model and publishes the entire training recipe.
0 comments
No comments yet. Be the first to weigh in.