Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
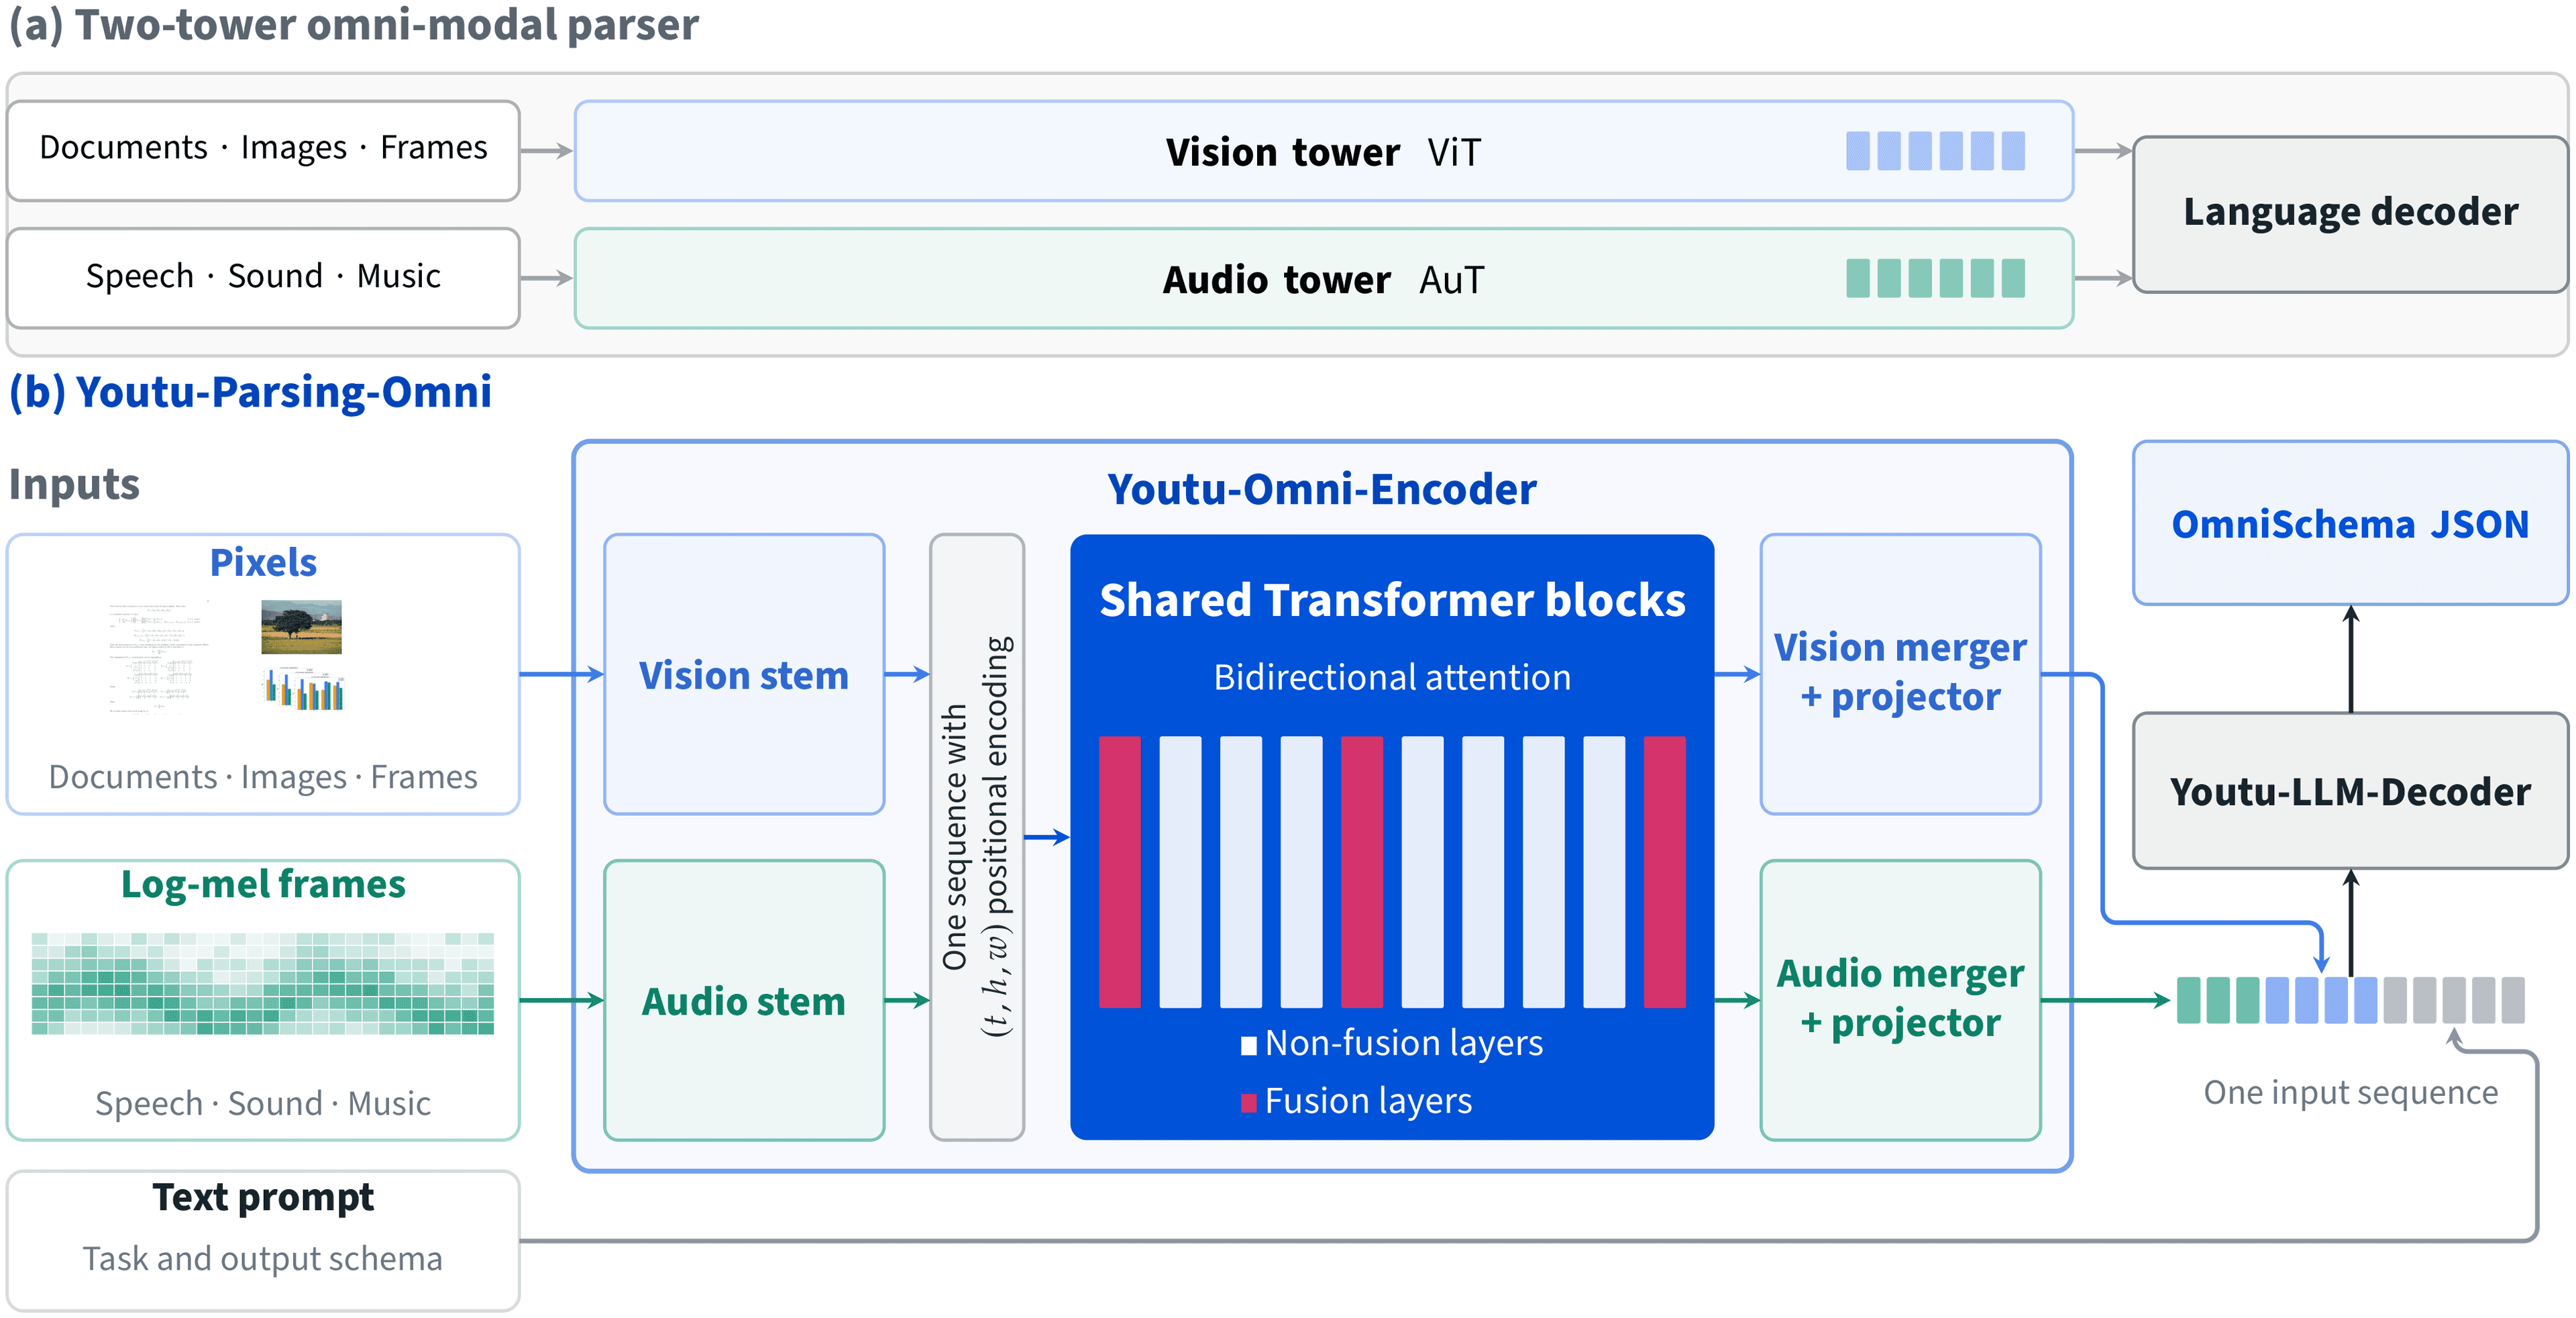
Tencent has published Youtu-Parsing-Omni, an omni-modal document parsing and OCR model, to Hugging Face. Unlike conventional OCR systems built solely around images, the model is described as handling image, audio, and video inputs, positioning it as a broader parsing engine rather than a single-purpose text extractor (Hugging Face).
The release falls under Tencent's Youtu line and is the first entry in this particular family. It is classified as a vision-language model with multimodal capabilities, though Tencent has not disclosed parameter counts, context length, or detailed architecture specifications in the record accompanying the launch.
Why it matters
Document parsing is one of the most practical applications of multimodal AI, underpinning everything from invoice processing to knowledge-base construction. Extending that work across audio and video suggests an attempt to unify parsing pipelines that today rely on separate tools for transcription, OCR, and layout analysis.
- Omni-modal scope: image, audio, and video inputs
- Focus on document parsing and OCR tasks
- Released as open weights on Hugging Face
The model carries a custom "other" license, so teams evaluating it for production should review the terms before deployment. As an initial release, it will be worth watching whether Tencent follows up with benchmarks and documentation that clarify how the omni-modal claims translate into real-world accuracy.
Sources
- Visit
tencent/Youtu-Parsing-Omni
Hugging Face
More from Tencent
All Tencent releases →Tencent's T1 Targets Long-Horizon Terminal Work
A 122B mixture-of-experts model trained with reinforcement learning claims state-of-the-art results on Terminal-Bench.

Tencent Previews Hunyuan Hy4, an Apache MoE Model
The company's next-generation Hunyuan language model arrives as an early preview with a permissive license and a mixture-of-experts design.
Tencent's WeMM-Embedding-9B Unifies Text, Image and Video
The WeChat team releases a 9-billion-parameter multimodal embedding model that maps three modalities into one shared vector space.
More in Vision-Language
All Vision-Language →
Liquid AI's d1-3B brings multimodal models to the edge
The new LFM2-based d1-3B is a compact vision-language model aimed at running decisions directly on-device.

Perplexity releases a 27B model for multimodal routing
The open-weight 'decider' model is designed to classify queries and route them inside Perplexity's stack.
Cloudflare's Clef brings structured decisions to open models
The new open-weight vision-language family outputs typed, structured results and arrives alongside a reinforcement-learning fine-tuning platform.
0 comments
No comments yet. Be the first to weigh in.