Indra OCR brings CPU-friendly document parsing
A new open vision-language model targets layout, handwriting and multilingual text extraction without a GPU.
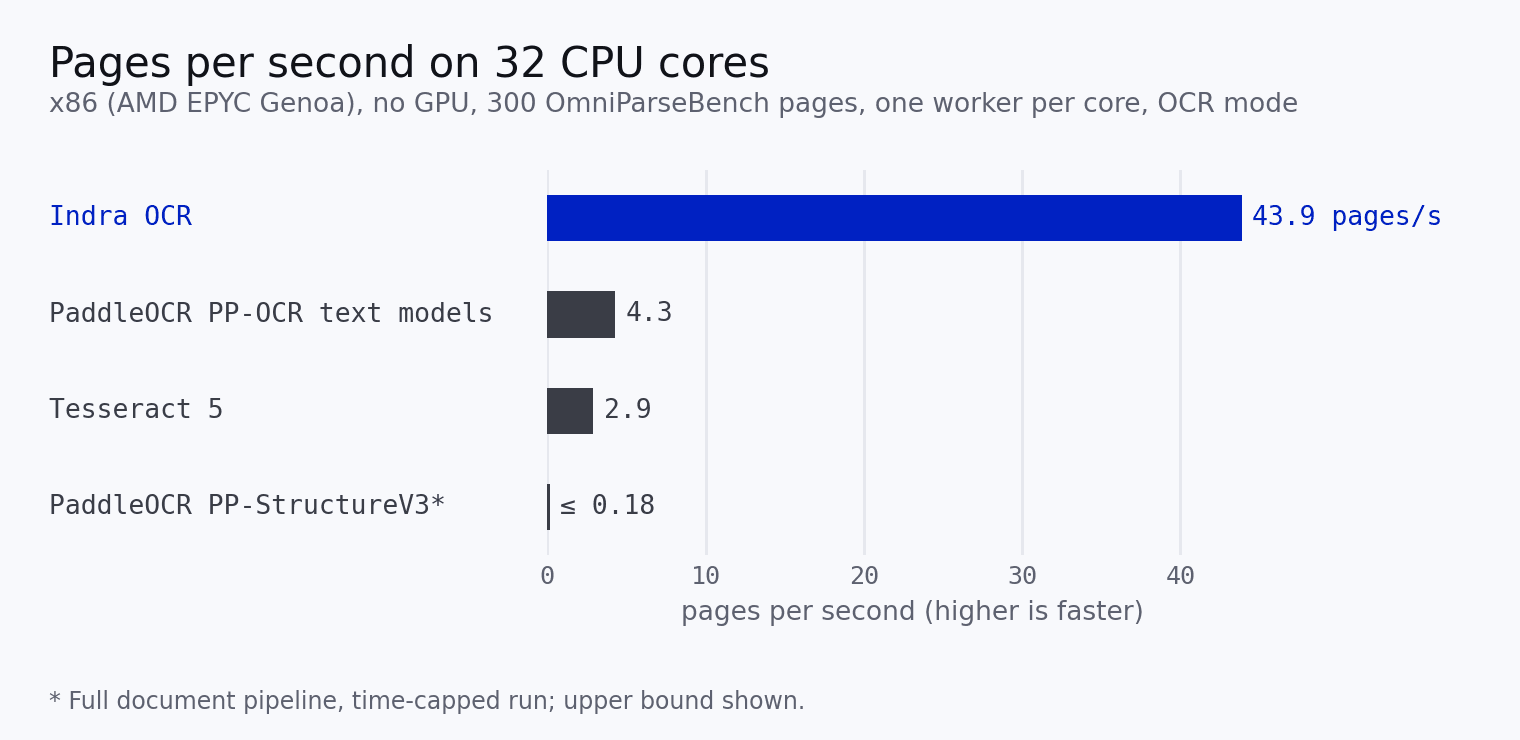
Indra OCR, published on Hugging Face under the datalab-to namespace, is a new vision-language model built for document understanding. Version 1.0 is pitched as a general-purpose OCR and parsing system that reads page layout, handles handwriting, and works across multiple languages.
What stands out is the deployment story: the model is designed to run on CPU, not just high-end accelerators. For teams processing invoices, forms, scanned archives or mixed-language paperwork, that lowers the barrier to self-hosting and makes batch document pipelines cheaper to operate.
Why it matters
Document OCR has quietly become one of the most practical uses of open models, feeding retrieval systems, data-entry automation and digitization projects. A release that combines layout awareness with handwriting and multilingual coverage covers the hard cases that trip up simpler OCR engines.
- Layout parsing to preserve document structure
- Handwriting recognition alongside printed text
- Multilingual support for mixed-language documents
- CPU execution for lower-cost deployment
The model ships under a non-standard license, so teams should review the terms on the model page before using it in production. As an initial 1.0 release, Indra OCR is worth watching for how it compares against established open OCR stacks in real-world accuracy.
Sources
- Visit
datalab-to/indra-ocr
Hugging Face
More from Datalab To
All Datalab To releases →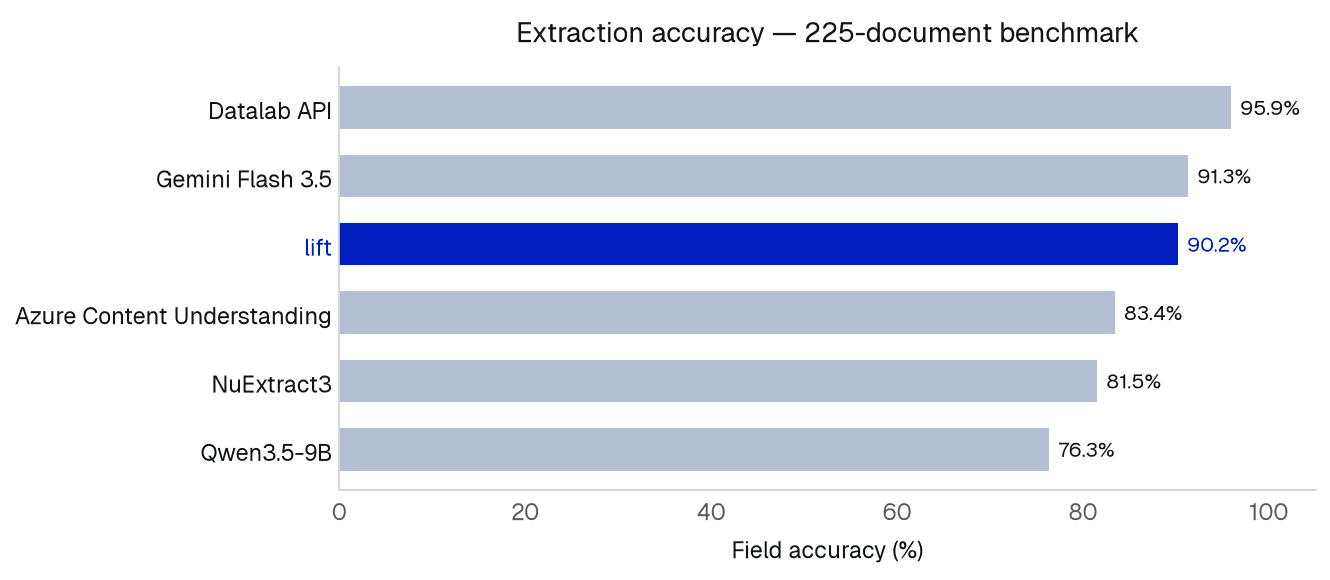
LIFT: A Qwen3.5-Based VLM for PDF-to-JSON Extraction
Datalab's new open vision-language model targets structured data extraction from documents, turning messy PDFs into clean JSON.
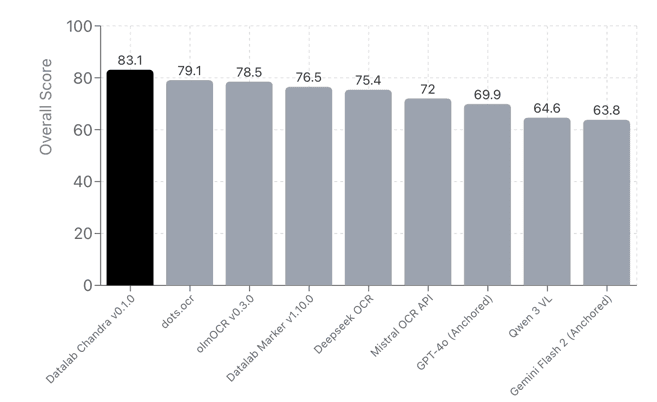
Datalab Releases Chandra, a New OCR Vision Model
The new vision-language model from Datalab is fine-tuned from Qwen2-VL to specialize in extracting text and structure from complex documents.
More in Vision-Language
All Vision-Language →
DeepSeek V4.1-Flash Adds Vision and Reasoning
The new MIT-licensed checkpoint folds image understanding and reasoning into DeepSeek's fast, mixture-of-experts Flash line.
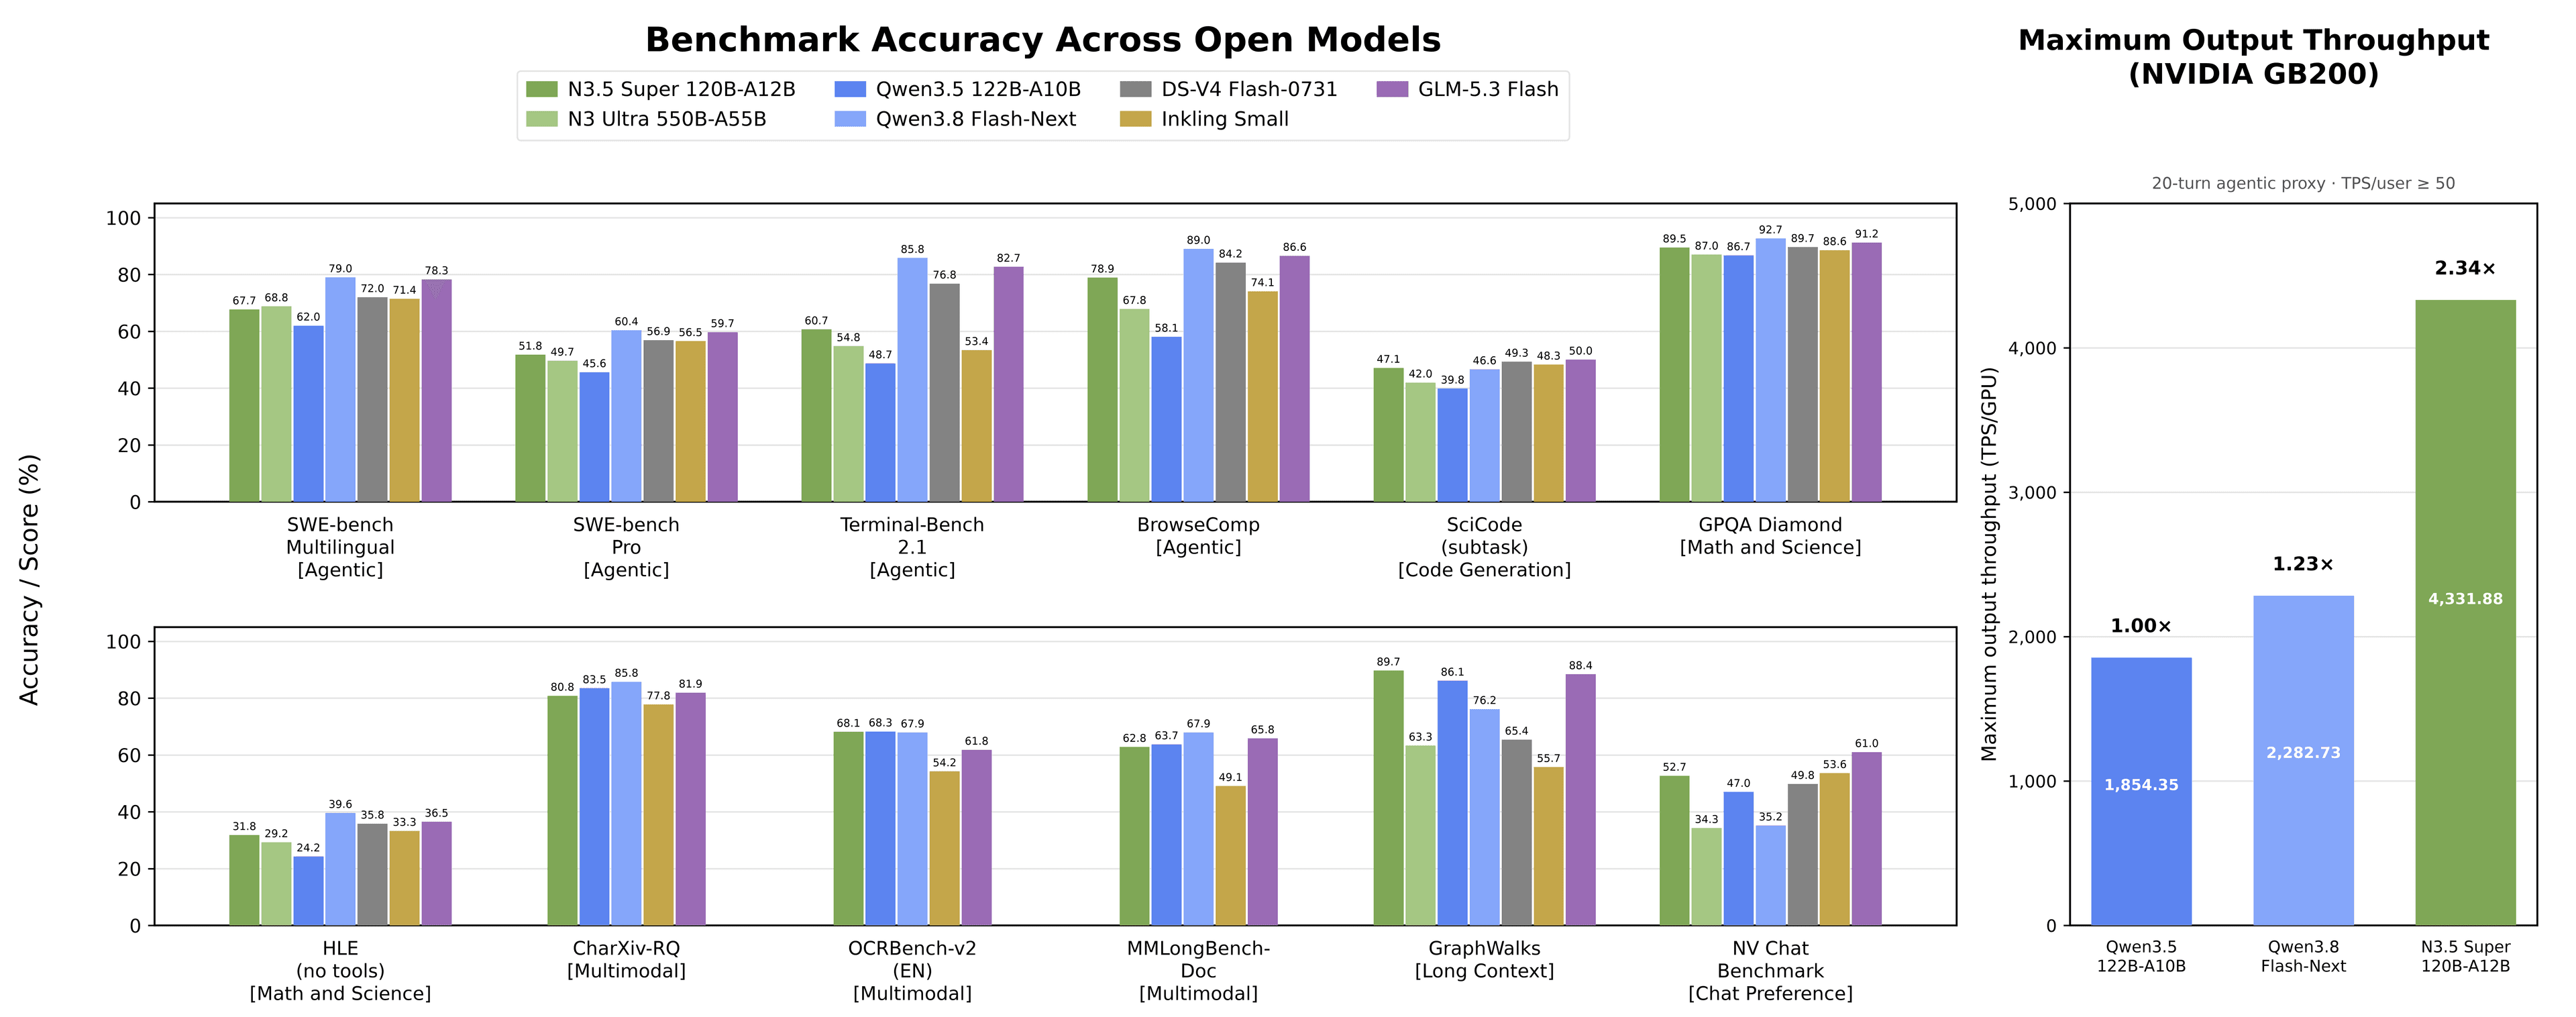
NVIDIA's Nemotron 3.5 Super VL Pairs Vision With MoE Efficiency
The 120B-parameter vision-language model activates just 12B per token and ships in NVIDIA's NVFP4 format for leaner inference.
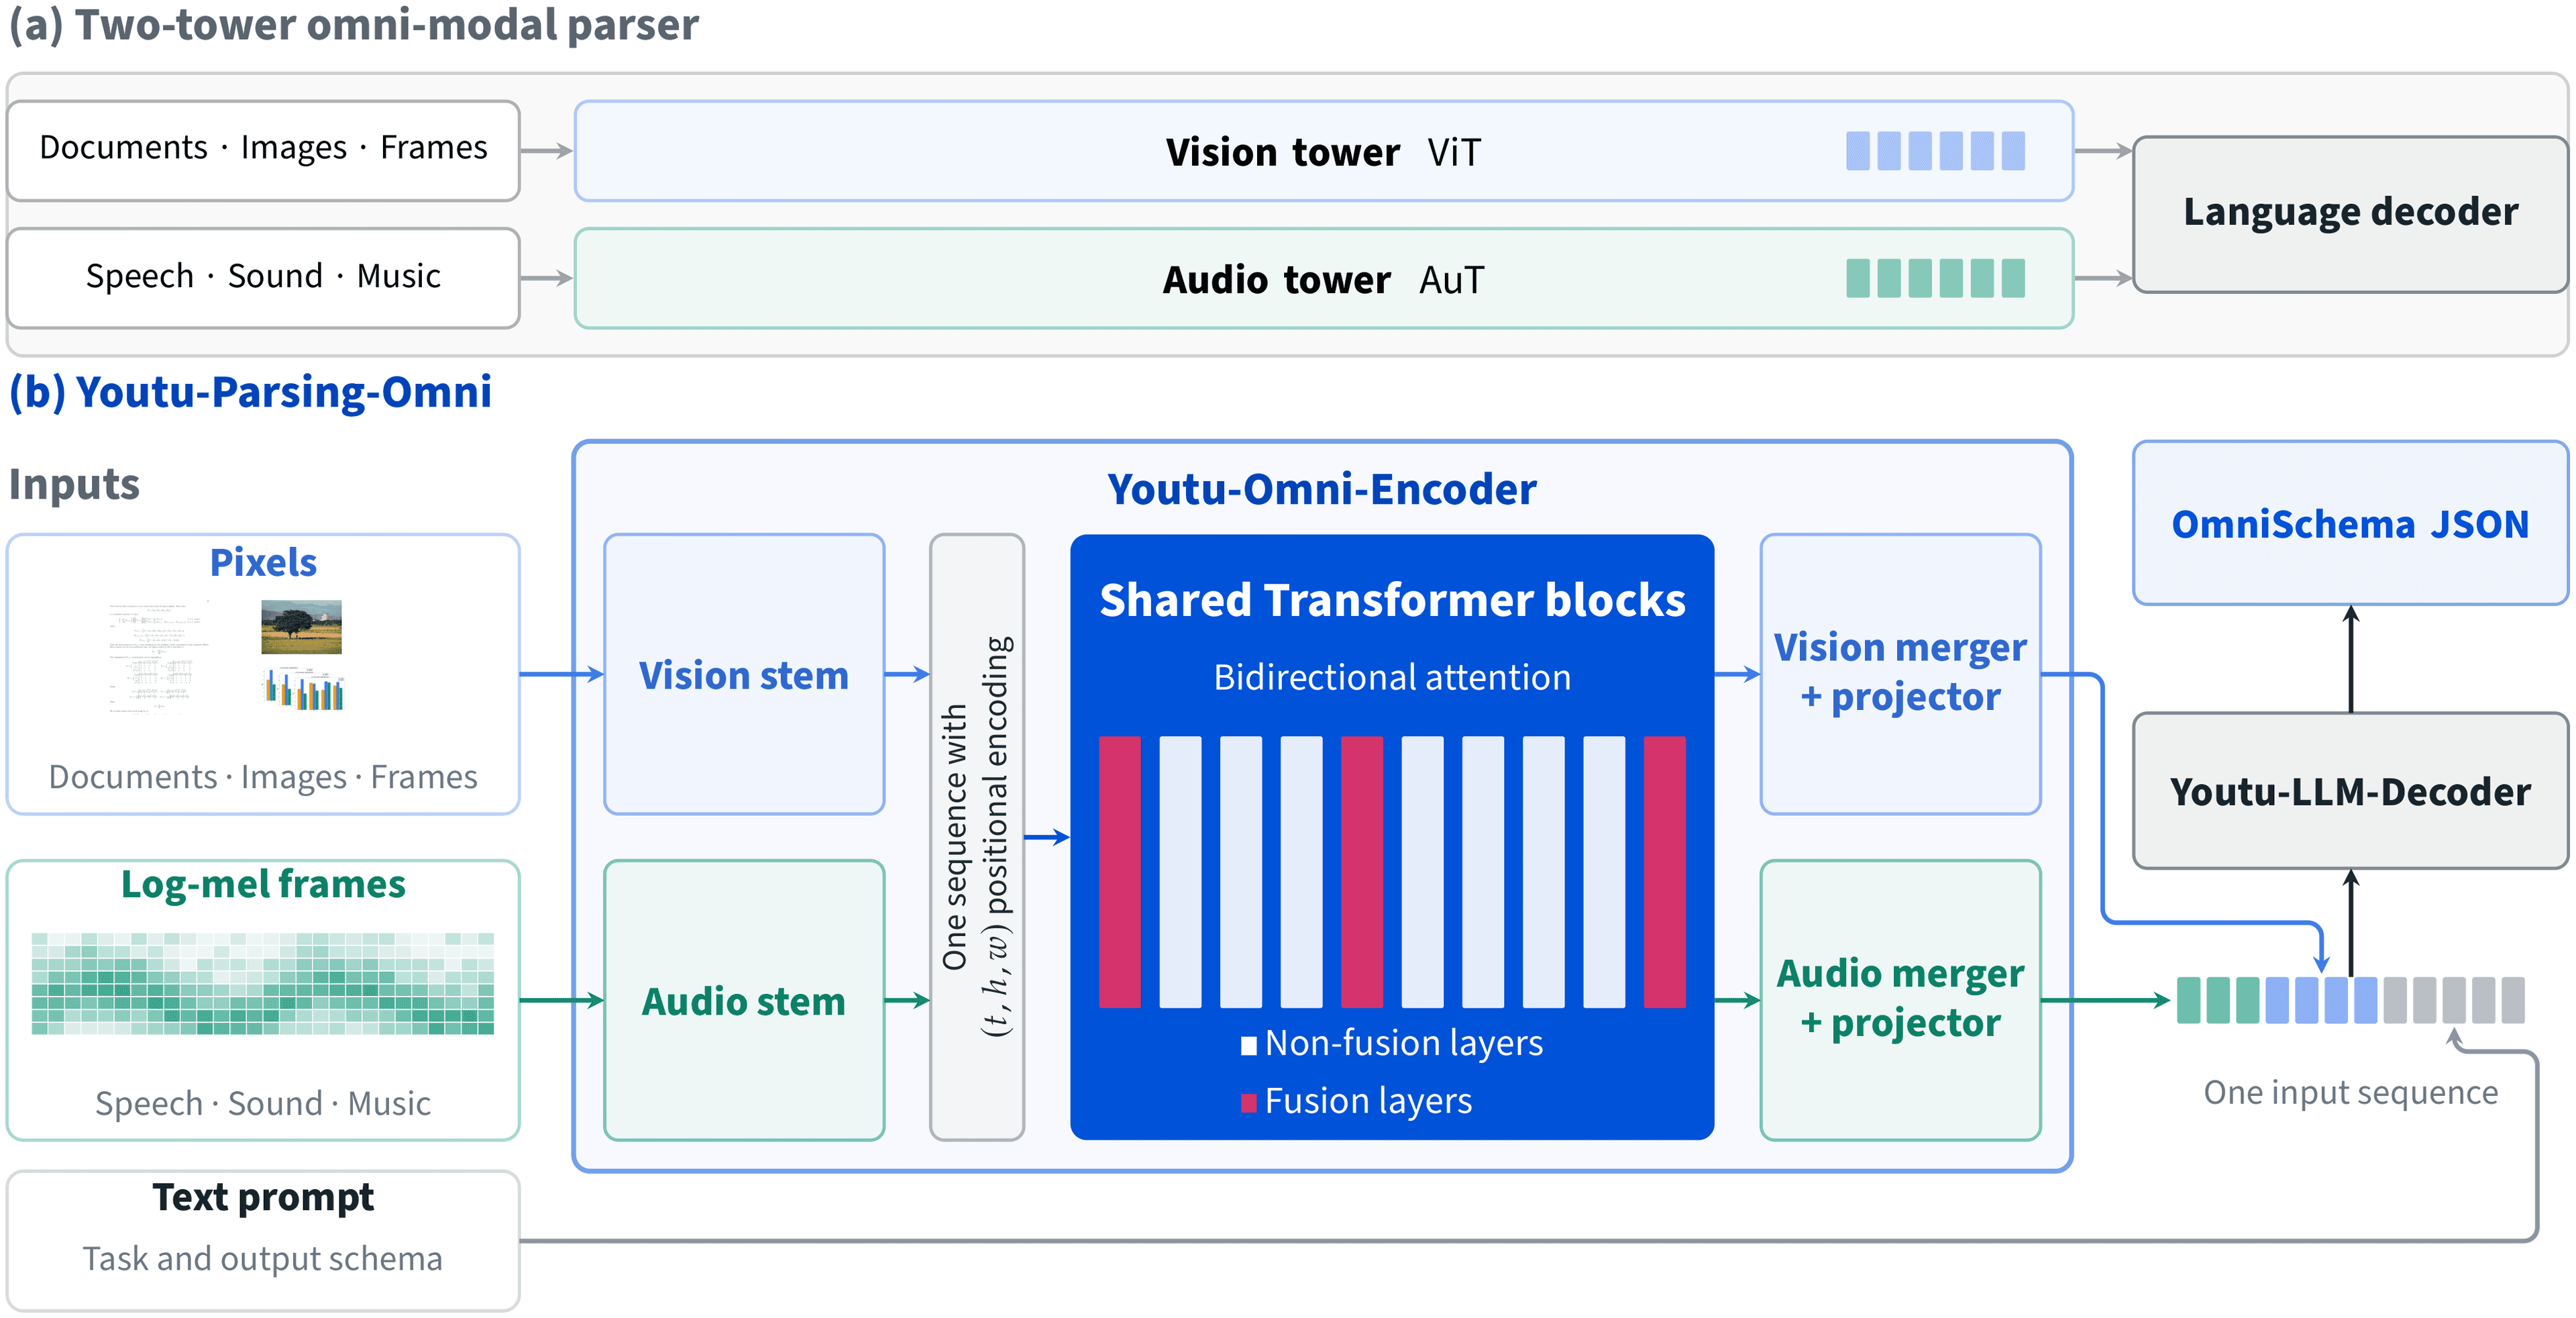
Tencent's Youtu-Parsing-Omni tackles docs, audio, video
A new open-weights parsing model from Tencent extends OCR beyond the page into audio and video inputs.
0 comments
No comments yet. Be the first to weigh in.