OpenMOSS Releases Apache-2.0 Bilingual Image Model
MOSS-Image Base arrives as a permissively licensed text-to-image foundation with English and Chinese support.
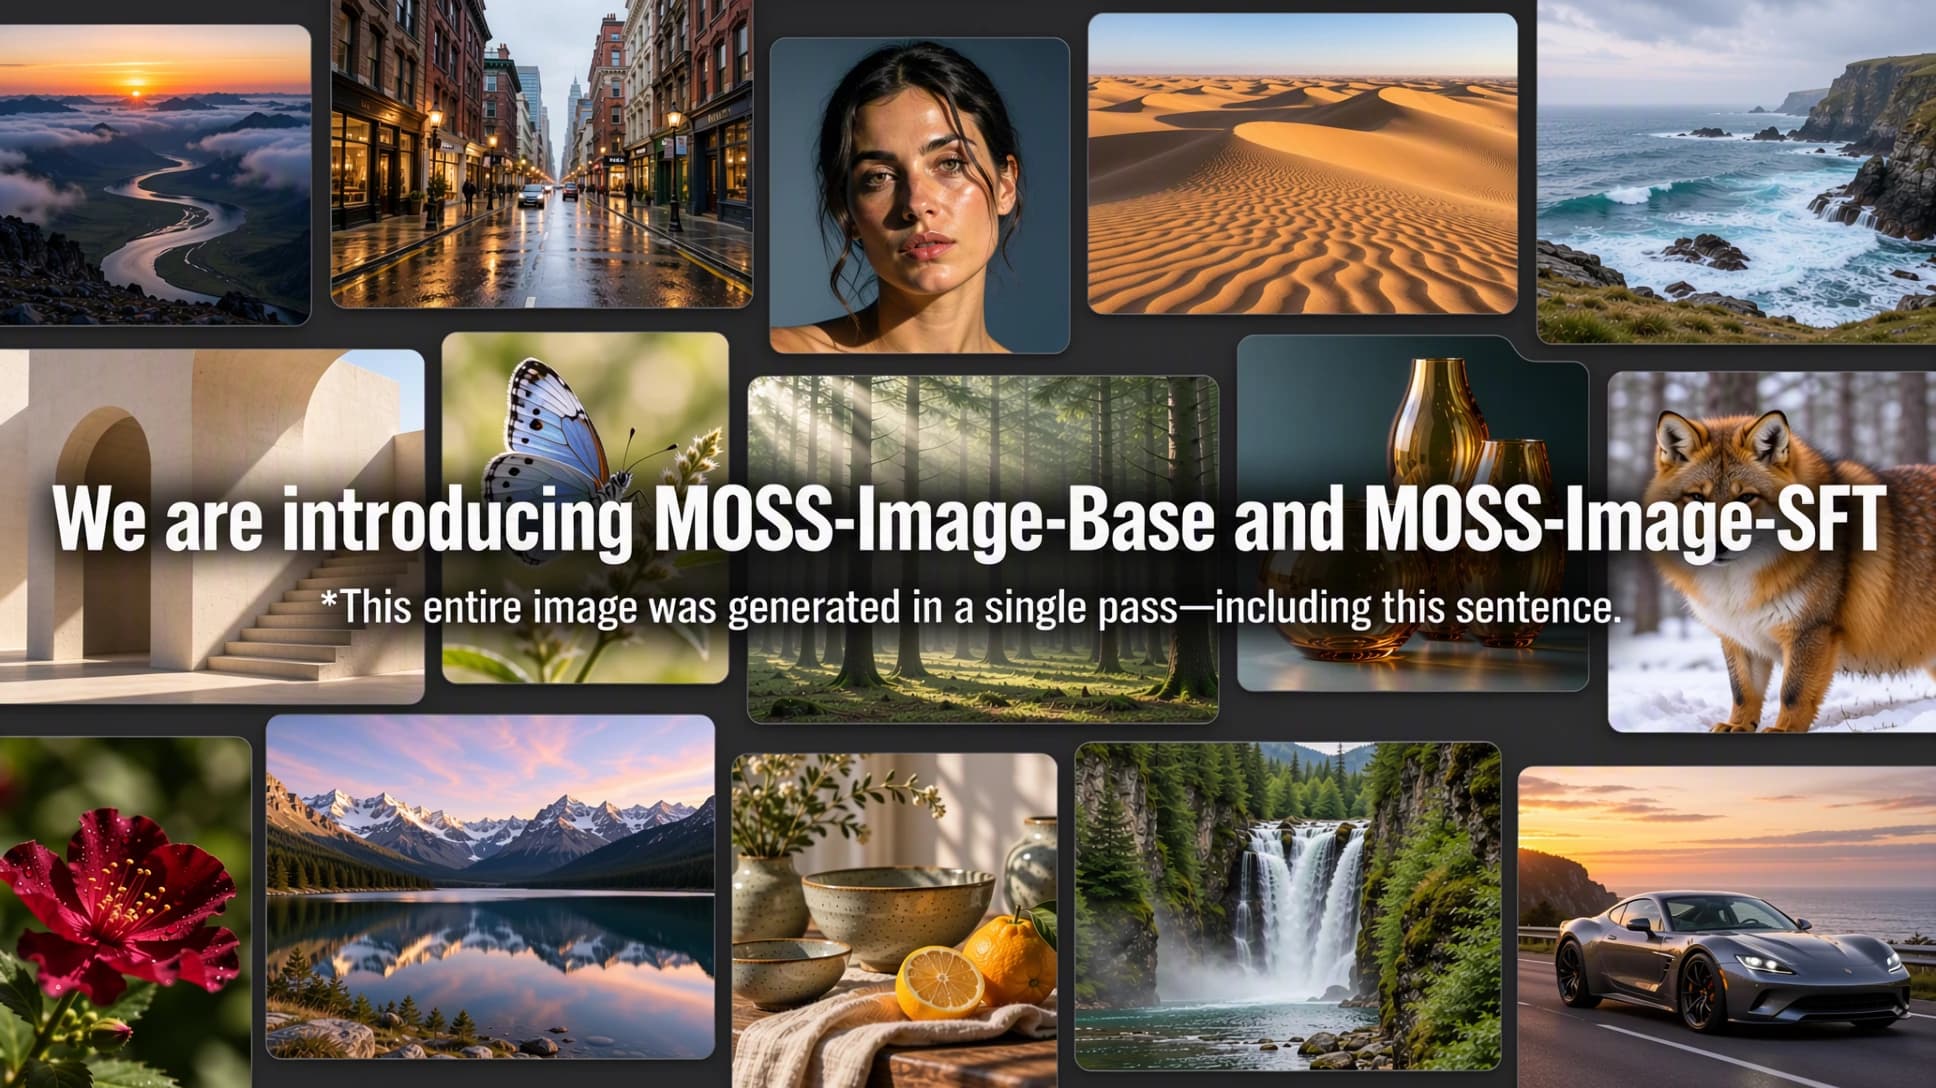
OpenMOSS has released MOSS-Image Base, a text-to-image model published under the permissive Apache-2.0 license. Positioned as a base model, it is aimed at developers and researchers who want a foundation to build on rather than a finished consumer product.
The standout detail is its bilingual design: the model is built to handle prompts in both English and Chinese. That broadens its usefulness for teams working across both languages, a practical gap that many Western-origin image models leave open.
Why it matters
Apache-2.0 licensing is the headline here. Unlike some image generators that ship with usage restrictions or research-only terms, a true permissive license gives teams clear latitude to fine-tune, deploy, and build commercial tools on top of the weights.
- Open Apache-2.0 license with few restrictions
- Bilingual English and Chinese prompt support
- Released as a base model for downstream fine-tuning
OpenMOSS has not published parameter counts, supported resolutions, or benchmark results alongside the initial drop, so direct comparisons to established open models remain hard to make. For now, the release is best read as an invitation to experiment, with the community likely to surface its real strengths and limits as people put it through its paces. The weights are available now on Hugging Face.
Sources
- Visit
OpenMOSS-Team/MOSS-Image-Base
Hugging Face
More from OpenMOSS
All OpenMOSS releases →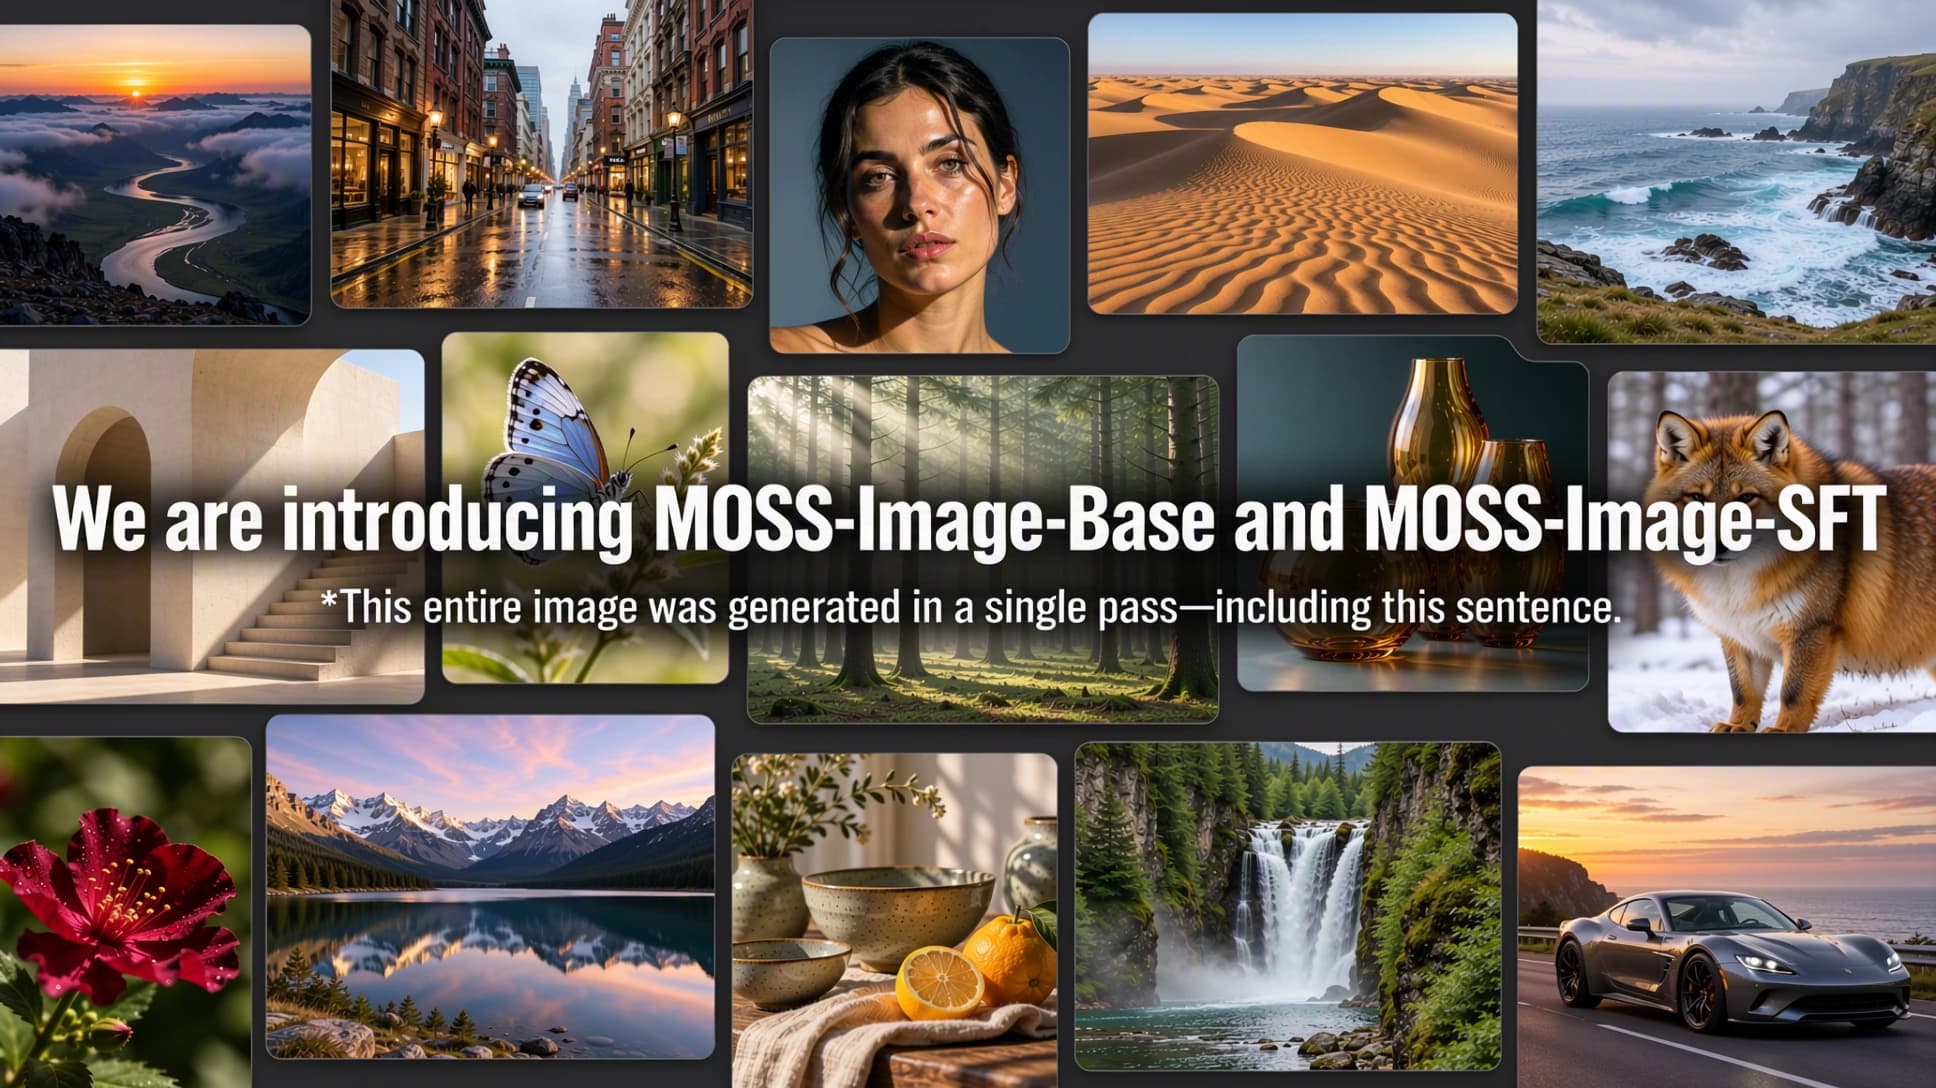
OpenMOSS Releases MOSS-Image Under Apache 2.0
The academic team behind the MOSS project moves into text-to-image generation with a permissively licensed model and a fine-tuned SFT variant.
OpenMOSS Debuts MOSS-VL for Real-Time Vision Interaction
A new open vision-language model family uses gated cross-attention to enable streaming, low-latency multimodal exchanges.
MameLoshnLM Brings Yiddish Into the Open LLM Era
OpenMOSS releases what it calls the first open-source 8B language model built specifically for Yiddish, paired with an evaluation benchmark.
More in Text → Image
All Text → Image →
MiniMax Releases H3 Image, Its Open Text-to-Image Model
The Chinese AI lab enters the open image-generation space with a single model that both creates and edits pictures from text.
Bria's Fibo 2.0 Brings Structured Prompts to Open Image AI
The new text-to-image and editing model leans on structured prompts and multi-reference inputs for more controllable generation.

Black Forest Labs ships FLUX.3 Image Klein for ComfyUI
The lab's latest open image model arrives packaged for ComfyUI with both generation and editing built in.
0 comments
No comments yet. Be the first to weigh in.